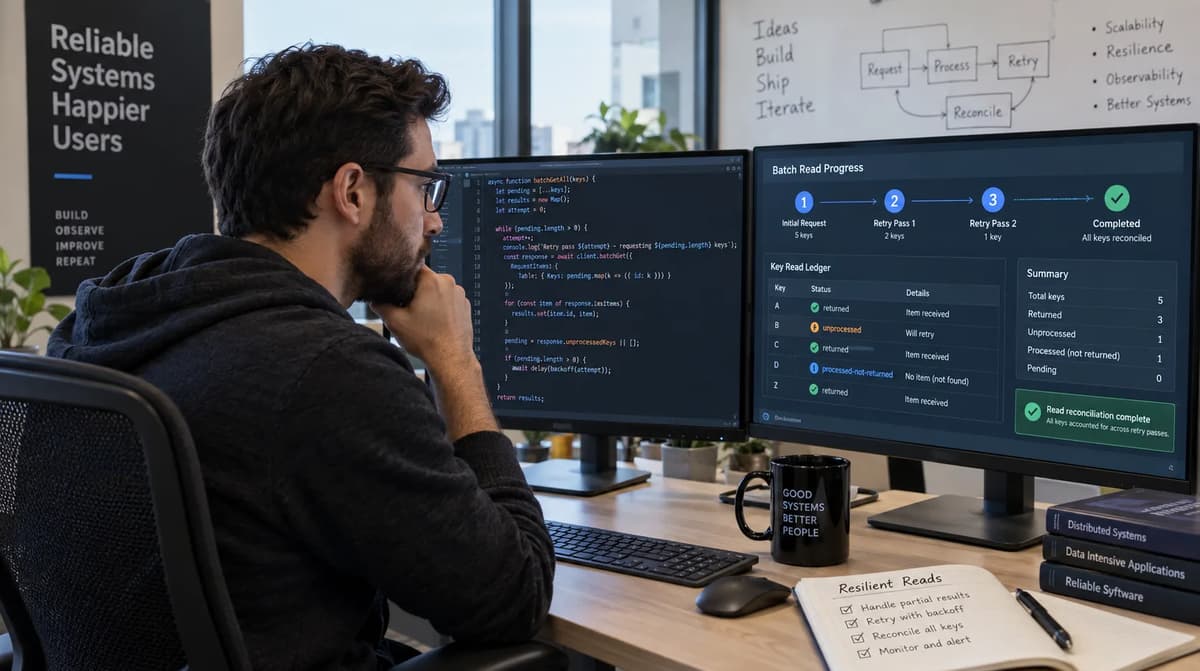
An HTTP 200 from BatchGetItem is not the acceptance criterion for a keyed read. The more useful question is narrower and harder: does every requested key now have an evidence-backed disposition? AWS documents that BatchGetItem can complete successfully while returning only a partial result, with unread keys carried in UnprocessedKeys; requested items that do not exist are omitted; and returned items have no guaranteed order. The operation is therefore a reconciliation problem, not a row-count problem. See the AWS BatchGetItem API reference.
This playbook freezes that problem into one deterministic fixture: one DynamoDB table, one string partition key named pk, one Region, no concurrent mutation, and requested keys Q={A,B,C,D,Z}. A through D exist with values 10,20,30,40; Z is deliberately absent. Three synthetic HTTP-200 responses progressively return C,A, then B, then D, while UnprocessedKeys shrinks from {B,D} to {D} to empty.
The approval target is not “the call succeeded.” It is a typed result in which every original key belongs to exactly one of three disjoint sets: returned, processed-but-not-returned, or unresolved. The helper must preserve that evidence across bounded application passes, distinguish SDK retries from UnprocessedKeys retries, reject impossible ledgers, and fail conservatively when evidence stops. The deterministic Botocore Stubber laboratory below was executed locally; the optional live smoke test was not, and no claim here treats a stubbed throttle or partial response as observed DynamoDB service behavior.
Define a complete read before inspecting the status code
Start with the caller contract, because BatchGetItem itself does not know whether an omitted item is acceptable to your application. For this fixture, the independent manifest is Q={A,B,C,D,Z}. The known answer says A-D exist and Z does not. That is fixture truth, not a conclusion inferred from the response.
Three questions must remain separate. First, did the API request produce a usable response? Second, among the keys in that specific request pass, which were processed and which remain explicitly unprocessed? Third, does the caller require every processed key to correspond to an existing item? These are different acceptance layers. The AWS API contract allows a successful partial response when at least some reads are processed and places unread keys in UnprocessedKeys; it also omits nonexistent items rather than returning placeholder rows.
For this playbook, DynamoDB BatchGetItem completeness means coverage of the original key manifest, not five returned rows. A complete ledger can legitimately contain four returned items and one processed-but-not-returned key. Conversely, four rows are not complete if the fifth key is still unresolved.
The decision rule is therefore:
Accept only when the three disposition sets are disjoint, their union equals the original manifest, unresolved is empty, and the caller’s required-item policy is satisfied.
Retry only keys named in UnprocessedKeys from a usable partial response, within explicit pass and deadline bounds.
Hold when evidence ends with unresolved keys or a request-level exception before a usable response.
Repair malformed input, impossible response membership, or a helper contract defect before retrying.
This is intentionally narrower than broad database integration choices: the database is already chosen, the access path is already keyed, and the review question is whether the client can prove a disposition for each requested key.
Freeze the client, table and consistency baseline
A reproducible acceptance test needs an environment manifest that distinguishes an installed runtime from living documentation. The documentation in this playbook was rechecked on the September 24, 2026 research cutoff; an access date for living AWS documentation is not treated as a publication or feature-launch date. The local deterministic execution used Python 3.13.5, boto3 1.43.18, botocore 1.43.18 and pytest 9.0.2. The fixture revision is batchget-ledger-fixture-r1; the helper revision represented by the code below is batchget-ledger-helper-r1. The table is KnownAnswer, with partition key pk of DynamoDB type S and no sort key. The lab uses one Region, us-east-1, solely to satisfy client construction; Stubber prevents endpoint calls.
That local package lock is deliberately not the same thing as the documentation selector. On September 24, 2026, PyPI showed boto3 1.43.101 and botocore 1.43.101 as newer releases than the installed 1.43.18 used for the execution recorded here. That mismatch is evidence to record, not something to hide by silently rewriting the test manifest.
Use explicit client retry configuration. AWS’s Boto3 retry guide documents standard mode and recommends total_max_attempts in a Config object when you want a number that always includes the initial request. The configuration below sets three total SDK attempts per low-level API call.
import boto3
from botocore.config import Config

client = boto3.client(
    "dynamodb",
    region_name="us-east-1",
    aws_access_key_id="stub-access-key",
    aws_secret_access_key="stub-secret-key",
    config=Config(retries={"mode": "standard", "total_max_attempts": 3}),
)
Fake credentials are appropriate only for the stubbed client because no service endpoint is contacted. A live smoke test belongs in an owned AWS account with normal credential resolution and a small, authorized table. Record account identifier, Region, table name, key schema, ConsistentRead mode, dependency versions, helper revision and fixture/data revision for every live run. Do not deliberately force throttling against a real table just to imitate this fixture.
For an optional smoke test, pre-create the five-key fixture in an owned table, intentionally omit Z, and run one small read through the same helper. The smoke test is an integration check, not a pressure test. Before invoking it, capture the account and Region with your normal operational tooling and preserve them alongside the consistency flag. A minimal runner can be:
import os
import boto3
from botocore.config import Config
from batch_read import batch_get_reconciled

region = os.environ["AWS_REGION"]
table = os.environ["DDB_TABLE"]
consistent = os.environ.get("DDB_CONSISTENT_READ", "true").lower() == "true"

client = boto3.client(
    "dynamodb",
    region_name=region,
    config=Config(retries={"mode": "standard", "total_max_attempts": 3}),
)
result = batch_get_reconciled(
    client,
    table_name=table,
    requested_pks=["A", "B", "C", "D", "Z"],
    consistent_read=consistent,
    max_passes=3,
    timeout_s=2.0,
)
print(result.complete, result.returned, result.processed_not_returned, result.unresolved)
No live execution evidence is supplied for that runner in this article. Its acceptable purpose is to confirm authentication, Region/table wiring, projection, result parsing and logging in the owned environment. If it happens to encounter UnprocessedKeys, the same bounded logic applies; the smoke plan must not attempt to induce them.
The broader career distinction between relational and non-relational operations is covered elsewhere under SQL and NoSQL specialization boundaries. Here, the only relevant boundary is client evidence for this low-level DynamoDB read.
Build the independent key manifest
The oracle must not be generated from the helper’s own output. Otherwise a defect in key normalization or response reconciliation can infect both implementation and expected result and still “pass.” Freeze the requested order and the known fixture values separately:
TABLE = "KnownAnswer"
ORDER = ["A", "B", "C", "D", "Z"]
EXPECTED_VALUES = {"A": "10", "B": "20", "C": "30", "D": "40"}


def typed_key(pk: str) -> dict:
    return {"pk": {"S": pk}}


def item(pk: str, n: int) -> dict:
    return {"pk": {"S": pk}, "value": {"N": str(n)}}
The low-level boto3 DynamoDB client uses DynamoDB AttributeValue shapes, so a string key is represented as {"pk": {"S": "A"}}; numeric attributes are represented with string payloads such as {"N": "10"}. The helper compares canonical Python strings such as "A", not nested typed dictionaries. That normalization matters because set reconciliation should operate on one stable key representation.
The request projection must retain pk. AWS explicitly notes that BatchGetItem does not return items in a particular order and recommends including primary-key values in the projection so the client can identify which item was returned. A response item without pk is therefore not merely inconvenient in this contract: it is untraceable evidence and must be rejected.
The three inert responses are independent test data:
RESPONSE_1 = {
    "Responses": {TABLE: [item("C", 30), item("A", 10)]},
    "UnprocessedKeys": {TABLE: {"Keys": [typed_key("B"), typed_key("D")]}},
    "ResponseMetadata": {"RequestId": "req-1", "HTTPStatusCode": 200, "RetryAttempts": 0},
}

RESPONSE_2 = {
    "Responses": {TABLE: [item("B", 20)]},
    "UnprocessedKeys": {TABLE: {"Keys": [typed_key("D")]}},
    "ResponseMetadata": {"RequestId": "req-2", "HTTPStatusCode": 200, "RetryAttempts": 0},
}

RESPONSE_3 = {
    "Responses": {TABLE: [item("D", 40)]},
    "UnprocessedKeys": {},
    "ResponseMetadata": {"RequestId": "req-3", "HTTPStatusCode": 200, "RetryAttempts": 0},
}
These are synthetic Stubber responses, not captured AWS responses. The HTTP 200 values are fixture fields chosen to reproduce the documented partial-success shape.
Three key sets, three different meanings
For every usable pass, let R be keys returned as items, U be keys named in UnprocessedKeys, and P be the keys requested in that pass. Then the keys processed without a returned item are exactly:
N = P - R - U.Do not compute N as “every initially requested key that has not appeared yet.” That would misclassify B and D after the first response. In pass one, P={A,B,C,D,Z}, R={A,C}, and U={B,D}, so N={Z}. In pass two, P={B,D}, R={B}, and U={D}, so N={}. In pass three, P={D}, R={D}, and U={}, so N={}.
Across the whole operation, the invariant is:
Q = returned ∪ processed-not-returned ∪ unresolved, with all three sets pairwise disjoint.
Under the frozen fixture, the mathematically expected terminal sets are returned={A,B,C,D}, processed-not-returned={Z}, and unresolved={}. Fixture existence is separate from read disposition: Z is known absent because the fixture says so; the helper’s job is only to prove that the read pass covering Z was processed and produced no item.
Reproduce the misleading HTTP 200 result
A deliberately flawed one-call helper makes the defect visible. It sends the whole manifest once and returns only the response items:
def flawed_batch_get(client, table_name: str, pks: list[str]) -> list[dict]:
    response = client.batch_get_item(
        RequestItems={
            table_name: {
                "Keys": [typed_key(pk) for pk in pks],
                "ConsistentRead": True,
                "ProjectionExpression": "#pk, #v",
                "ExpressionAttributeNames": {"#pk": "pk", "#v": "value"},
            }
        }
    )
    return response["Responses"].get(table_name, [])
The control test must compare response membership with the independent manifest, not with an expectation derived from the helper:
def test_intentionally_failing_one_call_control(client):
    with Stubber(client) as stubber:
        stubber.add_response(
            "batch_get_item",
            RESPONSE_1,
            {"RequestItems": request_items(ORDER)},
        )
        rows = flawed_batch_get(client, TABLE, ORDER)

    returned = {row["pk"]["S"] for row in rows}
    assert returned == set(ORDER)  # deliberately false
This control was actually executed in the local environment recorded above. It failed because the returned membership was {'A','C'} while the manifest was {'A','B','C','D','Z'}. That is local Stubber evidence only. It proves the test can expose the bad acceptance rule; it does not claim DynamoDB itself produced this response in a live account.
The control also prevents a subtle testing mistake: asserting only len(rows) == 2 would merely restate the stub. The meaningful failure is that the caller asked for five key dispositions and the one-call helper returned a list that carries no evidence about B, D, or Z.
A short result is not an absence certificate
After response one, three requested keys are missing from the returned rows, but they do not have the same status. B and D are explicitly unprocessed, so their existence is unknown from this pass. Z is neither returned nor unprocessed, so it is processed-but-not-returned for this pass. AWS documents both halves of that distinction: partial success reports unread keys in UnprocessedKeys, while a requested item that does not exist is omitted from the result.
That is the core of the BatchGetItem missing items problem. “Not in Responses” is not one state. The correct state depends on whether the same key appears in UnprocessedKeys for the same request. Any helper that converts every missing row directly into None or “not found” before that reconciliation destroys evidence.
Implement a bounded UnprocessedKeys loop
The replacement helper below makes the evidence model explicit. It validates unique requested keys, establishes one absolute monotonic deadline, retries only the current UnprocessedKeys, retains prior classifications, records pass evidence, and returns a typed result instead of silently returning a partial list. Malformed response membership raises LedgerInvariantError; a request-level ClientError or BotoCoreError returns an incomplete result with the current pending keys preserved as unresolved.
from future import annotations

from dataclasses import dataclass
import random
import time
from typing import Any, Callable, Mapping, Sequence

from botocore.exceptions import BotoCoreError, ClientError

DDBItem = dict[str, dict[str, Any]]
DDBKey = dict[str, dict[str, str]]


class LedgerInvariantError(RuntimeError):
    """The response cannot be reconciled to the request manifest."""


@dataclass(frozen=True)
class PassEvidence:
    application_pass: int
    request_id: str | None
    requested: frozenset[str]
    returned: frozenset[str]
    unprocessed: frozenset[str]
    processed_not_returned: frozenset[str]
    duration_ms: float
    sdk_retry_attempts: int


@dataclass(frozen=True)
class KeyOutcome:
    pk: str
    disposition: str
    item: DDBItem | None


@dataclass(frozen=True)
class BatchReadResult:
    requested_order: tuple[str, ...]
    returned: frozenset[str]
    processed_not_returned: frozenset[str]
    unresolved: frozenset[str]
    items_by_key: Mapping[str, DDBItem]
    outcomes: tuple[KeyOutcome, ...]
    ledger: tuple[PassEvidence, ...]
    complete: bool
    terminal_error: str | None


def typed_key(pk: str) -> DDBKey:
    return {"pk": {"S": pk}}


def canonical_pk(key_or_item: Mapping[str, Any]) -> str:
    try:
        value = key_or_item["pk"]
    except KeyError as exc:
        raise LedgerInvariantError("response item/key is missing projected pk") from exc
    if not isinstance(value, Mapping) or set(value) != {"S"} or not isinstance(value["S"], str):
        raise LedgerInvariantError("pk must be a low-level DynamoDB string AttributeValue")
    return value["S"]


def requestitems(table_name: str, pks: Sequence[str], consistent_read: bool) -> dict:
    return {
        table_name: {
            "Keys": [typed_key(pk) for pk in pks],
            "ConsistentRead": consistent_read,
            "ProjectionExpression": "#pk, #v",
            "ExpressionAttributeNames": {"#pk": "pk", "#v": "value"},
        }
    }


def orderedsubset(
    original_order: Sequence[str],
    subset: set[str] | frozenset[str],
) -> list[str]:
    return [pk for pk in original_order if pk in subset]


def errortext(exc: BaseException) -> str:
    if isinstance(exc, ClientError):
        err = exc.response.get("Error", {})
        code = err.get("Code", type(exc).__name__)
        request_id = exc.response.get("ResponseMetadata", {}).get("RequestId")
        return f"{code}; request_id={request_id or 'unknown'}"
    return type(exc).__name__


def batch_get_reconciled(
    client: Any,
    ,
    table_name: str,
    requested_pks: Sequence[str],
    consistent_read: bool,
    max_passes: int = 3,
    timeout_s: float = 2.0,
    clock: Callable[[], float] = time.monotonic,
    sleep: Callable[[float], None] = time.sleep,
    jitter: Callable[[float, float], float] = random.uniform,
    backoff_base_s: float = 0.05,
    backoff_cap_s: float = 1.0,
) -> BatchReadResult:
    order = tuple(requested_pks)
    if not order:
        return BatchReadResult(
            (),
            frozenset(),
            frozenset(),
            frozenset(),
            {},
            (),
            (),
            True,
            None,
        )
    if len(set(order)) != len(order):
        raise ValueError("requested_pks contains duplicate keys")
    if max_passes < 1:
        raise ValueError("max_passes must be >= 1")
    if timeout_s <= 0:
        raise ValueError("timeout_s must be > 0")

    manifest = frozenset(order)
    pending = set(order)
    returned: set[str] = set()
    absent: set[str] = set()
    items_by_key: dict[str, DDBItem] = {}
    ledger: list[PassEvidence] = []
    terminal_error: str | None = None
    deadline = clock() + timeout_s

    for app_pass in range(1, max_passes + 1):
        if not pending or clock() >= deadline:
            break

        current_order = orderedsubset(order, pending)
        current = set(current_order)
        params = {
            "RequestItems": requestitems(
                table_name,
                current_order,
                consistent_read,
            )
        }

        call_started = clock()
        try:
            response = client.batch_get_item(*params)
        except (ClientError, BotoCoreError) as exc:
            terminal_error = errortext(exc)
            break
        duration_ms = (clock() - call_started) 1000.0

        response_items = response.get("Responses", {}).get(table_name, [])
        current_returned: set[str] = set()

        for item in response_items:
            pk = canonical_pk(item)

            if pk not in manifest or pk not in current:
                raise LedgerInvariantError(
                    f"response returned key outside current request: {pk}"
                )

            if pk in current_returned:
                if items_by_key.get(pk) not in (None, item):
                    raise LedgerInvariantError(
                        f"conflicting repeat observations for key: {pk}"
                    )
                raise LedgerInvariantError(
                    f"duplicate response item for key: {pk}"
                )

            if pk in absent:
                raise LedgerInvariantError(
                    f"key previously classified absent was later returned: {pk}"
                )

            if pk in items_by_key and items_by_key[pk] != item:
                raise LedgerInvariantError(
                    f"conflicting repeat observations for key: {pk}"
                )

            current_returned.add(pk)
            items_by_key[pk] = item

        raw_unprocessed = (
            response.get("UnprocessedKeys", {})
            .get(table_name, {})
            .get("Keys", [])
        )

        current_unprocessed: set[str] = set()

        for key in raw_unprocessed:
            pk = canonical_pk(key)

            if pk not in current:
                raise LedgerInvariantError(
                    f"UnprocessedKeys contains key outside current request: {pk}"
                )

            if pk in current_unprocessed:
                raise LedgerInvariantError(
                    f"duplicate UnprocessedKeys entry: {pk}"
                )

            current_unprocessed.add(pk)

        overlap = current_returned & current_unprocessed
        if overlap:
            raise LedgerInvariantError(
                f"key both returned and unprocessed: {sorted(overlap)}"
            )

        current_absent = current - current_returned - current_unprocessed

        returned.update(current_returned)
        absent.update(current_absent)
        pending = set(current_unprocessed)

        meta = response.get("ResponseMetadata", {})
        ledger.append(
            PassEvidence(
                application_pass=app_pass,
                request_id=meta.get("RequestId"),
                requested=frozenset(current),
                returned=frozenset(current_returned),
                unprocessed=frozenset(current_unprocessed),
                processed_not_returned=frozenset(current_absent),
                duration_ms=duration_ms,
                sdk_retry_attempts=int(meta.get("RetryAttempts", 0)),
            )
        )

        if not pending or app_pass == max_passes:
            break

        upper = min(
            backoff_cap_s,
            backoff_base_s (2 ** (app_pass - 1)),
        )
        delay = max(0.0, jitter(0.0, upper))
        now = clock()

        if now + delay >= deadline:
            break

        sleep(delay)

    if (
        (returned & absent)
        or (returned & pending)
        or (absent & pending)
    ):
        raise LedgerInvariantError(
            "final disposition sets are not disjoint"
        )

    if returned | absent | pending != manifest:
        raise LedgerInvariantError(
            "final disposition sets do not cover the request manifest"
        )

    outcomes = tuple(
        KeyOutcome(
            pk=pk,
            disposition=(
                "returned"
                if pk in returned
                else "processed_not_returned"
                if pk in absent
                else "unresolved"
            ),
            item=items_by_key.get(pk),
        )
        for pk in order
    )

    return BatchReadResult(
        order,
        frozenset(returned),
        frozenset(absent),
        frozenset(pending),
        dict(items_by_key),
        outcomes,
        tuple(ledger),
        complete=not pending and terminal_error is None,
        terminal_error=terminal_error,
    )
AWS’s DynamoDB error-handling guide recommends retrying unprocessed batch members with exponential backoff. It also distinguishes batch partial processing from whole-request failures and notes that low-level clients may require application retry logic for unprocessed items. The helper adds jitter because production clients can collide; the test injects deterministic jitter and sleep.
Keep SDK retries separate from application passes
Two counters answer different questions. ResponseMetadata.RetryAttempts is Botocore’s retry count for the single low-level API call; AWS documents that field as a way to inspect client retries. application_pass counts successful BatchGetItem responses followed by explicit retries of UnprocessedKeys.
That distinction prevents accidental retry multiplication from being invisible. With total_max_attempts=3 and max_passes=3, each application pass may itself contain SDK-level retry activity before returning or raising. A production deadline must bound the combined effect. The helper never resets its monotonic deadline after a successful pass.
Do not infer that every higher-level SDK abstraction behaves like this helper. AWS documents some higher-level retry automation, but this article deliberately uses the Python low-level client and implements the UnprocessedKeys loop explicitly.
Prove completion without relying on response order
The corrected test queues three Stubber responses and asserts the request parameters for each pass. Botocore’s Stubber reference states that queued responses are returned in order and that expected_params are checked against the client call; a mismatch raises a stub response error. This makes the fixture useful for deterministic client-contract testing.
The essential test is:
def test_completes_reconciles_absence_and_restores_requested_order(client):
    with Stubber(client) as stubber:
        add_canonical(stubber)
        result = batch_get_reconciled(
            client,
            table_name=TABLE,
            requested_pks=ORDER,
            consistent_read=True,
            max_passes=3,
            timeout_s=5.0,
            sleep=lambda : None,
            jitter=lambda lo, hi: 0.0,
        )
        stubber.assertno_pending_responses()

    assert result.complete is True
    assert result.returned == {"A", "B", "C", "D"}
    assert result.processed_not_returned == {"Z"}
    assert result.unresolved == set()
    assert [o.pk for o in result.outcomes] == ORDER
    assert [o.disposition for o in result.outcomes] == [
        "returned",
        "returned",
        "returned",
        "returned",
        "processed_not_returned",
    ]
    assert {
        pk: result.items_by_key[pk]["value"]["N"]
        for pk in result.returned
    } == {
        "A": "10",
        "B": "20",
        "C": "30",
        "D": "40",
    }
The response order is intentionally different from caller order: the first response is C,A, not A,C, and later responses return B and D. The helper never positional-zips rows to requested keys. It indexes by the projected primary key and emits outcomes in the original request order. AWS explicitly says response item order is not guaranteed.
The terminal result contains four items for five requested keys, yet it is complete because every key has a disposition. Z receives processed_not_returned, represented deliberately rather than as a shifted list position. That is the corrected comparison: zero unresolved keys and four returned rows are simultaneously true.
The canonical corrected suite was actually executed locally with the environment manifest above. Excluding the deliberately failing control, pytest reported 9 passed, 1 deselected. The executed publication helper identity was SHA-256 e2e5cc4285baac9207ab30a3cb17c41df5fffbc8e769da8160fbbb5190b2bf2d; the test fixture identity was SHA-256 046ec59d8af3df5017818119a10d86a2ff11984ef9b37674a21c29926e0bd929. Those hashes identify this local evidence; they are not a release artifact or a production certification.
Test exhaustion and request-level failures
A bounded recovery path needs tests for what happens when completion does not occur. First, stop the canonical sequence after response two by setting max_passes=2. At that point the correct terminal sets are returned={A,B,C}, processed-not-returned={Z}, and unresolved={D}. D cannot be called absent because the last usable response explicitly placed it in UnprocessedKeys.
Second, inject a request-level exception before any usable response. Stubber.add_client_error can model a ProvisionedThroughputExceededException locally. The expected result is not “all keys missing”; it is unresolved=Q, because no response classified any key. AWS’s error guide distinguishes whole-request failures from partial batch processing; unread members can be reconciled only when a usable batch response exists.
Third, test a nonshrinking pending set. Two successful responses can each return no items and report UnprocessedKeys={A}. That is not an invariant violation by itself. The helper makes two bounded passes, then returns A unresolved. A retry loop that waits for the set to shrink before counting an attempt can spin forever.
Fourth, test the absolute deadline independently of pass count. With a fake clock, a 50 ms deadline, and an injected backoff delay that would start beyond that deadline, the helper stops after the current usable response and preserves the pending key. Clock, sleep and jitter are injected specifically so this branch is deterministic.
A compact deadline test is:
@dataclass
class FakeClock:
    now: float = 0.0

    def call(self) -> float:
        return self.now

    def sleep(self, seconds: float) -> None:
        self.now += seconds


def test_deadline_can_stop_before_another_pass(client):
    clock = FakeClock()

    with Stubber(client) as stubber:
        stubber.add_response(
            "batch_get_item",
            ok("req-1", [], ["A"]),
            {"RequestItems": request_items(["A"])},
        )

        result = batch_get_reconciled(
            client,
            table_name=TABLE,
            requested_pks=["A"],
            consistent_read=True,
            max_passes=5,
            timeout_s=0.05,
            clock=clock,
            sleep=clock.sleep,
            jitter=lambda lo, hi: hi,
            backoffbase_s=0.1,
        )

    assert result.complete is False
    assert result.unresolved == {"A"}
For a complete reproduction, save the helper listing as batch_read.py and the following executed fixture as test_batch_read.py. The control test is intentionally red; the corrected suite is selected separately so a broken control cannot be mistaken for a release failure. The expected-parameter assertions also verify that retries preserve table name, projection, consistency mode and the shrinking key subset.
from future import annotations

from dataclasses import dataclass

import boto3
import pytest
from botocore.config import Config
from botocore.stub import Stubber

from batch_read import (
    LedgerInvariantError,
    batch_get_reconciled,
    typed_key,
)

TABLE = "KnownAnswer"
ORDER = ["A", "B", "C", "D", "Z"]
EXPECTED_VALUES = {
    "A": "10",
    "B": "20",
    "C": "30",
    "D": "40",
}


def item(pk: str, n: int) -> dict:
    return {
        "pk": {"S": pk},
        "value": {"N": str(n)},
    }


def request_items(
    keys: list[str],
    consistent: bool = True,
) -> dict:
    return {
        TABLE: {
            "Keys": [typed_key(pk) for pk in keys],
            "ConsistentRead": consistent,
            "ProjectionExpression": "#pk, #v",
            "ExpressionAttributeNames": {
                "#pk": "pk",
                "#v": "value",
            },
        }
    }


def ok(
    request_id: str,
    items: list[dict],
    unprocessed: list[str],
) -> dict:
    body = {
        "Responses": {TABLE: items},
        "UnprocessedKeys": {},
        "ResponseMetadata": {
            "RequestId": request_id,
            "HTTPStatusCode": 200,
            "HTTPHeaders": {},
            "RetryAttempts": 0,
        },
    }

    if unprocessed:
        body["UnprocessedKeys"] = {
            TABLE: {
                "Keys": [
                    typed_key(pk)
                    for pk in unprocessed
                ]
            }
        }

    return body


@pytest.fixture
def client():
    return boto3.client(
        "dynamodb",
        region_name="us-east-1",
        aws_access_key_id="stub-access-key",
        aws_secret_access_key="stub-secret-key",
        config=Config(
            retries={
                "mode": "standard",
                "total_max_attempts": 3,
            }
        ),
    )


def add_canonical(
    stubber: Stubber,
    stop_after: int = 3,
) -> None:
    responses = [
        (
            ORDER,
            ok(
                "req-1",
                [item("C", 30), item("A", 10)],
                ["B", "D"],
            ),
        ),
        (
            ["B", "D"],
            ok(
                "req-2",
                [item("B", 20)],
                ["D"],
            ),
        ),
        (
            ["D"],
            ok(
                "req-3",
                [item("D", 40)],
                [],
            ),
        ),
    ]

    for keys, response in responses[:stop_after]:
        stubber.add_response(
            "batch_get_item",
            response,
            {
                "RequestItems":
                    request_items(keys)
            },
        )


def test_intentionally_failing_one_call_control(client):
    with Stubber(client) as stubber:
        stubber.add_response(
            "batch_get_item",
            ok(
                "req-1",
                [item("C", 30), item("A", 10)],
                ["B", "D"],
            ),
            {
                "RequestItems":
                    request_items(ORDER)
            },
        )

        response = client.batch_get_item(
            RequestItems=request_items(ORDER)
        )

    returned = {
        x["pk"]["S"]
        for x in response["Responses"][TABLE]
    }

    # Deliberately wrong acceptance rule.
    assert returned == set(ORDER)


def test_completes_reconciles_absence_and_restores_requested_order(client):
    with Stubber(client) as stubber:
        add_canonical(stubber)

        result = batch_get_reconciled(
            client,
            table_name=TABLE,
            requested_pks=ORDER,
            consistent_read=True,
            max_passes=3,
            timeout_s=5.0,
            sleep=lambda : None,
            jitter=lambda lo, hi: 0.0,
        )

        stubber.assertno_pending_responses()

    assert result.complete is True
    assert result.returned == {
        "A",
        "B",
        "C",
        "D",
    }
    assert result.processed_not_returned == {
        "Z"
    }
    assert result.unresolved == set()

    assert [o.pk for o in result.outcomes] == ORDER

    assert [
        o.disposition
        for o in result.outcomes
    ] == [
        "returned",
        "returned",
        "returned",
        "returned",
        "processed_not_returned",
    ]

    assert {
        pk: result.items_by_key[pk]["value"]["N"]
        for pk in result.returned
    } == EXPECTED_VALUES

    assert result.ledger[0].requested == set(
        ORDER
    )
    assert result.ledger[0].returned == {
        "A",
        "C",
    }
    assert result.ledger[0].unprocessed == {
        "B",
        "D",
    }
    assert (
        result.ledger[0].processed_not_returned
        == {"Z"}
    )

    assert result.ledger[1].requested == {
        "B",
        "D",
    }
    assert (
        result.ledger[1].processed_not_returned
        == set()
    )

    assert result.ledger[2].requested == {
        "D"
    }


def test_exhaustion_after_two_successful_passes_keeps_d_unresolved(client):
    with Stubber(client) as stubber:
        add_canonical(
            stubber,
            stop_after=2,
        )

        result = batch_get_reconciled(
            client,
            table_name=TABLE,
            requested_pks=ORDER,
            consistent_read=True,
            max_passes=2,
            timeout_s=5.0,
            sleep=lambda : None,
            jitter=lambda : 0.0,
        )

    assert result.complete is False
    assert result.returned == {
        "A",
        "B",
        "C",
    }
    assert result.processed_not_returned == {
        "Z"
    }
    assert result.unresolved == {
        "D"
    }


def test_duplicate_requested_key_is_rejected_before_api_call(client):
    with Stubber(client):
        with pytest.raises(
            ValueError,
            match="duplicate",
        ):
            batch_get_reconciled(
                client,
                table_name=TABLE,
                requested_pks=["A", "A"],
                consistent_read=True,
            )


def test_missing_projected_pk_is_rejected(client):
    bad = ok(
        "req-bad",
        [{"value": {"N": "10"}}],
        [],
    )

    with Stubber(client) as stubber:
        stubber.add_response(
            "batch_get_item",
            bad,
            {
                "RequestItems":
                    request_items(["A"])
            },
        )

        with pytest.raises(
            LedgerInvariantError,
            match="missing projected pk",
        ):
            batch_get_reconciled(
                client,
                table_name=TABLE,
                requested_pks=["A"],
                consistent_read=True,
            )


def test_out_of_request_response_key_is_rejected(client):
    bad = ok(
        "req-bad",
        [item("X", 99)],
        [],
    )

    with Stubber(client) as stubber:
        stubber.add_response(
            "batch_get_item",
            bad,
            {
                "RequestItems":
                    request_items(["A"])
            },
        )

        with pytest.raises(
            LedgerInvariantError,
            match="outside current request",
        ):
            batch_get_reconciled(
                client,
                table_name=TABLE,
                requested_pks=["A"],
                consistent_read=True,
            )


def test_conflicting_repeat_observations_are_rejected(client):
    bad = ok(
        "req-bad",
        [
            item("A", 10),
            item("A", 11),
        ],
        [],
    )

    with Stubber(client) as stubber:
        stubber.add_response(
            "batch_get_item",
            bad,
            {
                "RequestItems":
                    request_items(["A"])
            },
        )

        with pytest.raises(
            LedgerInvariantError,
            match="conflicting repeat",
        ):
            batch_get_reconciled(
                client,
                table_name=TABLE,
                requested_pks=["A"],
                consistent_read=True,
            )


def test_request_level_exception_keeps_current_pending_unresolved(client):
    with Stubber(client) as stubber:
        stubber.add_client_error(
            "batch_get_item",
            service_error_code=(
                "ProvisionedThroughputExceededException"
            ),
            service_message=(
                "synthetic request-level failure"
            ),
            http_status_code=400,
            expected_params={
                "RequestItems":
                    request_items(ORDER)
            },
            response_meta={
                "RequestId":
                    "req-error"
            },
        )

        result = batch_get_reconciled(
            client,
            table_name=TABLE,
            requested_pks=ORDER,
            consistent_read=True,
            max_passes=3,
            timeout_s=5.0,
        )

    assert result.complete is False
    assert result.returned == set()
    assert result.processed_not_returned == set()
    assert result.unresolved == set(ORDER)

    assert result.terminal_error
    assert (
        "ProvisionedThroughputExceededException"
        in result.terminal_error
    )


def test_nonshrinking_pending_stops_at_pass_bound(client):
    first = ok(
        "req-1",
        [],
        ["A"],
    )
    second = ok(
        "req-2",
        [],
        ["A"],
    )

    with Stubber(client) as stubber:
        stubber.add_response(
            "batch_get_item",
            first,
            {
                "RequestItems":
                    request_items(["A"])
            },
        )
        stubber.add_response(
            "batch_get_item",
            second,
            {
                "RequestItems":
                    request_items(["A"])
            },
        )

        result = batch_get_reconciled(
            client,
            table_name=TABLE,
            requested_pks=["A"],
            consistent_read=True,
            max_passes=2,
            timeout_s=5.0,
            sleep=lambda : None,
            jitter=lambda : 0.0,
        )

    assert result.complete is False
    assert result.unresolved == {
        "A"
    }
    assert len(result.ledger) == 2


@dataclass
class FakeClock:
    now: float = 0.0

    def call(self) -> float:
        return self.now

    def sleep(
        self,
        seconds: float,
    ) -> None:
        self.now += seconds


def test_deadline_can_stop_before_another_pass(client):
    clock = FakeClock()

    first = ok(
        "req-1",
        [],
        ["A"],
    )

    with Stubber(client) as stubber:
        stubber.add_response(
            "batch_get_item",
            first,
            {
                "RequestItems":
                    request_items(["A"])
            },
        )

        result = batch_get_reconciled(
            client,
            table_name=TABLE,
            requested_pks=["A"],
            consistent_read=True,
            max_passes=5,
            timeout_s=0.05,
            clock=clock,
            sleep=clock.sleep,
            jitter=lambda lo, hi: hi,
            backoffbase_s=0.1,
        )

    assert result.complete is False
    assert result.unresolved == {
        "A"
    }
    assert len(result.ledger) == 1
Run the evidence in two steps:
python -m pytest -q -k 'not intentionally_failing_one_call_control'
python -m pytest -q test_batch_read.py::test_intentionally_failing_one_call_control
In the recorded local environment, the first command produced nine passing tests with one deselected control; the second produced the intended assertion failure because only A and C were returned by the first synthetic response. The test file itself does not contact AWS because every DynamoDB call is under Stubber.
Preserve uncertainty when evidence stops
The resume record for a held read should contain the original manifest and order, completed returned items or their immutable references, processed-not-returned keys, current unresolved keys, consistency mode, table/schema revision, helper version, application pass count, deadline outcome and request identifiers. It should not contain credentials or unnecessary business payloads.
A continuation can safely retry the unresolved subset as a new bounded observation, but it cannot retroactively prove that earlier item values remained unchanged while the continuation occurred. Even a strongly consistent per-item read does not turn multiple reads at different times into a multi-item snapshot. The read-consistency documentation says strongly consistent reads reflect prior successful updates for the item being read, while read-committed isolation does not prevent later modification.
Reject malformed keys and untraceable projections
A reliable helper must reject evidence it cannot reconcile. Four negative cases deserve explicit tests.
A duplicate requested key is an input defect. AWS states that BatchGetItem returns a ValidationException if the same key is specified multiple times. The helper rejects duplicates before the API call so the caller gets a deterministic repair signal and the ledger still has a set-like manifest.
An item missing projected pk is an internal contract defect. Because the response is unordered, an unkeyed item cannot be tied to the manifest. The helper raises LedgerInvariantError("response item/key is missing projected pk"). The repair belongs with the client owner: restore the key to the projection and add a regression test.
A response item whose key is outside the current requested subset is also rejected. Even if that key appeared in the original manifest on an earlier pass, a later response returning it when it was not requested would make pass-level reconciliation ambiguous. The client must never silently merge such a row.
Conflicting repeat observations are rejected rather than “last write wins.” In the negative fixture, one response contains two items with pk=A and different values. That shape is synthetic, but it tests the helper’s internal invariant: one requested key cannot produce two conflicting accepted values in one evidence pass. A repeated identical row is also rejected as duplicate evidence, because the API contract does not require the caller to invent a deduplication rule for malformed responses.
These cases divide cleanly by ownership. Duplicate input is application repair before invocation. Missing pk, out-of-request membership, overlapping returned/unprocessed sets, and conflicting repeats are client-helper repair or an escalation if observed from a real service response. They should not be converted to ordinary unresolved states, because doing so would hide an inconsistent ledger rather than preserve uncertainty.
Capture the response and reconciliation ledger
The ledger should be compact enough to log and complete enough to audit. For each usable pass, record the application pass number, request ID, current requested set, returned set, unprocessed set, processed-not-returned set, call duration, and SDK retry count. Do not log credentials, full item payloads, or sensitive key values if those keys are business data; production systems can hash or tokenize keys while retaining a secure correlation path.
For the canonical fixture, the expected reconciliation ledger is:
Pass | Request ID | Requested | Returned | Unprocessed | Processed-not-returned | SDK retries |
1 | req-1 | A,B,C,D,Z | A,C | B,D | Z | 0 |
2 | req-2 | B,D | B | D | ∅ | 0 |
3 | req-3 | D | D | ∅ | ∅ | 0 |
The table is an expected fixture trace whose membership was also asserted in the executed local Stubber tests. The request IDs, HTTP status values and retry counts are synthetic fixture values. No service endpoint supplied them.
Keep four evidence labels visible in review notes. Documented behavior comes from the DynamoDB or Botocore specification and guide pages: partial responses, unordered items, omitted nonexistent items, UnprocessedKeys, retry configuration and Stubber parameter validation. Mathematically expected result comes from the frozen manifest and the set equation; for example, pass one necessarily classifies only Z as processed-not-returned. Synthetic/stubbed response describes the three queued dictionaries and every request ID inside them. Actually observed output is limited to the local Python process: the corrected tests passed and the control failed as described. This vocabulary prevents a common evidence upgrade in which a deterministic unit test is retold later as though an AWS service endpoint had been throttled and recovered.
A review artifact should also state what would falsify approval. Examples include a request shape that drops ConsistentRead, a retry that sends already classified keys, an output adapter that discards unresolved, or any live response whose membership cannot satisfy the disjoint-set invariant. Those are stronger stop signals than a dashboard showing a green HTTP-success rate, because they test the actual acceptance contract.
General monitoring and logging evidence can help operators correlate client failures and service symptoms, but dashboards do not prove per-key completeness by themselves. The proof lives in the request manifest and the reconciliation ledger.
A useful production event can therefore be smaller than the rows themselves: helper revision, table alias, consistency mode, manifest cardinality, hashes of membership sets, pass count, deadline outcome, request IDs, SDK retry counts and final decision. That supports incident reconstruction without turning logs into a second copy of the database.
Use stubs as client evidence, not service evidence
Botocore Stubber validates the client call against queued expected parameters and returns the queued response without calling DynamoDB. That makes it strong evidence for client logic: request shaping, pass ordering, key reconciliation, stop conditions and malformed-response handling.
It is not evidence that real throttling occurs at a particular rate, that a specific partition will produce the same partial pattern, or that backoff timings have a measured production effect. The API documentation establishes that partial results and UnprocessedKeys are supported behavior; the stubbed experiment demonstrates how this helper reacts to that documented shape. Those are different claims.
An optional live smoke test should verify only integration: credentials resolve, the owned table schema matches, projected attributes are readable, consistency mode is accepted, and returned request metadata can be captured. It should remain small and should not attempt to manufacture pressure.
Check what read consistency does not settle
The known-answer laboratory sets ConsistentRead=True and forbids concurrent mutation so that response membership can be compared with a frozen fixture. That is an experiment design choice, not a statement that strong consistency makes BatchGetItem atomic across keys.
AWS’s DynamoDB read-consistency guide says eventually consistent reads are the default and may not reflect a recently completed write; strongly consistent reads on supported resources return the most up-to-date item state with respect to prior successful writes. It also states that read-committed isolation does not prevent an item from being modified immediately after a read.
Therefore, a completed ledger establishes what this bounded sequence observed under its stated consistency mode. It does not establish a multi-item snapshot, a simultaneous point in time, or permanent nonexistence. In a mutable application, key A can be read on pass one and key D on pass three after A has changed. Both reads can be individually valid while the assembled dictionary never existed as one atomic database state.
Eventual consistency adds another limit. A processed-but-not-returned key can mean “no item visible to this read” rather than “this key has never existed” or “it will remain absent.” The caller must state whether that observation is sufficient for its business contract. If the application requires snapshot semantics or transactional coupling, this helper is the wrong primitive; that question is outside this article’s scope.
The acceptance test stays narrow: one table, one Region, string partition key pk, no concurrent mutation, and no claim about global tables, transactions, pagination, Query, Scan, write batches, queue acknowledgements or performance.
Recover without losing the original request contract
Recovery starts from the original manifest, not from the number of rows accumulated so far. Preserve Q, original order, all accepted returned values, the processed-not-returned set, and the current unresolved subset. A continuation request contains only unresolved keys, but it remains traceable to the original evidence record.
There are two legitimate recovery modes. Continue the same bounded observation only while the original helper invocation is still within its pass and deadline limits. Start a new labeled read after those bounds are exhausted or after control returns to a caller. The second mode may reuse unresolved keys, but it needs a new observation identifier and new timing context. Do not splice the later values into the earlier result and relabel the combination as a snapshot.
This discipline mirrors a broader principle in cloud-native pipeline design: component boundaries need explicit state and recovery contracts. Here the state is much smaller than a pipeline checkpoint, but the same operational rule applies: resume from preserved evidence rather than reconstructing intent from partial output.
A safe hold record should answer: what was originally requested; what is already returned; what was processed without a row; what remains unresolved; why the helper stopped; which consistency mode was used; which helper and fixture revisions produced the record; and which request IDs are available for support correlation.
What it must not claim is equally important. It does not prove unchanged data between passes, it does not authorize unlimited retries, and it does not transform an exception into “not found.” Bounded recovery preserves uncertainty until new evidence resolves it.
Roll out the helper behind a reversible boundary
Adoption should be reversible at the caller boundary. Keep the old and new helpers behind the same feature switch or dependency interface, but do not preserve the old helper’s unsafe semantics. The reversible boundary should let the system fall back to a conservative failure mode, not back to silently accepting partial lists.
Before enabling authoritative use, compare old and new behavior on inert fixtures and, where permitted, mirrored or authorized low-risk traffic. Compare requested key membership, returned key membership, unresolved membership, required-item policy outcome and exception behavior. Do not compare only row counts. The new helper’s added information is exactly what the old interface may have discarded.
For a compatibility period, callers that previously expected a list can receive an adapter only when result.complete is true and the caller’s missing-item policy passes. Otherwise the adapter should raise or return a typed failure. This makes incompleteness visible rather than smuggling the old defect through a new implementation.
Rollback criteria should be operationally explicit: unexpected invariant failures on well-formed responses, unacceptable caller incompatibility, evidence that request shaping changed table/consistency/projection settings, or a dependency regression. The client-reliability owner controls helper rollback; the application owner controls whether traffic can safely fall back to a conservative error response; a service owner or AWS support path is engaged only if captured real responses appear to violate the documented API contract.
Version the result contract and its tests
Store the result schema, helper revision, fixture revision, dependency lock, table/key schema, consistency policy, and caller acceptance policy together. A code rollback without its matching tests can reintroduce exactly the ambiguity this playbook removes.
The evidence identity for the local run in this article is intentionally concrete: Python 3.13.5; boto3/botocore 1.43.18; pytest 9.0.2; helper and fixture revision r1; plus the two SHA-256 source identities recorded earlier. A production repository should generate the equivalent manifest in continuous integration rather than copy these numbers.
Reverting code also cannot repair an already accepted incomplete read. If an old helper allowed business actions based on unresolved keys, rollback stops new exposure but does not reconstruct the missing historical evidence. Those prior decisions need application-level review according to their business impact.
Apply the accept, retry, hold and repair matrix
A keyed-read helper is ready only when each fixture has an owner and a next action. The matrix below treats acceptance as a property of the ledger plus caller policy, not of HTTP status.
Evidence state | Decision | Accountable owner | Next action |
Canonical pass 1: returned A,C; unprocessed B,D; processed-not-returned Z | Retry | Client reliability | Retry only B,D within existing pass/deadline budget; retain A,C,Z classifications |
Canonical pass 2: returned B; unprocessed D | Retry | Client reliability | Retry only D; do not reread A,B,C,Z inside this observation |
Canonical pass 3: returned D; no unprocessed; final returned A-D, processed-not-returned Z | Accept if caller permits Z absent | Application owner | Consume ordered outcomes; record complete ledger |
Exhaustion after pass 2: D unresolved | Hold | Application owner with client reliability | Return incomplete typed result or fail request; persist D as unresolved for a new labeled read if policy allows |
Request-level exception before usable response | Hold | Client reliability | Preserve all current pending keys unresolved; use SDK/request error policy, then start a new bounded observation if authorized |
Nonshrinking UnprocessedKeys until pass bound | Hold | Client reliability | Stop at bound; inspect throttling/capacity context if live; never spin indefinitely |
Deadline would expire before next pass | Hold | Application owner | Stop without resetting deadline; propagate unresolved keys |
Duplicate requested key | Repair | Application owner | Deduplicate only if business semantics permit; otherwise fix caller input |
Response item lacks pk | Repair | Client reliability | Restore primary key projection; reject untraceable result |
Response key outside current request, overlap with unprocessed, or conflicting repeat | Repair / escalate | Client reliability; service owner if live evidence persists | Reject ledger, retain request ID, reproduce with minimal authorized case, compare installed SDK and current API docs |
Empty Responses, empty UnprocessedKeys, all requested keys reconciled as processed-not-returned | Accept only if absence is allowed | Application owner | Treat as a complete read of absent/not-visible keys under the stated consistency contract, not proof they never existed |
Three acceptance conditions are non-negotiable. First, the final membership sets must be legal and cover the original manifest. Second, unresolved must be empty for a complete result. Third, the application must apply its required-item policy: a caller that requires A-D can accept this fixture even though Z is absent; a caller that requires all five items must reject it despite complete read coverage.
That last distinction is where partial read acceptance criteria become useful. Client completeness answers “did every key receive a disposition?” Application completeness answers “are those dispositions acceptable for this operation?” Conflating the two either rejects legitimate absent-key reads or accepts unresolved ones.
The same separation belongs at an API boundary. Backend API contract foundations provide the wider context for explicit response semantics; this helper contributes a precise internal state that an API can map to its own success, not-found, retryable or dependency-failure contract.
For service-side investigation, retain AWS request identifiers and the exact installed client versions. Do not log credentials or sensitive payloads. If a live response appears inconsistent with the current AWS specification, hold acceptance, preserve the raw minimally necessary response evidence, and escalate rather than “repairing” the fixture to make the test pass.
Build the cloud-development discipline behind the fix
The reusable review checklist is short. Freeze an independent key manifest. Preserve the primary key in the projection. Reconcile returned, processed-not-returned and unresolved membership per pass. Retry only UnprocessedKeys. Bound both SDK attempts and application passes with one monotonic deadline. Inject timing and jitter for deterministic tests. Reject impossible ledgers. Preserve request identifiers. Keep caller absence policy separate from client completeness. Treat stubs as client evidence, not AWS pressure evidence. For a live smoke test, record account, Region and consistency mode, and keep the test intentionally small.
The broader engineering skill is not “retry DynamoDB until it works.” It is designing a cloud client whose result type preserves uncertainty and whose recovery path has explicit stop conditions. That discipline transfers to many service integrations without pretending they share the same API semantics.
Refonte Learning’s Cloud Development page lists a three-month program at 12–15 hours per week and covers broader foundations such as building and deploying cloud applications, cloud architecture, containerization/orchestration, CI/CD, security and monitoring. The page also says no prior experience is required and basic programming knowledge is beneficial, while a separate admission-prerequisites section requires applicants to be working toward a bachelor’s or higher-level degree; prospective learners should read both conditions together. It advertises projects, seasoned guidance and a potential internship, not a guaranteed placement.
Those foundations are relevant to operational review, deployment and observability around a helper like this, but the program page does not establish that DynamoDB, boto3, Botocore Stubber, or this specific BatchGetItem reconciliation lab is taught. The specialist mechanism in this playbook therefore stands on its own: approve the helper only when every requested key has evidence, every unresolved key remains visible, and every recovery path stops before uncertainty is mistaken for success.