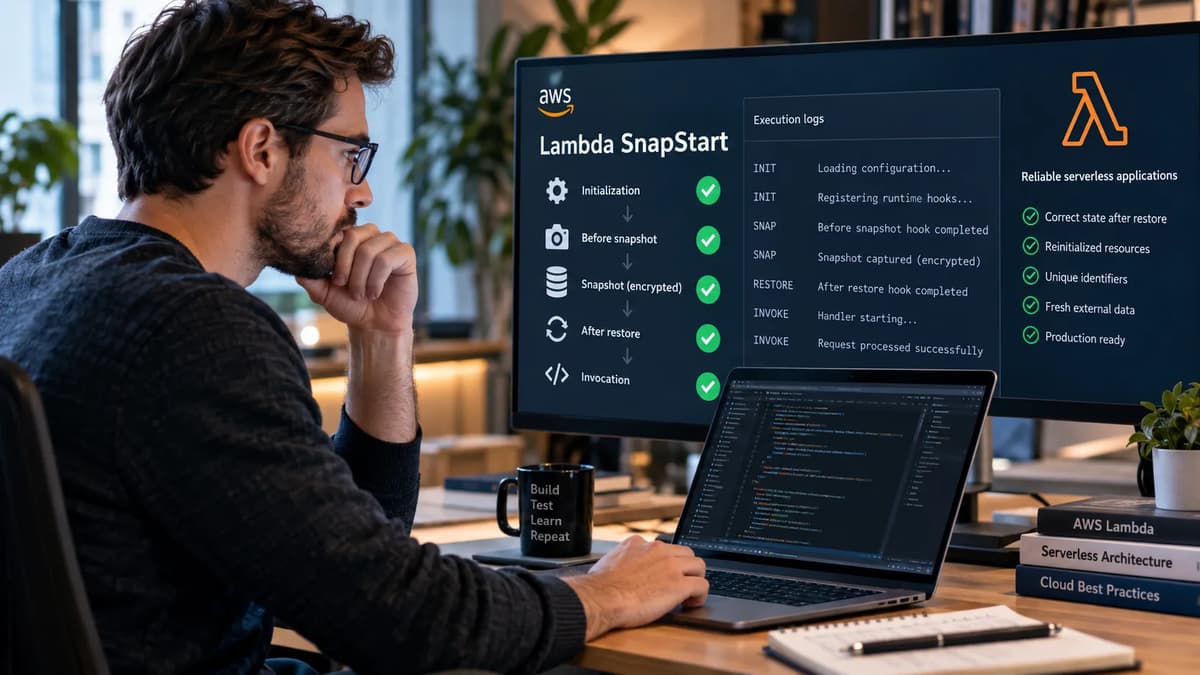
AWS Lambda SnapStart changes a lifecycle assumption that is easy to miss in code review: initialization is no longer necessarily followed by one execution environment continuing from that initialization. Lambda can initialize a published version, capture its memory and disk state, then resume multiple execution environments from that same snapshot as invocations scale. State that looked private to one process at initialization can therefore become cloned state.
That distinction is operationally more important than another cold-start comparison. The acceptance question is not “Did SnapStart make startup faster?” It is: After restore, is every piece of state either intentionally reusable or demonstrably reinitialized before the handler depends on it?
AWS explicitly calls out unique IDs, secrets, pseudorandom state, network connections, temporary credentials, and cached timestamps as categories that can require post-initialization treatment. AWS Lambda SnapStart runtime hooks provide defined points before the snapshot and after restore for that work. For Python, the managed runtime exposes register_before_snapshot and register_after_restore; the after-restore work occurs before the handler and must fit inside the Restore-phase time limit.
This article therefore treats restore correctness as an evidence problem. The proposed lab uses only synthetic data: one disposable Lambda function, one disposable DynamoDB ledger, a mutable synthetic “external epoch,” and an intentionally unsafe deterministic identifier generator. No experiment described here is presented as executed, and there are no invented measurements or observations.
For broader context, Refonte Learning’s secure and scalable API design article covers monitoring, scaling, versioning, CI/CD, and rollback concepts. Its cloud database administration article addresses HA, DR, and multi-cloud database design.
Related Refonte Learning articles cover System Design for AI-Powered Features and Infrastructure From Code. This article stays focused on lifecycle correctness after a SnapStart restore.
Scope and acceptance target
The scope is deliberately narrower than “testing SnapStart.” AWS documents that SnapStart initializes a function when a version is published, captures an encrypted snapshot of the initialized execution environment, and later resumes environments from that cached state. It also documents that one snapshot can seed multiple execution environments. SnapStart applies to published versions rather than $LATEST.
The engineering target follows from those facts: classify every initialized value according to whether cloning it is acceptable. Immutable configuration can be safe to preserve. A cached representation of an external value can already be stale when restore occurs. A counter, execution-environment identifier, seed, or other uniqueness-sensitive value can become unsafe precisely because every restored environment begins from the same captured state. AWS specifically requires applications that depend on uniqueness to evaluate their state for snapshot resilience.
There is also a second freshness boundary. An after-restore hook runs when an environment is restored, not before every later invocation. Consequently, a value that must be fresh for every request cannot become correct merely because it was refreshed once after restore. AWS separately advises refreshing ephemeral data such as temporary credentials or cached timestamps in the handler before use.
The acceptance target is therefore not simply “hook ran.” It is “hook ran at the correct lifecycle boundary and produced the required state before the first handler, while state needing per-request freshness still has a separate refresh policy.”
State under test | Safe acceptance condition | Unsafe evidence |
Immutable application configuration | Same expected digest before snapshot, after restore, and during invocation | Digest changes unexpectedly or depends on external mutable data |
Cached external state | Restored environment observes the post-snapshot control value before relying on it | Handler still sees the value captured during initialization |
Uniqueness-sensitive generator state | Distinct restored environments receive distinct generator namespaces | Two restored environments emit the same first deterministic ID |
Network/resource state | Resource is validated or recreated before it is relied upon | Code assumes an initialized connection remains valid |
Request-fresh state | Refreshed according to request/TTL semantics in the handler | Refreshed only once in an after-restore hook |
This article consequently excludes generic Lambda design, serverless selection criteria, Lambda/SQS retry behavior, API architecture, cold-start benchmarking, and database resilience architecture. Those questions do not prove lifecycle correctness after a snapshot restore.
Documented behavior versus engineering inference
AWS documentation gives the lifecycle primitives; it does not know which objects in an application are semantically safe to clone. Keeping that boundary explicit prevents an experiment design from turning its own assumptions into supposed platform guarantees.
Documented behavior: runtime hooks can run before Lambda creates a snapshot and after Lambda resumes from one. AWS describes after-restore hooks as suitable for reinitializing resources or state that should not remain as captured, and Python exposes the hooks through the Snapshot Restore for Python library included in managed Python runtimes.
Documented behavior: Python before-snapshot hooks execute in reverse registration order; after-restore hooks execute in registration order. A hook defined in another module is ignored unless that module is imported by the handler module. Python initialization plus before-snapshot work is subject to the extended initialization limit, while runtime loading plus after-restore work must complete within ten seconds or a SnapStartTimeoutException results.
Engineering inference: an immutable lookup table compiled into a version can normally remain frozen because every restored environment is supposed to see the same value. Conversely, an application-level lease, environment identity, local sequence namespace, or value whose correctness depends on “what exists now” should be treated as suspicious until its restore semantics are tested.
Proposed experiment: create one fixture that deliberately contains examples of all three categories: immutable, stale-external, and uniqueness-sensitive; then vary only the restore logic.
Actual observation: none. The tables below describe evidence that a real run must produce; they are not fabricated run results.
One documentation issue deserves recording. As researched on September 22, 2026, the broad SnapStart overview still says container images and OS-only runtimes are unsupported, while AWS’s dedicated container-image SnapStart documentation describes lifecycle integration for managed-runtime images and a /runtime/restore/next contract for other compatible images. The more specific container document also explains initialization, before-snapshot, restore, after-restore, and failure handling.
That documentation drift is itself an operational lesson: record the documentation date and exact deployment form used by the evidence run. To remove that ambiguity from the primary lab, the fixture below uses a ZIP-deployed managed Python runtime, not a container image.
Statement | Classification | What it allows us to conclude |
One snapshot can initialize multiple restored environments | AWS-documented | Init-time state may be cloned |
After-restore hook runs before handler invocation | AWS-documented | It is a valid boundary for per-environment repair |
Immutable build configuration is safe to clone | Engineering inference | Must still be verified for the actual object |
Atomic restore ticket prevents fixture ID collisions | Proposed experiment property | Testable, not an AWS platform guarantee |
Candidate passed the lab | Actual observation | Not available; lab has not been executed |
Container-image support status | Documentation conflict | Verify current AWS documentation for that deployment form |
The key discipline is simple: use AWS documentation to define lifecycle behavior, then make the application prove that its own state classification is correct.
Lab fixture and version matrix
The fixture needs to make the wrong behavior obvious rather than probabilistic. A random UUID generator would weaken the demonstration because absence of collisions in a small sample would not establish lifecycle correctness. Instead, use an intentionally deterministic generator whose output namespace is frozen unless the after-restore hook changes it.
A disposable DynamoDB table acts as both control plane and evidence ledger. It holds external_epoch, an atomic restore_ticket counter, and append-only fixture events. No production data, credentials, queues, databases, or business APIs are required.
At initialization, the function computes a hash of immutable fixture configuration, reads external_epoch, sets restore_ticket = 0, sets local_counter = 0, and records an init event. A before-snapshot hook records the same state immediately before checkpointing.
Once AWS reports the published version as State=Active and SnapStart.OptimizationStatus=On, the test controller changes external_epoch from, for example, E1 to E2. AWS documents those configuration fields as the indication that the snapshot for the published version is available.
The no-hook variant therefore resumes with cached_external_epoch=E1, restore_ticket=0, and local_counter=0. The hook-enabled variant reads the current epoch after restore and obtains a unique ticket through an atomic ledger update before the handler runs.
A minimal generator can be deterministic:
local_counter = 0
restore_ticket = 0
def next_fixture_id(function_version: str) -> str:
global local_counter
local_counter += 1
return f"{function_version}:{restore_ticket:08d}:{local_counter:08d}"
When several environments restore the frozen no-hook state, each first invocation can produce the same suffix, 0:00000001. That is intentional breakage. In the corrected variant, each restore gets a different ledger-issued restore_ticket, so deterministic output remains distinguishable by environment.
AWS’s guidance supports the underlying concern: initialization-time unique IDs or RNG state can cease to be unique when the same snapshot is reused, and uniqueness should be created after initialization, either in the handler or through a restore hook.
Version and environment matrix
The managed runtime for the proposed fixture is python3.14 on Amazon Linux 2023. AWS lists Python 3.14 as a supported Lambda runtime, while Python 3.15 is still public preview as of September 22, 2026; that makes 3.14 the preferable current target for this reproducibility fixture.
The dependency manifest should explicitly pin snapshot-restore-py==1.0.0 and boto3==1.43.98. PyPI lists 1.0.0 as the Snapshot Restore library release and identifies AWS as its author; the package is also included by AWS in managed Python runtimes. PyPI’s Boto3 release history shows 1.43.98 as the latest listed release on September 18, 2026. AWS also recommends packaging SDK modules when applications need control over dependency versions rather than depending on the runtime-bundled SDK.
Component | Proposed version/configuration | Evidence to record |
Lambda runtime | python3.14 | Runtime identifier plus platform.python_version() |
Operating-system family | Amazon Linux 2023 | Runtime configuration record |
Snapshot Restore library | snapshot-restore-py==1.0.0 | importlib.metadata.version( |
AWS SDK for Python | boto3==1.43.98 | boto3.__version__ |
Fixture schema | snapstart-state-fixture/1.0.0 | Constant in every ledger event |
Deployment form | ZIP archive | Deployment manifest |
SnapStart | ApplyOn=PublishedVersions | GetFunctionConfiguration |
AWS CLI | Version 2 | Exact aws --version output must be attached to a real run |
Architecture | Choose one of x86_64 or arm64, then hold constant | Published-version configuration |
Region | One disposable supported Region | Run manifest; no region is invented here |
The Python patch level and operator’s exact AWS CLI build cannot honestly be supplied as an observation before the lab runs. They must be captured in the run manifest. A run missing them fails the reproducibility requirement rather than being “filled in” editorially.
Baseline state and evidence model
The lab is strongest when evidence is modeled before the test. Otherwise, the test can succeed while producing no proof that the critical transition happened.
Use one run_id generated by the controller before deployment. The table contains a control item for that run and append-only event items. Every event should include a monotonic ledger event sequence allocated atomically by DynamoDB, rather than treating function-local time as the ordering authority.
Each application event should record run_id, fixture schema version, build digest, published Lambda version, lifecycle phase, immutable-config digest, cached external epoch, live external epoch where applicable, restore ticket, local counter, generated fixture ID where applicable, SDK/library versions, and invocation request ID when a handler exists.
The ledger deliberately performs external writes during initialization and before-snapshot because it is a disposable diagnostic fixture. That should not be generalized into a recommendation to perform irreversible business writes in lifecycle hooks. Lambda can regenerate snapshots while applying software updates, so application logic should not assume a before-snapshot hook represents one permanent, exactly-once event for the lifetime of a published version.
A state transition for a hook-enabled candidate should be interpretable as:
publish version
↓
INIT
cached_epoch = E1
restore_ticket = 0
immutable_hash = H
↓
BEFORE_SNAPSHOT
same H, E1, ticket 0
↓
snapshot becomes Active
↓
controller mutates external_epoch: E1 → E2
↓
RESTORE
frozen memory initially contains E1 / ticket 0
↓
AFTER_RESTORE
cached_epoch refreshed to E2
restore_ticket atomically assigned N
local_counter reset
↓
INVOKE
generated_id = version:N:1
AWS places the after-restore hook at the end of the Restore phase and invokes the handler only after Restore completes.
Evidence field | Init | Before snapshot | After restore | Invoke |
immutable_hash | Required | Required | Required | Required |
cached_external_epoch | Required | Required | Required | Required |
live_external_epoch | Optional | Optional | Required | Required |
restore_ticket | 0 | 0 | Required for hook variant | Required |
generated_id | Not applicable | Not applicable | Not applicable | Required |
Lambda request ID | Not applicable | Not applicable | Not applicable | Required |
Published version | Required | Required | Required | Required |
Dependency versions | Required | Optional | Required | Required |
The immutable hash is the positive control. The stale epoch is the freshness control. The deterministic identifier is the uniqueness control. Together they answer a much better question than “did invocation return HTTP 200?”
Normal-path validation
The normal-path experiment requires two SnapStart-enabled published versions built from nearly identical code. Candidate A intentionally omits the after-restore repair. Candidate B registers it. Both begin with the ledger’s external_epoch=E1.
Publish Candidate A, then wait until AWS reports OptimizationStatus=On and State=Active. SnapStart is only exercised through the published version or an alias resolving to it, not $LATEST. After Active is confirmed, update the ledger control value to E2.
Now produce enough concurrent synchronous work to require more than one execution environment, but do not declare that multiple environments existed merely because requests were concurrent. Use SnapStart Restore evidence in CloudWatch to identify invocations for which a new environment was restored. AWS reports Restore Duration on the REPORT record when a new SnapStart execution environment is created.
Candidate A is expected to demonstrate the defect. Among first invocations associated with distinct restores, cached_external_epoch should still be E1, while a direct live control read sees E2. More importantly, restored copies start from restore_ticket=0 and local_counter=0; first invocations can therefore emit the identical deterministic ID.
That duplicate is not a performance defect. It is proof that uniqueness-sensitive initialization state was cloned exactly as the lifecycle model predicts. AWS warns that a single initialized snapshot is reused across multiple environments and that values intended to be unique should not be captured in that state.
For Candidate B, register an after-restore hook that creates or validates the service client, rereads external_epoch, atomically increments the disposable restore_ticket, resets the local counter, and records an after_restore event. AWS explicitly lists dynamic configuration and reinitializing resources/state as runtime-hook use cases.
The expected Candidate B result, which is not an observation, is cached_external_epoch=E2 before the first handler and a different restore ticket for each restored environment. The immutable hash should remain unchanged for both candidates.
Check | No-hook candidate: expected demonstration | Hook candidate: acceptance predicate |
Snapshot confirmed Active | Yes | Yes |
External value changed after snapshot | E1 → E2 | E1 → E2 |
Immutable hash after restore | H | H |
Cached epoch at first invoke | E1 | E2 |
Live epoch at first invoke | E2 | E2 |
First ID across multiple restored environments | Duplicate possible by construction | No duplicate |
After-restore ledger event | None | One per successful restore |
REPORT contains Restore evidence | Required | Required |
Actual result reported here | None | None |
The comparison is powerful because Candidate A is supposed to fail the freshness and uniqueness assertions. Without that negative control, a green Candidate B can still leave open the possibility that the test never crossed a meaningful restore boundary.
Boundary-condition experiment
Normal success is not sufficient. Restore logic has its own error boundary, and a safety case should show what evidence survives when that boundary fails.
AWS documents a ten-second limit for runtime loading and after-restore hooks in the Restore phase. A Restore failure is represented by a RESTORE_REPORT error, and a timeout can lead to SnapStartTimeoutException. The custom-runtime contract is even more explicit: an after-restore failure is reported through the restore error endpoint; Lambda fails the in-flight invocation and tears down that execution environment.
For the managed Python lab, do not infer additional internal implementation behavior beyond what the managed-runtime evidence actually exposes. The acceptance artifact should rely on observable Restore failure records and on whether the handler event exists, rather than claiming undocumented internals.
Deliberately failing boundary test
Publish a third candidate whose hook performs three synthetic operations:
after_restore_started
↓
atomic restore_ticket allocation
↓
raise DeliberateFixtureRestoreFailure
↓
after_restore_completed ← must never be reached
↓
handler ← must never be reached for that failed restore
This order is deliberate. It produces an external side effect before the forced failure. The test therefore distinguishes execution-environment failure from transactional cleanup of everything the hook already changed.
AWS documents that Restore failures produce error information in RESTORE_REPORT. For its custom/container-runtime contract, AWS also says the in-flight invocation fails and the environment is torn down following an after-restore failure.
The important lesson comes on the next attempt. Suppose a later restore succeeds and all normal assertions turn green. That green rerun proves only that the later environment reached a healthy state. It cannot prove that the previous failed attempt’s external effects were cleaned up.
The failed hook may already have consumed restore ticket 17, written after_restore_started, or altered some other external disposable state before raising. A successful next restore using ticket 18 does not retroactively prove that ticket 17 was released, compensated, or harmless.
Therefore the evidence set must preserve the failed attempt independently. The expected pattern is: a start record, a consumed ticket, Restore failure evidence, no after_restore_completed, and no handler ledger record attributable to the failed invocation. Gaps in the restore-ticket sequence are acceptable because the counter is a uniqueness namespace, not a transactional sequence.
Boundary-test artifact | Expected interpretation |
after_restore_started exists | Hook began execution |
Restore ticket allocated | External side effect occurred before failure |
after_restore_completed absent | Hook did not finish |
RESTORE_REPORT ... Status: error | Restore failed at the platform lifecycle boundary |
Handler event absent for failed attempt | Business handler did not run for that failed Restore |
Later candidate succeeds | Recovery path can create a healthy new environment |
Ticket gap remains | Evidence of prior side effect, not a cleanup failure by itself |
Green rerun deletes/overwrites failed record | Invalid evidence practice |
A robust after-restore hook should therefore be short, retry-aware, and designed so partial external effects are either harmless, idempotent, or explicitly compensatable. That is engineering guidance derived from the lifecycle boundary; it is not an AWS exactly-once guarantee.
Recovery and rollback behavior
SnapStart snapshots belong to published Lambda versions. AWS says that Lambda creates a snapshot for each published version and that publishing a new version is how application changes produce a new snapshot. SnapStart-enabled versions pass through states including Pending, Active, Inactive, and Failed.
That makes rollback primarily a version-selection problem, not a request to mutate the broken snapshot. The operational fallback should already exist as a separate, validated published version.
For the lab, maintain one known-safe fallback that does not depend on an unvalidated restore repair. It can be a previously accepted SnapStart version or, if lifecycle safety is uncertain, a version whose correctness comes from refreshing the relevant state in the handler. The purpose is to preserve application correctness while the SnapStart candidate is quarantined.
Do not define the intentionally broken no-hook candidate as the “rollback” simply because it is older. Age is not evidence of safety.
Aliases are useful because SnapStart can be invoked through aliases that point to published versions. AWS’s runtime documentation also recommends versions and aliases as deployment and rollback mechanisms when managing runtime changes. This article leaves general CI/CD and deployment strategy to the adjacent secure API and Infrastructure From Code material; here the only concern is restoring a lifecycle-safe version.
A failed candidate should remain available long enough to retain its evidence, but it should not receive normal traffic. Deleting it immediately can destroy useful linkage between published version, snapshot state, logs, and fixture evidence.
Condition | Operational response | Evidence required before return |
Candidate never reaches Active | Do not route to it | Initialization/before-snapshot error evidence |
Restore hook errors | Quarantine candidate | RESTORE_REPORT, ledger failure markers |
Duplicate generated IDs | Immediate correctness failure | Distinct restore evidence plus duplicated IDs |
Cached epoch remains stale | Quarantine/refactor | Post-snapshot control mutation and invocation record |
Monitoring evidence incomplete | Hold rollout | Repeat evidence run with retention fixed |
Candidate passes all gates | Eligible for controlled routing | Acceptance matrix tied to exact version |
Production concern after routing | Point alias to known-safe published version | Confirm fallback version and post-rollback health |
Rollback is complete only when traffic resolves to the intended safe version and the evidence record says which version received the subsequent invocations.
Concurrency, lifecycle, or version interaction
The uniqueness defect can hide in a single execution environment. One environment with a local counter produces 1, 2, 3 and appears perfectly healthy. The failure becomes visible when the same frozen counter state is used as the origin for multiple restored environments.
That is exactly why concurrency belongs in this validation. AWS states that SnapStart resumes new execution environments from the persisted snapshot on first invocation and as a function scales. The test needs multiple confirmed Restore events, not simply a high request total.
An after-restore hook also has different semantics from an invocation interceptor. It runs once when a particular execution environment is restored, before that environment starts its invoke loop. It does not rerun before every warm invocation.
That distinction splits external state into two categories. An execution-environment identity or connection that only needs repair after snapshot restoration is a good candidate for after-restore initialization. A feature flag, lease, authorization fact, or timestamp whose correctness can expire while the environment remains warm still needs handler-time or TTL-based validation. AWS’s explicit guidance to refresh ephemeral data in the handler supports that distinction.
Version interaction matters too. Updating the DynamoDB control item does not update the snapshot for an already published version; AWS says updating a snapshot requires publishing another version. That is what lets the proposed lab create the controlled E1-snapshot/E2-external-state condition.
There is another reason to attach evidence to runtime details rather than only the function version. Lambda periodically regenerates snapshots to apply software updates, and managed runtimes can receive automatic runtime updates. A published application version is therefore not a license to assume every underlying runtime component remains bit-for-bit unchanged forever.
Interaction | What can go wrong | Required evidence |
One warm environment only | Local sequence looks unique | Confirm multiple Restore Duration records |
Multiple restored environments | Frozen counter namespaces collide | Compare first invocation from each Restore |
After-restore vs invocation | Restore hook mistaken for per-request refresh | Warm follow-up invocation with controlled state change |
Published version vs $LATEST | Test accidentally bypasses SnapStart | Log qualified version |
External value changes | Snapshot retains old cached value | Record mutation time and both values |
Automatic runtime maintenance | Old evidence assumed universal forever | Record runtime/package version per run |
Alias routing | Results attributed to wrong version | Record context.function_version per invocation |
For uniqueness testing, the strongest unit of comparison is therefore not “all IDs returned by a load test.” It is “the first deterministic ID produced by each execution environment for which Restore evidence exists.”
Observability and evidence retention
Application logs alone cannot establish the platform lifecycle. Platform logs alone cannot establish whether application state was correctly repaired. The acceptance package needs both.
For SnapStart, AWS places initialization duration in INIT_REPORT. On the first invocation of a new restored environment, the regular REPORT includes Restore Duration and Billed Restore Duration; Restore Duration covers restoring the snapshot, loading the runtime, and running after-restore hooks. AWS X-Ray can expose a Restore subsegment, and the Telemetry API has platform.restoreStart, platform.restoreRuntimeDone, and platform.restoreReport events.
A failed Restore separately produces RESTORE_REPORT error information. Those records are important because a Lambda response payload saying “success” cannot, on its own, prove that the invocation crossed a fresh Restore boundary.
The application ledger supplies semantic evidence: what the frozen epoch was, what the hook refreshed it to, which ticket the environment acquired, and which deterministic ID its first invocation produced.
Do not build the correlation strategy around AWS_LAMBDA_LOG_STREAM_NAME or AWS_LAMBDA_LOG_GROUP_NAME environment variables; AWS says those variables are unavailable in SnapStart functions. The CloudWatch event itself still has log metadata, while application-level correlation should use fixture IDs, request IDs, published versions, and ledger event sequences.
A useful preflight command is:
aws lambda get-function-configuration \
--function-name "$FUNCTION_NAME:$VERSION" \
--query '{
Runtime:Runtime,
State:State,
LastUpdateStatus:LastUpdateStatus,
SnapStart:SnapStart,
Version:Version,
Architectures:Architectures
}'
Do not paste a fabricated response into the evidence package. The documented acceptance condition is State=Active with SnapStart.OptimizationStatus=On.
A corresponding CloudWatch Logs Insights investigation can isolate lifecycle records:
fields @timestamp, @logStream, @message
| filter @message like /INIT_REPORT|RESTORE_REPORT|REPORT/
| sort @timestamp asc
The interpretation matters more than the query: a REPORT with Restore Duration identifies a restored-environment invocation; RESTORE_REPORT Status: error identifies a restore failure; the application ledger then shows what happened to application state around that event.
Evidence that must survive a rerun
Never let rerunning the test overwrite the failing evidence. Give every run a separate run_id, retain the qualified Lambda version, and keep failed lifecycle records alongside successful reruns.
Artifact | Why it must survive |
Deployment/build digest | Ties evidence to exact code |
aws --version capture | Identifies operator tooling |
Runtime and Python patch capture | Identifies execution environment |
Boto3 and Snapshot Restore package versions | Identifies dependency behavior |
GetFunctionConfiguration result | Proves candidate was Active with SnapStart On |
Control mutation E1 → E2 | Proves freshness condition existed |
App lifecycle ledger | Shows state through init/restore/invoke |
CloudWatch Restore records | Proves restore boundary occurred |
Deliberate failure record | Prevents green rerun from hiding failed attempt |
Invocation request IDs and function versions | Correlates app events to requests/version |
Retention is part of correctness evidence. A dashboard that only shows the latest successful run is insufficient for the deliberately failing boundary experiment because it erases exactly the state transition the experiment was designed to investigate.
Negative tests and false confidence
A lifecycle test should be capable of failing for the intended reason. Otherwise, “green” might mean the test never exercised the dangerous state.
One easy false positive is failing to mutate the external epoch after snapshot creation. If both snapshot and live source contain E1, reading E1 during invocation cannot distinguish a correctly refreshed cache from a frozen stale cache.
Another is testing only $LATEST. AWS says SnapStart applies to published function versions, not the unpublished version. A perfect $LATEST test therefore says nothing about the snapshot restore path.
Python hook registration introduces another trap: putting the decorator in a module that is never imported. AWS explicitly says Lambda ignores hooks in such a module. A handler that independently rereads the external value could then mask the missing hook and make the application response look correct.
Hostname is also unsuitable as proof that two restored environments are different. AWS warns that restored environments originating from the same SnapStart snapshot return the same hostname and recommends creating an identity in the handler or an after-restore hook when an environment-specific identifier is needed.
Finally, testing a random generator by observing “no collisions” is weak evidence. AWS provides specific CSPRNG guidance and says managed SnapStart runtimes reseed relevant system entropy sources, but the application still needs to audit any stored unique state or custom generator assumptions. This lab deliberately uses an unsafe deterministic generator because failure should be deterministic, not statistically rare.
Negative test | Required failure signal | False-green pattern it prevents |
Leave external epoch unchanged | Test declared invalid | Frozen E1 mistaken for refreshed E1 |
Invoke $LATEST | Preflight rejection | Non-SnapStart execution mistaken for Restore |
Remove hook-module import | Stale epoch/duplicate namespace | Unregistered hook hidden by application behavior |
Use one environment only | Insufficient restore count | Local counter appears unique |
Disable hook but refresh in handler | Hook assertion must fail | Handler masks broken restore hook |
Use hostname as environment ID | Test design rejection | Cloned hostname misclassified |
Force after-restore exception | Restore failure evidence | Only success path tested |
Rerun after failure | Preserve original failed run | Later green result erases partial side effect |
A test suite should include these controls intentionally. Confidence comes not from a large number of green invocations, but from evidence that the fixture becomes red when the lifecycle repair is removed.
Operational rollout and rollback criteria
The production gate should be stricter than “candidate code passed unit tests.” SnapStart correctness depends on published-version lifecycle behavior that ordinary local tests cannot reproduce by merely importing the module twice.
First, the candidate must reach Active with OptimizationStatus=On. AWS documents Pending while the snapshot is being produced and Failed if initialization or snapshot creation fails; Lambda can also enter Inactive during periodic snapshot regeneration if initialization fails.
Second, the synthetic fixture must prove all three state classes: an immutable value remains unchanged, a deliberately stale external value becomes current at the required boundary, and uniqueness-sensitive frozen state is replaced before the first handler.
Third, the failing boundary test must have been preserved. A release process that deletes failed evidence and retains only a later green run does not satisfy this acceptance model.
Fourth, the after-restore path must remain comfortably designed around AWS’s ten-second Restore constraint. The test should not set a private “acceptable” threshold based on an invented benchmark; it should record actual restore duration and enforce the application team’s documented operational limit below the AWS hard boundary.
Fifth, the rollback target must be a known-safe published version and the routing mechanism must identify the qualified version serving traffic. General CI/CD design is outside this article’s anti-cannibalization boundary.
Rollout gate | Release | Hold |
Published version is Active and SnapStart On | Yes | Otherwise |
Exact runtime/dependency evidence retained | Yes | Missing |
Immutable-state assertion passes | Yes | Any mismatch |
External-state refresh assertion passes | Yes | Frozen value survives unexpectedly |
Uniqueness assertion across restored environments passes | Yes | Any duplicate namespace/ID |
Deliberate failure produces expected Restore evidence | Yes | Failure cannot be explained |
Failed run remains retained after rerun | Yes | Evidence overwritten |
Restore path fits documented lifecycle limit | Yes | Timeout or unexplained near-boundary behavior |
Known-safe rollback version identified | Yes | No validated fallback |
The rollout decision should be attached to the qualified function version, not to a mutable notion such as “the current Lambda.” That lets a later operator establish exactly which snapshot-bearing version the evidence covered.
Acceptance matrix
The final matrix converts the lab from a demonstration into a release criterion. Every row needs three things: a precondition that makes the test meaningful, evidence that can be retained, and an unambiguous decision.
Most importantly, do not collapse “application response was correct” and “after-restore state was correct.” A handler can compensate for a broken hook, or an invocation can reuse an already-warm environment and never execute Restore at all.
The immutable-state check is intentionally positive: its hash should remain identical. The external-state test is intentionally discontinuous: the source must change after the snapshot, and the repaired cache must match the new value. The uniqueness test is intentionally adversarial: restored environments begin from an identical deterministic generator state, and the hook must partition their namespaces.
AWS provides the lifecycle facts that make those conditions meaningful: shared initial state across restored environments, post-initialization uniqueness requirements, and after-restore execution before the handler.
Acceptance dimension | Preconditions | Passing evidence | Failing evidence |
SnapStart actually exercised | Published version, Active/On | Restore-bearing invocation | $LATEST or no Restore evidence |
Immutable state | Known config hash H | H at all phases | Unexpected hash change |
External freshness | Source changed E1 → E2 after snapshot | Hook and first handler show E2 | Cache remains E1 |
Uniqueness | Multiple confirmed restores | Distinct restore tickets and first IDs | Duplicate first ID |
Lifecycle ordering | Hook enabled | after_restore before related handler | Handler appears without required repair |
Boundary failure | Failing candidate published | Restore failure, no completed hook/handler | Business handler proceeds |
Failure retention | New run_id on rerun | Both failed and green evidence retained | Old attempt overwritten |
Dependency identity | Versions recorded | Manifest matches runtime record | Unknown/mismatched dependency |
Version identity | Qualified version recorded | Every handler attributed | Alias/version ambiguous |
Request-fresh data | Separate freshness rule | Handler/TTL refresh proves current value | Restore-only refresh assumed sufficient |
Pass criteria
A candidate passes only if all mandatory rows are supported by retained evidence. “No duplicates happened” is not sufficient unless more than one restored execution environment was actually confirmed. “External state was current” is not sufficient unless it was changed after the snapshot had become available.
The no-hook candidate is not expected to pass. Its purpose is to prove the fixture can expose frozen stale state and duplicated deterministic state.
Pass condition | Required |
Candidate is a SnapStart-enabled published version | Yes |
Multiple Restore boundaries confirmed | Yes |
Immutable digest unchanged | Yes |
Post-snapshot external epoch visible before first handler | Yes |
No duplicate deterministic IDs across confirmed restores | Yes |
Correct hook/version/package identity recorded | Yes |
Deliberate failure produces attributable failure evidence | Yes |
Failed attempt remains inspectable after green rerun | Yes |
Hold, refactor, or quarantine conditions
Some failures mean “fix the hook.” Others mean the state does not belong in an after-restore hook at all.
A configuration value that can change repeatedly during a long-lived environment should usually be treated with handler or TTL semantics rather than assuming restore-time refresh is enough. A network resource that cannot be validated quickly enough may need lazy handler initialization. A generator whose correctness cannot be demonstrated under clone-and-restore semantics should be replaced with a SnapStart-safe source of uniqueness rather than patched with increasingly complicated lifecycle code. AWS explicitly recommends creating unique data after initialization and provides SnapStart-safe randomness guidance for supported runtimes.
Finding | Decision |
Immutable value unexpectedly differs | Hold and investigate build/runtime source |
Hook not registered/imported | Refactor registration |
Cached state stale immediately after restore | Quarantine candidate |
Value becomes stale later during warm reuse | Refactor to handler/TTL freshness |
Duplicate ID across restored environments | Quarantine immediately |
Hook approaches or exceeds Restore timeout | Refactor work out of Restore path |
Failed hook leaves harmful non-idempotent external state | Refactor side-effect design |
Evidence cannot distinguish environments/restores | Hold; improve instrumentation |
Runtime/dependency versions unknown | Hold; run is not reproducible |
Documentation behavior differs from assumptions | Quarantine assumption, revalidate against current AWS docs |
The acceptance matrix should be stored with the build and published-version identifiers so that “SnapStart was validated once” never becomes a timeless claim detached from what was actually tested.
Common implementation mistakes
The first mistake is treating “initialized successfully” as equivalent to “safe to snapshot.” Initialization proves that an object can be created. SnapStart correctness asks whether duplicating its captured state across restored environments preserves the object’s semantics.
The second is classifying data by programming-language type instead of lifecycle meaning. A Python string can represent immutable configuration, a short-lived credential, a cached feature flag, a lease token, or an execution-environment ID. The fact that all are strings says nothing about whether they may safely be frozen.
Third, teams can move too much work into after-restore. AWS provides only ten seconds for runtime loading plus after-restore hooks. Network-dependent repair paths therefore need bounded behavior and explicit failure handling.
Fourth, hook registration order can become invisible application behavior. In Python, before-snapshot hooks execute in reverse registration order and after-restore hooks in registration order; module imports determine registration as well. If Hook B assumes Hook A has already repaired a client, that ordering belongs in tests.
Fifth, connection objects are frequently treated as frozen configuration. AWS says initialization-time connection state is not guaranteed after resume and recommends reestablishing connections after restore, either in the handler or an after-restore hook.
Sixth, application code can manually cache temporary credentials even though Lambda itself has SnapStart-aware credential handling. AWS says the SnapStart runtime uses container credentials rather than frozen access-key environment variables to avoid credentials expiring before restore. That does not make an arbitrary application credential cache automatically safe.
Finally, before_snapshot should not casually perform irreversible business operations. Lambda can regenerate snapshots for software updates, which makes an “exactly once over the version’s lifetime” interpretation unsafe.
Mistake | Why it fails restore reasoning | Preferred correction |
Generate environment ID during init | Value is cloned | Generate after init or in restore hook |
Seed custom deterministic generator during init | Generator state is cloned | Repartition/reseed after restore |
Cache mutable external config forever | Snapshot preserves old value | Restore refresh plus handler/TTL if needed |
Assume socket remains live | Connection state not guaranteed | Validate/reconnect |
Put hook in unimported module | Hook is ignored | Explicit import and registration test |
Treat hook as per-request middleware | Hook runs per restore, not per invocation | Handler-time validation |
Depend on hostname uniqueness | SnapStart environments can share hostname | Generate explicit environment identity |
Put unbounded I/O in restore hook | Restore has a hard time limit | Bound work or defer safely |
Assume before-snapshot is lifetime exactly-once | Snapshots can be regenerated | Make diagnostic/external effects idempotent |
Call a later green rerun “cleanup proof” | Prior side effects can remain | Retain and inspect failed-attempt evidence |
The safest review question is therefore not “Does this variable look static?” It is “What property would become false if ten execution environments began from exactly this value?”
Final decision
The final decision should be conditional rather than promotional: AWS Lambda SnapStart runtime hooks are an appropriate lifecycle mechanism for state that must be repaired once per restored execution environment, but only when the application can prove the repair before handler execution. AWS supplies the lifecycle boundary; the application still owns the correctness classification.
The proposed lab provides that proof structure without pretending to provide executed results. It makes safe frozen state stay constant, forces external state to become stale after snapshot creation, forces uniqueness-sensitive state to collide without repair, and introduces an intentional restore failure whose evidence must survive the subsequent rerun.
The result should be recorded against a qualified Lambda version and exact dependency/runtime evidence. Because Lambda can regenerate snapshots during software updates and managed runtimes evolve, an old lifecycle validation should not automatically be treated as evidence for materially changed runtime conditions.
Final decision question | Accept | Reject or hold |
Did the test unquestionably use a SnapStart restored environment? | Restore evidence present | No Restore evidence |
Is every frozen value classified by lifecycle semantics? | Documented classification | Unknown state |
Does immutable state remain invariant? | Exact digest match | Unexpected difference |
Is restore-fresh state refreshed before first handler? | Ledger proves current value | Stale value survives |
Is uniqueness restored across multiple environments? | Distinct namespace/IDs | Any duplicate |
Is request-fresh state handled beyond Restore? | Handler/TTL rule exists | Restore hook treated as sufficient |
Does intentional Restore failure stop the path as expected? | Failure evidence retained | Handler proceeds or evidence ambiguous |
Can failed-attempt side effects still be inspected? | Yes | Green rerun overwrote them |
Are exact execution/version details retained? | Yes | Reproducibility gap |
Is a known-safe rollback version available? | Yes | No verified fallback |
Decision record
For each candidate, the release record should contain a conclusion in this form:
Decision: Accept, hold, refactor, or quarantine.
Qualified Lambda version: recorded from the run.
SnapStart status: Active / OptimizationStatus=On required for the tested candidate.
Runtime: python3.14, with the observed Python patch recorded.
Dependencies: expected snapshot-restore-py==1.0.0 and boto3==1.43.98, verified from the deployed runtime.
Immutable-state result: evidence reference.
External-state result: evidence reference.
Uniqueness result: evidence reference.
Deliberate-failure result: evidence reference.
Failed-run retention: evidence reference.
Rollback version: qualified version identifier.
Actual observations in this article: none; execution remains required.
That record keeps four categories separate: AWS-documented behavior, engineering inference, proposed experimental method, and actual observation. Until the evidence fields are populated by a real run against disposable resources, the honest status is experiment specified, restore safety not yet proven.
Explore Refonte Learning’s Cloud Architecture Program for current program information. Review the published program page before making an enrollment decision.