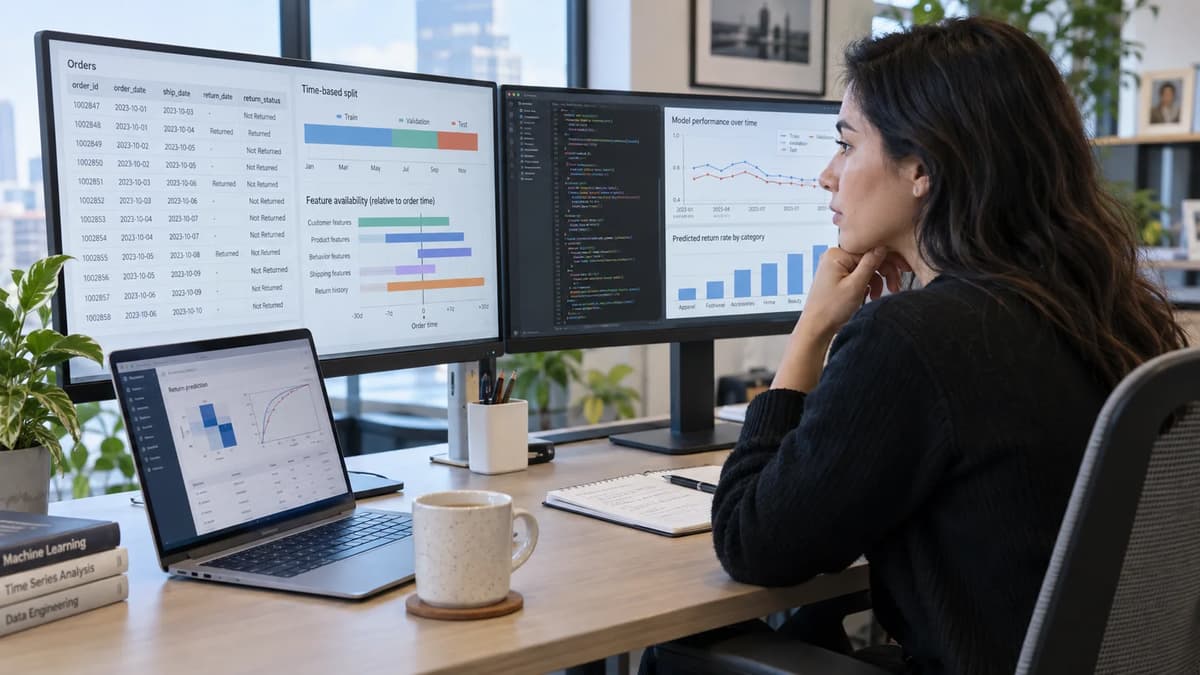
A synthetic retail-return model has an uncomfortable property: its offline backtest gets better after the warehouse team repairs several months of customer-history data. The repaired values have older event dates, so a conventional chronological join treats them as historical. But the corrections were not actually published until weeks after the original predictions. The model is being credited for information that did not exist online when it supposedly made those decisions.
That is the failure this playbook is designed to find.
A time-ordered split answers one question: did training rows precede validation rows? Point-in-time machine-learning validation asks a stricter one: for every prediction and every model-fit cutoff, what information was genuinely knowable then? That requires separate evidence for event time, feature availability, correction history, prediction time, label maturity and fold-local fitting.
Throughout this article, documented behavior means behavior supported by cited software documentation. Proposed operating model means a validation contract recommended here. Unverified assumption means a statement that still requires evidence from the actual warehouse, feature pipeline, serving path or installed software version.
The objective is not to improve an accuracy score. It is to build a row-level temporal evidence ledger, deliberately attack it with late and corrected records, and reach a reproducible accept, hold or invalidate decision about an evaluation dataset.
Define the decision and the historical knowledge boundary
Start from the prediction decision, not from whatever tables happen to exist today.
Proposed operating model: our synthetic task predicts, at the moment an order is released for fulfillment, whether that order will enter an approved-return state during the next 30 days. The entity is order_id. The prediction timestamp is recorded in UTC. Customer-history and product-history features are retrieved as of that timestamp. Models are hypothetically retrained weekly. No production performance is claimed; every identifier, timestamp and value below is illustrative.
Before querying data, write down the estimand: what future population and decision does the offline score intend to represent? A backtest for repeat customers asks a different question from one that claims to generalize to entirely unseen customers.
Contract field | Synthetic definition | Required evidence | Owner |
Prediction target | Return approved within 30 days after prediction | Label specification | Model/data owner |
Entity | order_id; customer may repeat | Entity-key contract | Analytics engineering |
Prediction time | Fulfillment-release timestamp, UTC | Serving/request record | ML engineering |
Feature context | Only information available by prediction time | Historical snapshot or availability timestamp | Data engineering |
Training cadence | Weekly synthetic retrain | Fit-cutoff manifest | Model owner |
Evaluation purpose | Estimate future-period performance for the stated population | Fold specification | Model-quality reviewer |
The key distinction is available information, not merely “rows with old dates.” A customer statistic calculated on May 31 but published on June 20 was not usable for a June 15 prediction, even though its business-effective date is May 31.
A reviewer should refuse to discuss model scores until these semantics are explicit. Otherwise an attractive result can be perfectly reproducible yet answer the wrong historical question.
Separate temporal leakage from ordinary model evaluation
Chronological validation is necessary for many temporal problems, but it does not prove point-in-time correctness. This article therefore starts where the statistical foundations of model validation leave off: after recognizing that split design matters, inspect whether each row itself contains knowledge from the future.
The scikit-learn 1.9.1 API documents TimeSeriesSplit(n_splits=5, ..., gap=0) and explains that gap is the number of samples excluded between training and test portions. It also states that equally spaced samples are required for its documented comparable-duration interpretation. Those defaults are API semantics, not a leakage certificate. See scikit-learn, TimeSeriesSplit, stable 1.9.1 documentation as accessed September 17, 2026.
Four failure classes should be kept separate:
Failure class | Example | Fixed by chronology alone? | Correct control |
Future-feature leakage | May event corrected in July and joined into June row | No | Availability-qualified history |
Fitting leakage | Scaler or feature selector fit on validation data | No | Fold-local fit |
Target leakage | Feature directly encodes return disposition | No | Feature-semantic review |
Legitimate later observation | June prediction scored after its 30-day outcome matures | Not an error | Keep features frozen; observe outcome later |
The scikit-learn pitfalls guide defines leakage broadly as using information that would not be available at prediction time and recommends learning preprocessing only from training data. Its synthetic feature-selection demonstration uses 200 samples and 10,000 random features to show how preprocessing before splitting can create an optimistic result. That is a teaching fixture, not evidence that leakage occurs at any particular prevalence in real projects. See scikit-learn, Common pitfalls and recommended practices, current stable guide, publication date not stated, accessed September 17, 2026.
The important practitioner distinction is that a Pipeline protects the fitting boundary for estimators and transformations placed inside it. It does not inspect whether an input column was backfilled after the historical prediction. If the table presented to the pipeline already contains tomorrow's corrected customer history, a perfectly scoped pipeline faithfully learns from contaminated data.
Later labels are different. A prediction made on June 15 may be evaluated in August after the return window has closed. That is not future-feature leakage because the label is being used to measure a prediction that was already fixed. It becomes leakage only when information about that future outcome influences the model, features, preprocessing, threshold selection or training data before the relevant cutoff.
Give every relevant timestamp a precise meaning
A column called created_at is evidence only after its generating semantics are documented. Database insertion time, source-system creation, warehouse ingestion, batch recomputation and online visibility can all produce different timestamps.
Proposed schema:
Field | Meaning in this playbook | Null policy |
event_time | When the underlying business fact was valid or occurred | Required for temporal features |
available_time | Earliest time this exact feature value could be consumed by the prediction path | Required for approval; unknown means hold/exclude |
prediction_time | Time the model input must have been knowable | Required |
model_fit_cutoff | Latest information the training run was permitted to use | Required per fitted model |
outcome_window_end | End of the target-observation horizon | Required |
label_available_time | Time the completed target value became usable by training/evaluation logic | Required for training eligibility |
revision_id | Identity of a correction/version of a historical fact | Required where mutable history exists |
Store timestamps in an explicit timezone, preferably normalized to UTC, while retaining any source timezone needed to interpret local business cutoffs. Equality rules must be written down: this playbook uses availability at or before the cutoff as eligible, expressed as available_time <= prediction_time.
Separate event occurrence from feature availability
A fact can belong to the past and still arrive in the future.
Suppose a customer had three prior returns by May 31. The warehouse initially reported two, so customer_return_count_90d=2 was available on June 1. A reconciliation process discovers the third return on June 20 and rewrites the May 31 history to 3.
Both versions describe an event-valid period before a June 15 prediction. Only the first was knowable on June 15.
Version | Event-valid time | Available time | Value | Eligible at June 15? |
Original | 2026-05-31 23:59Z | 2026-06-01 02:00Z | 2 | Yes |
Correction | 2026-05-31 23:59Z | 2026-06-20 04:00Z | 3 | No |
A latest-state warehouse that retains only 3 has destroyed evidence needed for exact historical reconstruction. An event timestamp cannot recreate the superseded value by itself.
Separate label occurrence from label maturity
Labels need their own knowledge boundary.
For the synthetic task, define the target as “approved return within 30 days following prediction_time.” To avoid treating an apparently negative order as final too early, this operating model declares the target mature only after the full 30-day window closes and the label pipeline publishes the completed state.
Time | Role |
2026-06-15 12:00Z | Prediction fixed |
2026-07-15 12:00Z | Thirty-day outcome horizon closes |
2026-07-16 02:00Z | Synthetic nightly label table becomes available |
2026-07-16 02:00Z onward | Label eligible for a later training cutoff |
A model fitted July 10 cannot train on this target. A reviewer scoring the already-fixed June 15 prediction on August 1 can use it. Training eligibility and evaluation observability are deliberately different predicates.
Inventory history, snapshots and upstream ownership
Point-in-time validation often fails because nobody can prove what the historical table represents. Before implementing joins, inventory every source that contributes to a model input.
This is where upstream data and database ownership matters: the reviewer who needs an availability guarantee is rarely the person who controls source CDC retention, warehouse restatements or batch-publication timestamps.
Use a source evidence matrix:
Source | Claim needed | Strong evidence | Unknown that triggers hold |
Order facts | Original event record preserved | Immutable event log / dated snapshot | Rows overwritten in place |
Customer aggregates | Value visible by prediction cutoff | Publication timestamp plus revision history | Only latest aggregate retained |
Product attributes | Historical version selected | Valid-from plus availability history | Current dimension joined retrospectively |
Return labels | Label mature by fit cutoff | Label build timestamp and horizon logic | Only outcome date retained |
Serving features | Offline reconstruction matches served values | Approved serving log/fingerprint | No historical serving evidence |
An immutable daily snapshot can sometimes substitute for a native availability timestamp, but its resolution matters. A midnight snapshot cannot prove whether a feature was available at 10:00 or 23:00 unless the operational cadence makes that inference defensible.
Hold rule: when a materially predictive field has no trustworthy historical availability evidence and no immutable snapshot from which availability can be bounded, do not silently substitute event_time. Record the uncertainty. Exclude the field, narrow the evaluation claim, or keep the dataset on hold.
Unverified assumption: “warehouse created_at equals online availability” is not acceptable merely because the names sound compatible. Establish which process writes it, whether retries preserve or replace it, whether upstream backfills inherit old timestamps, and whether online serving reads the same publication path.
A plausible temporal reconstruction is useful for investigation. It is not evidence that the deployed model actually knew those values.
Build point-in-time joins that enforce the intended boundary
Three joins that look superficially similar can answer different questions.
Join type | Eligibility rule | Main risk |
Latest-value join | Latest row visible today for entity | Historical restatements leak backward |
Event-time join | feature_event_time <= prediction_time | Late arrivals/backfills may still leak |
Availability-qualified join | Event rule and available_time <= prediction_time | Depends on trustworthy availability semantics |
The general contract is independent of any feature store:
# Pseudocode: availability-qualified historical lookup
candidate_rows =
feature_history[
entity_key matches
AND feature_event_time <= prediction_time
AND feature_available_time <= prediction_time
]
eligible_row =
latest candidate under documented event/version ordering
IF no trustworthy feature_available_time exists:
mark eligibility = UNKNOWN
do not substitute event_time silently
Current Feast documentation makes this distinction explicitly. By default, its point-in-time historical retrieval constrains feature event timestamps. If a source has a created_timestamp_column, that timestamp is used to deduplicate records sharing an event timestamp, but, by default, is not otherwise an availability cutoff. The documentation describes filter_by_created_timestamp=True, which adds created_timestamp <= entity_timestamp; rows with null created timestamps are excluded, and unsupported offline stores raise an error rather than silently ignoring the option. See Feast, Point-in-time joins, current reference, publication/feature-launch date not inferred here, accessed September 17, 2026.
That is documented behavior, but two qualifications are essential.
First, Feast's point-in-time join documentation says this reproduces availability only if the created timestamp actually represents when the value became available online. A generic source-creation timestamp is not automatically equivalent to serving visibility.
Second, support is offline-store dependent. Do not copy the following documented call shape into a production repository and assume it works merely because the current documentation shows it:
# Version-qualified API shape to verify locally before execution.
# Record Feast SDK version, offline-store implementation and capability test.
training_job = store.get_historical_features(
entity_df=entity_df,
features=feature_refs,
filter_by_created_timestamp=True,
)
As of the research cutoff, PyPI lists Feast 0.66.0 as the latest release, uploaded August 21, 2026. A reproducible project should nevertheless pin the exact installed SDK and store plugin rather than rely on the word “current.”
Feast's point-in-time join documentation treats TTL as a separate rule: the historical lookup scans backward from each entity timestamp by the feature view's TTL. It is not measured backward from the current clock. Therefore TTL limits historical age; it does not prove that a feature had arrived by prediction time.
Construct folds around time, labels and deployment purpose
After row-level eligibility is defined, construct temporal folds. Do not reverse that order.
Write the intervals before viewing locked-test performance. For a weekly synthetic model, one candidate plan could be:
Fold | Training prediction interval | Fit cutoff | Validation prediction interval | Label rule |
A | Jan 1–Mar 31 | May 1 02:00Z | May 2–May 15 | Train labels available by fit cutoff |
B | Jan 1–Apr 15 | May 16 02:00Z | May 17–May 31 | Same |
C | Jan 1–Apr 30 | Jun 1 02:00Z | Jun 2–Jun 15 | Same |
Locked test | Predeclared history | Predeclared final fit | Later untouched period | Score only after labels mature |
The dates are synthetic. The principle is to reproduce the intended training cadence and the amount of history actually available to each fitted model.
Choose a real temporal gap rather than an accidental sample gap
TimeSeriesSplit.gap is not a timedelta. scikit-learn documents it as a count of samples removed from the end of each training set before the test set, with default 0. The same API notes that equal spacing is needed for test folds to represent comparable durations.
Consequently, gap=48 means “48 rows,” not “48 hours,” unless the dataset has exactly one ordered sample per hour under the intended semantics.
For irregular retail events, define time masks directly:
train:
prediction_time < validation_start - embargo_duration
AND label_available_time <= fit_cutoff
validation:
validation_start <= prediction_time < validation_end
Boundary test | Expected result |
Feature available one microsecond after prediction | Exclude |
Feature available exactly at prediction | Include if contract uses <= |
Train label available one second after fit cutoff | Exclude from training |
Event stream has 1 row one day and 50,000 next day | Timestamp masks still preserve duration |
The gap or embargo should correspond to a documented dependency: label windows, overlapping aggregates, delayed upstream feeds or other contamination paths. Do not add an arbitrary gap and call the dataset safe.
Handle repeated entities and immature labels deliberately
Repeated customers are not automatically leakage. The correct handling depends on the estimand.
If production predicts another order for known customers, allowing earlier customer history can be appropriate. If the claim is performance on previously unseen customers, customer-level isolation is required.
The groups argument does not make TimeSeriesSplit group-aware: the current scikit-learn API documents groups as ignored for split.
Intended claim | Entity treatment |
Future orders from existing customer population | Repeated customers may be valid; history must be point-in-time correct |
New-customer generalization | Isolate customers across train/evaluation according to design |
Unknown deployment population | Hold claim until estimand is specified |
Similarly, immature labels are removed from training at that fit cutoff, not automatically from all later scoring. A prediction can remain in evaluation until its target becomes observable, provided the prediction and features are frozen.
Fit transformations only inside the permitted training scope
After temporal eligibility comes estimator hygiene.
The scikit-learn pitfalls guide recommends splitting before learned preprocessing and shows that a Pipeline helps ensure transformations are fit on the appropriate training subset during validation.
A minimal pattern for the already-audited feature matrix is:
# Illustrative structure; execute only after point-in-time eligibility is built.
from sklearn.compose import ColumnTransformer
from sklearn.impute import SimpleImputer
from sklearn.pipeline import Pipeline
from sklearn.preprocessing import OneHotEncoder, StandardScaler
from sklearn.linear_model import LogisticRegression
numeric = ["price", "customer_return_rate_90d"]
categorical = ["category", "fulfillment_channel"]
preprocess = ColumnTransformer(
transformers=[
("num", Pipeline([
("impute", SimpleImputer(strategy="median")),
("scale", StandardScaler()),
]), numeric),
("cat", Pipeline([
("impute", SimpleImputer(strategy="most_frequent")),
("encode", OneHotEncoder(handle_unknown="ignore")),
]), categorical),
]
)
model = Pipeline([
("preprocess", preprocess),
("classifier", LogisticRegression(max_iter=1000)),
])
# X_train and y_train must already satisfy the fold's temporal predicates.
model.fit(X_train, y_train)
The crucial phrase is already satisfy. Pipelines have no concept of warehouse revision history. If customer_return_rate_90d has been reconstructed from a July correction for a June prediction, the pipeline will not detect it.
Separate selection layers:
Stage | Data permitted |
Imputer/scaler/encoder fit | Current fold's training rows |
Feature selection | Current fold's training scope |
Hyperparameter search | Training plus designated inner validation only |
Probability threshold selection | Predeclared validation data, never locked test |
Final test scoring | Exactly once under the locked policy |
Model selection itself can induce leakage when repeated decisions are made against the final test period. A temporal audit therefore records not only rows and timestamps but also which results humans were allowed to inspect before freezing the candidate model.
Falsify the backtest with a synthetic retail timeline
Now build records intended to break the historical reconstruction.
All rows below are synthetic and illustrative. Let the focal prediction be 2026-06-15 12:00:00Z, and let one synthetic model-fit cutoff be 2026-07-10 02:00:00Z.
Record | Type | Event time | Available time | Value / label fact | Expected audit result |
R1 | Clean customer feature | Jun 14 20:00Z | Jun 15 02:00Z | prior-return rate = 0.08 | Eligible |
R2 | Late-arriving feature | Jun 15 10:00Z | Jun 15 12:05Z | carrier-risk = 0.31 | Exclude at prediction |
R3a | Original history | May 31 23:59Z | Jun 1 02:00Z | return count = 2 | Eligible |
R3b | Backfilled correction | May 31 23:59Z | Jun 20 04:00Z | return count = 3 | Exclude at prediction |
R4 | Training label | Window ends Jul 15 12:00Z | Jul 16 02:00Z | final return label | Exclude from Jul 10 fit |
R5 | Feature with unknown availability | Jun 10 00:00Z | NULL | loyalty tier = Gold | Unknown; hold/exclude |
An event-only reconstruction admits R2 and R3b because both have event timestamps no later than the prediction. R2 is only five minutes late, but the magnitude of lateness is irrelevant to correctness: the feature either crossed the knowledge boundary or it did not.
R5 is equally important. Silently replacing a null availability timestamp with event time manufactures evidence that does not exist. Under this operating model it receives UNKNOWN, not TRUE.
Compare a clean historical row with a late correction
Keep the prediction fixed and compare R3a with R3b.
Record | Event-time rule | Availability rule | Final eligibility |
R3a | Pass | Pass | Include |
R3b | Pass | Fail | Exclude |
This is the adversarial fixture every mutable aggregate should be able to survive. Introduce a correction whose business-valid time precedes the prediction but whose knowledge time follows it. If the corrected value appears in the reconstructed June feature vector, the join is not enforcing the intended boundary.
For Feast, the current point-in-time join documentation says filter_by_created_timestamp=True applies the extra created-timestamp condition where supported and excludes null created timestamps. It also says an unsupported offline store raises an error. Therefore the test plan must record the real Feast SDK, offline-store implementation and created-timestamp semantics before treating the flag as evidence of correctness.
A successful API call is not enough. The test fixture should assert the value: R3a must win at June 15; R3b must not appear.
Test fit-time labels and evaluation-time observation separately
R4 isolates the label question.
The June 15 prediction's 30-day window closes July 15 at 12:00Z, and the synthetic label pipeline publishes its finalized state July 16 at 02:00Z.
Use | Cutoff | R4 eligible? | Reason |
Fit model | Jul 10 02:00Z | No | Label unavailable |
Fit model | Jul 16 02:00Z | Yes under <= policy | Mature label available |
Score frozen June prediction | Aug 1 | Yes | Future outcome can now be observed |
Add explicit edge cases: a label available exactly at the fit cutoff passes only if the contract uses inclusive <=; a timestamp lacking timezone interpretation fails schema validation; a null label-availability timestamp does not become eligible by assumption.
The expected result follows from the fixture specification; it is not an executed test result.
For the initial candidate dataset, any extract that uses current corrected history and event-time-only filtering should be invalidated, because R3b is known by construction to violate the historical knowledge boundary. A rebuilt availability-qualified extract that still contains R5 should remain on hold until that uncertainty is resolved or the row/feature is excluded under a documented policy.
Compare reconstructed features with serving-time evidence
A reconstruction is stronger when it can be checked against what the serving path actually saw.
Google's Rules of Machine Learning defines training-serving skew as differences between training and serving behavior and, in Rule 29, recommends saving serving-time feature values so they can be compared with training data. Rule 31 separately warns that joined tables can change between training and serving. The page was last updated August 25, 2025; accessed September 17, 2026. See Google for Developers, Rules of Machine Learning: Best Practices for ML Engineering.
For privacy-conscious validation, that principle need not mean indiscriminately logging every raw sensitive field. A controlled evidence record can contain approved feature values, hashes, bucketed values or a canonical fingerprint, depending on what is necessary and permitted.
Evidence field | Example purpose |
prediction_id | Join audit record to prediction |
prediction_time | Historical cutoff |
feature_schema_version | Detect definition mismatch |
feature_vector_hash | Detect reconstructed-value mismatch |
Approved replay subset | Diagnose which fields differ |
Retrieval code/version | Reproduce transformation |
Online source revision | Tie value to serving state |
For deterministic, non-sensitive features, a canonical serialization plus cryptographic hash can answer a narrow question: “Did the reconstructed vector equal the vector captured at serving?” A mismatch does not immediately tell you why. Possible causes include historical correction, different feature code, stale online materialization, serialization differences or a reconstruction bug.
Do not label every mismatch “model drift.” Drift concerns changes in distributions or relationships over time; a point-in-time mismatch is first an evidence-integrity problem.
This is deliberately narrower than the broader notebook-to-production workflow. The audit here asks whether an offline evaluation faithfully represents past information, not how to operate an entire deployment platform.
Unverified assumption: if no serving-time evidence was retained, offline reconstruction may be the best available approximation, but it cannot prove the exact feature vector the historical service consumed.
Add automated invariants and negative controls
Temporal rules become credible when deliberately bad rows make the build fail.
The strongest test suite mixes positive controls, boundary cases and negative controls:
Invariant | Synthetic adversary | Required outcome |
Feature availability | Set available_time = prediction_time + 1s | Row rejected |
Label maturity | Set label_available_time = fit_cutoff + 1s | Training row rejected |
Join cardinality | Duplicate eligible versions | Fail unless ordering resolves uniquely |
Correction history | Add late backfill with older event time | Backfill not selected |
Missing availability | Set availability null | Unknown/excluded, never silently event-time |
Fold-local fit | Pre-fit transformer globally | Test detects fitted state or workflow violation |
Entity policy | Insert same entity across forbidden partitions | Isolation check fails |
A compact implementation contract might look like:
ASSERT all(feature_available_time <= prediction_time)
for included features
ASSERT all(label_available_time <= model_fit_cutoff)
for rows used to fit
ASSERT one resolved feature version
per (prediction_id, feature_definition)
ASSERT deliberately_future_feature_fixture IS EXCLUDED
ASSERT missing_availability_policy IS EXPLICIT
ASSERT preprocessing objects ARE FIT ONLY INSIDE fold training scope
The negative control matters. A test that merely confirms ordinary rows pass may be testing the wrong field or an always-true predicate. Deliberately future-date a feature and confirm that the evaluation build rejects it.
Likewise, inject two versions with identical event time and different correction times. Confirm that the version available before prediction is selected, not merely whichever row is newest today.
For irregular events, add boundary records immediately before, exactly at and immediately after every fold cutoff. For timezone-sensitive pipelines, test equivalent instants expressed in different offsets and reject naïve timestamps when the contract requires aware UTC values.
These are proposed tests, not executed results from the Refonte Learning environment or any external dataset. The audit artifact should store the test code, fixture revision and result when somebody actually runs it.
A broader data-science learning roadmap can provide surrounding skill context, but this temporal evidence suite should remain an engineering acceptance test, not a generic project checklist.
Interpret score changes without rewarding a contaminated dataset
When leakage is removed, the score may rise, fall or barely move. None of those outcomes determines whether the repair was correct.
Validity is upstream of performance.
scikit-learn's official lagged-feature example uses the Bike Sharing Demand dataset with 17,379 original records and contrasts a random train/test split with time-aware evaluation. In that specific worked example, the random split produces a more optimistic error estimate than the temporal procedure. The numbers belong to that dataset and implementation; they are not a universal “penalty” for chronological validation. See scikit-learn, Lagged features for time series forecasting, current stable worked example, publication date not stated, accessed September 17, 2026.
Report score changes alongside validity changes:
Report field | Why it matters |
Original evaluation definition | Shows what was previously claimed |
Rows/features removed | Quantifies audit impact |
Exclusion reason | Separates leakage from missingness |
Temporal cohort | Reveals period-specific behavior |
Updated estimate | Measures model only after validity repair |
Uncertainty | Avoids overinterpreting small differences |
Locked-test status | Shows whether model decisions contaminated final evaluation |
Do not praise an evaluation because it scores higher. If a higher score depends on a July correction being inserted into a June prediction, the result is unusable regardless of apparent predictive strength.
Conversely, a lower score after cleaning is not evidence that the model became worse. The estimator may be identical; what changed is the credibility of the measurement.
Reviewers should compare temporal cohorts that correspond to meaningful operational periods and report uncertainty appropriate to the task. This article intentionally does not prescribe a universal classification metric, confidence-interval method or business threshold because the exercise is about the information boundary, not a metric catalog.
Package a reproducible dataset and evaluation audit
A point-in-time backtest should be reconstructible by a reviewer who was not present when the data was built.
The audit manifest is the interface between model evaluation and data provenance:
Manifest field | Example content |
Raw snapshot IDs | Immutable object/version IDs or table snapshots |
Query revision | Git commit / SQL hash |
Timestamp semantics | Definitions, timezone and inclusivity |
Availability evidence | Source fields and producing pipelines |
Correction policy | How superseded versions are selected |
Fold definitions | Exact timestamp intervals |
Label maturity rule | Outcome horizon plus availability predicate |
Exclusion ledger | Row ID, field, reason, reviewer status |
Preprocessing revision | Pipeline/code/package versions |
Model revision | Model code and parameters |
Environment | Python and dependency lock |
Locked-test policy | Who can view results and when |
Reviewer | Named accountable role, not merely team alias |
The row-level exclusion ledger deserves first-class status. “Removed 1.7% of data” is less useful than knowing which records were late features, which lacked availability timestamps and which labels were immature.
For each exclusion, preserve a machine-readable reason such as FEATURE_AVAILABLE_AFTER_PREDICTION, LABEL_IMMATURE_AT_FIT, AVAILABILITY_UNKNOWN, AMBIGUOUS_CORRECTION_ORDER or ENTITY_POLICY_VIOLATION.
This is closely related to documenting a reproducible data-science project, but the audit's purpose is operational review rather than portfolio presentation. A reviewer should be able to reproduce the dataset without relying on screenshots, notebook cell state or undocumented manual fixes.
Recommended package:
Artifact | Acceptance evidence |
dataset_manifest.yaml | Inputs and snapshot identities |
timestamp_contract.md | Exact semantic definitions |
folds.csv | Prediction/fit boundaries |
eligibility_ledger.parquet | Row-level decisions |
fixtures/ | Late, corrected, null and boundary records |
tests/ | Automated invariants |
dependency lock | Exact executable environment |
review decision | Accept/hold/invalidate plus rationale |
Record unresolved uncertainty rather than editing it out of the narrative. A reproducible audit can legitimately conclude that historical availability is unknowable.
Build the data-science foundations behind the method
Point-in-time validation sits on ordinary foundations used with unusual discipline: Python to manipulate and test timestamped records; exploratory analysis to discover duplicates and anomalous histories; statistics to distinguish an estimand from an observed sample; and predictive modeling to keep fitting, selection and evaluation scopes separate.
Foundation | Application in this audit |
Python | Build deterministic eligibility predicates and fixtures |
Exploratory analysis | Inspect lateness, nulls and correction multiplicity |
Statistical reasoning | Define the population and evaluation estimand |
Machine learning | Separate training, validation and locked testing |
Model optimization | Tune only inside permitted folds |
Project work | Package evidence so another reviewer can reproduce it |
The verified Refonte Learning Data Science & AI Program page states a three-month duration with 12–14 hours per week and lists Python Data Science, Statistical Modelling, EDA and Data Visualization, Machine Learning and Predictive Modelling, Model Optimization, Deep Learning Methods and application to industry projects among its competencies.
Those foundations can support an exercise like this, but this article's bitemporal audit should be treated as an independent advanced application. The page inspected for this research does not establish a dedicated Feast module or this specific temporal-validation lab.
For readers strengthening those underlying skills, the Refonte Learning Data Science & AI Program provides the verified Python, statistics, exploratory-analysis and predictive-modeling foundations described above.
Decide whether the backtest is valid, conditional or unusable
The final review is an evidence decision, not a vote on whether the score looks reasonable.
Does a time split eliminate leakage? No. It prevents certain future-to-past training/test arrangements, but a historical row can still contain a feature backfilled after its prediction timestamp. The scikit-learn TimeSeriesSplit documentation defines ordering mechanics; it does not audit feature provenance.
Is event time enough? Not when records can arrive late or be corrected. Feast's point-in-time join documentation distinguishes its default event-time constraint from the optional created-timestamp availability filter.
Does a gap measured in samples mean days? No. TimeSeriesSplit.gap counts samples. A duration interpretation requires the corresponding sampling structure; irregular event data generally need explicit timestamp logic.
May future outcomes be used to score past predictions? Yes, once those predictions and their inputs were already fixed. Later outcome observation is how delayed targets become measurable. What cannot happen is allowing the future outcome, or information derived from it, to cross backward into the model or feature construction.
Use this decision table:
Decision | Evidence standard |
ACCEPT | Every material feature has defensible point-in-time availability; fit labels were mature; correction history is resolved; fold-local fitting is verified; required negative controls have actually passed |
HOLD | No demonstrated leakage, but important availability, label, entity, version or serving evidence remains unknown or tests have not run |
INVALIDATE | Known future information is admitted, immature labels trained the model, locked-test information influenced fitting/selection, or historical reconstruction contradicts serving evidence without resolution |
For the synthetic fixture in this article, the expected decision for a latest-state or event-time-only candidate extract is INVALIDATE: R3b is explicitly a correction unavailable until after the June 15 prediction, yet such a join would admit it. That conclusion follows from the fixture definition, not from an executed production test.
After rebuilding with availability filtering, removing or resolving R5, enforcing label maturity and adding fold-local preprocessing, the dataset should remain HOLD until its automated invariants and negative controls are actually executed. Only recorded passing evidence should move it to ACCEPT.
That is the standard worth defending: not that the backtest knows the past as the warehouse represents it today, but that it knows only what the model could have known then.