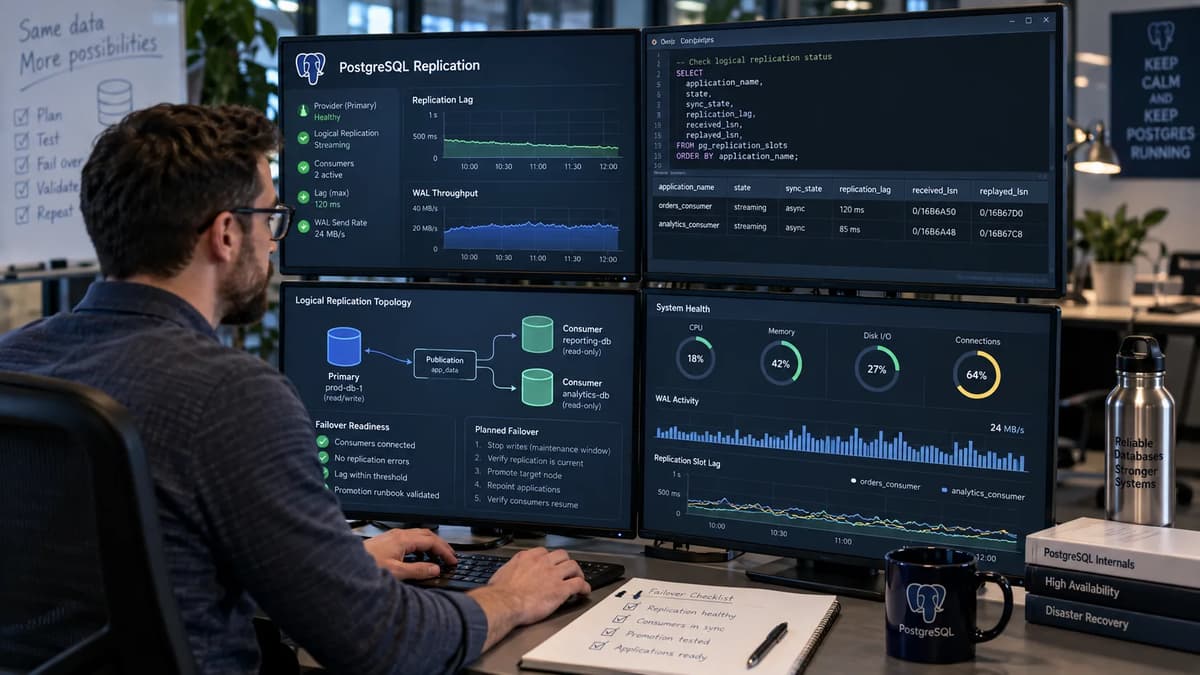
A synthetic incident makes the risk concrete. A planned PostgreSQL failover completes, the promoted server accepts writes, application health checks turn green, and most dashboards look normal. One CDC consumer, however, never resumes because its logical replication slot was not actually present and usable on the promoted standby. The database is available; the downstream contract is broken. That distinction is the center of this runbook.
This article uses PostgreSQL 18 as the fixed technical baseline and treats native logical-replication failover as an established capability, not a 2026 launch. The PostgreSQL Global Development Group’s PostgreSQL 17 release announcement, published September 26, 2024 and accessed September 17, 2026, records the introduction of failover controls for logical replication in September 2024. The PostgreSQL 18 logical replication failover documentation, accessed September 17, 2026, describes the current procedure, including the requirement to identify the complete needed slot set and verify that those slots are synchronized to the standby before promotion. Slot synchronization is asynchronous.
The objective is therefore not “promotion succeeded.” It is a defensible proceed, hold, or recover decision based on three separate evidence classes: the expected consumer inventory, the observed standby slot state, and post-promotion downstream reconciliation. A healthy row is evidence about that row; it is not evidence that no expected row is missing.
Define the continuity contract before choosing a promotion
Failover arguments become confused when the word “continuity” is asked to cover five different properties. Source availability is whether a writable PostgreSQL primary exists. Acknowledged-write durability is whether transactions already reported successful to clients survive the physical failover. Consumer restart is whether each logical consumer can resume from a valid position. Duplicate handling is whether replayed changes are safe. Downstream completeness is whether the intended business effects are ultimately present in each target system.
The PostgreSQL 18 logical decoding documentation, accessed September 17, 2026, explains that logical decoding can send recent changes again after a crash because a slot’s current position is persisted at checkpoints; clients are responsible for avoiding harmful effects from repeated messages. That makes duplicate handling a consumer contract, not a property to infer from a synced slot.
Proposed operating model: write the continuity contract before scheduling promotion. The recovery objectives below are team policy choices, not PostgreSQL guarantees.
Contract dimension | Owner | Required evidence | Team-selected objective |
Source availability | DBA/platform | new primary writable; old primary fenced | agreed recovery time |
Acknowledged-write durability | DBA/incident commander | physical-replication evidence to cutover barrier | agreed loss tolerance |
Consumer restart | CDC owner | expected slot exists and is failover-ready; endpoint reconnects | agreed restart time |
Duplicate safety | application/data owner | idempotency, dedupe key, or replay procedure tested | no unbounded duplicate business effect |
Downstream completeness | data/application owner | bounded event-ledger reconciliation | all expected business transitions accounted for |
Unverified assumption: any row in this table without an owner, evidence source, or tested objective remains unknown. Unknown is a hold, not a reason to reinterpret a database-level signal as an end-to-end guarantee.
Pin the versions, topology and promotion boundary
Start with identities, because the most dangerous failover mistakes are boundary mistakes. The physical standby being promoted is not a logical subscriber. A PostgreSQL subscriber may itself be another database cluster, while an external CDC platform may consume a slot and write to Kafka, object storage, a warehouse, a search index, or an application service. Track the publisher database, slot, consumer, and designated physical standby as separate identifiers.
The runbook baseline should record the exact PostgreSQL 18 minor version in use, packaging source, logical output plugin, connector or subscriber version, HA manager, endpoint mechanism, and configuration revision. PostgreSQL’s upstream documentation describes server behavior; it does not certify that a managed provider exposes every setting or that a connector preserves slot state in a particular way. Those are deployment checks. The PostgreSQL 18 failover documentation visible at the research cutoff is versioned independently from PostgreSQL 19 development documentation, so this procedure deliberately does not import PostgreSQL 19 beta behavior.
Inventory field | Example value format | Evidence owner | Promotion significance |
Publisher cluster | stable cluster ID | platform | identifies old and new primary |
Publisher database | orders_prod | DBA | logical slots are database-associated |
Designated standby | stable node ID | DBA/platform | intended promotion target |
Logical consumer | subscriber/connector ID | CDC owner | restart and reconciliation owner |
Slot name | cluster-wide slot ID | DBA + CDC owner | join key for readiness |
Output plugin | pgoutput or deployed plugin | DBA | compatibility dependency |
Endpoint | writer DNS/service alias | platform | reconnection and fencing path |
Evidence time | UTC timestamp | incident scribe | freshness control |
Config revision | commit/change ID | platform | reproducibility |
Provider capability | tested/unknown | service owner | outside scope until verified |
A major-version replay or upgrade qualification is a different exercise: it asks whether workloads, extensions, drivers and operational tooling behave correctly on a changed software version. Keep that work in a separate PostgreSQL workload-replay readiness exercise. This runbook keeps the software baseline fixed and asks whether the existing logical estate can survive the actual promotion path.
Proposed acceptance rule: topology evidence must be captured from the environment scheduled for the drill, with a named revision and timestamp. A diagram copied from an architecture wiki without a freshness claim is context, not promotion evidence.
Build an expected slot inventory that cannot silently shrink
The expected slot set must originate independently of the standby query used to judge health. Otherwise a deleted or never-created slot can disappear from both the system and the checklist, producing a false green result. Maintain a canonical consumer register with one row per logical consumer or required table-synchronization slot, then compare that register with PostgreSQL observations.
A practical proposed schema is: publisher_cluster, publisher_database, consumer_id, consumer_type, subscription_name, slot_name, slot_kind, failover_required, designated_standby, owner, recovery_method, and inventory_revision. Reject an empty set for a known CDC-enabled publisher, duplicate slot_name assignments, missing publisher database names, or ownerless external consumers unless a reviewed exception explains them.
Validation | Pass condition | Failure meaning |
Expected set non-empty | expected consumers represented | discovery or governance gap |
Slot names unique | no conflicting assignment | ambiguous ownership |
Publisher DB known | every logical slot mapped | incomplete recovery context |
Consumer owner known | responder can act | operationally unrecoverable during incident |
Failover requirement explicit | yes/no justified | silent scope shrink |
Designated standby explicit | one intended target | readiness checked on wrong node |
Inventory PostgreSQL subscriptions and table synchronization
For PostgreSQL subscribers, the PostgreSQL 18 logical replication failover procedure, accessed September 17, 2026, says to identify slots for failover-enabled subscriptions on each subscriber that will be served after failover. It also identifies table-synchronization slots that matter only when table copy has reached the documented finished state; other table-sync slots may be dropped or recreated and therefore should not be demanded indiscriminately. The pg_subscription_rel catalog reference, accessed September 17, 2026, defines f as “finished table copy,” followed by synchronized and ready states.
A read-only discovery pass can first record current_database(), subscription name, slot name, subfailover, and enabled state from pg_subscription, then run the documented table-sync discovery logic in every subscriber database containing failover-enabled subscriptions. The point is completeness across databases, not merely obtaining one array of slot names from one node.
Account for external CDC consumers and missing rows
The PostgreSQL 18 failover procedure states that non-PostgreSQL subscribers may use their own mechanisms to identify the slots they use. In a planned failover, the primary-side query for non-temporary failover-enabled slots is a useful cross-check, but it should not replace the independent business-consumer register. A slot can exist without anyone remembering why it exists, and a consumer can be expected even when its slot is missing.
A proposed completeness query should preserve missing rows with a left join:
-- Read-only audit pattern. Replace VALUES with the reviewed expected inventory.
WITH expected(slot_name, database_name, consumer_id) AS (
VALUES
('sub_orders', 'orders_prod', 'pg-subscriber-a'),
('cdc_billing', 'orders_prod', 'billing-cdc'),
('cdc_search', 'orders_prod', 'search-cdc')
)
SELECT e.consumer_id,
e.slot_name,
e.database_name,
r.synced,
r.temporary,
r.invalidation_reason,
CASE
WHEN r.slot_name IS NULL THEN 'MISSING'
WHEN r.synced AND NOT r.temporary AND r.invalidation_reason IS NULL THEN 'READY'
ELSE 'NOT_READY'
END AS audit_state
FROM expected e
LEFT JOIN pg_replication_slots r
ON r.slot_name = e.slot_name
AND r.database = e.database_name
ORDER BY e.consumer_id;
Expected observation: if cdc_search is absent on the standby, it still appears as MISSING. That row blocks approval until the discrepancy is explained and repaired.
Check synchronization prerequisites and backpressure deliberately
Slot failover is not one switch. The PostgreSQL 18 logical decoding documentation, accessed September 17, 2026, documents a chain of prerequisites for synchronizing logical failover slots to a hot standby. The standby must enable sync_replication_slots; synchronization also requires a physical replication slot between primary and standby through primary_slot_name, hot_standby_feedback enabled on the standby, and a valid database name in primary_conninfo. PostgreSQL highly recommends naming that physical slot in synchronized_standby_slots on the primary so logical consumers cannot advance beyond what the intended standby has received.
Requirement | Evidence to capture | Failure/hold condition |
Logical slot marked for failover | subscription/slot property | required slot not failover-enabled |
sync_replication_slots on standby | config snapshot | false or unknown |
primary_slot_name | standby config + physical slot exists upstream | missing/mismatched |
hot_standby_feedback | standby config | disabled where slot sync depends on it |
primary_conninfo database | redacted config proof | no valid dbname for slot sync |
synchronized_standby_slots policy | primary config | required physical slot omitted or unknown |
Separate slot copying from transmission ordering
Automatic slot synchronization is periodic and asynchronous. PostgreSQL also exposes pg_sync_replication_slots, but the logical decoding documentation says that manual function is primarily for testing and debugging, lacks cyclic retries, and should be used cautiously. Do not turn it into an invented production polling design.
The names matter. sync_replication_slots runs synchronization behavior on the standby. primary_slot_name identifies the physical upstream slot used by that standby. According to the PostgreSQL 18 replication configuration reference, accessed September 17, 2026, synchronized_standby_slots is a primary-side list of physical replication slot names that logical WAL senders wait for before transmitting decoded changes. It is not interchangeable with synchronous_standby_names, which governs synchronous replication acknowledgements for transaction commit policy.
Evaluate the availability cost of waiting for a standby
When a slot named in synchronized_standby_slots does not exist or is invalidated, the PostgreSQL 18 replication configuration reference says logical replication will not proceed; the associated replication management functions can also block until the required physical slots confirm WAL receipt. That is deliberate ordering protection with an availability cost.
Proposed operating model: test that consequence. Temporarily make the required standby unavailable in nonproduction and verify which logical consumers stall, what alerts fire, how WAL retention changes, and who owns escalation. Do not make “remove the safety constraint” the automatic response to lag. The decision to trade failover protection for immediate logical throughput belongs to the incident commander and data owners under an explicit policy. For broader context on service responsibility, keep cloud database recovery and ownership boundaries separate from the upstream PostgreSQL behavior documented here.
Make readiness a fresh, complete evidence set
The PostgreSQL 18 failover procedure gives a readiness predicate for the required standby slot rows: the slot is synchronized, not temporary, and has no invalidation reason. The documentation additionally says all required slots must be present. That second clause is easy to lose when an operator runs a WHERE slot_name IN (...) query and only looks at the returned rows. If three rows return true but four slots were expected, the result is not “all healthy”; it is “one missing.”
The pg_replication_slots catalog reference, accessed September 17, 2026, defines the fields that make this predicate useful. temporary slots are not persisted to disk. synced identifies a logical slot synchronized from a primary; on a hot standby such slots cannot be used for decoding before promotion. invalidation_reason is null only when the slot is not invalidated. After promotion, the slot becomes part of the new primary’s state, but consumer continuity still depends on reconnection and downstream behavior.
Proposed acceptance rule: add set completeness and evidence freshness to the documented predicate.
Expected slot | DB | Observed | synced | temporary | invalidation | Captured | Reviewer | Decision |
sub_orders | orders_prod | yes | true | false | null | T0 | DBA-A | ready |
cdc_billing | orders_prod | yes | true | false | null | T0 | DBA-A | ready |
cdc_search | orders_prod | no | not observed | not observed | not observed | T0 | DBA-A | hold |
A read-only standby query can capture the relevant fields:
SELECT slot_name,
database,
slot_type,
synced,
temporary,
restart_lsn,
confirmed_flush_lsn,
wal_status,
safe_wal_size,
invalidation_reason,
inactive_since
FROM pg_replication_slots
ORDER BY slot_name;
Do not reinterpret confirmed_flush_lsn as “the business side effect completed.” The pg_replication_slots catalog reference defines it as the address up to which a logical slot’s consumer has confirmed receiving data. That says nothing about a Kafka consumer committing a transaction, a warehouse merge finishing, an email being sent, or a search index reflecting the event. restart_lsn is different again: it is the oldest WAL address still potentially required by the slot.
Freshness also needs policy. Define a maximum evidence age appropriate to the change window and recapture immediately before the cutover decision. A screenshot or query result from yesterday can prove historical configuration; it cannot prove that an asynchronous synchronization process is ready now. A stale snapshot is therefore a separate hold condition even if every recorded row was true.
Observe WAL retention and invalidation before the drill
Logical slots retain resources. The pg_replication_slots catalog reference defines restart_lsn as the oldest WAL that might still be required by the slot and wal_status as the availability state of claimed WAL. reserved and extended still retain needed WAL; unreserved means the slot no longer retains all required files and some may be removed at the next checkpoint; lost means the slot is no longer usable. invalidation_reason can identify causes including removed WAL, removed required rows, insufficient wal_level, or idle timeout.
safe_wal_size requires context. The pg_replication_slots catalog reference defines it as the number of additional WAL bytes that can be written before the slot risks becoming lost, but PostgreSQL returns null both for lost slots and when max_slot_wal_keep_size = -1. Null is therefore not an unconditional healthy value; inspect wal_status, invalidation, and configuration together.
The PostgreSQL 18 replication configuration reference, accessed September 17, 2026, sets the documented default for max_replication_slots to 10 and max_slot_wal_keep_size to -1, the latter permitting unlimited slot-related WAL retention. Those are software defaults, not sizing recommendations for a CDC estate.
Signal | Interpretation | Proposed action |
wal_status = lost | slot unusable | recover, do not promote for that consumer |
non-null invalidation_reason | slot invalidated | hold/recover based on cause |
wal_status = unreserved | WAL at removal risk | hold and investigate retention |
small positive safe_wal_size | finite remaining margin | compare with measured WAL rate and drill duration |
null safe_wal_size, max keep -1 | unlimited slot cap configured | monitor filesystem capacity instead |
growing restart gap | consumer/slot lag retaining WAL | owner investigates before cutover |
Estimate retention from measurements, not invented throughput. Record WAL generation over representative intervals, the gap between current WAL and each slot’s restart_lsn, free space on the WAL filesystem, archive health, and the longest expected recovery or consumer outage. The database owner should define alerts that trigger before disk pressure turns a CDC problem into a primary availability problem.
Stop condition: missing required WAL, a lost or invalidated required slot, unexplained retention acceleration, or insufficient disk headroom to complete the planned window. Promotion may still be necessary during a real infrastructure emergency, but that becomes a recover path with acknowledged consumer risk, not a “ready” result.
Prepare fencing, endpoints and consumer ownership
Logical continuity can fail even when the slot is perfect if the old primary remains reachable. The PostgreSQL slot-synchronization guidance recommends disabling subscriptions before promotion, changing the subscription connection to the new primary, then re-enabling. It explicitly warns that if the old primary remains up, subscribers can continue receiving from it after promotion until the connection string changes, creating inconsistency.
That guidance is for PostgreSQL subscriptions. External connectors need their own pause, endpoint-change, credential, and restart procedure. Treat connector-specific behavior as deployment evidence, not something inferred from upstream PostgreSQL documentation.
Preparation item | Owner | Evidence | Stop condition |
Old-primary fencing method | platform/commander | rehearsed command or control-plane action | cannot prevent writes/reconnects |
Writer endpoint identity | platform | DNS/service target before and after | ambiguous target |
PostgreSQL subscription control | DBA/subscriber owner | disable/connection/enable privileges | insufficient privileges |
External connector control | CDC owner | pause/repoint/resume procedure | owner absent or procedure untested |
Credentials | service owner | secret reference, not secret value | unavailable at cutover |
Rollback/rebuild path | DBA + data owner | authoritative-source plan | no safe divergence recovery |
Keep the runbook and its configuration assertions under version-controlled database operations. The change record should point to secret references but never store passwords, tokens, full connection strings with credentials, or private keys in evidence bundles.
A physical standby that has been promoted and accepted divergent writes is not simply “the standby again” if the former primary later returns. The PostgreSQL 18 physical failover documentation, accessed September 17, 2026, requires a mechanism to ensure the old primary knows it is no longer primary and describes rebuilding or re-establishing a standby after failover. Rejoining therefore requires an approved HA recovery method and an authoritative timeline. The exact tooling depends on deployment architecture, so this runbook does not prescribe an upstream-only command as a universal provider procedure.
Proposed operating model: assign one promotion commander, one database operator, one platform/fencing operator, and one owner per logical consumer cohort. Separate roles reduce the chance that a single operator both causes the topology change and declares downstream correctness without independent review.
Run a controlled promotion with an auditable event ledger
Use a synthetic fixture whose expected outcome is known independently of replication. The fixture should carry stable business identifiers such as event_id and order_id, plus a small set of state transitions that the downstream system can expose. Do not use wall-clock ordering alone as proof: clocks can differ, queues can reorder observation time, and downstream processing can be asynchronous.
A useful synthetic sequence is: one event committed well before the cutover barrier, one immediately before the controlled write stop, one after the new primary is established, and one event deliberately replayed at the consumer boundary during a failure injection. The test harness records which event IDs it created and what business state each should produce. This is expected test design, not a claim that the drill was executed.
Step | Evidence captured | Owner | Stop condition |
Establish fixture | expected event IDs and target states | test owner | expected set uncertain |
Capture slot inventory | complete expected-versus-observed snapshot | DBA | missing/not-ready/stale slot |
Quiesce or bound writes | cutover barrier and acknowledged-write policy | commander/app owner | durability barrier unknown |
Pause consumers | PostgreSQL subscriptions/external connectors paused as designed | CDC owners | old source can still feed consumer |
Fence old primary | writer path disabled | platform | divergent writes possible |
Promote designated standby | HA control-plane evidence | DBA/platform | wrong node or recovery state unclear |
Repoint consumers | endpoint/connection evidence | CDC owners | any consumer points to old primary |
Resume by cohort | consumer starts from intended slot | CDC owners | slot unusable or repeated fatal error |
Reconcile ledger | expected IDs and business states matched | data/app owner | missing or unexplained duplicate effect |
Follow the successful rehearsal path
Immediately before cutover, recapture the canonical expected set, subscriber discovery results, standby slot state, physical replication position, WAL-retention signals, and configuration revision. The PostgreSQL 18 failover procedure requires the needed slots to be present and ready on the standby before failover; synchronization itself is asynchronous.
For a planned promotion, stop or tightly bound new writes according to the organization’s durability policy, then prove that the designated standby has received/applied the required cutover state under the physical-replication design. Slot readiness does not prove that acknowledged transactions are durable on the standby. If the physical link is asynchronous, an unplanned primary loss can still lose acknowledged transactions that had not reached the standby; the runbook must state that risk rather than laundering it through a logical-slot check.
Disable PostgreSQL subscriptions according to the documented recommendation; pause external consumers using their approved procedure. Fence the old primary from application writes and, where possible, from consumer connections. Promote the designated standby through the deployment’s approved HA mechanism. The PostgreSQL 18 physical failover documentation describes pg_ctl promote and pg_promote() for triggering promotion of a log-shipping standby, while failure detection, fencing and provider control planes remain deployment-specific.
After promotion, verify the expected logical slots exist and are usable on the new primary. For PostgreSQL subscribers, alter the subscription connection to the new primary and re-enable only after the connection target is proven. The ALTER SUBSCRIPTION documentation covers ALTER SUBSCRIPTION ... CONNECTION, ENABLE, and DISABLE for these controls. External connectors should be repointed or allowed to follow a tested writer endpoint only when the owner has evidence that the endpoint now resolves to the promoted primary.
Resume one consumer cohort, generate the post-promotion synthetic event, and compare downstream observations with the independent expected-event ledger. Expected success is not “the slot advanced.” It is: all expected pre-cutover and post-cutover event IDs are accounted for; any repeated transport is handled according to the consumer contract; and the accepted business state matches the fixture.
Inject missing-slot, replay and retention failures
The rehearsal should also fail on purpose.
1. Remove one expected slot from the audit input or test against a standby where it is absent; the left join must show MISSING, and approval must stop.
2. Present an old readiness snapshot after changing the environment; the freshness gate must reject it.
3. Stop synchronization for the physical standby used in synchronized_standby_slots; observe the documented effect on logical progress described in the PostgreSQL 18 replication configuration reference and confirm alerting and escalation.
4. Crash or restart a logical consumer in a way that causes repeated delivery; verify that transport duplicates do not create unbounded duplicate business effects. The PostgreSQL logical decoding documentation explains that crash recovery can resend recent changes.
5. Exercise a bounded retention-pressure scenario without exhausting production storage; verify that wal_status, safe_wal_size, disk alerts, and the hold path are understood.
If a required slot is missing after promotion, do not silently create a new one and declare continuity restored. Recovery depends on whether the needed history is still obtainable and on the connector’s bootstrap semantics. Preserve evidence first, then choose reconnect, repair, or rebootstrap.
Reconcile downstream effects, not just replication positions
Database positions are necessary but not sufficient. The pg_replication_slots catalog reference defines confirmed_flush_lsn as the position the logical slot’s consumer has confirmed receiving; it is not evidence that the next system in the chain committed its own transaction or that an external effect occurred exactly once. restart_lsn describes the oldest WAL that might still be required. Neither field proves semantic completeness in a downstream business model.
Reconciliation should therefore use stable identifiers and a bounded interval around the cutover. The event ledger should know which source events were expected, which state transitions they imply, and which consumer-specific evidence counts as accepted. For a warehouse that may be a durable row keyed by event_id; for a queue it may be a committed offset plus an idempotent sink record; for an application it may be a durable domain-state transition. These are consumer contracts, not PostgreSQL server guarantees.
Observation | Interpretation | Decision |
Same event delivered twice, one business effect | transport replay safely deduplicated | acceptable if contract allows |
Same event creates two charges/messages | duplicate business effect | recover |
Event absent but later correction exists | investigate domain semantics | do not classify by count alone |
Expected event absent everywhere downstream | probable gap | recover/hold |
Row counts equal, IDs differ | semantic mismatch | recover |
Schema apply error blocks subscriber | target schema incompatible | hold/recover |
The PostgreSQL 18 logical replication restrictions, accessed September 17, 2026, state that logical replication does not replicate DDL or schema changes, and sequence state is not replicated. A subscriber can therefore have correct replicated rows while still being unsuitable for independent writes or promotion without separate schema and sequence management.
That boundary matters during incident response. Do not compare only total row counts and call the systems equal. A duplicate and a missing row can cancel numerically. Compare the stable event IDs, expected transitions, relevant keys, and accepted final state over a defined interval. Where the consumer transforms or filters data, reconcile the transformed contract rather than demanding physical equality with the publisher.
The same principle applies to corrections. A legitimate compensating event after failover is not necessarily a replication duplicate. Keep transport identity, business identity, and final business state as separate fields in the ledger so the incident team can explain why a repeated message did or did not matter.
Recover without erasing the failure evidence
Recovery begins by preserving what failed. Before recreating a slot, resetting a connector, skipping a transaction, resnapshotting a target, or rewinding/rebuilding a node, capture the expected inventory revision, observed pg_replication_slots rows, subscription state, endpoint target, relevant logs, physical-replication positions, connector offsets, and downstream mismatch sample. Store references to secrets, never the secrets themselves.
A replication slot does not contain a copy of the downstream database. Recreating a missing or invalidated slot at a new position does not automatically reconstruct history that has already become unavailable. The pg_replication_slots catalog reference explicitly marks lost slots unusable, and synchronization can refuse to persist a slot when required WAL or catalog rows are no longer available on the standby.
Failure state | Preferred decision | Conditional recovery path |
Standby slot missing before planned cutover | hold | restore sync prerequisites; wait for valid synchronized slot; recapture evidence |
Slot invalidated/lost | recover | connector-specific rebootstrap from retained source/snapshot; reconcile gap |
Endpoint still reaches old primary | recover | stop consumer, fence old source, establish authority, assess divergence |
Repeated delivery only | reconnect/repair | apply tested idempotency or dedupe contract; reconcile effects |
Subscriber schema mismatch | repair | align schema under change control; resume and reconcile |
Consumer position unknown | hold/recover | prove restart point or rebuild; never guess |
Physical acknowledged-write loss suspected | escalate | authoritative source and business reconciliation, not slot repair alone |
For PostgreSQL subscriptions, the ALTER SUBSCRIPTION documentation defines the ownership and privilege conditions for changing connection details, enabling or disabling a subscription, and altering subscription properties. A runbook that assumes emergency operators have those privileges but has never tested them has an access-control gap. That is why database performance and security fundamentals belong in the operational foundation: recovery depends on disciplined privileges as much as on replication syntax.
Do not destroy the original evidence in the act of recovery. If a rebootstrap succeeds, retain the reason it was required, the interval potentially affected, the source used to rebuild, and the post-recovery reconciliation result. “Green now” is not a substitute for explaining whether any business effect was lost, repeated, or corrected.
Roll out by consumer cohort with explicit stop rules
A single rehearsal is evidence for the topology and versions tested, not a permanent certification. Rollout should move from nonproduction rehearsal to a deliberately limited consumer cohort and only then to broader use. The cohort boundary should reflect consumer semantics and blast radius: for example, a replay-tolerant analytical sink should not be treated as equivalent to a payment-side effect processor.
Gate | Proceed when | Hold when |
Nonproduction rehearsal | success and injected failures behave as expected | missing stop condition or owner |
Limited cohort | slot, endpoint, replay and reconciliation evidence complete | unknown connector behavior |
Broader rollout | prior cohort stable; no unresolved exceptions | provider support unknown |
Topology change | runbook revalidated | standby/endpoint identity changed without test |
PostgreSQL/connector upgrade | compatibility retested | version behavior assumed |
No universal waiting period is proposed here. Teams should choose observation windows based on transaction volume, consumer latency, business criticality, and the time needed to expose delayed failures. What matters is that the duration is explicit before the change rather than shortened after a partial success.
Reassess the contract whenever the designated standby changes, a new publisher database appears, a connector changes slot management, subscriptions are added, failover properties change, or the management layer is upgraded. PostgreSQL’s server behavior is only one layer; managed-service restrictions and connector-specific recovery remain deployment checks.
Hard hold gates: a required consumer has no owner; provider support for the required failover behavior is unverified; the expected slot inventory cannot be independently reproduced; a required slot is missing or invalid; consumer duplicate handling is unknown; or downstream reconciliation cannot be run. In an emergency, commanders may still promote to restore the database service, but the decision must be recorded as recover, with explicit downstream risk, rather than retroactively labeled ready.
Package the evidence and divide ongoing ownership
The closeout record should allow a reviewer who was not on the call to reconstruct the decision. Capture what topology was intended, which exact slot set was expected, what the standby showed, which physical durability condition was used, how endpoints changed, which consumers reconnected, and how downstream correctness was reconciled. Keep timestamps, but do not treat timestamp ordering across systems as proof of causality.
Evidence item | Minimum retained content | Primary owner |
Topology revision | cluster IDs, designated standby, endpoint identity | platform |
Expected set | consumer, DB, slot, owner, failover requirement | CDC/data platform |
Observed slot state | readiness fields + capture time | DBA |
Config proof | relevant setting values, revision, redacted secrets | DBA/platform |
Promotion ledger | commands/control-plane actions and approvals | incident commander |
Endpoint proof | old source fenced; new source selected | platform |
Consumer restart | start result, restart position/evidence | CDC owner |
Reconciliation | expected IDs, duplicates, gaps, corrections | data/app owner |
Residual exception | risk, owner, remediation date | commander/service owner |
A practical evidence-retention checklist is compact: keep machine-readable query output where possible; store the reviewed expected-set revision; preserve logs around synchronization and promotion; retain configuration diffs; record consumer restart evidence; and retain the reconciliation result. Redact or omit passwords, tokens, private keys, raw secret-bearing connection strings, and unnecessary customer data.
Responsibility should match system boundaries. The DBA owns PostgreSQL configuration, slot state, WAL retention, and physical-replication evidence. Platform engineering owns fencing, endpoint routing, infrastructure automation, and provider control-plane behavior. CDC/data engineering owns connector restart semantics, offsets, dedupe behavior, and target reconciliation. Application/domain owners define what a correct business effect means. Incident command owns the final risk decision. That division aligns with the practical distinction discussed in DBA and data-engineering ownership, while the technical authority for PostgreSQL behavior remains upstream documentation.
The closeout should state one of three outcomes plainly. Proceed means the expected set is complete and fresh, required slots are ready, physical durability assumptions are satisfied for the planned procedure, endpoints/fencing are controlled, and downstream reconciliation passed. Hold means the change has not happened and evidence is missing or unsafe. Recover means promotion happened or a failure was exposed, and consumer correctness now requires repair, rebootstrap, or business reconciliation.
Build the database foundations behind this exercise
This failover drill sits on ordinary database disciplines: knowing what data must be durable, understanding recovery boundaries, querying system catalogs safely, monitoring resource pressure, and controlling privileged changes. Those foundations are broader than PostgreSQL failover slots, but without them the specialized runbook becomes a collection of commands without an evidence model.
Foundation | Application in this runbook |
Backup and recovery | distinguish physical recovery from logical consumer rebuild |
SQL and catalog reading | build expected-versus-observed slot audits |
Monitoring | detect lag, WAL pressure, invalidation and stale evidence |
Access control | ensure promotion and subscription changes use approved privileges |
Disaster recovery | define fencing, authority, rollback and reconciliation |
Change management | version the runbook and topology assumptions |
The verified Refonte Learning program page, accessed September 17, 2026, lists a three-month program at 12–14 hours per week and explicitly covers database design, SQL optimization, backup and recovery, performance tuning, security, cloud database management, migration, disaster recovery, role-based access control, and monitoring; its FAQ names MySQL Workbench, Oracle SQL Developer and AWS RDS. The page does not establish PostgreSQL 18 failover-slot labs or CDC connector certification.
For readers building those broader foundations, the Refonte Learning Database Administrator Program is one relevant starting point; treat the PostgreSQL 18 failover exercise in this article as an independent advanced application, not as a promised syllabus module.
Answer the final proceed, hold or recover questions
Is a synced slot enough? No. The PostgreSQL 18 failover procedure requires the needed slots to be present and ready, and readiness for the standby row includes synchronized, persistent rather than temporary, and not invalidated. This runbook adds two proposed controls: independently prove that the expected set is complete, and require fresh evidence.
What does a missing result row mean? It means the health query has no evidence for that expected slot. It does not mean the slot is healthy. A left join or explicit set difference should make missing expected rows visible. The operational decision is hold before a planned cutover, or recover if promotion has already happened.
Can a crash repeat changes? Yes. The PostgreSQL logical decoding documentation explains that logical decoding can resend recent changes after a crash because slot position persistence occurs at checkpoints. The consumer must tolerate or correctly reconcile repeats. Do not promise exactly-once external effects from PostgreSQL slot state.
Does promotion prove no acknowledged-write loss? No. Logical-slot readiness addresses the ability to resume logical replication from the promoted server. Acknowledged-write durability depends on the physical replication and commit policy actually in force at the cutover. A planned failover can establish a controlled durability barrier; an unplanned loss of an asynchronously replicated primary can have a different recovery point.
Final gate | Proceed | Hold | Recover |
Expected slot set | complete | unknown/missing | missing after promotion |
Standby readiness | all required rows ready and fresh | stale/not-ready | slot lost/invalidated |
WAL retention | adequate measured margin | pressure unexplained | needed history unavailable |
Physical durability | planned barrier satisfied | unknown | suspected acknowledged-write loss |
Fencing/endpoints | old source fenced; new target proven | ambiguous | divergence detected |
Consumer replay | contract tested | unknown | harmful duplicate effect |
Reconciliation | expected business states accounted for | not yet run | gap/mismatch found |
The strongest decision is sometimes hold. Promotion is an availability action; logical-consumer continuity is a separate evidence problem. Approve the planned cutover only when the complete expected inventory, synchronized standby state, physical durability assumptions, reconnection path, and downstream reconciliation all agree. Anything less is not proof; it is an unverified assumption waiting to become an incident.