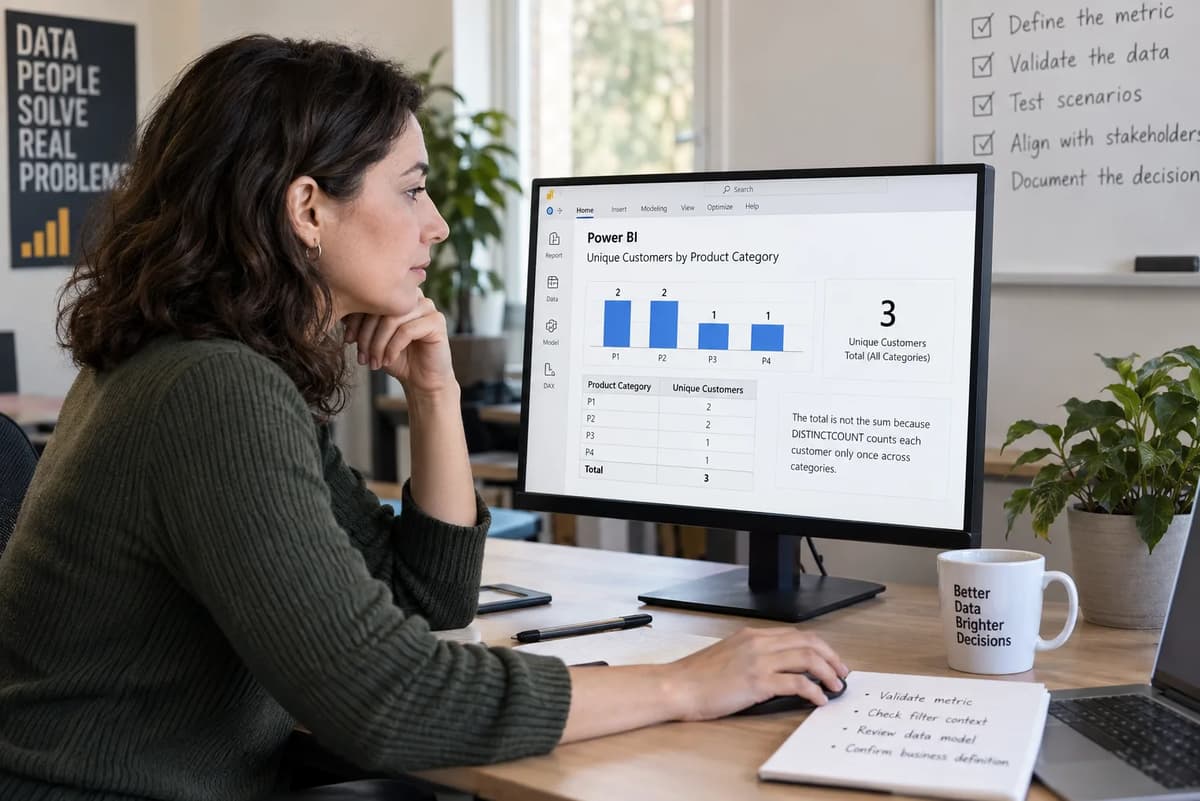
A dashboard shows distinct customer counts by product category. For January, it reports 2 unique customers in Category P1 and 2 in P2, yet the combined total is 3. That lower total can look like a defect. In fact, Microsoft’s DISTINCTCOUNT documentation describes this as expected behavior: the total counts each customer once across the combined population rather than adding category counts. Before changing DAX, the team must decide whether to accept the union count, clarify an additive membership requirement, or repair a proven data or model defect.
This playbook defines the metric, fixes a small star-schema fixture, and creates an independent oracle of customer sets. It traces the customer identities behind each category, subtotal, and grand total, then compares those sets with the expected DAX results. It also separates blank customer identifiers from empty filter contexts and shows how each filter changes the population being counted. The final outcome is an evidence-based decision to accept the measure, clarify the business definition, or repair the model.
This is a detailed check of one measure in context, not a general DAX course. Before running the lab, record the exact Power BI Desktop build, data types, relationships, measures, and active filters. The independent Python oracle in this article was executed; Power BI Desktop results remain expected assertions until a reviewer records them. The closing checklist identifies the minimum evidence required to approve or change the measure.
Name the Business Quantity Before Touching DAX
First, define exactly what is being counted. Is the report counting distinct customers across all selected categories, or customer-category memberships in which the same customer can count once per category? A customer who appears in two categories belongs once in the union but twice in the membership count. Before inspecting formulas, identify the metric owner and its business definition. Questions about metric grain and semantic ownership include:
What event makes a customer countable, such as any qualifying purchase in January?
Is the grain one unique customer across categories or one unique customer per category?
Who owns the definition, and which accounts, events, or identifiers are excluded?
Should the total mean all distinct customers or the sum of category memberships?
These questions form the metric contract. “Unique customers” may be the intended quantity, or the stakeholder may actually need category-specific memberships. A non-additive DISTINCTCOUNT total is not inherently a bug; it reflects one definition. The legitimate outcomes are:
Accept the measure: If the metric was intended to be unique customers across all categories, then the lower total is correct. We just document that and explain it.
Clarify the definition: If the stakeholder really meant “customer-category memberships,” we may need a new measure (summing counts per category). The distinct-customer total would then need to be renamed or hidden.
Repair the model: If we find data issues (duplicate events, wrong relationships, missing dimension keys), fix those first. But never remove legitimate events just to force additivity.
This is a semantic-ownership decision. Do not label a lower total as wrong until the team has agreed on the question the measure must answer. Only then can the DAX output be interpreted correctly.
Fix the Fact Grain and Relationship Contract
Use a bounded Import-mode star schema with the following contract:
Fact table Events: one row per event, with a stable EventID. Columns: EventID, CustomerKey, ProductCategory, EventDate (and any surrogate keys for dimensions). In our fixture, all events are unique.
Dimension tables: Customer, ProductCategory, Date. Each has a unique key (e.g. CustomerKey, Category, Date). ProductCategory could simply be a table of category names P1, P2.
Relationships: active, single-direction, one-to-many relationships from Customer to Events, ProductCategory to Events, and Date to Events. The dimension is on the one side and the event fact is on the many side. This follows Microsoft’s Power BI star-schema guidance, in which dimensions support filtering and grouping while facts support summarization.
Power BI Desktop: use Import mode and record the exact installed build from the application’s About dialog before testing. This article does not claim an executed Desktop lab.
The fact grain is one row per event. Each row has one stable EventID, one category, one date, and a customer key that may be blank only in the controlled missing-identifier variant. Confirm that the five January events are present exactly once so join duplication is not mixed into the non-additivity test.
A known star schema and fixed fact grain keep the formula focused on business logic rather than hidden model defects. Every fact row must remain one event. Teams that need a broader tooling primer can review Power BI and SQL foundations before running this validation.
Make the Disputed Total Small Enough to Inspect
To understand the discrepancy concretely, let’s list the actual events and sets of customers. In January we have 5 events:
EventID | CustomerKey | ProductCategory
--------------------------------------
1 | A | P1
2 | A | P1
3 | B | P1
4 | B | P2
5 | C | P2
Here, the category-unique-customer sets are:
P1: customers {A, B}. Customer A appears twice but counts once, so the distinct count is 2.
P2: customers {B, C}, so the distinct count is also 2.
The sum of these category counts is 2 + 2 = 4 (the count of customer-category memberships).
The unique customers across P1 and P2 are {A, B, C}, so the union count is 3.
The category counts sum to 4 because they count four customer-category memberships. The all-category union contains only three customer identities. That is the documented non-additive behavior of DISTINCTCOUNT totals, not a hidden correction.
Use Sets as the Independent Oracle
Run an independent set-based oracle that applies the same filters without reusing the DAX expression:
events = [
 ('Jan', 'P1', 'A'),
 ('Jan', 'P1', 'A'),
 ('Jan', 'P1', 'B'),
 ('Jan', 'P2', 'B'),
 ('Jan', 'P2', 'C'),
]

p1 = {customer for month, category, customer in events if category == 'P1'}
p2 = {customer for month, category, customer in events if category == 'P2'}
all_customers = p1 | p2

print('P1:', sorted(p1), 'count', len(p1))
print('P2:', sorted(p2), 'count', len(p2))
print('Union:', sorted(all_customers), 'count', len(all_customers))
Running the script returns:
P1: ['A', 'B'] count 2
P2: ['B', 'C'] count 2
Union: ['A', 'B', 'C'] count 3
The oracle applies the same product filter and derives independent identity sets. Any later date filter or eligibility rule must be applied identically in both the oracle and the model test. Because the oracle does not invoke DAX, it can expose a formula that answers a different question even when a visual looks plausible.
With this oracle, we’ve made the problem small enough to inspect. We see the key invariant: the customer sets in P1 and P2 overlap by B, so summing per-category counts overstates the unique count by 1. The “misleading success” here would be to simply sum 2+2 and assume 4. We avoid that by examining the sets explicitly.
Trace the Filter Context of Each Cell
In Power BI, each cell in the report has its own filter context. For our table (categories in columns, time in rows, with totals), the context is:
Category row (P1): Filter ProductCategory = P1 and EventDate = January. No filter on Customer, so the measure DISTINCTCOUNT(Events[CustomerKey]) counts distinct among events where Category = P1 in Jan.
Category row (P2): Similarly, ProductCategory = P2 and EventDate = January.
Grand Total: No filter on ProductCategory (all categories included), but EventDate = January still applies at the row level. Thus it sees all January events, irrespective of category.
Use one explicit measure throughout the matrix:
UniqueCustomers = DISTINCTCOUNT(Events[CustomerKey])Each cell evaluates that measure under its own filter context. The CALCULATE documentation explains how filter context can be modified and notes that a model measure receives automatic context transition when it is evaluated in row context. Here, the visual supplies the date and category filters; the grand-total cell omits the category filter.
Because of this, the Grand Total result is not the sum of the P1 and P2 results. Instead, it is calculated over the full set of events (all categories). In our January example, the P1 cell returned 2 and P2 returned 2, but the Grand Total cell returned 3 – because in that filter context (no category filter), the distinct set of customers is {A,B,C}. In other words, the measure was counted on a different population, not simply adding two numbers.
We can illustrate filter context explicitly:
Cell Context | Active Filters | Customer Events Seen | Distinct Count |
P1 (January) | EventDate = Jan; Category = P1 | A, A, B | 2 |
P2 (January) | EventDate = Jan; Category = P2 | B, C | 2 |
Grand Total (January) | EventDate = Jan; no category filter | A, A, B, B, C | 3 |
(We omit the BLANK-customer event for now; it will be added below.)
The grand-total cell sees all January events from P1 and P2, so its distinct identity set is {A, B, C}. Each cell answers the same measure over a different filtered population. The total is therefore recalculated over all selected categories; it is not a hidden sum of the visible category cells.
DISTINCTCOUNT totals are intentionally non-additive when identities overlap. Diagnose the population represented by each cell before considering any alternative measure.
Separate Rows From the Total Evaluation
To further clarify, we explicitly list the customer identities counted in each context:
In context Category = P1, January events, customers = {A, B}.
In context Category = P2, January events, customers = {B, C}.
In the Grand Total context (no Category filter), January events, customers = {A, B, C}.
The measure’s change from 2 to 3 (rather than 4) is solely because the filter set changed. The measure always did DISTINCTCOUNT on Events[CustomerKey]; what changed is which rows were included. This shows clearly that the “missing” 1 is due to the same customer (B) appearing in both categories. The Grand Total eliminated the duplicate counting of B. There is no hidden arithmetic adjustment beyond that.
Implement One Explicit Unique-Customer Measure
Define the measures and state the expected assertions before opening the visual:
-- Model measure: count distinct customers in the event fact
UniqueCustomers = DISTINCTCOUNT(Events[CustomerKey])
For the five-row January fixture, the expected results are P1 = 2, P2 = 2, and Total = 3. Record the actual Desktop output separately; do not present these expected values as an observed product test.
It can help to also write a “known-customer” variant that explicitly excludes blank CustomerKeys. For example:
KnownCustomers =
CALCULATE(DISTINCTCOUNT(Events[CustomerKey]),
 NOT (Events[CustomerKey] IN { BLANK() }))
The known-customer variant excludes actual blank fact identifiers. That rule matters because DISTINCTCOUNT counts BLANK as one distinct value. The five-row base fixture has no blank identifier, so both measures have the same expected results until the controlled sixth event is added.
Do not assume that counting the Customer dimension answers the same question. With single-direction dimensions, a ProductCategory filter reaches Events but does not filter Customer through the fact table. COUNTROWS(VALUES(Customer[CustomerKey])) can therefore return all customer dimension rows rather than the customers represented by the filtered events. Counting Events[CustomerKey] keeps the measure aligned with the event population.
For completeness, here are two approaches side by side:
-- Approach 1: Count in fact table (subject to both filters on Category and Date)
UniqueCustomers = DISTINCTCOUNT(Events[CustomerKey])

-- Approach 2: Sum distinct counts by iterating categories
SumOfCategoryCustomers =
SUMX(VALUES(ProductCategory[Category]),
 CALCULATE(DISTINCTCOUNT(Events[CustomerKey])))
SUMX is an iterator: it evaluates an expression for each row of a table and sums the results. When a model measure such as [UniqueCustomers] is evaluated inside SUMX, context transition is automatic; the CALCULATE context-transition rules matter when a raw expression is evaluated in row context. For January, the expected membership result is 4. That answers “how many customer-category memberships?” rather than “how many unique customers?”
Do not overwrite UniqueCustomers with the additive expression. Keep the unique-customer measure and, if approved, add a separately named membership measure. The model then exposes two different business quantities instead of disguising one as a total fix.
Treat BLANK and Empty Results as Different Cases
So far we assumed every event has a non-blank customer. What if that is not the case? Suppose we add a 6th event in January with a blank customer (i.e. CustomerKey = BLANK) in category P2:
EventID | CustomerKey | ProductCategory
--------------------------------------
6 | (blank) | P2
P2 now contains {B, C, BLANK}. The raw DISTINCTCOUNT measure treats BLANK as one distinct value, so the expected assertions are:
Category P1: still {A, B} → 2.
Category P2: {B, C, BLANK} → 3 (because BLANK is counted).
Grand Total: {A, B, C, BLANK} → 4.
The raw measure is expected to show P1 = 2, P2 = 3, and Total = 4. If the agreed customer definition excludes missing identifiers, KnownCustomers is expected to remain P1 = 2, P2 = 2, and Total = 3. The excluded event must still remain visible in a data-quality count; excluding its identifier from the business metric does not erase the event.
An empty filter context is different. When no rows qualify, DISTINCTCOUNT returns BLANK. A report can display that BLANK as zero, but that is a presentation policy. It must not be confused with the identity rule for an event whose CustomerKey is actually BLANK. Record the raw result and the display result separately.
Keep Unknown Dimension Members Visible
A missing dimension match is another distinct condition. The VALUES documentation explains that VALUES can add a blank member when referential integrity is violated. That relationship-generated unknown member is not the same as an actual blank CustomerKey in the fact. Keep unmatched fact keys visible and count their affected events separately; do not silently merge several unknown identities into one customer.
Treat blank or unmatched keys as an explicit policy and data-quality boundary. The customer metric can exclude them, include one unknown bucket, or remain on hold, but the reconciliation ledger must still show how many events and source keys are unresolved. DISTINCTCOUNTNOBLANK is available, yet choosing it changes the eligibility rule and still does not repair unmatched relationships.
Decide Whether an Additive Measure Is Actually Required
After exploring the intentional distinct-customer count, revisit the question: Does the stakeholder actually need an additive number? If yes, that is a different metric, not a “fix” of this one. For example, they might actually want the number of customer-category memberships. We already drafted it as SumOfCategoryCustomers. Another clean formulation is:
MembershipCount =
SUMX(VALUES(ProductCategory[Category]),
 [UniqueCustomers])
The expected January result is 4 because the measure counts two memberships in P1 and two in P2. It is additive across the approved category grain, but it answers “How many customer-category memberships exist?” rather than “How many unique customers exist?”
It’s important to document this alternative measure explicitly. We should label it and use it only where appropriate. For instance, if a report is intended to show “memberships,” we use MembershipCount; if it’s “unique customers,” we use UniqueCustomers. We should not silently replace a unique-customer measure with an additive hack without telling users. Instead, create and name it for clarity. For example,
Distinct Customer-Category Memberships = SUMX(VALUES(ProductCategory[Category]), [UniqueCustomers])Apply a clear name, tooltip, and owner-approved definition. There is no universal formula that should force every visual total to equal the visible row sum; the correct expression depends on the business quantity being requested.
To summarize, the choice is:
Use UniqueCustomers (DISTINCTCOUNT in the fact) if you indeed want one count per customer. This measure’s total is intentionally not the sum of parts.
Use an explicitly defined additive measure, such as MembershipCount, when the approved quantity is customer-category memberships.
Each must have its own name and explanation.
Test Product Filters and Drill Levels
Evaluate both measures under controlled product filters and at every supported grouping level. In this fixture, the expected assertions are:
P1 only: UniqueCustomers = 2 and MembershipCount = 2.
P2 only: UniqueCustomers = 2 and MembershipCount = 2.
P1 and P2 together: UniqueCustomers = 3, while MembershipCount = 4.
P3 with no events: the raw UniqueCustomers result is expected to be BLANK. A presentation measure may display zero only if that policy is approved.
At any hierarchy level, the oracle must group at exactly the same grain as the visual. The semantic question remains the same even when teams revisit broader BI platform choices; this laboratory remains scoped to Power BI and its filter context.
For each filter state, calculate the oracle set first, then record the actual DAX output from Power BI Desktop. Matching the P1 oracle {A, B} with an output of 2 would satisfy that assertion; the article does not claim that Desktop observation has already been recorded.
These tests reaffirm that the measure does exactly what it’s defined to do. It does not do something else because of visualization trickery. It’s important not to let a visual piece of formatting hide the measure logic. For instance, if a card shows “3” for total and a table shows (2,2), one might mistakenly think it’s “correct” or “wrong” based on alignment. Always consider the measure formula and filter context, not just coincidentally equal numbers. The rule of thumb is: similar-looking values under one filter do not prove equivalence of measures (the eventual 3 vs 4 difference will surface under a different filter or combined context).
Do Not Let a Visual Hide the Metric Change
Make sure to always display measure names in reports (tooltips, chart legends, or a small key) so users know which metric they are looking at. If you accidentally apply the new MembershipCount measure without relabeling, a user might be misled. For instance, in one filter state (say, Product=P1) both UniqueCustomers and MembershipCount give “2”. If the user only sees “2” and doesn’t know which measure it is, they could assume the formula is unimportant. Always annotate the report (e.g. in a table header or footnote) to clarify “Unique Customers (count each customer once)” vs. “Total Memberships (sum of category counts)”. Don’t let identical numbers in a subset hide the difference in definition.
Repeat the Test Across Overlapping Time Periods
The January oracle established three known customers. Extend the fixture with two February events:
EventID | CustomerKey | ProductCategory | EventDate
---------------------------------------------------
7 | A | P2 | Feb
8 | D | P1 | Feb
In February alone, the customers are {A, D}. That’s 2 unique. Notice A overlaps with January’s P1. We’ll test combined Jan+Feb:
January known customers: {A, B, C} → count 3.
February known customers: {A, D} → count 2.
Combined Jan–Feb known customers: {A, B, C, D} → count 4.
For the full January-through-February period, UniqueCustomers should be 4. The monthly rows are expected to show 3 for January and 2 for February, but their total is recalculated over the combined identity set and should be 4, not 5.
Adding the monthly counts 3 + 2 would count customer A twice. DISTINCTCOUNT must be evaluated over the union of the selected periods when the metric is unique customers across time.
We keep all date logic fixed. For example, we do NOT attempt to solve this by changing the measure to do something like INTERSECT or anything fancy. We simply ensure our DAX measure and oracle handle multiple months naturally via context.
For February alone, P1 contains {D} and P2 contains {A}. Across January and February, P1 contains {A, B, D}, P2 contains {A, B, C}, and the all-category union is {A, B, C, D}. Re-run the independent oracle:
events_extended = [
 ('Jan', 'P1', 'A'), ('Jan', 'P1', 'A'), ('Jan', 'P1', 'B'),
 ('Jan', 'P2', 'B'), ('Jan', 'P2', 'C'),
 ('Feb', 'P1', 'D'), ('Feb', 'P2', 'A'),
]

jan = {customer for month, category, customer in events_extended if month == 'Jan'}
feb = {customer for month, category, customer in events_extended if month == 'Feb'}
combined = jan | feb

print('Jan:', sorted(jan), 'count', len(jan))
print('Feb:', sorted(feb), 'count', len(feb))
print('Combined:', sorted(combined), 'count', len(combined))
The executed Python oracle returns:Jan: ['A', 'B', 'C'] count 3
Feb: ['A', 'D'] count 2
Combined: ['A', 'B', 'C', 'D'] count 4The independent oracle was executed during preparation of this document. The Power BI measure should match these assertions when the same rows, relationships, data types, and date filters are used; record the actual Desktop result before approval.
The combined total removes the month grouping but retains the selected date range. No special time formula is required for this fixture. A mismatch should place the decision on hold until filters, relationships, and data are reconciled.
Build a Reconciliation Matrix That Can Fail
Create a reconciliation matrix that stores the following evidence for every filter state:
Filter state: all active product, date, and eligibility filters.
Expected identity set: the independent oracle output.
Expected cardinality: the size of that identity set.
Diagnostic alternative: an intentionally wrong row, category, or period sum.
Expected DAX output: the assertion to compare with the recorded Desktop result.
Blank policy: the raw BLANK behavior and any separate display-as-zero rule.
Decision: accept, clarify, repair, or hold.
For example:
Filter State | Expected Set | Expected Count | Diagnostic Alternative | Expected DAX | Acceptance Note |
P1 only (January) | {A, B} | 2 | Not applicable | 2 | Expected match |
P2 only (January) | {B, C} | 2 | Not applicable | 2 | Expected match |
P1 + P2 (January) | {A, B, C} | 3 | 4 pairs | 3 | Reject 4 for unique customers |
P3 (no events) | {} | 0 | 0 | BLANK | Display zero only by policy |
All categories, Jan + Feb | {A, B, C, D} | 4 | 5 (monthly total sum) | 4 | Reject monthly sum 5 |
The diagnostic value 5 is the unapproved sum of January and February totals, 3 + 2. It is not the distinct union across the two months.
The matrix deliberately includes alternative values that can look reasonable. Four is the category-membership count for January, while five is the sum of monthly unique-customer counts. Neither is the all-category, all-period unique-customer union. A test pack that cannot distinguish those quantities is not strong enough to approve the measure.
For P3 with no events, the oracle cardinality is zero while the raw DISTINCTCOUNT result is expected to be BLANK. If the visual displays zero, record that as presentation behavior rather than rewriting the identity policy.
The matrix must be able to fail. If the recorded January all-category output is 4 instead of 3, reject it as a unique-customer result and investigate whether the wrong measure, wrong filter, or wrong model population was evaluated.
Test Equal Numbers With Different Definitions
It’s worth noting that we could accidentally create a test scenario where two different measures happen to give the same number, potentially fooling a naive check. For example, if each customer were in only one category (no overlap), then sum-of-categories would numerically equal the distinct total. One might mistakenly think “the formula works.” But this would be a coincidence. We must test overlapping cases (as we did with January) to be sure. If the matrix test had only non-overlapping data, we would never see a mismatch. By explicitly testing an overlapping scenario (customer B in both P1 and P2), we ensured the two measures diverged and our test could catch it. This reinforces that our reconciliation must include overlapping cases to be valid.
Separate Data Defects From Correct Non-Additivity
Whenever totals don’t add, we first check for data/model errors before blaming measure semantics. Here’s a quick triage:
Duplicate or missing fact rows? Confirm that each EventID appears once and that the fixture contains every expected event. A bad merge can multiply the fact population; use the separate join-cardinality and duplicated-row diagnosis when that mechanism is suspected.
Relationship or filter errors? Verify that the Customer, ProductCategory, and Date relationships are active, one-to-many, and single-direction as declared. An inactive relationship or an incorrectly configured filter direction can change the evaluated population.
Identity policy? Confirm how to treat blanks and duplicates as above. If the business decided to exclude certain customers, we must implement those rules.
Intended non-additivity? If the fact, relationships, filters, and identity policy all match the contract, an overlapping DISTINCTCOUNT total is working as defined.
We never “fix” non-additivity by dropping legitimate data. For example, we wouldn’t eliminate the duplicate count of B in P2 just to make 2+2=4. That would change the metric. The proper “fix” is to clarify the definition: if they want 4, they need the membership measure instead, or rename the metric. Unintentional defects (like a bad merge) require a real fix, not just a DAX hack.
For every discrepancy, record the cause and the action: repair a proven data or model defect, clarify a different business quantity, or accept the non-additive union. Keep the decision on hold when the evidence does not identify which condition applies.
Approve the Metric With the People Who Use It
Now that we’ve traced the logic, align with stakeholders. The metric needs a home: a definitive business definition, technical implementation, and examples. Steps:
Write a clear metric definition: e.g. “Number of distinct customers who made at least one event in the selected categories (each customer counted once in total).” Document this in a semantic layer, data dictionary, or report tooltip.
List known-answer examples from the fixture: in January, customers A, B, and C produce UniqueCustomers = 3, not 4, because B appears in both categories.
If an additive alternative is required, define it separately. Customer-Category Memberships counts each customer once per category; the January fixture therefore produces four memberships: A and B in P1, plus B and C in P2.
Get owner sign-off: Have the business confirm they understand which metric is which, and where each is used. The distinct-customer total might go on a “Customers Dashboard,” whereas the memberships total might be for a “category spread analysis.”
Place the approved definition in the report tooltip, data dictionary, or semantic-model documentation. Governed self-service analytics depends on consumers seeing consistent metric names and definitions. The unique-customer and membership measures must remain distinguishable wherever they are displayed.
Write the Total Explanation Beside the Measure
Write a plain-language explanation beside the measure. For example: “Unique customers counts each customer once across all selected categories. A customer present in both P1 and P2 contributes one to the total.” This explanation should accompany cards, matrices, exports, and stakeholder sign-off so that the lower union total is not mistaken for missing data.
Version the Measure and Its Known-Answer Tests
Treat these measures and tests like code. Each approved measure should have:
A version or date (e.g. in a repository or model documentation).
The exact DAX definition recorded (with any filters or parameters).
The test cases: each filter context, expected set, and expected result (like our reconciliation table).
Re-run the known-answer pack after changes to facts, relationships, dimensions, measure expressions, or visual filters. Add a case for every new supported category or hierarchy level. Retain the previous approved measure definition so the team can compare outputs and perform a controlled revert if a change fails.
The tests can later be automated, but the minimum record is tool-independent: model version, fixture version, DAX expression, filters, expected sets, expected counts, actual results, reviewer, and decision. Store that evidence in the model repository or BI governance log.
This playbook does not prescribe a deployment platform. Its purpose is to make the approved measure and its assertions reproducible so a future reviewer can evaluate the same contract against changed data or model versions.
Accept, Clarify or Repair the Total
Use the final evidence to choose one of three outcomes:
Accept the union count: the business definition is unique customers, and the model output matches the independently derived identity sets.
Clarify the additive requirement: stakeholders need customer-category memberships, so add a separately named SUMX measure and retain the unique-customer measure for union questions.
Repair the data or model: a fact, key, relationship, filter, or eligibility defect is proven. Correct it, rerun every assertion, and keep the release on hold until the evidence passes.
The minimum evidence differs by path. Acceptance requires an owner-approved definition plus matching oracle and Desktop results. Clarification requires sign-off on the new quantity and display locations. Repair requires evidence of the defect, the correction, and a complete passing rerun.
In all cases, the outcome is not “a magic new formula” but a clear contract:
Scenario | Outcome |
Distinct customers intended | Accept the measure; document the union definition and evidence. |
Category memberships intended | Clarify the definition; add a separately named SUMX measure. |
Data or model error proven | Repair the defect, rerun the full test pack, and then decide. |
The objective is not a cosmetic formula that makes every total equal the visible row sum. It is a documented metric contract whose population, identity policy, grouping behavior, and known-answer tests support the decision.
To strengthen the modeling, reporting, and KPI foundations behind this kind of review, explore Refonte Learning’s Business Intelligence Program. The three-month program lists Power BI, Tableau, Excel, and SQL-based platforms, together with data analysis, visualization, reporting, data warehousing, SQL for BI, and KPI monitoring. The stated commitment is 8–10 hours per week, providing a structured foundation for teams that build and review BI metrics.