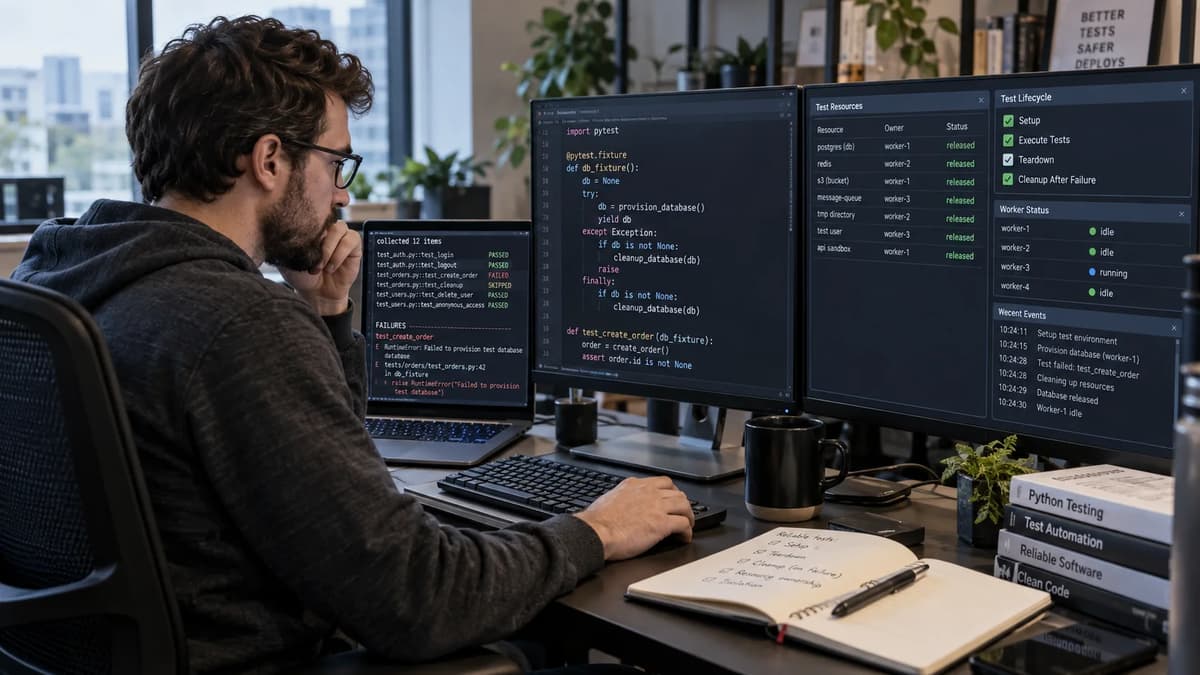
A passing pytest run is not enough proof that all test-created resources were cleaned up. A fixture that creates a database row or cloud tenant may fail halfway and never delete that resource. Rerunning the test until it passes is not a fix. A green result can hide an orphaned resource or unnecessary cost.
Define success as a complete lifecycle for every test-owned resource. Every resource marked created during setup must be released or explicitly retained. Track created (allocated), owned (cleanup registered), released (cleanup confirmed), and unresolved (still present). Any resource left created or unresolved when the run ends is a failure. This boundary extends Refonte Learning’s QA automation practices and test isolation by handling partial fixture failures and orphaned resources explicitly.
We focus on fixtures that fail before yielding a value, when a resource may already exist but normal teardown has not been established. Pytest’s handling of yield-fixture errors states that teardown code after that fixture’s yield is not run, while fixtures that completed setup are still torn down normally. A ledger that persists outside the worker lets us compare created and released resource IDs instead of inferring cleanup from the test result. This playbook covers acquisition, ownership registration, teardown, and recovery after abrupt termination, with outcomes of Accept, Refactor, Quarantine, or Hold. Pytest’s flaky-test guidance also links uncontrolled system state and inadequate isolation to intermittent failures, reinforcing the need to isolate and clean test state.
Define success as a reconciled resource lifecycle
Each resource created by a fixture must either be explicitly released or deliberately retained. Table 1 defines the resource states we track. Ideally, right after creation we register a cleanup (finalizer) to mark the resource owned. During teardown or normal test completion, an owned resource should move to released. If a resource never reaches released (for example, the fixture failed before yielding and no cleanup ran), it ends up unresolved. A test only truly passes if every created resource is eventually released. Any mismatch is flagged. For example, if a fixture failed midway and left res123 as created with no finalizer, that ID remains in the ledger as unresolved. We reconcile each created ID against its deletion evidence; any leftover IDs trigger investigation.
State | Description | Next/Cleanup Action |
Created | Resource allocated during setup (before yield) | Register a cleanup callback (e.g. via request.addfinalizer or yield fixture) |
Owned | Cleanup callback has been registered for the resource | Teardown is scheduled; release still requires confirmation |
Released | Resource deletion confirmed (cleanup succeeded) | None; the resource is gone |
Unresolved | Resource exists but no cleanup happened | Requires external recovery (leak) |
Table 1: Resource lifecycle states and expected cleanup actions.
Pin the test environment and sandbox service
Consistent tooling and a safe resource namespace are critical. Pin the laboratory to CPython 3.14.x and record the exact installed pytest, pytest-xdist, and dependency versions in the run manifest. An invocation such as pytest -n 2 --maxfail=1 -q exercises two workers. Use a durable file-backed ledger or local service outside worker processes so create and release records survive worker exits. Confine operations to a disposable run/worker namespace, and enforce an explicit hard cap of 50 synthetic resources in this example. The table summarizes the required manifest and sandbox controls:
Component | Value / Example |
Python interpreter | CPython 3.14.x; record the exact patch version |
pytest framework | Record the exact installed version |
pytest-xdist | Record the exact installed version |
Invocation | pytest -n 2 --maxfail=1 -q |
Resource ledger | Durable file-backed ledger or local service outside workers |
Namespace prefix | res-{testrun}-{worker}- |
Max resources | 50 per synthetic run (example cap) |
Table 2: Pinned test environment and sandbox ledger configuration.
This mirrors Refonte’s Python backend testing foundations emphasis on explicit, reproducible test environments. Our synthetic service never touches real customer accounts or cloud; it only creates disposable dummy IDs and logs them along with the owning run/worker identity.
Trace setup, yield and finalization as separate events
Treat each fixture’s setup, yield, and teardown as separate phases. Suppose Fixture A yields after creating resource A, then Fixture B raises before its yield. Under pytest’s yield-fixture error handling, pytest attempts A’s teardown but does not run code after B’s unreached yield. If both fixtures yield and the test later fails, pytest tears them down in reverse order. Think of each fixture as a mini-protocol (setup, test, teardown), much like Refonte Learning’s browser automation protocol boundaries distinguish phases in a browser session. Table 3 summarizes the expected teardown attempts:
Scenario | Resources Created | Teardown Attempted |
A yields, then B fails before yield | A, B | Cleanup A only (B skipped) |
A fails before yield (first fixture) | (none or partial) | None (no fixture yielded) |
A yields, B yields, then test fails | A, B | Cleanup B then A |
Table 3: Fixture execution scenarios and expected cleanup calls.
For each successful setup or yield, logs should capture a resource ID or setup-complete event. An attempted teardown invokes the post-yield code or registered finalizer in reverse order, but an invocation is not proof of deletion. Correlate each teardown attempt with its setup event and a release acknowledgment. Pytest’s fixture instantiation order depends on scope, dependencies, and autouse behavior, not textual declaration order, so cleanup reasoning should follow the declared fixture graph.
Reproduce a partial acquisition before yield
Let’s build a minimal example. In conftest.py we create a fixture that acquires two resources then fails before yielding:
# conftest.py
import pytest
class DummyService:
ledger = []
def create(self, owner):
rid = f"res{len(self.ledger)}"
self.ledger.append((rid, owner))
print(f"Created resource {rid} for {owner}")
return rid
def delete(self, rid, owner):
if (rid, owner) in self.ledger:
self.ledger.remove((rid, owner))
print(f"Deleted resource {rid} owned by {owner}")
@pytest.fixture
def fixture_with_fail(worker_id, testrun_uid):
owner = f"{testrun_uid}-{worker_id}"
svc = DummyService()
a = svc.create(owner)
b = svc.create(owner)
raise RuntimeError("Simulated setup failure")
yield b
svc.delete(a, owner)
svc.delete(b, owner)
# test_fail.py
def test_never_runs(fixture_with_fail):
# This assertion never executes because setup already failed.
assert False, "This should never run"
In this proposed synthetic example, DummyService.create prints and records each created ID. With worker_id="master", the fixture creates res0 and res1 for that owner, then raises. The yield is never reached, so no post-yield cleanup is registered or run. The class-level list is only an ordinary-exception demonstrator; worker-termination tests must use the durable ledger defined in the sandbox.
Run scenario | Resources created | Resources released | Unresolved |
Normal run (no failure) | res0, res1 | res1, res0 | (none) |
Setup failure | res0, res1 | (none) | res0, res1 |
Table 4: Created vs released resources in a normal run and in the setup-failure scenario above.
Observe the resource created before the exception
After the ordinary setup failure, the synthetic ledger contains the created IDs. A worker-loss test must produce equivalent create acknowledgments in the durable ledger outside the worker. For this example, if worker_id="master", the expected entry is:
DummyService.ledger == [("res0", "master"), ("res1", "master")]
This expected state confirms that res0 and res1 were created and left behind during the ordinary exception path. The fixture never reached the cleanup lines after yield, so nothing was deleted. An in-process list can demonstrate this path while the worker remains alive, but it is not evidence for recovery after a hard process termination.
Prove the assertion never ran
Because the fixture raised before yielding, the test body did not execute at all. Pytest’s output will show only the setup error, not the “assert False” from test_never_runs. For example:
test_fail.py F [100%]
_________________________________ test_never_runs __________________________________
...
E RuntimeError: Simulated setup failure
No mention of assert False appears, confirming that the test body was skipped. The leaked resources (from the ledger) cannot be blamed on the test code, since it never ran. This cleanly separates setup failure evidence from test logic.
Prefer one safely managed acquisition per fixture
A better design is to have each fixture acquire at most one external resource, with its own cleanup. We refactor the example into two fixtures with a dependency:
@pytest.fixture
def resourceA(worker_id, testrun_uid):
owner = f"{testrun_uid}-{worker_id}"
svc = DummyService()
a = svc.create(owner)
yield a
svc.delete(a, owner)
@pytest.fixture
def resourceB(resourceA, worker_id, testrun_uid):
owner = f"{testrun_uid}-{worker_id}"
svc = DummyService()
b = svc.create(owner)
# Simulate an error during B's setup
raise RuntimeError("Resource B setup failed")
yield b
svc.delete(b, owner)
Here resourceB depends on resourceA. If resourceB fails before its yield, resourceA has already yielded and will register its teardown. Thus in cleanup, resourceA will be deleted, but resourceB was never released. Table 5 compares outcomes:
Scenario | Resources created | Resources released | Unresolved |
Fail in resourceB | A, B | A | B |
All succeed (control) | A, B | B, A | (none) |
Table 5: Resource sets for the refactored fixtures example. When resourceB fails, the ledger shows both A and B created, but only A gets cleaned (teardown for resourceA runs). B remains unresolved. In the normal (no-error) case, resourceB would yield and be cleaned first, then resourceA, leaving no unresolved resources.
This explicit pairing of one acquisition with one cleanup per fixture means that if a later fixture fails, earlier resources still have their cleanup scheduled. It is not enough to say “cleanup will happen eventually.” The evidence must show that it did.
Register finalizers and ExitStack callbacks at the right time
Register cleanup callbacks immediately after acquisition succeeds, never before. Pytest’s direct-finalizer guidance explains that once a finalizer is registered, pytest will run it even if the fixture later fails. Registering too early risks deleting an uninitialized, stale, or incorrectly owned identifier. The two patterns below show the boundary:
Incorrect: Register cleanup at fixture start.
@pytest.fixture
def bad(request):
svc = Service()
def cleanup():
svc.delete(resource_id) # resource_id not created yet
request.addfinalizer(cleanup)
resource_id = svc.create()
yield resource_id
Here the finalizer is added before svc.create. If the fixture fails after adding it, pytest will run cleanup with resource_id undefined or stale.
Correct: Register after creation.
@pytest.fixture
def good(request):
svc = Service()
resource_id = svc.create()
request.addfinalizer(lambda: svc.delete(resource_id))
yield resource_id
In this version, the finalizer is only registered once we have a valid resource_id. If svc.create() fails, we never register a cleanup at all, avoiding a bogus delete.
For multiple acquisitions, use Python’s ExitStack documentation when each acquisition exposes a context manager or explicit callback. Already-entered contexts are unwound if a later entry fails. For example:
import contextlib
@pytest.fixture
def multi_resources():
svc = Service()
with contextlib.ExitStack() as stack:
a = stack.enter_context(svc.acquire("A"))
b = stack.enter_context(svc.acquire("B"))
yield (a, b)
# On exiting the with, both a and b (if acquired) are cleaned in reverse order.
If acquiring B raises, ExitStack invokes A’s registered cleanup. It unwinds registered callbacks and context managers in last-in, first-out order on normal exit or exception. This protects resources that were successfully registered with the stack; it does not create an external janitor after a hard process kill.
Finalizer strategy | Behavior if setup fails | Recommendation |
Add at fixture start | Finalizer runs regardless; may delete wrong target | Avoid: register only after creation |
Add immediately after creation | Finalizer only exists if create succeeded | Preferred: cleanup matches the resource |
Using ExitStack (with-stmts) | Ensures any partial acquisitions are cleaned on exception | Good for multiple resources |
Table 6: Timing of cleanup callback registration. In practice, always pair each create() with its cleanup callback right away. This prevents registering teardown for a non-existent resource.
Make cleanup outcomes and cleanup failures observable
When cleaning up, never swallow errors or silence logs. Pytest will report a teardown error separately if a finalizer fails. For example, if a resource deletion fails with an exception, pytest shows it under “ERROR at teardown,” after any test outcome. Both the primary error (if any) and the cleanup error are visible. Table 7 summarizes possible scenarios:
Scenario | pytest result | Remaining resources |
Test passes, delete succeeds | Exit code 0 (pass) | none |
Test fails (setup or body), delete succeeds | Exit code ≠0 (fail) | none |
Test passes, delete fails | Exit code ≠0 (error) | resource remains |
Test fails, delete fails | Exit code ≠0 (errors) | resource remains |
Table 7: Outcomes for test and cleanup scenarios. In all cases, if a delete fails, pytest will indicate it. A failed cleanup leaves the resource in unresolved state. Crucially, a passed test does not excuse a leak, nor does a failed test hide a failed cleanup.
Make repeated cleanup safe for the owned resource
Design your cleanup to be idempotent within the owning context. If delete(id) is called twice by accident, the second call should not throw an unhandled exception if the resource was already removed by the same run. However, it should be an error if the missing ID belongs to another test run or worker. In other words, only treat “not found” as benign if the owner matches the current worker_id/testrun_uid. This ensures a finalizer retry doesn’t silently delete someone else’s resource. In practice, code the delete function to check ownership: if a resource is already gone or was never there, simply return or log a warning; if a resource exists but has a different owner tag, raise an exception (quarantine scenario).
Keep cleanup errors distinct from setup errors
Let pytest show cleanup errors explicitly. Do not wrap your teardown logic in a broad try/except that hides exceptions. For example, avoid:
try:
svc.delete(rid)
except Exception:
pass # Not recommended: hides deletion failures
Instead, let the exception propagate. Pytest will mark the test with an additional teardown error. For instance, you might see an output like:
E RuntimeError: Failed to delete resource res5
----------------------------- Captured teardown -----------------------------
Error while deleting resource res5 owned by master
This makes it clear that the resource is unresolved. In all cases, keep test failures and cleanup failures separate in logs. Retain stack traces or error messages for each. This dual-reporting is expected: an unresolved resource is just as important a failure signal as an assertion error, and must not be ignored.
Partition ownership across xdist workers and runs
Under pytest-xdist, fixture code runs in worker processes. Use the built-in worker_id fixture and testrun_uid fixture to tag resources. The worker identifier is typically gw0, gw1, and so on, or master when distribution is disabled; testrun_uid identifies the current test invocation. Combine them with a resource-specific suffix, for example f"myres_{testrun_uid}_{worker_id}_001". A session-scoped fixture can still execute in multiple workers, so its resources are not automatically global to the distributed run.
Identifier | Provided by | Scope of uniqueness |
testrun_uid | pytest-xdist fixture | Globally unique per entire test run |
worker_id | pytest-xdist fixture | Unique per worker process (or “master”) |
Resource suffix | Custom (e.g. counter) | Unique within one worker’s run |
Table 8: Ownership tagging for distributed tests.
Each resource name encodes the run ID, worker ID, and resource suffix. Pytest-xdist’s session-scoped fixture guidance explains that high-scope fixture code can execute in more than one worker. A genuinely shared resource therefore needs an explicit lock or external coordination mechanism; a session label alone is not a distributed lock.
Test concurrent runs without cross-run deletion
We must ensure that cleanup only targets resources belonging to the same test run. For example, imagine two isolated runs happening back-to-back or in parallel, with IDs RunA and RunB. RunA creates resources RunA-gw0-1 and RunA-gw1-2; RunB creates RunB-gw0-1 and RunB-gw1-2. A cleanup job for RunA must delete only RunA-* IDs, and leave RunB-* untouched. Table 9 illustrates:
Resource ID | Owner run | Delete by RunA? | Delete by RunB? |
RunA-gw0-1 | RunA | Yes | No |
RunA-gw1-2 | RunA | Yes | No |
RunB-gw0-1 | RunB | No | Yes |
RunB-gw1-2 | RunB | No | Yes |
(broad) Run*- | * | Prohibited (must filter by owner) | Prohibited |
Table 9: Resources created by two runs and which run’s cleanup should delete them. In practice, use the testrun_uid to filter. Never attempt a wildcard cleanup (e.g. delete_all(prefix="Run")) without checking ownership, because you could erase another run’s resources. Our ledger entries include the run and worker ID so reviewers (or automated tools) can easily spot if a cleanup call is targeting the wrong run. If any resource in the ledger does not match the current run’s UID, the cleanup should skip it (quarantine) and warn.
Recover after the worker cannot run teardown
A test process may be killed unexpectedly (e.g. SIGKILL, OOM, or manual termination). In such cases, no in-process cleanup will occur. We must prepare for this by external measures:
Stage | Action |
Before acquisition | Atomically write a pending intent with owner, run/worker identity, and an idempotency or request key |
After create succeeds | After a positive create acknowledgment, record the confirmed resource ID and ownership token |
Process kill | Keep the entry pending; query by request key and prove existence and ownership before deletion |
External cleanup job | Scan registry for stale entries (older than threshold), verify run is inactive, delete resources if owned |
Table 10: Durable registration and recovery strategy. By persisting intent and ownership externally (e.g. a service database), we have evidence of who owns a resource even if the worker dies.
Retain durable ownership evidence before risky work
Never rely on in-memory state for important cleanup. Before calling the resource service, durably record a pending intent containing the run ID, worker ID, ownership token, and an idempotency or provider request key. After a positive creation acknowledgment, update that entry with the confirmed resource ID. If the worker dies while the entry is still pending, do not infer that creation failed or succeeded. The reconciler must query the service by the recorded key, verify the owner, and keep the entry quarantined when the result remains uncertain.
Use a bounded external reconciliation job
Implement a dedicated cleanup process with explicit authorization that runs outside pytest after test runs. It should:
1. Query the registry for unresolved resources older than the approved age or lease threshold.
2. Check whether the owning test run and worker are still active.
3. Verify the resource ID and ownership token; delete only when the owner is inactive and the ownership match is exact, then mark the entry released.
4. Start with a dry-run inventory and compare the planned deletion set with the resource ledger before enabling deletion.
5. Log every decision, including skipped and quarantined resources, with run, worker, resource, and reason fields but no credentials.
This bounded job prevents unbounded leakage. Any resource whose ownership cannot be proved (missing registry entry) should be quarantined, not blindly deleted. Over time, this approach can recover from even hard crashes, provided there’s a well-justified policy (age or lease) for cleanup.
Build a failure matrix around acquisition boundaries
To make acceptance decisions, enumerate each failure point and its expected outcomes. Table 11 below summarizes common cases:
Failure point | Pytest outcome | Allowed unresolved | Evidence |
Before resource is created | Fixture error (E) | 0 (none created) | Setup traceback; empty ledger |
After create, pre-yield | Fixture error (E) | 1 unresolved | Ledger shows created ID; no teardown run |
In test body (post-yield) | Test failure (F) | 0 (cleanup should run) | Ledger empty if cleanup ok; teardown logs |
During teardown (cleanup) | Teardown error (E) | 1 (failed to release) | Pytest shows teardown error; ledger has ID |
Worker killed mid-run | Aborted/timeout/error | 1 (unknown) | External registry entry; resource exists |
Table 11: Failure modes, pytest results, and expected resource states.
Before create: No resource was made, so nothing to clean. The fixture’s traceback is the only output.
After create, pre-yield: One resource was created, but its fixture failed. Pytest marks an error, and our ledger will list that ID as created. The cleanup didn’t run.
In test body: All fixtures yielded. A test assertion error still runs teardown, so no resources should remain. The ledger should be empty (or only contain entries already cleaned).
Teardown failure: If cleanup throws, pytest reports it as a teardown error. The resource stays unresolved and is logged. Both the test result and teardown exception appear.
Worker kill: The run likely aborts. The ledger or registry has the last created ID (if logged). An external job will need to handle it.
By covering these cases, test reviewers can decide: Accept if no leaks; Refactor if fixture design made cleanup hard; Quarantine if leaks occurred despite correct ownership; or Hold if evidence is missing.
Check test datasets and temporary paths separately
Not all resources are equal. The pytest tmp_path fixture provides a temporary directory unique to each test function, but that local path is not a deletion contract for data stored in a database, object store, or remote service. Treat external test data as an owned resource: give it a run-specific name, register it in the ledger, and delete it explicitly. A fixture that creates a test database should drop only the database whose provenance and owner are verified. Do not rely on an unrelated pipeline or background script to clean it implicitly.
Resource type | Scope/Lifetime | Cleanup approach |
Local tmp_path | Temporary file system (per-test) | Managed by pytest as a local temporary directory; not a remote-resource deletion contract |
Test-created data | External store (DB, file server) | Must explicitly delete in teardown (use ledger) |
Generated datasets | Possibly large/persistent | Use namespacing (e.g. with testrun_uid); clean in finalizer |
Pipeline input/output | Usually external (e.g. cloud buckets) | Manage via API (with owner tags); do not leave behind |
Table 12: Handling local and external test data.
In data-intensive tests, the same ownership rule applies to testing data pipelines and datasets: test-owned data is temporary by policy even when the underlying storage is persistent. Verify who created a dataset, which run owns it, and when it was created before deleting it, so cleanup cannot reach production data.
Approve cleanup with a closed resource ledger
Before calling a test Accept, review the resource ledger and logs to ensure all created IDs have matching deletes (or justified retention). Possible decisions:
Accept: The ledger shows every created ID was deleted (no unresolved). No ledger entries unaccounted for.
Refactor: The design made cleanup complex (e.g. a single fixture creating multiple resources or combining test logic and setup). The code needs clearer ownership or simpler fixtures.
Quarantine: There are unreleased resources, but their ownership is unambiguous (they belong to this run/worker). Investigate manually or clean up outside the test, and mark the test as flaky until fixed.
Hold: The ledger is missing or incomplete, or an ID has no matching owner tag. Here we cannot safely proceed; manual investigation is needed.
In each case, preserve the run’s logs and the resource ledger (without any secret values) for traceability. This is essentially applying operational evidence and correlation to testing: correlate resource IDs with test run and worker IDs in your observability tools. As a concrete review question, ask: “For every external resource allocated by this fixture, is there a matching teardown registered immediately after, using the same owner context?” This ensures that the first side effect (creation) has an owner and a cleanup path.
Make fixture ownership a code-review requirement
Every fixture that performs an external side effect should immediately declare who owns that resource and how it will be cleaned up. For example, add a reviewer check such as:
Review checklist | Rationale |
After any resource allocation, is a cleanup callback registered with the same worker_id/testrun_uid context? | Ensures no leaks and correct ownership |
These review practices reinforce the automation-framework and CI/CD foundations described on Refonte Learning’s QA Automation Engineering Program page. Review the published curriculum to assess whether it matches your training goals.