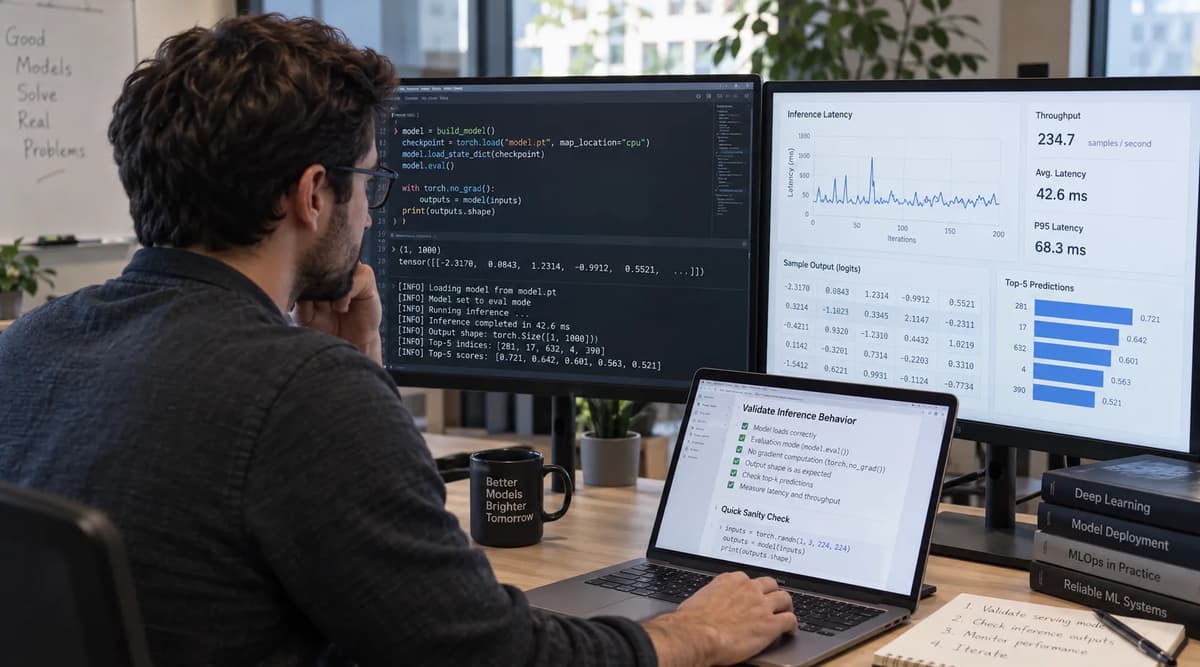
Deploying a machine-learning model means more than shipping code. The serving process must preserve a clear contract for preprocessing, checkpoint identity, module state, autograd context, and output interpretation. A process can disable gradient recording and still execute Dropout or update BatchNorm buffers because module evaluation state and gradient recording are independent controls.
The decision is not whether model.eval() or torch.no_grad() appears somewhere in the code. The decision is whether the worker that performs the forward pass produces acceptable raw outputs without unauthorized state mutation. The acceptance outcome is release, hold, or rebuild the serving instance. The examples below are reproducible test patterns, not transcripts of an executed production lab.
Define What Correct Serving Must Preserve
Write the serving contract before comparing tensors. Define the exact preprocessing specification, checkpoint digest, model definition, device, dtype, module flags, gradient context, output interpretation, and numerical tolerances. State whether the product expects deterministic evaluation or an explicitly authorized stochastic policy. According to PyTorch autograd mechanics, evaluation mode is distinct from gradient modes, so both must appear in the contract.
Expected invariants: Use the approved checkpoint and preprocessing. Confirm that Dropout, BatchNorm, and any custom stateful modules use the declared mode.
Allowed mutation: Name every buffer or counter that may change. For deterministic evaluation with tracked BatchNorm statistics, running_mean, running_var, and num_batches_tracked must remain unchanged during requests.
Acceptance threshold: Compare raw scores and state snapshots using declared tolerances. A stable class label alone is not sufficient evidence.
Decision rule: Release only when the running worker satisfies the contract. Hold unresolved cases. Rebuild any instance whose mutable state no longer matches the approved baseline.
This runtime audit complements the broader notebook-to-production workflow. It does not replace packaging, model-quality evaluation, monitoring, or rollback planning.
Pin the Model and Runtime Before Comparing Outputs
Capture the environment before running the mode matrix. Record the exact installed PyTorch patch and build string, Python version, operating system, CPU model, math libraries, process and thread settings, input dtype, preprocessing code version, model code version, checkpoint digest, and random seeds. The documentation baseline here is the versioned PyTorch 2.8 documentation; revalidate on the deployment build rather than treating documentation examples as evidence for another runtime.
Runtime identity: record torch.__version__, torch.version.git_version, Python, operating-system, and CPU-library details.
Execution settings: record device, dtype, interop and intraop thread counts, environment variables, and worker configuration.
Artifact identity: record an immutable model-code identifier and a SHA-256 digest for the checkpoint and preprocessing artifacts.
Randomness controls: record seeds and deterministic settings, while recognizing that fixed seeds do not guarantee bitwise identity across arbitrary hardware or runtime versions.
Use a manifest such as the following. Populate every value from the candidate deployment rather than copying sample values.
Manifest item | Required recorded value |
PyTorch build | Exact installed version, build suffix, and build configuration |
Python and operating system | Exact interpreter, operating-system, and architecture details |
CPU and math libraries | CPU model plus BLAS, MKL, oneDNN, or other relevant libraries |
Checkpoint digest | Full SHA-256 digest of the approved checkpoint |
Model and preprocessing code | Immutable commit, package version, or artifact identifier |
Thread settings | Exact intraop, interop, and worker-thread configuration |
Device and dtype | CPU device and the declared tensor dtype |
Seeds and deterministic settings | Recorded values plus any documented limitations |
Run the acceptance pack again inside the actual image or virtual machine that will serve traffic. This work belongs within AI and ML engineering responsibilities because it connects model behavior to the deployed runtime rather than assuming that an artifact behaves identically everywhere.
Build a Mode Matrix Instead of a Single Switch
Test module mode and gradient context as separate axes. The PyTorch Module documentation defines eval() as equivalent to train(False) for modules affected by training or evaluation behavior. It does not say that evaluation mode disables autograd. Test these five combinations on independently reset instances:
Training mode with gradient recording enabled.
Training mode inside torch.no_grad().
Evaluation mode with gradient recording enabled.
Evaluation mode inside torch.no_grad().
Evaluation mode inside torch.inference_mode().
For every row, record root and child training flags, torch.is_grad_enabled(), torch.is_inference_mode_enabled(), raw output tensors, and BatchNorm buffers before and after controlled forwards. The Dropout contract states that Dropout samples during training and acts as the identity during evaluation. The BatchNorm1d contract describes tracked running statistics and the evaluation-time exception when tracking is disabled.
Case | Dropout | Tracked BatchNorm buffers | Gradient enabled | Interpretation |
train + grad | Samples masks | May update | Yes | Training behavior |
train + no_grad | Still samples masks | May update | No | No backward graph, but training behavior remains |
eval + grad | Identity | Remain unchanged | Yes | Evaluation behavior with autograd available |
eval + no_grad | Identity | Remain unchanged | No | Common bounded inference path |
eval + inference_mode | Identity | Remain unchanged | No | Evaluation behavior with inference-only autograd restrictions |
The matrix exposes the misleading-success case: training mode plus no_grad can show that gradients are disabled while Dropout remains stochastic and BatchNorm continues updating tracked statistics. Disabled gradients therefore do not prove serving correctness.
Audit Child Modules, Not Just the Root Flag
Inspect model.named_modules() and record each child module's training flag. A root value of False is useful evidence, but it does not prove that custom code, functional calls, or manually reconfigured children honor the intended policy. A child can be deliberately switched back to training mode after the root call. Functional implementations may also use explicit training arguments that require separate review.
Accept: every relevant built-in and custom component matches the declared policy.
Hold: the root flag is correct but a child override or custom path is unresolved.
Rebuild: the executing instance was initialized with an unauthorized child configuration.
Create a Clean Reference Instance for Every Case
Start every matrix case from the same approved state. Do not run a training-mode probe and then reuse that object as the evaluation baseline. Training-mode forwards can change BatchNorm buffers even without an optimizer step or backward pass. Copy parameters and buffers, not just trainable weights, and capture the initial state ledger before the first forward.
import copy
import torch


def load_case(model_factory, approved_state):
    model = model_factory().to(device="cpu", dtype=torch.float32)
    model.load_state_dict(copy.deepcopy(approved_state), strict=True)
    return model


case_model = load_case(ModelFactory, approved_state_dict)
initial_state = copy.deepcopy(case_model.state_dict())
For each case, record parameter and buffer digests plus the initial values of running_mean, running_var, and num_batches_tracked. Then apply the selected module mode and gradient context. Dispose of the case instance after collecting evidence.
This isolation is separate from model-quality evaluation beyond serving mechanics. Runtime-state acceptance can show that the reviewed worker executes consistently, but it does not establish accuracy, calibration, fairness, or task suitability.
Keep the Toy Model Out of Accuracy Claims
A tiny CPU network with Linear, BatchNorm1d, Dropout, and another Linear layer is sufficient to expose mode-dependent behavior. Its nonzero inputs, synthetic checkpoint, and raw outputs are fixtures for execution semantics. Stable output from this fixture does not demonstrate useful predictive performance. Preserve that boundary in test names, review notes, and release evidence.
The fixture can establish | The fixture cannot establish |
Whether module flags match the serving contract | Real-world model accuracy or usefulness |
Whether tracked BatchNorm buffers mutate | Calibration or decision-threshold quality |
Whether the worker enters the intended autograd context | Cross-hardware bitwise reproducibility |
Whether raw outputs meet the declared local tolerance | Safety for consequential real-world decisions |
Expose Training-Time Dropout Without a Backward Pass
The documented Dropout behavior depends on module mode, not on whether a backward graph is recorded. Use multiple forward passes under training mode plus torch.no_grad() and inspect raw outputs. Do not reseed to the same value before every forward because that can conceal the stochastic path you are trying to detect.
model = load_case(ModelFactory, approved_state_dict)
model.train()

with torch.no_grad():
    train_outputs = [model(batch).detach().clone() for _ in range(8)]

# Expected assertion for this negative control:
# at least one pair of raw outputs differs beyond the declared tolerance.
Avoid a brittle assertion that every pair must differ. Independent masks can occasionally produce equal outputs, especially for small tensors or downstream layers that collapse differences. The robust control performs several forwards and requires evidence that training-time stochastic behavior is observable across the set.
model = load_case(ModelFactory, approved_state_dict)
model.eval()
with torch.no_grad():
    baseline = model(batch).detach().clone()
    for in range(2):
        candidate = model(batch).detach().clone()
        torch.testing.assertclose(
            candidate, baseline, rtol=declared_rtol, atol=declared_atol
        )
A passing evaluation comparison is evidence only for the tested inputs, runtime, and tolerance. It does not make arbitrary hardware or future versions bitwise reproducible. If the training-mode negative control also appears stable, hold the release because the test may be insensitive or the fixture may not exercise Dropout.
Check BatchNorm Buffers Before and After Inference
BatchNorm1d with tracked statistics owns mutable buffers. In training mode, a forward can update running_mean, running_var, and num_batches_tracked even when gradients are disabled. The BatchNorm1d documentation lists a default momentum of 0.1 and explains when running estimates are used.
Training-mode control: use a batch size above one and nonzero inputs selected to make a change observable. At least one tracked buffer should change across controlled forwards.
Evaluation acceptance case: load an independent clean instance, call eval(), and require all tracked BatchNorm buffers to remain equal to the initial snapshot.
Failure handling: if a serving candidate mutates tracked buffers, remove it from candidate traffic, preserve diagnostics, and rebuild from the approved checkpoint.
Do not publish fabricated before-and-after numbers. Store the actual tensor snapshots or stable digests produced by the deployment build. Lack of optimizer steps is not evidence that the instance stayed unchanged.
Test the Untracked-Statistics Exception
Use a separate control constructed with track_running_stats=False. In that configuration, BatchNorm1d does not maintain running-statistic buffers and uses current batch statistics during evaluation. Its running_mean and running_var values are None. Batch-dependent evaluation can therefore be intentional rather than a defect.
Do not alter a trained model's configuration merely to make an acceptance test pass. The control exists to prove that the test detects the documented exception. If the approved model intentionally uses untracked statistics, declare batch dependence in the serving contract and test it as such. If the setting is unexpected, hold the release and investigate the model definition and checkpoint provenance.
Choose a Gradient Context for the Actual Work
Choose the gradient context for the complete bounded serving path. torch.no_grad disables gradient calculation within its thread-local scope, with a documented exception for factory functions that create tensors requiring gradients. torch.inference_mode is also thread-local and adds inference-specific restrictions, including disabling view tracking and version-counter updates for tensors created in the context.
Question | Use no_grad when | Use inference_mode when |
Does downstream code require autograd later? | Possibly; validate the boundary explicitly | No; inference tensors must stay within the compatible path |
Is the path fully inference-only? | Allowed, but broader than necessary | A strong candidate after compatibility testing |
Does either context select evaluation mode? | No | No |
Does either freeze arbitrary Python state? | No | No |
Initialize module evaluation mode separately. Then enter the selected gradient context around the code that actually performs the forward and any compatible postprocessing. If downstream logic needs tensors that participate in autograd, test that requirement explicitly before choosing inference mode.
Enter the Context Where the Worker Executes
A context entered in the main thread is not an application-wide policy. The worker that runs the model must enter the intended context and record its actual state. The controlled thread demonstration below returns only mode metadata and a detached output for test evidence.
from concurrent.futures import ThreadPoolExecutor
import torch


def worker(model, input_tensor):
    with torch.inference_mode():
        output = model(input_tensor)
        return {
            "grad_enabled": torch.is_grad_enabled(),
            "inference_mode": torch.is_inference_mode_enabled(),
            "output": output.detach().clone(),
        }


serving_model = load_case(ModelFactory, approved_state_dict)
serving_model.eval()

with ThreadPoolExecutor(max_workers=1) as pool:
    evidence = pool.submit(worker, serving_model, batch).result()

assert evidence["grad_enabled"] is False
assert evidence["inference_mode"] is True
Run the negative control without the worker context and require it to report gradient recording enabled. If both cases report the same state, the test is not exercising the boundary you intend to approve. The thread-local behavior is part of the documented inference_mode contract, not a process-global switch.
Do Not Toggle a Shared Model Per Request
Create a dedicated serving instance, load the approved checkpoint, call eval(), audit relevant child flags, and expose it to concurrent requests only after initialization completes. Do not switch a shared object between training and evaluation around overlapping requests. Module mode is mutable state, and request-level toggling can make one request observe another request's policy.
Allowed: an immutable serving-mode policy established before the worker accepts traffic.
Review separately: custom caches, counters, mutable Python attributes, hooks, or state outside registered parameters and buffers.
Reject: per-request train/eval toggling on a model shared by concurrent work.
Test Repetition and Batch Composition Separately
Repeated-request testing and batch-composition testing answer different questions. Run both on independently reset instances and compare raw outputs, not only labels.
Repeated requests: send the same nonzero input through the evaluation path multiple times. Compare raw outputs with the declared relative and absolute tolerances and confirm that tracked buffers remain unchanged.
Permutation control: place the same example in differently ordered evaluation batches. With tracked BatchNorm statistics, its raw output should not change merely because peers moved.
Peer-composition control: compare the same example when paired with different peers. Training-mode BatchNorm or untracked evaluation statistics can make the result batch-dependent; tracked evaluation statistics should not.
Batch-size safety: use batch sizes above one for BatchNorm training controls. Treat an unsupported singleton training input as a fixture error, not as evidence about evaluation behavior.
Define thresholds from the approved baseline and runtime rather than copying a convenient constant. Keep latency and throughput of API endpoints as a separate performance concern. A fast response can still be semantically wrong, and a semantically stable result does not prove adequate throughput.
Make the Acceptance Tests Detect Real Failures
A test pack that only passes the intended case is not yet trustworthy. Run negative controls from clean instances and require each one to fail for the expected reason. Restore the approved state before moving to the next control.
Omit eval(): the repeated-output or buffer-stability checks should detect training behavior.
Omit the worker context: the worker-state check should report gradient recording enabled or inference mode disabled.
Contaminate a buffer baseline: the state digest or known-answer comparison should reject the instance.
Override one child module: the child audit should identify the mismatch even when the root reports evaluation mode.
Use an insensitive input: the control should reveal that the fixture cannot expose the intended failure, prompting a fixture change rather than a false release.
Record the expected failure category and the observed category. A failure for an unrelated reason does not validate the control. For example, a batch-shape error does not prove that the test detected active Dropout.
Separate Label Stability From Score Stability
A class label can remain unchanged while logits, probabilities, or buffers move materially. Include a misleading-success control in which the argmax label stays the same but raw scores or state digests differ. Then show that the score-level or state-level criterion blocks release.
Evidence | Can it approve release by itself? | Reason |
Same predicted label | No | Different raw scores can still cross later thresholds or alter ranking |
Stable raw scores within declared tolerance | Not alone | The instance may still have unauthorized buffer mutation |
Unchanged buffers | Not alone | The worker may still use the wrong gradient context or preprocessing |
Combined mode, output, and state evidence | Yes, for serving semantics | It addresses the declared runtime contract, not model quality |
Instrument Serving State Without Logging User Data
Record enough metadata to prove worker initialization and detect drift without logging private inputs or full prediction tensors. This is a focused application of operational evidence and observability: availability signals and semantic-correctness signals should be visible but kept distinct.
Safe field | What to record |
Model and checkpoint identity | Immutable version plus approved checkpoint digest |
Runtime identity | Exact PyTorch, Python, device, dtype, and worker build |
Worker initialization | Timestamp, pseudonymous worker ID, and initialization result |
Mode summary | Relevant module training flags, gradient state, and inference-mode state |
Buffer integrity | Approved and current digests or aggregate drift status |
Acceptance status | Pass, hold, or rebuild reason code without private tensors |
Operational health | Latency, errors, saturation, and availability kept separate from semantic checks |
Do not emit raw user features, identifiers, full logits, or model internals into routine logs. Store detailed known-answer tensors only in the controlled acceptance evidence store with appropriate access controls. An available worker is not necessarily a semantically correct worker, so keep both states reviewable.
Recover a Serving Instance That Mutated
When a serving candidate shows unexpected output drift or buffer mutation, remove it from candidate traffic. Preserve the runtime manifest, mode summary, before-and-after buffer snapshots, raw known-answer comparisons, and request-free diagnostic metadata. Do not continue probing the same instance in ways that overwrite the evidence.
Contain: stop routing candidate traffic to the suspect instance.
Preserve: capture state and runtime evidence without private request data.
Reconstruct: create a new process or instance from the approved code, checkpoint, and preprocessing artifacts.
Reinitialize: apply the serving module mode and worker gradient context before any acceptance forward.
Retest: run the complete mode, worker, output, and state pack, including negative controls.
Calling eval() after contamination does not restore earlier BatchNorm values. Evaluation mode prevents further tracked-statistic updates in the intended path, but it does not reverse mutations that have already occurred. The recovery unit is a clean serving instance, not a late flag change.
Verify the Restored Baseline Before Release
Compare the reconstructed instance with the approved artifact, never with the contaminated live object. Verify parameter and buffer digests, preprocessing identity, module flags, worker gradient state, and known-answer outputs. Apply the same declared tolerances used for the original candidate.
Recovery check | Required result |
Checkpoint and preprocessing digests | Match the approved release record |
Parameter and buffer state | Match the approved initial baseline |
Root and child module flags | Match the declared serving policy |
Worker autograd state | Matches the chosen no_grad or inference_mode contract |
Known-answer raw outputs | Within the approved runtime-specific tolerance |
Negative controls | Fail for the intended reasons |
Review the Evidence Across the Deployment Boundary
Package the evidence so another reviewer can reproduce the decision. Include the environment manifest, artifact digests, model definition, preprocessing specification, mode matrix, child-module audit, worker-context results, raw known-answer comparisons, BatchNorm snapshots, negative-control outcomes, and cleanup record.
Rerun when the PyTorch patch or build changes.
Rerun when Python, CPU libraries, dtype, hardware, thread settings, or serving framework changes.
Rerun when the model definition, checkpoint, preprocessing, postprocessing, or batching policy changes.
Document limits: CPU eager results do not automatically transfer to CUDA, compiled, exported, distributed, or differently typed runtimes.
The reviewer should be able to tell which behavior is documented, which assertion is derived from the serving contract, which test was executed, and which limitations remain. Keep the evidence tied to an immutable deployment candidate rather than to a generic claim that the model was once evaluated.
Release, Hold or Rebuild the Serving Instance
Make the decision from the declared contract and the evidence generated by the executing worker. Do not treat a green request, a disabled gradient flag, or a root training=False value as sufficient on its own.
Decision | Evidence condition | Required action |
Release | Approved artifacts; correct root and child modes; intended worker context; stable raw outputs; no unauthorized buffer mutation; negative controls behave as designed | Admit candidate traffic and retain the evidence pack |
Hold | Evidence is incomplete, thresholds are undefined, worker state is ambiguous, or a discrepancy remains unexplained | Do not release; repair the test or configuration and rerun from a clean baseline |
Rebuild serving instance | The candidate mutated, loaded the wrong state, or executed with an unauthorized mode or worker context | Remove it from traffic, preserve diagnostics, reconstruct from approved artifacts, and rerun acceptance |
Minimum release evidence consists of immutable artifact identity, a complete mode audit, worker-local gradient or inference status, raw-output comparisons within declared tolerances, unchanged protected buffers, and negative controls that fail for the intended reasons. These findings approve serving semantics for the tested deployment build; they do not establish real-world model quality.
The Refonte Learning AI Engineering Program covers building, training, evaluating, deploying, and scaling AI models, including neural networks and deep learning. Its published FAQ names PyTorch, TensorFlow, and Keras, and the page lists a three-month format at 12-14 hours per week. Use those foundations to place runtime acceptance work within the broader engineering lifecycle; participation does not by itself certify a production serving instance.