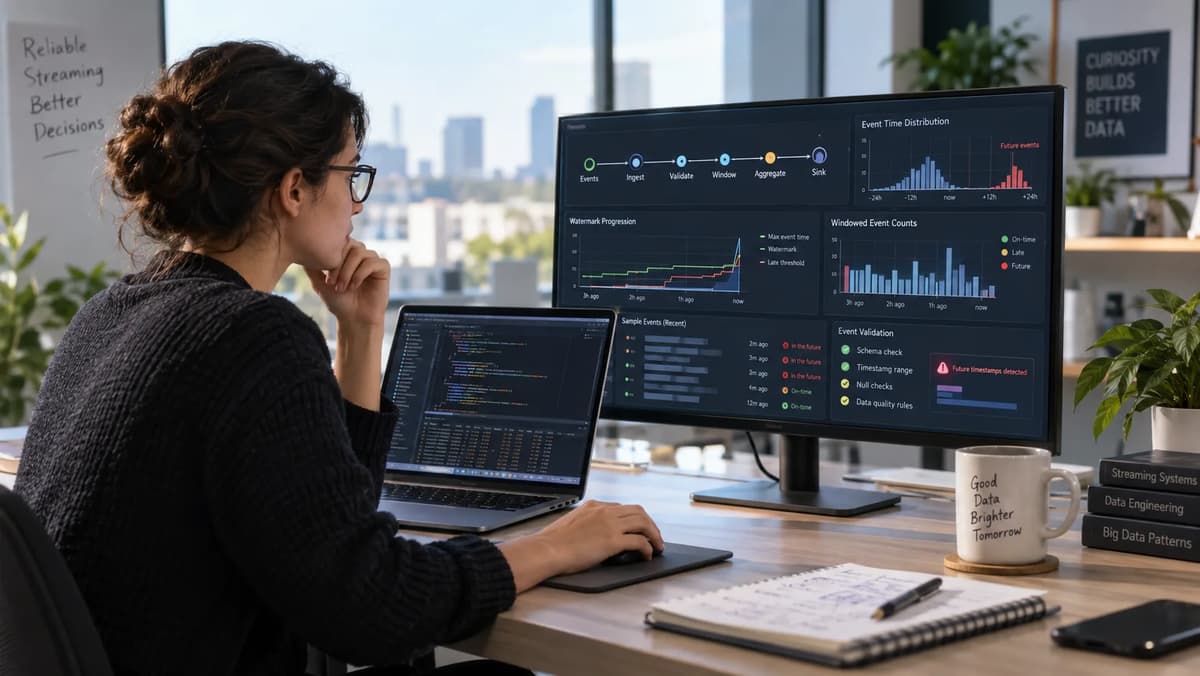
Real-time streams can fail silently if an implausible event timestamp skews watermarks, closing windows too early. In our synthetic streaming lab, we run two identical Spark Structured Streaming pipelines: one without any timestamp guard and one with an explicit validation rule before applying withWatermark. In both runs, a single future-dated record appears. We track each record’s raw event time, a stable ingestion timestamp, window grouping, and emitted aggregates. The goal is to preserve the intended aggregation (the set of events that meet business criteria) while quarantining any outliers. We will decide whether the late event should be accepted (and thus possibly disrupt state), quarantined (prevented from impacting the aggregation), held (delay publishing results), or rebuilt (recompute using a clean checkpoint). No actual query runs have been executed yet; this playbook lays out how to test and trace the behavior systematically.
Define the aggregate and the result you must preserve
Begin by naming the metric to compute and the data it should include. For example, suppose our business logic is “count sales by 10-minute event-time windows.” The data has a sale_time timestamp column and a value field, grouped by product_id. The production owner is Alice and the reporting approver is Bob. Normally we assume events arrive late by at most 5 minutes. We then define “future-dated” as anything more than, say, 1 hour ahead of ingestion. The outcome of our policy is as follows:
Aggregate Key | Event-Time Column | Window Duration | Value Field (counted) | Output Mode | Owner / Approver |
SalesCountBy10min | sale_time (TIMESTAMP) | 10 minutes (event-time tumbling) | sale_value | Append (no updates) | Alice / Bob |
Business rule: Only sales where sale_time is within [ingestion_time - 5 min, ingestion_time + 1 hr] are valid. Others are quarantined.
Approve/Quarantine/Hold/Rebuild: If the future-skewed records are validated, we hold publishing until resolved. If they are rejected early, we publish normally. If published output already dropped an expected record, we rebuild.
This fixture is narrower than a generic tutorial: it focuses on whether the window results contain exactly the intended events (from the immutable input). Do not compare different streaming technologies or cloud data pipelines here (for that see the cloud-native pipeline architecture overview). Instead, trace every event from raw input through to final output.
Freeze the timestamp contract and runtime manifest
Document the exact runtime environment and timestamp handling as part of data contracts and producer-owned timestamp rules. For Spark 4.0.1, record:
Spark and language: Apache Spark 4.0.1 with PySpark (Python 3.10). (Scala/Java versions aligned to 4.0.1.)
Session timezone: UTC (set via spark.sql.session.timeZone=UTC).
Event-time type: using SQL TimestampType by default (which in 4.0.1 means session-local time-zone, i.e. TIMESTAMP_LTZ, representing an absolute instant). (Alternatively, TIMESTAMP_NTZ yields a wall-clock value without zone, but we assume LTZ by default.)
Ingestion timestamp: A separate ingestion_time column, recorded at data arrival. We will not use current_timestamp() inside Spark (which could change on replay). Instead, we assign ingestion_time in the upstream producer or ingestion job and store it with the raw record.
Timestamp parsing: The raw event timestamp strings will be parsed strictly. Malformed or ambiguous strings count as parse failures and go to quarantine. (We do not silently interpret local-time variants.)
Watermark delay: We choose withWatermark("sale_time", "5 minutes") (allowing 5 min lateness).
Output mode: Append (so windows finalize once closed). We note Spark cannot drop old state in Complete mode.
Record these details in a small manifest or table, e.g.:
Setting | Value |
Spark version | 4.0.1 |
Python version | 3.10 |
Session timezone | UTC |
TimestampType used | TIMESTAMP_LTZ (absolute instant) |
Watermark column/delay | sale_time, 5 minutes |
Output mode | Append (final counts only) |
This locking down ensures any behavior (e.g. watermark calculations) is measured against a fixed contract. It also surfaces that Spark’s TIMESTAMP alias depends on session config, so we must note exactly which type we chose. We explicitly declare null, malformed, future, and normal event-times in our spec. (Any “filter by sale_time” we apply must also handle NULL properly; as SQL semantics say, WHERE condition only retains rows where the condition is true.)
Preserve an immutable raw ledger before admission
Before running any streaming job, save all incoming events in a raw, immutable store (e.g. files or a database). Each event gets a stable unique ID. For our synthetic test we might use a CSV or JSON file per batch. Include these columns per record:
RawID: a unique identifier for the event (e.g. a UUID or an autoincrement).
EventTimestampRaw: original timestamp string from the source.
ParsedEventTimestamp: the normalized TimestampType instant if the string is valid and in range. (Or null if unparseable.)
IngestionTime: the trusted time when the event was ingested (e.g. recorded by the ingestion job). This column is also a TimestampType value.
Payload: any other data (e.g. sale amount).
Classification: later we will mark each event as Accepted or Quarantined.
QuarantineReason: if quarantined, a code (e.g. NULL_TS, PARSE_FAIL, FUTURE_TS).
PolicyVersion: the version of the validation rules applied.
For example, one synthetic raw row might be:
RawID | EventTimestampRaw | ParsedEventTimestamp | IngestionTime | Payload | Classification | QuarantineReason | PolicyVersion |
a1b2 | 2030-01-01T12:00:00Z | 2030-01-01T12:00:00Z | 2026-09-19T12:00:00Z | 100 | Quarantined | FUTURE_TS | v1 |
Make sure every raw event is recorded, whether later accepted or not. This ledger is our ground truth. As recommended in best practices for raw-data governance, we do not delete these inputs. Store the classification results separately so raw data is unmodified.
Keep ingestion time stable during replay
When re-running or replaying batches, use the same IngestionTime values from the raw ledger. Do not re-evaluate current_timestamp() inside Spark, which could shift everything. For example, if an event was ingested on 2026-09-19T12:00Z, that exact timestamp is persisted. The classification (Quarantined or Accepted) must remain the same if we rerun the logic later. This is crucial for deterministic testing.
Make accepted and quarantined a complete partition
Our admission check should be exhaustive. In SQL this means using an explicit predicate and its complement. For example:
from pyspark.sql import functions as F

valid_condition = (
    F.col("parsed_ts").isNotNull()
    & F.col("ingestion_time").isNotNull()
    & (
        F.col("parsed_ts")
        <= F.col("ingestion_time") + F.expr("INTERVAL 1 HOUR")
)
)

classified = raw_events.withColumn(
    "classification",
    F.when(valid_condition, F.lit("Accepted"))
.otherwise(F.lit("Quarantined"))
)

valid_events = classified.filter(F.col("classification") == "Accepted")
quarantined_events = classified.filter(
    F.col("classification") == "Quarantined"
)
This way, every event goes into exactly one of valid or quarantined. Note: because SQL WHERE drops rows where the condition is unknown, a naive WHERE (parsed_ts <=..) would drop rows with parsed_ts IS NULL. We must explicitly classify null timestamps. In other words, avoid writing WHERE NOT (parsed_ts > buffer) alone; use parsed_ts IS NULL OR parsed_ts > buffer to catch nulls. As a check, the counts of valid_events + quarantined_events should equal the total raw count. Any duplication or omission is a test failure.
Explain the watermark without promising a deadline
Watermarks in Spark are event-time based, not wall-clock based. Conceptually, Spark tracks the maximum event timestamp seen so far and subtracts the configured delay. For example, if the highest event time seen is 2026-09-19T12:00:00Z and the delay is 5 minutes, the candidate cutoff is 11:55:00Z. However, due to coordination limits, Spark’s actual watermark for each micro-batch may lag behind this ideal. The documentation notes:
“The current watermark is computed by looking at the MAX(eventTime) seen across all partitions minus the delayThreshold… [B]ecause of the cost of coordinating this value… the actual watermark used is only guaranteed to be at least delayThreshold behind the actual event time.”
In practice, a sudden future-dated event can advance the candidate watermark sharply. Once Spark applies the reported watermark, older windows can be finalized in Append mode. A later eligible event for a finalized window may then be too late to contribute. Crucially, the guide emphasizes that the watermark guarantee is one-sided: setting a delay of 2 hours protects data delayed by less than that bound under the documented aggregation conditions, while data delayed by more than 2 hours may or may not be aggregated. In other words, the configured bound is a protection guarantee, not a promise that every older record is always discarded.
Also note: watermark logic only affects Append/Update modes. In Complete mode, Spark retains all state and does not remove any window data (so watermark-based cleanup doesn’t apply). Since we use Append mode, windows finalize once the watermark passes their end time. But we must not treat the delay as a strict SLA. It’s a tuning parameter, not a promise that “every record older than this is dropped.” Unexpected spikes or clock skew can cause earlier drops.
A simple illustration for a normal run (no future event):
Trigger | New events | Max Event Time | Watermark (prev trigger) | Output Windows Emitted |
1 | Events with times up to 12:04 | 12:04 | – (initially none) | None (watermark undefined) |
2 | More events up to 12:09 | 12:09 | 12:04–5m = 11:59 | None (waiting for window end) |
3 | ... | 12:14 | 12:09–5m = 12:04 | Window [12:00–12:10] closes, its count output |
If a future-skewed outlier arrives at 14:00, well ahead of the ordinary event times, then:
Candidate cutoff after the outlier: 14:00 - 5 minutes = 13:55.
After the 14:00 record is admitted, the maximum observed event time can raise the candidate cutoff to 13:55. The watermark reported and applied by a subsequent trigger must be captured from query progress; the calculation alone does not prove same-batch timing. If the reported watermark advances past the end of the 12:00-12:10 window, later eligible events for that window may no longer contribute under the documented watermark semantics.
Key point: The watermark delay is not measured from processing time. It is relative to the highest event-time seen. A spike in event-time can immediately trigger closing of many windows.
Create paired micro-batch fixtures with an outlier
Design controlled inputs for two runs. Use static file directories as sources, feeding one file per micro-batch to Spark. For example:
# Batch file: batch1.csv (first trigger)
RawID,EventTimestampRaw,IngestionTime,Payload
1,2026-09-19T12:00:00Z,2026-09-19T12:05:00Z,10
2,2026-09-19T12:02:00Z,2026-09-19T12:05:00Z,20

# Batch file: batch2.csv (second trigger; includes future outlier)
3,2026-09-19T12:04:00Z,2026-09-19T12:10:00Z,15
4,2026-09-19T14:00:00Z,2026-09-19T12:10:00Z,25    # future-dated outlier
# (Note: IngestionTime is fixed per batch, even if event times vary.)
# Batch file: batch3.csv (third trigger; normal events continue)
5,2026-09-19T12:06:00Z,2026-09-19T12:15:00Z,5
6,2026-09-19T12:08:00Z,2026-09-19T12:15:00Z,30
Each file contains events with unique RawIDs and fields matching our schema. In the control run, Spark reads batch1.csv, batch2.csv, batch3.csv without any filtering; the future outlier (RawID 4) is treated as just another event. In the guarded run, before watermarking we filter out any events beyond ingestion_time + 1 hour. Thus in batch2, RawID 4 is quarantined and never reaches the aggregation. Both runs use fresh checkpoints and separate output directories. Never compare a “new run” to a “dirty run”; each run’s state should start empty.
Expected aggregate (count per 10-min window): Without the outlier, the 12:00–12:10 window should have RawIDs 1, 2, 3, 5, 6 (count 5). With the outlier accepted, the watermark jumps and that window closes early, likely missing some of these events. With the outlier quarantined, the window should stay open until events 5 and 6 arrive. These inputs are simple enough that the expected count can be manually tallied. This fixture pinpoints exactly how the future timestamp affects window state.
Classify timestamps before the stateful operator
Implement the validation rule on each new batch before any watermark or aggregation. For instance, in PySpark pseudocode:
from pyspark.sql import functions as F

raw = (
    spark.readStream
.schema(input_schema)
.option("header", True)
.csv("input/path")
)

parsed = raw.withColumn(
    "parsed_ts",
    F.to_timestamp("EventTimestampRaw")
)

future_limit = F.col("IngestionTime") + F.expr("INTERVAL 1 HOUR")
valid_condition = (
    F.col("parsed_ts").isNotNull()
    & F.col("IngestionTime").isNotNull()
    & (F.col("parsed_ts") <= future_limit)
)

classified = parsed.withColumn(
    "classification",
    F.when(valid_condition, F.lit("Accepted"))
.otherwise(F.lit("Quarantined"))
)

valid = classified.filter(F.col("classification") == "Accepted")
quarantined = classified.filter(
    F.col("classification") == "Quarantined"
)
Important: Do not clamp or reset a bad event’s timestamp to “now”. That would silently hide the issue. The correct action for an outlier is quarantine it, preserving evidence of its original timestamp and origin. Also reject clearly malformed timestamps explicitly (they lead to parsed_ts IS NULL). In our example policy, the 14:00 event in batch2 is rejected because it is later than 12:10 plus one hour. This rule (1-hour future skew) is a lab example, not a Spark default.
Test boundary, null and clock-skew cases
Include edge cases in the fixtures. For example:
An event exactly 1 hour ahead of ingestion (event_time = ingestion_time + 1h). Is this in or out? (Our policy above includes it, using <=.) Verify it goes to valid.
One second beyond 1 hour, verify quarantine.
An event with no EventTimestampRaw (NULL), or an unparsable string, must be classified as quarantined (NULL_TS), not simply filtered out.
If IngestionTime were accidentally null (bug), all events would also quarantine; ensure IngestionTime is always filled.
Document each test in a small table, e.g.:
RawID | EventTime | IngestTime | Condition | Classification |
X1 | 12:00 + 1h | 12:00 | at boundary | Accepted |
X2 | 12:00 + 1h + 1s | 12:00 | 1s over | Quarantined |
X3 | NULL | 12:00 | missing time | Quarantined |
X4 | 12:02 | NULL | missing ingest | Quarantined (or fail) |
Run these as mini-batches to assert the classification logic works before moving to aggregation.
Distinguish source correction from timestamp clamping
Sometimes a future timestamp is due to an upstream clock error. We should never simply convert EventTime = Now() or similar. That would change the event’s meaning. Instead, if a producer can correct its timestamp and resend the event (with the same RawID) that could be ingested as a new valid event (and possibly deduplicated). But silent clamping inside Spark hides this workflow. Our test must flag the outlier for human/producer action, not pretend it was on time. For this lab, we’ll assume no source correction is happening; the outlier is quarantined and noted.
Observe state effects across actual trigger boundaries
With both pipelines running on the same inputs, record the query progress in each micro-batch. We capture fields like batch ID, number of input rows, maximum event time seen, and the watermark emitted (via StreamingQuery.lastProgress) for each run. For example:
Trigger | Control input IDs | Control max event time (expected) | Control reported watermark | Guarded input IDs | Guarded max event time (expected) | Guarded reported watermark |
1 | 1, 2 | 12:02 | Capture from progress | 1, 2 | 12:02 | Capture from progress |
2 | 3, 4 | 14:00 | Capture from progress | 3 | 12:04 | Capture from progress |
3 | 5, 6 | 14:00 (max so far) | Capture from progress | 5, 6 | 12:08 | Capture from progress |
This is a proposed capture table. Populate each reported watermark from the actual Spark 4.0.1 query-progress output; do not infer it from the event-time maximum alone.
In the control run, Trigger 2 admits the 14:00 outlier, so the maximum event time seen can move far ahead of the ordinary records. In the guarded run, that record is quarantined before watermarking, so the expected maximum remains 12:04 after Trigger 2 and 12:08 after Trigger 3. The actual reported watermark and the trigger in which it affects state are observations to collect, not values to invent.
Also capture state metrics: e.g. how many partitions/state entries Spark stores. In the Control run, state for earlier windows may purge sooner. If Spark’s UI is available, note “numStateRows” or similar. If not, logging the progress JSON is enough. Keep going until the watermark surpasses the window of interest. If by Trigger 3 both runs emitted the 12:00–12:10 window, the test can continue; if only one did, we have observed the difference. If not enough triggers occur (e.g. watermark stuck), mark the run inconclusive; do not assume behavior without evidence.
Reconcile every eligible event and emitted window
After running, build an oracle by replaying all raw events in batch mode with the same admission rule and aggregate logic (no streaming state). Compute, for each 10-minute window, the set of event IDs that should have been counted. Then compare this to what each streaming query actually output, using operational signals with enough diagnostic context to explain each difference. For example, a reconciliation table might look like:
Window Interval | Oracle IDs | Control assertion to verify | Guarded assertion to verify | Decision evidence |
12:00-12:10 | 1, 2, 3, 5, 6 | May omit 5 and 6 if the outlier advances state first | Should include all five eligible IDs | Compare actual ID membership with the oracle |
12:10-12:20 | No fixture events | No output expected before finalization | No output expected before finalization | Do not treat an open window as missing data |
This checks that:
The guarded-run assertion is that the 12:00-12:10 window contains exactly IDs 1, 2, 3, 5, and 6, for a count of five.
The control-run failure assertion is that IDs 5 and 6 may be absent if the outlier advanced the watermark before the third batch contributed. Flag every discrepancy by RawID, and separate records excluded by the approved policy from eligible records missing in the finalized output.
Distinguish delayed output from lost contribution
It’s possible an output is merely delayed (watermark not yet passed) rather than lost. Our table keeps “open” windows (like 12:10–12:20) separate. We only consider a window finalized when both runs output it. If the Control run’s watermark closed a window early, causing a final output, the Guarded run’s slower watermark might not have output that same window yet; this is not an error, just not ready. We ensure to compare only fully-closed windows between runs.
Turn the outlier into a regression assertion
Finally, codify the key expected behaviors as assertions. For example:
In the Guarded run, ID 4 (future outlier) is not counted in the 12:00–12:10 window.
In the Control run, IDs 5 and 6 (which had event times 12:06 and 12:08) are not included in the 12:00–12:10 window output.
The guarded run’s final count for [12:00-12:10] matches the oracle: five events.
Record these as expected versus actual outcomes for the lab. Do not fabricate successful log output; state what should happen, then attach the observations produced by the executed run.
Inspect the checkpoint before choosing a recovery path
Before deleting or rebuilding any state, pause and examine the checkpoint directory of the affected run. The checkpoint contains the query ID, committed offsets, state store, and the sink’s data info. Check which version of the query it corresponds to. If you only changed code (e.g. logic bug fix) but the checkpoint’s metadata shows a different query plan, Spark will refuse to restart it (per StreamingQuery restart rules.
Changes that require a full rebuild include: altering the watermark delay, changing the grouping or aggregation logic, or applying a new admission policy (since it affects historical results). If only unrelated config changed, you might resume.
Do not delete the live checkpoint as a routine repair. That can create data loss or duplicate publication. Use the query manifest, retained source history, and sink behavior to choose the recovery path:
Change or condition | Evidence to inspect | Decision |
Source, sink, query plan, and stateful logic unchanged | Checkpoint and query manifest match the approved version | Resume only after validation and reconciliation |
Watermark delay, grouping, aggregation, or admission policy changed | Historical state may not represent the revised logic | Launch an isolated rebuild with a fresh checkpoint |
Retained raw history is incomplete | The oracle or rebuild cannot cover affected windows | Hold publication and restore source history |
Replay safety for the sink is unresolved | Duplicate or overwrite risk remains | Keep consumers on the prior output and build a separate candidate |
Rebuild affected results without overwriting the evidence
If we decide to rebuild, do it with a fresh query, separate checkpoint, and a new output location. For example, spin up spark.readStream on the entire raw ledger (all historical batch files) plus any quarantined-but-relevant records, using the approved policy version. The rebuild query should use the same SQL/transformation code but start from batch 1. Its output goes to a new “candidate” directory or table. This ensures the rebuild does not clobber the old output yet retains the same schema.
Check: Before switching outputs, reconcile the rebuilt output against the oracle again, as above. Only when the new counts match should you replace the consumer dataset. Preserve the old output and checkpoint until consumers have migrated.
You might summarize the rebuild plan as steps or in a table:
Step | Description |
1. Launch new query | Read full raw input + same logic (valid events only) |
2. Use new checkpoint and sink | Ensure no overlap with old output |
3. Run to completion | (No new live data yet) |
4. Reconcile new output vs oracle | Verify all eligible events included |
5. Cutover | Swap old output with new, mark policy version |
Also record the timestamp of the last raw event used so the live stream (post-repair) doesn’t reprocess historical data or leave a gap. Both datasets (old and new) can be kept until clients have switched.
Monitor producer clocks and enforce stop conditions
To prevent recurrence, set up operational alerts in production. For instance:
Signal | Condition | Action/Owner |
Future-skew events | Quarantine count spikes above threshold (e.g. >5% of batch) | Alert data team; pause or throttle ingestion |
Null/malformed ts | More than X% of rows | Data ops investigate upstream timestamp issues |
Watermark jump | Watermark advances by >Y minutes in one trigger | Schedule root-cause analysis |
Raw coverage gap | Missing RawIDs (expected sequence holes) | Alert pipeline owner; re-run missing data if needed |
Reconcile mismatch | Output count ≠ oracle count after grace period | Trigger hold/pause for manual review |
These thresholds (X%, Y minutes) are specific to each system and workload. Assign each alert to an owner; for example, “Data Engineering team” for pipeline issues, “Data Producer team” for clock errors, etc. Simply increasing the watermark delay is a temporary guardrail, not a cure for bad timestamps. The real fix is to have data contracts and producer-owned timestamp rules in place so producers ensure monotonic or at least realistic clocks.
Approve publication and retain a reversible transition
Before declaring the fix done, validate all evidence. Construct a matrix of conditions vs actions:
Scenario | Evidence Needed | Outcome |
All windows reconciled, only expected quarantines | Query progress logs, reconciliation table | Approve: Switch to (new) stream outputs, release hold |
Quarantine count grew abnormally | Quarantine logs vs baseline | Hold: Investigate source data; do not republish yet |
Unexplained missing IDs | Raw vs output diff shows unaccounted gaps | Rebuild/Hold: Investigate state; possibly rebuild |
Policy changed during replay | Version mismatch in log, oracle difference | Hold: Rollback policy or rebuild with correct version |
During this transition, keep the old output available. Consumers should remain pointed at the old dataset until you are certain the new one is correct. Version the data contract and pipeline (e.g. label output tables with the policy version and timestamp of cutover). If any source data is still missing or mismatched, maintain a “hold” until resolved.
This approval step ensures we do not silently publish an incorrect result. The switch to the corrected stream is a reversible migration: both datasets coexist until a controlled cutover, at which point the old one can be archived.
Develop the foundations for stateful data reviews
This incident underscores the need for end-to-end data quality infrastructure. Key foundations include: transactional streaming sinks, immutable raw logs (with raw-data governance), tight schema and timestamp contracts, and idempotent transformations. By explicitly recording and validating timestamps, and building batch-based oracles, we apply devops observability best practices to streaming. Teams should incorporate deterministic replay tests for their stateful jobs as part of continuous integration.
Readers building broader data engineering foundations can use that roadmap as contextual preparation. Refonte Learning’s Data Engineering Program page describes a three-month path at 12-14 hours per week covering pipeline design, real-time processing, streaming and batch ingestion, transformation, governance, warehousing and ETL, Hadoop, and Spark. It does not confirm this specific future-timestamp validation or checkpoint-recovery exercise.
Trust the reconciled windows, not the running query
Before publishing, run through a final evidence checklist. Ensure you have:
Input audit: Every RawID accounted for in either accepted or quarantined sets.
Timestamp policy: The exact rule (e.g. “≤1h in future”) and code version documented.
Classification completeness: No raw row left unclassified (accepted vs quarantine covers all cases).
Watermark log: Observed watermark progression from logs or Spark UI (shows how the outlier shifted state).
Output reconciliation: Table or logs showing expected vs actual per window, with explanations for any differences.
Publication decision: A clear record of who approved the cutover (including policy version, code version, timestamp).
The final trusted output is the one matching our reconciled oracle, not just the checkpoint of the live stream. By verifying each step against the immutable raw ledger, we ensure the aggregate truly reflects the intended data. Keep a copy of both the old and new outputs in case an unexpected discrepancy appears later.