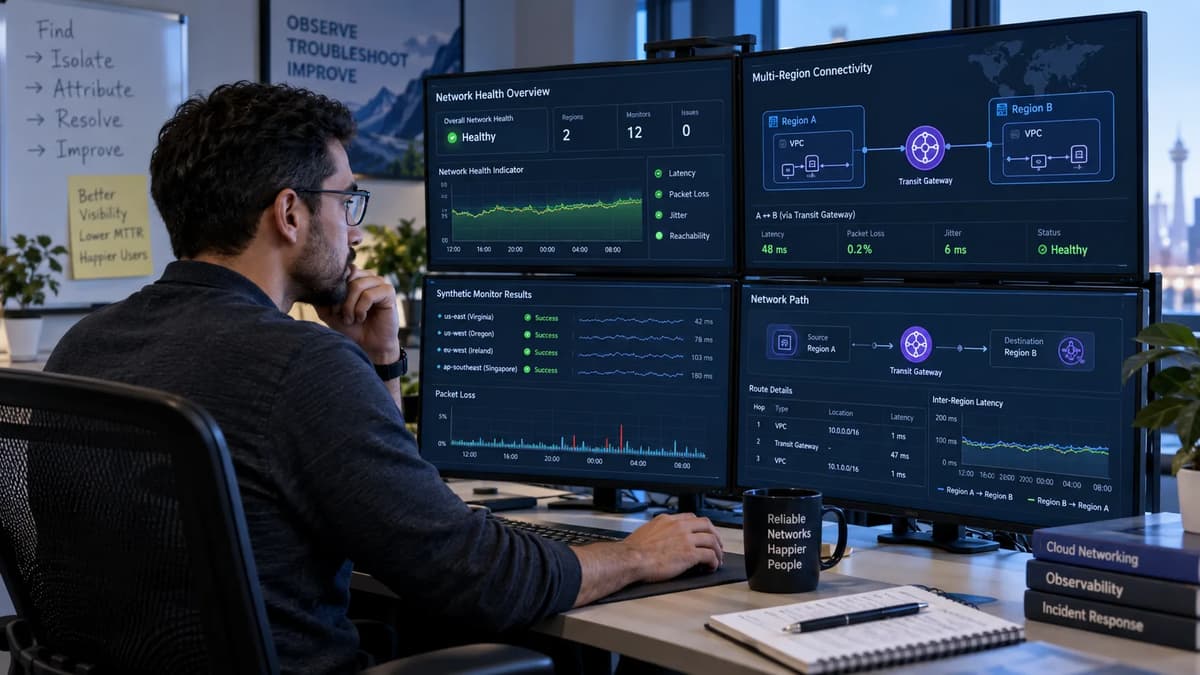
A reroute during a cross-Region incident is not a diagnostic action; it is a production change with its own blast radius. The operating question is therefore narrower than “is AWS healthy?” and more useful: what has been observed on the monitored AWS path, what remains unobserved, and what evidence is strong enough to justify moving traffic?
That distinction matters after AWS’s September 10, 2026 change to CloudWatch Network Synthetic Monitor. The release extended the Network Health Indicator (NHI) to paths that cross an AWS Transit Gateway inter-Region peering connection. AWS states that, for these paths, NHI reflects the health of the AWS network path up to the Transit Gateway peering connection.
It does not claim to validate every destination-side route, DNS lookup, endpoint, dependency or application transaction. See AWS, “Amazon CloudWatch now supports network health indicator for TGW inter-Region peering using synthetic monitors,” September 10, 2026.
This runbook is for network engineers, SREs, cloud architects and incident commanders who need defensible attribution, not a green/red shortcut. It separates documented product behavior from a proposed operating model and from unverified assumptions. The outcome is an evidence packet that can support routing decisions, service-owner decisions and AWS escalation without pretending that one synthetic signal is an end-to-end availability SLO.
Define the question NHI is supposed to answer
Start with the claim you are trying to prove. “The application is down” and “AWS observed degradation on the monitored network path” are different claims with different evidence. AWS describes Network Synthetic Monitor as publishing packet loss, round-trip latency and the binary NHI to CloudWatch; NHI is intended to indicate whether degradation was observed within the AWS-controlled network for the covered path.
AWS also states that Network Synthetic Monitor does not provide automatic network failover. AWS, “Using Network Synthetic Monitor” (live documentation; publication date not stated; accessed September 15, 2026).
Claim under discussion | Evidence that can support it | Evidence that does not prove it |
AWS network degradation was observed on the covered path | NHI = 100 for the relevant monitor/path and time window, plus packet-loss/latency context | Application 5xx errors alone |
Destination is reachable from the workload’s real path | Application-side or workload-originated reachability, routing and policy evidence | A peering attachment existing |
Business transaction succeeds | Request success, dependency health, traces and service SLI data | NHI = 0 |
Traffic should be failed over | Corroborated service impact, alternate-path readiness, owner approval and a recovery hypothesis | One NHI transition by itself |
The incident commander’s decision is not “which dashboard is right?” It is “which failure domain is currently supported by evidence, and what is the least risky next action?” For broader background on combining metrics, logs and traces, Refonte Learning’s observability fundamentals are useful context, but the operating boundary here is narrower: NHI is one network-attribution signal, not a universal system-health verdict.
Proposed operating rule: phrase incident updates as “observed,” “not observed,” and “not yet tested.” Avoid “AWS is fine,” “the network is down,” or “the application is healthy” unless independent evidence supports those broader conclusions.
Mark the monitored path and its stopping point
For Transit Gateway inter-Region monitoring, draw the path before you interpret the metric. The September 10 announcement says the new support applies when a synthetic-monitor path crosses a Transit Gateway inter-Region peering connection, and that NHI reflects the AWS network path up to that peering connection. That wording is the control point for incident attribution.
Path segment | Typical owner | Evidence to collect | Is it cleared by NHI = 0? |
Selected source subnet and probe origin | Workload/network team + AWS-managed monitor infrastructure | Probe identity, subnet/VPC, status, timestamps | No; 0 only means no AWS degradation was observed on the covered path |
Regional routing from source toward Transit Gateway | Network team/AWS | VPC route tables, TGW associations, synthetic loss/RTT | Not completely; configuration errors remain possible |
AWS-controlled inter-Region path up to TGW peering connection | AWS, observed by Network Synthetic Monitor | NHI plus loss/RTT | This is the NHI attribution domain described by AWS |
Destination-side TGW routing and VPC attachment path | Network team/AWS | Static TGW routes, associations, VPC routes, flow evidence | No |
DNS, load balancer, endpoint, host and service dependencies | Platform/service owners | Resolver tests, endpoint health, logs, traces, request SLIs | No |
Business transaction | Service/product owner | Real or synthetic transaction result | No |
What the inter-Region extension covers
The documented change is specific. AWS says the NHI previously covered synthetic-monitor paths using AWS Direct Connect and now also covers paths to a destination in a peered Region over Transit Gateway inter-Region peering.
The “How Network Synthetic Monitor works” documentation repeats the boundary: for these paths, NHI reflects the health of the AWS network path up to the Transit Gateway peering connection. AWS, “How Network Synthetic Monitor works” (live documentation; publication date not stated; accessed September 15, 2026).
There is a documentation wording tension worth preserving. The overview page still defines a “destination” primarily in hybrid/on-premises terms, while the newer behavior text explicitly discusses a destination in a peered Region. Do not stretch the older generic terminology into a stronger end-to-end claim; for this use case, the release announcement and the specific TGW behavior statement are the more precise scope descriptions.
What remains outside that conclusion
A normal NHI cannot exclude a missing destination-side static route, an asymmetric return path, a security-policy mismatch, a DNS failure, a load-balancer problem, an unhealthy target, a dependency failure or an application defect. Those are separate hypotheses requiring separate observations.
The practical boundary statement for the incident channel is: “NHI tells us whether AWS observed degradation on the covered AWS path to the inter-Region peering boundary; it does not certify the complete request path.” That sentence is intentionally narrower than “network healthy.”
Verify peering and routing prerequisites independently
A Transit Gateway peering attachment is a topology object, not proof of reachability. AWS documents two separate prerequisites after creating a peering request: the peer Transit Gateway owner must accept it, and traffic requires static routes in Transit Gateway route tables pointing to the peering attachment. AWS also states that Transit Gateway peering supports only static routes. AWS, “Transit gateway peering attachments in AWS Transit Gateway” (live documentation; publication date not stated; accessed September 15, 2026).
Use a readiness review that tests the intended flow in both directions rather than checking only for an attachment ID.
Readiness check | Required evidence | Owner | Pass condition |
Peering request | Requester/accepter TGW IDs and Regions | Network platform | Correct peer relationship and accepted/usable state |
TGW routes | Source- and destination-side TGW route tables | Network platform | Expected prefixes point to intended attachments; no conflicting blackhole/override |
VPC routes | Workload and attachment-subnet route tables | VPC owners | Forward and return paths exist for selected source/destination |
Monitor selection | Monitor, probe, source subnet, destination, protocol/port | Observability/network owner | Probe represents the incident path closely enough for the question being asked |
Permissions/ownership | Read access and named approvers | Incident commander | Responders can gather evidence without guessing who owns a route |
AWS’s VPC attachment documentation adds an important routing detail: resources need the appropriate subnet routes to reach the transit gateway, and attachment subnets are the entry/exit points for Transit Gateway traffic. A usable TGW peering route does not repair an incorrect workload subnet route.
The readiness discipline is more important than the specific dashboard tool. Refonte Learning’s broader DevOps monitoring tools article can help teams frame general monitoring practices, but for this runbook, topology ownership and route evidence must be explicit before NHI is used in an incident decision.
Interpret the indicator before configuring an alert
The CloudWatch Network Health Indicator is binary, but binary does not mean simple. AWS says NHI is based on a probabilistic/statistical assessment of the AWS-controlled path and correlation with sample datasets plus the monitor’s packet-loss and round-trip latency measurements. It is therefore an attribution aid, not a direct packet-by-packet truth table and not a percentage availability metric.
Signal/state | Documented meaning | Collection context | Prohibited interpretation |
NHI = 0 | Network Synthetic Monitor did not observe degradation for the covered AWS network path | Binary NHI, statistically derived | “100% available,” “application healthy,” or “all routing correct” |
NHI = 100 | Network Synthetic Monitor observed degradation within the covered AWS-controlled network path | Binary NHI, statistically derived | “100% outage,” “all requests must fail,” or “root cause proven” |
Packet loss | Percentage of transmissions without the expected response | Measured per probe and aggregated | Equivalent to NHI or application error rate |
Round-trip time | Average RTT observed during the aggregation interval | Measured per probe | End-to-end business transaction latency |
No usable NHI yet | No valid NHI evidence available for the decision | Could include documented warm-up or an operational telemetry gap | Healthy state |
Read 0 and 100 without reversing the meaning
The direction is easy to reverse because many “health” metrics treat a larger number as better. NHI does not. AWS states: 100 means Network Synthetic Monitor observed network degradation within the AWS-controlled path; 0 means it did not observe network degradation along that covered AWS path.
That still does not make 0 equivalent to application availability. It is a negative observation about a defined AWS-network failure hypothesis. Conversely, 100 supports provider-path degradation evidence but does not guarantee user-visible failure: applications may tolerate the degradation, use a different path, retry successfully, or have sufficient latency margin.
Separate valid observations from warm-up and missing data
AWS documents aggregation intervals of either 30 or 60 seconds for the measured results. It separately says Network Synthetic Monitor sends periodic active probes. Those statements do not define the aggregation interval as the probe cadence, nor do they guarantee a 30- or 60-second incident detection time.
AWS also documents a warm-up behavior: after creating a new monitor, adding a probe or reactivating a probe, NHI is delayed by a few hours while AWS collects data for anomaly detection. Treat that interval as “NHI not ready,” not as NHI = 0.
Proposed alerting policy: require the runbook to preserve three operational states: degraded observation, normal observation and no valid observation. Do not collapse missing/warming data into “OK.” Any local alarm evaluation window or debounce policy should be labeled as your own operating choice, not as a vendor detection guarantee.
Establish a baseline with independent telemetry
The first useful baseline is not “NHI usually equals 0.” It is a synchronized view of network attribution, network performance, application outcome and change history. CloudWatch exposes NHI alongside probe loss and round-trip time; those measurements answer different questions and should remain separate in the incident record. AWS’s monitor dashboard documentation explicitly says NHI pertains only to AWS-network health, and that it does not describe the overall health of the AWS network or of the probes themselves.
Evidence stream | Baseline to retain | Incident comparison |
NHI | Valid 0/100 observations by monitor and time | Did the state change for the relevant path? |
Probe loss/RTT | Typical ranges and known maintenance patterns | Did loss/latency shift with the symptom? |
Application SLI | Success rate, latency, dependency errors by Region/path | Did user-visible impact occur at the same time? |
Change events | Route, security, deployment and infrastructure changes | What changed immediately before or during impact? |
Topology snapshot | TGW/VPC associations, intended prefixes, owners | Is the current path the path the monitor represents? |
The local design I recommend is to timestamp all four streams in UTC, retain raw timestamps, and compare overlapping observation windows rather than rounding every event to the same minute. That is a proposed operating model, not an AWS service default. The purpose is causality hygiene: a route commit at 10:14:58 and an error-rate rise at 10:15:41 should not be recorded as “simultaneous at 10:15” without preserving the raw sequence.
For teams standardizing dashboards and log retention, Refonte Learning’s monitoring and logging foundations offer broader implementation context. The specific requirement here is correlation: NHI, loss/RTT, application SLIs and change events need timestamps that can be compared without turning one signal into a proxy for the others.
Build an evidence-led incident attribution matrix
A useful attribution matrix does not map each signal combination to a single root cause. It maps the combination to a next evidence request and an owner. This prevents “normal NHI” from becoming a premature provider exoneration and “degraded NHI” from becoming an automatic failover trigger.
NHI evidence | Application outcome | What it supports | What remains open | Next owner/action |
Valid 0 | Requests healthy | No AWS degradation observed on covered path; service currently succeeding | Latent/partial issues, other paths | Observe; no change solely on NHI |
Valid 0 | Requests failing | Failure exists without NHI evidence of AWS degradation on covered path | Destination routing, DNS, policy, endpoint, app, unmonitored AWS segment | Service + network owners inspect destination-side evidence |
Valid 100 | Requests failing | AWS observed covered-path degradation and business impact is present | Whether degradation is causal, whether alternate path is safer | Network owner correlates loss/RTT; service owner evaluates failover |
Valid 100 | Requests healthy | AWS observed degradation but current transaction path remains successful | Hidden redundancy, tolerance, different route, future risk | Watch capacity/error budget; do not fail over automatically |
Missing/not ready | Requests failing | Business impact exists; NHI cannot currently attribute it | All network and application hypotheses remain | Restore/validate measurement while troubleshooting independently |
Missing/not ready | Requests healthy | Service appears healthy but NHI attribution is unavailable | Monitoring readiness | Observability owner repairs readiness outside the incident path |
This matrix intentionally separates absence of evidence from evidence of absence. A 0 is a valid observation with a defined scope; missing NHI is not a 0. And a 100 is provider-path evidence, not a business-impact measurement.
The escalation language should match that discipline. “At 10:22 UTC, NHI was 100 on monitor X for the path represented by source subnet A and destination B; packet loss also increased, and application errors rose in the same interval” is defensible. “AWS caused the outage” is a root-cause conclusion that may require additional confirmation.
For command decisions, add a confidence field rather than forcing an early verdict. A useful local scale is confirmed observation, supported hypothesis, and unverified assumption. “NHI was 100” can be a confirmed observation when the datapoint is valid and correctly scoped.
“AWS-path degradation contributed to retries” is a supported hypothesis only after timing and request-path evidence line up. “The peering link is the root cause” remains unverified until competing route, endpoint and application explanations have been tested. This wording keeps the incident channel precise without pretending uncertainty can be eliminated in real time.
Check routing and policy changes before moving traffic
A route change that happens near the incident is important evidence, but coincidence is not causation. Transit Gateway peering relies on static routes, and Transit Gateway route tables can contain blackhole routes that drop matching traffic. AWS also documents that VPC subnet routes determine whether traffic is forwarded to the Transit Gateway in the first place.
Read-only verification | Question to answer | Stop condition |
Diff TGW route tables and associations | Did the intended destination prefix or next-hop attachment change? | Ownership or intended state is unclear |
Diff source/destination VPC route tables | Did forward or return routing change? | Proposed fix would alter unrelated prefixes |
Check security controls | Did a policy, firewall or security-group rule change? | “Fix” requires bypassing an approved control |
Check DNS/endpoint targeting | Did name resolution or endpoint selection change? | Probe destination is not representative of application destination |
Check change record | Who approved, implemented and can reverse the change? | No accountable owner or rollback plan exists |
Do not “open everything” to make a synthetic probe pass. A probe that succeeds after security controls are bypassed proves very little about the intended production design and may create a more serious incident. The same principle appears in broader Zero Trust cloud architecture: evidence gathering should preserve intended trust boundaries rather than disable them for convenience.
Stop boundary: suspend reroute, route repair or failover when the team cannot identify route ownership, cannot state which path NHI actually represents, or cannot articulate how the proposed change is expected to improve the observed symptom. Escalation with uncertainty is safer than an unowned routing change.
Work through a fictional cross-region outage
The following scenario is fictional. It is a tabletop exercise, not a report of an AWS incident and not a claim that fault injection was performed. Assume a service normally sends requests from a source VPC in Region A across two Transit Gateways joined by inter-Region peering to a private service endpoint in Region B. The monitor uses a source subnet and destination/protocol chosen to approximate that network path.
Time (UTC) | Hypothetical observation | Interpretation at that moment | Next evidence |
10:00 | NHI = 0; requests healthy | Baseline only | Preserve topology/change snapshot |
10:12 | Approved route change completes on destination-side TGW table | Coincidence candidate, not yet causal | Capture exact route diff and owner |
10:15 | Requests fail; NHI remains 0 | Covered AWS degradation not observed | Check route, DNS, endpoint and return path |
10:18 | Route diff shows unexpected destination prefix target | Configuration hypothesis strengthens | Validate intended route with owner; prepare reversible correction |
10:22 | NHI becomes 100 while some requests now succeed via retries | AWS degradation also observed; business impact is mixed | Correlate probe loss/RTT and real request path |
10:27 | NHI datapoint unavailable after probe was reactivated for test | NHI evidence is not usable for attribution | Mark warm-up/readiness; do not call it healthy |
10:35 | Route restored; requests recover | Recovery correlates with route restoration | Compare before/after; do not yet declare root cause |
Normal NHI with failing application requests
At 10:15, the most important discipline is to avoid saying “the network is healthy.” NHI = 0 means AWS did not observe degradation on the covered AWS path; it does not eliminate a customer-controlled route error or an unmonitored destination-side problem. The route change at 10:12 increases the priority of configuration review, but it still does not prove causality.
Competing hypotheses include a wrong TGW static route, missing return route, DNS selecting a bad endpoint, destination policy rejection, unhealthy service target or application release issue. The next move is evidence collection, not failover by instinct: read the route diff, test the intended destination from a representative workload path, inspect endpoint/service telemetry and verify the return path.
Degraded or unavailable NHI without a clear application failure
At 10:22, NHI = 100 supports a new statement: AWS observed degradation on the covered AWS path. If retries keep most user transactions successful, the service may not yet have demonstrated material business impact. The right incident update is “AWS-path degradation observed; service impact currently partial/uncertain,” not “application outage.”
At 10:27, assume the probe was reactivated. AWS documents that NHI can be delayed by a few hours after reactivation while anomaly-detection data is collected, so the unavailable NHI should be marked not ready.
The route restoration at 10:35 and application recovery strongly support the route hypothesis, but they still do not mathematically prove it. A provider degradation also appeared during the incident. The post-incident record should therefore say that route restoration was followed by recovery and that concurrent AWS-path degradation was observed, with root cause pending deeper timeline and packet/application evidence.
Test observation and alert behavior safely
Production incidents are the wrong time to discover that responders cannot distinguish NHI warm-up from a genuine 0, or that the probe destination does not represent the service path. Use non-production or otherwise controlled validation to exercise the runbook without deliberately destabilizing shared production routing.
Proposed test | Expected evidence | Restore/exit condition | What the test must not claim |
Newly create or reactivate a non-production probe | NHI may be delayed during documented warm-up | Wait for valid observations before acceptance | Exact warm-up completion time |
Temporarily stop ingesting/displaying a copied telemetry stream in a test dashboard | Dashboard shows missing/unknown rather than healthy | Restore ingestion; verify gap is visible | That AWS itself stopped producing data |
Point a test monitor at an intentionally non-representative destination | Metadata review should expose path mismatch | Restore approved destination | That NHI is “wrong” because app path differs |
Introduce a controlled, approved route mistake in an isolated lab path | Reachability/app test fails; NHI may or may not change depending on boundary | Restore known-good route and verify recovery | Guaranteed NHI response to customer route errors |
Simulate signal disagreement in a tabletop | On-call follows matrix and escalation language | Exercise ends when evidence packet is complete | Real provider degradation |
The first test validates a documented behavior: AWS says creating a monitor, adding a probe or reactivating one delays NHI by a few hours. The remaining tests are proposed local exercises. They validate your dashboards, classification logic and human response; they are not product behavior claims.
For alerting, test three conditions explicitly: valid NHI 100, valid NHI 0 and no usable NHI. Also test that packet loss and RTT alarms remain independent from NHI. AWS allows CloudWatch alarms on monitor metrics, but the thresholds and escalation logic should be chosen for your workload rather than treated as universal defaults.
A safe acceptance gate is evidence-oriented: the on-call engineer can identify the monitor and probe, state the boundary, distinguish aggregation interval from detection time, find the associated application SLI, locate the current route owner and produce a timestamped packet without changing production. Only after that should teams automate paging around NHI.
Run the tests with an explicit safety envelope. Name the lab or non-production accounts, the prefixes that may be changed, the engineer authorized to restore them, and the maximum duration of any deliberately broken route. Capture the known-good route and monitor configuration before the exercise.
If the test unexpectedly affects shared connectivity, stop the exercise and restore the known-good state before collecting more experimental data. Those controls are local reliability practice, not Network Synthetic Monitor requirements; their purpose is to make the test reversible and to prevent the observability exercise from becoming the incident.
Define failover gates that use more than one signal
Failover is a reliability mechanism, but unnecessary failover can amplify an incident through cold capacity, cache misses, dependency limits, route convergence, data consistency or operator error. Network Synthetic Monitor itself does not provide automatic network failover, and AWS does not document NHI as a mandatory failover controller.
The following is a proposed local policy, not an AWS requirement:
Gate | Required before reroute/failover | Why it exists |
Demonstrated service impact | Error/latency SLI or critical transaction failure | Avoid acting on network evidence without user impact |
Corroboration | NHI plus loss/RTT, or route evidence, or independent path test | Reduce single-signal false attribution |
Alternate-path capacity/readiness | Capacity, dependencies and health checks pass | Avoid moving traffic into a weaker failure domain |
Explicit recovery hypothesis | “Moving X traffic away from Y should reduce Z symptom” | Makes the change testable and reversible |
Owner approval | Service owner and network change authority agree | Preserves accountability under pressure |
A valid NHI = 100 can satisfy part of the corroboration gate; it should not satisfy all gates. A valid 0 with failing requests may justify a destination-side routing correction if evidence supports it, but again not because “NHI said AWS is fine.”
Set a stop rule before executing: if the current route owner is unknown, the monitor boundary is ambiguous, or the alternate Region cannot demonstrate readiness, do not reroute solely to gain diagnostic information. Continue evidence gathering and escalate. This complements general cloud development practices around resilient delivery, but the specific multi-region gate here is an operating policy proposed for this NHI/TGW boundary.
Recover without losing the original evidence
Recovery work should preserve the state that made attribution possible. The quickest way to make a post-incident review inconclusive is to overwrite route tables, dashboards and deployment state without recording what changed.
Recovery step | Evidence to retain before change | Evidence to capture after change |
Restore intended TGW/VPC route | Route-table export/diff, association, owner, timestamp | New route state and propagation/association view |
Reverse security/policy change | Prior policy and change record | Restored policy and validation result |
Move traffic back | Service SLI, capacity, NHI/loss/RTT, active path | Stabilization window and same signals after move |
Reactivate/replace monitoring | Prior probe state and reason | Valid-observation time; warm-up marked explicitly |
Close incident | Known facts, hypotheses, unresolved contradictions | Final timeline and evidence archive |
Use “recovered” and “root cause confirmed” as separate milestones. If requests recover immediately after restoring a route, that is strong correlation. It does not prove that the route change was the only cause, especially if NHI also indicated AWS degradation during part of the interval.
Similarly, a return from NHI 100 to 0 means AWS no longer observed degradation on the covered path at those observations. It does not prove the application recovered; the application SLI must show that independently.
Proposed recovery boundary: keep the incident open for evidence reconciliation until the service is stable, the intended route state is restored or intentionally changed, NHI readiness is understood, and contradictory observations have an owner. Do not prolong customer impact merely to preserve evidence, but capture read-only snapshots before destructive changes whenever feasible.
Build a useful escalation packet
A strong escalation packet lets another engineer reproduce your reasoning without access to your memory. It should be useful both for an internal network/platform escalation and for a provider support case. Minimize data while preserving topology and time correlation.
Packet field | Include | Avoid |
Time window | UTC start/end, raw timestamps, timezone stated | “Around lunchtime” |
Monitor identity | Monitor/probe identifiers, source VPC/subnet, destination IP/protocol/port as appropriate | Secrets, credentials, unrelated customer data |
Boundary statement | Exact segment the monitor represents and where NHI conclusion stops | “End-to-end AWS path healthy” |
Signals | NHI states, loss, RTT, application SLI, alarms | Screenshots without timestamps/context |
Routing/topology | TGW IDs/Regions, peering attachment, relevant route-table entries and associations | Entire account inventory |
Changes | Route, policy, deployment changes with owner and approval record | Unsupported blame statements |
The concise escalation statement should separate fact from inference. Example: Known: “Between 10:22 and 10:26 UTC, NHI was 100 for monitor M on the Region-A-to-peering-boundary path; probe loss increased and application errors were elevated.” Inferred: “The AWS-path degradation may have contributed to the errors.” Open: “A destination-side route change occurred at 10:12 UTC and may independently explain part of the failure.”
AWS’s own dashboard documentation cautions that NHI pertains only to AWS-network health for the represented path and does not describe the overall AWS network or probe health. That sentence is useful discipline when writing a support case.
For broader team roles and preparation practices, Refonte Learning’s incident response planning provides organizational context. In this network runbook, the escalation packet is the concrete handoff artifact: scoped identifiers, synchronized evidence, recent changes, a boundary statement and explicit unknowns.
Pilot the monitor and train its owners
Treat first deployment as an operational pilot, not as immediate authority to drive failover. A proposed 30-day pilot gives enough calendar time to test ownership, maintenance changes, on-call handoffs and at least one tabletop; it is not an AWS recommendation or a promise that every failure mode will occur.
Pilot exit gate | Evidence required |
Boundary understood | On-call can state source, destination, TGW peering boundary and unmonitored segments |
Signal semantics understood | Engineers correctly interpret 0, 100, warm-up and missing data |
Correlation works | Dashboard/runbook links NHI, loss/RTT, service SLI and change timeline |
Ownership is actionable | Named network, service and incident-command owners can approve/reject changes |
Tabletop passes | Team produces an escalation packet and applies stop/failover gates without unsafe changes |
During the pilot, review every NHI transition even when there is no service impact, and review every material service incident even when NHI remains 0. The purpose is not to “prove accuracy” from a small sample. It is to learn where the monitor is representative, where the application path diverges, and whether responders preserve uncertainty correctly.
For practice in networking and observability foundations, Refonte Learning’s Cloud Architecture Program lists multi-cloud networking, routing, private connectivity, multi-AZ/region resilience, observability and SLO/SLA design. Its Program Specifics section lists four months at 8–12 hours per week; Linux, Git and one programming language are expected foundations, networking/HTTP/database familiarity is recommended, and the admissions section requires applicants to be working toward a bachelor’s or higher-level degree. These verified foundations align with the boundary and incident-evidence disciplines used here.
Answer the indicator questions and issue a readiness verdict
Does NHI 0 mean the service is healthy? No. AWS documents 0 as “no AWS network degradation observed” for the covered path. It is not 100% availability and does not clear DNS, destination routing, policy, endpoints, dependencies or application processing.
Does NHI 100 mean every request should fail? No. AWS documents 100 as observed degradation within the covered AWS-controlled network path. Application impact still requires application evidence, and resilient services may continue succeeding through retries, redundancy or unaffected flows.
Can I trust NHI immediately after creating or reactivating a probe? Not for immediate attribution. AWS says NHI is delayed by a few hours after a new monitor, added probe or reactivated probe while data is collected for anomaly detection. Mark the signal “not ready”; do not reinterpret the missing value as 0.
Should NHI trigger automatic inter-Region failover? The product does not provide automatic network failover, and this runbook does not recommend treating one NHI change as sufficient authority. Failover should require demonstrated service impact, corroboration, alternate-path readiness, owner approval and an explicit recovery hypothesis.
Use this final readiness verdict before making NHI operationally consequential:
Evidence-ready | Not ready |
Monitor boundary is documented and matches the question responders ask | Team describes NHI as end-to-end application health |
NHI 0/100 semantics are correctly documented | 0 is called “100% healthy” or 100 “100% outage” |
Warm-up/missing data has a distinct state | Missing NHI is silently treated as normal |
Loss, RTT, application SLIs and changes are time-correlated | NHI is the only incident signal |
Route ownership, failover gates and recovery evidence are named | Responders can reroute without corroboration or owner approval |
The readiness verdict is therefore binary only at the process level: evidence-ready when the team can state what NHI proves, what it cannot exclude and which independent observation comes next; not ready when the signal is being asked to make an end-to-end decision it was never documented to make.