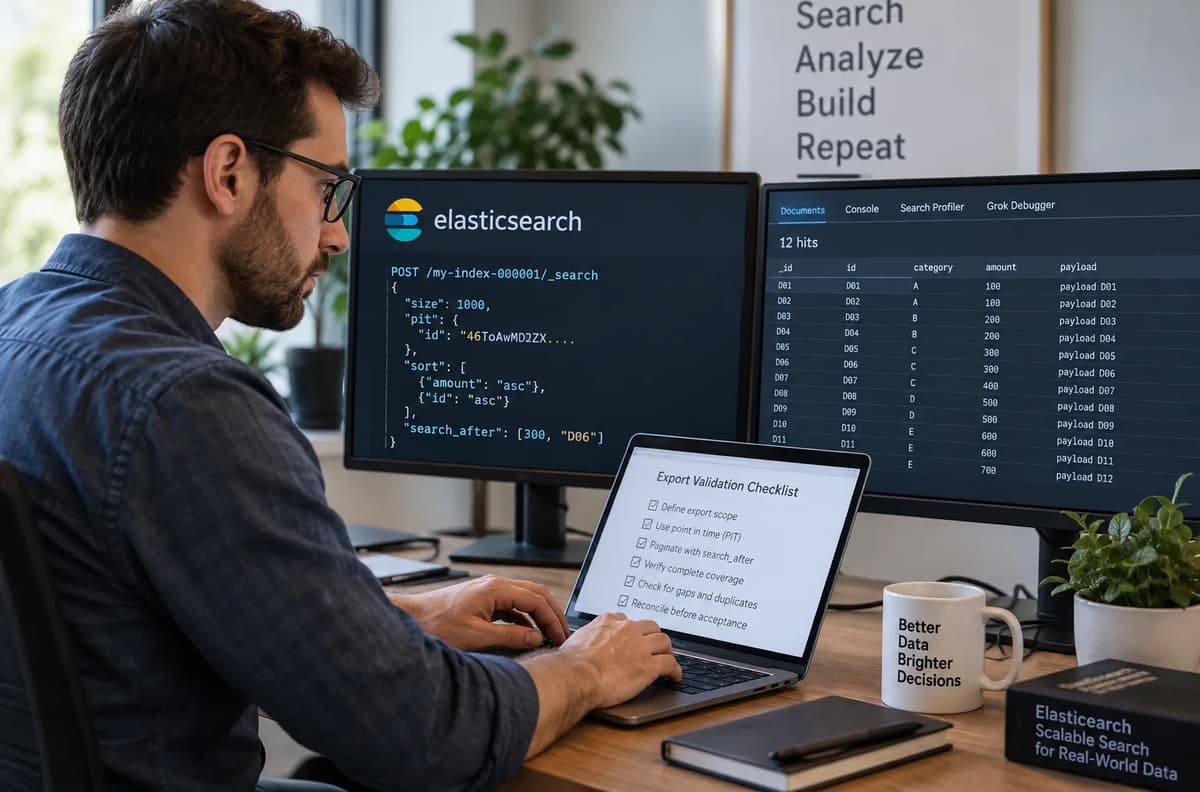
Exporting data from Elasticsearch, even with a point in time (PIT), is not automatically safe. You can page through an index while it is being modified, use search_after, receive results, and believe every document has been captured. Yet a concurrent deletion, addition, or update can introduce omissions, duplicates, or mixed populations in the final export. This article presents a practical method for verifying that a page-by-page export covers the expected population and for making an evidence-based decision.
The lab described below is a reproducible synthetic protocol. It is not presented as an executed test or an observed result. The stated responses and assertions are expected outcomes that must be verified in the pinned environment before any real use.
Define the Export You Are Willing to Accept
Begin by defining exactly what the export must contain: the target index, such as my-index-000001; the authorized principal; a fixed filter; the fields to extract; the _source projection; and the output format. This definition is the contract: the export must return every document that matches the filter, with no omissions or duplicates. This discipline extends pagination and frontend API contracts and prevents a sequence of valid responses from being mistaken for a complete artifact.
The final decision has three states: accept when all evidence confirms completeness; hold when uncertainty can still be resolved within the existing view; or restart when the original view has been lost. The data owner or the team responsible for the API authorizes publication, not the search engine.
Elastic's pagination documentation explains that deep pagination with from and size is limited to 10,000 hits by default through index.max_result_window. This scenario uses search_after to go deeper, but the cursor alone is not proof of a complete snapshot.
Pin the Runtime and Resolve the Index Target
Before sending any request, record the exact Elasticsearch and client versions, the resolved concrete index, mappings, shard count, routing, authorization principal, query, sort, projection, and sink format. In this example, the server and client are pinned to Elasticsearch 8.14.0 and elasticsearch-py 8.14.0, with one shard to keep the test readable.
PUT /my-index-000001
{
  "settings": {
    "number_of_shards": 1,
    "number_of_replicas": 0
  },
  "mappings": {
    "properties": {
      "id":       { "type": "keyword" },
      "amount":   { "type": "integer" },
      "category": { "type": "keyword" },
      "payload":  { "type": "text" }
    }
  }
}
The {"match_all":{}} query and the amount ascending, id ascending sort remain identical throughout the run. Any change to permissions, filters, mappings, projection, or sort creates a separately identified export.
Shard size and replication also affect search cost. They belong to API performance trade-offs, but they never replace the completeness controls described here.
Build an Independent Baseline Before Paging
Prepare a stable dataset and a manifest that is independent of the exporter. The scenario uses 12 documents, D01 through D12, with a business identifier named id, an integer amount, a category, and a payload. Repeated amount values deliberately create sort ties.
_id | id | category | amount | payload |
D01 | D01 | A | 100 | payload D01 |
D02 | D02 | A | 100 | payload D02 |
D03 | D03 | B | 200 | payload D03 |
D04 | D04 | B | 200 | payload D04 |
D05 | D05 | C | 300 | payload D05 |
D06 | D06 | C | 300 | payload D06 |
D07 | D07 | C | 400 | payload D07 |
D08 | D08 | D | 500 | payload D08 |
D09 | D09 | D | 500 | payload D09 |
D10 | D10 | E | 600 | payload D10 |
D11 | D11 | E | 600 | payload D11 |
D12 | D12 | E | 700 | payload D12 |
Keep this manifest outside the export code, including identifiers, canonical fields, checksums when appropriate, and the expected amount total. After indexing, make the fixture searchable before opening the PIT.
POST /my-index-000001/_refreshThe refresh response confirms that the operation succeeded on the shard, but it does not by itself prove that all 12 expected documents are present. A control search must then verify the identifiers and content. The Elasticsearch Refresh API establishes the visibility boundary used by this test.
Separate Write Acknowledgement From Search Visibility
An indexing acknowledgement does not necessarily mean that the document is already visible to search. The refresh documentation explains this boundary. In this lab, the explicit _refresh call defines the initial population, and the control search then confirms all 12 documents. This choice is specific to the fixture; it is not a general recommendation to force refreshes in production.
Show How Live Pagination Can Change the Population
To demonstrate the risk, repeat the same mutation schedule against an isolated fixture, but paginate without a PIT. With size=3 and the amount ascending, id ascending sort, use the following control:
Live page 1: D01, D02, and D03.
Mutation: delete D05, which has not yet been exported; change D06's sort position and payload; add D13 with amount=250.
Live page 2: resume search_after from D03. One possible execution returns D04, D13, and D06; D05 is missing, while D13 belongs to a newer population.
This sequence illustrates the risk mechanism, not an observed transcript. A nondeterministic run that happens to return the expected 12 documents does not prove that live pagination is safe. Concurrent writes can move, remove, or introduce documents between pages.
Give Every Page a Complete Ordering
Every subsequent request must carry all sort values from the last hit, without rounding or type conversion. The search_after documentation for PIT searches explains that Elasticsearch implicitly adds a sharddoc tie-breaker when a PIT is used. The application identifier id remains useful for reconciliation; sharddoc is not a business identifier and must not be treated as one.
Open a PIT With the Required Shard Coverage
After confirming that the fixture is visible, open the PIT on the concrete index:
POST /my-index-000001/_pit?keep_alive=2mThe expected response has this form:
{
  "id": "47pITnEXAMPLEid",
  "_shards": {
    "total": 1,
    "successful": 1,
    "failed": 0
  }
}
Store the creation response securely and verify shard coverage. The Open Point in Time API exposes shard availability and the costs of retaining the context. For a complete export, reject creation if any required shard is unavailable. The keep_alive=2m value is a demonstration parameter that must be validated against the actual time between pages; it is not a guarantee for the entire job.
Keep Query, Sort and Cursor Together
Then paginate sequentially within that same PIT. The proposed first request is:
curl -XGET "localhost:9200/_search" \
  -H 'Content-Type: application/json' \
  -d '{
    "pit": {
      "id": "47pITnEXAMPLEid",
      "keep_alive": "2m"
    },
    "query": { "match_all": {} },
    "sort": [
      { "amount": "asc" },
      { "id": "asc" }
    ],
    "size": 3,
    "track_total_hits": true
  }'
Do not add a separate index to a search request that uses a PIT. The PIT search rules define that context. After every complete response, retain the latest PIT ID and the complete sort array from the last hit. The next page uses that exact array in search_after. Do not drop the tie-breaker or convert values to strings or approximate numbers.
Version the Cursor Envelope
The application checkpoint must contain at least:
the unique run identifier;
the fingerprint of the query, filter, sort, and projection;
the latest returned PIT ID;
the sort tuple from the last validated hit;
the page number;
the sink manifest or checkpoint corresponding to the last validated output.
Before every request, verify that the envelope belongs to the same run and the same contract. Reject a cursor from an earlier export, a different query, or a different sink. Advance the checkpoint only after validating the corresponding output.
Commit Output Before Advancing the Checkpoint
Write each page to the sink before advancing the cursor. A page can be represented by an immutable file containing the run and page number, or by a transaction in a staging table with a content hash. Explicitly test three failure points:
Before the write: the page is not durable; the checkpoint does not move, and the same request can be replayed while the PIT remains valid.
After the write but before checkpoint acknowledgement: on restart, the process detects the existing artifact by its key and hash, then validates it or rewrites it idempotently.
After the checkpoint: the page and its sink evidence are consistent, so pagination can continue.
This rule targets at-least-once recovery for each page. Sink idempotency prevents a replay from creating a second logical row or file, without claiming an exactly-once guarantee across Elasticsearch, the export process, and the output storage.
Reject Partial Success and Uncertain Responses
Inspect every Search response before accepting its hits. The official Search response structure exposes timed_out, shard outcomes, and the total hit count. A page is admissible only when timed_out=false and _shards.failed=0. In this fixture, request an exact total and expect hits.total.value=12 with relation="eq". An HTTP 200 response or a nonempty hits array is not sufficient.
A timeout, shard failure, client disconnect, or truncated sink write creates an uncertain response. Keep the previous checkpoint and distinguish replayable work in the same view from loss of the PIT. Integration error and retry handling principles help structure this classification, but PIT validity must be proved separately.
Do Not Treat a Partial Page as the End
A page containing fewer hits than size is not, by itself, proof of exhaustion. If the response is complete, validate its hits, advance the checkpoint, and request the next page. If the response is incomplete, accept no hits from that attempt and replay it within the same PIT. Normal exhaustion is confirmed by an empty page with timed_out set to false and no failed required shard.
Draw a Hard Boundary Around PIT Expiry
The keep_alive value extends the context lifetime with each request, but it does not turn the PIT into a durable backup. PIT lifetime limits create a hard boundary: if the original PIT can no longer be used, do not open a new PIT and reuse the old search_after tuple. That combination would mix two views, and a context-local tie-breaker cannot reconstruct the earlier population.
Mark the unfinished artifact as quarantined, close any surviving contexts when possible, and start a new run with a new identifier, a new PIT, and a new sink prefix. Never silently attach the end of a new view to the beginning of the old one.
Reconcile Keys, Content and Totals Independently
After the complete empty page, compare the sink with the initial manifest across several independent dimensions:
Identifiers: the same set as the manifest, with no missing or repeated ID.
Content: the same canonical fields for each ID, using direct comparison or a stable checksum.
Totals: the exact hit total, the sink row count, and the expected amount sum.
Provenance: the same run, query fingerprint, and format version across every page.
Do not compare the export only with the current index contents, because the index was deliberately changed after the PIT was opened. The reference is the manifest of the population that was visible before the context opened, together with evidence that the control search found all 12 documents.
Make Equal Counts Fail When Contents Differ
Build a negative 12-row variant in which D08 is missing and D09 appears twice. The row count remains 12, but the identifier multiset, content, and checksums differ. Reject the run. Equal counts do not compensate for a missing ID, a duplicate, or an extra document from another population.
Keep the Export Endpoint Within Its Authorization Boundary
Treat the PIT ID and exported data as internal information. The server must own the tenant filter, principal, projection, and sink destination; the client must not be able to substitute those parameters freely inside an opaque cursor. Apply appropriate API security and observability controls: authentication, authorization, correlated logging, encryption, and limited metadata retention.
The effect of an authorization change made after opening a PIT must be verified separately for the relevant version and architecture. This playbook does not assume that a later change retroactively alters the retained view. When uncertain, block publication of the artifact and open a new run under the approved authorization contract.
Budget Context Lifetime and Clean Up Failed Runs
Measure inter-page time, PIT age, sink backlog, and the search resources exposed by the pinned version. A PIT can retain segments, file handles, and memory. On success or abort, use the Close Point in Time API to release the context explicitly when it still exists. Expiry or closure never validates the output.
Track Search Resources Separately From Output State
Maintain two separate ledgers:
PIT context: latest identifier, opening time, expiry, closure state, and cleanup result.
Export state: durable pages, hashes, last validated tuple, reconciliation status, and publication decision.
An orphaned context requires cleanup; an incomplete export requires a resume or restart decision. The two problems can coexist and must not share a single "finished" flag.
Review the Evidence Before a Canary Export
Before a canary, retain the fixture creation commands, manifest, raw requests and responses, server and client versions, contract fingerprint, page manifests, and failure-injection matrix. Use only synthetic or explicitly approved data. HTTP assertions can be automated, but content checks must accompany them.
pm.test("HTTP 200", () => pm.response.to.have.status(200));
pm.test("No timeout", () => pm.expect(pm.response.json().timed_out).to.eql(false));
pm.test("No shards failed", () => {
  pm.expect(pm.response.json()._shards.failed).to.eql(0);
});
Then add the expected identifiers, total relation, sort tuple, and sink hashes. Refonte's guide to API response assertions with Postman provides testing context; here, the decisive evidence remains independent reconciliation of the population and content.
Accept, Hold or Restart the Export
Apply the decision to the complete artifact, never to an isolated page:
Accept: every response is complete, every page is durable, the provenance belongs to one valid PIT, and reconciliation of IDs, content, and totals succeeds.
Hold: uncertainty remains, but the original PIT is still valid and the last safe checkpoint permits replay without publishing an incomplete artifact.
Restart: the original PIT has expired, been lost, or become invalid, or the page provenance can no longer be tied to a single view. Quarantine the output and begin a new run.
Condition | Action |
Complete export tied to one PIT and fully reconciled | Accept |
Uncertain response, safe checkpoint, and original PIT still valid | Hold |
PIT lost or possible mixture of views | Restart |
A cursor therefore does not prove that an export is complete. Acceptance depends on a visible population defined before the PIT opens, complete search responses, sink-aligned checkpoints, and independent reconciliation. To strengthen your foundations in API design, testing, logging, performance, and security, explore the Refonte Learning APIs Developer Program. The program presents these general foundations; this article does not assume that it teaches Elasticsearch, PIT, or search_after.