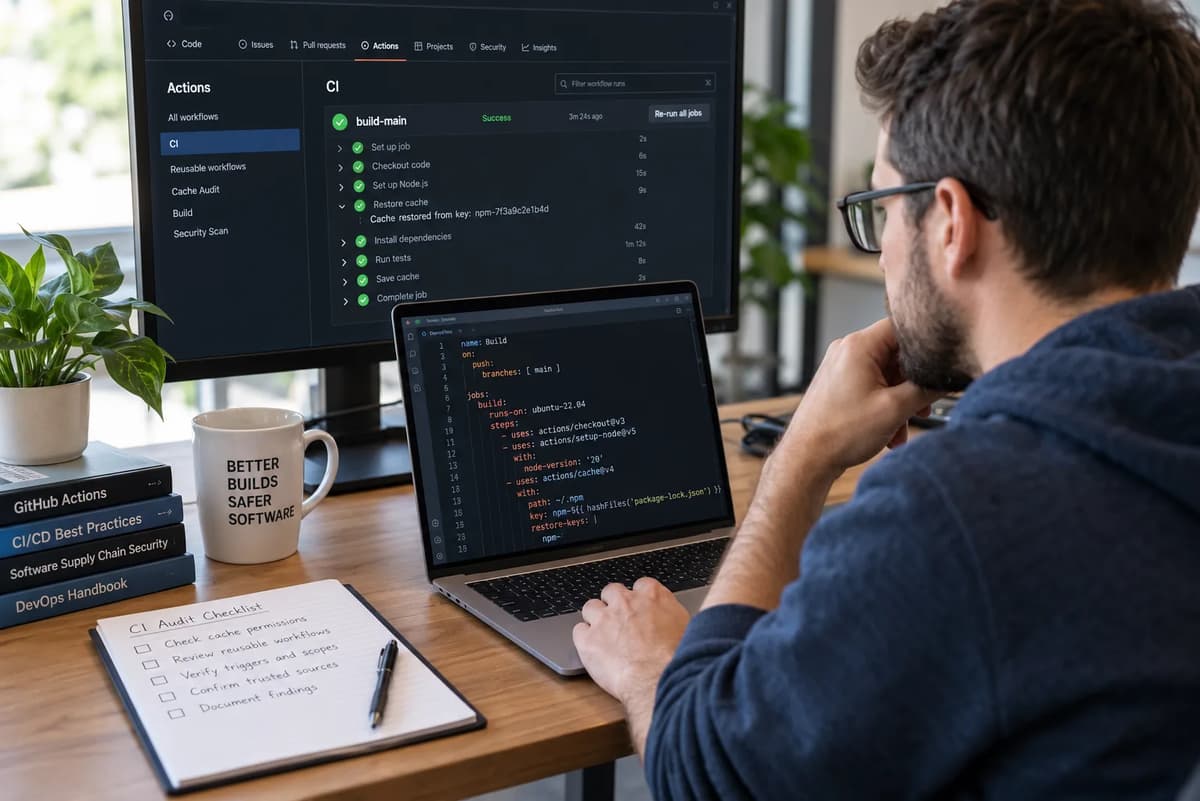
Consider a synthetic CI audit in which a success badge and a “Cache restored” message were mistakenly treated as proof of a secure build. Closer review shows that the cache could have been written by a different workflow from a separate branch than the release job. That scenario raises three distinct questions: (1) Effective access: which jobs can restore or save a cache, and under which cache-mode; (2) Addressable scope: which branches or pull-request contexts can use or update the key; and (3) Producer trust: whether the origin of the contents is acceptable or a clean rebuild is required. This playbook stays inside an owned disposable repository with inert text sentinels, no production credentials, no deployment permissions, and no execution of restored content. A green workflow and a cache hit are evidence about operations, not proof of software-supply-chain integrity. The disposition for each case is Allow, Restrict, Isolate, or Rebuild, based on the caller/callee graph, resolved mode, addressable scope, restore/save evidence, and recovery path.
Before any proposed run, write down the expected mode, eligible namespace, exact key, permitted operation, and acceptance outcome. That pre-run record prevents a reviewer from explaining an unexpected result after the fact. It also makes a green job useful evidence only when its observed restore and save behavior matches the permission graph that was approved in advance.
Define cache access separately from build approval
Scope and roles: Name the owned lab repository, the workflows under review, and their reusable-workflow call graph. For each job, record the intended cache consumer and security owner. Distinguish restore permission from save permission, and branch or key visibility from trust in the contents. A reusable job may have read-only cache access while still executing code; another may be allowed to write to a default-branch cache. Access answers who can read or write which cache. Trust answers whether a later build should accept those bytes. A cache is an optional optimization, not the canonical release artifact.
Restore and save capabilities: GitHub’s workflow syntax defines four cache-mode values: read, write, write-only, and none. The dependency-caching reference explains that a disallowed restore is treated as a cache miss and a disallowed save is skipped without failing the job. Record the effective mode and compare it with the runner’s ACTIONS_CACHE_MODE value.
Key scope: A cache key (often including branch name or workflow ref) is just a lookup. It defines which caches are addressable by branch or PR, not a secret. We keep our caches free of secrets or credentials (never caching secrets), and we avoid ever executing a restored artifact. We treat each cache entry itself as untrusted input until proven safe.
Trust and evidence: If a write-capable job processed untrusted code or inputs, treat any cache it saved as suspect. GitHub’s cache security guidance notes that cache contents are not signed or verified; an exact hit does not establish producer identity or content integrity. Isolate or bypass the cache and rebuild from trusted inputs instead of treating a successful restore as approval. The decision record uses four outcomes:
Allow: The cache access aligns with policy (trusted trigger, reviewed workflow) and contents are known good.
Restrict: We tighten a write limit (e.g. change caller’s mode to read) to cap a callee.
Isolate: We block a cache (e.g. delete it) if its origin is unknown or wrong.
Rebuild: We disregard the cache and force a fresh build from trusted inputs.
Throughout this audit, we keep the CI build approval decision separate. We are not clearing the path for a production release by a green badge; we are auditing the cache subsystem. Production deployment requires its own approval step after reviewing the audited results.
Inventory the actual workflow and runner configuration
First, record the exact CI definitions and runner environment. For every caller and reusable callee, capture the reviewed workflow revision, event trigger, job-level settings, runner image, runner version, repository visibility, cache paths, and cache keys. Include caches created by setup actions, not only explicit actions/cache steps. The synthetic inventory below uses action names rather than fabricated commit hashes; replace every action reference with a verified full commit SHA before running the lab.
Workflow / job | Trigger | Workflow and checkout ref | Runner record | Action revisions | Cache path and key |
build-main | push on main | Reviewed main workflow SHA and checkout SHA | ubuntu-22.04; record runner version and image digest | Reviewed full commit SHAs for checkout, setup-node, and cache | .npm; npm-${{ hashFiles('package-lock.json') }} |
build-pr | pull_request | Record workflow context and actual merge/head checkout SHA separately | Same recorded runner fields | Same reviewed full SHAs | .npm; isolated key includes the synthetic PR case ID |
test-reusable (caller) | push on main | Reviewed caller workflow SHA | Same recorded runner fields | Reviewed full SHAs for every action | .venv; venv-${{ runner.os }}-${{ hashFiles('requirements.txt') }} |
reusable-build (callee) | workflow_call | Callee resolved to one reviewed revision | Same recorded runner fields | Reviewed full SHAs for every action | Explicit callee path and key; do not assume inheritance |
This inventory ties every job to a specific execution context. For example, build-main should record the workflow SHA, checked-out SHA, runner version, and image digest rather than a generic “latest” label. Use the runner lifecycle and execution-environment inventory to capture runner support status, launch source, and image provenance without confusing those controls with workflow-level cache authorization.
Also record repository visibility and the explicit permissions block. GITHUB_TOKEN permissions and cache-mode are separate controls; contents: read does not prove that the job has read-only cache access. The proposed lab grants no deployment permission and exposes no production secret. Resolve every called workflow to the reviewed revision, and do not invoke a reusable workflow through an unreviewed moving ref.
Inventory completeness is an acceptance gate. Hold the audit if a setup action enables caching implicitly, a reusable workflow resolves through a moving branch or tag, the runner build cannot be identified, or the actual checkout SHA is missing. These gaps matter because an unchanged caller file can invoke changed callee logic, and a stable cache key can outlive the runner or action revision that originally populated it.
Separate code trust, token permissions and cache scope
To clarify the trust boundaries, map each trigger to the workflow definition, the code actually checked out, the event origin, available secrets, explicit GITHUB_TOKEN permissions, cache-mode, and cache scope. Use only inert text files in the fixture: no production libraries, executables, credentials, or deployment tokens.
Trigger event | Workflow and checked-out revision | Secret and token boundary | Addressable cache scope | Trust note |
push on main | Pushed workflow revision and actual checkout SHA | Explicit permissions; no lab secrets | Current/default branch under documented rules | Trusted repository code; cache contents still require policy |
pull_request | Event context plus actual merge/head checkout SHA | Fork restrictions vary by context; record the effective permissions | PR merge ref; eligible base/default caches may be readable | Untrusted head code or input |
pull_request_target | Base/default workflow; record any explicit checkout | Potentially privileged context; no secrets in the lab | Default-branch scope with low-trust read default | Untrusted event input; do not run PR head code |
workflow_run | Default-branch workflow plus triggering run ID and downloaded inputs | Separate permissions; no secrets in the lab | Default-branch scope with low-trust read default | Prior-run data may be untrusted |
schedule | Default-branch workflow and actual checkout SHA | Explicit permissions; no lab secrets | Default branch | Trusted trigger; revisions still require review |
Map the code revision a job actually executes
Record the workflow definition and checked-out ref separately. GitHub’s events that trigger workflows reference shows that pull_request normally uses a merge-ref context, while pull_request_target runs in the base-repository context; workflow_run uses the workflow file from the default branch. None of those event names alone proves what a later checkout step fetched, so preserve the actual checkout ref and commit SHA as separate evidence.
Record which cache namespaces are addressable
GitHub’s branch and pull-request cache scope rules distinguish capability from addressability. A workflow run can restore eligible caches from its current branch and the default branch; a pull-request run can also access eligible base-branch caches. A cache created by pull_request is scoped to refs/pull/N/merge and can be restored only by reruns of that pull request, not by the base branch or another pull request. Record these namespaces independently from cache-mode.
Test only caches belonging to the owned lab repository. Use the REST API endpoints for GitHub Actions cache, or the repository interface, to list the key, ref, version, ID, size, creation time, and last access time that GitHub exposes. A readable inventory does not prove which workflow or commit produced the contents, so retain that limitation in the evidence ledger.
Do not mix fork code or other repositories into this fixture. In production, a privileged event can still be dangerous if the job explicitly checks out or processes untrusted input. GitHub’s secure-use guidance treats that as a code-execution and credential boundary, while the cache reference treats write access as a separate capability. Keep publishing identity as a separate trust boundary as well: registry authority, workflow credentials, and cache authorization require different evidence.
Resolve the effective mode at each job
GitHub Actions workflow syntax allows cache-mode at the workflow level and at jobs.<job_id>.cache-mode; the job value overrides the workflow value. For every job, record the workflow setting, job override, trigger-derived default, and effective mode before evaluating any restore or save evidence.
Workflow-level cache-mode (if set).
Job-level override (if any).
Trigger type (push, PR, etc) to know the default.
We then compute the effective mode per the official table:
Workflow setting | Job override | Trigger-derived default | Effective mode | Restore allowed? | Save allowed? |
write | omitted | push → write | write | Yes | Yes |
omitted | read | push → write | read | Yes | No |
omitted | omitted | pull_request_target → read | read | Yes | No |
omitted | write-only | workflow_run → read | write-only | No | Yes |
write-only | omitted | push → write | write-only | No | Yes |
none | omitted | Any | none | No | No |
In the matrix above, the trigger-derived default applies only when cache-mode is omitted. The current dependency-caching reference classifies trusted triggers such as push as write by default and low-trust default-branch triggers such as pull_request_target and workflow_run as read. An explicit job value overrides the workflow value. Compare the resolved result with ACTIONS_CACHE_MODE at runtime.
Next, compare capability with actual operations. In write mode, restore and save are permitted. In read mode, restore is permitted and save is skipped. The expected evidence for a push job with no override is ACTIONS_CACHE_MODE=write; the expected evidence for a job capped at read is a normal restore or miss, followed by no completed save. These are proposed observations, not an execution transcript.
Removing one cache step does not prove that the job lacks cache capability. Another cache action, setup action, or toolkit call may still use the scoped cache token. REST API authorization is a separate control and must be audited independently. This cache-specific review complements CI/CD workflow design foundations; it does not replace broader pipeline ownership, review, and release controls. If runtime evidence differs from the documentation, place the case on hold and investigate the runner, action revision, workflow revision, and event configuration.
For quick reference: read permits restore only; write permits restore and save; write-only permits save only; none permits neither operation. Proposed tests should confirm each capability set and the trigger-derived default. Do not model read and write-only as adjacent levels on a single privilege ladder.
Resolve the mode independently for every job, including jobs in the same workflow. A workflow-level value may be narrowed or changed by a job override, while an omitted value depends on the event default. Record both the requested mode and the effective capability set. That distinction exposes cases in which the YAML looks restrictive at the top level but one job, setup action, or reusable callee still receives save rights.
Audit trigger defaults without relying on old shorthand
The current cache access rules for low-trust triggers are more specific than the old shorthand that every privileged event can always write a default-branch cache. Use a small event set and preserve each event’s ref context. The proposed matrix covers the following cases:
Push to main: This is a trusted trigger for the documented default. With cache-mode omitted, the expected mode is write, and a successful job may restore an eligible cache or save a new one in the applicable branch scope. An explicit cache-mode: none should result in neither operation.
Scheduled run: schedule is also in the documented set allowed to maintain default-branch caches. The proposed nightly case should resolve to write when no explicit limit is present, while still using only reviewed workflow code and inert inputs.
Pull request (pull_request): This event is handled through its merge-ref scope rather than the default low-trust rule. A PR run may create a cache under refs/pull/N/merge, and a rerun of that same pull request may restore it. The default branch and other pull requests cannot restore that PR-scoped cache.
Pull request target (pull_request_target): This event runs in the base-repository context and receives the documented read default for default-branch caches. The expected no-override result is an allowed restore and a skipped save. Explicitly setting cache-mode: write overrides that protection and therefore requires a separate security justification; never add the override merely to make the demonstration pass.
Workflow run (workflow_run): This completion-driven event can operate with credentials and data that differ from the triggering workflow, but its default-branch cache access is read by default. The proposed case should show writes skipped unless an explicit write-capable mode is declared. That cache result does not make downloaded artifacts or checked-out code trusted.
The proposed cases follow the live cache defaults table rather than a broad privileged-trigger label. A read-only cache default does not make the workflow safe by itself, because untrusted code execution, artifact handling, secrets, and token permissions remain separate boundaries. Likewise, a cache written under a pull-request merge ref is not a write to the default-branch namespace.
For each event, preserve four separate facts in the acceptance record: the workflow definition GitHub loaded, the ref and commit actually checked out, the default or explicit cache-mode, and the cache namespace that the resulting key can address. This prevents an event label from standing in for evidence. A trusted trigger can still run an unreviewed checkout, while a low-trust trigger with read-only cache access can still expose privileged tokens or process dangerous inputs.
Propagate explicit limits through reusable workflows
Next, trace cache-mode from the calling job into every reusable workflow it invokes. GitHub’s reusable-workflow cache rules distinguish a trigger-derived default from an explicit caller limit. Build paired cases for an omitted caller setting and a deliberate read cap.
Distinguish an implicit default from an explicit ceiling
Create paired cases in which the caller omits cache-mode and therefore receives the trigger default, or explicitly declares cache-mode: read. In both cases, call a reviewed reusable workflow that requests write. Record the caller revision, callee revision, event, requested mode, effective result, and whether the callee starts.
Caller without an explicit mode: On push, the trigger default is write, so a callee requesting write is expected to start with restore and save capability. On workflow_run, the caller’s implicit default is read, but the documentation says the callee may explicitly request write when no explicit caller limit exists. Treat that documented behavior as a reason to declare an explicit cap, not as permission to process untrusted input and write a privileged cache.
Caller with cache-mode: read: The caller now establishes an explicit ceiling. A callee requesting write or write-only is expected to fail workflow validation before it starts. A callee requesting read remains within the cap. Preserve the validation message and the unchanged cache inventory as evidence; do not widen the caller merely to make the test run.
We record outcomes in a table:
Caller setting | Trigger-derived default | Callee request | Expected outcome |
omitted | push → write | write | Allowed: callee can restore and save. |
omitted | workflow_run → read | write | Allowed by documented propagation because no explicit caller cap exists; security review required. |
cache-mode: read | push → write | write | Validation error: the run does not start. |
cache-mode: read | push → write | read | Allowed: restore only. |
cache-mode: read | push → write | write-only | Validation error: read and write-only are non-overlapping capabilities. |
Every row is a proposed test case. The dependency-caching reference treats read and write-only as different, non-overlapping capabilities, so a mismatch is an over-request even though both names may sound like positions on one scale. The decisive distinction is whether the caller explicitly limited the callee, not merely which default the trigger supplied.
Test capability mismatches rather than a numeric hierarchy
Test both mismatch directions: a write-only caller invoking a read callee, and a read caller invoking a write-only callee. Both are expected to fail validation because the requested operation is absent from the caller’s explicit capability set. Record the failure instead of converting the modes into a numeric “higher than” comparison.
The evidence table should state whether the callee started, which mode it requested, and which explicit caller cap applied. A reusable workflow used by many repositories needs a documented minimum capability contract. Prefer a design that can operate under read or none when writes are not essential.
Use inert sentinels to verify restore and save behavior
Use harmless sentinel files to verify what each job can do. Before each proposed test, create a unique nonsensitive text marker under a dedicated cache-audit path and assign an isolated key. The workflow must never execute restored content. After the run, compare the cache action messages and authorized cache inventory with the expected mode and scope.
Prefix each key with a synthetic case ID so one test cannot contaminate another. For example, use sentinel-push-CASE01 for a push case and sentinel-pr-CASE02 for a pull-request case. Omit broad restore-keys unless fallback behavior is the subject of the test.
Compare each proposed run with the expected capability and scope:
Read: If the exact eligible cache exists, the sentinel should be restored. If it does not exist, the result should be a normal miss and no new cache should be saved.
Never execute or source restored content. Record only presence, size, key, version, and inventory metadata.
Keep the fixture benign and isolated. In none mode, expect no restore and no save. In write-only mode, expect no restore and a save only after a successful job. The documented skipped-operation behavior should align with the action messages and post-job inventory.
The following YAML is illustrative. Replace the action tag with a reviewed full commit SHA before use, run it only in the owned disposable repository, and supply no secrets or deployment permissions:
name: Sentinel cache-mode lab
on:
  workflow_dispatch:

cache-mode: write

jobs:
  sentinel:
    runs-on: ubuntu-22.04
    permissions: {}
    steps:
      - name: Record effective mode
        shell: bash
        run: printf 'ACTIONS_CACHE_MODE=%s\n' "$ACTIONS_CACHE_MODE"

      - name: Restore inert sentinel
        id: sentinel-cache
        uses: actions/cache@v4
        with:
          path: .cache-audit/sentinel.txt
          key: sentinel-${{ github.run_id }}

      - name: Create sentinel on miss
        if: steps.sentinel-cache.outputs.cache-hit != 'true'
        shell: bash
        run: |
          mkdir -p .cache-audit
          printf '%s\n' 'TestXYZ' > .cache-audit/sentinel.txt

      - name: Record sentinel evidence without execution
        shell: bash
        run: |
          test -f .cache-audit/sentinel.txt
          wc -c < .cache-audit/sentinel.txt
With cache-mode: write at workflow level, the first run should miss and save the inert file after the job completes; an eligible rerun using the same key should restore it. Verify the effective mode, hit or miss output, post-job save message, and cache inventory. Those are expected observations until the lab is actually executed and recorded.
Detect skipped operations inside successful jobs
A green job does not prove that a cache was saved. Collect the cache action messages, hit or miss output, ACTIONS_CACHE_MODE value, and post-job save evidence, then compare them with the authorized cache inventory. Distinguish exact restore, fallback restore, forbidden restore, absent key, completed save, and skipped save.
If the mode disallows restore, as with write-only or none, the action should log an informational skip and continue as a cache miss. The job can still finish successfully.
If the mode disallows save, as with read or none, the job may still be green after a restore or miss. Confirm that no new cache ID, key, or creation timestamp appears. For a no-write test, that absence is positive control evidence.
If write or write-only applies, require the post-job save result and the corresponding cache inventory entry. Record the final key, ref, version, cache ID, and job result.
Two checks prevent an early log line from becoming a false approval:
Check the post-job outcome rather than one early log line
Review the complete job, including post-job steps. “Cache restored” appears before the main work; a later save may be skipped, may not run because the job failed, or may fail independently. Correlate the final job result with the before-and-after cache inventory rather than inferring persistence from the restore step.
Keep restore-key fallback visible
When restore-keys are present, record the key and cache version actually selected. A fallback hit is not an exact-key hit, even if GitHub accepts it. If the test requires one exact key, treat any fallback as a failed acceptance condition. Use narrow keys in the main matrix, then test fallback behavior in a separate case.
These checks ensure we do not misinterpret a green build as confirming a write. A missing “Cache saved” or a “save skipped” message is as meaningful as a “Cache saved” message.
The skipped-operation ledger should capture the expected operation, the action message, the cache-hit output, the effective mode, the selected key and version, the post-job save result, and the inventory delta. Use separate statuses for exact hit, fallback hit, miss, restore skipped, save skipped, save completed, and unresolved. “Unresolved” is the correct disposition when logs or inventory evidence are missing; do not convert uncertainty into an assumed miss or assumed save.
Qualify cache contents before privileged reuse
Even when a cache restores successfully and the build tests pass, qualify its provenance before reuse in a privileged job. Adopt a trusted-input policy that prefers a clean rebuild for release work. A cache hit is a performance signal, not a certificate of producer identity, immutability, or correctness.
Enforce lockfiles and trusted registries independently from cache status. If a dependency directory came from an unknown or low-trust writer, remove it and perform a clean package-manager install in the trusted workflow. A hash stored inside the same untrusted cache is not independent integrity evidence.
When the producer chain cannot be established, set the privileged consumer to cache-mode: none or use a new isolated namespace and rebuild from known sources. Document that action as a recovery decision rather than treating scanner success as permission to reuse the original bytes.
Separate “can this job access the cache?” from “should this workflow accept the contents?” A vulnerability scan can add context, but it does not establish effective cache authorization, identify the producer, or prove every restored byte harmless. For high-integrity release work, preserve a clean rebuild path.
Privileged reuse gate:
Producer workflow and revision are independently identified.
Lockfile and trusted source policy pass without relying on cached metadata.
A cache-disabled rebuild path is available and reviewed.
Unknown or low-trust contents are isolated rather than promoted.
A trusted rebuild must be independent of the suspect bytes. Start from the reviewed workflow and runner definition, enforce the committed lockfile, download from the approved dependency source, and apply the ecosystem’s available integrity checks. Compare the rebuilt result with the expected tests and release criteria, but do not use equality with the suspect cache as the trust proof. The rebuild record should name the inputs and controls that made the new result acceptable.
Build an evidence ledger without logging secrets
Compile an evidence ledger for every proposed or executed case. For each job, record:
The workflow and commit SHA of the YAML file.
The trigger event (push, PR number, workflow_run origin) and branch/ref.
Caller and callee relationships (who invoked whom).
The explicit cache-mode at workflow/job and the trigger default used.
The resolved mode (ACTIONS_CACHE_MODE env).
Which cache key was attempted, which was actually restored (if any), and cache ID.
Whether a save was attempted and if it succeeded or was skipped.
The final cache list (IDs) before and after.
Store the ledger in an access-controlled location and do not log secrets. The proposed runs use only nonsensitive markers. When listing or deleting caches through the REST cache API, use the minimum documented Actions repository permission, sanitize output, and never print the token. The following illustrative command deletes one cache by ID in the owned lab:
curl -L \
  -X DELETE \
  -H "Accept: application/vnd.github+json" \
  -H "Authorization: Bearer $GH_TOKEN" \
  -H "X-GitHub-Api-Version: 2026-03-10" \
  "https://api.github.com/repos/${OWNER}/${REPO}/actions/caches/${CACHE_ID}"
Record the repository, ref, key, version, and cache ID, but never echo GH_TOKEN. The cache listing API exposes useful metadata, but it does not independently identify the workflow name, workflow SHA, action revision, or human actor that produced the contents. State that limitation instead of filling the gap with inference.
Sanitize hashes, IDs, timestamps, and event data according to the evidence policy. Correlating a cache with job start times and unique test keys can support an investigation, but metadata correlation is not a cryptographic producer identity. Preserve uncertainty where the platform does not expose the field you need.
Security scanners and lockfile checks complement the ledger but do not replace the permission analysis. Use security scanning without confusing it with cache provenance: a passed scan describes the examined copy and rule set, not the cache writer’s authorization or the trustworthiness of every restored byte.
A practical ledger row therefore joins configuration evidence and runtime evidence: repository visibility; workflow and callee revisions; event, ref, and checkout SHA; workflow, job, caller, and callee modes; ACTIONS_CACHE_MODE; requested and selected keys; cache ref, version, and ID; restore outcome; save outcome; and final Allow, Restrict, Isolate, or Rebuild disposition. Limit access to the ledger because repository names, branch strategy, and workflow timing can still be operationally sensitive even when no secret value is recorded.
Contain a suspect cache before rebuilding
Stop or cap the unauthorized writer and consumer paths.
Inventory affected keys, refs, versions, IDs, and fallback selectors.
Preserve required evidence, then delete only the targeted caches.
Remove broad restore-key reachability and verify the old cache is inaccessible.
Rebuild from reviewed workflows and trusted dependency sources.
If a cache should not have been written, stop or restrict the writer path before cleanup. Inventory all affected keys, refs, versions, IDs, and restore-key prefixes. Use the targeted cache deletion endpoints with authorized credentials to remove only the identified entries; avoid a repository-wide destructive cleanup when narrower evidence-backed deletion is possible.
Changing only the primary key is insufficient when broad restore-keys can still select the old cache. Review every fallback prefix and consumer, remove the suspect selector, and confirm through inventory that the old entry is no longer addressable by the recovered workflow.
Then perform a trusted rebuild with cache-mode: none, or another reviewed cold-build path, using known workflow revisions, lockfiles, registries, and downloads. Do not use the suspect cache to validate its own replacement.
Preserve relevant logs and metadata under the owner’s evidence policy. Record why the write was unauthorized, which keys and selectors were contained, and which clean inputs produced the replacement. Never run suspect cached content merely to see what it does.
Close containment with an explicit invalidation record. State which writer was stopped, which consumers were capped or bypassed, which cache IDs were deleted, which restore-key prefixes were removed, and which clean build replaced the suspect entry. If a cache cannot be conclusively matched to the incident window, retain an Isolate decision for the broader selector rather than deleting unrelated repository caches or allowing an uncertain entry back into a privileged build.
Roll out reviewed cache limits and test the clean path
Version the reviewed caller and callee definitions, submit explicit cache-mode caps to code review, and exercise both a cache-hit path and a cold-build path. Stop the rollout when any of the following conditions appears:
Unexpected write: A cache is saved where the resolved mode or policy requires a skip. Stop and correct the workflow or caller cap.
Incorrect scope: The restored or saved cache uses an unintended ref, fallback key, version, or namespace.
Unreviewed callee change: The resolved reusable-workflow revision differs from the reviewed revision or changes its cache contract.
Missing evidence: The run lacks the effective mode, selected key, post-job result, inventory correlation, or clean-build comparison required by the acceptance record.
Maintain a functional cache-bypass route so the build can fetch and verify dependencies from trusted sources when caching is unavailable. Test cache-mode: none and isolated keys before approval. Document incident containment and recovery handover so the security owner, CI owner, and release owner agree on which caches were removed and which rebuild is authoritative.
Do not roll back to a known unsafe permission configuration because it is faster. Retain the reviewed narrower mode, document any performance cost, and improve the cache design only after the trust boundary and evidence path remain intact.
A final policy might allow cache-mode: write only for reviewed push or scheduled maintenance jobs, cap low-trust default-branch workflows at read, and require release jobs to support a cold build. The exact policy must match the tested repository and workflow graph; never silently trust a cache to satisfy a functional dependency.
Roll out the reviewed graph in small, observable cohorts. Begin with the disposable repository, then apply the same explicit caps only to workflows whose event, checkout, callee, and cache selectors match the tested pattern. Run an exact-hit case and a cold-build case for each cohort. Stop when a job gains unexpected write capability, addresses an unintended ref, resolves an unreviewed callee revision, or cannot produce the required before-and-after evidence.
Develop the security foundations behind CI controls
Effective CI controls rest on identity and access management, a secure software development lifecycle, risk assessment, threat detection, and incident-response planning. Cache authorization is one application of those foundations: least privilege defines the mode, secure review fixes the workflow and action revisions, and recovery planning determines how to contain and rebuild when the evidence fails.
For readers building those foundations, the Cloud Security Engineer Program lists a three-month format at 10–12 hours per week. Its page describes cloud-security fundamentals, identity and access management, secure SDLC, risk assessment, threat detection, and incident-response planning. Those capabilities are relevant to evidence-led CI control review; the page does not state that this exact GitHub Actions cache-mode laboratory is included.
IAM evidence: explicit token permissions and cache-mode limits.
Secure-SDLC evidence: reviewed workflow, callee, runner, and action revisions.
Incident-response evidence: containment, targeted invalidation, and trusted rebuild records.
The useful learning outcome is the ability to connect a declared control to observable evidence: who owns the identity, which workflow revision was reviewed, what operation was permitted, and how recovery returns the pipeline to a known state. That foundation applies across CI systems without promising that one course or one cache setting can certify an entire software supply chain.
Approve the permission graph, not the cache-hit label
A completed audit should produce a permission graph and evidence matrix, not a blanket approval for cache hits. Preserve the caller-to-callee graph, each job’s declared and effective cache-mode, the inert-fixture restore and save outcomes, the addressable scope, and the trusted rebuild record. Assign Allow, Restrict, Isolate, or Rebuild to each reviewed job, callee, and cache tuple.
Approval applies only to the exact reviewed workflow and action revisions, event context, cache selectors, and input policy. A successful restore proves that GitHub selected and extracted an eligible cache under those conditions; it does not establish a trusted producer or make every repository build supply-chain safe. State which triggers, repositories, runners, and fallback paths remain untested.
Approval checklist:
Every trigger, caller, callee, and effective mode is enumerated.
ACTIONS_CACHE_MODE and actual restore/save behavior match the resolved matrix.
Keys, refs, versions, and cache IDs match the intended scope.
No unauthorized writer remains, and suspect caches are isolated or deleted.
The clean cache-disabled path succeeds from trusted inputs.
Untested paths retain a Restrict or Isolate disposition until reviewed.