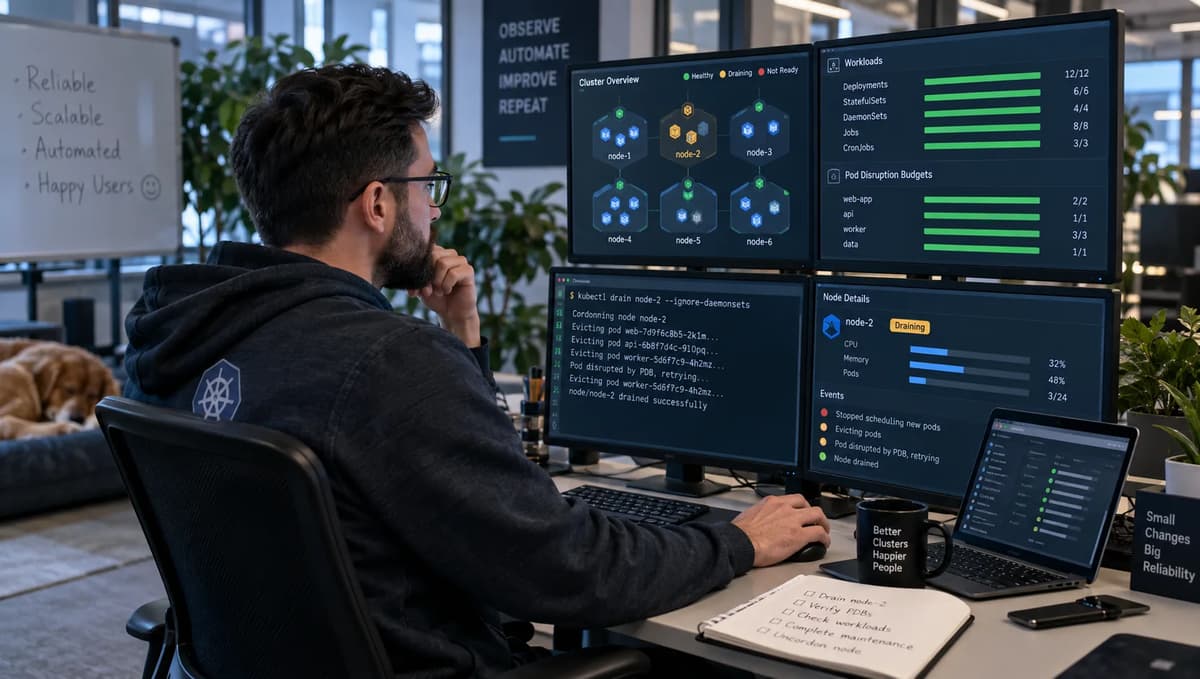
Consider two synthetic maintenance scenarios. In the first, a team cordons a node and runs kubectl drain, but the command stalls: two of three pods move and recreate successfully, while the third remains Pending. In the second, the drain finishes, yet client requests fail during shutdown because the only serving pod was evicted before a replacement became Ready. These are proposed test conditions, not reported execution results. They show why a completed command is not the acceptance criterion. The real question is whether the service recovered within its local contract. The decision must be Proceed, Hold, or Recover, supported by budget state, replacement feasibility, graceful termination evidence, and application behavior.
Define What Maintenance Must Preserve
Before draining a node, define a proposed local service contract. A synthetic example might allow no more than 5% request errors, no more than 100 ms of additional latency for two minutes, and full restoration within five minutes. These figures are not universal thresholds. The application owner must approve the request and latency gates, the platform owner must execute the maintenance procedure, and the incident decision-maker must have authority to pause or abort when a gate is breached. The responsibility table below makes that ownership visible.
Stakeholder | Responsibility |
Application Owner | Defines SLAs (error rate, latency, RTO), ensures probes/logging are in place. |
Platform/SRE Team | Computes allowed disruptions from PDB, checks node capacity, executes drain commands. |
Incident Commander | Monitors metrics during drain, authorizes overrides or rollbacks, documents the outcome. |
Kubernetes's disruption guidance makes clear that a PodDisruptionBudget (PDB) is not a service-level guarantee. The documented percentage-rounding behavior also matters: with maxUnavailable: 30%, a two-replica Deployment allows one voluntary disruption, leaving one replica available. A one-replica workload permits one disruption because the result rounds up, which can make the service completely unavailable. Treat the replica count and rounding result as explicit contract inputs rather than interpreting a percentage as an availability promise.
The API-initiated Eviction documentation defines the admission path that a PDB constrains. The Kubernetes disruptions guide separately distinguishes voluntary disruptions from involuntary failures such as node loss. A PDB cannot prevent an involuntary failure, although an already unavailable pod reduces the remaining allowance for a later voluntary eviction. Define those failure classes precisely before maintenance begins.
Base the decision on signals that represent client experience. The broader discipline of observability in DevOps helps teams establish a baseline from metrics, logs, and traces before the drain. Measure normal request success, latency, connection handling, and dependency health so that deviations are visible. The PDB counter is one control-plane signal, not a complete service-health metric.
Before draining, ensure you have visibility into the system: dashboards, logs, and alerts should be ready to show any anomalies. The acceptance criteria should explicitly mention acceptable error/latency increments, not just “drain must finish.” A blocked drain due to policy can be the correct safe outcome if your contract prioritizes availability over completing maintenance.
Inventory the Selected Workload and the Node
Gather the exact details of the workload on the target node and how they relate to disruption policies. Record:
Namespace, workload, and pods: e.g. namespace=payments, Deployment=checkout-service. List the specific pod names on that node (e.g. checkout-service-abcde-1, checkout-service-abcde-2).
Labels and selector: e.g. pods labeled app=checkout, role=frontend. Verify the PDB selector matches them.
Replica count: desired vs current healthy replicas. (E.g. desired=3, currentHealthy=2, one is NotReady.)
Readiness status: use kubectl get pods -o wide to confirm which pods report Ready=false.
Services and endpoints: note if a Service or Ingress points to these pods. Check kubectl get endpoints or kubectl describe svc.
PodDisruptionBudget: the PDB object for this workload. Include its .spec (minAvailable or maxUnavailable, and unhealthyPodEvictionPolicy) and .status (currentHealthy, desiredHealthy, disruptionsAllowed).
Node characteristics: kubectl describe node <node>. Note CPU/memory allocatable vs used, taints, labels, and any special resource (GPU, local storage) the pods need.
Pod constraints: affinity/anti-affinity, topologySpread, storage. E.g. if pods use a nodeAffinity for zone/us-east, ensure other nodes match that.
Confirm that the PDB selects the exact pods affected by the node drain. Under the policy/v1 selector rules, an empty selector matches every pod in the namespace. A mismatched selector can make the review about one pod set while the drain affects another. Treat a selector that matches extra pods, no pods, or pods covered by overlapping PDBs as a hold condition until the ownership and admission behavior are resolved.
Make a short table of any unmanaged pods or special cases on the node:
Pod type | Default drain behavior |
ReplicaSet or Deployment pods | Submitted through the Eviction API and subject to matching PDBs. |
DaemonSet pods | Drain requires --ignore-daemonsets and then leaves these pods on the node. |
Static pods | Not deleted by drain because they are managed directly by the kubelet. |
Unmanaged pods | Drain stops unless --force is used for pods that lack an eligible controller. |
Pods using emptyDir | Drain blocks unless --delete-emptydir-data is approved; the pod-local data is deleted with the pod. |
Use the inventory alongside your Kubernetes production hardening controls, such as security contexts and network policies, without turning this maintenance review into a security checklist. Proceed only when the selected pods, their controlling workload, their Services, and their disruption policy are unambiguous.
Calculate the Budget for the Replica Count That Exists
With the current replica count, compute exactly how many pods the PDB allows to be unavailable at once. Kubernetes documents integer and percentage behavior in Specifying a Disruption Budget for your Application. Perform the arithmetic against the desired replica count, then reconcile it with the time-stamped PDB status before another maintenance action begins.
Desired replicas | Policy | Spec value | Allowed unavailable | Synthetic interpretation |
3 | minAvailable | 2 | 1 | Three desired minus two required leaves one voluntary disruption. |
3 | maxUnavailable | 30% | 1 | ceil(3 × 30%) = 1. |
2 | minAvailable | 2 | 0 | No voluntary disruption is currently allowed. |
2 | maxUnavailable | 30% | 1 | ceil(2 × 30%) = 1, leaving one replica. |
1 | maxUnavailable | 30% | 1 | ceil(1 × 30%) = 1, so the single replica may be unavailable. |
The PDB percentage rules round fractional results up. That behavior is especially important at small replica counts: 30% of one replica still permits one disruption. Record the arithmetic in the acceptance packet; do not translate the percentage into a service-level guarantee.
After computing with the desired replica count, verify against the current status. For instance, maybe you scaled up or down recently. Use kubectl get pdb/<name> -o yaml to see status.currentHealthy and status.desiredHealthy. The field status.disruptionsAllowed tells you how many more evictions you can do right now. Ensure that this matches your expectation. If there’s any discrepancy, reconcile it before proceeding.
Compare Integer and Percentage Policies
Compare the configured form without silently substituting one policy for the other. An integer policy has no percentage rounding, while Kubernetes percentage calculations round up for both minAvailable and maxUnavailable. Treat the result as an admission count, not a soft service-level target.
For example, if you have 7 pods and minAvailable: "50%", Kubernetes requires 4 pods up (ceil(7*50%)). If you wrongly thought 3 would suffice, you could accidentally drop below the PDB during a drain.
Account for Pods That Are Already Unavailable
Now include any currently unhealthy or failed pods. If one pod is CrashLooping or the node was NotReady, that means currentHealthy < desiredHealthy. In our example above with 3 desired, maybe 2 are currently healthy, 1 crashed. The PDB’s remaining allowance is affected.
If one pod is already unavailable because of an involuntary event, the PDB status reflects that shortage. The Kubernetes disruptions model explains why involuntary loss still counts against the budget available for subsequent voluntary evictions. With three desired replicas, two healthy replicas, and maxUnavailable: 1, the next voluntary eviction is held until health recovers.
A reduced allowance is not evidence that Kubernetes miscounted. It can mean an earlier failure consumed the availability margin. A drain attempt may then receive HTTP 429. The Eviction API guidance requires the operator to inspect response details and current PDB state rather than treating the status code alone as proof of a budget rejection. If disruptionsAllowed is zero, hold the drain and restore health or capacity before continuing.
In summary, perform this arithmetic table with live data. E.g.:
PDB: minAvailable=2 on Deployment (desired=3)
CurrentHealthy=1 (one pod NotReady)
status.disruptionsAllowed = 1 (currentHealthy) - 2 (minAvailable) = -1 => 0 allowed (min 0).
Zero means stop. If it were positive, that’s the count of pods you could evict. Document these values with timestamps, because currentHealthy can change if pods recover.
Prove a Replacement Can Be Scheduled and Serve
An admitted eviction is not proof of safe maintenance; the successor pod must actually come up and work. Verify beforehand that a new pod can be scheduled and become useful.
Preflight checks:
Node capacity: identify at least one eligible node with sufficient allocatable CPU and memory for the workload's declared requests. Resource-usage metrics are supplemental; scheduling feasibility depends on requests, allocatable capacity, taints, affinity, topology, quotas, and other scheduler constraints.
kubectl top nodes
kubectl describe node <CANDIDATE_NODE>
Check that the sum of requests of existing pods plus the new pod’s requests does not exceed a target node’s allocatable.
Node and pod constraints: stage a disposable copy of the actual Pod template, including requests, affinity, tolerations, topology spread constraints, security context, and readiness probes. Do not use a simplified pod as proof that the production template can schedule.
kubectl apply -f <ISOLATED_LAB_POD_MANIFEST.yaml>
kubectl describe pod <LAB_POD>
kubectl delete pod <LAB_POD> --wait=true
If the pod remains Pending, fix affinity or add tolerance.
Volume and PVC: If pods use a PersistentVolume, try attaching it on another node. For AWS EBS or GCE PD, describe the PVC:
kubectl describe pvc <claim-name>Check for warnings like “multi-attach”. If it’s a local or ReadWriteOnce volume, ensure pod spec has anti-affinity or do not drain if another replica can’t mount.
Readiness and application checks: start the same application image with the same probes in the isolated lab. Confirm that Kubernetes readiness becomes true and that an application-level request through the intended Service path succeeds.
kubectl get pod <LAB_POD> -o wide
kubectl get endpointslice -l kubernetes.io/service-name=<SERVICE>
<APP_PROBE_COMMAND>  # configure a non-destructive request before use
If the staged pod does not become Ready, inspect kubectl logs <LAB_POD> and kubectl describe pod <LAB_POD>. Scheduling alone is not proof that the replacement can serve.
Service connectivity: Ensure the Service (if any) that fronts these pods has endpoints on other nodes already, so that traffic would reach the new pod.
Pod quotas or limits: Confirm that no cluster quota or namespace limit would forbid scaling a replica.
Create a quick checklist:
☐ Node free resources: Enough for 1 more pod on another node? (kubectl top nodes).
☐ Affinity and taints: Simulated scheduling succeeded.
☐ Volume attachments: PVC is Bound and attachable to another node.
☐ Readiness and application probes: Start a pod with the same image and probes; it reached Ready or passed health checks.
☐ Service endpoints: kubectl get endpoints shows other endpoints or will accept new.
If any item fails, you may need to wait or fix (e.g. add resources or temporarily scale up). Do not proceed if a successor would be stuck Pending. For example, if the workload requires a GPU and only the drained node has it, evicting that pod would bring capacity to zero. In that case the safe decision is to hold and ensure a GPU node is available before draining.
Blocked replacement example: the synthetic Pod template requests 2 GiB of memory, while every eligible node has less than 1 GiB of unallocated schedulable capacity. If the staged pod remains Pending with an insufficient-memory event, hold the drain, retain kubectl describe pod <LAB_POD>, and add capacity or change the reviewed workload requirements before retrying.
Choose the Unhealthy-Pod Policy Deliberately
The PDB configuration guide defines unhealthyPodEvictionPolicy for Running pods that are not Ready. The feature-state note identifies it as stable from Kubernetes 1.31; that historical milestone does not imply that version 1.31 is currently supported. Record the actual supported cluster and client versions used by the lab.
IfHealthyBudget is the API default. Under the documented unhealthy-pod policy, an unhealthy Running pod can be evicted only when the guarded application is not already disrupted. This preserves a chance for the impaired pod to recover, but it can hold a drain.
AlwaysAllow permits eviction of an unhealthy Running pod even when the budget's health requirement is not met. The same policy documentation does not remove protection for healthy pods. The trade-off is local: deleting the impaired instance may aid node maintenance, but it may also remove an instance that could have recovered.
Make the choice explicit in the reviewed PDB manifest. The proposed comparison below keeps the controller, workload, scheduling conditions, and versions constant while changing only the unhealthy-pod policy.
Observe IfHealthyBudget During a Stalled Drain
Design this as an isolated, unexecuted comparison. Scale the synthetic Deployment to three replicas, make one pod Running but not Ready, place that unhealthy pod on the target node, and confirm the PDB status before draining. With IfHealthyBudget and no remaining allowance, the Eviction API should reject the voluntary eviction. Capture the response body, pod condition, PDB status, scheduler state, and application symptoms. Do not fabricate console output if the test has not been run.
Capture logs or describe:
kubectl describe pdb checkout-pdb
kubectl get pod <UNHEALTHY_POD> -o wide
kubectl drain <TARGET_NODE> --ignore-daemonsets --timeout=5m
If the expected rejection is observed, it shows that the configured admission policy is holding the drain. Treat the unhealthy application state as a workload issue to diagnose before retrying, and do not present the expected outcome as executed evidence until the test has run.
Test AlwaysAllow Without Overstating Its Protection
In the same isolated lab, change only unhealthyPodEvictionPolicy to AlwaysAllow and repeat the observation. The documented policy behavior makes the unhealthy Running pod eligible for eviction even while the application is disrupted. Healthy-pod evictions remain subject to the budget.
Document the accepted risk. Removing the unhealthy instance may clear a node that must be serviced, but replacement may reproduce the same readiness failure. The unhealthy-pod policy description does not promise recovery or service availability. Continue to apply the client-error, latency, and recovery gates after the eviction.
The Kubernetes disruptions guide recommends considering AlwaysAllow to support draining misbehaving applications, while the PDB API default remains IfHealthyBudget. Preserve that distinction: one is operational guidance to consider, and the other is the default behavior. The reviewed manifest must state which risk the application owner accepts.
apiVersion: policy/v1
kind: PodDisruptionBudget
metadata: { name: checkout-pdb }
spec:
  minAvailable: 2
  selector: { matchLabels: { app: checkout } }
  unhealthyPodEvictionPolicy: AlwaysAllow
Keep the workload constant between tests, and note outcomes separately for clarity. Do not assume the policy is the only factor for any failure; always correlate with the metrics from the previous section.
Run a Bounded, Observable Drain
Use the Kubernetes safe-drain workflow only in an isolated rehearsal or an explicitly approved maintenance window. Before any state-changing command, record the API server and kubectl versions, the controller build or provider control-plane version available to the operator, and each target node's kubelet, operating-system image, and container-runtime version. A managed control plane may not expose every controller detail; record that limitation instead of guessing.
kubectl version -o yaml
kubectl get nodes -o wide
kubectl get node <TARGET_NODE> -o jsonpath='{.status.nodeInfo.osImage}{"\n"}'
kubectl get node <TARGET_NODE> -o jsonpath='{.status.nodeInfo.containerRuntimeVersion}{"\n"}'
kubectl cordon <TARGET_NODE>
kubectl drain <TARGET_NODE> \
--ignore-daemonsets \
--delete-emptydir-data \
--timeout=5m0sExplanation of flags:
--ignore-daemonsets: required when DaemonSet-managed pods are present; those pods are ignored rather than evicted by the drain.
--delete-emptydir-data: allows deletion of pods with emptyDir volumes, acknowledging local data will be lost.
Normal acceptance path: omit --force and --disable-eviction so the drain uses the Eviction API and respects PDB admission.
While this runs, have parallel observation commands:
kubectl get pods --selector=app=checkout -o wide  # track pods on all nodes
kubectl get events --watch                      # monitor related events
Record an evidence timeline. The table below is an illustrative schema, not observed output.
Relative time | Evidence milestone |
T+00 | Target node cordoned and exact drain command recorded. |
T+05 | The Eviction API request is admitted or rejected; preserve the response and PDB status. |
T+06 | Selected pod enters Terminating; capture deletion timestamp and grace period. |
T+10 | Replacement pod is scheduled, or Pending reason is recorded. |
T+15 | Replacement reports Ready; readiness evidence retained. |
T+16 | Application probe succeeds or the service gate remains failed. |
T+20 | Next eviction is attempted, held, or cancelled under the reviewed decision. |
Include these in a report: exactly which pod names and nodes, PDB status before/after, and service test results (e.g. curl output or client error rate).
When a pod eviction is denied, inspect the Eviction API response and the current PDB status. A budget-related rejection is a Hold condition, not permission to force-delete the pod. Preserve the reason, determine whether health or capacity can recover, and resume only after the reviewed gates pass.
Read-only checks: After the drain (or hold), run:
kubectl get pods -o wide     # final pod list and states
kubectl describe node <node> # check Node.Status and Pod list
Verify that the node has no evictable pods remaining except those you excluded (DaemonSets, etc). If it’s drained properly (either fully or up to the hold point), the node should show no ready pods that match the selector.
Do not use --force as the normal success path. The kubectl drain reference distinguishes it from --disable-eviction: the first addresses unmanaged pods, while the second bypasses the Eviction API and therefore PDB admission. Any exception requires explicit authorization and a recorded impact.
Separate a Policy Hold from a Dangerous Bypass
Document what kubectl drain reports. Typically, it will loop through pods and either evict them (OK) or stop on one. We create a quick reference:
Outcome | Indication (kubectl/drain) | Action |
Allowed eviction | 200 OK / “Eviction created” | Continue and wait |
Rejected by PDB | 429 Too Many Requests + PDB note | HOLD: Stop and diagnose |
API Rate limit | 429 with no PDB message | Retry after pause, or throttle |
Misconfiguration | 500 Internal Server Error | Fix config (e.g. overlapping PDBs) |
Timeout | Terminating pods not finishing | Investigate pod shutdown |
Log the exact API response, current PDB status, and pending workload state. A 429 accompanied by zero disruptionsAllowed supports a budget hold. A 429 that identifies throttling requires backoff and reduced concurrency, not a PDB change. A timeout requires termination and application-shutdown diagnosis.
Distinguish Eviction Rejection from API Throttling
An HTTP 429 might mislead an operator. To differentiate:
Inspect the response details. The Eviction API documentation notes that HTTP 429 can indicate either PDB rejection or request rate limiting, so the status code alone is not a verdict.
Check kubectl describe pod <pod> or events for a message.
If unclear, check kubectl get pdb <name> -o yaml for status.disruptionsAllowed. If it’s 0, it’s PDB (and should remain 0 until recovery).
If the PDB still shows an allowance but the API returns 429, investigate throttling or another admission path. Apply backoff, reduce concurrency, and preserve the response details before retrying.
Whenever you stop due to PDB, record it as a planned “hold” in your runbook, not as a failure. Update the evidence log with “Drained 1 pod, second eviction blocked by PDB (0 allowed remaining). Maintenance paused to fix the app.”
Review Force, Disable-Eviction and Local-Data Flags
Understand these bypass options as exceptions:
--force allows drain to continue when pods lack an eligible controller. It does not mean “ignore the PDB.” Use it only after confirming the selected unmanaged pods and accepting their loss or manual recovery requirements.
--disable-eviction switches drain to direct pod deletion rather than the Eviction API. That path bypasses PDB admission and can violate the service contract. Require explicit exceptional approval and retain the reason.
--delete-emptydir-data: Instructs the kubelet to delete the contents of emptyDir volumes on pod termination. This is not a bypass for scheduling or budgets, but it means any in-memory cache or temporary data in the pod is gone. Log this too if used, as it affects data integrity.
Create a quick summary table in your notes (for reviewers):
Flag | Effect | Reviewed use |
Continues despite unmanaged pods; does not itself bypass PDB admission for managed pods. | Only when the affected unmanaged pods and recovery impact are explicitly accepted. | |
Uses direct deletion instead of the Eviction API, bypassing PDB checks. | Exceptional, approved path when the service contract accepts the additional loss. | |
--delete-emptydir-data | Allows deletion of pods using emptyDir; their pod-local data is lost. | Only when the local data is disposable or reproducible. |
Treat these flags as exceptional controls, not routine remedies for a blocked drain. If direct deletion is proposed, pause and reassess timing, replica health, replacement capacity, and the service contract. An emergency exception still needs a named approver and an evidence record.
Measure Termination and Application Recovery
Track end-to-end impact with a proposed, non-production request stream before, during, and after the drain. The compact table below is a synthetic evidence format; its values are illustrative, not measured results.
Synthetic phase | Pods Running | Endpoint 200s | Endpoint 503s | Notes |
Baseline | 3 | 100 | 0 | Illustrative only; replace with measured evidence. |
During drain | 2 | 80 | 20 | One pod gone, transient errors. |
Recovery | 3 | 100 | 0 | Replacement came up, healthy. |
Also correlate Kubernetes events with external behavior. For each pod evicted, note:
Eviction start (TerminationGracePeriodSeconds begins).
Pod deletion timestamp.
Replacement pod creation and Ready time.
Any logged application errors (e.g. connection refused for a few seconds).
Load balancer logs if available.
Correlate resource, request, error, latency, and dependency signals through the maintenance window. Broader DevOps monitoring practices provide context for this evidence, but the acceptance gate must remain specific to this workload and request path. A readiness transition and a client-visible failure can occur at the same time; retain both facts.
If the new pod becomes Ready (kubectl get pods shows ReadyCount = desired) but your application still fails its own health checks, do not ignore it. Record that as a problem. For example: “New pod is Ready at T=120s, but backend database connections are failing; see log snippet…”. This means your gate wasn’t actually passed, despite readiness. The evidence packet should note such cases rather than using “pod count = desired” as the sole criterion.
Test Concurrent Maintenance and Competing Rollouts
In a disposable environment, compare one drain with two concurrent drains. The safe node-drain guidance notes that simultaneous drain commands still honor PDBs. With three replicas and minAvailable: 2, only one voluntary eviction should be admitted at a time. Capture both command transcripts and the single shared PDB status.
Run a separately labelled Deployment rollout case rather than treating it as another drain. The Deployment rolling-update strategy has its own maxUnavailable and maxSurge controls; the default rolling-update maxUnavailable is 25% when not specified. The Kubernetes disruptions guide also distinguishes controller-driven rolling updates from voluntary Eviction API requests. A PDB does not constrain Deployment rollout deletions in the same way that it constrains a node drain.
Does the Deployment strategy permit another pod to be unavailable while the drain is in progress?
Do controller events and ReplicaSet status show rollout pressure or unavailable replicas?
Do the client-facing error, latency, and recovery gates remain within the local contract?
The expected lesson is that maintenance and rollout controls can act independently. A synthetic record might show a drain evicting pod A under the PDB, followed by the Deployment controller deleting pod B under its rollout strategy. If two replicas are then unavailable, the service gate can fail even though each controller followed its own rules. Coordinate the changes rather than assuming the PDB supplies separate protection against every disruption path.
Apply established CI/CD rollout practices to prevent an application release from competing with infrastructure maintenance. Keep the rollout record distinct from the Eviction API record so reviewers can identify which controller changed availability.
Recover from a Partial Drain Without Inventing Rollback
If the drain stops, use a controlled recovery sequence. First, stop further maintenance and record the exact hold reason. Second, decide whether the target node should remain cordoned for repair or be made schedulable again. Uncordoning is an explicit change:
kubectl uncordon <TARGET_NODE>Uncordoning only reopens the node to scheduling; it does not resurrect deleted pods or restore emptyDir data. Third, reconcile the desired and available replica counts and confirm that replacements can schedule. Fourth, require the application and platform owners to approve the next action, such as restoring health, adding capacity, or increasing replicas under change control. Fifth, rerun the application and service gates before any drain resumes.
Do not call this a rollback unless an actual reversible deployment change is being undone. Recovery from a partial drain means stopping further loss, restoring schedulability when appropriate, and allowing controllers to create replacement instances. Deleted pods are not resurrected, and erased local data is not restored by uncordoning.
T+00: Drain paused because disruptionsAllowed reached zero; two of three replicas are Ready.
T+05: Target node uncordoned after platform and application approval.
T+07: Replica count temporarily increased under reviewed change control; a replacement schedules.
T+10: Desired replicas are Ready and the application probe passes.
This shows the outcome of stopping maintenance. The important thing: agree with the team on what “safe state” means before continuing.
Approve with an Eviction-to-Service Evidence Packet
For final sign-off, assemble everything into a reviewable report (a "drain packet"). It should include:
Workload and Policy: Name of the workload (Deployment, namespace, image tag), the PDB manifest (minAvailable/maxUnavailable, unhealthyPodEvictionPolicy).
Versions: Record the API server, kubectl, controller or provider control-plane build, kubelet, node operating-system image, and container-runtime versions that were actually observed.
Initial Status: Timestamped kubectl get pdb showing .status.currentHealthy/.desiredHealthy.
Command Log: The exact kubectl drain command and flags used.
Eviction Results: A timeline as above, noting each pod evicted or blocked, with the PDB remaining allowance. If a drain was held, mark why (e.g. budget exhausted).
Replacement Pods: Node name and status of each new pod that came up.
Service Health: Pre/post metrics or test results (e.g. integration test logs or endpoint returns). Confirm the service remained within SLAs.
Exception Flags: Any use of --force, --disable-eviction, or similar. Justify them.
Decision: State Proceed, Hold, or Recover and tie it to evidence, such as “Proceed because one disruption was allowed and the replacement served within the local gate,” or “Hold because disruptionsAllowed was zero.”
Retain synthetic accepted, held, and failed examples in the packet format, but never present them as executed results. A reviewer should be able to identify the exact reason for a decision without rerunning the maintenance. A completed drain is insufficient unless the application stayed within the approved gates.
Store manifests, selector changes, command templates, and approvals in version control. Clear infrastructure-as-code change ownership makes it possible to trace who reviewed the PDB, which labels and flags were used, and which versioned change governed the maintenance.
Rehearse Maintenance in Four Controlled Stages
Use the following as an illustrative, proposed 30-day rehearsal plan rather than a claimed schedule:
Inventory and lab (Days 1–2): in an isolated staging cluster, select a disposable replicated stateless Deployment with three pods. Define a PDB, record versions, run the preflight checks, and capture the evidence schema. (Owner: application owner and SRE.)
Policy Experiments (Day 3–7): On the same lab, vary conditions: introduce an Unready pod, try IfHealthyBudget vs AlwaysAllow, simulate insufficient capacity. Document outcomes for each. (Owner: SRE).
Low-Risk Rehearsal (Day 8–15): Select a non-critical production namespace (or a canary app). Schedule a real node drain during off-peak, with full monitoring on standby. Write up that evidence packet for stakeholder review. (Owner: SRE on-call).
Rollout and scaling (Days 16–30): expand only to additional replicated stateless workloads whose owners approve the same evidence model. Stateful quorum systems require a separate storage, quorum, failover, and recovery playbook; this stateless result does not qualify them. (Owner: platform and workload owners.)
Put this plan in a calendar with responsible teams and “stop” criteria (e.g. abort if errors > X%). Don’t assume success on one service means all services are safe. Each workload and cluster may behave differently.
Connect the Lab to DevOps Practice
This reviewable maintenance exercise combines version-controlled infrastructure, Linux and scripting, container orchestration, CI/CD coordination, and monitoring. Those foundations help an operator explain not only what command ran, but why the selected workload was safe to move and how the service recovered.
The Refonte Learning DevOps Engineer Program lists a three-month commitment of 12–14 hours per week and foundations including Linux and scripting, Git and GitHub, CI/CD, Docker and Kubernetes, Terraform, cloud platforms, and monitoring and logging. Review the live programme page for current details. This article does not claim that the programme includes this exact PDB drain lab.
Require More Than a Completed Drain
A finished kubectl drain does not prove success. Approval requires the correct target, an understood policy, a feasible replacement, controlled termination, and observed service recovery within the local contract. A budget block or Pending replacement can be the correct Hold result.
Proceed only when the eviction-to-service evidence is complete. Hold when the policy, capacity, or application gate is unresolved. Recover when maintenance has already changed workload state and the service must be stabilized before another action.