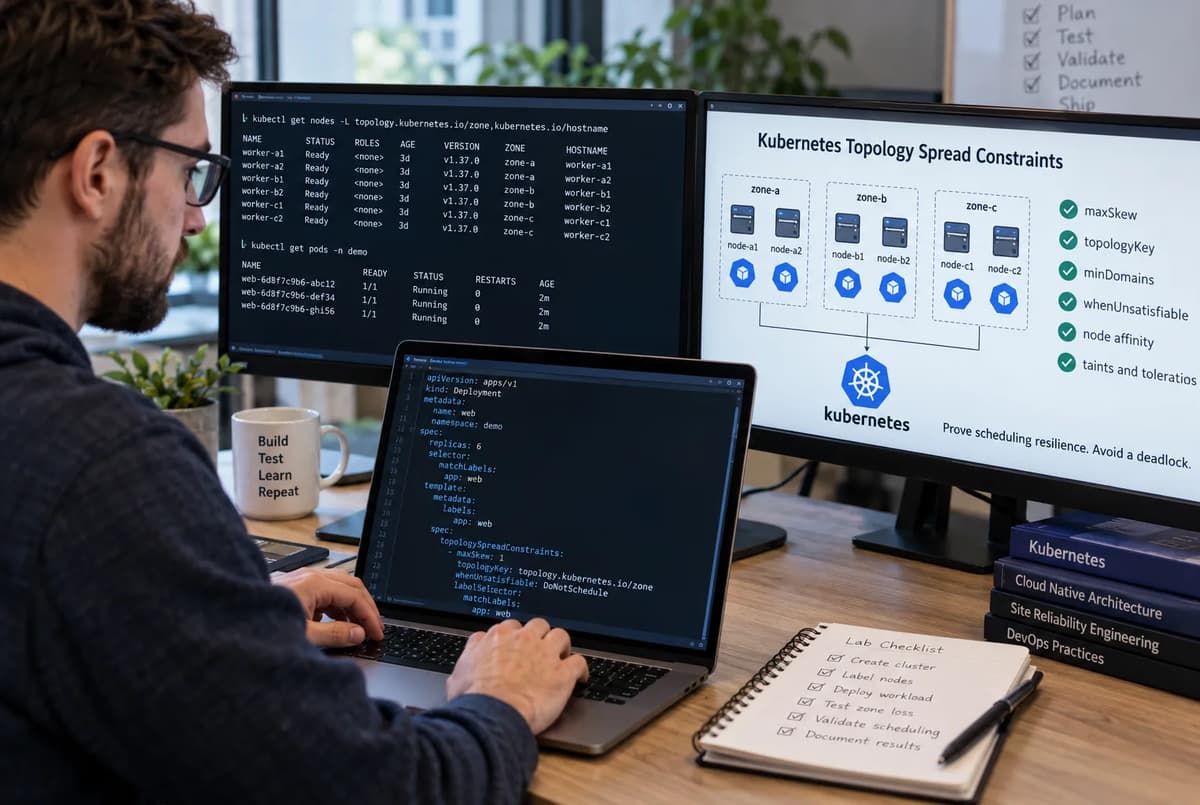
A topology spread constraint does not, by itself, prove workload resilience. It describes how the scheduler should evaluate an incoming Pod against Pods already present, topology domains that remain eligible, and other scheduling filters. With whenUnsatisfiable: DoNotSchedule, a configuration that looks perfectly balanced in the nominal state can become impossible to satisfy as soon as a zone, node set, or node class is no longer eligible.
Documented Kubernetes behavior. The primary reference for this playbook is Kubernetes: Pod Topology Spread Constraints, last modified October 27, 2025; accessed September 22, 2026. Kubernetes defines maxSkew, minDomains, topologyKey, whenUnsatisfiable, labelSelector, matchLabelKeys, nodeAffinityPolicy, and nodeTaintsPolicy, and states that multiple constraints are combined with logical AND.
Evidence discipline. Every important conclusion in this article belongs to one of four categories: documented Kubernetes behavior, engineering inference, proposed experiment, or actual observation. None of the experiments described below was executed while writing this article. Every "actual observation" field must therefore remain empty until the lab is run.
The objective is not to show that a Deployment turns green. The objective is to show that, after a defined topology change, the intersection of all constraints still leaves the scheduler at least one acceptable placement whenever the resilience contract requires one.
Why topology constraints need acceptance testing
Documented Kubernetes behavior. With DoNotSchedule, maxSkew acts as a hard constraint on the placement of a new Pod. With ScheduleAnyway, Kubernetes may still place the Pod when the other scheduling rules permit it and uses topology spread as a scoring preference. The same manifest can therefore express either an admission gate or a non-blocking balancing objective.
Engineering inference. "The Deployment is 5/5" proves only that five Pods could be placed in the cluster's current state. It does not prove that a sixth Pod, a replacement Pod, or a Pod from a new revision will remain placeable after a domain disappears. Acceptance testing must therefore exercise future candidate-node states, not only the nominal state.
Scheduling and eviction must also be separated. Node maintenance can trigger both, but they answer different questions: a PDB governs tolerance for voluntary disruptions, while topology spread constraints determine where a new Pod may be placed. The Refonte Learning node-drain and PDB acceptance playbook covers that boundary separately.
Item to prove | Sufficient evidence | What is not sufficient |
Nominal placement | Measured distribution and reproduced skew calculation | Deployment Available |
Domain loss | New Pod schedulable or blocking explicitly accepted | Existing replicas still Running |
DoNotSchedule | Candidate-node set calculated and tested | Syntactically valid YAML |
Resilience | Success for every failure state in the contract | One zone-loss test |
No scheduling deadlock | Non-empty intersection of all constraints | Each constraint examined separately |
Acceptance criterion. A green state is an observation of the present. Scheduling resilience is accepted only when the planned failure states also retain a demonstrable placement, or when blocking is explicitly the intended safety behavior.
Build a synthetic cluster that exposes topology assumptions
Proposed experiment. Use a disposable local cluster with one control plane and six workers, modeled as three zones with two nodes each: zone-a, zone-b, and zone-c. Workloads, namespaces, labels, and taints must be synthetic. Production clusters, customer workloads, real secrets, and unbounded cloud resources are outside the lab boundary.
The target lab version is Kubernetes v1.37.0. The v1.37 branch was released on August 26, 2026; see Kubernetes v1.37: Garhwal, published August 26, 2026; accessed September 22, 2026. The current API reference is generated for v1.37.
Record the version that is actually executed rather than assuming it:
mkdir -p evidence
kubectl version -o yaml > evidence/00-kubernetes-version.yaml

kubectl get nodes \
  -L topology.kubernetes.io/zone,kubernetes.io/hostname \
  -o wide > evidence/01-node-topology.txt
Then assign zones to the six workers:kubectl label node worker-a1 worker-a2 \
topology.kubernetes.io/zone=zone-a
kubectl label node worker-b1 worker-b2 \
topology.kubernetes.io/zone=zone-b
kubectl label node worker-c1 worker-c2 \
topology.kubernetes.io/zone=zone-c
kubectl create namespace topology-acceptanceThe Refonte Learning guide to DevOps practices and Kubernetes provides broader DevOps context. This lab intentionally remains limited to scheduler behavior.
Lab property | Proposed value | Evidence to retain |
Kubernetes | Target v1.37.0 | kubectl version -o yaml |
Workers | 6 | Node list |
Zones | 3 × 2 workers | Zone labels |
Namespace | topology-acceptance | Manifest or command |
Workloads | Synthetic only | YAML used |
Credentials | No real credentials | Manifest review |
Cloud resources | No unbounded resources | Local configuration |
Actual observation: none. The 00-kubernetes-version.yaml file becomes the execution source of truth and must accompany the acceptance result.
Model domains, labels, and eligible nodes before testing
Documented Kubernetes behavior. topologyKey names a node-label key. Nodes with the same value for that key belong to the same domain. For topology.kubernetes.io/zone, values typically represent zones; for kubernetes.io/hostname, each hostname value can form its own domain. Eligible domains also depend on nodeAffinityPolicy and nodeTaintsPolicy.
The generated v1.37 definition, Kubernetes Pod API: TopologySpreadConstraint, last modified August 26, 2026; accessed September 22, 2026, confirms these fields and their defaults. nodeAffinityPolicy: null is equivalent to Honor, while nodeTaintsPolicy: null is equivalent to Ignore.
Documented Kubernetes behavior. For explicit constraints, a node missing a required topologyKey is bypassed. Pods placed on that node do not participate in the corresponding maxSkew calculation. Topology-label consistency is therefore a test precondition, not a cosmetic detail.
Before each scenario, produce this model:
Node | Zone | Hostname? | Affinity? | Taint OK? | Eligible? |
worker-a1 | zone-a | yes | yes | yes | yes |
worker-a2 | zone-a | yes | yes | yes | yes |
worker-b1 | zone-b | yes | yes | yes | yes |
worker-b2 | zone-b | yes | yes | yes | yes |
worker-c1 | zone-c | yes | yes | yes | yes |
worker-c2 | zone-c | yes | yes | yes | yes |
Proposed experiment. Temporarily remove the zone label from worker-b2, create a candidate Pod, and compare the candidate set with the nominal model. The test can show that missing labels change the calculations and the nodes considered. It cannot show that Kubernetes will automatically reconstruct or correct an incorrect topology label.
Validate maxSkew with deterministic replica placements
The most reliable way to test maxSkew is to remove randomness from the starting state. Create seed Pods with the same label as the labelSelector, but bind them explicitly to nodes to build a known distribution. Because nodeName bypasses the scheduler, those seed Pods are never scheduling evidence. They only build the fixture.
The candidate Pod, by contrast, must pass through the scheduler.
Example zone constraint:
topologySpreadConstraints:
- maxSkew: 1
  topologyKey: topology.kubernetes.io/zone
  whenUnsatisfiable: DoNotSchedule
  labelSelector:
    matchLabels:
      app: tsc-lab
Calculating actual skew against the configured maxSkew
Documented Kubernetes behavior. Under DoNotSchedule, Kubernetes compares the matching-Pod count in the target domain with the global minimum. Unless minDomains changes the rule, that minimum is the smallest matching-Pod count across eligible domains. The official 2/2/1 example with maxSkew: 1 allows the incoming Pod only in the third domain.
For an incoming Pod that also matches the selector, use this acceptance calculation:
G = global minimum
candidateSkew(D) = existingMatchingPods(D) + 1 - G

Domain D is acceptable under DoNotSchedule
when candidateSkew(D) <= maxSkew.
With 2/2/1, G=1. Placing the new Pod in zone-c produces 2-1=1, so the placement is allowed. Placing it in zone-a produces 3-1=2, so it is blocked. This is the case described in the Kubernetes API.
The 3/1/1 case exposes an important nuance. G=1. Adding a Pod to either zone that contains one Pod produces a target count of two and a candidate skew of one. The scheduler can therefore improve an already imbalanced distribution incrementally without requiring the entire cluster to return immediately to a maximum difference of one. That conclusion follows directly from the definition of skew applied to the target domain.
Initial split | G | Target | After | Skew | Expected |
2/2/1 | 1 | zone-c | 2 | 1 | allowed |
2/2/1 | 1 | zone-a | 3 | 2 | blocked |
3/1/1 | 1 | zone-b | 2 | 1 | allowed |
3/1/1 | 1 | zone-a | 4 | 3 | blocked |
1/1/1 | 1 | any zone | 2 | 1 | allowed |
Proposed experiment. Repeat the test with topologyKey: kubernetes.io/hostname. Seed five Pods on five of the six workers, then submit the sixth. With maxSkew: 1, the node with a count of zero should be the placement that reduces the imbalance. This proves node-level behavior for that state; it does not prove that zone and hostname constraints will remain jointly satisfiable after a failure.
Test DoNotSchedule versus ScheduleAnyway
Documented Kubernetes behavior. DoNotSchedule is the default value of whenUnsatisfiable and rejects a placement that would violate the constraint. ScheduleAnyway turns spread into a preference: the scheduler continues and favors topologies that reduce skew, provided the other scheduling mechanisms allow the node.
DoNotSchedule as a deliberate admission gate
Engineering inference. DoNotSchedule should not be read as "more resilient." It means, "leave this Pod Pending rather than cross this concentration limit." That can be an excellent policy for a workload that refuses excessive concentration, but it can conflict with an objective that requires every replica to be recreated after a zone is lost.
Proposed experiment. Build 2/2/1, then artificially restrict candidate nodes to the two zones that already contain two Pods. Test DoNotSchedule first, then repeat the same state with ScheduleAnyway. Capture the Pod, its Events, and any final nodeName.
Mode | Spread violation? | Spread effect | Expected evidence |
DoNotSchedule | no | hard filter | Pod remains Pending when no valid candidate exists |
ScheduleAnyway | yes | scoring preference | Placement possible when other filters pass |
ScheduleAnyway + blocked affinity | not relevant | spread does not override affinity | Pending |
ScheduleAnyway + blocked taint | not relevant | spread does not override the taint | Pending |
This test can show that spread is no longer the hard cause of blocking under ScheduleAnyway. It cannot show that the Pod will always be schedulable: resources, affinity, taints, and other plugins can still eliminate every node.
Test minDomains when a topology domain disappears
Documented Kubernetes behavior. minDomains can be used with whenUnsatisfiable: DoNotSchedule. When the number of eligible domains is lower than minDomains, Kubernetes sets the global minimum to zero. When the eligible-domain count reaches or exceeds minDomains, the field does not affect the calculation. Omitting the field is equivalent to minDomains: 1.
Before Kubernetes v1.30, minDomains depended on the MinDomainsInPodTopologySpread feature gate, which had been enabled by default since v1.28. The v1.37 lab is outside that historical compatibility window, but an organization replaying the test on an older version must verify the feature gate.
When minDomains changes the global minimum
Consider five replicas distributed 2/2/1 with:
maxSkew: 1
minDomains: 3
topologyKey: topology.kubernetes.io/zone
whenUnsatisfiable: DoNotSchedule
Proposed experiment. Remove zone-c completely from the Node model. Only two eligible domains remain. Because 2 < minDomains(3), G=0. If the two remaining zones each contain two Pods, adding a Pod would produce 3-0=3, which exceeds maxSkew: 1. The new Pod should therefore remain unschedulable. That result follows directly from the documented formula.
State | Eligible domains | Min domains | Global min | Candidate | Result |
2/2/1 | 3 | 3 | 1 | zone at 1 → 2 | skew 1, allowed |
2/2 after zone loss | 2 | 3 | 0 | 2 → 3 | skew 3, blocked |
1/1 after zone loss | 2 | 3 | 0 | 1 → 2 | skew 2, blocked |
2/2 after zone loss | 2 | 1 | 2 | 2 → 3 | skew 1, allowed |
Engineering inference. minDomains: 3 can be the exact mechanism that converts the loss of a zone into a deliberate halt in placement. This is not a scheduler bug. If the acceptance contract requires replicas to be recreated across the two remaining zones, this configuration fails that contract despite its anti-concentration benefit.
The test proves the behavior for the counts and domains examined. It does not prove resilience for other ReplicaSet sizes because a different starting count can produce a different skew.
Test node affinity and node selector interactions
nodeSelector and node-affinity rules reduce the nodes on which a Pod can actually be placed. Kubernetes: Assigning Pods to Nodes, last modified February 10, 2026; accessed September 22, 2026, documents those mechanisms. For topology spread constraints, nodeAffinityPolicy also controls whether those restrictions affect the skew calculation.
The distinction matters: nodeAffinityPolicy: Ignore does not remove the Pod's real affinity. It only tells the spread calculation to ignore that affinity when deciding which nodes and domains to count. A domain can therefore influence skew even though the Pod still cannot be placed there.
For broader cloud-design context without turning this article into a general introduction, see the Refonte Learning Cloud Development Architect guide.
Affinity narrowing the eligible topology domains
Proposed experiment. Start with zone-a=2, zone-b=2, and zone-c=0. Add required node affinity that permits only A and B.
With nodeAffinityPolicy: Honor, which is also the behavior when the field is null, C is excluded from the spread calculation. A and B therefore have a minimum of two, and a candidate placed in either domain reaches a skew of one.
With Ignore, C can participate in the calculation with a count of zero while affinity still prevents the Pod from going there. Under DoNotSchedule and maxSkew: 1, A and B can then be rejected because of C's low count, leaving an empty intersection.
Affinity | Policy | Counted domains | Candidates | Risk |
A/B/C | Honor | A/B/C | A/B/C | nominal |
A/B only | Honor | A/B | A/B | aligned with eligibility |
A/B only | Ignore | A/B/C | A/B | C can distort the minimum |
no valid zone | either | depends on policy | none | blocking outside spread |
This scenario proves whether the selected policy matches the operational definition of a usable domain. It does not prove that the affinity rule itself is appropriate for the workload; that decision belongs to a separate architecture contract.
Test taints and nodeTaintsPolicy interactions
The primary source Kubernetes: Taints and Tolerations, last modified July 27, 2026; accessed September 22, 2026, states that a NoSchedule taint rejects new Pods without a matching toleration. nodeTaintsPolicy does not replace that rule; it determines which nodes participate in the spread calculation.
nodeTaintsPolicy: Honor includes untainted nodes and tainted nodes tolerated by the incoming Pod. Ignore includes all nodes in the calculation without considering taints. A null value is equivalent to Ignore, unlike nodeAffinityPolicy, where null is equivalent to Honor.
This distinction should be verified explicitly during security and scheduling reviews. The Refonte Learning cloud security guide provides broader security context, while this test remains focused on scheduler eligibility.
Proposed experiment. Build A=2, B=2, and C=0, then apply this taint to both nodes in C:
kubectl taint nodes worker-c1 worker-c2 \
lab.refonte.dev/blocked=true:NoSchedule
Give the candidate Pod no matching toleration.
Policy | C counted? | Pod can use C? | Expected consequence |
Honor | no | no | A/B may remain valid |
Ignore | yes | no | C=0 can make A/B too skewed |
Honor + toleration for C | yes | yes | C becomes usable and counted |
field omitted | yes | no without a toleration | equivalent to Ignore |
Engineering inference. This is one of the easiest paths to an apparent "deadlock": the calculation sees a sparsely populated domain, but the taint filter forbids the Pod from entering that exact domain. Kubernetes is not internally deadlocked; the constraint intersection is empty.
This test can prove that intersection for the defined taints. It proves nothing about future taints or taints added dynamically by other components.
Test labelSelector and matchLabelKeys across revisions
Documented Kubernetes behavior. labelSelector defines which Pods are counted in each domain. matchLabelKeys adds a dynamic dimension: when the Pod is created, the API server reads the specified key values from the incoming Pod and combines them with the selector. The same key cannot appear in both labelSelector and matchLabelKeys, and matchLabelKeys cannot be used without labelSelector.
For a Deployment, Kubernetes specifically recommends pod-template-hash, a controller-added label, to distinguish revisions. matchLabelKeys is beta and enabled by default from v1.27. Since v1.34, key-value pairs are explicitly merged into labelSelector, subject to the corresponding API-server feature gate.
Proposed configuration:
topologySpreadConstraints:
- maxSkew: 1
  topologyKey: topology.kubernetes.io/zone
  whenUnsatisfiable: DoNotSchedule
  labelSelector:
    matchLabels:
      app: tsc-lab
  matchLabelKeys:
  - pod-template-hash
Proposed experiment. Start revision R1 and record its distribution, then change the Pod template so the Deployment creates R2. Run the scenario once without matchLabelKeys and once with it.
Configuration | Pods counted for an incoming R2 | What the test must verify |
labelSelector: app=tsc-lab only | Matching R1 + R2 Pods | Influence of the old revision |
+ matchLabelKeys: pod-template-hash | Pods with the R2 hash | Revision-specific spread |
Key absent from the Pod | Key ignored | Remaining selector |
Label changed directly after creation | Merge not recalculated | Behavior not to rely on |
Kubernetes warns that a later direct change to a label used by matchLabelKeys is not reflected in the merged selector. Test this mechanism with controller-managed labels, not with manual label edits intended to simulate a revision.
The test proves which Pods a given revision counts in this lab. It does not prove that a rollout will remain schedulable after topology loss; that proof requires combining the revision test with the failure scenario.
Detect constraint combinations that create unschedulable intersections
Documented Kubernetes behavior. When bd268, the scheduler combines them with logical AND. Kubernetes documents an example in which the zone constraint permits one node set, the node constraint permits another, and their empty intersection leaves the Pod Pending.
The practical rule is:
Final candidates =
  nodes that pass general filters
  ∩ zone-spread candidates
  ∩ hostname-spread candidates
  ∩ affinity candidates
  ∩ taint candidates
  ∩ other Pod constraints
Engineering inference. Testing each rule in isolation is insufficient. Two constraints that are each satisfiable on their own can be unsatisfiable together.
Combining zone and hostname spread constraints
A topology.kubernetes.io/zone constraint and a kubernetes.io/hostname constraint do not create a hierarchy that means "balance nodes inside each zone." They are evaluated as two independent constraints that must both be satisfied.
For example, prepare these hostname counts:
Node | Zone | Matching Pods |
a1 | A | 3 |
a2 | A | 0 |
b1 | B | 1 |
b2 | B | 1 |
c1 | C | 2 |
c2 | C | 1 |
The resulting zone counts are A=3, B=2, and C=3. With maxSkew: 1, the zone constraint favors B. At hostname level, the minimum is zero; with the same hardness, a2 is the placement that respects the low skew. The zone constraint requires B while the hostname constraint requires A, so the intersection is empty.
Constraint | Calculated candidate set | State in isolation |
Zone, maxSkew=1 | b1, b2 | satisfiable |
Hostname, maxSkew=1 | a2 | satisfiable |
Zone AND hostname | ∅ | unsatisfiable |
Hard zone + hostname ScheduleAnyway | b1, b2 | placement possible when other filters pass |
Proposed experiment. Build this fixture, submit a Pod with both hard constraints, and capture its Events. Then change only one constraint to ScheduleAnyway and repeat.
This test can prove that a specific combination has an empty intersection. It cannot prove that every future combination will do so, which is why each failure state must be evaluated in a matrix.
Exercise node and zone loss without claiming automatic recovery
Proposed experiment. Start the critical scenario from a known nominal state, such as 2/2/1, then remove either one worker or both workers that represent a zone from the synthetic cluster. Do not assume that "Kubernetes fixes everything." Observe separately what the controller attempts to recreate and what the scheduler can actually place.
For complete zone loss, remove the Nodes from the scheduler model rather than merely changing Pod counts. This distinction is essential with minDomains because the eligible-domain count directly affects the global-minimum calculation.
Kubernetes also states that the scheduler knows only topology domains represented by existing Nodes; a domain with no Nodes is not inherently known to it. This limitation matters especially for node groups scaled to zero, although autoscaling is outside this lab.
Failure injection | Acceptance question | Evidence to collect |
Loss of one worker | Does a placement remain in its domain? | Node list, Pending status or placement |
Loss of both workers in a zone | Does the domain count fall? | Before-and-after model |
Lost zone + minDomains=3 | Does G become 0? | Written calculation + candidate result |
Lost zone without minDomains=3 | Is concentration in two zones allowed? | Resulting distribution |
Zone restoration | Does a Pending Pod become schedulable? | Events and placement after restoration |
Engineering inference. For a service whose contract says, "five replicas must become schedulable again after one zone is lost," a 2/2/1 test with maxSkew: 1, minDomains: 3, and DoNotSchedule can reveal a direct conflict with that objective. If the contract instead says, "never increase concentration when fewer than three domains exist," the same Pending result can be correct.
Acceptance testing must therefore define the intended behavior before labeling a Pending Pod as either a failure or a protection mechanism.
Validate rolling updates against topology constraints
Rolling updates temporarily add a second Pod population and can create surge Pods. Kubernetes: Deployments, last modified July 7, 2026; accessed September 22, 2026, states that maxSurge controls the number of Pods created above the replica count and maxUnavailable controls the allowed unavailability during the rollout.
Topology spread constraints apply to the new Pods produced by this process. A Deployment can therefore have surge capacity at the controller level while the scheduler is unable to place the surge Pod. These are separate constraints that must be tested together.
Proposed lab configuration:
strategy:
  type: RollingUpdate
  rollingUpdate:
    maxSurge: 1
    maxUnavailable: 0
progressDeadlineSeconds: 120
Proposed experiment. Start with revision R1 distributed 2/2/1. Trigger R2 by changing only a field in the Pod template. Capture the R1 and R2 distributions, Pending Pods, Events, and Deployment status.
Kubernetes reports ProgressDeadlineExceeded when the Deployment has not progressed before progressDeadlineSeconds; the controller continues retrying. This is a useful experiment-failure signal, but it is not an automatic explanation of the cause. You must still prove that the topology constraint eliminated every node.
Proving rollout recovery after a topology change
Now combine a rollout with zone loss.
Without matchLabelKeys, an incoming R2 Pod can count R1 and R2 through the shared selector. With matchLabelKeys using pod-template-hash, it counts its own revision. That difference can materially change the first placement in the rollout.
An especially instructive case uses minDomains: 3 after zone loss. For a new revision with no existing R2 Pods, the global minimum is zero and the first R2 in a domain produces a skew of one, so it can still pass with maxSkew: 1. After one R2 exists in each of the two remaining domains, a third R2 would exceed the limit. This is an inference from the official formula and must be verified experimentally rather than presented as an observation.
Phase | Action | Expected result to verify | What it proves |
nominal | R1 stable | known distribution | valid fixture |
rollout | create R2 | placements match the selector | revision behavior |
failure | remove one zone | progress or calculable Pending state | schedulability under loss |
restoration | restore the domain | Pending Pods become eligible | recovery for the tested case |
finish | kubectl rollout status | complete rollout or explainable failure | acceptance result |
This scenario can demonstrate recovery after this specific topology change. It does not demonstrate universal automatic recovery, application availability, or success across every possible failure sequence.
Build an evidence matrix and acceptance gates
A strong acceptance record contains more than screenshots of Running Pods. For every scenario, retain the exact manifest, Kubernetes version, Node state before and after failure injection, manual global-minimum and skew calculations, the candidate Pod, scheduler Events, and the verdict.
Documented Kubernetes behavior. Two limitations also matter: Kubernetes does not guarantee that constraints remain satisfied when Pods are removed, and Pods that do not match their own labelSelector do not count themselves, which the documentation describes as "ghost Pods." These cases prevent a point-in-time distribution from becoming a permanent invariant.
Engineering inference. A robust acceptance gate therefore asks, "For every permitted failure state, does at least one placement exist for every Pod the controller still needs to create?" Calculate and verify the answer rather than inferring it from the current number of available Pods.
Gate | Scenario | Success condition | Evidence class |
A | version and topology | Target v1.37.0; actual version captured | actual observation |
B | 2/2/1, maxSkew=1 | candidate enters the domain at 1 | actual observation |
C | 3/1/1 | no placement in the domain at 3 | actual observation |
D | hard versus soft | hard/soft behavior matches policy | actual observation |
E | domains < minDomains | global minimum of 0 reproduced | actual observation |
F | affinity excludes one zone | Honor/Ignore produce the expected model | actual observation |
G | taint excludes one zone | Honor/Ignore behavior reproduced | actual observation |
H | missing topology label | node bypassed and counts affected | actual observation |
I | new revision | matchLabelKeys isolates R2 | actual observation |
J | zone + hostname | intersection measured | actual observation |
K | complete zone loss | schedulability contract satisfied | actual observation |
L | rolling update | rollout progresses or expected block is demonstrated | actual observation |
For every gate, also record a "what this test does not prove" column. For example, passing the loss of zone-c does not show that losing zone-a is equivalent when affinity, taints, capacity, or the initial distribution differ.
The final outcome can then use four simple levels:
Verdict | Meaning |
ACCEPT | Every failure state in the contract retains a scheduling path |
ACCEPT WITH INTENTIONAL GATE | Some Pending states are explicitly intended to prevent concentration |
REJECT | A state expected to recover produces an empty intersection |
INCONCLUSIVE | Calculation or runtime evidence missing, version not recorded, or result not deterministic |
Actual observation: until the lab is executed, no gate can be marked PASS. The tables in this playbook contain expected results derived from Kubernetes rules, not measured results.
Final acceptance decision
Final decision | Condition |
ACCEPT | Every declared loss state retains the required placements and observations match the calculations |
ACCEPT WITH INTENTIONAL GATE | Blocking after domain loss is explicitly the intended behavior |
REJECT | maxSkew, minDomains, affinity, taints, or combined constraints create an empty intersection where recovery is required |
INCONCLUSIVE | Version, topology map, calculations, or actual observations are missing |
Deepen these architecture skills with Refonte Learning's Cloud Architecture Program, a four-month pathway requiring 8–12 hours per week.
The program covers multi-cloud architecture; IAM, VPCs, routing, and private connectivity; resilience and DR/BCP/RTO/RPO; security by design; Terraform modules and policy as code; observability; FinOps; performance and scalability; and event-driven architecture.