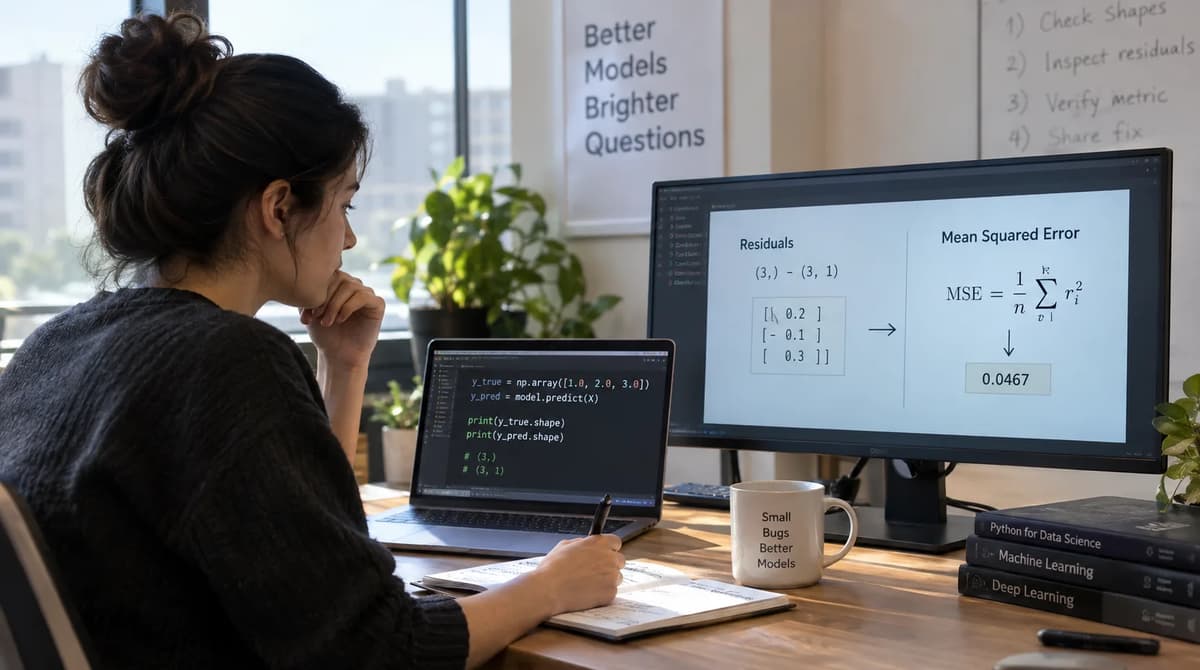
A custom regression loss can return a finite, plausible scalar and still fail the evaluation contract that matters: compare prediction i with target i, exactly once, for every observation.
The canonical failure is only one line:
np.mean((prediction - target) ** 2)
With target.shape == (3,) and prediction.shape == (3, 1), NumPy does not have to reject the subtraction. The shapes are broadcast-compatible. The subtraction therefore creates nine residuals rather than the intended three, and mean then reduces those nine values to one valid scalar. The numerical operation succeeds; the paired-observation contract fails.
This playbook treats that distinction as an acceptance problem. The primary contract is deliberately narrow: single-output, unweighted paired MSE over n > 0 observations, fixed observation order, float64, and finite values. There are no datasets, models, training runs, GPUs, external services, production evaluations, weighted losses, or multioutput metrics.
The commissioning fixture is intentionally small enough to audit by hand. Its expected paired MSE is zero. The malformed mixed-shape expression instead has a mathematically derived expectation of 4/3.
For the commissioning reproduction performed for this article, the residual shape was observed as (3, 3) and the flawed scalar as 1.3333333333333333; after explicitly authorizing (n,1) -> (n,), the residual was (3,) and the repaired score agreed with the independent paired reference at 0.0. Those observations are local evidence for the recorded runtime, not universal proof for every NumPy build.
Define paired MSE before writing the expression
The acceptance contract comes before the vectorized implementation.
For observations indexed in the fixed order , single-output paired mean squared error is
The important object is not merely the final scalar. It is the sequence of intended pairs:
For this playbook, the declared per-observation residual array is therefore one-dimensional:
residual.shape == (n,)
residual[i] == prediction[i] - target[i]
That is the release gate. Shape must be checked before subtraction, and the resulting residual must still be (n,) before mean is allowed to reduce it.
This scope is narrower than general model evaluation fundamentals. We are not choosing between MAE, RMSE, MSE, calibration measures, or business metrics. We are verifying that one already-selected MSE implementation actually computes the declared observation pairs.
A scalar cannot establish that fact. 0.0, 1.0, or 1.3333333333333333 contains no record of the residual array's dimensionality, row identities, or number of pair comparisons. A scalar should therefore be treated as the end of an evidence chain, not as a substitute for one.
Equal one-dimensional shapes are also only a necessary condition under this contract. If upstream code silently reordered observations while preserving (n,), the metric would still have acceptable shapes while comparing the wrong identities. This fixture fixes row order deliberately so dimensional correctness can be tested independently of upstream alignment.
Pin a small numerical baseline
The semantic reference for the article is deliberately frozen to NumPy 2.2 documentation. That is a documentation baseline, not a claim that NumPy 2.2 was the newest release on September 25, 2026.
The commissioning execution used a different installed runtime and records that fact rather than hiding it:
Evidence field | Commissioning value |
Commissioning batch | 2026-09-25-batch2 |
Fixture revision | canonical-three-observation-r1 |
Contract revision | paired-mse-single-output-v1 |
Normalization revision | explicit-column-vector-adapter-v1 |
Python | 3.13.5 (main, Jul 15 2026, 20:25:40) [GCC 14.2.0] |
NumPy | 2.3.5 |
Operating system | Linux-6.18.44-x86_64-with-glibc2.41 |
Machine | x86_64 |
Valid-input dtype policy | NumPy float64 only |
Value policy | finite values only |
Numerical comparison | rtol=1e-12, atol=1e-12 |
Execution | CPU-only synthetic arrays |
Research/source access cutoff | September 25, 2026 |
The installed NumPy version is reported because an observed run without its runtime is weak evidence. It does not silently replace the fixed NumPy 2.2 documentation baseline.
This is deliberately smaller than a survey of the data scientist toolkit. The laboratory needs NumPy arrays, ordinary Python arithmetic, and deterministic tests; it does not need library comparisons, model tooling, notebooks, storage systems, or training infrastructure.
The canonical arrays are:
target = np.array([1.0, 2.0, 3.0], dtype=np.float64)

prediction = np.array(
    [[1.0],
     [2.0],
     [3.0]],
    dtype=np.float64,
)
So:
target.shape      == (3,)
prediction.shape  == (3, 1)
target.ndim       == 1
prediction.ndim   == 2
Make the expected pairing independent of array shape
Write the expected ledger before constructing the NumPy representations:
Position | Observation ID | Target | Prediction | Intended residual | Intended squared error |
0 | obs-001 | 1.0 | 1.0 | 0.0 | 0.0 |
1 | obs-002 | 2.0 | 2.0 | 0.0 | 0.0 |
2 | obs-003 | 3.0 | 3.0 | 0.0 | 0.0 |
The expected value is consequently
Observation IDs remain part of the evidence ledger even though reordering is explicitly excluded from this primary shape fixture. That separation matters: the shape test answers, “Did the residual retain one element per declared observation?” It does not answer, “Did every upstream system preserve semantic row identity?”
Compute the reference loss without broadcasting
An independent reference should not use the same array expression that is under investigation. Otherwise the supposed oracle can reproduce the implementation defect.
The scalar reference below first validates both lengths, checks n > 0, rejects non-finite values, and only then uses zip. The length check is essential because Python's zip stops at the shorter input; using it without a prior equality check could convert an unequal-length defect into another plausible number.
import math

def paired_mse_reference(target_values, prediction_values):
    target_len = len(target_values)
    prediction_len = len(prediction_values)

    if target_len != prediction_len:
        raise ValueError(
            "scalar-reference-v1: unequal lengths "
            f"target={target_len}, prediction={prediction_len}"
        )

    n = target_len
    if n <= 0:
        raise ValueError("scalar-reference-v1: n must be > 0")

    target_checked = []
    prediction_checked = []

    for index, value in enumerate(target_values):
        scalar = float(value)
        if not math.isfinite(scalar):
            raise ValueError(
                f"scalar-reference-v1: target[{index}] must be finite"
            )
        target_checked.append(scalar)

    for index, value in enumerate(prediction_values):
        scalar = float(value)
        if not math.isfinite(scalar):
            raise ValueError(
                f"scalar-reference-v1: prediction[{index}] must be finite"
            )
        prediction_checked.append(scalar)

    total = 0.0
    for target, prediction in zip(target_checked, prediction_checked):
        error = prediction - target
        total += error * error

    return total / n
For the canonical ledger, ordinary Python arithmetic evaluates:
obs-001: (1.0 - 1.0)^2 = 0.0
obs-002: (2.0 - 2.0)^2 = 0.0
obs-003: (3.0 - 3.0)^2 = 0.0

sum = 0.0
n   = 3
MSE = 0.0 / 3 = 0.0
That reference has no NumPy broadcasting step. It is therefore independent of the failure mechanism we are testing.
This does not make ordinary Python generally preferable to NumPy or add anything to arguments about Python’s data-science ecosystem. Its purpose is much narrower: preserve a scalar oracle whose pairing semantics cannot be altered by array-dimensional broadcasting.
The acceptance comparison is consequently two-part: the repaired vectorized implementation must produce the declared (n,) residual, and its final scalar must agree with this independent paired calculation within the stated tolerance.
Reproduce the mixed-shape loss
Now evaluate the deliberately flawed expression:
np.mean((prediction - target) ** 2)The first question is not “What scalar did it return?” The first question is “What did subtraction produce?”
prediction is (3,1):
[[1.0],
 [2.0],
 [3.0]]
target is (3,):
[1.0, 2.0, 3.0]The mathematically derived residual matrix is:
[[ 0.0, -1.0, -2.0],
 [ 1.0,  0.0, -1.0],
 [ 2.0,  1.0,  0.0]]
and therefore has:
shape = (3, 3)
size  = 9
Squaring element by element gives:
[[0.0, 1.0, 4.0],
 [1.0, 0.0, 1.0],
 [4.0, 1.0, 0.0]]
The independent arithmetic for the flawed expression is therefore:
over nine matrix entries:
That is the mathematically derived expectation for the malformed expression.
The commissioning execution then supplied a separate category of evidence:
Quantity | Derived expectation | Observed commissioning run |
Raw mixed input shapes | (3,), (3,1) | (3,), (3,1) |
Residual shape | (3,3) | (3,3) |
Residual element count | 9 | 9 |
Paired oracle | 0.0 | 0.0 |
Flawed expression | 4/3 | 1.3333333333333333 |
Contract decision | reject | reject |
The observation agrees with the derivation in this recorded runtime. That agreement is evidence for the fixture; it does not turn the malformed expression into a valid paired metric.
Read the residual matrix by observation identity
The matrix becomes much less mysterious when its rows and columns are labeled.
Each row comes from one prediction because prediction has its observation axis in the first dimension and a length-one second dimension. Each column comes from one target because (3,) aligns with the trailing dimension.
target obs-001 = 1 | target obs-002 = 2 | target obs-003 = 3 | |
prediction obs-001 = 1 | 0 | -1 | -2 |
prediction obs-002 = 2 | 1 | 0 | -1 |
prediction obs-003 = 3 | 2 | 1 | 0 |
The bold diagonal entries are the three intended paired residuals. The six off-diagonal entries are comparisons the paired-MSE contract never authorized.
This is why the phrase “the values look identical” is insufficient. They are identical in corresponding positions, but the malformed shapes ask NumPy for all row-versus-column combinations. NumPy complies.
Explain why mean hides the earlier mistake
The behavior is documented NumPy semantics, not a NumPy defect.
In the NumPy v2.2 Manual, NumPy Developers' Broadcasting documentation states that shapes are compared from their trailing dimensions and that dimensions are compatible when they are equal or one; it also illustrates how a shape such as (4,1) combined with (3,) yields (4,3). This is versioned documentation with no publication date asserted here; accessed September 25, 2026.
Apply that rule to the fixture:
prediction: 3 x 1
target:         3
result:     3 x 3
The last dimensions, 1 and 3, are compatible because one is 1. The target has no preceding dimension, which is treated compatibly for broadcasting. The output therefore takes the expanded (3,3) form.
The NumPy v2.2 numpy.subtract documentation independently states that differently shaped inputs must be broadcastable to a common shape and that the common shape becomes the output shape; it also states that x1 - x2 is equivalent in broadcasting terms. NumPy Developers, versioned v2.2 documentation, no publication date asserted; accessed September 25, 2026.
So:
prediction - targetis numerically well-defined. The error is in the application's contract: the program wanted three corresponding comparisons but supplied representations that authorize nine.
The second half of the failure is reduction. The NumPy v2.2 numpy.mean documentation states that, by default, the average is taken over the flattened array when no axis is supplied. NumPy Developers, versioned v2.2 documentation, no publication date asserted; accessed September 25, 2026.
Therefore:
np.mean(residual ** 2)does not know that only the diagonal was intended. Once residual is (3,3), the default reduction averages all nine squared values.
Reduction cannot repair provenance lost earlier. A successful mean merely proves that the supplied array can be averaged.
That is the numerical-validity versus evaluation-validity gap:
NumPy operation valid?             yes
Paired residual contract valid?    no
Finite scalar returned?            yes
Declared observation pairs used?   no
The acceptance control belongs before the subtraction, not after the scalar appears.
Reject incompatible inputs before subtraction
The strict base metric should accept exactly one representation: two numpy.ndarray objects, each with shape (n,), equal n > 0, dtype float64, and finite values.
Do not depend on broadcasting errors to enforce that contract. The mixed fixture will not produce one.
The complete runnable commissioning module below contains the deliberately flawed metric, strict validation boundary, authorized column adapter, independent scalar reference, evidence record, and deterministic controls.
# paired_mse_contract.py
from future import annotations
import json
import math
import platform
import sys
import unittest
from dataclasses import asdict, dataclass
from typing import Sequence
import numpy as np
COMMISSIONING_BATCH = "2026-09-25-batch2"
CONTRACT_REVISION = "paired-mse-single-output-v1"
FIXTURE_REVISION = "canonical-three-observation-r1"
NORMALIZATION_REVISION = "explicit-column-vector-adapter-v1"
RTOL = 1e-12
ATOL = 1e-12
OBSERVATIONS = (
("obs-001", 1.0, 1.0),
("obs-002", 2.0, 2.0),
("obs-003", 3.0, 3.0),
)
class ContractError(ValueError):
"""Input does not satisfy the declared paired-MSE contract."""
def flawed_mse(
target: np.ndarray,
prediction: np.ndarray,
) -> np.float64:
"""Deliberately flawed for mixed (n,) / (n,1) inputs."""
return np.mean((prediction - target) ** 2)
def validatestrict_vector(
name: str,
value: np.ndarray,
) -> np.ndarray:
if not isinstance(value, np.ndarray):
raise TypeError(
f"{CONTRACT_REVISION}: "
f"{name} must be a numpy.ndarray"
)
if value.dtype != np.dtype(np.float64):
raise ContractError(
f"{CONTRACT_REVISION}: "
f"{name} dtype must be float64; got {value.dtype}"
)
if value.ndim != 1:
raise ContractError(
f"{CONTRACT_REVISION}: "
f"{name} shape must be (n,); "
f"got shape={value.shape}, ndim={value.ndim}"
)
if value.shape[0] <= 0:
raise ContractError(
f"{CONTRACT_REVISION}: "
f"{name} must contain n > 0 observations; "
f"got shape={value.shape}"
)
if not np.isfinite(value).all():
raise ContractError(
f"{CONTRACT_REVISION}: "
f"{name} must contain only finite float64 values"
)
return value
def strict_paired_mse(
target: np.ndarray,
prediction: np.ndarray,
) -> tuple[np.float64, np.ndarray]:
target = validatestrict_vector("target", target)
prediction = validatestrict_vector(
"prediction", prediction
)
if target.shape != prediction.shape:
raise ContractError(
f"{CONTRACT_REVISION}: target and prediction "
"must have equal shape (n,); "
f"got target={target.shape}, "
f"prediction={prediction.shape}"
)
n = target.shape[0]
# Only now is subtraction authorized.
residual = prediction - target
# Pre-reduction internal invariant.
if residual.shape != (n,):
raise AssertionError(
f"{CONTRACT_REVISION}: residual shape invariant "
f"failed; expected {(n,)}, got {residual.shape}"
)
if residual.dtype != np.dtype(np.float64):
raise AssertionError(
f"{CONTRACT_REVISION}: residual dtype invariant "
f"failed; got {residual.dtype}"
)
squared = residual residual
score = np.mean(squared)
return np.float64(score), residual
def column_vector_to_1d(
name: str,
value: np.ndarray,
) -> np.ndarray:
"""
Authorize exactly one representation change:
shape (n, 1) -> shape (n,).
"""
if not isinstance(value, np.ndarray):
raise TypeError(
f"{NORMALIZATION_REVISION}: "
f"{name} must be a numpy.ndarray"
)
if value.dtype != np.dtype(np.float64):
raise ContractError(
f"{NORMALIZATION_REVISION}: "
f"{name} dtype must be float64; got {value.dtype}"
)
if (
value.ndim != 2
or value.shape[1] != 1
or value.shape[0] <= 0
):
raise ContractError(
f"{NORMALIZATION_REVISION}: "
f"{name} must have shape (n, 1) with n > 0; "
f"got {value.shape}"
)
if not np.isfinite(value).all():
raise ContractError(
f"{NORMALIZATION_REVISION}: "
f"{name} must contain only finite float64 values"
)
normalized = value[:, 0]
if normalized.shape != (value.shape[0],):
raise AssertionError(
f"{NORMALIZATION_REVISION}: "
f"expected normalized shape {(value.shape[0],)}, "
f"got {normalized.shape}"
)
return normalized
def paired_mse_reference(
target_values: Sequence[float],
prediction_values: Sequence[float],
) -> float:
"""
Independent paired scalar oracle.
No NumPy broadcasting is used.
"""
target_len = len(target_values)
prediction_len = len(prediction_values)
# Must happen before zip.
if target_len != prediction_len:
raise ContractError(
"scalar-reference-v1: unequal lengths "
f"target={target_len}, "
f"prediction={prediction_len}"
)
n = target_len
if n <= 0:
raise ContractError(
"scalar-reference-v1: n must be > 0"
)
target_checked: list[float] = []
prediction_checked: list[float] = []
for index, value in enumerate(target_values):
scalar = float(value)
if not math.isfinite(scalar):
raise ContractError(
"scalar-reference-v1: "
f"target[{index}] must be finite; "
f"got {scalar!r}"
)
target_checked.append(scalar)
for index, value in enumerate(prediction_values):
scalar = float(value)
if not math.isfinite(scalar):
raise ContractError(
"scalar-reference-v1: "
f"prediction[{index}] must be finite; "
f"got {scalar!r}"
)
prediction_checked.append(scalar)
total = 0.0
for target, prediction in zip(
target_checked,
prediction_checked,
):
error = prediction - target
total += error error
return total / n
@dataclass(frozen=True)
class Evidence:
case: str
target_shape: tuple[int, ...]
target_ndim: int
target_dtype: str
prediction_shape: tuple[int, ...]
prediction_ndim: int
prediction_dtype: str
n: int
normalization: str
residual_shape: tuple[int, ...]
residual_element_count: int
paired_reference: float
observed_score: float
decision: str
def build_canonical_evidence() -> list[Evidence]:
target = np.array(
[row[1] for row in OBSERVATIONS],
dtype=np.float64,
)
prediction_column = np.array(
[[row[2]] for row in OBSERVATIONS],
dtype=np.float64,
)
reference = paired_mse_reference(
[row[1] for row in OBSERVATIONS],
[row[2] for row in OBSERVATIONS],
)
flawed_residual = prediction_column - target
flawed_score = flawed_mse(
target,
prediction_column,
)
prediction_1d = column_vector_to_1d(
"prediction",
prediction_column,
)
repaired_score, repaired_residual = strict_paired_mse(
target,
prediction_1d,
)
return [
Evidence(
case="raw-mixed-shape-flawed-expression",
target_shape=target.shape,
target_ndim=target.ndim,
target_dtype=str(target.dtype),
prediction_shape=prediction_column.shape,
prediction_ndim=prediction_column.ndim,
prediction_dtype=str(prediction_column.dtype),
n=target.shape[0],
normalization="none",
residual_shape=flawed_residual.shape,
residual_element_count=flawed_residual.size,
paired_reference=reference,
observed_score=float(flawed_score),
decision=(
"reject/refactor; raw input violates "
"paired contract"
),
),
Evidence(
case=(
"authorized-column-adapter-then-strict-metric"
),
target_shape=target.shape,
target_ndim=target.ndim,
target_dtype=str(target.dtype),
prediction_shape=prediction_1d.shape,
prediction_ndim=prediction_1d.ndim,
prediction_dtype=str(prediction_1d.dtype),
n=target.shape[0],
normalization=NORMALIZATION_REVISION,
residual_shape=repaired_residual.shape,
residual_element_count=repaired_residual.size,
paired_reference=reference,
observed_score=float(repaired_score),
decision="accept this fixture path",
),
]
class PairedMSETests(unittest.TestCase):
def assertFloat64ArrayEqual(
self,
actual: np.ndarray,
expected: np.ndarray,
) -> None:
self.assertEqual(actual.shape, expected.shape)
self.assertEqual(actual.dtype, expected.dtype)
np.testing.assert_allclose(
actual,
expected,
rtol=RTOL,
atol=ATOL,
equal_nan=False,
strict=True,
)
def test_both_1d(self) -> None:
target = np.array(
[1.0, 2.0, 3.0],
dtype=np.float64,
)
prediction = np.array(
[1.0, 2.0, 3.0],
dtype=np.float64,
)
score, residual = strict_paired_mse(
target,
prediction,
)
self.assertFloat64ArrayEqual(
residual,
np.zeros(3, dtype=np.float64),
)
self.assertEqual(float(score), 0.0)
def test_both_column_vectors_require_normalization(
self,
) -> None:
target_col = np.array(
[[1.0], [2.0], [3.0]],
dtype=np.float64,
)
prediction_col = np.array(
[[1.0], [2.0], [3.0]],
dtype=np.float64,
)
with self.assertRaises(ContractError):
strict_paired_mse(
target_col,
prediction_col,
)
target = column_vector_to_1d(
"target",
target_col,
)
prediction = column_vector_to_1d(
"prediction",
prediction_col,
)
score, residual = strict_paired_mse(
target,
prediction,
)
self.assertFloat64ArrayEqual(
residual,
np.zeros(3, dtype=np.float64),
)
self.assertEqual(float(score), 0.0)
def test_mixed_shape_exposes_all_pairs(self) -> None:
target = np.array(
[1.0, 2.0, 3.0],
dtype=np.float64,
)
prediction_col = np.array(
[[1.0], [2.0], [3.0]],
dtype=np.float64,
)
expected_residual = np.array(
[
[0.0, -1.0, -2.0],
[1.0, 0.0, -1.0],
[2.0, 1.0, 0.0],
],
dtype=np.float64,
)
actual_residual = prediction_col - target
self.assertFloat64ArrayEqual(
actual_residual,
expected_residual,
)
self.assertAlmostEqual(
float(flawed_mse(target, prediction_col)),
4.0 / 3.0,
places=15,
)
with self.assertRaises(ContractError):
strict_paired_mse(
target,
prediction_col,
)
prediction = column_vector_to_1d(
"prediction",
prediction_col,
)
score, residual = strict_paired_mse(
target,
prediction,
)
self.assertEqual(residual.shape, (3,))
self.assertEqual(float(score), 0.0)
def test_single_observation_can_mask_flaw(
self,
) -> None:
target = np.array(
[1.0],
dtype=np.float64,
)
prediction_col = np.array(
[[2.0]],
dtype=np.float64,
)
# Flawed expression happens to equal paired MSE.
self.assertEqual(
float(flawed_mse(target, prediction_col)),
1.0,
)
prediction = column_vector_to_1d(
"prediction",
prediction_col,
)
# Observation axis is preserved.
self.assertEqual(prediction.shape, (1,))
self.assertEqual(prediction.ndim, 1)
score, residual = strict_paired_mse(
target,
prediction,
)
self.assertEqual(residual.shape, (1,))
self.assertEqual(float(score), 1.0)
def test_nonzero_hand_calculated_fixture(
self,
) -> None:
target = np.array(
[1.0, 2.0, 3.0],
dtype=np.float64,
)
prediction = np.array(
[2.0, 2.0, 1.0],
dtype=np.float64,
)
# Squared errors: 1, 0, 4 => 5 / 3.
reference = paired_mse_reference(
[1.0, 2.0, 3.0],
[2.0, 2.0, 1.0],
)
self.assertAlmostEqual(
reference,
5.0 / 3.0,
places=15,
)
score, residual = strict_paired_mse(
target,
prediction,
)
self.assertFloat64ArrayEqual(
residual,
np.array(
[1.0, 0.0, -2.0],
dtype=np.float64,
),
)
self.assertAlmostEqual(
float(score),
reference,
places=15,
)
def test_all_equal_values_can_mask_pairing_error(
self,
) -> None:
target = np.array(
[5.0, 5.0, 5.0],
dtype=np.float64,
)
prediction_col = np.array(
[[5.0], [5.0], [5.0]],
dtype=np.float64,
)
self.assertEqual(
(prediction_col - target).shape,
(3, 3),
)
self.assertEqual(
float(flawed_mse(target, prediction_col)),
0.0,
)
def test_invalid_row_vector(self) -> None:
row = np.array(
[[1.0, 2.0, 3.0]],
dtype=np.float64,
)
with self.assertRaises(ContractError):
column_vector_to_1d(
"prediction",
row,
)
def test_invalid_multioutput(self) -> None:
matrix = np.array(
[
[1.0, 10.0],
[2.0, 20.0],
[3.0, 30.0],
],
dtype=np.float64,
)
with self.assertRaises(ContractError):
column_vector_to_1d(
"prediction",
matrix,
)
def test_invalid_unequal_length(self) -> None:
target = np.array(
[1.0, 2.0, 3.0],
dtype=np.float64,
)
prediction = np.array(
[1.0, 2.0],
dtype=np.float64,
)
with self.assertRaises(ContractError):
strict_paired_mse(
target,
prediction,
)
with self.assertRaises(ContractError):
paired_mse_reference(
[1.0, 2.0, 3.0],
[1.0, 2.0],
)
def test_invalid_empty(self) -> None:
empty = np.array(
[],
dtype=np.float64,
)
with self.assertRaises(ContractError):
strict_paired_mse(
empty,
empty,
)
with self.assertRaises(ContractError):
paired_mse_reference([], [])
def test_invalid_nonfinite(self) -> None:
finite = np.array(
[1.0, 2.0],
dtype=np.float64,
)
invalid_cases = (
np.array(
[1.0, np.nan],
dtype=np.float64,
),
np.array(
[1.0, np.inf],
dtype=np.float64,
),
np.array(
[1.0, -np.inf],
dtype=np.float64,
),
)
for invalid in invalid_cases:
with self.subTest(invalid=invalid):
with self.assertRaises(ContractError):
strict_paired_mse(
finite,
invalid,
)
with self.assertRaises(ContractError):
paired_mse_reference(
[1.0, 2.0],
[1.0, float("nan")],
)
def test_invalid_dtype(self) -> None:
target = np.array(
[1.0, 2.0],
dtype=np.float32,
)
prediction = np.array(
[1.0, 2.0],
dtype=np.float32,
)
with self.assertRaises(ContractError):
strict_paired_mse(
target,
prediction,
)
def runtime_record() -> dict[str, object]:
return {
"commissioning_batch": COMMISSIONING_BATCH,
"contract_revision": CONTRACT_REVISION,
"fixture_revision": FIXTURE_REVISION,
"normalization_revision": NORMALIZATION_REVISION,
"python_version": sys.version.replace("\n", " "),
"numpy_version": np.__version__,
"platform": platform.platform(),
"machine": platform.machine(),
"dtype_policy": (
"inputs and residuals must be numpy.float64; "
"finite values only"
),
"rtol": RTOL,
"atol": ATOL,
}
if name == "__main__":
print("RUNTIME_RECORD")
print(
json.dumps(
runtime_record(),
indent=2,
sort_keys=True,
)
)
print("EVIDENCE")
print(
json.dumps(
[
asdict(row)
for row in build_canonical_evidence()
],
indent=2,
)
)
unittest.main(
argv=[sys.argv[0]],
verbosity=2,
)The commissioning invocation was:
python paired_mse_contract.pyIt has no dataset or external-state dependency. Reset consists of starting a new Python process; cleanup requires no model artifacts, caches, remote resources, or production changes. Keep this fixture in an isolated test directory rather than wiring experimental repair code directly into a production evaluator.
The observed commissioning execution reported all 12 included tests as OK.
Assert the residual shape before reducing it
The central invariant appears between subtraction and reduction:
residual = prediction - target

if residual.shape != (n,):
    raise AssertionError(...)
That check may look redundant after strict input validation. It is intentional.
The input gate protects the function's declared boundary. The residual assertion protects the implementation itself. If future refactoring changes how subtraction is constructed, the test still demands one residual per observation before reduction.
A scalar assertion such as:
assert np.isclose(score, expected)
cannot replace it. As later controls demonstrate, malformed pair construction can accidentally produce the expected scalar.
Normalize only the representation the contract permits
There are two different design decisions here, and they should not be blurred.
The strict metric accepts only (n,).
The adapter may authorize a specific external representation, (n,1), and convert it before calling that metric.
For the raw canonical mismatch:
target.shape      # (3,)
prediction.shape  # (3, 1)

strict_paired_mse(target, prediction)
the decision is reject the input contract. The strict function should not infer that the extra axis is harmless.
Where the caller has explicitly documented that (n,1) means “one scalar output for each of n observations,” adaptation is deliberate:
prediction_1d = column_vector_to_1d(
    "prediction",
    prediction,
)

score, residual = strict_paired_mse(
    target,
    prediction_1d,
)
prediction_1d.shape is (3,), the residual is (3,), and the paired oracle is zero.
The same rule applies when both values arrive as columns:
target_col.shape      # (3, 1)
prediction_col.shape  # (3, 1)
Raw submission to the strict function is rejected. Explicitly normalize both:
target = column_vector_to_1d(
    "target",
    target_col,
)

prediction = column_vector_to_1d(
    "prediction",
    prediction_col,
)
then call the strict metric.
The adapter deliberately uses:
value[:, 0]not:
value.reshape(-1)
value.ravel()
np.squeeze(value)
The first operation communicates a specific representation policy: there must be exactly one column, and that column becomes the observation vector.
By contrast, flattening a (3,2) multioutput matrix would silently turn six values into six apparent observations. Flattening (1,3) would silently reinterpret a row representation the adapter never authorized. “Make it one-dimensional until tests stop failing” is not normalization; it is loss of structural evidence.
The adapter consequently rejects both (1,n) and (n,m) for m != 1.
Keep the one-observation case from hiding the defect
A useful negative control is one observation:
target = np.array(
    [1.0],
    dtype=np.float64,
)

prediction = np.array(
    [[2.0]],
    dtype=np.float64,
)
The malformed subtraction has shape (1,1) rather than the declared (1,), but there is only one matrix cell. Both flawed and correctly paired arithmetic therefore produce:
So this test can report the right number while the raw representation still violates the strict contract.
That is negative evidence about test adequacy. A one-item test cannot expose an all-pairs explosion because one-by-one contains no off-diagonal cells.
The constant-value control is even more deceptive:
target = np.array(
    [5.0, 5.0, 5.0],
    dtype=np.float64,
)

prediction = np.array(
    [[5.0], [5.0], [5.0]],
    dtype=np.float64,
)
The residual is wrongly shaped (3,3), but every one of its nine values is zero. The malformed MSE is therefore 0.0, exactly like the correctly paired result.
Passing this fixture says only that all compared numbers were equal. It does not demonstrate that the implementation made the intended three comparisons.
A regression test suite that contains only n=1, constant values, or both can therefore give strong-looking numerical agreement while leaving the dimensional defect completely exposed.
Preserve the observation axis during normalization
The n=1 case is also why unrestricted squeezing is a poor boundary policy.
The NumPy v2.2 numpy.squeeze documentation says squeezing removes length-one axes and notes explicitly that removing all such axes yields a zero-dimensional array. NumPy Developers, versioned v2.2 documentation, no publication date asserted; accessed September 25, 2026.
For a column with one observation:
x = np.array([[2.0]], dtype=np.float64)unrestricted squeezing can produce:
np.squeeze(x).shape
# ()
But the paired-MSE contract requires one observation:
shape == (1,)The authorized operation:
x[:, 0]produces exactly that:
(1,)An explicit axis operation could also work if its preconditions were checked, but the representation policy must stay visible. The goal is not to remove every singleton axis; it is to remove the known column axis and preserve the observation axis.
Add nonzero and invalid-input controls
Zero-error fixtures are useful because the canonical mixed-shape failure becomes visually obvious, but acceptance also needs a nonzero oracle.
Use:
target     = [1, 2, 3]
prediction = [2, 2, 1]
The paired residuals are:
[1, 0, -2]and squared errors:
[1, 0, 4]so the hand-calculated reference is:
The commissioning test verifies the vectorized implementation against that independently derived 5/3, not merely against another call to the vectorized function.
Invalid cases belong in the same acceptance suite. This complements general Python data-cleaning practices, but the responsibility here is specifically at the metric boundary: malformed numerical evaluation inputs must not be silently repaired into a score.
Input case | Expected acceptance behavior | Why |
target (n,), prediction (n,) | accept if equal positive length, float64, finite | native strict contract |
both (n,1) | reject strict call; accept only after explicit adapter on each | authorized representation conversion |
target (n,), prediction (n,1) | reject raw; adapter may normalize prediction | canonical failure |
(1,n) | reject adapter | row vectors are not an authorized representation |
(n,2) | reject adapter | this is not single-output (n,1) |
unequal (3,) and (2,) | reject | no one-to-one observation count |
empty (0,) | reject | contract requires n > 0 |
NaN | reject | non-finite score inputs prohibited |
+Inf or -Inf | reject | non-finite inputs prohibited |
wrong dtype such as float32 | reject under this strict base revision | dtype contract is explicitly float64 |
An expected rejection is not the same as an implementation crash. Tests should assert the declared exception type and boundary whenever practical, so reviewers can distinguish “we intentionally rejected this contract” from “some later operation happened to fail.”
Qualify the numerical assertions themselves
Numerical closeness is useful after structural validity has already been established.
For residual arrays, the acceptance sequence should be explicit:
assert actual.shape == expected.shape
assert actual.dtype == expected.dtype

np.testing.assert_allclose(
    actual,
    expected,
    rtol=1e-12,
    atol=1e-12,
    equal_nan=False,
    strict=True,
)
The explicit shape and dtype assertions are retained even though strict=True can enforce those properties. That duplication makes the application contract readable without requiring a reviewer to know test-helper semantics, and it keeps structural acceptance conceptually separate from tolerance-based numerical comparison.
The NumPy v2.2 numpy.testing.assert_allclose documentation documents that strict=True rejects shape or dtype mismatches and disables special scalar broadcasting behavior. The page marks strict as new in NumPy 2.0.0. It is therefore an established NumPy 2.0 addition, not a feature introduced in the 2026 commissioning batch. NumPy Developers, versioned v2.2 documentation, no publication date asserted; accessed September 25, 2026.
The same documentation shows that equal_nan exists and defaults to permitting corresponding NaNs to compare equal. This playbook deliberately passes:
equal_nan=Falsebut that is only a testing backstop. The strict metric rejects non-finite arrays before any MSE calculation. A pair of NaNs comparing “equal” in an assertion would not constitute a valid regression-score input under this contract.
Likewise, tolerance does not establish structure. These two objects should not be accepted as equivalent representations merely because their values can be broadcast:
array([0.0, 0.0, 0.0])       shape (3,)
array(0.0)                    shape ()
The contract wants three per-observation residuals. Numerical closeness to scalar zero is irrelevant to that requirement.
The commissioning run used rtol=1e-12 and atol=1e-12 for its deterministic float64 synthetic controls. Those are fixture-specific acceptance tolerances, not a universal recommendation for arbitrary regression workloads.
Keep the scalar oracle from silently truncating inputs
The scalar reference has its own acceptance boundary:
if len(target_values) != len(prediction_values):
    raise ContractError(...)
That statement must occur before:
for target, prediction in zip(...):Consider:
targets     = [1.0, 2.0, 3.0]
predictions = [1.0, 2.0]
Bare zip would yield only:
(1.0, 1.0)
(2.0, 2.0)
and never expose the missing third prediction.
The reference test therefore asserts that unequal lengths fail. It also asserts failure for empty and non-finite sequences. An independent oracle is useful only when it has a contract at least as explicit as the implementation it is judging.
Build an evaluation evidence ledger
A metric acceptance record should preserve enough intermediate evidence to reconstruct the decision without rerunning mental broadcasting rules from a scalar.
For each evaluation fixture, capture at least:
Evidence field | Purpose |
target shape and ndim | proves the supplied target representation |
prediction shape and ndim | exposes mixed dimensionality |
target/prediction dtype | verifies the float64 contract |
n | records intended observation count |
fixture revision | anchors expected values and ordering |
normalization decision/revision | distinguishes raw versus authorized representation |
residual shape | proves dimensionality before reduction |
residual element count | makes n versus n² expansion visible |
paired reference | independent scalar oracle |
observed score | records vectorized result |
observation IDs | preserves intended row identity |
metric/contract revision | identifies affected implementation |
decision | accept, reject, refactor, quarantine, or hold |
For the canonical commissioning reproduction:
Evidence field | Raw flawed path | Approved adapter + strict metric |
Target shape | (3,) | (3,) |
Prediction shape | (3,1) | (3,) |
Normalization | none | explicit-column-vector-adapter-v1 |
Residual shape | (3,3) | (3,) |
Residual elements | 9 | 3 |
Paired oracle | 0.0 | 0.0 |
Observed score | 1.3333333333333333 | 0.0 |
Decision | reject/refactor | accept fixture path |
The second row demonstrates the property under test: one residual per observation and scalar agreement with the independent paired calculation.
It does not prove upstream row identity merely because shapes are equal. The observation IDs in the expected ledger are retained so a separate data-lineage or alignment check can verify that obs-001 still means the same record on both sides. Feature-column alignment, category encoding, train/test leakage, point-in-time joins, and similar upstream meaning changes are outside this fixture.
Recover scores from the affected implementation
Repairing the function and adding tests resolves future use. It does not automatically repair historical score artifacts.
Recovery should begin with provenance, not with an assumption that every prior score was wrong.
Identify the metric versions or code revisions capable of executing the unvalidated expression. For each score artifact produced by those versions, locate retained inputs or metadata that can establish:
target shape
prediction shape
dtype
observation count
metric version
normalization path, if any
fixture/evaluation identity
retained prediction and target values, where policy permits
Then divide historical results by recoverability.
A result is recomputable when trusted retained targets and predictions preserve the observation pairing needed by the repaired contract. Re-run the repaired metric, preserve the original score as provenance, write the replacement as a new artifact, and record the code and contract revisions responsible for the recomputation.
A result may remain valid without recomputation if evidence establishes that both original inputs already satisfied the strict (n,) paired contract and there is no reason to believe the affected broadcast path changed the residual construction. Do not label every score produced by a shared function version invalid merely because some callers supplied malformed shapes.
A result should be quarantined when the metric version is affected and surviving artifacts cannot establish the original shapes or reconstruct the paired inputs. The quarantine is an evidence decision, not a claim that the number was definitely wrong.
A result should be placed on hold for missing provenance when the available evidence conflicts or is incomplete. For example, logs report (n,) while retained serialized arrays report (n,1), or the metric revision cannot be determined.
Never reverse-engineer the original residual pairing from the scalar. Many different residual arrays can share the same mean squared value. 1.3333333333333333 does not prove a (3,3) matrix, and 0.0 does not prove a correct (n,) residual. A scalar alone cannot recover the comparison graph that produced it.
Decide whether the metric is ready for reuse
The repaired implementation is ready for reuse only when its release evidence addresses both structure and arithmetic.
Decision | Apply when |
Accept | inputs satisfy (n,), equal n > 0, float64, finite; residual is (n,); paired oracle agrees within declared tolerance; required controls pass |
Reject the input contract | caller supplies an unauthorized shape such as (1,n), (n,2), unequal lengths, empty arrays, wrong dtype, or non-finite values |
Refactor the metric | implementation permits subtraction/reduction before enforcing paired dimensionality, or the residual invariant is absent |
Quarantine prior scores | an affected metric revision produced artifacts whose original pairing cannot be reconstructed reliably |
Hold missing provenance | evidence conflicts or is insufficient to determine shapes, metric revision, normalization, or retained pairing |
Metric maintainers own the strict boundary, adapter specification, test fixtures, and versioned implementation. Report consumers own the decision not to continue publishing a score after its evaluation provenance has been quarantined or placed on hold.
Before release, require the deliberately adversarial controls, not merely happy paths:
native (n,) + (n,)
both (n,1) only after explicit adapters
mixed (n,) + (n,1) raw rejection
mixed case proving flawed 4/3 versus paired 0
n=1 misleading numerical pass
constant-value misleading numerical pass
hand-calculated nonzero 5/3
(1,n) rejection
(n,2) rejection
unequal-length rejection
empty rejection
NaN/Inf rejection
wrong-dtype rejection
That engineering emphasis is complementary to broader data-science engineering practices, but the release criterion here stays intentionally local: demonstrate that this metric maintains one residual for each declared observation before reducing anything.
Review the contract at every array boundary
A repair is not a permanent waiver from dimensional review.
Changing the adapter from (n,1) to additional representations requires new acceptance evidence. So does broadening float64 to another dtype policy, adding multiple outputs, introducing weights, changing reduction axes, or changing what constitutes one observation.
Those would be new contracts, not cosmetic refactors.
Similarly, historical numerical agreement cannot authorize a future shape. A previous scalar that happened to match its reference does not prove a new representation is safe. The contract should travel with the array boundary:
representation accepted
        ↓
shape validated
        ↓
dtype/value policy validated
        ↓
subtraction
        ↓
residual shape asserted
        ↓
squaring
        ↓
reduction
        ↓
independent scalar comparison
        ↓
evidence-ledger decision
For the primary contract in this playbook, the answer to the two acceptance questions is now unambiguous.
Does the malformed canonical expression produce the declared per-observation residual shape before reduction? No. It produces (3,3), nine residuals, when the contract requires (3,), three residuals.
Does its resulting MSE agree with the independent paired calculation? No. The malformed expression is mathematically 4/3, observed as 1.3333333333333333 in the recorded commissioning runtime, while the paired reference is 0.0.
After the explicitly authorized column-vector adapter, the repaired metric produces (3,) and the observed MSE is 0.0, agreeing with the independent reference for this fixture.
That is sufficient evidence to accept the repaired fixture path, not evidence that arbitrary upstream alignment, every historical report, or every future contract has been validated.
Build evaluation foundations with Refonte Learning
The practical lesson is not “avoid broadcasting.” Broadcasting is documented and useful NumPy behavior. The engineering requirement is to state which dimensions have application meaning, validate them before arithmetic can expand them, and preserve enough evidence to audit the resulting metric.
Refonte Learning's Data Science & AI programme currently describes a three-month programme with a stated workload of 12–14 hours per week and lists Python for data science, statistical modelling, machine learning/predictive modelling, and model-optimization/problem-solving topics. The programme page also describes virtual-internship opportunities. These are Refonte Learning's own programme-page descriptions, accessed September 25, 2026, rather than independent guarantees of outcomes.
Those foundations are relevant to the discipline behind this playbook: making a numerical implementation demonstrate the exact claim an evaluation report intends to make.
A dedicated broadcasting/MSE acceptance laboratory, however, was not established from the verified programme information used here, so it should not be presented as confirmed programme coverage.