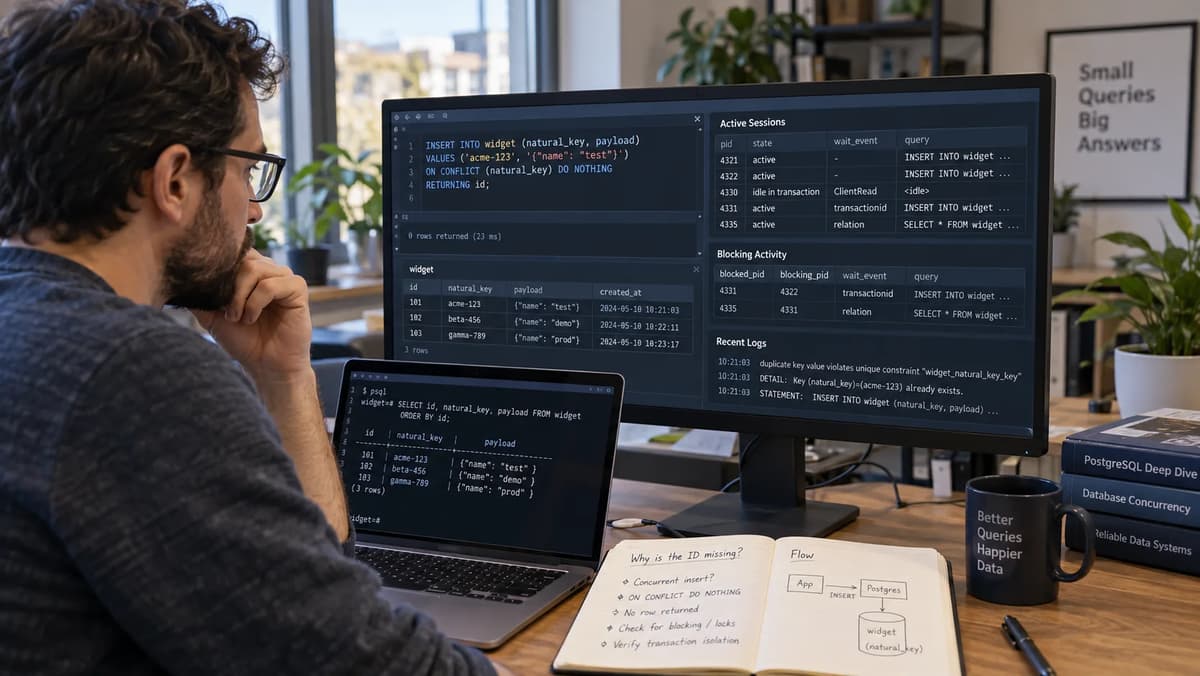
A PostgreSQL get-or-create helper can finish without an error, preserve the unique constraint perfectly, and still fail its caller because no identifier comes back. The misleading success signal is “the insert did not fail.” The real acceptance question is stricter: did the operation return the ID that is authoritative for this natural key under the caller’s declared lifetime policy?
The critical PostgreSQL 18 behavior is documented in two places that must be read together. At READ COMMITTED, a command normally reads a snapshot established when that command begins, yet INSERT ... ON CONFLICT DO NOTHING may suppress an insertion because of a concurrent transaction whose row is not visible to that snapshot. PostgreSQL states this explicitly in its PostgreSQL 18 Transaction Isolation documentation, accessed September 25, 2026. Data-modifying CTEs do not rescue the situation: the PostgreSQL 18 WITH documentation, also accessed September 25, 2026, says their substatements and main query execute with the same snapshot.
That combination predicts a specific race: conflict handling can decide that B must not insert item-7, while the fallback SELECT in that same statement still cannot see the row that caused the conflict. Zero rows can therefore be a correct PostgreSQL result and an incorrect application result.
The laboratory below is deliberately narrow: one disposable PostgreSQL database, one small table, two writers, one read-only observer, explicit integer IDs, no pool, ORM, replicas, partitioning, external service or production traffic. The canonical result remains a documented-behavior hypothesis until somebody executes and records the prescribed run. No PID, timing, wait event or terminal result below is presented as measured evidence.
Define the identity-return contract
Start by separating database integrity from API acceptance.
The database invariant is:
For natural_key = 'item-7', at most one committed row is authoritative, and its id must be reported rather than guessed.
The caller contract has two legitimate strengths.
A momentary identity lookup needs the ID that maps to the key at the instant a successful lookup statement observes it. Once that ID is returned, ordinary later transactions remain free to update or delete the row. The helper must not imply permanent existence.
A row-lifetime contract is stronger. The caller needs to perform additional transactional work while preventing some class of concurrent change to the identified row. That requirement belongs in an explicit transaction with a consciously chosen row lock. It cannot be inferred merely from the fact that an INSERT or SELECT once returned an ID.
This distinction matters more than whether the code is called “get-or-create.” A helper that preserves uniqueness but occasionally returns no ID is acceptable only if its published contract permits “no identity.” The helper in this playbook does not: success means either the newly inserted ID or the ID currently mapped to the requested natural key.
That is the narrow concurrency extension to broader database integration strategies. The integration question here is not SQL-versus-NoSQL selection, pooling or migrations; it is whether one named database operation meets its externally visible identity contract. Refonte Learning's adjacent integration article covers that broader scope, while this fixture isolates one statement-snapshot race.
Keep three values separate in every test record:
Evidence item | Meaning |
Inserted ID | The ID B actually inserted, if any |
Returned ID | What the helper returned to its caller |
Authoritative mapping | A separately checked natural_key -> id mapping after the schedule |
For the core fixture, A proposes (101, 'item-7') and B proposes (202, 'item-7'). The expected authoritative mapping after A wins is therefore item-7 -> 101; returning 202 without actually creating that mapping would be a serious identity bug. Returning nothing is a different bug. Neither should be called duplicate creation, data loss or a failed unique constraint.
Prepare an isolated PostgreSQL baseline
The documentation baseline for this article is deliberately fixed at PostgreSQL 18. It is not a claim that PostgreSQL 18 is the newest possible release at publication time. The PostgreSQL documentation site currently labels 18 as a supported branch, but an acceptance run must record the installed server build and installed psql build independently rather than copying a documentation version into its evidence.
Use this fixture revision:
refonte-goc-pg18-2026-09-25-batch2-r1The following commands are destructive by design and are LAB ONLY. They must not be pointed at production.
# LAB ONLY. Example local test cluster endpoint.
export PGHOST=127.0.0.1
export PGPORT=5432

# Capture the actual psql build before changing anything.
psql --version

# Administrative bootstrap. The role may instead be provisioned by
# your disposable-cluster tooling; do not put production credentials here.
psql -X -U postgres -d postgres
In that administrative connection:
-- LAB ONLY: destroy and recreate the disposable database.
DROP DATABASE IF EXISTS refonte_goc_lab WITH (FORCE);

-- Create the role only if it is not already a disposable lab role.
-- Run this CREATE ROLE once; omit it on later resets.
CREATE ROLE refonte_goc_app LOGIN;

CREATE DATABASE refonte_goc_lab OWNER refonte_goc_app;
If the role already exists, recreate only the disposable database. Do not repeatedly CREATE ROLE and mistake the resulting error for fixture evidence.
Open a setup connection with the exact client form you intend to record:
psql -X \
  -h 127.0.0.1 \
  -p 5432 \
  -U refonte_goc_app \
  -d refonte_goc_lab
-X prevents local psqlrc customization from silently changing the laboratory. Before any concurrency run, record the installed environment:
SELECT version() AS server_build;

SELECT current_user AS application_role,
       current_database() AS database_name,
       current_schema() AS initial_schema,
       pg_backend_pid() AS setup_pid;

SHOW default_transaction_isolation;
SHOW transaction_isolation;
SHOW lock_timeout;
SHOW statement_timeout;
SHOW search_path;
Also record the client-side autocommit state:
\echo psql_build=:VERSION
\echo server_version=:SERVER_VERSION_NAME
\echo autocommit=:AUTOCOMMIT
PostgreSQL's psql documentation defines AUTOCOMMIT as a client variable and says it defaults to on; it also exposes ROW_COUNT, SQLSTATE, VERSION and SERVER_VERSION_NAME, which are useful for preserving command-level evidence. Do not infer those values when the test can record them directly. PostgreSQL 18 psql documentation, accessed September 25, 2026.
Create the core schema:
CREATE SCHEMA lab AUTHORIZATION refonte_goc_app;

SET search_path = lab, pg_catalog;

CREATE TABLE lab.items (
    id          integer PRIMARY KEY,
    natural_key text UNIQUE NOT NULL
);

COMMENT ON TABLE lab.items IS
'fixture=refonte-goc-pg18-2026-09-25-batch2-r1';

SELECT id, natural_key
FROM lab.items
ORDER BY id;
That final query should be recorded as the precondition, but its result is not asserted here as observed.
Explicit integer IDs are intentional. PostgreSQL documents separate transactional rules for sequences, including visibility and rollback behavior, so sequences would add an irrelevant second subject to a test about identity retrieval. Candidate 101 belongs to A and 202 to B; sequence allocation and gaps are outside this contract.
For every writer session use:
SET search_path = lab, pg_catalog;
SET default_transaction_isolation = 'read committed';
SET lock_timeout = '60s';
SET statement_timeout = '75s';
lock_timeout aborts a statement after too much time waiting to acquire a lock, while statement_timeout bounds the whole statement. PostgreSQL recommends not setting equal values when both are enabled because the statement timeout would make an equal-or-longer lock timeout ineffective. PostgreSQL 18 Client Connection Defaults, accessed September 25, 2026.
A 55P03 lock timeout or 57014 statement cancellation invalidates the canonical acceptance run. The PostgreSQL 18 Error Codes maps those SQLSTATE classes and identifies 40001 as serialization_failure. A timed-out run is evidence that the synchronization window was not completed within its bound, not evidence for or against the missing-ID hypothesis.
Each comparison starts from an independently reset core table:
-- Only after both writer transactions have ended.
TRUNCATE TABLE lab.items;

SELECT count(*) AS reset_row_count
FROM lab.items;
Do not reset by racing a TRUNCATE against active writers.
The three runtime connections are:
# Session A
PGAPPNAME=refonte-goc-A \
psql -X -h 127.0.0.1 -p 5432 \
  -U refonte_goc_app -d refonte_goc_lab

# Session B
PGAPPNAME=refonte-goc-B \
psql -X -h 127.0.0.1 -p 5432 \
  -U refonte_goc_app -d refonte_goc_lab

# Observer O
PGAPPNAME=refonte-goc-observer \
psql -X -h 127.0.0.1 -p 5432 \
  -U refonte_goc_app -d refonte_goc_lab
In A and B, record:
SELECT pg_backend_pid() AS pid,
       current_user,
       current_database(),
       current_schema();

SHOW transaction_isolation;
SHOW lock_timeout;
SHOW statement_timeout;

\echo autocommit=:AUTOCOMMIT
\echo psql_build=:VERSION
In the observer, make every transaction read-only:
SET SESSION CHARACTERISTICS AS TRANSACTION READ ONLY;
SET statement_timeout = '10s';

SHOW transaction_read_only;
SELECT pg_backend_pid() AS observer_pid;
The observer must never query lab.items while coordinating the writers. Its job is scheduling evidence, not inspecting the business row.
Write the insert-and-fallback statement
The canonical B command is:
WITH ins AS (
    INSERT INTO lab.items (id, natural_key)
    VALUES (202, 'item-7')
    ON CONFLICT (natural_key) DO NOTHING
    RETURNING id
)
SELECT id FROM ins
UNION ALL
SELECT id
FROM lab.items
WHERE natural_key = 'item-7'
LIMIT 1;
The intended reasoning looks attractive:
If B inserts, RETURNING supplies 202.
If the row already exists, the second branch finds its ID.
LIMIT 1 returns one identity.
The first two statements do not, however, imply the third under the race being tested.
The PostgreSQL 18 INSERT documentation, accessed September 25, 2026, says RETURNING produces values for rows actually inserted, or actually updated when ON CONFLICT DO UPDATE is used. Only successfully inserted or updated rows are returned. A conflicting row skipped by DO NOTHING does not become an “inserted” row merely because it caused conflict handling.
So test DO NOTHING RETURNING independently from the CTE fallback:
INSERT INTO lab.items (id, natural_key)
VALUES (202, 'item-7')
ON CONFLICT (natural_key) DO NOTHING
RETURNING id;
An empty result from this statement means B inserted no row that RETURNING can report. It does not, by itself, mean the conflicting row is visible to some SELECT in the same command.
The CTE adds a second route to an identity, but PostgreSQL's WITH Queries documentation states that data-modifying CTE substatements and the main query use the same snapshot; RETURNING is the mechanism by which modified rows are communicated to the outer command. A base-table SELECT in the outer query does not acquire a fresh READ COMMITTED command snapshot merely because its sibling INSERT spent time waiting.
That is the difference between this playbook and a general discussion of advanced SQL building blocks. The question is not whether CTEs, indexes or procedures are useful. It is exactly what this data-modifying CTE can observe under one concurrent command snapshot.
The independent expected mapping for the canonical schedule is:
natural_key: item-7
authoritative id after A commits: 101
B candidate id: 202
That expectation is derived from the proposed transaction order. It is not a substitute for the post-run mapping query.
Hold the first insert uncommitted
Reset first, then configure all three sessions. Record A's and B's real PIDs before executing the race.
In Session A:
SET search_path = lab, pg_catalog;
SET default_transaction_isolation = 'read committed';
SET lock_timeout = '60s';
SET statement_timeout = '75s';

SELECT pg_backend_pid() AS a_pid;
\echo autocommit=:AUTOCOMMIT

BEGIN ISOLATION LEVEL READ COMMITTED;

INSERT INTO lab.items (id, natural_key)
VALUES (101, 'item-7')
RETURNING id, natural_key;

-- Stop here. Do not COMMIT yet.
At this point A's insert is intentionally uncommitted.
In Session B, with AUTOCOMMIT on, record its PID and launch exactly one command:
SET search_path = lab, pg_catalog;
SET default_transaction_isolation = 'read committed';
SET lock_timeout = '60s';
SET statement_timeout = '75s';

SELECT pg_backend_pid() AS b_pid;
SHOW transaction_isolation;
\echo autocommit=:AUTOCOMMIT

WITH ins AS (
    INSERT INTO lab.items (id, natural_key)
    VALUES (202, 'item-7')
    ON CONFLICT (natural_key) DO NOTHING
    RETURNING id
)
SELECT id FROM ins
UNION ALL
SELECT id
FROM lab.items
WHERE natural_key = 'item-7'
LIMIT 1;
Do not type COMMIT in A merely because B appears visually stalled. Establish the dependency from O.
PostgreSQL documents that inserts involving unique indexes can block when concurrent sessions manipulate matching unique-index values, and its READ COMMITTED isolation documentation explicitly says ON CONFLICT DO NOTHING can decline an insertion because of another transaction whose effects are not visible to the insert's command snapshot.
Use this observer query, substituting the B PID actually recorded from B:
SELECT
    a.pid,
    a.application_name,
    a.state,
    a.wait_event_type,
    a.wait_event,
    a.xact_start,
    a.query_start,
    pg_blocking_pids(a.pid) AS blocking_pids,
    left(a.query, 180) AS query_excerpt
FROM pg_stat_activity AS a
WHERE a.datname = 'refonte_goc_lab'
  AND a.application_name IN (
      'refonte-goc-A',
      'refonte-goc-B',
      'refonte-goc-observer'
  )
ORDER BY a.application_name;
Then specifically validate B:
SELECT
    pid,
    application_name,
    state,
    wait_event_type,
    wait_event,
    pg_blocking_pids(pid) AS blocking_pids
FROM pg_stat_activity
WHERE application_name = 'refonte-goc-B';
pg_stat_activity provides backend PID, transaction/query timestamps, state and wait-event fields. PostgreSQL warns that state and wait_event are independent: an active backend can simultaneously be waiting. PostgreSQL 18 Cumulative Statistics documentation, accessed September 25, 2026.
pg_blocking_pids(pid) returns the PIDs blocking a backend from acquiring a lock; the function is documented in PostgreSQL 18's System Information Functions.
The acceptance gate before releasing A is therefore:
actual B PID recorded
AND B command is still in progress
AND pg_blocking_pids(actual_B_PID) contains actual_A_PID
AND neither writer has timed out
AND A's transaction has not committed or rolled back
The exact wait_event should be captured rather than invented. Do not make an arbitrary sleep such as sleep 2 the synchronization primitive. The observer query establishes that B is waiting on A; elapsed wall-clock time alone does not.
If O does not show the expected dependency before the timeout, mark that attempt invalid schedule. Do not call it a disproved hypothesis, and do not keep retrying until an aesthetically pleasing transcript appears. Preserve the failed attempt with its PIDs, query starts, SQLSTATE and observer output.
The observer's catalog queries are not a proof that literally nothing else exists anywhere in the database cluster. They establish the scheduling relationship relevant to this fixture. O must remain read-only and must not inspect lab.items until the writer schedule is complete.
Commit A and capture the empty result
Only after the observer has recorded the A-blocks-B dependency should Session A execute:
COMMIT;

\echo a_sqlstate=:SQLSTATE
\echo a_row_count=:ROW_COUNT
Now let B finish naturally. Do not rerun its statement.
Immediately after B returns control, preserve:
\echo b_sqlstate=:SQLSTATE
\echo b_row_count=:ROW_COUNT
Also save B's actual result grid exactly as emitted.
The predicted canonical result is zero rows from the combined statement, with successful SQLSTATE 00000. That is a prediction derived from PostgreSQL 18's documented READ COMMITTED, conflict and CTE-snapshot rules; this article does not label it an observed result.
Why can zero rows occur?
B's command starts while A's row is uncommitted. Its ordinary statement snapshot therefore cannot see (101, 'item-7'). B's unique-key insertion then encounters the in-progress conflicting transaction and waits. When A commits, conflict processing has enough information to suppress B's proposed insertion. PostgreSQL specifically documents that DO NOTHING can suppress an insert because of a transaction whose effects are not visible to the command snapshot.
Because B did not insert, its RETURNING branch contributes no row. PostgreSQL says RETURNING reports successfully inserted or updated rows; DO NOTHING did neither.
The fallback SELECT, however, is still part of the same top-level command. The data-modifying CTE and outer query share their command snapshot, rather than the outer SELECT acquiring a second post-wait snapshot. A's newly committed row can therefore be decisive for uniqueness while remaining absent from the outer base-table read.
That outcome is not:
a duplicate row,
lost data,
a unique-constraint failure,
proof that PostgreSQL ignored A's transaction, or
proof that RETURNING should have returned the pre-existing row.
It is a mismatch between the one-command helper and the caller's “return an identity” contract.
Once B has finished, execute a genuinely new READ COMMITTED statement in B:
SELECT id, natural_key
FROM lab.items
WHERE natural_key = 'item-7';

\echo post_lookup_sqlstate=:SQLSTATE
\echo post_lookup_row_count=:ROW_COUNT
If A committed and no later writer deleted the row, the mathematically derived expectation for this fixture is:
id = 101
natural_key = item-7
row_count = 1
The crucial point is that this expected later observation does not rewrite history. PostgreSQL says that at READ COMMITTED, successive commands in one transaction can observe different committed data because each command takes a new snapshot. PostgreSQL 18 Transaction Isolation. Therefore a later query seeing 101 is not evidence that the earlier same-command fallback could see it.
Finally, independently verify the mapping after all writer activity relevant to the run has ended:
SELECT natural_key, id
FROM lab.items
WHERE natural_key = 'item-7';

SELECT count(*) AS rows_for_key
FROM lab.items
WHERE natural_key = 'item-7';
Those are post-run integrity checks, not scheduling controls. For the canonical A-commits schedule the expected mapping is one row, item-7 -> 101. Preserve the actual result.
A useful transcript distinguishes these questions explicitly:
Measurement | Canonical documented expectation | Observed value |
A insert returned | 101 | Record during execution |
B observed blocked by A | yes | Record during execution |
B ins branch | empty | Record during execution |
B same-command fallback | cannot see A's post-snapshot commit | Record during execution |
Combined B row count | 0 | Record during execution |
New-statement lookup | 101 if row remains | Record during execution |
Final rows for item-7 | 1 | Record during execution |
Final mapping | item-7 -> 101 | Record during execution |
Do not replace the rightmost column with the expectation before running the fixture.
Explain the two visibility boundaries
The race becomes easier to reason about when uniqueness and query visibility are drawn as separate mechanisms.
time ------------------------------------------------------------>

A: BEGIN
A: INSERT (101,'item-7')
   row exists in A's uncommitted transaction
                     |
B:                   | command begins at READ COMMITTED
B:                   | snapshot S_B established
B:                   | INSERT candidate (202,'item-7')
B:                   | unique conflict handling waits on A
                     |
O:                   | confirms B blocked by A
                     |
A:                   COMMIT 101
                     |
B: conflict resolution now prevents inserting 202
   BUT snapshot S_B does not become a new statement snapshot
   RETURNING => no inserted row
   outer SELECT using same command snapshot => may not see 101
   combined result => predicted zero rows

B: command ends

B: NEW SELECT
   new READ COMMITTED command snapshot => can see committed 101
This is the answer to the central question: yes, INSERT ... ON CONFLICT DO NOTHING conflict handling and a fallback SELECT in the same statement can effectively encounter different aspects of the same concurrent row. Conflict handling can take the concurrent row into account sufficiently to suppress B's insertion while ordinary snapshot visibility for the same command still excludes that row. PostgreSQL documents the DO NOTHING exception explicitly and separately documents the command snapshot.
A data-modifying CTE does not impose “insert first, then refresh the snapshot, then select.” PostgreSQL says data-modifying CTE substatements and the main query share a snapshot and that their execution order should not be used as an inter-substatement visibility mechanism.
Nor does placing a separate INSERT and SELECT inside one explicit READ COMMITTED transaction freeze a single snapshot for the whole transaction:
BEGIN ISOLATION LEVEL READ COMMITTED;

INSERT INTO lab.items (id, natural_key)
VALUES (202, 'item-7')
ON CONFLICT (natural_key) DO NOTHING
RETURNING id;

-- This is a different command and therefore gets
-- a new READ COMMITTED command snapshot.
SELECT id
FROM lab.items
WHERE natural_key = 'item-7';

COMMIT;
That is precisely why the separate-command repair can work. At READ COMMITTED, transaction boundaries and snapshot boundaries are not synonymous. Two statements inside the transaction can see different committed states.
The independent controls should be run from a reset table, never stacked onto the canonical evidence.
Schedule | Expected insert outcome for B | Expected B identity | Expected final mapping |
A committed before B command begins | B skips insert | 101 from fallback SELECT | item-7 -> 101 |
A waits; B blocks; A rolls back | B can insert | 202 from ins | item-7 -> 202 |
B runs with no competing row | B inserts | 202 from ins | item-7 -> 202 |
Canonical A commit during B command | B skips insert | same-command result predicted empty | item-7 -> 101 |
Canonical conflict, then new SELECT | B skipped insert | new statement expected 101 if row remains | item-7 -> 101 |
For the committed-first control:
-- A
BEGIN;
INSERT INTO lab.items (id, natural_key)
VALUES (101, 'item-7');
COMMIT;

-- B, started only after A's commit has completed
WITH ins AS (
    INSERT INTO lab.items (id, natural_key)
    VALUES (202, 'item-7')
    ON CONFLICT (natural_key) DO NOTHING
    RETURNING id
)
SELECT id FROM ins
UNION ALL
SELECT id
FROM lab.items
WHERE natural_key = 'item-7'
LIMIT 1;
The expected identity is 101 because B's command snapshot begins after A's commit.
For the rollback-after-observed-wait control, reproduce the canonical blocking dependency but issue ROLLBACK in A only after O proves B is waiting on A:
-- A, after O has captured the blocker relationship
ROLLBACK;
B can then proceed with its candidate row. The expected returned ID is 202, because its INSERT can complete and its CTE RETURNING output is visible to the outer query through ins.
For the no-conflict control, start from an empty reset and execute only B. Expected: B actually inserts 202, so the ins relation contributes 202.
For the sequential fallback control, reproduce the A-commit race using only:
INSERT INTO lab.items (id, natural_key)
VALUES (202, 'item-7')
ON CONFLICT (natural_key) DO NOTHING
RETURNING id;
After it finishes empty, issue a new command:
SELECT id
FROM lab.items
WHERE natural_key = 'item-7';
The expected second-command identity is 101 if A's row is still present.
The word “if” is operationally important: another transaction can delete the row between those commands. A separate statement fixes the invisible-conflict snapshot problem; it does not promise an immortal row.
Decide whether to accept, retry, refactor or hold
The repaired lookup policy should make the fresh-snapshot boundary explicit rather than disguising it inside the CTE.
A bounded helper can be written as follows:
function get_or_create_id(natural_key, candidate_id, max_attempts = 3):

    for attempt from 1 through max_attempts:

        try:
            inserted_id =
                execute one statement:
                    INSERT INTO items(id, natural_key)
                    VALUES(candidate_id, natural_key)
                    ON CONFLICT(natural_key) DO NOTHING
                    RETURNING id

            if inserted_id exists:
                return SUCCESS_INSERTED(inserted_id)

            existing_id =
                execute a NEW statement:
                    SELECT id
                    FROM items
                    WHERE natural_key = natural_key_parameter

            if existing_id exists:
                return SUCCESS_EXISTING(existing_id)

            # No permission to return candidate_id here.
            # The conflicting row may have been deleted between commands.
            if attempt < max_attempts:
                continue

            return RETRY_EXHAUSTED_NO_MAPPING

        catch SQLSTATE 40001:
            return RETRY_WHOLE_TRANSACTION

        catch SQLSTATE 40P01:
            return RETRY_WHOLE_TRANSACTION

        catch SQLSTATE 23505:
            return HOLD_UNEXPECTED_UNIQUE_CONFLICT

        catch SQLSTATE 55P03 or 57014:
            return HOLD_TIMEOUT_OR_CANCELLATION

        catch any other database error:
            return HOLD_DATABASE_ERROR
That bounded behavior is the practical database-specific layer beneath broader backend reliability skills: the caller needs explicit retry semantics and terminal outcomes rather than a loop that retries until the race becomes invisible.
An empty new-statement lookup is materially different from the canonical empty same-command CTE result. After the insert command has ended, the new READ COMMITTED lookup has a fresh snapshot. If it still finds nothing, one plausible schedule is:
A commits item-7 -> 101
B's INSERT sees the uniqueness outcome and does nothing
another transaction deletes item-7 -> 101
B starts its new SELECT
B sees no row
That condition is retry or hold, not authorization to return 101, 202 or any synthetic identifier. The helper knows that its candidate was not returned as inserted; it cannot invent which identity is now authoritative.
The maximum attempt count is a product policy, not a PostgreSQL constant. Three attempts above is an example bound. Record the configured value. Exhaustion should surface a named terminal outcome so callers can distinguish “no mapping could be stabilized” from a successful get-or-create.
For applications that need the row held stable for subsequent transactional work, change the contract rather than pretending a momentary lookup has stronger semantics. For example:
BEGIN ISOLATION LEVEL READ COMMITTED;

INSERT INTO lab.items (id, natural_key)
VALUES (202, 'item-7')
ON CONFLICT (natural_key) DO NOTHING
RETURNING id;

-- Fresh command snapshot plus explicit lifetime protection.
SELECT id, natural_key
FROM lab.items
WHERE natural_key = 'item-7'
FOR UPDATE;

-- Perform only the transactional work that actually requires
-- the row to remain protected.

COMMIT;
The PostgreSQL 18 Explicit Locking documentation, accessed September 25, 2026, says row locks last until transaction end. FOR UPDATE prevents other transactions from modifying or deleting the locked row until the transaction ends.
Choose a weaker mode only because its exacbd268t conflict matrix fits the application. In particular, FOR KEY SHARE blocks deletion and updates that change key values but does not block every non-key update. PostgreSQL documents that distinction explicitly. If subsequent work depends on non-key columns remaining unchanged, FOR KEY SHARE is not enough merely because its name sounds protective.
No row lock makes a promise beyond the lock-holding transaction. After COMMIT, a later transaction can delete the row unless some separate application or schema rule prevents it.
Controls, update alternatives and stronger isolation
Do not repair the missing ID mechanically by converting DO NOTHING into a fake update such as:
INSERT INTO lab.items (id, natural_key)
VALUES (202, 'item-7')
ON CONFLICT (natural_key)
DO UPDATE SET natural_key = EXCLUDED.natural_key
RETURNING id;
At READ COMMITTED, PostgreSQL gives ON CONFLICT DO UPDATE stronger per-row insert-or-update behavior than DO NOTHING, including the ability to operate on the conflicting row even when that version was not conventionally visible to the original command snapshot. That can make RETURNING attractive, but it is not a free read.
The INSERT documentation says ON CONFLICT DO UPDATE requires UPDATE privileges in addition to the relevant insert/select permissions. It also performs an update, which means update locking and update triggers enter the behavior contract.
Prove that distinction in a separate disposable branch. First end every core transaction, then deliberately replace the schema:
-- LAB ONLY comparison branch.
DROP TABLE lab.items;

CREATE TABLE lab.items (
    id          integer PRIMARY KEY,
    natural_key text UNIQUE NOT NULL,
    touches     integer NOT NULL DEFAULT 0
);

CREATE OR REPLACE FUNCTION lab.bump_touches()
RETURNS trigger
LANGUAGE plpgsql
AS $$
BEGIN
    NEW.touches := OLD.touches + 1;
    RETURN NEW;
END;
$$;

CREATE TRIGGER items_touch_on_update
BEFORE UPDATE ON lab.items
FOR EACH ROW
EXECUTE FUNCTION lab.bump_touches();

INSERT INTO lab.items(id, natural_key)
VALUES (101, 'item-7');

SELECT id, natural_key, touches
FROM lab.items
WHERE natural_key = 'item-7';

INSERT INTO lab.items(id, natural_key)
VALUES (202, 'item-7')
ON CONFLICT (natural_key)
DO UPDATE
SET natural_key = EXCLUDED.natural_key
RETURNING id, natural_key, touches;

SELECT id, natural_key, touches
FROM lab.items
WHERE natural_key = 'item-7';
The proposed observation is that the conflict path is an actual PostgreSQL update and therefore invokes the update trigger. PostgreSQL's RETURNING documentation also notes that values returned after modification include changes made by triggers. PostgreSQL 18 Returning Data from Modified Rows, accessed September 25, 2026. Record the real before/after touches values when executed rather than inserting fabricated output into the evidence file.
After that branch, restore the exact core schema before rerunning the canonical test:
DROP TABLE lab.items;
DROP FUNCTION lab.bump_touches();

CREATE TABLE lab.items (
    id          integer PRIMARY KEY,
    natural_key text UNIQUE NOT NULL
);
A DO UPDATE design is legitimate when an update is semantically intended. It should be rejected as a universal missing-ID repair when the only justification is “we need RETURNING,” because permissions, trigger behavior and lock interactions have changed.
Stronger isolation also changes the acceptance boundary. Under PostgreSQL REPEATABLE READ, a transaction uses a stable transaction snapshot rather than acquiring a new normal snapshot for every command, and PostgreSQL warns applications to be prepared for serialization failures. It explicitly recommends aborting and retrying the whole transaction when such a failure occurs.
Therefore do not copy the expected READ COMMITTED transcript into a REPEATABLE READ evidence directory. The PostgreSQL documentation says the special DO NOTHING behavior involving a conflicting transaction invisible to the command snapshot is specific to READ COMMITTED. Under stronger isolation, a conflicting concurrent change can instead cause a serialization failure; 40001 is PostgreSQL's documented SQLSTATE for serialization_failure.
Correct retry structure:
begin transaction attempt

    run every statement belonging to the business transaction

if COMMIT succeeds:
    accept

if SQLSTATE 40001:
    discard every result from that transaction
    start a brand-new transaction attempt from the beginning
Incorrect structure:
BEGIN;
... statement fails with serialization failure ...

-- Wrong: transaction is failed; do not pretend this is a clean retry.
retry_only_the_failed_statement();

COMMIT;
This whole-transaction discipline belongs with wider database administration practices, but this article keeps the scope to the retry boundary for one identity operation rather than branching into topology, replicas or general tuning.
Keep API latency discussions similarly separate. A fresh SELECT costs another database command, so there is an API performance trade-off; that does not justify returning the wrong ID or hiding an ambiguous outcome. Correctness defines the admissible implementations first, then performance work chooses among them.
The evidence tree should preserve every schedule separately:
evidence/
  fixture-revision.txt
  environment/
    server-version.txt
    psql-version.txt
    invocation.txt
    settings.txt

  canonical-a-commit-after-b-waits/
    session-a.txt
    session-b.txt
    observer.txt
    ledger.csv
    final-mapping.txt

  control-a-committed-first/
    ...

  control-a-rolls-back-after-wait/
    ...

  control-no-conflict/
    ...

  control-sequential-fallback/
    ...

  update-returning-trigger-branch/
    ...

  repeatable-read/
    ...
A minimal ledger schema is:
fixture_revision,case_name,run_id,server_build,psql_build,database_name,schema_name,application_role,a_pid,b_pid,observer_pid,b_isolation,b_autocommit,lock_timeout,statement_timeout,a_begin_at,a_insert_at,b_query_start_at,wait_observed_at,blocking_pids,a_resolution,a_resolution_at,b_finished_at,b_sqlstate,b_row_count,b_returned_id,new_select_sqlstate,new_select_row_count,new_select_id,final_rows_for_key,final_mapping_id,retry_decision,acceptance_status,notesDo not fabricate unavailable fields. Use an explicit marker such as NOT_CAPTURED and hold the run if the missing field is acceptance-critical.
psql exposes ROW_COUNT and SQLSTATE, making these easy to append after commands without parsing localized human error text. PostgreSQL itself recommends checking SQLSTATE rather than matching textual messages.
The final disposition matrix is:
Evidence | Decision |
Uncontended B inserts 202; returned ID and mapping are 202 | Accept control |
A committed before B; B returns existing 101; mapping is 101 | Accept control |
A rolls back after proven wait; B inserts and returns 202 | Accept control |
Canonical dependency proved; A commits; same-command result is empty; new statement returns 101; final mapping is 101 | Refactor original one-command helper; accept separate-command repair for momentary lookup policy |
DO NOTHING RETURNING empty but new-statement SELECT returns expected existing ID | Accept lookup result |
New-statement SELECT also empty | Retry within declared bound or hold; never invent an ID |
Caller needs row stability beyond lookup | Refactor into transaction plus consciously selected row lock |
40001 | Retry the whole transaction from the beginning |
Timeout during acceptance schedule | Invalid run / hold evidence |
B was not demonstrated to be blocked by A | Invalid schedule / hold evidence |
Unexpected 23505, including an ID/primary-key collision outside the intended natural-key conflict | Hold and investigate fixture or ID policy |
UPDATE-trigger side effects are unacceptable | Reject no-op DO UPDATE repair |
Documentation and executed PostgreSQL 18 behavior materially disagree | Hold; preserve both records and investigate rather than selecting the convenient interpretation |
Identity lifetime is undefined | Hold design |
Release qualification should include the uncontended path, committed-existing path, rollback-after-wait path, the deliberately invisible-conflict path and the delete-between-statements retry path. A helper proven only by a happy-path insert has not demonstrated its negative identity semantics.
Likewise, successful local runs are scoped evidence for the recorded server build, client build, fixture revision and settings. They are not evidence that every PostgreSQL version, driver, pooling mode or application topology behaves identically. That is why the baseline records the software actually executed instead of borrowing a version number from the documentation.
The acceptance principle is simple: database uniqueness and identity return are two different contracts. PostgreSQL can preserve the first while the original one-command helper violates the second.
Strengthen database integration practice with Refonte Learning
This concurrency fixture sits at the boundary between backend code and database administration: the developer must define what “success” means, while the database maintainer must prove that transaction visibility, locking and retry behavior satisfy that definition.
Refonte Learning's Database Administrator Essentials programme page, accessed September 25, 2026, describes a three-month programme at 12–14 hours per week and lists areas including SQL/query optimization, database design, backup and recovery, performance and security. Those foundations are relevant to building disciplined database test and integrity practices, although the programme page does not establish that this specific PostgreSQL ON CONFLICT concurrency laboratory or PostgreSQL 18 is part of its syllabus.
The useful habit to carry from this playbook is narrower than any product feature: declare the caller's integrity contract, force the difficult schedule intentionally, capture the database evidence that separates snapshots from conflicts, and refuse to convert an unexplained empty result into an invented identity.