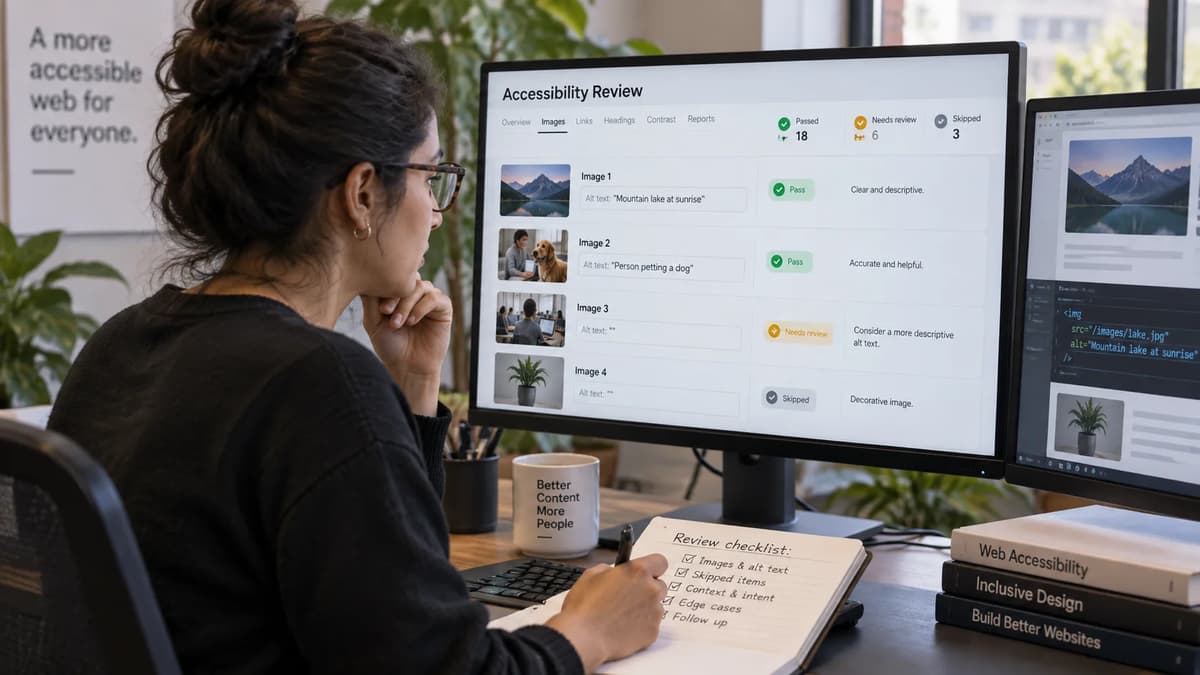
A clean alt-text scan creates a dangerous management shortcut: “no issues” can be read as “the images are accessible.” For GitHub’s accessibility-scanner alt-text plugin, that conclusion is only defensible after you can answer a narrower set of questions: which content was eligible, which checks were attempted, which items were skipped, which images reached the optional model path, and which findings were actually reviewed by a person.
This guide is for accessibility engineers, QA leads, frontend teams, and security reviewers who need an alt-text scanner coverage audit, not a product demo. GitHub Engineering’s August 24, 2026 article titled “Your alt text passes automated checks. That doesn’t mean it’s any good” documents five deterministic checks, an opt-in model-backed quality check, image re-fetch failures outside the browser session, and skipped model or fetch errors. The live GitHub accessibility-scanner alt-text plugin repository, accessed September 15, 2026 adds configuration and output details.
The operating principle is simple: evidence must distinguish “not applicable,” “not eligible,” “attempted,” “completed,” “skipped,” “flagged,” “model-inspected,” and “human-reviewed.” The result should be a coverage ledger that survives CI, privacy review, and later audit. It should never convert tool silence into a completeness claim.
As of the September 15, 2026 research cutoff, the practical decision is not whether AI can write better alt text. It is whether your test platform can prove the boundaries of execution and information flow well enough for reviewers to trust a scoped result.
Define what a complete scan would need to account for
Start with the denominator, not the issue count. The plugin’s documented scope is narrower than “all non-text content,” so the denominator for a GitHub alt-text plugin run must be explicit. A useful coverage ledger starts with content discovered in the test state, then records why each item did or did not enter the plugin’s rule path. GitHub documents extraction through Playwright’s image role and then narrowing to actual HTML <img> elements; several classes are filtered before rules run.
Proposed coverage ledger
Ledger field | What it answers |
Content scope | Which URL, state, viewport, authentication state, and commit were evaluated? |
Relevant non-text inventory | What image-like content existed, including items outside plugin scope? |
Plugin-eligible <img> set | Which elements reached extraction after documented filtering? |
Rule attempts | Which configured rules were invoked for each eligible item? |
Completed / skipped | Did the rule finish, or did fetch/model/execution handling prevent a result? |
Findings | Which deterministic or model-backed rules emitted issues? |
Human decision | Accepted, rejected, corrected, escalated, or deferred with owner? |
The important distinction is that “zero findings” is an output count, not a coverage denominator. If ten relevant items exist, six are eligible, five complete the intended rule path, and none produces a finding, the report is not “ten passed” or even “six passed.” It is “five completed checks with no finding, one eligible item unresolved, and four relevant items outside plugin scope,” subject to the exact rule matrix.
That accounting complements broader AI-assisted accessibility testing, but it solves a different QA problem: proving what this specific plugin did and did not execute.
Coverage gate: Do not publish “complete alt-text assessment” unless the relevant-content denominator, plugin-eligible denominator, completed-check denominator, skip count, and human-review status are all stated.
Separate structural rules from contextual quality review
The repository documents five default deterministic rules: missing alt, vague alt, filename-as-alt, repeated alt, and placeholder alt. A sixth rule, alt-text-quality, is model-backed, disabled by default, and requires separate enablement plus credentials. The repository explicitly says the five defaults do not call a model.
This separation matters because deterministic evidence and contextual judgment support different claims. A literal filename detector can prove that a string ends in a recognized image extension. It cannot prove the alternative serves the equivalent purpose of the image in context. Likewise, a model may judge that prose is incomplete or suggest replacement wording, but GitHub describes model findings as prompts for human attention rather than final verdicts.
Five default rules and an optional model-backed path
The documented defaults are cheap and predictable relative to a model call, but they remain scoped heuristics. The repeated-alt rule, for example, uses rendered layout proximity rather than simple DOM adjacency; GitHub notes that its distance multiplier is a judgment call and that a missing measurable box can cause the check to fail open.
Rule class | Default? | Evidence produced | What it cannot establish |
Missing / whitespace alt | Yes | Attribute-state problem on eligible <img> | Correct contextual alternative |
Vague / filename / placeholder | Yes | String matches documented pattern | Full semantic inadequacy |
Repeated alt | Yes | Repetition under plugin layout heuristic | Whether repetition is always harmful in context |
Model-backed quality | No | Model judgment, reasoning, possible suggestion | Conformance or human intent |
The repository also warns that its missing-alt rule overlaps with the scanner’s built-in axe image-alt rule when both scans are enabled. Deduplicate evidence by rule source rather than counting two findings as two independent defects.
Missing, empty, questionable and inadequate are different states
W3C’s live alt Decision Tree, accessed September 15, 2026 says empty alt="" can be appropriate for decorative content, redundant content, and some images whose nearby text already provides what users need. It also says functional images in links or buttons should communicate the destination or action.
WCAG 2.2 Success Criterion 1.1.1 is the normative anchor: non-text content presented to users needs a text alternative serving the equivalent purpose, subject to stated exceptions such as controls, tests, sensory content, CAPTCHA, and decoration/formatting/invisible content. W3C’s Understanding SC 1.1.1, accessed September 15, 2026 explains those cases.
Review distinction: missing alt is an attribute state; valid empty alt is a contextual choice; “questionable” is a heuristic classification; contextually inadequate alt is a human judgment tied to purpose. Do not collapse those states into one severity bucket.
Inventory the content the plugin can and cannot reach
The repository says extraction begins with page.getByRole('img') and then narrows to actual <img> elements. It filters non-<img> elements with role="img", images in aria-hidden="true" subtrees, images hidden with display:none or visibility:hidden, and decorative <img alt=""> elements before rules run. GitHub’s engineering article separately states that only HTML <img> is covered; SVG, role="img" containers, CSS backgrounds, and canvas are not covered.
That is a plugin eligibility boundary, not a WCAG boundary. A canvas chart or inline SVG can still be relevant non-text content even though this plugin will not inspect it. Similarly, a decorative image filtered out by the plugin may be correctly excluded from alt-quality rules, but the team still needs confidence that its decorative classification is intentional.
Proposed eligibility inventory
Fixture/content type | Relevant to page accessibility? | Plugin eligible? | Audit treatment |
Visible <img alt="Product assembly diagram"> | Yes | Yes | Record deterministic path; model only if approved/enabled |
Visible <img alt=""> intended decorative | Yes, as a classification decision | No, filtered | Record excluded; human spot-check purpose |
<svg role="img"> | Often | No | Route to another check/manual review |
<div role="img"> | Often | No | Route to another check/manual review |
Canvas-rendered chart | Often | No | Review equivalent information separately |
CSS background carrying information | Potentially | No | Treat as design/accessibility review item |
Hidden <img> | Depends on state | No in documented filtered states | Confirm whether another interactive state exposes it |
A practical test plan should therefore maintain two inventories: “relevant visual/non-text content in the test state” and “plugin-eligible content.” The delta between them is first-class evidence. That same discipline is familiar in visual regression testing: a tool’s observation surface is not identical to the product’s complete user-experience surface.
Inventory check: For every excluded class, name the compensating test owner. “Excluded by plugin” is a routing decision, not closure.
Trace the data path before enabling model analysis
The deterministic rules do not require model calls. The opt-in quality path does. GitHub’s repository says that, in model mode, each image as a data URL, its alt text, and nearby page text are sent to GitHub Models; optional Azure AI Vision can add an OCR-and-tags pre-pass. GitHub’s engineering article adds that the model context includes the nearest heading, page title, any <figcaption>, whether the image is inside a link or button, and up to 600 characters of nearby prose.
For AI accessibility testing data boundaries, that means the unit of review is not “an image.” It is a composite payload assembled from image bytes plus page context. Context can contain personal data, confidential project names, internal navigation labels, signed URLs, or adversarial text. Before enabling the model path on sensitive systems, use synthetic fixtures and obtain approval for the actual recipient and artifact flow.
Proposed data-flow register
Stage | Data category | Recipient / location | Required decision |
Browser extraction | <img> HTML, alt, layout/context | CI runner / scanner process | Is this environment approved for page content? |
Image retrieval | Image URL and fetched bytes | Network target + runner | Can authenticated assets be fetched safely? |
Model request | Image bytes/data URL, alt, nearby context | Documented model recipient | Is external processing approved? |
Optional OCR pre-pass | Image bytes | Azure AI Vision when configured | Is this second recipient approved? |
Finding output | Page URL, original HTML, problem/solution text | Scanner reporting / GitHub issue flow | Are issue permissions and retention appropriate? |
Logs | Error and execution information | CI/logging system | Are sensitive values minimized and access-controlled? |
Review GitHub Models and optional additional processing
The live repository, accessed September 15, 2026, documents alt-text-quality as disabled by default and requiring a GitHub Models token; it says Azure AI Vision is optional. The August 24 engineering article describes the same data flow.
There is, however, a source tension that a QA or security review should not hide. A separate GitHub Changelog entry dated August 4, 2026 says that “GitHub Models, the inference service used by Spark’s llm() function,” retired on July 30, 2026. The plugin repository and engineering article published or updated after that date still document a GitHub Models path.
I would therefore classify runtime availability of the documented model path in a target organization as unverified until exercised in a controlled environment. Do not infer from repository documentation alone that credentials will produce a successful model call on September 15, 2026. This is precisely the kind of product-documentation conflict that belongs in a pre-production fact check.
Distinguish model-input redaction from issue-output content
GitHub’s engineering article says query strings and fragments are stripped from image URLs and link href values before model context or rule error logs, while src and srcset are replaced with (omitted) in markup sent to the model. The same article explicitly warns that findings still carry the real page URL and original HTML into the scanner’s normal reporting pipeline.
That boundary is easy to miss. A security reviewer must test model-input redaction and finding-output minimization separately. Reducing what reaches a model does not prove that issue payloads, CI artifacts, logs, or downstream integrations contain the same reductions.
Stop boundary: Do not enable model analysis on sensitive content until recipients, payload categories, issue outputs, access controls, and organizational retention rules are approved. Redaction in one branch of the pipeline is not a blanket privacy guarantee.
Make skipped work visible in the result
GitHub states that the model-backed rule re-fetches images outside the browser session. Authenticated assets can therefore fail even when the browser rendered them successfully. Fetch failures and model errors are logged and skipped, which means a clean issue list can coexist with incomplete execution.
This is the central failure mode for skipped accessibility checks: “skipped” is not a finding, and many issue systems are optimized to display findings rather than absent evidence. Your wrapper or post-processing layer should promote execution state to a first-class result.
Proposed state model
State | Meaning | Allowed release interpretation |
eligible-not-attempted | Item met scope but configured path never ran | Coverage gap |
attempted-completed-no-finding | Rule finished and emitted nothing | No finding for that rule only |
attempted-finding | Rule finished and emitted issue | Needs triage/review |
skipped-fetch | Image could not be obtained for model path | Unresolved coverage |
skipped-model | Model call failed/unavailable | Unresolved coverage |
excluded-scope | Relevant item is outside plugin target | Route elsewhere |
human-reviewed | Person made contextual decision | Record decision and rationale |
Do not overload “pass.” A deterministic rule can complete without a finding, but that does not mean the alt is contextually adequate. A model call can complete without a finding, but GitHub itself says model output is not unfailingly correct. A skipped check supplies no negative evidence at all.
Ownership prevents skips from becoming permanent blind spots. Fetch failures belong to the test-platform or application team depending on cause; model-service failures belong to the platform owner; scope exclusions belong to the accessibility test strategy; unresolved semantic questions belong to a qualified human reviewer.
Recovery checklist: identify the skipped item; preserve a minimized locator; assign an owner; define the rerun or manual substitute; block completeness language until the gap is resolved or explicitly accepted.
Build a text and HTML fixture inventory
A scanner audit should begin with synthetic fixtures whose intended purposes are known. That lets you test extraction, rule routing, skip accounting, model-data boundaries, and human review without exposing production content. The fixture set below is a proposed test design, not an observed result from GitHub’s plugin.
Use deliberately artificial names, routes, and image bytes. Keep credentials fake. This is also where general automation engineering foundations matter: controlled inputs, deterministic assertions, isolated failure modes, and versioned test data make later CI evidence interpretable.
Proposed fixture matrix
ID | Synthetic fixture | Intended purpose | Expected coverage state | Expected recipient path | Human decision |
F1 | <img src="/decorative-wave.png" alt=""> | Pure decoration | Excluded before plugin rules | Local only | Confirm empty alt is intentional |
F2 | <img src="/team.png"> | Informative photo | Eligible; missing-alt rule should be attempted | Local deterministic | Require author-provided contextual alternative |
F3 | <img src="/chart.png" alt="chart"> | Informative chart | Eligible; vague rule expected to flag | Local deterministic | Escalate because chart may need longer equivalent data |
F4 | <img src="/hero.jpg" alt="IMG_0042.jpg"> | Informative hero image | Eligible; filename rule expected to flag | Local deterministic | Rewrite from content purpose |
F5 | Two nearby <img ... alt="3/5 stars"> elements | Rating visualization | Eligible; repetition path exercised | Local deterministic | Decide whether group needs one consolidated alternative |
F6 | <a href="/billing"><img src="/card.png" alt="Credit card"></a> | Image-only functional link | Eligible | Model only if approved | Review whether alt should name destination/action |
F7 | <svg role="img" aria-label="Quarterly trend">…</svg> | Informative vector graphic | Excluded from plugin | No plugin recipient | Route to separate SVG/manual check |
F8 | <canvas id="trend"></canvas> plus text table | Complex chart | Excluded from plugin | No plugin recipient | Verify equivalent data and naming |
F9 | <img src="/protected/account.png" alt="Account summary"> | Authenticated asset | Eligible structurally; model fetch deliberately denied | Model attempt then skipped-fetch expected | Manual review or authenticated retrieval design |
F10 | <img src="/person.png" alt="A smiling person"> under synthetic named profile heading | Context-sensitive informative photo | Deterministic no-finding plausible; model path optional | Approved model recipient only | Decide whether identity is necessary in this context |
F11 | Same as F10 with model endpoint intentionally unavailable | Failure-path exercise | skipped-model expected | Attempted model recipient, no completed judgment | Require fallback/manual review |
F12 | <img aria-hidden="true" src="/ornament.png" alt="Ornament"> | Hidden decoration | Filtered | Local only | Confirm hidden state matches user experience |
For F9 and F11, the acceptance criterion is not a finding. It is visible skip evidence. For F10, the acceptance criterion is not that the model “improves” the text; it is that a reviewer receives enough context to accept, reject, or revise any suggestion without losing the author’s intended meaning.
Fixture rule: Expected outcomes describe what the test is designed to exercise. They are not audit scores, recall estimates, or evidence that the tool behaved that way until the test actually runs.
Design contextual human review
Human review begins where literal string evidence stops. W3C’s decision tree makes purpose central: the same image may require a description, an action/destination name, an empty alternative, or additional equivalent information depending on how it is used.
GitHub also documents a limitation in the model context: the plugin records that an image sits inside a link, but does not determine whether it is the link’s only content. That distinction matters because an image-only link may depend on the image alternative for its accessible name, while a link with sufficient adjacent text may not.
Proposed alt-text human review checklist
Purpose: What information or function would be lost if the image were unavailable?
Context: Is the needed information already present in nearby text, caption, heading, or data table?
Function: Is the image inside a link or control, and what action or destination must be communicated?
Meaning: Does the proposed alternative preserve the intended identity, relationship, tone, or data, not merely visible objects?
Decision: Accept, revise, reject as unnecessary, or escalate for content/design clarification.
A model-generated replacement is a draft, not an edit authorization. Reject a suggestion when it adds unsupported identity, changes emphasis, repeats surrounding text, describes decoration that should be silent, substitutes visual detail for functional purpose, or omits information necessary to understand a complex image.
Review quality also depends on QA judgment rather than tool familiarity alone. The related Refonte article on QA skills for AI-assisted testing is useful background for that broader skill set, but it is not evidence about this plugin’s behavior.
Stop boundary: Stop automated edits when a proposed change can alter meaning, identity, destination, or information hierarchy. Require contextual approval before source code or CMS content is changed.
Work through a clean report with incomplete coverage
Consider a fictional run against F1–F12 from the fixture matrix. This is a reasoning exercise, not an observed scan. Suppose the deterministic path completes for every plugin-eligible item. Suppose the opt-in model path is approved for synthetic fixtures, but F9 cannot be fetched outside the browser session and F11 reaches a deliberately unavailable model service. Suppose every completed check emits zero model-backed findings after deterministic findings are remediated.
A naïve dashboard can display “0 open alt-text issues.” The coverage ledger tells a different story.
Hypothetical arithmetic for the fixture exercise
Measure | Count | Interpretation |
Relevant fixtures inventoried | 12 | Test-plan denominator |
Outside plugin extraction/rule scope | 4 | F1, F7, F8, F12 need documented handling |
Plugin-eligible fixtures | 8 | Candidate denominator for plugin rules |
Model-path candidates in this exercise | 4 | F6, F9, F10, F11 by local test design |
Completed model judgments | 2 | F6 and F10 only, hypothetically |
Model skips | 2 | F9 fetch, F11 service |
Open findings after remediation | 0 | Issue count, not completeness |
The clean issue count cannot erase the two model skips or four scope exclusions. Nor can it prove that the deterministic no-finding cases are semantically correct. The scoped verdict must preserve those distinctions.
Protected content that cannot be fetched
GitHub’s article says the model rule re-fetches images outside the browser session, so an authenticated image can render in the tested browser and still fail when the plugin independently retrieves it. Fetch and model errors may be logged and skipped.
For F9, record two separate facts: “browser state displayed the protected image” and “model retrieval did not obtain the image.” Do not write “image passed model review.” The missing evidence is the image-content judgment itself.
Recovery checklist: preserve the browser-visible locator; classify skipped-fetch; capture a non-secret failure reason; assign platform/authentication ownership; rerun only after an approved retrieval design or substitute manual review.
A plausible suggestion that changes the intended meaning
For F10, imagine the model proposes “Portrait of Dr. Avery Chen, Chief Medical Officer,” while the fixture’s only verified context is a heading with the fictional name “Avery Chen” and no verified role. The suggestion is fluent but adds an unsupported title.
The human decision should reject the title, determine what identity is actually needed, and choose an alternative supported by page purpose. That may be a shorter name-focused alternative, a description, or even different surrounding markup depending on the design.
Correction workflow: reject unsupported semantics; record why; edit through the normal content-review path; rerun deterministic checks; optionally rerun model review; close only after a person confirms the final alternative in context.
Use WebAIM’s numbers without mixing populations
The WebAIM Million 2026 report, accessed September 15, 2026 evaluated the rendered home pages of the top one million sites in February 2026 using WAVE plus additional tooling. WebAIM explicitly says automated tools have limitations and that absence of detected errors does not indicate accessibility or conformance.
For images, WebAIM reports more than 66.6 million images in the sample. It says 16.2% of all home-page images had missing alternative text, excluding alt="". Separately, 10.8% of images with alternative text had alternative text classified as questionable or repetitive, including examples such as generic words, filenames, or duplication with adjacent content.
Those percentages use different denominators. The first percentage starts from all sampled images; the second starts from the subset that already has alternative text. Adding 16.2% and 10.8% would mix populations and create a number that does not represent a valid plugin recall target.
Denominator discipline
WebAIM measure | Denominator | Safe use here | Unsafe use |
16.2% missing alternative text | All images in sampled home pages | Market/context evidence that missing alternatives remain common | Expected plugin defect rate |
10.8% questionable/repetitive | Images that have alternative text | Evidence that presence alone does not settle quality | Add to 16.2% as if same population |
53.1% of home pages with missing-alt failures | Sampled home pages | Page-level prevalence context | Convert to image-level probability |
WAVE automated findings | Rendered sampled home pages | Automated-accessibility context | Full WCAG conformance assessment |
There is another important mismatch: WebAIM’s questionable/repetitive classification and GitHub’s plugin rules are not the same measurement instrument. Some labels overlap conceptually (filenames, generic strings, repetition), but that does not establish a recall rate, precision rate, or expected finding count for the plugin.
Use the dataset to motivate disciplined testing, not to validate the tool. No source supplied here shows the GitHub plugin run against WebAIM’s million-page corpus under a controlled protocol. A model suggestion also does not convert WebAIM’s descriptive statistics into evidence of WCAG satisfaction.
Reporting rule: Always name the population immediately beside a percentage. Never turn WebAIM’s web-wide observations into a plugin performance benchmark without a separate evaluation.
Define QA gates for coverage and data handling
A useful release gate separates three questions: did the planned checks execute, did qualified people review context-sensitive results, and was the information flow approved? None of those alone establishes full WCAG conformance.
The following thresholds are proposed local policy examples, not GitHub defaults or WCAG requirements. Teams should set their own based on risk, architecture, and release process.
Proposed gate matrix
Gate | Proposed denominator | Example local condition | Owner |
Extraction accounting | Relevant inventory | 100% classified as eligible, excluded-with-route, or not applicable | Accessibility QA lead |
Deterministic completion | Eligible item × enabled deterministic rule | No unexplained execution gaps | Test-platform owner |
Model completion | Approved model candidates | No unowned fetch/model skips | QA + platform |
Human review | Context-sensitive findings and sampled no-finding cases | Required reviews completed | Accessibility reviewer |
Data-flow approval | Enabled external-processing paths | All recipients/payload classes approved | Security/privacy reviewer |
Conformance claim | Applicable WCAG evaluation scope | Separate criterion-based evidence | Accessibility program owner |
The value is not the percentage itself; it is the named denominator and owner. “98% complete” is meaningless unless readers know whether the missing 2% represents two decorative images, an authenticated checkout flow, or the only chart conveying financial results.
This gate model also fits a wider delivery discipline described in Refonte’s DevOps lifecycle management: checks need visible ownership and feedback loops across development and operations. That article is adjacent process context, not authority for GitHub plugin behavior.
Blocking conditions: unaccounted skips; undisclosed excluded relevant content; unapproved model recipients; unreviewed meaning-changing suggestions; or a report label that implies full accessibility assessment from plugin evidence alone.
Integrate the audit with CI without automating meaning away
Continuous integration (CI) is where coverage evidence becomes repeatable, but it can also turn a narrow rule set into a misleading binary. The safer design is to gate on evidence states, not simply on “finding count equals zero.”
Pin the plugin implementation or package version according to your dependency policy, retain the configuration used for each run, and review changes that enable alt-text-quality, disable deterministic rules, alter fixture expectations, or add an optional processing service. The live repository recommends a pinned plugin version in its workflow example and says unknown/non-boolean rule configuration values are warned and ignored, while missing or malformed configuration falls back to defaults.
Proposed CI policy
CI event | Automated action | Required evidence |
Pull request | Run deterministic rules on controlled states | Version, config hash, eligible count, completed count, findings |
Scheduled synthetic job | Exercise model path if approved | Recipient mode, model-attempt count, skips, fixture assertions |
Sensitive environment | Keep model path disabled until approved | Approval record or explicit “not enabled” state |
Config change | Require code-owner/security review | Diff showing rule and recipient changes |
Suggested alt change | Do not auto-merge solely from model output | Human contextual decision |
Do not bulk-replace alt text because a model produced fluent suggestions. GitHub says suggested text is a draft and cannot account for the full audience, house style, or the role an image plays on the whole page.
Teams already using browser automation can borrow orchestration ideas from Playwright AI test workflows, while preserving the sharper boundary here: generation, execution, evidence, and human semantic approval are separate stages.
Safe failure policy: CI may fail or warn on deterministic findings according to local policy, but unresolved skips must never be converted to passes. A model outage should degrade to an explicit incomplete state, not a green semantic-quality gate.
Preserve a useful and minimized audit trail
An accessibility QA evidence ledger should be detailed enough to reconstruct what ran without turning the issue tracker into a copy of sensitive page content. GitHub’s documented finding shape includes scannerType, ruleId, page url, offending <img> outer HTML, problem fields, a reference URL, and solution fields; model-backed findings can include a suggested replacement and explanation. The scanner uses those fields in its issue flow.
GitHub’s engineering article is especially important for data minimization: redaction before the model does not mean the resulting issue is similarly redacted. Findings can still contain the real page URL and original HTML.
Proposed evidence record
Evidence category | Retain | Minimize / avoid |
Execution identity | Commit, workflow/run ID, plugin version, config fingerprint | Unnecessary environment dumps |
Scope | Tested route/state labels, relevant and eligible counts | Real customer identifiers in fixture names |
Rule execution | Enabled rules, attempts, completions, skip reasons | Full response bodies when a reason code suffices |
Findings | Stable locator, rule ID, concise problem statement | Secrets, signed query strings, unrelated nearby DOM |
Model path | Enabled/disabled, approved recipient mode, attempt/skip state | Raw prompt payload unless explicitly required and protected |
Human review | Decision, rationale category, reviewer role/date | Personal notes unrelated to the decision |
Remediation | Change reference and verification status | Copies of production data in tickets |
Retention duration and access should come from organizational policy, contractual requirements, and risk classification. This guide does not infer a vendor retention promise from the plugin README. If your organization needs vendor-specific retention, training-use, regional processing, or subprocessor answers, verify the current applicable service documentation and agreement before production use.
Also treat logs and issues as separate stores. CI logs may expose error context; GitHub issues may persist longer and have broader readership; exported reports may leave both systems. Security review should follow the actual artifact graph.
Minimum useful trail: enough evidence to reproduce scope and execution, explain every skip, tie each human decision to a finding or sampled item, and show what changed, without retaining unrelated page content by default.
Pilot with synthetic fixtures before sensitive content
A 30-day pilot can validate the operating model without implying that the plugin itself requires a 30-day rollout. The schedule below is a proposed local progression designed to surface extraction, skip, privacy, and review problems before sensitive pages are scanned.
Proposed 30-day progression
Period | Activity | Exit condition |
Days 1–7 | Run deterministic rules on F1–F12; validate eligible/excluded accounting | Every fixture has an expected coverage state |
Days 8–14 | Exercise protected-asset and failure fixtures with no sensitive data | Fetch/model skips appear distinctly from passes |
Days 15–21 | Security review of model inputs, recipients, issue outputs, logs, permissions | Data-flow approval or documented rejection |
Days 22–26 | Enable approved model path only on synthetic fixtures | Model attempts/completions/skips are measurable |
Days 27–30 | Trial one low-sensitivity internal page with human review | Scoped verdict template accepted by QA/security |
The checklist before expansion is short: confirm content classification; confirm model/data recipients; validate skip reporting; validate issue payload minimization; confirm human reviewer ownership. Do not move to sensitive content because the synthetic findings “look good.” Move only when the evidence path is observable and approved.
For practitioners building the underlying QA, automation, CI/CD, and security-testing foundations, the Refonte Learning QA Automation Engineering Program lists a three-month format at 12–14 hours per week and covers QA fundamentals, automated scripts, test frameworks, CI/CD, performance testing, and security/compliance testing; admissions state that applicants are pursuing or have completed a bachelor’s degree in computer science, engineering, or a related field. Those are transferable foundations for this kind of coverage accounting, not a claim that the program teaches this plugin or an accessibility specialization.
Pilot stop rule: No sensitive model analysis before data-flow approval; no completeness claim with unresolved skips or undisclosed scope exclusions; no unattended semantic edits.
Answer the coverage questions and issue a scoped verdict
A mature alt-text scanner coverage audit ends with a bounded statement, not a victory label. The team should be able to say what content the plugin was eligible to inspect, what it actually attempted, what completed, what was skipped, what the model saw, what a person reviewed, and which accessibility obligations remained outside the tool.
Is empty alt text always an error?
No. W3C’s decision tree explicitly identifies cases where empty alt="" is appropriate, including decorative and redundant images. WCAG 2.2 SC 1.1.1 also provides a decoration/formatting/invisible exception when content is implemented so assistive technology can ignore it. The correct question is whether empty alt matches the image’s purpose in context.
Can a skipped check be counted as a pass?
No. GitHub says authenticated image re-fetches can fail and fetch/model errors can be logged and skipped. A skip means the intended evidence was not produced. It should remain unresolved until rerun, replaced by an approved manual check, or explicitly accepted as a scoped limitation.
Does the default plugin run inspect images with a model?
No, according to the live repository. Five deterministic rules run by default; alt-text-quality is opt-in. Because GitHub’s separate August 4 changelog creates uncertainty about current GitHub Models runtime availability, treat actual model execution as an environment-specific fact to verify, not an assumption.
Does a clean plugin report establish WCAG conformance?
No. The plugin targets a narrow class of HTML images and specific alt-related heuristics. WCAG 2.2 SC 1.1.1 covers non-text content more broadly and contains contextual requirements and exceptions. WebAIM likewise warns that absence of automatically detected errors does not indicate accessibility or conformance.
Use this proposed final verdict template:
Statement | Status |
Tested | Named URLs/states; documented eligible <img> set; enabled deterministic rules; approved model attempts; listed human reviews |
Not tested by this plugin | SVG/role="img" containers, canvas, CSS backgrounds, filtered content, unvisited UI states, and any other disclosed exclusions |
Incomplete | Any fetch/model/execution skip, inaccessible state, or unreviewed context-sensitive item |
Data boundary | Named model/OCR recipients actually enabled plus issue/log destinations |
Conformance | Not claimed from plugin output alone; requires criterion-based evaluation beyond this scan |
The release statement should read like evidence: “For commit X and the listed test states, the plugin completed the named deterministic checks on the recorded eligible <img> population. The model-backed path was [disabled / attempted under approved configuration], with [blank] unresolved skips. Human reviewers completed the listed contextual decisions. Non-<img> content and other disclosed exclusions were not assessed by this plugin. No full WCAG conformance claim is made from these results.”
That is less satisfying than “all clear,” but it is the statement a principal test-platform engineer can defend.