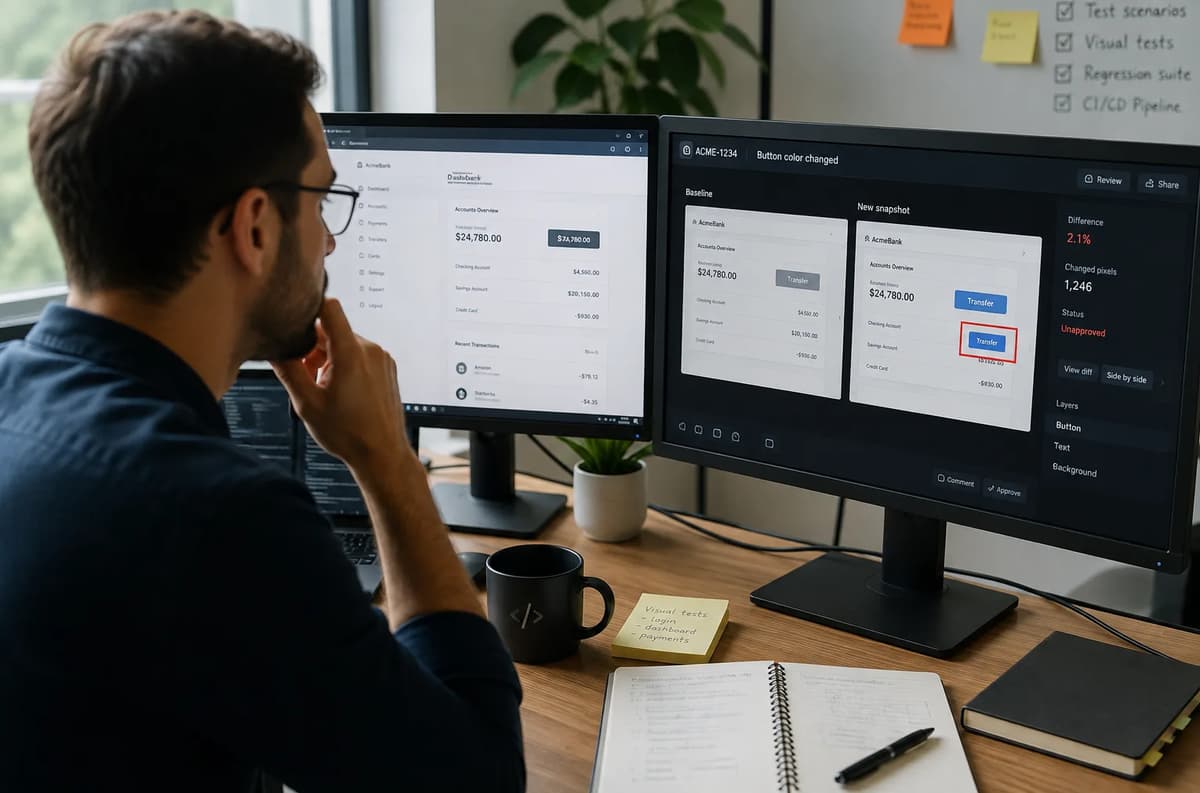
An AI coding assistant can generate a functional test, run it, repair it, and leave you with a green build while a button has silently moved three pixels to the left. The workflow can still succeed because the assertion asked whether the button exists, whether it can be clicked, or whether the click reaches the expected page, not whether the rendered interface still looks correct.
That distinction matters more in visual regression testing in 2026 because the leading visual-testing vendors have spent the year attacking a problem that is almost the inverse of autonomous test generation. Applitools is reducing noisy visual differences through Dynamic Match Level and Regions Only while connecting Eyes to coding assistants through MCP; Chromatic is filtering unstable visual tests and publishing Storybook context through MCP; Percy is using Visual AI, Intelli-ignore, natural-language review summaries, and root-cause information to cut the amount of visual noise a reviewer has to inspect.
The practical lesson is that AI visual testing tools and AI test-generation agents occupy different layers of the QA stack. Playwright's Test Agents include a planner that creates a test plan, a generator that turns the plan into Playwright tests, and a healer that executes and repairs tests; visual regression systems compare rendered states against baselines and help teams understand whether the change is intentional.
This comparison explains what Applitools vs Percy vs Chromatic actually means in 2026, where the vendors genuinely differ, where their strategies converge, why MCP is becoming an important bridge, and which QA automation engineer skills in 2026 matter when you add visual regression to an existing framework.
Visual Regression Testing Is Not What Playwright's Agent Mode Does
The cleanest way to understand visual testing vs AI test agents is to stop treating “AI testing” as one product category.
Playwright's current Test Agents solve a test-authoring and maintenance problem. The planner explores an application and writes a test plan, the generator converts that plan into Playwright Test files, and the healer runs tests and repairs failures; Microsoft explicitly describes the sequential workflow as producing test coverage for the product.
Visual regression testing asks a different question. Instead of primarily asking, “Did this workflow behave as expected?”, it asks, “Did this interface render differently from the accepted state, and is that difference legitimate?”
Agentic Test Generation: Playwright Test Agents | Visual Regression Testing: Applitools, Percy, Chromatic |
Plans, generates, and repairs test code | Captures or renders visual states and compares them with baselines |
Primarily verifies workflows and functional expectations | Primarily verifies appearance, layout, styling, assets, and rendered states |
AI participates in creating or repairing tests | AI increasingly filters noise, explains diffs, stabilizes comparisons, or exposes visual context |
Best at finding broken journeys and behavioral failures | Best at finding unintended rendering and presentation changes |
Output is test code or repaired test execution | Output is a visual comparison, review signal, or baseline decision |
A login test illustrates the boundary. A functional assertion can prove that the username field accepts text, the submit button is clickable, authentication succeeds, and the dashboard URL loads while completely missing a CSS change that overlays the submit button with another element, truncates its label, changes its color contrast, or moves it outside its intended grid.
That is not a defect in functional automation. It is a mismatch between the type of assertion you wrote and the class of risk you expect it to detect.
There is an important technical nuance here: Playwright itself can perform visual comparisons. Its toHaveScreenshot() assertion creates reference screenshots and compares subsequent output against them, while its documentation warns that operating system, browser version, hardware, fonts, headless mode, and other environmental factors can alter rendering.
So the accurate distinction is not “Playwright cannot do visual testing.” The distinction is that Playwright's Test Agents are an agentic test-generation capability, whereas screenshot comparison, whether implemented with Playwright's native snapshots or a dedicated service such as Applitools, Percy, or Chromatic, is a separate visual-testing discipline.
That separation is also why this article does not repeat Playwright's new AI test agents and how they generate and repair tests. The useful question here starts after you already have functional coverage: what observes the rendered result that functional assertions never inspect?
Why “AI Testing” Isn't One Thing
The phrase hides at least three distinct uses of machine intelligence: generating test logic, stabilizing or maintaining test execution, and interpreting visual output. Conflating them creates the dangerous assumption that adopting an AI test agent automatically gives you visual coverage.
Applitools makes that gap unusually explicit. Its July 28, 2026 MCP article argues that coding assistants can generate functional test code while layout regressions, component misalignment, and UI shifts still pass code-level checks; its MCP integration then makes visual verification available from the same coding-assistant workflow.
Chromatic makes almost the same observation from the component-testing side. Its May 27, 2026 Vitest visual-testing preview says a browser-test assertion can pass while the interface remains visually wrong, then shows Vitest creating the component state while Chromatic captures that state, compares it with the baseline, and sends the visual change to the team for a decision.
That is the core of visual regression testing 2026: functional automation answers whether the software works according to programmed behavior, while visual regression testing establishes whether the software still presents that behavior correctly to a user.
Applitools vs Percy vs Chromatic: What Actually Changed in 2026
The strongest evidence that visual regression testing has become its own AI-assisted discipline is not a generic prediction about AI. It is the release history.
Applitools and Chromatic both published multiple dated 2026 visual-testing releases. Percy presents a dense current AI feature set too, but Percy's official release note supplies an important date correction: Percy's Visual Review Agent has an official release note dated June 6, 2025, so it should not be misrepresented as a newly shipped 2026 feature simply because it appears prominently on the current 2026 product page.
Vendor | Date | Release or capability | Visual-testing job it addresses |
Applitools | May 12, 2026 | Eyes MCP Server | Brings visual checkpoints/results into AI-assisted IDE workflows |
Applitools | May 21, 2026 | Regions Only | Limits comparison to meaningful areas and avoids dynamic-page noise |
Applitools | July 16, 2026 | DLMs + Visual AI positioning for codeless monitoring | Makes repeatable visual checks possible without conventional locator scripts |
Applitools | July 23, 2026 | Dynamic Match Level, diff descriptions, PDF testing | Suppresses expected dynamic changes and expands visual coverage |
Applitools | July 28, 2026 | MCP/AI-assistant visual-testing integration article | Defines visual verification as an external signal for AI-generated code |
Percy | June 6, 2025 | Visual Review Agent launch | Filters/prioritizes diffs and summarizes changes |
Percy | Current product page (2026) | Intelli-ignore, Root Cause Analysis, visual-test integration agent | Cuts visual noise, explains source of diffs, accelerates setup |
Chromatic | March 23, 2026 | Published Storybook MCP servers | Gives coding agents shared component, story, test, and API context |
Chromatic | May 13, 2026 | React Native visual-testing preview | Extends visual comparison to hosted iOS/Android simulator workflows |
Chromatic | May 27, 2026 | Vitest Visual Testing preview | Adds managed visual snapshots and review to browser tests |
Chromatic | July 14, 2026 | Automatic flaky-test filtering | Detects unstable visual tests and removes them from blocking PRs |
What Applitools Actually Shipped in 2026
The May 12 release of the Applitools MCP Server is important because it does not replace the Eyes execution engine or create a new functional test-generation architecture. Applitools says the server connects AI assistants to Eyes, can set up Eyes in an existing project, add visual checkpoints to existing tests, configure its Ultrafast Grid, fetch results, and expose batch information from the IDE.
At publication, Applitools documented support specifically for the Playwright JavaScript/TypeScript Fixtures SDK, with Selenium, Cypress, and WebdriverIO not yet supported by that MCP server. The post explicitly says MCP augments the workflow rather than replacing the underlying Eyes SDK, a useful distinction when evaluating MCP as integration infrastructure rather than another execution engine.
Nine days later, on May 21, Applitools introduced Regions Only for Autonomous. Instead of treating a highly dynamic full page as one visual assertion, the feature lets you target components such as navigation, data grids, or brand assets while allowing intentionally variable areas outside those regions to change without triggering the same volume of review noise.
That is a classic visual-regression engineering problem. The hard part is often not detecting every pixel difference; it is maintaining enough sensitivity to catch a broken component without teaching the team to ignore the test because rotating banners, personalized content, timestamps, promotions, and data values change on every build.
On July 16, Applitools described Autonomous using Deterministic Language Models and Visual AI for codeless, repeatable production-facing visual checks. That release positioning matters because it extends how checks get expressed and executed, but the target remains a deterministic/repeatable verification signal rather than the planner-generator-healer model documented by Playwright Test Agents.
Then, on July 23, Applitools announced plain-English diff descriptions in Eyes and Dynamic Match Level, conditional steps, and PDF testing in Autonomous. Dynamic Match Level recognizes six built-in categories of content expected to change, including dates, emails, links, numbers, currency, and input fields, plus custom patterns, while still performing a Strict comparison and accounting for positional shifts caused by changing values.
PDF support expands the surface being visually validated: invoices, contracts, statements, and reports can be opened and checked inside an Autonomous custom flow instead of requiring a separate document-comparison pipeline. Plain-English diff descriptions attack the review bottleneck from another direction by grouping visual changes into descriptions that can be surfaced through the UI, APIs, and the MCP server.
Finally, the July 28 article connects those ideas directly to AI-assisted development. Applitools' argument is that an IDE assistant may write functional test code, yet an element can remain technically present while looking wrong to the user; the Eyes MCP integration gives that assistant access to a separate visual-verification system and lets it summarize visual differences alongside code changes.
Applitools also announced on January 20, 2026 that it had been named a Strong Performer in The Forrester Wave™: Autonomous Testing Platforms, Q4 2025. That is useful market context, but it should be described precisely as an Applitools announcement about Forrester's Q4 2025 evaluation rather than as evidence that every Applitools marketing claim has received independent validation.
What Percy Actually Offers in 2026
BrowserStack's current Percy page concentrates heavily on AI-assisted visual review. The Percy Visual Review Agent prioritizes meaningful changes and produces natural-language summaries, with BrowserStack claiming a 3x reduction in review time; Intelli-ignore filters dynamic elements such as carousels, ads, and banners; and Root Cause Analysis identifies whether a visual difference stems from DOM, CSS, or layout changes.
Percy also markets a visual test integration agent with a claimed 6x faster setup, including identifying and configuring requirements and adding visual coverage to existing tests from the IDE. The stronger technical wording comes from BrowserStack's current Visual Testing Plugin documentation: it requires an existing test suite and adds coverage by inserting percySnapshot() calls; BrowserStack explicitly says, “It does not write the tests for you.”
That documentation makes the boundary unusually concrete. The plugin can run the visual review loop, classify differences, drive an agent toward fixes, and gate visual changes, but it starts from existing Playwright, Cypress, Selenium, Puppeteer, Storybook, or another supported test suite rather than replacing that suite with autonomously generated functional scenarios.
The date needs equal precision. BrowserStack's official release notes date the Visual Review Agent launch to June 6, 2025, with the company then claiming a 3x reduction in review time and filtering of up to 40% of visual changes; the current Percy product page presents it as part of today's feature set but does not turn that original 2025 launch into 2026 news.
Likewise, the current product page presents cross-browser capabilities, current Visual AI features, and its integration experience without supplying a 2026 release date for every capability. Any specific Percy “Visual Engine rebuild” or cross-browser/mobile date that cannot be independently tied to a dated 2026 BrowserStack announcement should therefore be treated as established background capability, not a fresh 2026 release.
Percy's customer framing reinforces the review-efficiency theme. Its current page features Basecamp, Canva, Autodesk, and other customers around visual confidence, while the Intercom case-study excerpt emphasizes eliminating extra manual QA cycles; the same page positions AI around setup acceleration, noise reduction, and review/debugging rather than around replacing the underlying functional suite.
What Chromatic Actually Shipped in 2026
Chromatic has the cleanest dated release sequence of the three around flake management and AI-agent context. On March 23, it announced published Storybook MCP servers, giving teams a shared authenticated MCP resource containing component APIs, stories, usage patterns, and tests, while Chromatic handles publishing, authentication, and versioning.
This is not identical to Eyes MCP. Applitools exposes a visual-testing service and its visual results to an AI assistant; Chromatic publishes Storybook context so an agent understands the design system and can use Storybook's testing tools while generating and correcting UI code.
On May 13, Chromatic previewed React Native visual testing using hosted iOS Simulator and Android Emulator environments, automatic parallelization, baseline tracking, pull-request checks, and collaborative diff review. The announcement was explicitly an early-access preview rather than a claim of universal general availability.
On May 27, its Vitest Visual Testing preview connected browser tests to cloud visual snapshots. Chromatic's example is particularly useful pedagogically: Vitest verifies that an accordion opens, while Chromatic snapshots the closed and open states so the same underlying state setup verifies both behavior and appearance.
Then Chromatic flaky test filtering arrived on July 14. Flake Filter renders tests multiple times to determine whether they are stable; unstable tests move into an automatically ignored group, stop blocking the build, remain reviewable, and receive traces for debugging, while Chromatic reevaluates them on subsequent builds so recovered tests re-enter the suite.
Chromatic's comparison strategy is unusually explicit as well. Its visual-testing comparison page, updated in March 2026, links dedicated comparisons or categories for Applitools, Percy, Sauce Labs, Katalon, LambdaTest, SmartBear, TestingBot, Lost Pixel, Backstop, and Playwright, making it a useful primary source for how Chromatic wants buyers to frame the market, but it remains a vendor source whose performance and ROI claims should not be mistaken for neutral benchmarking.
The Pattern Across All Three: AI Reduces Noise, Humans Still Decide
Once you strip away vendor terminology, the shared 2026 engineering problem becomes obvious: visual regression systems become unusable when legitimate or unstable visual variation overwhelms genuine regressions.
A naïve screenshot comparator can detect an enormous amount of change. A useful visual-testing system has to tell you which change deserves attention.
Tool / feature | Source of noise being addressed | What the system does | What remains for the team |
Applitools Dynamic Match Level | Dates, prices, IDs, changing text and resulting layout movement | Recognizes expected dynamic data patterns and associated movement | Decide whether remaining visual changes are legitimate |
Applitools Regions Only | Dynamic areas surrounding a stable critical component | Restricts visual validation to chosen components/regions | Choose meaningful regions and review failures |
Percy Intelli-ignore | Dynamic banners, ads, carousels and other recurring variation | Filters/suppresses visual noise according to sensitivity | Inspect meaningful differences |
Percy Visual Review Agent | Large sets of raw visual diffs | Classifies, prioritizes and summarizes changes | Approve or reject the actual change |
Chromatic Flake Filter | Intermittently unstable renders | Rerenders, identifies unstable tests and removes them from build-blocking diffs | Debug flaky tests and review real diffs |
The sources describe different algorithms and configuration models, so it would be inaccurate to say they all use the same mechanism. What they share is the operational objective: increase the signal-to-noise ratio before a human spends review time.
That distinction matters because a visual baseline is not an oracle. A deliberate redesign produces a visual difference just as surely as a broken CSS selector does, so any production-worthy workflow needs a decision about whether the new image becomes the accepted baseline.
Percy's documentation is exceptionally explicit about this boundary. Its Visual Review Agent can categorize changes as likely bugs or valid updates and compare changes with a pull-request summary, but BrowserStack states that the classification advises the reviewer and does not approve or reject the changes for them; its interface reminds users to review before approving.
Chromatic's Vitest workflow expresses the same model without calling it an agent. When a snapshot differs from the accepted baseline, Chromatic reports the change in the pull request so the team can inspect it and decide whether to accept it.
Even Percy's newer AI-coding-agent plugin keeps human control around consequential review outcomes. BrowserStack documents “human review at every decision,” while the plugin requires confirmation for attention-worthy outcomes and explicitly starts from an existing test suite rather than generating the tests itself.
This is why the blanket statement “AI approves the visual changes now” is not a good description of these products. The more defensible description is: AI narrows, classifies, stabilizes, summarizes, and contextualizes visual evidence so a reviewer can reach the right decision faster.
Dynamic Match Level vs. Intelli-ignore
Applitools Dynamic Match Level and Percy Intelli-ignore are easy to lump together because both reduce noise from content expected to change, but the details matter. Dynamic Match Level recognizes classes of changing values and can absorb the resulting positional movement; Percy describes Intelli-ignore in terms of controlling sensitivity and filtering dynamic elements such as ads, banners, and carousels.
Regions Only is closer to a deliberate scope-selection strategy: the engineer declares which portions of a page should act as visual assertions while allowing the rest of a dynamic page to vary. It is therefore useful when you can draw a clear boundary between “this component must remain visually stable” and “this surrounding content legitimately changes every run.”
From a QA architecture perspective, the lesson is not to chase the cleverest diff algorithm. It is to choose a tool whose stabilization and configuration model your team can understand well enough to distinguish environmental variation, expected product change, and an actual rendering defect.
That ability is what prevents alert fatigue. Once engineers routinely click “accept” because a visual suite cries wolf on every pull request, the nominal amount of visual coverage stops mattering.
MCP Is Becoming the Bridge Between Visual Testing and AI Coding Agents
MCP, the Model Context Protocol, is emerging as an integration layer between coding agents and systems that hold information the model does not natively possess. In visual testing, the important development is that both Applitools and Chromatic shipped concrete MCP integrations in 2026 rather than merely publishing roadmaps about them.
Their implementations solve related but different problems.
MCP implementation | What the coding assistant can reach | Primary purpose |
Applitools Eyes MCP Server | Eyes setup, visual checkpoints, cross-browser configuration, visual results and batch information | Bring visual verification into an existing AI-assisted test/development workflow |
Chromatic published Storybook MCP servers | Component APIs, stories, usage patterns, tests, design-system context and Storybook testing tools | Give coding agents shared UI/component context and a way to iterate against Storybook feedback |
Applitools' May 12 implementation can add Eyes setup and visual checkpoints to an existing Playwright project, return structured visual results, and expose the dashboard when deeper review is necessary. The July 28 article extends that idea by showing the assistant summarizing visual differences alongside the code changes that produced them.
That architecture is significant because the AI assistant does not have to become the visual comparison engine. It can call a specialized system that owns baselines and visual analysis, then bring that evidence back into the development context.
Chromatic's March 23 approach begins from Storybook as the source of UI context. A published Storybook MCP server gives coding agents information about real components, their APIs, stories, usage conventions, and tests, and Chromatic can publish a server for each Storybook deployment with authentication and version-specific access.
In practical terms, this can reduce a different failure mode: an agent inventing a component API, choosing a component inconsistent with the design system, or generating UI without knowledge of the states already documented in Storybook. Chromatic says Storybook MCP also connects agents with testing tools so they can iterate after render errors, failed tests, or accessibility problems.
The two products therefore should not be described as identical “visual MCP servers.” Eyes MCP is explicitly a bridge into a visual-testing service; Chromatic publishes a Storybook MCP endpoint that carries component and test context into agentic UI development.
Their convergence is still strategically meaningful. Two separate visual/UI-testing vendors decided in 2026 that AI coding agents should consume context from dedicated QA/UI systems instead of relying only on what the general-purpose model can infer from source code.
That is a healthier architecture than asking one probabilistic agent to generate a change, invent its own expectation, and act as the only judge of whether the output is correct. A specialized visual system provides a second evidence channel, even when an AI assistant becomes the interface through which the developer consumes that evidence.
For a senior QA engineer, MCP knowledge therefore belongs in the “useful architectural literacy” category rather than the “first skill to learn” category. You still need to understand baselines, false positives, deterministic environments, component stability, visual-review policy, and CI/CD before an MCP endpoint improves anything.
First: build a reliable visual signal.
Then: reduce its false positives.
Then: integrate it into pull-request and CI/CD workflows.
Finally: expose that signal to coding agents through MCP where it actually shortens feedback loops.
MCP makes visual context more accessible. It does not remove the need to design the visual test correctly.
Choosing Between Applitools, Percy, and Chromatic: A Practical Framework
There is no defensible universal winner in Applitools vs Percy vs Chromatic because the three products enter the stack from different starting points. The best decision usually follows your existing UI architecture, browser/device requirements, review process, and tolerance for baseline configuration more closely than it follows a single headline AI feature.
Factor | Practical best fit | Why |
Team already uses Storybook as a core UI-development system | Chromatic | Storybook-native workflow plus published Storybook MCP context |
Need broad BrowserStack-centered browser/device testing workflows | Percy | Percy sits inside BrowserStack's broader testing infrastructure and emphasizes cross-browser visual review |
Need granular visual matching and targeted dynamic-content controls | Applitools | Dynamic Match Level, Regions Only and long-standing Eyes visual-validation model |
Want visual results exposed directly to an AI coding assistant | Applitools | Eyes MCP explicitly exposes setup, checkpoints and visual results |
Want coding agents grounded in the team's published component system | Chromatic | Published Storybook MCP servers expose APIs, stories, usage patterns and tests |
Main pain is overwhelming review volume | Percy | Visual Review Agent, natural-language summaries, Intelli-ignore and RCA center the experience on review triage |
Main pain is flaky component snapshots | Chromatic | Flake Filter repeatedly evaluates stability and automatically separates unstable tests |
Need to validate PDFs inside the same visual-testing workflow | Applitools Autonomous | July 2026 PDF support extends visual validation to document flows |
The Storybook case is particularly straightforward. Chromatic is made by the Storybook maintainers, builds its visual workflow around stories as testable UI states, and in 2026 extended that relationship to published MCP infrastructure and new Vitest/React Native integrations.
Percy's strength is different. BrowserStack's current product experience brings visual testing into the same vendor ecosystem as its browser/device infrastructure, while the product page emphasizes automated cross-browser checks, review workflows, Visual AI filtering, Intelli-ignore, RCA, and AI-assisted integration.
Applitools gives you the deepest 2026 discussion around how visual matching should behave when content is dynamic. Regions Only, Dynamic Match Level, diff descriptions, PDF testing, and Eyes MCP collectively cover comparison scope, expected change, triage, new content types, and agent integration.
Do not turn those observations into an unchecked procurement recommendation. Vendor performance figures, including Percy's 3x/6x claims or any vendor's test-execution and ROI numbers, should be validated against your own component count, browser matrix, CI environment, baseline churn, pull-request volume, and reviewer workflow before you treat them as expected results.
A useful proof of concept is not “run the homepage once.” Give each candidate the same difficult set of conditions: one intentional redesign, one genuine layout regression, one rotating or randomized component, one delayed font or asset load, one viewport-specific defect, and one pull request containing dozens of legitimate visual changes.
Then measure reviewer effort rather than screenshot count.
Proof-of-concept metric | What you are really measuring |
True regression detected | Sensitivity |
Legitimate changes incorrectly escalated | False-positive burden |
Dynamic changes automatically handled | Stabilization quality |
Time from build completion to reviewer decision | Workflow efficiency |
Ease of tracing a diff back to CSS/DOM/component change | Debuggability |
Baseline update effort after an intended redesign | Maintenance cost |
CI configuration required | Integration overhead |
Quality of PR/IDE feedback | Developer usability |
When Visual Regression Testing Isn't Worth the Investment
A small application with a stable UI, infrequent releases, one browser target, and a team that can reliably inspect every visual change may not need a commercial visual-testing platform. Playwright's own screenshot comparisons can already create and compare reference screenshots, although teams still need to control rendering environments because browser and host differences affect screenshot output.
The economics shift when the interface grows faster than manual inspection. A component library with dozens of states, frequent design-system changes, multiple browsers, responsive breakpoints, multiple teams, or AI-assisted UI generation creates enough visual surface area that manual “looks fine to me” review becomes difficult to perform consistently.
Start with the stable, business-critical surface. Checkout controls, navigation, pricing presentation, authentication screens, dashboards, reusable design-system components, and regulated documents usually produce more meaningful early coverage than snapshotting every transient marketing widget.
The right tool is the one that lets your team keep high sensitivity without high fatigue.
Where Visual Regression Testing Fits in a Modern QA Stack
Visual regression works best as a layer, not as a replacement for the test architecture underneath it.
A mature pipeline should be able to distinguish a functional failure, a visual regression, a flaky render, and an intentional design change because each demands a different engineering response.
QA layer | Question it answers | Example failure |
Unit/component logic | Does isolated logic produce the right result? | Price calculation returns the wrong value |
Functional UI automation | Can the user complete the workflow? | Checkout button does not submit |
Agentic test generation/maintenance | Can we create or repair functional coverage more efficiently? | Missing test journey or stale generated locator |
Visual regression testing | Does the rendered UI still look like the accepted state? | Button is clipped, shifted, overlapped, wrong color, or incorrectly sized |
Accessibility testing | Can users with accessibility needs operate the UI according to tested rules? | Missing accessible name or contrast issue |
Performance/security testing | Does the system satisfy nonfunctional requirements? | Excessive load time or security weakness |
The middle two rows are where teams frequently confuse categories. AI-assisted generation can increase the amount of functional test code you have, while visual comparison increases the kinds of UI regressions the test system can observe.
That means adding one does not make the other redundant. The broader context of automation, AI, CI/CD, and professional testing roles is covered in the broader AI testing shift covered in this ISTQB-aligned guide; the narrower skill here is knowing where visual evidence belongs in that stack.
The practical integration point is usually the pull-request pipeline. Functional tests bring the application into important states, visual snapshots capture selected states or components, a comparison service evaluates them against accepted baselines, and the CI system reports whether the build contains behavior failures, visual differences, or both.
Percy's own FAQ describes its model as capturing screenshots, comparing them against a baseline, and highlighting changes in an existing CI/CD pipeline. Chromatic's Vitest integration similarly reports visual changes into pull requests for review, while Applitools' MCP example describes Playwright running visual validation in CI and the developer consuming visual differences alongside the PR.
Skills Priority Order for QA Engineers Adding Visual Testing
For QA automation engineer skills in 2026, I would prioritize the following order:
Priority | Skill | Why it matters |
Must | Distinguish functional failures from visual regressions | You cannot triage correctly until you know what type of signal failed |
Must | Configure stable baselines, match behavior and ignore/target regions | Bad configuration converts real coverage into alert noise |
Must | Control rendering conditions | Visual output changes with browsers, fonts, OS and environment |
Should | Integrate visual checks into an existing CI/CD pipeline | Visual testing should extend, not duplicate, automation infrastructure |
Should | Review AI-generated diff summaries critically | Summaries accelerate review but do not remove reviewer accountability |
Should | Debug visual changes through DOM/CSS/component context | A diff tells you what changed visually; engineering still needs a cause |
Good | Understand MCP architecture | Useful for connecting visual/UI context to coding agents |
Good | Challenge vendor benchmark and ROI claims | Your application's change rate and visual surface determine actual value |
Playwright's own visual-comparison documentation reinforces why environment control belongs near the top. It warns that host operating systems, versions, settings, hardware, browser conditions, and other factors can change screenshot output and recommends comparing under consistent conditions.
Applitools, Percy, and Chromatic are all investing in ways to reduce that operational burden, but they do not make basic QA judgment obsolete. Chromatic's Flake Filter can identify unstable rendering, Percy can suppress dynamic noise, and Applitools can treat changing data differently; an engineer still needs to know why a test is unstable and whether ignoring variation creates a blind spot.
That is why distinguishing failure types ranks first. If every red visual result gets filed as a product defect, the product team will stop trusting QA; if every intermittent visual result gets accepted as “just flake,” real regressions will eventually hide inside the noise.
For the wider professional foundation surrounding those capabilities, the essential skills, tools, and portfolio projects for a QA automation career provides the broader career framework. Visual regression should sit on top of automation fundamentals rather than becoming the first tool a beginner learns.
Certifications and Portfolio Signals Worth Having
There is not a clearly established, vendor-neutral professional certification whose central assessment is mastery of Applitools, Percy, Chromatic, and production visual-regression engineering as a discipline. Applitools' Test Automation University does offer dedicated visual-testing education and certificates, while BrowserStack offers broader testing certifications, so it is more accurate to distinguish course completion credentials from a standardized industry certification specifically for visual regression.
For hiring, a strong visual-regression portfolio artifact can therefore say more than another tool logo in a skills section. Document one scenario in which a functional suite remained green, a visual check caught the defect, the raw diff initially contained noise, and you configured the workflow so the real regression remained detectable without recurring false alerts.
A good portfolio case study should include:
the functional assertion that passed;
the visual defect that assertion could not observe;
the baseline and changed state;
the stabilization or match configuration;
the CI result and reviewer workflow;
and a short explanation of why you accepted or rejected the new baseline.
That demonstration connects naturally with essential trends and career strategies for QA automation engineers in 2026 without reducing visual regression to another checkbox in a generic tool list.
Common Mistakes Teams Make Adopting Visual Regression Testing
Snapshotting Everything Instead of Stable Components Only
Teams often equate more snapshots with more coverage, including personalized dashboards, timestamps, ads, rotating carousels, unstable loading states, and components that change on nearly every commit.
The result is exactly the problem the 2026 feature releases are trying to control. Applitools' Regions Only targets stable regions inside dynamic pages, Dynamic Match Level recognizes expected changing content, Percy's Intelli-ignore suppresses dynamic elements, and Chromatic's Flake Filter separates unstable renders.
Start with stable, high-risk components and expand when the signal remains trustworthy.
Treating a Visual Diff as Automatically a Bug
A visual difference means the current render and accepted baseline disagree; it does not, by itself, tell you whether the new render is wrong.
A product redesign, approved typography change, localized copy, updated brand asset, or intentionally enlarged button should produce a visual diff. The correct workflow reviews that change and updates the baseline when the new state is intended.
Fixing Flake by Loosening Everything
Raising tolerances or ignoring whole areas may make a dashboard greener while destroying the test's ability to detect the regression you bought the tool to catch.
Prefer the narrowest correction that addresses the known instability: normalize test data, wait for fonts or assets, control animation, constrain the environment, target the stable region, or use a tool's purpose-built dynamic-content handling. Playwright, for example, supports applying a stylesheet during screenshot capture to hide volatile elements, while the commercial tools add their own stabilization models.
Creating a Second Automation Estate
If your functional framework already drives the application through the correct state, the visual layer should normally reuse that state rather than forcing QA to maintain a parallel set of journeys simply to take screenshots.
That pattern appears directly in current vendor integrations. Applitools MCP adds visual checkpoints to existing Playwright tests; Percy's visual-testing plugin requires an existing test suite and inserts snapshots; Chromatic's Vitest example layers visual snapshots onto an existing browser test.
The engineering goal is one maintainable automation architecture with multiple assertion types.
Self-Study vs. a Structured QA Automation Program: An Honest Comparison
The specific visual-testing vendor you eventually use matters less at the beginning than whether you understand test design, automation frameworks, repeatable execution, and CI/CD. Without those foundations, adding Applitools, Percy, or Chromatic tends to create another isolated dashboard rather than a coherent quality gate.
A self-study route can absolutely build those skills. The trade-off is that learners have to design their own sequence, create realistic CI failures, resist tutorial-only “happy paths,” and build enough project scope to demonstrate that their framework works outside a local laptop.
Factor | Self-study | Structured QA Automation Engineering Program |
Time to a working framework | Often planned as roughly 2–4 months, depending on prior coding experience | Framework implementation is an explicit curriculum module |
CI/CD depth | Depends on whether the learner deliberately builds a pipeline project | CI/CD Pipeline Integration is a dedicated module |
Agile QA discipline | Usually acquired through work or self-designed project practice | Managing QA in Agile Development is a dedicated module |
Portfolio proof | Personal repositories and case studies; scope varies | Capstone Project plus program completion credentials |
Route to foundational coverage | Commonly 6–12+ months when learning is fragmented; this is an illustrative planning range, not an employment guarantee | Program itself runs for 3 months and covers the framework/pipeline foundation |
Visual-vendor training | Can deliberately learn Applitools, Percy or Chromatic | The published curriculum does not name those tools |
The Refonte Learning QA Automation Engineering Program
The distinction is important. The Refonte Learning program page names core QA tools including Selenium, JUnit, Jenkins, and Cucumber; it does not list Applitools, Percy, Chromatic, Playwright, or Cypress as part of the published visual-testing curriculum. The defensible connection is architectural: its framework-implementation and CI/CD modules teach the foundation into which a visual-testing service would later integrate. Refonte Learning QA Automation Engineering Program
That distinction matters because visual regression tooling is not an isolated beginner skill. A visual screenshot has to come from a stable test state; the test needs repeatable data and environment handling; CI needs credentials and failure policies; developers need usable pull-request feedback; and somebody needs ownership of baseline changes.
The Refonte Learning QA Automation Engineering Program runs for 3 months with a stated 12–14 hours per week commitment. Its page lists career outcomes including QA Automation Engineer, QA Engineer, and Software Tester, and requires applicants to be pursuing or to have completed a bachelor's degree in computer science, engineering, or a related field.
The seven published curriculum areas are:
Introduction to Quality Assurance Engineering
Building and Running Automated Test Scripts
Implementing QA Automation Frameworks
CI/CD Pipeline Integration
Performance and Security Testing
Managing QA in Agile Development
Capstone Project in QA Automation
Those modules are confirmed on the current program page. In the context of visual regression, Implementing QA Automation Frameworks and CI/CD Pipeline Integration are the most directly relevant foundations because commercial visual tools are normally added to an existing framework and pull-request pipeline rather than deployed as a replacement for functional automation.
The program's named mentor is MSc Oskar Eriksson, Department of Software Engineering. Refonte's page describes him as having more than a decade of technology-industry experience and expertise spanning full-stack development, cloud technologies, and software optimization.
Upon successful completion, Refonte says participants receive a Training Certificate and Certificate of Internship. The page says students who demonstrate outstanding performance may also receive a Letter of Recommendation and Certificate of Appreciation.
The published fees are $300 as a one-time payment, or installments of $204 and $98. Those two installment amounts total $302, so applicants comparing payment options should use the currently displayed checkout/program terms rather than assuming the installment total equals the one-time price.
Refonte's own page also markets the QA Automation Engineering track with a “$94.0K+ Starting” figure and “120K+ (Jobs Annually)” figure. Those are Refonte Learning's marketing claims on its program inventory, not independently established salary or labor-market estimates in this article; readers comparing compensation should separately consult the full QA automation salary guide.
The useful connection to visual testing is therefore straightforward rather than promotional: learn to build and run test automation reliably, learn how frameworks are structured, learn how Jenkins-style CI/CD integration works, and then adding an Eyes checkpoint, Percy snapshot, Chromatic visual run, or another visual service becomes an extension of a system you understand rather than a ground-up rebuild.
That sequencing also makes you more vendor-independent. Match levels, diff algorithms, MCP integrations, and commercial product names will change; the ability to design test states, isolate instability, interpret failures, control CI/CD, and defend a baseline decision travels from one visual tool to another.
Program Snapshot
Item | Published detail |
Duration | 3 months |
Weekly commitment | 12–14 hours/week |
Format | Online, structured as a virtual internship program |
Core published tools to highlight | Selenium, JUnit, Jenkins, Cucumber |
Mentor | MSc Oskar Eriksson, Department of Software Engineering |
Completion credentials | Training Certificate + Certificate of Internship |
Additional recognition | Letter of Recommendation and Certificate of Appreciation may be awarded to top performers |
Career outcomes listed | QA Automation Engineer, QA Engineer, Software Tester |
Prerequisite | Pursuing or completed bachelor's degree in computer science, engineering, or related field |
One-time fee | $300 |
Installment option | $204 + $98 |
FAQ: People Also Ask
Is visual regression testing the same as AI test generation?
No. Visual regression testing captures or renders UI states and compares them with accepted baselines to identify appearance changes, while agentic test generation creates, plans, or repairs functional tests.
Playwright's current Test Agents demonstrate the latter: its planner creates a plan, its generator creates Playwright Test files, and its healer repairs failing tests. Applitools, Percy, and Chromatic visual workflows add a different verification layer focused on what the interface rendered.
What did Applitools ship in 2026?
Applitools published the Eyes MCP Server on May 12, Regions Only on May 21, a July 16 discussion of DLM-powered codeless visual monitoring, and on July 23 announced Dynamic Match Level, plain-English diff descriptions, conditional steps, and PDF testing. Its July 28 MCP article then positioned visual verification as a deterministic external signal that AI coding assistants can consume.
The visual-regression throughline is less about autonomously inventing a new functional suite and more about making visual checks easier to integrate, less noisy, broader in scope, and faster to review.
How does Percy's Visual Review Agent work?
Percy's Visual Review Agent analyzes detected visual changes, prioritizes meaningful differences, provides human-readable summaries, and can classify changes to help reviewers focus on likely regressions. BrowserStack currently claims a 3x reduction in review time, while Intelli-ignore filters dynamic elements such as carousels, ads, and banners and Root Cause Analysis helps identify DOM, CSS, or layout causes.
The release date needs precision: BrowserStack's official release note dates the Visual Review Agent launch to June 6, 2025, not 2026. Its documentation also states that AI classifications advise the reviewer rather than approving or rejecting visual changes on the reviewer's behalf.
What is MCP's role in visual regression testing?
MCP gives AI coding assistants a standardized route to external context instead of forcing them to infer everything from their model and the source files currently in context. Applitools' Eyes MCP Server exposes visual-testing setup, checkpoints, and visual results, while Chromatic's published Storybook MCP servers expose shared component APIs, stories, usage patterns, tests, and Storybook testing context.
The implementations are related but not identical: Applitools connects the agent directly to a visual-verification service, while Chromatic primarily publishes the team's Storybook/component context so agents can build and self-correct UI against the real design system.
Which visual regression testing tool should I choose?
Choose according to the architecture you already have. Chromatic is the natural candidate for Storybook-centered teams; Percy fits organizations that want visual testing inside BrowserStack's broader browser/device ecosystem and emphasize AI-assisted review; Applitools offers particularly granular 2026 controls for dynamic-content matching, region targeting, PDF testing, and Eyes integration through MCP.
Run the same proof-of-concept defects through all shortlisted tools and compare false positives, review time, debugging quality, baseline maintenance, CI effort, and reviewer confidence rather than selecting from vendor benchmark numbers alone.
Does the Refonte Learning QA Automation Engineering Program teach Applitools, Percy, or Chromatic?
No. The published curriculum does not support that claim. The program page names established QA automation tooling including Selenium, JUnit, Jenkins, and Cucumber, while its confirmed modules include Implementing QA Automation Frameworks and CI/CD Pipeline Integration; it does not list Applitools, Percy, or Chromatic as tools taught.
The relevant benefit is foundational: once you understand how an automation framework reaches repeatable states and how its tests run in CI/CD, adding a visual-testing service becomes an integration task instead of a second testing architecture.
Conclusion
Visual regression testing and agentic test generation solve different jobs. Playwright's Test Agents plan, generate, and heal tests; visual systems inspect rendered states that functional checks can structurally miss.
The 2026 visual-testing trend is higher signal, not simply more snapshots. Applitools' Dynamic Match Level and Regions Only, Chromatic's Flake Filter, and Percy's current Intelli-ignore/Visual Review Agent workflow all attack the cost of irrelevant visual differences.
MCP is becoming a bridge between AI coding assistants and specialized UI/visual context. Applitools shipped Eyes MCP in May 2026; Chromatic published shared Storybook MCP servers in March 2026, although the two expose different kinds of context.
Tool choice follows architecture. Storybook-heavy teams have a strong reason to examine Chromatic, BrowserStack-centered teams have a strong reason to examine Percy, and teams needing fine-grained visual matching and region controls have a strong reason to examine Applitools.
A functional suite can prove that the button works; only a visual assertion can tell you that the user can still see it where the design intended. For the test-framework and CI/CD-integration foundation that any of these visual-testing tools plugs into, the Refonte Learning QA Automation Engineering Program is the structured starting point.