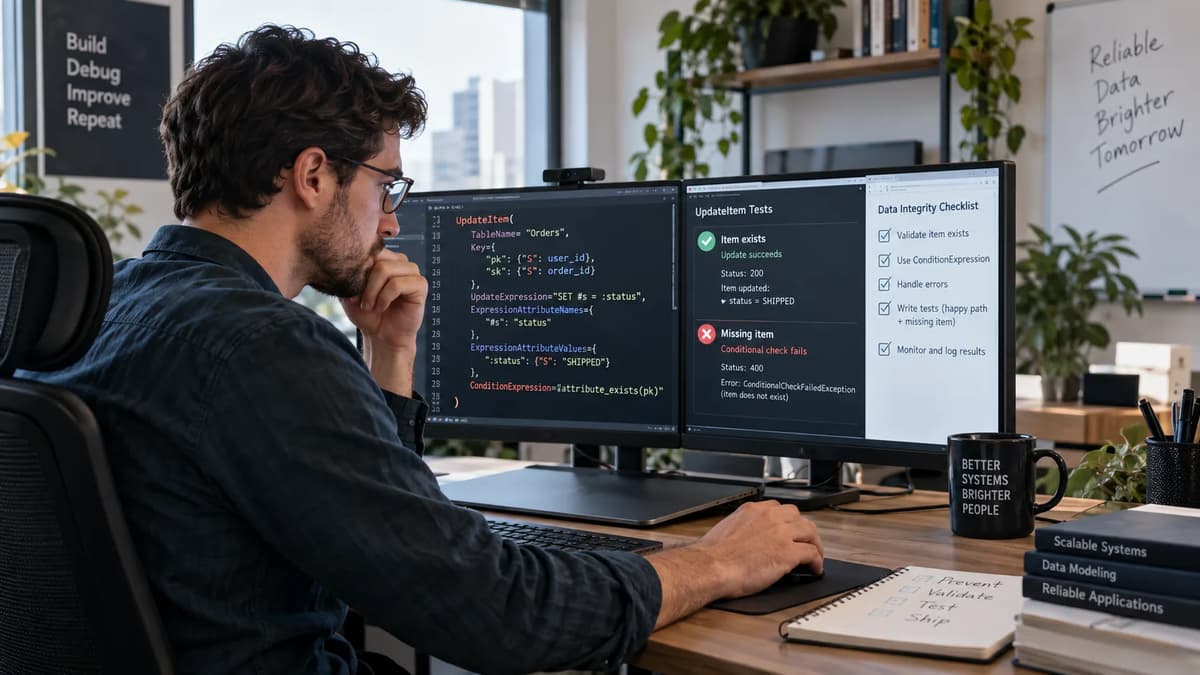
Update-only endpoints often assume the target item exists, but DynamoDB’s contract permits adding new items by default. In practice this can violate a business rule that only existing records are allowed to change.
This article examines a confined lab scenario for a single composite key, showing how an unguarded UpdateItem can insert a new item, and how to enforce the “update-only” policy. We will define an independent fixture (items E, M, Z) and run AWS CLI commands with consistent reads and condition checks. The playbook categorizes each outcome to ACCEPT, REPAIR, HOLD or RECONCILE actions based on the evidence.
We do not assume a pre-existing story or metrics; instead we build a reproducible scenario in one AWS account and Region. The code and tables given here can be copied and executed by any practitioner in a safe test setup.
No matter what a function name (like “updateStatus”) suggests, the actual DynamoDB API is not restricted to existing items unless you add a condition. We list the observed results and how they differ from the intended “update-only” contract. Throughout, we cite AWS’s documentation: for example, UpdateItem by default “adds a new item to the table if it does not already exist”, and condition expressions (on the exact key) can block such creation. After the experiments, we produce a decision table and an operational playbook for implementers.
Define what update-only means for this endpoint
At the highest level, our service-level contract is: “Changes are allowed only on the approved existing item; if the item is absent, it must remain absent.” Any UpdateItem request must therefore fail rather than create a new record when the exact key isn’t present. We separate request transport success (a valid JSON sent to AWS), service execution (DynamoDB’s processing) and business acceptance (does the result align with the intent). In this story the business rule is narrower than “no keys”, it is “no new entity for this key”.
We will gather four kinds of evidence from each test:
• Request: the JSON sent (keys, expression, values).
• Baseline: whether the target item existed just before the write (and its full attributes).
• DynamoDB response: HTTP status, returned attributes if any, or error name (e.g. ConditionalCheckFailedException).
• Post-state: an independent GetItem (with ConsistentRead=true) showing what the table contains after.
Given that evidence, each scenario can lead to a disposition: ACCEPT (write contract holds, no action needed), REPAIR (update code or caller logic), HOLD (ambiguous state requiring manual resolution), or RECONCILE (undo the unintended change before re-trying or aborting). We will define these formally in a decision matrix.
Broader database integration practices provide context, but the focus here is the precise key admission rule.
As a quick preview: if DynamoDB’s UpdateItem silently creates a new item (with only the attributes from our SET expression), that is technically successful by the API, but it fails our update-only contract. Conversely, a conditional check that stops the write is an error to the API caller, but the correct business outcome. We will need to clearly distinguish these layers of outcome.
Create an isolated table and an exact-key manifest
To test in isolation, we provision a new DynamoDB table and seed data. We enforce a single AWS account and Region with explicit names so nothing is shared or out-of-band. We show full AWS CLI commands and their expected outputs (note CLI v2, JSON format AttributeValues). We avoid any reliance on a real application’s table, or any global indexes or streams.
# Capture AWS CLI version (real-world output may vary)
aws --version
(Expected: AWS CLI version 2.x, e.g. aws-cli/2.8.0 Python/3.9....)# Use a unique table name and explicit region/account tags
export TABLE_NAME="TestUpdateOnlyLab"
export AWS_REGION="us-west-2" # replace with your chosen Region
aws configure set region $AWS_REGION
# Create the table with composite key (string pk, sk)
aws dynamodb create-table \
--table-name $TABLE_NAME \
--attribute-definitions AttributeName=pk,AttributeType=S \
AttributeName=sk,AttributeType=S \
--key-schema AttributeName=pk,KeyType=HASH AttributeName=sk,KeyType=RANGE \
--provisioned-throughput ReadCapacityUnits=1,WriteCapacityUnits=1 \
--cli-input-json file://create_table.jsonContents of create_table.json:{
"TableName": "TestUpdateOnlyLab",
"AttributeDefinitions": [
{ "AttributeName": "pk", "AttributeType": "S" },
{ "AttributeName": "sk", "AttributeType": "S" }
],
"KeySchema": [
{ "AttributeName": "pk", "KeyType": "HASH" },
{ "AttributeName": "sk", "KeyType": "RANGE" }
],
"BillingMode": "PROVISIONED",
"ProvisionedThroughput": { "ReadCapacityUnits": 1, "WriteCapacityUnits": 1 }
}After issuing the create command, we wait for the table to become ACTIVE. We capture its schema:aws dynamodb describe-table --table-name $TABLE_NAME
(Expected output: JSON showing TableStatus: ACTIVE, with key schema pk (HASH), sk (RANGE). The actual Table ARN and timestamps will appear.)
Now we seed the table with the baseline manifest. We define three conceptual items:
• E (existing): pk=TENANT#lab, sk=ITEM#present; with non-key attributes generation=G1, status=PENDING, owner=approved.
• M (missing target): pk=TENANT#lab, sk=ITEM#missing; absent. It shares pk with E but does not exist yet.
• Z (other partition): pk=TENANT#empty, sk=ITEM#missing; absent. Different partition.
These represent the universe of our test: only E truly exists with full data, M and Z do not. A handy reference is:
Item | pk | sk | generation | status | owner |
E | TENANT#lab | ITEM#present | G1 | PENDING | approved |
M | TENANT#lab | ITEM#missing | absent | absent | absent |
Z | TENANT#empty | ITEM#missing | absent | absent | absent |
E is the only one present with all fields. M and Z should remain empty unless a write creates them.
We load E with a PutItem (the CLI requires AttributeValues in JSON):
aws dynamodb put-item \
    --table-name $TABLE_NAME \
    --item file://item_E.json
Contents of item_E.json:{
"pk": {"S": "TENANT#lab"},
"sk": {"S": "ITEM#present"},
"generation": {"S": "G1"},
"status": {"S": "PENDING"},
"owner": {"S": "approved"}
}(Expected: an empty JSON ({}), indicating success.)
We do not put M or Z (they remain absent).
This precise setup follows isolation principles in cloud-native pipeline design, ensuring no shared state.
Keep composite keys and expected attributes explicit
We reiterate the fixture by showing E, M, Z. Their full expected key values and the approved attributes for E are listed above. Emphasizing the composite key: E and M share the same partition key (TENANT#lab). The condition attribute_exists(pk) is logically tied to both parts of the key together. We do not allow any global or partial lookups; each operation is per item key.
This manifest table is our “oracle”: after any write, we will check that E has exactly the approved fields (though status may change to REVIEWED), and that M and Z remain absent unless and until we explicitly reconcile them.
Record the baseline without turning a read into a lock
Before each write test, we verify the baseline state. We fetch each key with a consistent read (to avoid eventual consistency) but without any locking or transaction. This ensures we have evidence of what was in the table at that time. An empty Item: null indicates no record (which is the normal result for a missing item, not an error).
Commands:
aws dynamodb get-item \
    --table-name $TABLE_NAME \
    --key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}' \
    --consistent-read
(Expected: returns E’s full attributes: generation=G1, status=PENDING, owner=approved.)aws dynamodb get-item \
--table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#missing"}}' \
--consistent-read(Expected: returns no Item, since M is absent.)aws dynamodb get-item \
--table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#empty"},"sk":{"S":"ITEM#missing"}}' \
--consistent-read(Expected: returns no Item, Z is absent.)We do not treat an absent item as an API error; it’s a valid state per the service. We note these “no item” results as normal.
Note: This pre-read is evidence, not a lock. DynamoDB does not reserve that key just because we read it. A later write can still add or change the item. Thus, a request’s success cannot rely on a prior read beyond race controls we explicitly insert.
Having confirmed E exists and M, Z are absent, we proceed to the update tests. The next section covers the unguarded attempt using the provided SET request on M.
Let the unguarded request expose the unwanted creation
We now execute the original UpdateItem request (JSON given above) against M (TENANT#lab, ITEM#missing) without any condition expression. According to AWS’s API and the AWS CLI command reference, this should succeed and create item M if it was missing. Our request:
{
  "TableName": "TABLE_NAME",
  "Key": {"pk": {"S": "TENANT#lab"}, "sk": {"S": "ITEM#missing"}},
  "UpdateExpression": "SET #status = :reviewed",
  "ExpressionAttributeNames": {"#status": "status"},
  "ExpressionAttributeValues": {":reviewed": {"S": "REVIEWED"}},
  "ReturnValues": "ALL_NEW"
}
We run it (using the actual table name via shell substitution):
aws dynamodb update-item --cli-input-json file://update_M_unconditional.json
Contents of update_M_unconditional.json (with TABLE_NAME replaced):
{
  "TableName": "TestUpdateOnlyLab",
  "Key": {"pk": {"S": "TENANT#lab"}, "sk": {"S": "ITEM#missing"}},
  "UpdateExpression": "SET #status = :reviewed",
  "ExpressionAttributeNames": {"#status": "status"},
  "ExpressionAttributeValues": {":reviewed": {"S": "REVIEWED"}},
  "ReturnValues": "ALL_NEW"
}
Expected CLI outcome: HTTP 200, with JSON containing the new item’s attributes (since ReturnValues=ALL_NEW). Because the item did not exist, AWS will create it with only the specified attribute. The returned item will have:
{
  "Attributes": {
    "pk": {"S": "TENANT#lab"},
    "sk": {"S": "ITEM#missing"},
    "status": {"S": "REVIEWED"}
  }
}
Notice generation and owner are missing, because we only set status. We consider this a successful DynamoDB write, but it violates our intended contract (we “allowed” creation without the required fields).
To be thorough, we then do:
aws dynamodb get-item --table-name $TABLE_NAME \
    --key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#missing"}}' --consistent-read
(Expected after Update: returns M’s item with status=REVIEWED, no generation/owner.)We also re-check E to ensure it was untouched:aws dynamodb get-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}' --consistent-read(Expected: still generation=G1, status=PENDING, owner=approved.)
Outcome: The service performed the write (HTTP 200, ALLOW). The returned data confirms only the SET attribute is present. Business acceptance fails: M was created when it should not have been, and E is correct.
This is a textbook example of the API adding an absent item on UpdateItem. It shows an unguarded update can silently create an item, breaking the update-only rule.
Do not confuse if_not_exists with write admission
As a control, we try a different update expression on a fresh reset: use if_not_exists in the SET clause, but still no condition. The idea is to see if that function acts like an “exists check” (it does not).
Reset state: delete the M we just created (if it exists):
aws dynamodb delete-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#missing"}}'
(Expected: {})
Now run:
aws dynamodb update-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#missing"}}' \
--update-expression "SET #status = if_not_exists(#status, :reviewed)" \
--expression-attribute-names '{"#status":"status"}' \
--expression-attribute-values '{":reviewed":{"S":"REVIEWED"}}' \
--return-values ALL_NEW
We expect the same behavior: because M doesn’t exist, the update will create M and then apply SET with if_not_exists. The function if_not_exists(status,:reviewed) sees that status does not exist, so it uses the fallback:reviewed. The end result: item M is created with status=REVIEWED.
(Expected Return: Attributes with pk,sk and status=REVIEWED; generation/owner still missing.)
This proves that if_not_exists is not a guard against creation. It only prevents overwriting an existing attribute. The creation of M means we cannot use this as an “exists check”.
We capture this as a negative control: the update-expression fallback is not equivalent to a condition expression on item existence. In a deployed system, relying on if_not_exists in UpdateExpression does not enforce “item must exist”.
Put the existence predicate in the UpdateItem request
To enforce “no creation if missing”, we must use a ConditionExpression. The condition will explicitly check for the item’s existence by its key. One way is:
ConditionExpression: "attribute_exists(#pk) AND attribute_exists(#sk)"
with aliases #pk=pk, #sk=sk. This tests that both key attributes exist in the item, which for a composite key means an item with that exact key is present. Writing both ensures our intent is clear (note: DynamoDB inherently evaluates against the same item defined by both key values).
Our repaired JSON (for table name TestUpdateOnlyLab):
{
"TableName": "TestUpdateOnlyLab",
"Key": {"pk": {"S": "TENANT#lab"}, "sk": {"S": "ITEM#present"}},
"UpdateExpression": "SET #status = :reviewed",
"ExpressionAttributeNames": {"#pk":"pk", "#sk":"sk", "#status":"status"},
"ExpressionAttributeValues": {":reviewed": {"S": "REVIEWED"}},
"ConditionExpression": "attribute_exists(#pk) AND attribute_exists(#sk)",
"ReturnValues": "ALL_NEW"
}
And the analogous JSON for M or Z (changing the Key accordingly). We invoke it via CLI:
aws dynamodb update-item --cli-input-json file://update_E_condition.json
(Case: Target E)
• E exists: The condition attribute_exists(pk) AND attribute_exists(sk) should be true. DynamoDB locates E by that exact key and sees both pk and sk attributes (the item exists). It then applies the SET #status =:reviewed.
Expected outcome: HTTP 200, returning E’s new state. Now E’s status should become REVIEWED. The attributes returned (ALL_NEW) should show generation=G1, status=REVIEWED, owner=approved (others unchanged).
After running, we do:
aws dynamodb get-item --table-name $TABLE_NAME \
    --key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}' --consistent-read
(Expected: E with status=REVIEWED, generation=G1, owner=approved.)
• M or Z (absent): The same request but with Key for M (TENANT#lab, ITEM#missing) or Z (TENANT#empty, ITEM#missing) has no item. DynamoDB evaluates the condition on the (nonexistent) item. Since there is no item, attribute_exists(pk) is false (no record means attributes are not there). The ConditionExpression fails, and the service will reject the write with a ConditionalCheckFailedException (HTTP 400 error). No item is created.
So for M-targeted request:
aws dynamodb update-item --cli-input-json file://update_M_condition.json
We expect a ConditionalCheckFailedException. For Z-targeted:
aws dynamodb update-item --cli-input-json file://update_Z_condition.json
Also a conditional fail.
The returned values on failure do not include attributes; instead AWS CLI should show an error message. We should capture the exact error name (e.g. in bash it might be visible as An error occurred (ConditionalCheckFailedException)). Regardless, the key point is: no changes. Then we do a GetItem for M and Z to reconfirm they are still absent.
This demonstrates enforcing existence at write-time. We reiterate: using a condition expression checks the exact composite-key item, not the partition as a whole. Checking attribute_exists(pk) alone implies the same two-key combo because the request’s Key includes both pk and sk.
This careful condition fits into robust backend CRUD foundations where API validation complements service constraints.
Prove rejection at both kinds of missing key
We already saw M (missing key, same partition as E) vs Z (missing key, different partition). Both should behave identically under the ConditionExpression. To be thorough:
1. M (with neighbor E present): Condition attribute_exists(#pk) AND attribute_exists(#sk) is evaluated. E’s presence in the same partition has no effect, because DynamoDB uses both pk and sk to identify the item. For M’s key, both attributes are missing, so the condition fails. We capture E remains unchanged, M remains absent, and AWS returns a ConditionalCheckFailedException.
2. Z (completely separate partition): For Z’s key, again the item is missing. The fact that E (with a different pk) exists is irrelevant. The condition fails again. We observe Z remains absent, no new item, and a ConditionalCheckFailedException error.
For example:
# Case: M with condition (E exists in the same partition)
aws dynamodb update-item \
    --cli-input-json file://update_M_condition.json 2>&1 | tee result_M_cond.txt
(Expected: output contains "ConditionalCheckFailedException", and HTTP status 400 in non-JSON CLI error mode.)# Verify no creation of M:
aws dynamodb get-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#missing"}}' --consistent-read(Expected: no Item.)# Case: Z with condition
aws dynamodb update-item \
--cli-input-json file://update_Z_condition.json 2>&1 | tee result_Z_cond.txt(Expected: ConditionalCheckFailedException.)# Verify Z still absent:
aws dynamodb get-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#empty"},"sk":{"S":"ITEM#missing"}}' --consistent-read(Expected: no Item.)We record that the service errors are distinct from, say, table-not-found or permission errors. A ConditionalCheckFailedException specifically means “condition expression evaluated to false”. It is an application-level rejection, not a technical failure. If other errors occur (like network timeouts, missing table, etc.), those would fall under “operational failure” and get a different verdict (see next section).
HOLD vs REPAIR: A condition failure here means “the write was rejected as intended.” The contract (existing-only) is upheld. We interpret these as ACCEPT the application’s adherence, not as a bug needing fix. The application tried to update M when it should not; now it got a clear signal. Conversely, the unguarded creation (earlier) was not flagged by AWS, so that path needs REPAIR (to avoid creation).
Separate conditional rejection from an operational failure
We emphasize that a ConditionalCheckFailedException is a business-level rejection. It means “we didn’t perform the write because your condition said not to.” It is not the same as access denied, resource not found, or timeout. For example:
• AccessDenied: would mean AWS credentials or IAM misconfiguration (server refused).
• ResourceNotFoundException: table name wrong.
• ThrottlingException: too many requests.
• ValidationException: malformed expression syntax.
Only the ConditionalCheck exception tells us “your condition failed (the item isn’t there)”. A transport-level or authentication failure would leave us uncertain of state (HOLD until we can reconcile). In contrast, the conditional reject is safe: we know exactly the write did not happen, so E, M, Z remain as before.
The ledger (see below) will classify these differently.
Schedule a deletion between the read and the update
Next, we simulate a race: suppose an operator reads E, then E is deleted by some event, then our update runs. No concurrent locks happen automatically; we enforce sequence by separate calls. This tests that a pre-read cannot survive an intervening deletion.
Procedure:
1. Ensure E exists with generation=G1, PENDING.
2. Run a GetItem for E (to simulate the previous read).
3. Immediately delete E.
4. Now run the unguarded update on E (with no condition).
We already did steps 1–3 via CLI:
# 1. (Already E exists)
# 2. Get E
aws dynamodb get-item --table-name $TABLE_NAME \
    --key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}' --consistent-read

# 3. Delete E
aws dynamodb delete-item --table-name $TABLE_NAME \
    --key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}'

# Confirm deletion:
aws dynamodb get-item --table-name $TABLE_NAME \
    --key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}' --consistent-read
(Expected after deletion: no Item for E.)Now 4. Run update on E (unguarded):aws dynamodb update-item --cli-input-json file://update_E_unconditional.json(update_E_unconditional.json is similar to M but for E’s key.)Expected: Since E was deleted, the unguarded update should recreate it! The result: new item at E’s key with status=REVIEWED, but now generation and owner are missing. Just like the M case, we created an incomplete E object.(Expected return Attributes: pk,sk,status=REVIEWED.)Then:aws dynamodb get-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}' --consistent-read(Expected: E exists but without its original generation/owner.)Then we reset for the conditional test:# Delete E again to restore baseline:
aws dynamodb delete-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}'
# Now try update E with condition (after deletion)
aws dynamodb update-item \
--cli-input-json file://update_E_condition.json 2>&1 | tee result_E_delete_cond.txtFor the conditional case after delete, the condition fails, so E remains absent.
This confirms:
• Unguarded: deletion + update = recreation (contract broken).
• Guarded: deletion + update = rejection (contract held, albeit E lost).
Even a “strong pre-read” (GET) does not guard the item; DynamoDB is eventually consistent across operations and separate calls.
State the limits of an existence-only predicate
We’ve now enforced existence of some item at the key, but is that enough to guarantee we’re updating the same logical entity? In many applications, items have versions or tenant ownership. For example, E had generation=G1. If someone deletes E and re-creates it with G2, an existence check will pass, but it’s not the same item.
We test one variant: suppose we reset the table, then put E as before with generation=G1. Then for "parallel evolution", we delete E and re-create it manually with generation=G2 (approved owner, status REVIEWED), outside the normal update path. Now our contract might say “only update the G1 item”, but a condition that only checks existence will allow this silent replacement to bypass a real check on identity.
Procedure:
1. Reset baseline: Put E with generation=G1, PENDING again.
2. Simulate a change of incarnation: Delete E.
3. Put a replacement item E2 with generation=G2, status=REVIEWED, owner=approved (we do a PutItem or UpdateItem all in one shot).
4. Now attempt an update on E with a condition on existence only.
Commands:
# 1. Restore E G1,PENDING
aws dynamodb put-item --table-name $TABLE_NAME --item file://item_E.json

# 2. Delete E G1
aws dynamodb delete-item --table-name $TABLE_NAME \
    --key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#present"}}'

# 3. Put E G2,approved,REVIEWED
aws dynamodb put-item --table-name $TABLE_NAME --item file://item_E_G2.json
Contents of item_E_G2.json:{
"pk": {"S": "TENANT#lab"},
"sk": {"S": "ITEM#present"},
"generation": {"S": "G2"},
"status": {"S": "REVIEWED"},
"owner": {"S": "approved"}
}(Expected: success.)
Now 4. Run the conditional update on E (original Key, set status=REVIEWED again, condition as before):
aws dynamodb update-item \
--cli-input-json file://update_E_condition.json --return-values ALL_NEW
Expected: Because an item now exists at E’s key (the G2 item), the condition passes. The update sets status to REVIEWED (it was already REVIEWED in E2, so no change). The result will return the item with generation=G2.
The contract intended “only update the generation G1 item”, but we lost G1 already. All we tested was existence.
Key lesson: Checking existence alone cannot validate the identity or version of the item. A stronger condition (e.g. generation =:oldgen) would be needed if that was a requirement. Without it, an update may apply to a different incarnation.
This underscores that an existence gate is a minimal protection in API security and observability, but further identity checks (optimistic locking, ownership validation) require separate contracts.
Do not silently promote presence into identity
If the business context required “only the same entity (generation G1) is modifiable”, then ConditionExpression: "attribute_exists(pk) AND generation =:g1" (or using attribute_exists(#generation) with value check) might be needed. However, that moves beyond the literal “existence” policy into identity/version binding. In many systems that’s done via separate fields or context (e.g. if-match etags).
We avoid giving a generic “fix-all” solution here. The point is: existence condition does not imply that presence = correct item. If G1-vs-G2 matters, a different contract (and condition) is necessary.
Likewise, authorization is out of scope here: whether the caller is “owner=approved” or not. We could add a check like owner =:approvedUser, but that’s another rule. For now, we simply note that attribute_exists is a necessary but not sufficient predicate for richer semantics. It only enforces that “some item” is present at the key.
Thus, an unexpected creation of a new G2 record should trigger a RECONCILE or an ACL review, not a code fix.
Capture a mutation ledger that can be independently checked
For operational rigor, we define a ledger format to record each test case in structured form. This ledger can be a table (or JSON) showing for each step: the request details, the observed status, and the verdict. The idea is to automate or at least clearly log what happened, so that reviewers can verify independently.
The example ledger records the following fields:
Case | Key (pk,sk) | Baseline state | Condition | Request aliases / values | Response (HTTP / error name) | Returned attributes | Post-read attributes | Disposition |
1 | E (TENANT#lab, | gen=G1, | none | status=REVIEWED | 200 OK | gen=G1, | same | ACCEPT (status changed as expected) |
2 | M (TENANT#lab, | none (absent) | none | status=REVIEWED | 200 OK (item created) | pk, sk, | pk, sk, | REPAIR (violation: created) |
3 | M (TENANT#lab, | none | cond attr_exists(pk) & attr_exists(sk) | status=REVIEWED | 400 (ConditionalCheckFailedException) | N/A | none | ACCEPT (write rejected as intended) |
4 | Z (TENANT#empty, | none | cond same | status=REVIEWED | 400 (ConditionalCheckFailedException) | N/A | none | ACCEPT |
5 | E (then delete) | E deleted after read | none | status=REVIEWED | 200 OK (E re-created) | pk, sk, | pk, sk, | REPAIR |
6 | E (then delete) | E deleted | cond exists(pk) & exists(sk) | status=REVIEWED | 400 (ConditionalCheckFailedException) | N/A | none | ACCEPT |
7 | E (new G2) | gen=G2 exists | cond exists(pk) & exists(sk) | status=REVIEWED | 200 OK | gen=G2, | same | HOLD (entity replaced) |
For brevity, only key fields are shown here.
Each row ties a case ID to its key, baseline, request specifics, observed HTTP code or error (for CLI invocations, capturing 2>&1 | tee outputs is useful), the returned attributes (if any), and the post-operation read. The final column is our disposition: did this pass (ACCEPT) or fail the contract, etc.
We make sure to keep transport errors separate: if a request fails due to timeout or permission, we mark the outcome HOLD because we can’t trust the state. In our experiments, ConditionalCheck rejections are not a HOLD; they are expected (and cause ACCEPT or HOLD in a specific way as defined below).
This ledger is meant to be machine-parseable. In practice, one could implement it in a test harness (e.g. using Python or shell scripts) to automatically verify the fields. The table above is illustrative; an actual script might output JSON lines.
Important: Without this rigorous ledger, one might just eyeball counts or error codes. We insist on a complete mapping: which specific keys exist with which attributes, to prove the contract.
Reconcile the unwanted item before making another write
In a production incident where an update created an unwanted item (as in Case 2 above), the first step is to acknowledge and isolate that item. Since our fixture defined what M should have been, we can detect that M has appeared unexpectedly. We must then decide what to do with it.
The key is: do not just delete or patch items without a record of approval. In our lab, M’s only attributes are status=REVIEWED; it lacks the generation and owner needed to integrate it correctly. Simply deleting M could break audit trails.
The standard procedure would be:
1. Flag the item as “unintended”. For example, add a tag attribute (if our schema allowed it), or move the item to a quarantine table.
2. Ask the data owner or reviewer: Was this creation a false positive, and should the item be merged or removed?
3. If removal is decided, do so as a separate, consented operation. Possibly log the old state somewhere first.
4. If correction is decided, then ensure the correct fields (e.g. generation, owner) are populated, and record why (maybe an update with a fix conditional on someone’s approval).
In our lab, we can simply delete M after capturing its attributes. For example:
# Capture unintended M
aws dynamodb get-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#missing"}}' \
> unintended_M_before.json
(Inspect the saved unintended_M_before.json: it should contain only pk,sk,status.)
# Delete M as a cleanup (in real life, only after approval)
aws dynamodb delete-item --table-name $TABLE_NAME \
--key '{"pk":{"S":"TENANT#lab"},"sk":{"S":"ITEM#missing"}}'
(Expected: success.)
At this point, the table is back to the baseline. The existence of unintended_M_before.json in logs or version control serves as evidence of the anomaly.
This shows that old data wasn’t preserved by the faulty write path; an unintended creation must be treated as a partial transaction. The recommended fix is to stop using the faulty update call and use the conditional version before retrying any writes.
Bind corrective action to reviewed state
If the new item had valuable data that someone had entered (unlike our synthetic example where only status was set), we might attempt to salvage it. But even then, the correct workflow is to hold that data offline and get explicit approval from the data owner or stakeholder before merging. For example, a process could be: “the item M is now in a quarantine table, flagged as creation by error. A data steward reviews it, sets approvedToMerge: true if valid, then a separate reconciler job moves it into the live table with whatever fixes needed.”
Under no circumstances should a generic loop blindly issue a delete for “all items missing attribute X”. That could remove legitimate new items. We must tie cleanup to a known issue.
In summary, reconciliation here is a data-process step, not an automated code change. Once resolved, the team can be confident to retry any pending operations. The playbook items are: “identify the unintended item (artifact), review by domain owner (accountable party), then delete or correct (approved action).”
Make the matrix executable rather than relying on manual inspection
All the above steps should ideally be scripted. That way, the exact JSON files, command invocations, and expected checks can be run repeatedly (e.g. via a CI test or a local script). A reusable test harness ensures that each scenario’s state is reliably reset and validated.
Key points for automation:
• Reset: Before each case, clear M or E as needed (delete keys).
• Requests: Use a tool (shell script, Python, etc.) to send the JSON to AWS.
• Capture outputs: Save the response, exit code, and error message. CLI’s --output json can be piped to files.
• GetItem verification: After each write, run GetItem and parse that JSON.
• Assert: Compare the actual table state to expected (e.g. using jq or test assertions).
• Positive control: Include a known-success case (like updating E with no condition when E exists) to ensure the condition logic is applied correctly.
One could, for instance, write a small Python script using subprocess to run each AWS CLI command and check outcomes. Or use the AWS SDK (Boto3) to do the same with typed calls. The important thing is that we do not rely on eyeballing one run.
Without automation, errors in quoting or ordering can creep in. An executable matrix spells out the exact sequence:
1. Seed E.
2. Update M unguarded and check the expected FAIL (REPAIR scenario).
3. Reset M before the next case.
4. Update M with the condition and check PASS (ACCEPT).
We should also check the earlier state each time (so no dependencies bleed). This is essentially integration testing of the contract.
Remember: The harness should not assume success of AWS; any exception should trigger a HANDOFF to a HOLD state. We should clearly mark which failures are due to test logic versus actual AWS behavior.
Use a decision table for the narrowly tested contract
After running all cases, we condense the results into a decision table for acceptance/rejection. The table will cover:
• Key exists? (Yes/No)
• Pre-read sees item? (Yes/No)
• Condition used? (Yes/No)
• Update attempt (Yes/No, basically always yes but condition may block)
• Service result (OK/ConditionalFail)
• Final table state (Item updated, created, or unchanged)
• Verdict (ACCEPT, REPAIR, HOLD, RECONCILE)
For example:
Scenario | Key exists? | Condition? | AWS Result | Final State (E) | Final State (M) | Verdict |
1. Unguarded Update E (init) | Yes | No | 200 OK (updates status) | E updated | M still absent | ACCEPT (ok) |
2. Unguarded Update M | No | No | 200 OK (creates M) | E untouched | M created (status only) | REPAIR (bug) |
3. Guarded Update M (E exists) | No | Yes | 400 CondCheckFailed | E untouched | M absent | ACCEPT (ok) |
4. Guarded Update Z | No | Yes | 400 CondCheckFailed | – | – | ACCEPT |
5. Delete then Unguarded E | No (deleted) | No | 200 OK (recreates E) | E recreated (gen missing) | – | REPAIR |
6. Delete then Guarded E | No (deleted) | Yes | 400 CondCheckFailed | E absent | – | ACCEPT |
7. Existence-only (G2) | Yes (G2) | Yes | 200 OK (updates status) | E(G2) stays | – | HOLD (ambiguous) |
Here the verdict rules are:
• ACCEPT when the behavior aligns with update-only: either the item was updated as intended (E existed, updated; or write was correctly blocked on missing), and no unintended creations occurred.
• REPAIR when a service call succeeded but violated the policy (e.g. item created); we must fix the code.
• HOLD for ambiguous states (e.g. entity changed identity) requiring human input.
• RECONCILE is invoked not as a verdict for a single operation, but as a post-detection step; it could appear as a column or footnote (“resolve item M via data workflow”).
We then label each case’s outcome with the verdict. Note that for rule-blind requests (without condition), we regard the API success as expected by API but undesired for business, hence REPAIR. For condition-blocked, we regard the failed write as desired business outcome, hence ACCEPT (the caller must then handle that as an error case).
This succinctly answers the core question: Should the caller be allowed to proceed or not? If the table changed in a disallowed way, the outcome is REPAIR or RECONCILE, meaning do not blindly accept the change. If the table state is correct, and the caller sees an error, we ACCEPT that path (the caller must retry or abort).
Separate ACCEPT, REPAIR, HOLD and RECONCILE
For clarity:
• ACCEPT: The operation adhered to the “update-only” contract. This can mean either a successful update of an existing item, or a controlled failure preventing creation when missing. E.g. Case 1 (E updated) and Case 3 (M blocked) are ACCEPT. The code as written may succeed or throw, but ultimately the invariant holds (no new unwanted data). The next action is: no immediate code change needed, but the caller should properly handle the ConditionalCheck exception.
• REPAIR: The operation violated the contract by creating or modifying data it should not. This requires code changes or improved caller logic. E.g. Case 2 (created M) and Case 5 (recreated E) are REPAIR. The fix is to apply the existence condition or equivalent. The next action is to patch the UpdateItem calls or business logic.
• HOLD: The outcome is uncertain or requires human decision. Example: Case 7, where the existing item may not be the original generation. We “hold” further automation or retry until domain logic confirms which entity is intended. The record might need reconciliation.
• RECONCILE: This is a data-curation step, not exactly a verdict on the operation. It says “find the unintended item(s) and fix them before continuing.” It’s triggered whenever an unintended creation has been detected (cases leading to REPAIR will require RECONCILE before retry).
Each verdict has an associated role. Code maintainers will handle REPAIR items (change API logic). Data stewards will handle RECONCILE cases. Operations/QA handle HOLD cases (often investigating logs or guarding retries).
Assign rollout and recovery ownership
This section outlines who does what after we have the verdicts:
• API/Service Owner (Dev team): Responsible for patching the update endpoint code. They must deploy a new version of the client (or microservice) that adds the condition expression. They should also handle the exception thrown in the API client, for instance, returning HTTP 409 Conflict to the end-user if update fails due to missing item. They version-control the request-builder and condition (for example, in Terraform or CDK), and ensure the new contract is clearly documented. After changes, they should re-run the full test matrix to verify the fix.
• Data Owner (Business/domain expert): Oversees the semantics of the records. If an item was unintentionally created, they decide whether it should be kept, modified, or deleted. They may hold approval for any RECONCILE actions. For example, they might say “This ITEM#missing with status=REVIEWED is valid for lab XY, please merge it into the pipeline” or “No, it’s spam, delete it.” The data owner is also responsible for specifying if any additional conditions were needed (e.g. generation matching).
• Cloud Operator (Infra/Ops team): Monitors the AWS environment. They should tag or log the existence of ConditionalCheckFailedExceptions from this service as a normal event (or as an incident if unexpected). They ensure CloudWatch alarms or logs are in place so that if a sudden spike in missing-key rejections occurs, it’s visible. They own the rollback plan if needed (for example, if the new condition causes too many failures, they can roll back the service and raise an alert).
Additionally, we describe a rollback plan: if after deploying the condition check, some updates now fail that were previously allowed, we have to be careful. The rollback should disable the condition and may require manual backfill. After changes to keys or schema (e.g. adding fields), we should repeat the entire matrix because new code or data shapes could change the outcomes.
Throughout the process, evidence is preserved: request and response logs should be kept (with sensitive info redacted). The unreachable or timed-out outcomes should also be audited; any HOLD or unknown must be logged for later cleanup.
These practices tie into database automation and recovery discipline, where roles and workflows ensure data integrity.
Build the cloud foundations behind safer mutation reviews
In conclusion, this exercise not only tightens one API endpoint, but connects to broader cloud engineering best practices. A systematic lab like this aligns with the principles of the Cloud Development Program: using real AWS services in a controlled environment, automating checks, versioning infrastructure, and fostering collaboration between developers, data experts, and ops.
Our operational playbook is a blueprint for any team facing unintended data mutations. By combining consistent testing fixtures, explicit condition logic that is distinct from update-expression behavior, and a clear owner-driven decision matrix, we ensure that “update-only” truly means update-only. Cloud-native tools (CLI, IAM, monitoring) underpin this confidence. For engineers seeking to build these skills systematically, from writing safe update code to owning the rollout, programs like Cloud Development Program offer structured learning on AWS, CI/CD, security, and DevOps that reinforce these findings.
With disciplined automation and accountability, an organization can adopt the repaired UpdateItem contract safely. The final verdict: ACCEPT the update-only design in principle, but REPAIR by adding the existence check in every UpdateItem call and by refining any additional logical conditions as needed. Unintended creations are flagged for RECONCILE under review, and any uncertain states are held until clarified. The technology (DynamoDB) provides the primitives (ReturnValues, attribute_exists) to enforce this contract; it’s on the team to apply them and manage the outcomes.