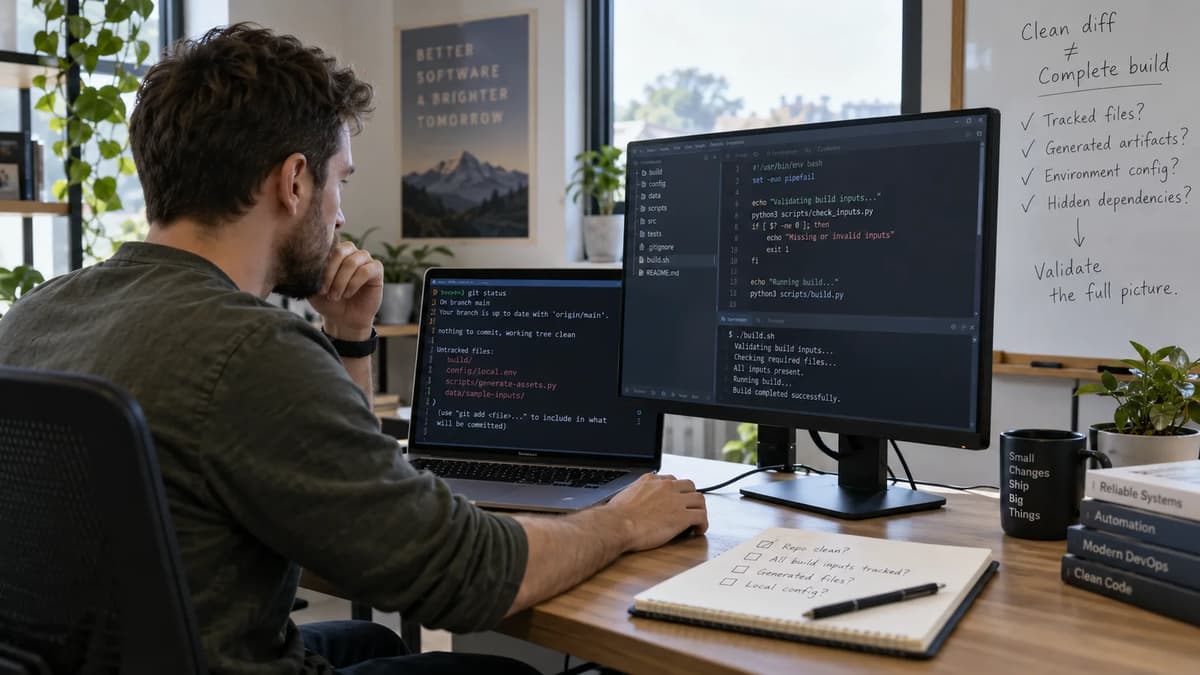
A release or continuous-integration script that relies on git diff --exit-code to ensure a clean working tree can be dangerously misleading. In practice, Git’s various modes of diff and status cover only some populations of files, not all possible build inputs. A working-tree change that is staged, an untracked file, or an ignored build input can slip past a “green diff” check even though downstream build tools might still see and use those files.
In this playbook we establish an explicit “no unapproved local inputs” policy for a simple repository and test it exhaustively. We create a fresh disposable Git repo (Git 2.47.3, CPython 3.13.5) with one committed file and an ignore rule (.gitignore ignores the scratch/ directory). From this baseline we try five cases: clean, modified-but-not-staged, modified-and-staged, an untracked file with a newline in its name, and an ignored scratch/input.txt. We capture exact bytes from git diff, git diff HEAD, git status --porcelain=v1 -z --untracked-files=all, and git ls-files --others --ignored --exclude-standard -z. A conservative gate will ACCEPT only if both status and ignored inventories are empty. Each test is inspected and labeled ACCEPT or HOLD.
A key result: only the fully clean case passes. The staged change yields a “diff 0” by default (green) yet fails diff HEAD. Untracked or ignored files yield green diffs but appear in status or ls-files. We learn that an empty diff exit code is meaningful only for the specific tree comparison it did; it does not imply “no extra inputs.” After the tests, we define how to accept or repair the release gate. We reject unsafe operations, never deleting work automatically. Instead we require owners to approve or remove untracked/ignored files, rebuild artifacts under the corrected input boundary, and compare outputs. In the end we present an Accept/Repair/Hold/Rebuild decision procedure to handle every case.
Throughout, we cite the Git manuals for documented git diff, git status and git ls-files behavior and emphasize evidence from our controlled fixture. This is not a Git tutorial or CI platform review, but a proven-by-experiment audit of what git diff actually checks. We also show how this fits into broader DevOps source-provenance practices.
Declare the repository inputs a release is allowed to use
Before any build, we must define what files are considered part of the source inputs. A commit ID names exactly the committed files in that tree; nothing more. Untracked files (new files not in Git) and ignored files (per .gitignore) are outside that definition unless explicitly approved. We treat all working-tree files not in the commit as “unapproved local inputs.” That is a policy decision, not a property proven by a diff command. For our example, the policy is “only the tracked files committed in HEAD are allowed inputs; no other files (including ignored build caches) may be read by the build.”
Any build or generator that runs on this tree should only see the committed files. (Compare general Git guides on staging, committing and ignore rules.) In practice, this means:
• Tracked content: files in Git’s index or HEAD commit are allowed; changes to them must be committed before release.
• Untracked files: by default, any new file in the working tree that isn’t committed is disallowed. For example, if a developer has an editor backup file or test input in the workspace, it should not influence the build if we’re locking down the inputs.
• Ignored files: files matching .gitignore are also disallowed unless an explicit policy says “cache X is OK.” The .gitignore by itself only hides those files from status; it does not make them part of a safe boundary. (Ignore rules affect what Git considers untracked, but an ignored file can still be read by a build and thus break reproducibility.)
• Configuration/environment: we assume no environment variables or external dependencies. Those are separate concerns (must be managed in manifests too).
This list shows what is allowed and disallowed for our tiny repo:
• Allowed: tracked.txt (because it’s added and committed).
• Disallowed: any modified-but-not-committed copy of tracked.txt; any other untracked file; anything in scratch/ (because .gitignore ignores scratch/).
Releases should hold (fail) if any disallowed input is present. Merely seeing a “clean diff” is not enough. We will conservatively disallow all ignored/untracked files. (A more nuanced policy might permit certain ignored build caches or generated files; in that case the allowlist must be explicitly documented by the build owner.)
For more on how Git’s staging and ignore work as a foundation, see Git staging and version-control foundations. But our goal here is not teaching Git, but auditing what the tools actually do. We take this policy as an a priori contract: the release script must verify that the current checkout has exactly the intended committed files and nothing else. The rest of this article proves that a simple git diff is insufficient, and shows how to enforce the policy with additional checks.
Create a disposable repository and record its boundaries
We now build our test setup in a clean environment. In a temporary directory, we initialize a new Git repo with no prior history or remotes. We isolate the user HOME and disable any system or user config to remove surprises. The commands are:
# Set up isolated environment (HOME, no system Git config)
git init -q # initialize empty repo
git config user.name "Local fixture"
git config user.email "[email protected]"
git config commit.gpgsign false
Then we add our baseline content. The .gitignore file contains:
scratch/
This ignores the scratch/ directory. We also create tracked.txt with some content:
echo "baseline" > tracked.txt
git add .gitignore tracked.txt
git commit -qm "fixture baseline"
At this point the repository root is at a fresh commit. We record:
• Git version: e.g. git version 2.47.3.
• HEAD commit ID: from git rev-parse HEAD. (This is the fingerprint of our allowed inputs.)
• Repository root path: for reference, although in CI one would know this environment’s directory.
All tests in this article assume exactly this starting commit. (No remote sync, no further branch creation.)
Hold unsupported repository features before testing cleanliness
We deliberately keep the scenario simple. A general clean-status check does not guarantee absence of many complex states. We state these explicitly as unsupported or out of scope for the gate:
• Submodules: if any submodules existed, by default git diff ignores their contents (ignore-submodules=all). A modified file inside a submodule could be hidden by a default diff, so we disallow submodules or require separate submodule checks.
• Nested repositories: a Git repository inside another repository’s directory breaks status logic. Our status does not traverse nested .git dirs.
• Sparse checkout: if the index only tracks part of the working tree, git status may not list everything. We do not simulate sparse scenarios.
• Git LFS or filters: Large-file storage objects or smudge/clean filters are not considered. A file that is “present” but stored outside index might fool ls-files.
• Assume-unchanged/skip-worktree flags: These can hide changes from status. Our test repo has none set. In general, if a file is marked assume-unchanged, Git may skip checking it; such cases would need separate preflight before trusting a “clean” status.
• Concurrent git operations: We assume no simultaneous processes are writing to the repo during our checks.
• External outputs: Our procedure only looks at Git-tracked/ignored files. Any files created by build tools not under version control (e.g., files downloaded during build) would require their own manifest or validation.
In practice, a full source-provenance gate in CI must ensure these conditions (for instance, scanning for nested repos or submodules) before running the diff check. If any such unsupported state is detected, the pipeline should fail closed (HOLD) until the issue is resolved. For this playbook, we only validate our declared simple repository state and do not simulate errors from git status itself.
Map the comparisons behind diff, cached diff and status
Git actually supports several “diff” comparisons, not just one. By default, git diff (without arguments) compares the index to the working tree. In other words, it shows unstaged changes in tracked files. In our fixture, after the initial commit, running:
git diff --exit-code
This produces exit code 0 (no differences) and no output, because the worktree matches the index (the commit we just made). The --exit-code flag causes Git to return 1 if differences are found, or 0 if none. Without --exit-code, Git would still print diffs, but we rely on the exit code for automation.
To compare with the last commit (HEAD), one typically runs:
git diff --exit-code HEAD --
(This is equivalent to git diff HEAD --exit-code or git diff HEAD with the --exit-code flag.) That compares the HEAD commit’s tree versus the index. It catches any changes that are staged (in the index) or committed differences. In our clean state, this also returns exit code 0, since no differences exist between HEAD, index, and worktree.
Important: if we had any staged changes, git diff (index vs worktree) might show nothing, while git diff HEAD (HEAD vs index) would show a difference. We will see this in the next sections.
Separately, git status --porcelain=v1 -z --untracked-files=all provides a machine-readable list of changed/added/removed files. With these options:
• --porcelain=v1 gives a stable format.
• -z ends each entry with a NUL byte (0x00) for NUL-safe parsing.
• --untracked-files=all includes untracked files even if a global config disables them.
In this format, each line (terminated by NUL) begins with status codes: XY (two characters) indicate staged (X) and unstaged (Y) changes for a tracked file, or ? for untracked, ! for ignored. For example, an untracked file line looks like ? <path>. A modification not yet staged appears as M <path>, etc.
Finally, git ls-files --others --ignored --exclude-standard -z independently lists files ignored by .gitignore or global exclude, whether or not they are tracked. The flags mean:
• --others: show untracked files.
• --ignored: show only those untracked files that match an ignore pattern.
• --exclude-standard: use the standard ignore rules (.gitignore, .git/info/exclude, user excludes).
• -z: NUL-terminate outputs.
This ls-files command gives us a full inventory of ignored files. If any appear here, they violate our “no unapproved inputs” policy.
In summary, we use:
• diff exit codes for a quick cleanliness check (zero vs nonzero).
• status output to see what files are changed/added/untracked.
• ls-files to see ignored files.
We interpret zero exit codes only in context (diff vs diff HEAD). A successful status command (exit code 0) merely means “Git ran without error”; it can still list uncommitted changes. One must inspect its output bytes. The playbook’s logic is: accept (ACCEPT) only if both the status output and ignored-list output are empty (no entries) in our strict policy; otherwise HOLD.
Do not confuse successful inspection with a clean result
One common misconception is to equate “exit code 0” from a status or diff command with “everything is clean.” This is incorrect. For example, running git status --porcelain in a very dirty tree might still exit 0 and print many lines of output. Likewise, git diff --exit-code exiting 0 only means “no differences for the comparison you made.” If you run git diff with no args (checking index vs worktree) and get 0, there could still be staged-but-uncommitted changes (which you would see with git diff HEAD).
Therefore, successful execution (exit code 0) of our checks only tells us the command ran. We must still parse the data. In our script harness, we capture the raw output (bytes) of status and ls-files; we check emptiness of those outputs, not just the exit code.
For a human-readable view, one might run git status or git diff, but our automation gate relies on the exact streams of data. For instance, git status -z ending with NUL allows us to distinguish filenames containing whitespace or newlines. If our status output bytes are non-empty, we have uncommitted changes (a policy violation). If ls-files --ignored -z output is non-empty, there are ignored files. Only both being empty yields ACCEPT under our gate.
Tip: Porcelain status returns 0 even when listing changes. Only an error (like running outside a repo) gives a non-zero exit. Likewise, a diff run without --exit-code would exit 0 even if differences are printed; we explicitly use --exit-code to get 1 when there are changes. But remember which tree each diff compared.
We will now exercise these observations in concrete examples.
Make a staged change pass the original diff gate
First, test the behavior of a modified tracked file. We change tracked.txt on disk, but do not stage it at first. In code:
echo "changed" > tracked.txt # modify the tracked file
git diff --exit-code # compare index vs worktree
This yields exit code 1 (differences), and git status would show an unstaged change (e.g. “ M tracked.txt”). Our gate should HOLD on this failure, since a committed source file was modified. The policy is violated until we commit or revert.
Next, we stage that change:
git add tracked.txt
Now the change is in the index. Run the checks again:
git diff --exit-code # compare index vs worktree
git diff --exit-code HEAD -- # compare HEAD vs index
git status --porcelain -z --untracked-files=all
We observe:
• git diff (index vs worktree) exit code 0, because the worktree matches the index exactly (no unstaged changes).
• git diff HEAD --exit-code exit code 1, because the index has a change that is not in HEAD.
• git status -z: output shows something like 1 M. ... tracked.txt (indicating X=M, Y=. in porcelain short format, or simpler view with git status).
• No untracked or ignored files appear.
The crucial point: a “green” default diff (exit 0) would have the old release script incorrectly conclude “no changes.” But in fact HEAD has not been updated. We have staged a change but not committed it. If a build generator script only ran git diff --exit-code (with no path argument), it would see 0 and accept. Yet the source is incomplete. This defect can cause non-committed edits to leak into a release.
In short: staging a change silences git diff, but not git diff HEAD. Our evidence from the harness confirms this: after staging, diff=0 and diff_head=1. The gate (our policy) remains HOLD until we actually commit or drop the change.
This situation is analogous to a CI process that runs formatting or code generation tools then checks git diff for edits. For example, a Go release playbook might run generators and expect git diff --exit-code to be 0. As we see, that check wouldn’t notice staged changes. (Refonte’s Go-1.27 migration checklist runs git diff --exit-code after code generation; our example shows that pattern misses staged changes.)
Conclusion: A clean git diff alone does not guarantee the HEAD commit has all edits. A safe gate must consider both worktree->index and index->HEAD differences. One could simply run git diff HEAD instead of default, or require a commit before building.
Add an untracked input that both diffs miss
Next, test an untracked file. We create a new file whose name contains a newline (to test NUL-safe output):
echo "untracked input" > "extra
input.txt"
This file is not in Git at all (neither committed nor staged). We also ensure Git’s config is set to hide untracked files by default:
git config status.showUntrackedFiles no
Normally, git status would omit untracked files if status.showUntrackedFiles=no, but the --untracked-files=all flag overrides that. Now run:
git diff --exit-code
git diff --exit-code HEAD --
git status --porcelain -z --untracked-files=all
Results:
• Both diffs exit code 0. Why? The new file extra\ninput.txt is not being compared in either diff mode: it’s not in the index, so neither diff (index vs worktree, nor HEAD vs index) shows it.
• git status -z --untracked-files=all produces a line:
?? extra
input.txt\x00
That is, the status sees an untracked file (marked ??) whose path contains a literal newline. The output is NUL-terminated, as specified. We confirm exactly (the harness asserts) that the status bytes are b'?? extra\ninput.txt\x00'. The path is a single entry (the newline is part of the name).
Even though the status return code is 0 (successful), its output is not empty. Our gate inspects the bytes: seeing any non-empty status output triggers HOLD. In text form, git status --porcelain shows something like ?? "extra\ninput.txt", but importantly the -z output ensures we capture the raw path safely.
We also note: because we set status.showUntrackedFiles=no, a plain git status would not list the new file, but --untracked-files=all forces it to appear. It’s critical that we explicitly request untracked files; otherwise the hidden file might slip through the gate. Even with default Git behavior, a hidden file with a newline could be problematic; using -z avoids splitting at newlines.
In summary, this test demonstrates that untracked files go unnoticed by git diff. Only the status command can reveal them. And one must handle weird filenames safely. The status output clearly marked an untracked file with a newline, terminated by a NUL. We treat this case as HOLD because there is an extra file the build could read.
Override ambient untracked-file visibility explicitly
We intentionally disabled automatic untracked-listing (status.showUntrackedFiles=no) to mimic environments where Git tries to speed up status. The key lesson is: explicitly specifying --untracked-files=all in the status command reliably finds them. Even if the config says “don’t show untracked,” adding -u or the above flag forces listing. In our test the explicit flag still listed the file.
If one were to omit --untracked-files and rely on default, one could wrongly believe the tree is clean. A robust gate should always list untracked files explicitly (or run with -uall). In our Python harness, we do just that. We capture every byte, including paths with spaces or newlines.
Note: An alternative parser might split status output on newlines; but with -z we get NUL delimiters. We should never naively split on “\n” when -z is used. For now, we only check emptiness, so we don't need a full parser. But keep in mind that future diagnostics (if we wanted to report the offending path) would have to understand the two-format record (renames, etc.) described in Git docs.
Expose ignored inputs with a separate inventory
Finally, test an ignored file. We create the ignored directory and file:
mkdir scratch
echo "ignored build input" > scratch/input.txt
The path scratch/input.txt matches our .gitignore rule, so Git treats it as ignored. Now:
git diff --exit-code
git diff --exit-code HEAD --
git status --porcelain -z --untracked-files=all
git ls-files --others --ignored --exclude-standard -z
We observe:
• Both diffs exit code 0 (no output), for the same reason as the untracked case: the file is neither in the index nor affecting tracked content.
• git status -z (even with --untracked-files=all) yields empty output. Ignored files do not show up in git status by default (status shows ! only if using --ignored flag). Our status output status.stdout is zero bytes.
• git ls-files --others --ignored --exclude-standard -z produces bytes b'scratch/input.txt\x00'. In other words, it lists the ignored file. The harness confirms the ignored inventory is scratch/input.txt\0.
This confirms that ignored files are invisible to normal diff/status checks but appear in an ls-files query. The .gitignore file only tells status and other commands to skip listing them; it does not remove them from the working directory. A build tool can still open scratch/input.txt if it knows to.
Therefore, our gate logic must include checking this inventory of ignored inputs. Under our strict policy, no ignored file is allowed. (If the build process intentionally writes cache under scratch/, the build owner would have to explicitly allow it; otherwise it triggers HOLD.)
The Git ls-files documentation explains that the --exclude-standard option “adds the standard Git exclusions: .gitignore in each directory, etc.”. In effect, it reads .gitignore and reports matching files. The combination --others --ignored --exclude-standard is a known way to list all ignored files.
We conclude: an ignored file must be separately checked and causes a hold. We never treat git diff as permission; the policy banned even ignored scratch files.
Build a NUL-safe bounded acceptance gate
Now we have the pieces to construct the gate. In pseudo-code, our acceptance test (for this policy) is:
status_bytes = git('status -z --porcelain=v1 --untracked-files=all')
ignored_bytes = git('ls-files --others --ignored --exclude-standard -z')
if status_bytes is empty AND ignored_bytes is empty:
    decision = 'ACCEPT'
else:
    decision = 'HOLD'
In practice, we run these commands in the CI script and capture the raw byte streams. In shell, one might do something like:status=$(git status --porcelain=v1 -z --untracked-files=all)
ignored=$(git ls-files --others --ignored --exclude-standard -z)
if [ -z "$status$ignored" ]; then
echo "Gate ACCEPT"
else
echo "Gate HOLD"
fiWe emphasize capturing the complete output (including NULs). Using -z avoids ambiguity when filenames contain special characters. If either stream is non-empty, the condition is false (we hold).
Because we have a very simple one-policy gate (“no unapproved file at all”), checking emptiness is enough. If our status output had rename/copy lines, a human might need to parse fields, but emptiness is still easy to detect. We explicitly avoid writing a full parser or splitting on newline, since -z output is NUL-terminated. (A parser for porcelain v1 would have to handle ‘1’, ‘2’, and ‘u’ record types, and rename paths with embedded NULs; we skip that complexity for decision-making.)
We should also handle error codes: if any Git command itself fails (unexpected environment, no HEAD, repo corruption), we treat that as HOLD/FAIL. For example, if HEAD was unborn, git diff HEAD would error. The gate should catch errors (ok=False in our harness) and hold, not ignore them.
The reference gate (in the code) was configured to ACCEPT only if status.stdout is empty and ignored.stdout is empty. That is, the most conservative policy for this repository with no exceptions. In a real build with allowed ignored paths, the condition might be “ignored is subset of allowlist”.
Avoid claiming a full parser when emptiness is sufficient
Some readers might wonder about more complex status output: for example, rename or copy lines produce two paths (source and dest). In porcelain v1 with -z, those entries are terminated by two NULs (one between old/new path, one at end). If a user considered writing a robust parse of every field, they would note Git’s format spec says:
git status -z prints entries separated by NUL. Rename/copy entries include an extra NUL between old and new names. However, since our gate’s logic is only “empty or not empty,” we do not parse internal fields at all. A single approach is: if the output byte length is zero, no changes. If non-zero, someone must inspect. The intricacy of how many NULs or the exact format is irrelevant for deciding empty vs not-empty.
In other words: we rely on emptiness. We do not inadvertently split on newline or mishandle rename records. This is why we prefer --porcelain=v1 -z; the docs warn that quoting rules differ without -z. We strictly use NUL mode. If in the future someone needs to build an evidence report (e.g. to show which files were found), they would have to correctly handle rename records in git status, but that is beyond this gate’s decision. Here, we explicitly say: “If anything at all appears, we hold.” That avoids parsing pitfalls.
Test the full negative matrix and command failures
Let us compile the results for all five test cases, combining git diff, git diff HEAD, status, and ignored:
Case | git diff exit | status output (porcelain -z) | ls-files ignored output | Decision | |
Clean | 0 | 0 | (empty) | (empty) | ACCEPT |
Tracked modified (unstaged) | 1 | 1 | e.g. b' M tracked.txt\x00' | b'' | HOLD |
Tracked modified (staged) | 0 | 1 | e.g. b'1 M. ... tracked.txt\x00' | b'' | HOLD |
Untracked file with newline | 0 | 0 | b'?? extra\ninput.txt\x00' | b'' | HOLD |
Ignored scratch/input.txt | 0 | 0 | (empty) | b'scratch/input.txt\x00' | HOLD |
(Note: status output bytes are shown in Python repr. Diff exit codes 0=clean, 1=changes. All status commands returned 0 exit code here, as did ls-files.)
Clean: Both diffs are 0, and status/ignored outputs are empty. Gate ACCEPT (as expected).
Unstaged change: Default git diff shows a diff (code 1), so immediate HOLD. Even without checking status, the diff exit code already indicates policy violation. Status output is non-empty (M tracked.txt).
Staged change: As discussed, git diff is 0 but git diff HEAD is 1. Our logic looks at status (non-empty: shows M in index) or diff_HEAD and finds a problem. Gate HOLD.
Untracked newline file: Both diffs are 0. The status output was non-empty (the ?? line). Gate HOLD. The key evidence is the status stream, which our gate caught.
Ignored input: Both diffs are 0. Status output is empty. But the ignored inventory is non-empty. Gate HOLD. This shows we need the ls-files step.
Additionally, any Git command failure would also cause HOLD. For example, if HEAD were unborn or if the repository is detached incorrectly, we would not interpret a missing output as “clean.” The gate script should check that git diff and git status all returned success code; if any return a genuine error, the script should abort/hold with an appropriate error message. (We did ok=False for diff to catch unexpected errors in the harness.)
In our isolated tests no command errored. All exit codes for status and ls-files were 0. But remember: exit code 0 here means “command finished,” not “no changes.” For policy, we only rely on the emptiness of status.stdout and ignored.stdout.
With this matrix, we see clearly the coverage of our checks. No row besides “Clean” meets the criteria of both empty. Only clean is ACCEPT. Uncovered case (not in matrix): if a user had staged a deletion or rename, those would also appear in status (with D or R flags). Our gate would similarly HOLD.
In conclusion, the complete gate is: ACCEPT if and only if both git status ... -z and git ls-files ... -z produce no bytes. All other states are HOLD. Any additional policy (e.g. permitting certain ignored paths) would require adding exceptions here.
Separate an observed clean tree from immutable build input
It’s important to recognize the limits of this point-in-time check. Even if our gate passes, that only means: at the moment of checking, the working tree (and index) had no unknown files. It does not guarantee that nothing changes by the time the build actually consumes the files. This is the classic “check-to-build race” problem. A malicious or buggy process could insert a file between our check and the build step.
To address this, one must enforce an owned checkout or some lock on the workspace. Options include:
• Building in a fresh cloned repository (or Nix/immutable path) immediately after verifying cleanliness.
• Materializing the committed source as a tarball or archive and building from that.
• Using commit IDs or container images to pin inputs.
This is similar to the issue of Terraform’s saved-plan identity: a saved plan is an artifact of an earlier configuration. The “approved input” boundary is the commit ID, but the live workspace might diverge. The Terraform blog page on saved-plan vs config identity touches on the idea that an artifact’s validity depends on what it was reviewed against, not the current state. Here, we say: passing a Git-clean check does not magically reproduce the same build inputs later unless we enforce build isolation.
In practice, a pipeline might do this: after the gate succeeds, immediately call git clean -ffdx and git reset --hard HEAD in a fresh workspace (on a build agent) to ensure only committed files are present. Or better, check out by commit ID in a fresh clone. Deleting ignored files in a user repository (as part of the build) is not something to do lightly if it could remove legitimate work. That's why our policy is “review and fix in source” rather than auto-clean. The next build after fix should run on a known state.
Name what the build can read outside the repository gate
Besides Git-tracked files, real builds read other inputs: environment variables, config files, external dependencies, generated outputs, etc. Those are not checked by our Git gate and must be documented in separate manifests. For example:
• Environment vars: If BUILD_URL or secrets influence the build, they need to be noted.
• Dependency repos: If the code uses go get to fetch libraries from elsewhere, those are external inputs (a “vendored” commit approach or lockfile can mitigate this).
• Generated files: If the build process reuses cached generated content (like a target/ directory), that should be explicitly permitted or cleaned.
• Containers/artifacts: e.g. Dockerfile references or Helm charts come from outside Git.
In the terminology of supply-chain security, the Git cleanliness gate is one part of source-provenance. Other parts (dependency list, environment record, packaging manifest) must complement it.
Capture source evidence before accepting generated outputs
When the gate passes, we should record evidence of the checked state as part of the artifact’s metadata. This should include:
• Commit ID (HEAD) of the repository.
• Repository root path or clone URL & ref.
• Git version and relevant flags (like porcelain version).
• Output bytes of the status and ignored checks (which should be empty, but record as proof).
• Input policy declaration (what paths were disallowed).
• Possibly a checksum or ID for the build outputs.
In our harness, we printed a JSON object with head, results, etc. In a real release script, one might record the raw NUL output streams alongside the release artifact or in CI logs (privately). This becomes part of the provenance: “we verified that on commit X, with Git v2.47.3 and this configuration, there were no uncommitted changes or ignored files.”
We distinguish this from the artifact identity (which could be a hash of compiled binaries). The artifact ID alone doesn’t testify to source purity; hence we keep the commit ID and gate outputs. If later someone inspects the artifact, they can check it against commit X for reproducibility.
Because the raw streams include NULs, when storing them in a log one could hex-encode or base64 them if needed. But we keep original bytes if we want machine-checkable data (a CI record parser could verify “bytes are empty” for acceptance). For human logs, showing repr(status) and repr(ignored) like the harness did gives an unambiguous record (e.g. it showed b'' or b'scratch/input.txt\x00').
In any case, treat these as test results, not the eventual authoritative manifest. The commit ID is the real fingerprint of content; the diff/status outputs are ephemeral evidence of the environment that produced the build.
Repair the boundary without deleting somebody else’s work
When the gate holds (rejects), action is needed. We outline the safe steps:
• Identify and review the disallowed files: If status shows a modified tracked file, ask the author: did they mean to commit it? If yes, incorporate it (commit). If it was a mistaken local edit, ask if it can be stashed or reverted. The gate only prevents release, it does not decide whether the change is good. A team or owner must explicitly accept or discard it.
• Untracked files: For each untracked path found, determine if it should be in source. E.g. if a new source file was added, maybe it should be git added. If it’s truly local scratch or temp, the developer should remove it or move it out. The release process should not forcibly rm user files without confirmation. In our fixture, we delete the file purely as a demonstration (odd.unlink() in Python), but we emphasize this is for the disposable test only. In a real repo, the gate script should instruct the committer to clean up the workspace, not wipe it out.
• Ignored inputs: Similar to untracked, but here we have a policy choice. If an ignored file (like scratch/input.txt) is actually required input (e.g. a local config), then the policy must be updated. Perhaps move it into version control or formally allow it (by modifying ignore lists and documentation). If it truly is an unwanted file, the user should remove it. Again, delete with caution.
• Explicit rebuild (isolation): We did not actually run the build in our harness. In a real repair, after fixing the workspace (committing or removing offending inputs), one would re-run the build from scratch to produce new artifacts. Only then compare with the old artifacts. If the changes were benign (like an accidental debug print), the artifacts should match; if not, this highlights the differences due to the fix.
• Never auto-clean the entire workspace: Commands like git clean -xfd or git reset --hard can obliterate files. They are powerful but dangerous if run on a developer’s machine. Our fixture uses git restore --staged --worktree tracked.txt as a limited example (it’s confined to the temp repo) to revert the staged change. We do not recommend pushing that into user repos. Instead, treat deletion of files as a substantive decision by a person, not an automatic parser fix.
The goal is to restore a safe commit boundary: what to use for the release source. That boundary could involve removing some unapproved inputs from consideration, or including some previously-ignored content properly. After doing that, we ensure the old artifact’s identity and source observations are preserved (for comparison), then do a rebuild with the corrected sources.
Choose accept, repair, hold or rebuild
To bring it all together, we frame a decision procedure:
• ACCEPT: Clean history. No disallowed changes. Proceed with release using the current workspace. Responsible: Release engineer, who verifies that the gate passed (status and ignored empty). No user action needed beyond the gate.
• REPAIR: Minor fix. There is some unapproved input (staged/unstaged change or untracked file), but it’s straightforward to resolve. For example, a developer just forgot to commit a change (so they do), or an extra untracked scratch file can be removed. In these cases, the maintainer fixes the repository state, then reruns the gate (and a build). We never unilaterally destroy files, only rectify the boundary. Responsible: Code owner or developer, under guidance from release process.
• HOLD: Ambiguous or unsupported. This is a catch-all if the situation cannot be auto-repaired or if policy forbids an automatic decision. For example, if the status shows multiple disallowed files and the team isn’t sure which to keep. Also if any git command failed. Human intervention is needed to clarify policy or code. Responsible: Project lead or security team to define the next step. Possibly escalate.
• REBUILD: If a release was already cut (artifact built) using inputs that violate policy (i.e., we discovered after-the-fact), we must rebuild under the correct inputs. The old artifact’s provenance is uncertain. The old build should be examined (retained) and the new build compared. If they differ, downstream consumers may need to be re-validated. Responsible: Release manager or QA, with artifact comparison tools.
Below is an illustration of how owners decide on ignored files:
Action | Who Decides / Confirms | Example |
Allowed ignored paths | Build owners or lead (approve safe caches) | e.g. Allow build/cache/ if shown unused |
Modify .gitignore | Dev team (if a file needs tracking) | e.g. Remove tmp/ from ignore if needed |
Delete ignored file | Committer (if file was stray) | e.g. scratch/input.txt was stale, removed |
Update build process | DevOps team (if reader changed) | e.g. Change build to never read certain dirs |
In particular, default .gitignore rules should not be assumed “safe.” If the build truly expects an ignored directory of artifacts, that allowlist must be explicit and justified. The guide to CI pipeline ownership and configuration reminds us that pipeline config (Jenkinsfile, GitHub Actions, etc.) belongs to the team, and they must ensure these checks fit into the pipeline. But no matter the CI system, the logic above still applies.
Once the appropriate fix is made (like committing the tracked change, or confirming the ignored file is intentional), we re-run the gate from a known-clean checkout. Ideally, we do this on a new clone of the repo at the same commit ID (or on a locked workspace). This avoids any race or partial state.
Rebuild artifacts produced under the incomplete gate
If the gate caught an issue after an artifact was built or released, we treat the old artifact as coming from an uncertain boundary. We then rebuild:
1. Label the old artifact with its source uncertainty. For example, note “artifact app-1.2.3.jar was built from commit abc123 with flagged inputs.” Preserve its identity (we do not overwrite it).
2. Correct the input boundary (remove/commit files, per repair above).
3. Rebuild from scratch using the same build commands. Use the same environment as much as possible (same tools, flags, etc.).
4. Compare the new artifact to the old one. If bit-for-bit identical, the unapproved inputs had no effect, and the original artifact can be certified. If they differ, the original may be invalid; at minimum, users should be alerted and may need to use the new artifact.
This is similar to patching a failing build: we don’t want to modify history silently. We produce a new artifact under a clean contract and then see what changed. It’s like proving a bug fix: if nothing changes, great; if something does, that’s a documented change. Never pretend the first artifact was “fine” if it might include hidden inputs.
We avoid saying “every historical build is wrong”; maybe no one actually used that ignored file. But from a provenance standpoint, only the clean boundary build is fully validated. Consumers who cached the old artifact should be notified if a change was necessary.
Therefore, our final step in the process is: rebuild and revalidate. This step ensures that going forward, the artifact matches known clean sources. It’s important to preserve the old identity for auditing (forensic) and not override it until after comparison.
Connect source-provenance testing to DevOps practice
In modern DevOps pipelines, ensuring source provenance is essential for reliable and secure releases. Automated gates like the one we built fit into continuous integration workflows alongside tests and static analysis. They make explicit the boundary between developer workspaces and production artifacts.
The Refonte Learning DevOps Engineering Program trains engineers in exactly this kind of practice: managing Git & GitHub, designing CI/CD pipelines, and enforcing reproducible builds. For example, students learn to write pipeline definitions that include preflight checks (like our diff gate), set up isolated build environments, and handle artifact promotion. By mastering these techniques, DevOps engineers can ensure that every deployment is traceable to a clean source commit, with no sneaky inputs escaping audit.
Interested readers can explore the DevOps Engineering Program to see how such source-integrity topics fit into a broader curriculum (including Git, containers, Kubernetes, Terraform, etc.). Emphasizing disciplined CI/CD practices and version control hygiene is exactly the kind of outcome this program aims for.
Overall, the key takeaway is: don’t assume git diff --exit-code gives full coverage of build inputs. Use a combination of diff vs HEAD, status, and ls-files as shown here. Accept releases only when no extra files slip through. That makes your pipeline more reliable, your artifacts more trustworthy, and your DevOps practice stronger.