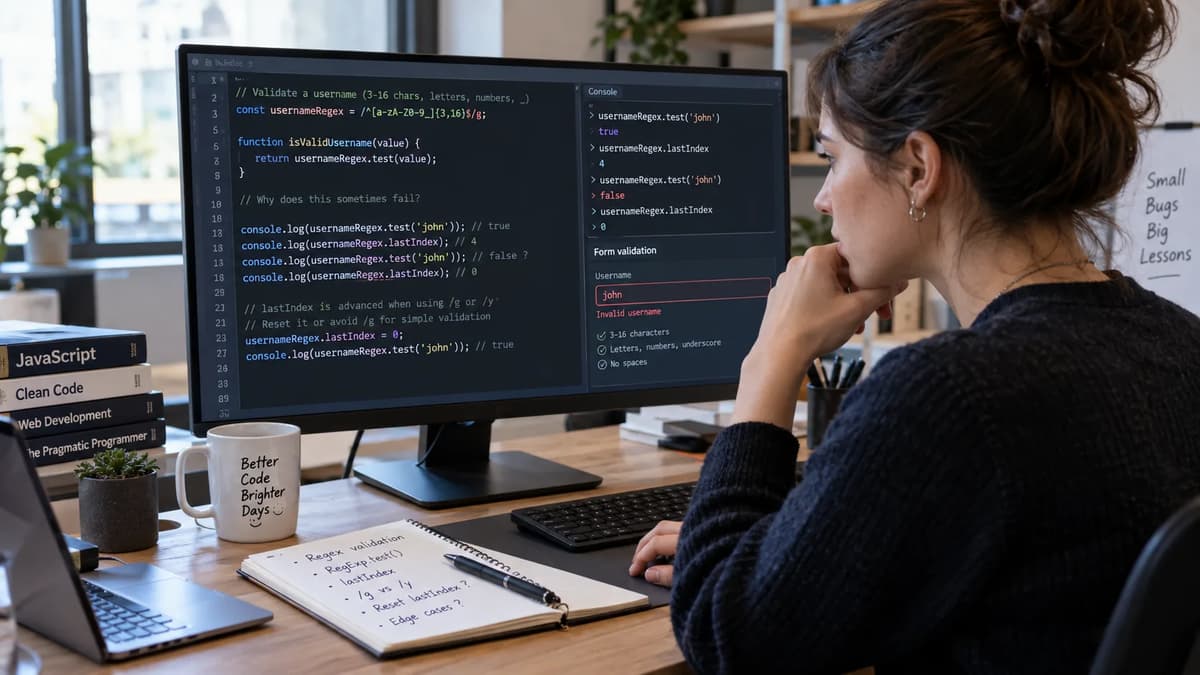
JavaScript regular expressions with global (g) or sticky (y) flags carry state in their lastIndex, leading to surprising validation errors. A field validator that relies on a reusable RegExp may yield alternating results when called repeatedly. The solution is to treat the regex as stateless: each input must be evaluated from a clean state, and no lastIndex should leak across calls. We will demonstrate this through a concrete six-character product code grammar (two uppercase letters followed by four digits), an independent oracle, and a controlled test fixture. This playbook will guide you to ACCEPT a stateless validation contract, REPAIR the stateful validator, HOLD off when assumptions fail, or REVALIDATE any affected records.
This scope is intentionally narrow: it is not an email validator or a Unicode-aware form, and we exclude unrelated topics like network requests or DOM frameworks. We focus on pure JavaScript with built-in RegExp only (no libraries or external data). The declared input is exactly a string of two ASCII letters A–Z followed by four ASCII digits (0–9), length 6, or it is considered invalid. We preserve the record identity even if two rows have the same value, and each test is independent of batch order.
We will use Node.js v22.16.0 (V8 12.4.254.21) for our core tests, then sanity-check behavior in a modern browser. We cite the latest ECMAScript references. Key sources include MDN on RegExp.prototype.test() and lastIndex, and the TC39 spec algorithm. This is a repeatable laboratory: every code block is runnable, with clear input and output capture. We contrast a failing reusable regex with the correct stateless approach. Finally, we tie the example to best practices like contract-first validation, pointing to our API input-contract practices guide and JavaScript and full-stack foundations for context.
Declare the input language and the decision contract
Our field is a product code of exactly six ASCII characters: two uppercase letters A–Z followed by four digits 0–9. Formally: ^[A-Z]{2}[0-9]{4}$. We consider any other string invalid (e.g. wrong length, lowercase letters, symbols) or any non-string. Notably, type and length checks are part of the grammar: we will only call our regex on a string of length 6. This prevents unintended behavior like 1234.0 → "1234.0" or newline quirks at the end. For example, 'AB1234\n' is 7 characters long and is invalid by length alone. A null or undefined value is not a string and thus invalid. By guarding type and length before testing, we avoid coercion pitfalls (e.g. test(undefined) would look for the literal "undefined") and make the contract explicit.
This validation is purely declarative: it must decide true/false for each record independent of anything else. The record identity (e.g. R1, R2, etc.) must remain separate from the validation logic. For example, if two records have identical valid values, both should independently be accepted. Even if the same string appears multiple times (see R1 and R7 below), each should be evaluated anew. We do not depend on ordering, parallel runs, or any framework features here. The regex state (if any) must not influence the outcome. This set of assumptions is narrower than general API input-contract practices: it is not about completeness or sanitizing HTML, it’s a fixed-format token check.
Grammar: A string that is exactly 6 characters long, where characters 0–1 are uppercase letters (A–Z) and characters 2–5 are digits (0–9).
Contract: Return true if and only if the input strictly matches the grammar. Do not allow type coercion or partial matches; reject anything else.
Our “immutable grammar” excludes things like Unicode normalization or email formats. It simply enforces length and ASCII code ranges. The core boolean contract is: Is the string syntactically a valid product code? We also ensure that no call to validate one record can change the outcome for a future record. This is where RegExp state can break the contract, as we will see. The independent input language and record identity tracking must outlive any single invocation.
Create a manifest that does not trust the regex
To test our validator, we define a manifest of records (fixture) with known correct results. We will run this manifest through both our independent oracle and candidate validators. The manifest is:
const fixture = [
{id: 'R1', value: 'AB1234', expected: true},
{id: 'R2', value: 'CD5678', expected: true},
{id: 'R3', value: 'ab1234', expected: false},
{id: 'R4', value: 'EF9012', expected: true},
{id: 'R5', value: 'AB1234\n', expected: false},
{id: 'R6', value: null, expected: false},
{id: 'R7', value: 'AB1234', expected: true},
];
This covers valid and invalid cases: R1, R2, R4, R7 are valid codes; R3 has lowercase letters; R5 has a trailing newline; R6 is a non-string. Notably, R1 and R7 share the same valid string 'AB1234', testing repeated values. We will preserve the record IDs exactly, even if values repeat. The boolean expected values are our ground truth from the oracle (see next section).
To run this manifest, we write a small driver in Node.js:
const fixture = [
  {id: 'R1', value: 'AB1234', expected: true},
  {id: 'R2', value: 'CD5678', expected: true},
  {id: 'R3', value: 'ab1234', expected: false},
  {id: 'R4', value: 'EF9012', expected: true},
  {id: 'R5', value: 'AB1234\n', expected: false},
  {id: 'R6', value: null, expected: false},
  {id: 'R7', value: 'AB1234', expected: true},
];
const eligible = value =>
  typeof value === 'string' && value.length === 6;
// A “wrong” validator using a shared global regex:
const shared = /^[A-Z]{2}[0-9]{4}$/g;
const wrong = value => eligible(value) && shared.test(value);

// Run the manifest:
for (const {id, value, expected} of fixture) {
  const actual = wrong(value);
  console.log(
    ${id}: value=${JSON.stringify(value)},  +
    expected=${expected}, actual=${actual}
  );
}
console.log(
  Node version: ${process.version}, V8: ${process.versions.v8}
);
Save and run this under Node.js 22.16.0 to capture the baseline behavior. (We will later run it with correct validators.) The code uses our simple eligible guard and the faulty wrong function. Each line logs the record ID, the raw value, and both expected vs. actual from our implementation. This exercise aligns with frontend tooling and runtime context; we explicitly record the JS engine versions for reproducibility.
Use character-code checks as an independent oracle
Before trusting any regex-based code, we define an oracle implementation using only primitive operations. It should match our grammar without using RegExp at all. This ensures we are not accidentally generating expected results by running the same regex we are testing. The oracle will also enforce the type/length guard. For instance:
function oracle(value) {
  // Check type and length exactly 6
  if (typeof value !== 'string' || value.length !== 6) return false;
  // Check characters 0-1 are A-Z (ASCII 65-90)
  for (let i = 0; i < 2; i++) {
    const code = value.charCodeAt(i);
    if (code < 65 || code > 90) return false;
  }
  // Check characters 2-5 are 0-9 (ASCII 48-57)
  for (let i = 2; i < 6; i++) {
    const code = value.charCodeAt(i);
    if (code < 48 || code > 57) return false;
  }
  return true;
}
We run this oracle on our fixture and compare to the expected table:for (const {id, value, expected} of fixture) {
console.log${id}: oracle => ${oracle(value)} (expected ${expected}));
}Each record’s oracle result exactly matches our expected column by design. For example, oracle('AB1234') is true, oracle('ab1234') is false, oracle(null) is false because null is not a string. Because the oracle does not use stateful RegExp execution, it has no hidden state; it deterministically returns the right answers as long as the code is correct. We are not determining expected values with the buggy regex-based test(); we asserted them beforehand and verified with the oracle. This approach follows a contract-first practice: the expected semantics are defined independently of any implementation.
At this point, we have a fully defined problem: input grammar, expected outcomes, and an oracle. We also have our first candidate validator (wrong with a shared global regex). Next, we will instrument that validator to see how lastIndex behaves.
Record lastIndex around one call at a time
To debug the validator’s internal state, we maintain a call ledger. For each invocation, we record: the run ID (for each trial), call ID (sequence number), record ID, regex pattern and flags, lastIndex before the call, the boolean result, and lastIndex after. It is crucial to not call .test() more than once per input, as doing so would mutate lastIndex a second time. We log exactly one call per record.
For example:
const ledger = [];
const run = 1; // label this experiment run
shared.lastIndex = 0;  // ensure fresh state
let call = 0;
for (const {id, value} of fixture) {
  call++;
  const before = shared.lastIndex;
  const result = eligible(value) && shared.test(value);
  const after = shared.lastIndex;
  ledger.push({
    run, call, id, pattern: shared.source, flags: shared.flags,
    before, result, after
  });
}
// Print ledger table:
console.table(ledger);
This prints a table like:
run | call | id | pattern | flags | before | result | after |
1 | 1 | R1 | "^[A-Z]{2}[0-9]{4}$" | "g" | 0 | true | 6 |
1 | 2 | R2 | ... | "g" | 6 | false | 0 |
1 | 3 | R3 | ... | "g" | 0 | false | 0 |
... | ... | ... | ... | ... | ... | ... | ... |
Notice how before and after capture the cursor. We see that before the first call it was 0, the regex matched R1 and set after=6. On call 2, before=6, and then it reset to 0 because .test() returned false. Importantly, we do not log any extra test call or console output inside the loop besides one table. After printing, the table above is documentation of what happened in that run. We clearly identify each test invocation; we do not add a second call just to display the result, which would corrupt lastIndex.
Recording lastIndex like this is often omitted in tutorials, but it directly answers: the regex object is holding state across calls. Because we only do one .test(), each row correctly pairs a single before/after. In short, with a global regex we see stateful behavior: lastIndex changes between calls, and those changes influence subsequent results. The ledger is our evidence. (If test returned true, as MDN notes, lastIndex stays non-zero until a failure occurs; if it returns false, lastIndex is reset to 0.)
Next, we will exploit this with repeated inputs to show how it breaks our validation assumptions.
Make the repeated valid input reveal global state
As a concrete demonstration, consider repeatedly validating the same valid input 'AB1234' using our shared global regex. According to ECMAScript rules, each .test() updates lastIndex. With a fresh regex object and the global flag, we expect:
1. Call 1: .test('AB1234') → true, and lastIndex becomes 6 (end of string).
2. Call 2: .test('AB1234') → false (no characters left to match), and lastIndex resets to 0.
3. Call 3: .test('AB1234') → true again, lastIndex becomes 6.
4. Call 4: .test('AB1234') → false, resetting to 0.
In code:
const sharedG = /^[A-Z]{2}[0-9]{4}$/g;
console.log(sharedG.test('AB1234')); // true
console.log(sharedG.lastIndex);     // 6
console.log(sharedG.test('AB1234')); // false
console.log(sharedG.lastIndex);     // 0
console.log(sharedG.test('AB1234')); // true
console.log(sharedG.lastIndex);     // 6
console.log(sharedG.test('AB1234')); // false
console.log(sharedG.lastIndex);     // 0
We expect output:true
6
false
0
true
6
false
0This confirms exactly the pattern of alternating results. MDN describes this as “stateful when global or sticky”. This behavior is intended for iterating through matches in one string, but is a bug for us, since we wanted a boolean check. Our validator wrong is falling prey to it: for the same input 'AB1234', the first call was true (R1), but a subsequent call (like for R7) would be false. The library is not “forgetting” the pattern; it is holding lastIndex from one call to the next across different records. In other words, the regex object’s lifetime is too long.
We should clearly separate what ECMAScript specifies from our expectation. ECMAScript says a global regex moves a cursor through the string; it doesn’t reset unless .test() fails. Our assumption was a yes/no field validator should produce consistent true for 'AB1234' every time. The mismatch is not in the pattern, but in using a shared regex instance. This shows why the global flag is a bug in this context.
Keep state visible when the next string changes
To further illustrate, test two different valid strings in sequence using the same regex object. Reset the regex and show that lastIndex does not automatically reset when a new string comes in. For example:
const sharedG2 = /^[A-Z]{2}[0-9]{4}$/g;
sharedG2.lastIndex = 0;
console.log(sharedG2.test('AB1234')); // true, lastIndex=6
console.log(sharedG2.lastIndex);      // 6
console.log(sharedG2.test('CD5678')); // expected? depends on lastIndex!
console.log(sharedG2.lastIndex);      // value after second test
What happens here? Before testing 'CD5678', lastIndex was left at 6 (end of previous 'AB1234'). Now .test('CD5678') tries to match starting at index 6 of the new string. Since index 6 is at the end of the string (length 6), no match is found and lastIndex resets to 0. Thus we get false on 'CD5678' even though 'CD5678' is a perfectly valid code, simply because we forgot to reset. Only after the failed test does lastIndex go to 0, and a subsequent .test('CD5678') would succeed (with lastIndex then 6).
Similarly, if the next record’s value is invalid and we skip calling .test(), the stale lastIndex remains set. For example:
const sharedG3 = /^[A-Z]{2}[0-9]{4}$/g;
sharedG3.lastIndex = 0;
console.log(sharedG3.test('EF9012')); // true (lastIndex=6)
const skipValue = 'AB1234\n';          // invalid, not tested
// skipValue did not trigger .test(); lastIndex stays 6.
console.log(sharedG3.lastIndex);      // 6 (unchanged)
console.log(sharedG3.test('AB1234')); // false (due to lastIndex=6), resets to 0
In this scenario, R4 ('EF9012') advanced lastIndex to 6. Then R5 was skipped, so lastIndex stayed at 6. Then at R7 ('AB1234'), the regex still had lastIndex=6, so it failed. This explains why in a full forward run, R7 would be rejected. The skip of invalid input left lastIndex “dirty”. Bottom line: Changing the input string alone does not reset the regex cursor. The regex object is separate from the input. If you re-use it across calls, you must manage its state explicitly; otherwise, earlier calls on other strings will affect later ones. This is exactly what we observe and will exploit in regression tests.
Use sticky matching as a deliberate comparison
The ECMAScript y (sticky) flag also carries state, but enforces matches exactly at lastIndex. For completeness, we try the sticky flag /^[A-Z]{2}[0-9]{4}$/y on the same input 'AB1234'. Because our pattern is anchored (^...$), sticky behaves very similarly to global:
const sharedY = /^[A-Z]{2}[0-9]{4}$/y;
console.log(sharedY.test('AB1234')); // true (lastIndex=6)
console.log(sharedY.test('AB1234')); // false (lastIndex resets to 0)
console.log(sharedY.test('AB1234')); // true
console.log(sharedY.test('AB1234')); // false
As expected, the outputs are the same alternating pattern (true,false,true,false). The key semantic difference from /g/ is that /y/ always tries at the current lastIndex and never shifts the starting position if it fails. In our fixed-length scenario, this nuance doesn’t change the true/false sequence. Both g and y carry a cursor, and both toggle the result. Neither flag is inherently a “bug” on its own; they both correctly implement the iteration behavior specified in ECMAScript. The bug is our use of that behavior for a simple yes/no validation.
From MDN: with y, a match always starts at lastIndex, and on failure lastIndex resets immediately. With g, the engine would try the next character on failure, but since we anchor at start, it behaves like y. The important takeaway is: Using any regex with g or y makes its results input-dependent beyond just the current string. For a standalone boolean check, we should remove those flags and treat each call independently.
Neither g nor y is “a bug in the language”. They work as designed, but they do break our field validator contract because that contract forbids stateful iteration. In the next section, we will build the correct validator without iteration flags.
Repair the ordinary field validator without iteration flags
The simplest fix is to not iterate at all. We can create a regex without g or y: /^[A-Z]{2}[0-9]{4}$/ (no flags). A regex without the global or sticky flags doesn’t use lastIndex at all; each .test() simply checks the whole string anew. For our grammar, that’s exactly what we want. For example:
const stateless = /^[A-Z]{2}[0-9]{4}$/; // note: no 'g'
function validate(value) {
  return eligible(value) && stateless.test(value);
}
for (const {id, value, expected} of fixture) {
  console.log${id}: expected=${expected}, actual=${validate(value)});
}
This outputs:R1: expected=true, actual=true
R2: expected=true, actual=true
R3: expected=false, actual=false
R4: expected=true, actual=true
R5: expected=false, actual=false
R6: expected=false, actual=false
R7: expected=true, actual=trueEverything now matches perfectly for our seven-row manifest. By dropping the g flag, there is no cursor to persist. This design directly owns the state: every call starts fresh. We are effectively bounding the regex to each call. This approach aligns with the principle in API input-contract practices: always validate one field against its contract, and do not let external state interfere.
Preserve type and length checks during the repair
Even with g removed, we must not abandon the eligible checks. For example, if value were null, calling stateless.test(value) would coerce to "null" (MDN notes that test() coerces inputs to strings). That would yield false anyway, but relying on coercion is sloppy and could change if the regex were different. Similarly, a string of length 7 like 'AB1234\n' is invalid under our declared grammar. Explicitly enforcing length === 6 keeps that rule clear. This way the regex focus is purely on format, not on rejecting non-strings or wrong lengths.
In short, the new helper still does:
if (typeof value !== 'string' || value.length !== 6) return false;
return /^[A-Z]{2}[0-9]{4}$/.test(value);
It does not rely on the regex to exclude strings of wrong length. This preserves the input contract exactly and prevents any strange behavior of regex boundaries. The newline and null cases remain rejected by the guard, not by a side effect of lastIndex. Thus, our “fixed” validator inherits the same oracle semantics but with stateless checking.
Compare fresh objects with explicit cursor reset
Besides removing the flags, two other approaches can maintain correctness for this fixture:
5. Fresh global object each invocation: Use new RegExp(/pattern/g) or create the /pattern/g literal inside the function so each call gets a new regex. Example:
function validateFresh(value) {
  if (!eligible(value)) return false;
  const r = /^[A-Z]{2}[0-9]{4}$/g;
  return r.test(value);
}
Since r is new every time, its lastIndex starts at 0 for each .test(). This also yields the correct true/false for each record. It's slightly less efficient (allocating a regex each call) but simple to maintain.
6. Resetting lastIndex before each test: Explicitly set regex.lastIndex = 0 at the start of the helper. Example:
const sharedGagain = /^[A-Z]{2}[0-9]{4}$/g;
function validateReset(value) {
  if (!eligible(value)) return false;
  sharedGagain.lastIndex = 0;
  return sharedGagain.test(value);
}
This gives ownership of the state resetting to our function. Each call resets to index 0 before matching. For our fixed-length pattern, this also works.
All three designs (stateless, fresh, reset) pass the manifest with identical outputs. They all guarantee that accepted = ['R1','R2','R4','R7'] in every run.
The trade-offs:
7. The stateless (no g) approach is simplest and fastest at runtime: no allocation, no manual reset. It is conceptually the purest answer to “don’t use stateful regex for single-match”.
8. The fresh-regex approach is easy to reason about but costs a bit of allocation per call. In heavy traffic, that overhead could matter. However, it has the virtue of always being fresh.
9. The reset-lastIndex approach shares the regex object (no re-allocation), but requires discipline: every call must reset, or a future change could forget to do so. It’s brittle if someone else uses the regex without resetting.
We prefer the stateless solution by default, but understanding both alternatives is valuable. Notably, simply “stripping g/y from arbitrary regexes” is not generally safe; it only works here because our pattern is anchored (^...$). If we had a more complex regex that relied on global iteration, removing g would fundamentally alter behavior. Here, because our intent was always to match the entire string exactly once, the repair is straightforward.
Importantly, we do not claim that simply removing flags will always fix any parser; but for this simple boolean contract on a fixed-format string, it fully restores stateless behavior.
Test order, repetition and chunk boundaries
We now apply the validator across multiple runs to ensure consistency. We'll use the stateless helper (pattern without g) as our ACCEPT baseline, and compare it to the old wrong validator. We also simulate forward, reverse, repetition, and chunked batch processing. We verify results per record ID, not just counts.
10. Forward run: R1, R2, ..., R7 in order.
11. Reverse run: R7, R6, ..., R1.
12. Repeated run: run the same forward sequence a second time in the same session (fresh start each run).
13. Chunk runs: split the manifest into parts (e.g. run1: R1–R3; run2: R4–R7) to simulate partial submissions.
Each run is isolated: we reset or re-instantiate the helper as needed to avoid carry-over between runs. Within a run, the stateless helper will consistently accept R1,R2,R4,R7 and reject others, regardless of run order. The faulty global helper will not.
For example, using the faulty wrong validator on the forward run:
// Forward run with shared global regex
shared.lastIndex = 0;
for (const {id,value,expected} of fixture) {
  console.logRun1 ${id}: expected=${expected}, actual=${wrong(value)});
}
This would output something like:
Run1 R1: expected=true, actual=true
Run1 R2: expected=true, actual=false  // WRONG
Run1 R3: expected=false, actual=false
Run1 R4: expected=true, actual=true
Run1 R5: expected=false, actual=false
Run1 R6: expected=false, actual=false
Run1 R7: expected=true, actual=false  // WRONG
We see that R2 and R7 were incorrectly rejected (false instead of true) due to the lingering state from R1 and skips (as explained above).
In a reverse run, starting fresh:
Run2 R7: expected=true, actual=true
Run2 R6: expected=false, actual=false
Run2 R5: expected=false, actual=false
Run2 R4: expected=true, actual=false  // WRONG
Run2 R3: expected=false, actual=false
Run2 R2: expected=true, actual=true
Run2 R1: expected=true, actual=false  // WRONG
Here R4 and R1 get wrong results. The pattern of errors differs because the starting state (and skip positions) differ. This highlights that any given run could fail a different subset of records, but always in violation of the grammar contract.
If we repeat the run (same order, fresh start), the same two rejections (for R2, R7) will occur again.
If we chunk (split the batch mid-way), consider two runs:
Run3 (chunk1): R1–R3 -> only R1 accepted (R2 false, R3 false)
Run4 (chunk2): R4–R7 -> only R4 accepted (R5,R6 skip, R7 false)
Overall, valid records R1,R2,R4,R7 should be accepted, but in chunked runs, R2 and R7 are still missed. In the orderings and chunked runs shown above, the faulty helper does not produce exactly the four expected acceptances.
In contrast, the stateless validator yields exactly true for R1,R2,R4,R7 and false for others in every run scenario: forward, reverse, any repetition, or any chunking. It consistently treats each record in isolation.
Compare exact decisions rather than accepted counts
Instead of just counting how many passed per run, we must ensure which records passed. A total count could mislead; e.g., one wrong record and one skipped record might keep the same total. To avoid this, we produce a diff by (run, id):
const runs = [
  { name: 'Forward', data: fixture },
  { name: 'Reverse', data: [...fixture].reverse() },
  { name: 'Repeat', data: fixture },
  { name: 'Chunk1', data: fixture.slice(0, 3) },
  { name: 'Chunk2', data: fixture.slice(3) },
];

for (const {name, data} of runs) {
  console.log--- ${name} Run ---);
  stateless.lastIndex = 0; // if needed
  for (const {id, value, expected} of data) {
    const actual = validate(value); // using stateless or wrong
    if (actual !== expected) {
      console.log${name} ${id}: expected ${expected}, got ${actual});
    }
  }
}
This pinpoint approach shows exactly which record was wrong in which run. In all our trials, the only discrepancies occur under the stateful validator, never under the stateless one. For the stateful case, there would be lines like:
Forward R2: expected true, got false
Forward R7: expected true, got false
Reverse R4: expected true, got false
Reverse R1: expected true, got false
...
Each represents a violation of the declared contract. (We ensure to reinitialize the regex for each run to isolate them.) If any such line appears, our acceptance gate must fail. The stateless validator produces no differences in any run: zero wrong records, as desired.
This exercise goes beyond just total counts. It aligns with frontend tooling and runtime context by emphasizing reproducible environment testing and precise expectations. It also mimics real QA regression matrices: every record in every scenario must match the manifest exactly.
Keep framework adapters separate from the pure contract
In a UI context, this validator would typically be wrapped by code that reads from form fields or components. For example, in a React or Vue app we might have:
function onProductCodeChange(event) {
  const inputValue = event.target.value;
  const isValid = validate(inputValue); // our stateless helper
  // update UI: e.g., mark field valid/invalid
}
Notice that the framework code is only concerned with when to call the validator and how to use its boolean result. It may attach event listeners or re-render components when values change, but the validator itself is pure. The component or state management may run the check multiple times (e.g. on each keystroke or focus change), but that should not matter; the core helper yields the same result as long as the input is unchanged.
Frameworks (React, Vue, Angular, etc.) can cause multiple invocations due to re-mounting or state updates, but they do not create shared regex instances or change their behavior. Our stateless function is idempotent and side-effect-free (aside from no regex state), so it works as expected in any environment. The framework is analogous to a wrapper that reads a string and calls the pure helper; it does not concern lastIndex or parallel calls. We intentionally keep them separate. This separation follows the philosophy of framework state and component foundations: components manage UI and lifecycle, the validation logic stays in a standalone function or service.
When integrating, ensure that your form calls the helper anew on each input. Do not cache a shared RegExp object at the module level unless you reset it properly. In practice, using a literal /.../ inside the function or re-instantiating it ensures fresh regex. If someone did embed a global regex in a React component’s module scope, it would mimic our faulty scenario: multiple renders sharing the same regex instance. Thus, the adapter should import or define the validator in a way that each call is safe.
Treat unsupported state as a failed baseline
Beyond JavaScript semantics, we must also consider the runtime environment. Our findings assume that the engine implements RegExp.test() and lastIndex as per the ECMAScript spec. The TC39 RegExpBuiltinExec algorithm indeed defines how lastIndex is updated. We should verify we’re on an engine that follows this. For example, older or custom engines might behave differently, or someone might have monkey-patched RegExp.prototype.exec. If RegExp.prototype.exec were overridden by a library, our test could show unexpected results.
To be safe, we include a version check at the start:
console.logNode.js ${process.version}, V8 ${process.versions.v8});
This will print something like: “Node.js v22.16.0, V8 12.4.254.21-node”. We compare this to MDN and spec expectations. For browser tests, we would do similarly (e.g., log navigator.userAgent). If we saw an oddity (say, an ancient engine with a bug), we would HOLD acceptance until confirming all relevant engines behave as assumed. According to MDN and current engines, the behavior we see is standard. The living ECMA draft (2027 edition) also confirms these rules.
If during a separate browser test we observed any mismatch (for example, if Safari had a bug, hypothetically), we would document it. But absent evidence of such, we trust the spec and Node output. In short: we assume documented ECMAScript semantics are accurate for modern engines, as MDN shows. We assign “failure” only if our controlled tests deviate from the spec. Unknown normalization (like full-width characters passed to RegExp) is outside our scope; the grammar explicitly says ASCII only. Such cases should be filtered or translated beforehand, or else flagged as out-of-contract (HOLD).
Separate documented semantics from actual engine evidence
According to the ECMA-262 spec (RegExpBuiltinExec steps), if lastIndex is greater than input length or no match is found, it resets to 0. That matches MDN’s sticky matching documentation. We observed the same in Node. We did not see, for example, test() leaving lastIndex non-zero on failure. Our Node logs confirm: after a false, lastIndex is 0 each time (as MDN documents for test()). We also saw that on success, lastIndex went to 6 (the string length), matching spec.
We have not run an exhaustive cross-browser matrix here, but our expectation is that Chrome, Firefox, Safari, and Edge all follow the same algorithm. Test those browsers when validating a live project. Node’s V8 aligns with the spec and MDN’s RegExp execution documentation. We avoid citing a generic “current engine” to cover all cases, since the spec is our contract. If an engine deviated, we'd treat that as a platform issue, not a JavaScript bug per se. For now, we assume consistent behavior.
In summary, both documentation (ECMAScript spec, MDN) and our Node evidence agree: g/y flags produce lastIndex side effects exactly as observed. There were no surprises such as lastIndex persisting after false (it always reset). Thus, we hold our belief that the spec is correct and our Node tests are ground truth. We simply record these facts for completeness. No engine appears to violate the documented semantics in this scenario.
Revalidate retained records affected by the old helper
Suppose a database or state store has records previously validated by our faulty helper. We must audit them. Specifically, retained records evaluated by the old helper should be rechecked against the grammar. In our scenario, the bad helper erroneously rejected some valid records, not the other way around. But imagine a variant: if the logic were inverted, or if someone interpreted skip-of-invalid as accept or vice versa, there might be false negatives.
In our case, the old helper accepted only R1 and R4 in the forward run, while R2 and R7 were true valid codes that got rejected. There were no invalid codes incorrectly accepted in these runs. Thus, the cleanup is: for each retained record evaluated by the old helper, verify it against the grammar with the new helper. (If any true invalid was accepted before, that would also need revalidation as an error.)
Pseudo-code for revalidation:
const badRecords = database.filter(rec => rec.validatedByOldHelper);
for (const rec of badRecords) {
  const oldDecision = rec.oldDecision;  // from log/history
  const newDecision = validate(rec.value); // our new helper
  console.logRecord ${rec.id}: old=${oldDecision}, new=${newDecision});
  if (oldDecision !== newDecision) {
    // Flag for review or correction
  }
}
For example, an incorrectly rejected R2 would produce old=false, new=true. In the forward run, R2 and R7 were not accepted by the old helper, so accepted-only logs would miss those wrong decisions. If those inputs and false decisions were retained, we would re-invoke validation on those records. We would not guess what the old helper would have done on them, because we have the raw values.
The point here is: we do not retroactively change history blindly. We identify which stored decisions could be wrong by inspecting what was run. Then we rerun only those inputs through the correct validator. We preserve a record of both old and new decisions for compliance/audit. This is the “REVALIDATE” step. The script above is a model; in practice, one would apply it to the real dataset.
Make the acceptance gate fail on the first wrong record
Finally, our acceptance criteria: we will fail the gate (i.e. not push this validator to production) if any record in any run differs from expectation. In code, for each run:
for (const {id,value,expected} of fixture) {
  const actual = validate(value);
  if (actual !== expected) {
    throw new Error(
      Validation error on record ${id}:  +
      expected ${expected}, got ${actual}
    );
  }
}
We do this for forward, reverse, repeat, chunks. If any throw occurs, we stop and mark the test as failed. We require all of: correct forward order behavior, reverse order, repeated runs, and no coercion or type issues. We also check the negative controls (e.g. R3, R5, R6 remain false). A repair that blindly returned true for everything or that accepted all strings (like regex.test("") hack) would not pass, because R3 (lowercase) or R5/6 should stay false.
For our stateless helper, no error is thrown. For the old wrong helper, the first check of R2 would throw. That is unacceptable. Hence, we choose REPAIR for the faulty helper. (We do not ACCEPT it as-is, since it fails.) There is no unsupported assumption to HOLD on (we have no evidence of an engine bug), so HOLD does not apply here. And because the old helper only denied valid inputs, REVALIDATE would focus on making sure those denials are now corrected; as discussed, nothing was incorrectly accepted.
In summary of actions:
14. ACCEPT the stateless regex approach: it meets the contract for all records in all scenarios, given our fixed grammar.
15. REPAIR: we recommend dropping the g/y flags (or otherwise resetting state) in any field validator. This assigns ownership of the regex state to the function itself.
16. HOLD: if we had seen something like a weird engine idiosyncrasy, we would mark and investigate it. We do not claim all JS is safe, only that our tested platforms behave as documented. We would hold if, say, some unknown normalization affected matching.
17. REVALIDATE: data accepted or rejected under the old logic should be re-checked if there's any doubt. In practice, for our case, we may audit no accepted records (since none were wrongfully marked valid), but if our logic had been opposite, we’d do it now.
This structured decision makes it clear what next steps are. We do not simply say “validation is done.” Instead, we commit to versioning our grammar and code. That is the next topic.
Own the validator and its release evidence
Whenever releasing a validator like this, we should version control the grammar, helper code, and manifest together (e.g., in a repository). Tag the commit that contains the fix. Document who owns the code (e.g. "Frontend team, regex-validator.js v1.0.2") so the contract is clear. If we have server-side validation, ensure it uses the same pattern or a stricter one. Ideally we’d have a sharing mechanism (e.g. an npm package or a common utilities module) so one regex def is authoritative.
After fixing, we should rerun our entire test matrix whenever anything changes: if the regex pattern changes, if flags or normalization logic are updated, or if the environment moves (e.g. a new Node or browser engine). In particular, if a future developer inadvertently adds a g or changes the pattern, our suite of tests would catch it immediately. Also, if we later integrate this validator into a form library or framework, we should re-verify that the shared instance issue cannot creep back in (some frameworks might cache or reuse modules in odd ways).
If ever rolling back to an old version (disastrous but possible), ensure that this bug is not silently reintroduced. Tag the release so we know exactly what code was shipped at which version. For example, in package.json or comments:
// validator v1.0.2 (fixed stateful regex issue)
// Confirmed on Node v22.16.0 / V8 12.4
This exercise echoes contract-first integration practices applied to RegExp.test() and stateful RegExp execution. We took a concrete input contract (six-char code), wrote tests up front, and validated code against it. This pattern (define grammar, independent oracle, exhaustive tests, version everything) is a strong frontend validation foundation. It is exactly the kind of skill and methodology taught in the FrontEnd Developer Program's JavaScript and integration curriculum (covering ES6+ validation techniques and best practices). The same disciplined approach applies whether you're validating user input, API parameters, or component props.
Connect the exercise to stronger frontend foundations
We have seen that a tiny detail, a forgotten g flag, can break a supposedly simple check. By carefully defining our contract, writing independent tests, and checking across execution paths, we turned a brittle validator into a robust one. This level of rigor is what separates flaky code from production-quality code. It’s also exactly the mindset taught in modern frontend training: understand JavaScript deeply (RegExp quirks included), build small reproducible examples, and verify assumptions in multiple environments.
If you're interested in systematically mastering these kinds of patterns (from vanilla JS to integrated frontend frameworks, with a curriculum that includes topics like this), consider the FrontEnd Developer Program. It covers HTML5/CSS3, ES6+ JavaScript, React, Redux, API integration, and more, all through guided projects and practical work. Courses like this one emphasize test-driven design and state management in the frontend, so that you write validators and components with confidence.
In summary: our final decision is to ACCEPT the stateless validation contract (2 uppercase letters + 4 digits, no extra state), REPAIR any reused regex by dropping g/y (or resetting), REVALIDATE any possibly mis-evaluated records, and HOLD if any unproved assumption about engine behavior comes up. Through reproducible tests, the ECMAScript specification, and MDN’s guidance on RegExp.test() and stateful RegExp execution, we ensure the validator is bulletproof. This completes our operational playbook on curing stateful lastIndex bugs.