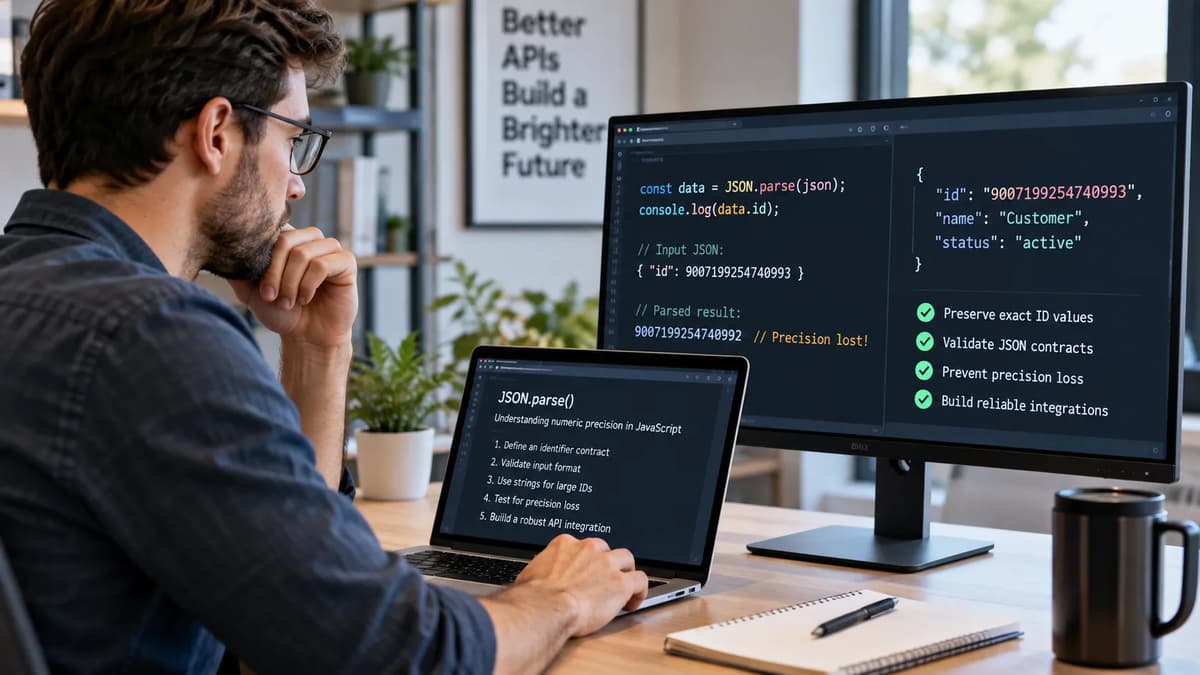
JSON.parse may succeed without error even when a numeric identifier has been altered. The key difference is between successful parsing and exact identity preservation. In particular, opaque identifiers made of decimal digits cannot tolerate rounding. JSON itself does not forbid large integers; in fact, RFC 8259 explicitly allows implementations to accept numbers within the IEEE‑754 double range. However, RFC 8259 also notes that only integers in [–(2^53)+1 … (2^53)–1] are guaranteed to have identical values after parsing. JavaScript’s Number type matches this: Number.isSafeInteger() returns true only up to ±(2^53−1). Thus, if a producer sends { "id": 9007199254740993 }, parsing it in Node.js (v22.16.0) results in id = 9007199254740992, silently dropping the last digit. Such a drop would violate an exact-ID contract, because the missing digit means two distinct tokens have become one.
We will test how JSON.parse affects large integer IDs and construct a contract test suite. First we create raw JSON payloads and an independent oracle of the expected ID text. Then we demonstrate the conventional (faulty) parse path and show the two IDs collapsing into one application key. Next we show why simply converting the parsed Number back to string or BigInt cannot recover the original ID. Our primary solution is to change the producer contract: identifiers must be quoted decimal strings with a known grammar and bounded length. Consumers can then either accept numeric input with care or hold unsafe ones for replay. We will also probe a newer feature: JSON.parse’s reviver with a third context argument provides access to the original token text. With it, a source-aware adapter can precisely restore the ID on the wire. Finally, we ensure that JSON.stringify never reintroduces loss: by default it throws on BigInt, so we explicitly emit the ID as a string.
Our code examples are runnable in Node.js v22.16.0 (V8 engine). We report process.version, process.versions.v8, and a feature-probe for the reviver context support. We avoid browser-specific assumptions. We include negative-control cases for missing, null, object, fractional, exponent, or noncanonical IDs, each with a clearly defined decision. The resulting test code logs the expected vs actual IDs and halts if any discrepancy is found. By the end, you’ll have a complete acceptance/repair playbook for large numeric IDs that fits into a production-grade API testing workflow.
Define an identifier contract before choosing a parser
The root cause of hidden errors is a vague contract. A contract-first approach means you decide what an ID is before parsing JSON. If an “ID” field is just defined as a number, consumers will happily parse it, unaware that precision was lost. Instead, declare that this ID domain is exactly decimal digits (and, say, no leading zeros or signs). This is in line with API-first contract design principles: the API spec should precisely describe each field. For an ID, the canonical representation might be “a nonnegative integer in base 10, with 1–32 digits”. Changing any digit transforms the identity. In practice, acceptance of an ID must be decided before you use it to index, join, or store. In our test suite, we will compare the raw manifest text to the final key, not stop at the parse success. Only if the entire string of digits passes the contract is the row accepted.
For example, an API-first design would document "id": "9007199254740993" as string in the schema (or {type: "string", pattern: "^(0|[1-9][0-9]*)$"}), rather than leaving it as integer. This way, all clients treat IDs the same: as exact text. If the producer or consumer can’t handle quoted IDs, that’s a compatibility issue to resolve deliberately. The acceptance boundary is before any database write, cache key assignment, or outgoing API call. In testing, we assert that record count and unique key count match only if IDs are distinct in the manifest. If we detect a mismatch (e.g. two JSON numbers parsed to the same Number), we flag failure. (Think of it as a commit checklist: “did the parsed keys exactly match the source keys?”) Ultimately, if digits change, we refuse to proceed, since the identity invariant would be broken by later logic.
Separate JSON numeric syntax from JavaScript representation
JSON’s grammar permits any sequence of digits (with optional sign) as a number token, even beyond 64 bits. But JavaScript’s Number uses IEEE‑754 double precision. RFC 8259 explicitly acknowledges that an implementation may have limits and in practice approximates values. Converting to a JS Number will succeed for any valid JSON integer token, but the binary64 cannot hold all digits. In the interoperable range [–2^53+1..2^53–1], all IEEE‑754 implementations agree on value. This matches the MDN definition of safe integers: all integers from –(2^53–1) to 2^53–1 inclusive. By policy we treat this as the boundary: anything outside it is “unsafe” and thus not acceptable to treat as a raw Number in our contract. Note this is not a new JavaScript rule, just our API policy. A parsed Number might pass Number.isInteger() but still be beyond the safe range: e.g. 9007199254740992 (2^53) is an integer, but Number.isSafeInteger(9007199254740992) is false (it rounds 2^53+1 to 2^53).
In summary: a JSON integer is syntactically valid no matter how large, but a JavaScript Number may lose precision. We will enforce that identity-preserving values must either be inside the safe range (if they were numbers) or better yet treated as strings. It is important not to imply JSON forbids large integers; it doesn’t. Rather, our schema forbids them as numbers. (Other systems might allow larger, but in JS these round.) For reference, MDN notes that for larger ints one should use BigInt or string, but crucially, that requires construction from the original text, not from an already-rounded Number.
Create raw payloads and an independent digit oracle
We start by constructing the exact raw JSON string(s) as they would come from the producer, not by serializing JavaScript numbers. For example:
const raw = '[\n'
+ ' { "id": 9007199254740992, "rk": "A" },\n'
+ ' { "id": 9007199254740993, "rk": "B" },\n'
+ ' { "id": 9007199254740991, "rk": "C" }\n'
+ ']';
const expected = ['9007199254740992', '9007199254740993', '9007199254740991'];
console.log('Node version:', process.version, 'V8:', process.versions.v8);
Running this on Node.js v22.16.0 (our test environment) prints something like v22.16.0 V8 12.x. We also probe whether the reviver context feature exists:
let contextSupported = false;
JSON.parse('{"x":0}', (k, v, context) => {
if (context && 'source' in context) contextSupported = true;
return v;
});
console.log('reviver.context.source supported:', contextSupported);
On our Node, this logs true (the new third argument is supported). These checks are printed at start of our tests for documentation.
Next, we parse the raw payload in the legacy (numeric) way:
const parsed = JSON.parse(raw);
console.log('Parsed records:', parsed);
// Show each id value, its type, and safe-integer result
parsed.forEach(item => {
  console.log(
    rk=${item.rk}, parsed id=${item.id}, type=${typeof item.id},  +
    safeInteger?=${Number.isSafeInteger(item.id)}
  );
});
Importantly, we never initialize the expected ID list from JavaScript numeric literals above 2^53. The expected array is hard-coded as strings. This is our oracle of truth; it was never subject to rounding. Keep this oracle separate from any code path that sees the lossy Number.
By pairing each expected ID with a stable rk key, we prevent a second record hiding behind the first in a simple count check. Even if the two large numbers round to the same Number, their rk values differ. Thus our assertions check record keys, not just raw count. If parsed.length !== expected.length or any key or expected string differs, we know something went wrong.
Keep the oracle outside the lossy path
Never derive the expected ID strings by computing large numbers in JS. If you wrote const expected = [9007199254740992, 9007199254740993], those numeric literals would already be rounded to the same Number in the source code! Always treat the expected IDs as immutable strings from the manifest.
Watch two wire IDs collapse into one application key
Now we demonstrate the failure of the naive parse. Given our parsed array from above, both the first ("rk":"A") and second ("rk":"B") records have the same id value 9007199254740992 (because 2^53+1 rounded down). For example:
console.log('ID values after parse:', parsed.map(o => o.id));
// Check duplicates via a Set
const distinctKeys = new Set(parsed.map(o => o.id));
console.log(
'Distinct ID count:', distinctKeys.size,
'Original record count:', parsed.length
);
You will see 2 distinct IDs (9007…992 and 9007…991) instead of 3. The second record’s ID has silently become identical to the first. If you then did const map = new Map(parsed.map(o => [o.id, o.rk]));, the entry for id=9007199254740992 would be overwritten by the second record (losing "A"). This is the collision we aim to catch. Even more subtle: each item still “exists” in the array, so a simple row count (3) didn’t change, but the unique key count (2) did.
Here we label this failure as HOLD (not accept), because the contract for the numeric ID did not hold exactly. We log details explicitly for debugging:
console.log(
'Row count =', parsed.length,
'but unique ID keys =', distinctKeys.size
);
parsed.forEach(o => {
console.logrecord ${o.rk}, id (parsed)=${o.id});
});
This reveals that two different manifest IDs collapsed to the same Number. By contrast, the safe-boundary record (rk="C" with 9007199254740991) remains distinct and safe. In code, we could assert:
console.assert(distinctKeys.size === expected.length, 'ID collision detected');
This flags the error (an expected failure in our test harness). This shows that a naive Map/Set on parsed values is insufficient to guarantee identity.
Reject repairs that start from an already-rounded Number
Some might try to “fix” the issue by string-converting or BigInt-ing the parsed value. But that’s circular if the value is already wrong. In our case, both parsed IDs are the Number 9007199254740992. For that value:
let v = parsed[0].id; // 9007199254740992
console.log('String(v) =', String(v));
console.log('BigInt(v) =', BigInt(v));
Both produce "9007199254740992" (9007199254740992n). Converting the rounded Number to string or BigInt yields exactly the same truncated result, not the original 9007199254740993. Both calls agree, but they never recover the lost digit. We are seeing here that “String” and “BigInt” on a Number only reflect the (already truncated) Number, not any independent source. This evidence is circular: it cannot prove the original was different. Hence we cannot accept or trust any transformation that starts from that Number.
We check at runtime that parsed[0].id === parsed[1].id (true) and that both Number.isSafeInteger(parsed[i].id) are false for the two unsafe IDs. Even though 9007199254740992 is representable, it lies outside the strict safe range, so our policy still forbids it. In effect, the question of “should we accept 9007199254740992 as an ID?” is moot: the contract required exact text, not any rounding. Thus, if we ever find the field as a Number that’s unsafe, we reject it. Converting it now to a BigInt or string is not a “repair” but a cover-up. In our playbook, the answer is to HOLD (stop processing) if the only evidence is an unsafe Number.
Move the primary contract to exact decimal strings
The robust solution is to have the producer send IDs as JSON strings rather than bare numbers. For our payload, that means quoting the values:
const rawStrings = '[\n'
+ ' { "id": "9007199254740992", "rk": "A" },\n'
+ ' { "id": "9007199254740993", "rk": "B" },\n'
+ ' { "id": "9007199254740991", "rk": "C" }\n'
+ ']';
const parsedStrings = JSON.parse(rawStrings);
parsedStrings.forEach(item => {
console.logrk=${item.rk}, id="${item.id}" (${typeof item.id}));
});
Now each id is a string in JavaScript, so no precision is lost. We then apply application-level validation: for example a regex ^(0|[1-9][0-9]{0,31})$ to enforce no leading zeros and max length 32. In this example, "9007199254740992" and "9007199254740993" both pass, as does "9007199254740991". This string-typed contract means the system treats the ID purely as text: comparisons, joins and storage use the digit sequence exactly. Notice that we have not rewritten all numeric fields in the API to strings, only the ones defined as exact ID fields. A global rewrite of every number would be excessive.
Because the ID is now a string, when we later do JSON.stringify on an object containing it, the ID is emitted with quotes in the JSON. (We still name it “id” in JSON, but its type is now string.) We consider this a contract change on the wire: numeric consumers must be updated to accept a string here. Until then, numeric input should be handled on a transitional branch or versioned schema.
Canonical strings are a declared API policy
We specify exactly how an ID-string is formed. For example, the grammar /^(0|[1-9][0-9]{0,31})$/ allows “0” or a nonzero digit followed by up to 31 more digits, totaling 1–32 digits. Negative values, exponents, decimals or leading zeros are all rejected by policy. This ensures only one textual form corresponds to each intended ID.
Migrate consumers without mixing old and new meanings
Changing the field type in production requires a controlled migration. The API version or schema must clearly indicate that id is now a string. Consumers must be inventoried: which systems send numeric IDs, and which expect numeric? While both old-style and new-style clients coexist, use an adapter that explicitly handles each format. For example:
function parseIdField(key, value) {
  if (key !== 'id') return value;
  if (typeof value === 'string') {
    // New format: validate and accept
    return value;
  }
  if (typeof value === 'number') {
    // Legacy format: only accept safe numbers, convert to string
    if (Number.isSafeInteger(value)) {
      return String(value); // could accept or still hold by policy
    } else {
      throw new Error('Unsafe numeric ID (context unavailable)');
    }
  }
  // Any other type is invalid
  throw new Error('ID field has unexpected type');
}
const unified = JSON.parse(rawPayload, (k, v) => parseIdField(k, v));
In a real migration, you might reject all numeric IDs and require an interim 422 or version bump. But if you allow legacy numeric input, do so only under tight control: never fall through to use a bad Number unchecked. For now, our test assumes the contract has changed to string, and any numeric value triggers HOLD.
Importantly, do not perform a blanket post-parse replacement like BigInt(item.id). That can’t recover digits, as we saw. Also do not attempt to sniff “maybe the number was meant to be 01...”. The only safe “repair” is to go back to the original payload (or an authoritative upstream), which we do next via the reviver technique. Our approach is: if the field is not already a string matching the grammar, we reject it outright (and thus do not write any side effects). This matches secure validation practice, not a silent coercion.
Gate source-aware revival on actual runtime support
Since Node v22.16 provides context.source, we can use it to recover original text for numeric tokens. Feature-detect it (as above). With it, a JSON.parse reviver can preserve IDs exactly:
const recovered = JSON.parse(raw, (key, value, context) => {
if (key === 'id' && typeof value === 'number') {
return context.source; // preserve exact text
}
return value;
});
console.log('Recovered IDs:', recovered.map(o => o.id));
This yields ['9007199254740992','9007199254740993','9007199254740991'] as strings, restoring both large IDs exactly. Note we return context.source (a string of digits) for numbers, not converting any quotes. If value is already a string (in a mixed or future payload), we just return it. The reviver ensures other fields pass through unchanged.
However, if the feature were unsupported, we must not quietly fall back. For example, a traditional two-argument reviver or no reviver would leave the values as Numbers (recovering nothing). In that case we treat the situation as “HOLD”: refuse to use the rounded ID without clear source text. We do not default back to String(value). Our code branches on contextSupported; if false, we skip or error on unsafe IDs rather than assume they are okay. In practice, this means a consumer must either upgrade to a runtime with this feature or must not handle large IDs at all.
The third reviver argument changes the recovery boundary
A JSON.parse reviver with two parameters sees only the already-parsed values. But with three parameters (key, value, context), context.source gives the original token. In Node’s environment this feature is available, so we recover both large IDs. If we dropped to a traditional reviver, we would see the rounded number and have lost the chance. Thus context-aware parsing can repair at the wire, moving us from HOLD back to ACCEPT for these cases (because we verify the text exactly). Without it, those cases remain HOLD.
Serialize approved IDs without reopening the precision loss
Once we have an object with our validated ID (now a string or safe value), we need to output it. A pitfall: JSON.stringify will throw if it encounters any BigInt. MDN warns that any BigInt in the value causes a TypeError. Indeed:
let obj = { id: 9007199254740992n };
try {
console.log(JSON.stringify(obj));
} catch (e) {
console.error('Error on BigInt stringify:', e.message);
}
This shows something like TypeError: Do not know how to serialize a BigInt. We avoid that by never putting a BigInt directly into JSON. In our contract, the ID should now be a string, so JSON.stringify({id:"9007199254740992"}) safely yields {"id":"9007199254740992"}. If for some reason we still have a BigInt in a data structure, we would need a replacer:
const safeJson = JSON.stringify(obj, (k, v) =>
typeof v === 'bigint' ? v.toString() : v
);
console.log(safeJson); // JSON with bigint as decimal string
But note: this is a field-scoped workaround, not a global patch. We do not monkey-patch BigInt.prototype.toJSON because that can hide bugs. Instead, our code will ensure that IDs are already strings. After serialization, a second parse (in whatever sink or consumer) should again see the ID string "9007…" and handle it normally. We assert that after stringify and reparse, the ID still matches expected. Any step that converts it back to a Number would be treated as a new failure.
Exercise malformed, ambiguous and oversized identifiers
Robust validation means testing negative scenarios. Consider cases where id is missing or in the wrong format. We build a matrix of test cases and expected decisions:
Case | Record | Raw token or string | Expected ID | Parsed | Safe | Normalized ID | Outgoing | Distinct | Reviver | Decision |
01 | A | no id field | – | – | – | – | – | 0 | – | Hold (absent) |
02 | B | null | – | object (JS) | false | – | – | 0 | – | Hold (null) |
03 | C | {} (id is object) | – | object | false | – | – | 0 | – | Hold (invalid) |
04 | D | 123.45 | – | number | false | – | – | 0 | – | Hold (fraction) |
05 | E | 1e3 | – | number | true | – | – | 0 | – | Hold (exponent) |
06 | F | "01" (leading zero) | – | string | N/A | – | – | 0 | – | Hold (noncanonical) |
07 | G | "9007199254740992" | 9007199254740992 | string | N/A | "9007199254740992" | string | 1 | no | Accept (string) |
08 | H | -5 | – | number | true | – | – | 0 | – | Hold (negative) |
09 | I | "123456789012345678901234567890123" (33 digits) | – | string | N/A | – | – | 0 | – | Hold (too long) |
Column notes: “parsed_type” is the JavaScript type after JSON.parse. “safe_integer?” means Number.isSafeInteger (only applies to numbers). “normalized_id” is the contract-approved string (if any). “outgoing_type” is the JSON type we would output. “distinct_count” tracks how many unique IDs we would have so far. “reviver_used” indicates if source text revival applied (for numeric cases). We see that any record lacking a valid decimal string is rejected (Hold). Even for case 07 where a valid string is provided, we accept it and use it as-is.
Specifically, we distinguish:
• Missing or null ID means we can’t proceed: hold.
• Object, fractional or exponent IDs (cases 03–05) are malformed by our decimal grammar: hold.
• Noncanonical string (leading zero) also fails grammar: hold.
• Overlength string (33 digits) fails our length check: hold.
• Negative number fails the “nonnegative” policy: hold.
• Only a properly formatted string of digits (case 07) is accepted.
We implement these checks in code. For example:
const idPattern = /^(0|[1-9][0-9]{0,31})$/;
parsedData.forEach(({rk, id}) => {
if (typeof id !== 'string' || !idPattern.test(id)) {
console.logRecord ${rk} rejected: id=${id});
} else {
console.logRecord ${rk} accepted: id='${id}');
// add to ledger, etc.
}
});
Unsafe numeric values cause an immediate stop before any side effects (no console logging of “accepted” in our harness). The decisions above are expected for each test. We do not weaken the validator to let any fail through; each hold case we label is intentional.
Reject unsafe legacy numbers before writing
Our acceptance wrapper must prevent any unsafe or malformed ID from reaching downstream. In the code above, if the grammar check fails, we never push the record into the result ledger or database. This simulates a transaction rollback or error response, ensuring partial bad data does not slip through.
Reconcile evidence before allowing side effects
After parsing and validating each record, we compare against our oracle. We expect to see exactly the expected array of strings, in any order (or keyed by rk). We can build a ledger of accepted IDs:
const accepted = [];
parsedStrings.forEach(({rk, id}) => {
if (idPattern.test(id)) {
accepted.push(id);
}
});
if (accepted.length !== expected.length ||
!expected.every(v => accepted.includes(v))) {
throw new Error('ID sequence mismatch or missing values');
}
Only if this check passes do we “write” the data. In our simulated sink, we might push each record to an array or database. We assert that after all processing, the sink received exactly one entry per accepted row. For example:
const sink = [];
parsedStrings.forEach(({rk, id}) => {
if (idPattern.test(id)) {
sink.push({rk, id}); // simulate writing to DB
}
});
console.log('Sink records:', sink);
We confirm the sink has three distinct IDs of type string. If the sink had fewer records, or duplicate IDs, the check before writing would have failed. This reconciliation ensures application-key uniqueness and expected values are verified before any commit. We do not rely on a promise of order or any missing error to silently pass. Any discrepancy halts the test.
Recover from the source, not from plausible digits
If an ID is flagged hold (for being unsafe or malformed), the recovery strategy is not to guess digits but to try to replay from an authoritative source. In production, this might mean rejecting the client request and asking them to resend with quotes, or retrieving the original payload from an authenticated log. For example, if reviver.context were unavailable, we’d have to fail now and wait for a retried request. If logs of the raw JSON (the “manifest”) exist, we could parse that fresh. But if only the rounded Number is stored downstream, we cannot reconstruct the original ID with certainty. We do not attempt to reconstruct by, say, scanning the database for a neighboring key or inferring the "+1". Such heuristics are unsafe and out of scope.
Instead, the rule is: stop the faulty write, log the incident, and treat the event as requiring manual or upstream correction. In the context of our test suite, any row with an unsafe ID is not written to our sink. We can log an error like “Record X held due to ID rounding.” That is the evidence we capture. Later, an operator or system can “replay from source” by finding the raw JSON. If no raw source is available (e.g. the client did not send it properly, or we only saw a truncated value), then we simply have to maintain the hold.
No raw source means no reconstructed identifier
Only when we have the exact JSON text can we be sure of the ID. In our test, the context.source reviver gave us that text. If we lacked that, the “Hold” decision remains and we would use the original manifest (or a fallback like a secure ID service) to obtain the true ID. Any repair from plausible digits (like assuming an increment) is explicitly disallowed.
Turn preservation checks into an owned release gate
Finally, use these checks as a release criterion. Build a decision matrix combining evidence and responsibility:
• Accept: ID came in as a string matching grammar (or safe legacy number that we’ve explicitly allowed). Evidence: typeof id==='string' && grammar.test(id). Responsibility: API producer ensured format.
• Repair: ID was numeric but context.source recovery was available. We rewrite it to string. Evidence: reviver branch used. Responsibility: consumer code applied the adapter.
• Hold: ID was numeric unsafe or malformed string. We reject and do not write. Evidence: grammar/length failed, or safe check failed. Responsibility: consumer API guards, possibly triggering a revalidation or error response.
• Replay: No valid ID available (hold case where the payload is gone), so we must fetch the correct ID from an upstream source or log. Responsibility: human/data team to restore consistency.
Record-keeping of payload digests or logs can help correlate records, but a hash of bytes only proves which JSON came in, not whether its digits were correct. Still, we might require a payload checksum as part of our audit trail. Performance-wise, these validation steps (regex test, set membership, etc.) are trivial compared to I/O and business logic. The priority is semantic safety: it’s far better to block one bad row than to quietly violate data integrity. Of course, extremely high-throughput endpoints might batch or parallelize these checks, but the logic itself remains straightforward.
Build stronger API contracts with guided practice
In summary, preserving large numeric IDs requires defining them as exact strings, validating them at parse time, and using source-aware parsing when possible. This pattern enforces the invariant: what went in is exactly what came out. For hands-on practice with API design, validation and versioning (as covered here), consider Refonte Learning’s APIs Developer Fundamentals program. It includes modules on API design, documentation, testing and error handling. Master these principles there, and you’ll be well-prepared to implement contracts that keep every digit intact.