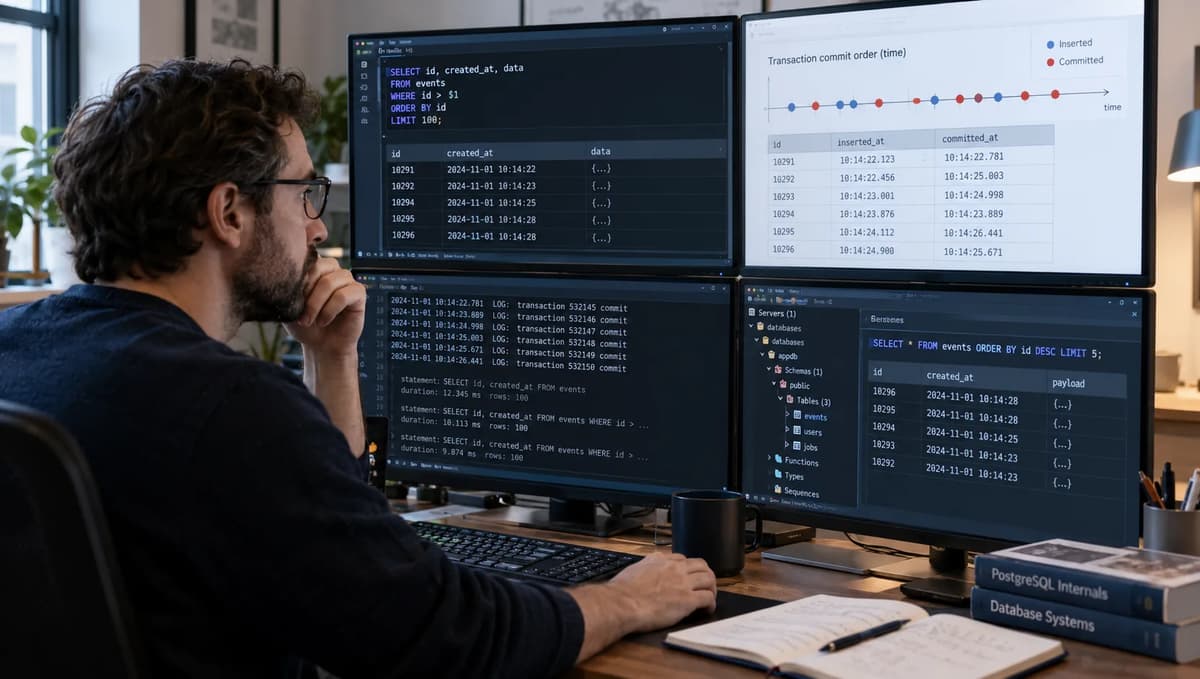
PostgreSQL’s sequences are designed for generating unique IDs, not for establishing commit order guarantees. In many database integration contracts, engineers use a numeric ID column as a “watermark” checkpoint, assuming that once an ID is persisted, no row with a lesser ID can appear later. However, PostgreSQL explicitly separates sequence allocation from transactional row visibility. A nextval call (e.g. during an INSERT) allocates a new ID immediately, and that allocation is not rolled back even if the transaction aborts. Moreover, one transaction’s committed ID is visible to others immediately, while uncommitted rows remain hidden. As a result, it is entirely possible for a lower-numbered row to commit after a higher-numbered one. An incremental reader using WHERE id > last_seen would then skip the later-committing lower ID forever.
We will demonstrate this concretely with a controlled lab: three concurrent sessions (A, B, C) inserting two events with sequential IDs. Despite both inserts eventually committing, our reader (session C) will advance its checkpoint to 102 after seeing only the second insert, permanently missing the first. We will define an independent “manifest” of expected rows, and show how a later reconciliation uncovers the omitted row. Finally, we’ll decide whether to HOLD the live checkpoint contract, REPAIR the extraction design, RECONCILE the closed population, or ACCEPT only a fully audited result. All code and observations below are reproducible in PostgreSQL 18 with explicit sequence and isolation settings.
Define the completeness claim hidden in an ID checkpoint
The hidden assumption in an ID-based watermark is: if the reader has recorded a checkpoint of 102, then all committed events with id <= 102 must be visible. In other words, the reader treats IDs as a closed committed prefix. This claim goes beyond mere uniqueness or sort order of IDs; it asserts exact event membership and payload equality. For completeness, our acceptance criterion will be that the sink contains exactly the same (id, event_key, payload) rows as the source. We will verify this against an independent manifest of approved events.
By default, PostgreSQL enforces unique IDs and allows queries like ORDER BY id, but that does not prevent later commits of smaller IDs. Crucially, sequences in PostgreSQL are not rolled back: “because nextval and setval calls are never rolled back, sequence objects cannot be used if gapless assignment of sequence numbers is needed”. We will use a manifest listing the expected (id, key, payload) of each event. This oracle, not the numeric value 102 alone, defines correctness. Thus, our reader must deliver each event’s identity and payload; merely reaching a high ID is insufficient.
Build a shared three-connection PostgreSQL fixture
We set up a fresh owned schema and objects in PostgreSQL 18 to run the experiment. We do not use temporary tables, because sessions A, B, and C must see the same shared tables. We start by aborting if the schema already exists, then creating it, the sequence (cache=1, no cycle), and tables. We record the actual server version and ensure READ COMMITTED isolation is used (the default). A fresh reader_state table holds the checkpoint. For reproducibility, we commit all setup before starting the schedule.
-- Setup: use one session to create schema and tables (committed)
DO $$BEGIN
  IF EXISTS (SELECT 1 FROM information_schema.schemata
             WHERE schema_name = 'lab_id_watermark') THEN
    RAISE EXCEPTION 'Schema lab_id_watermark already exists';
  END IF;
END$$;

CREATE SCHEMA lab_id_watermark;
CREATE SEQUENCE lab_id_watermark.event_id_seq
  AS bigint START WITH 101 INCREMENT BY 1 NO CYCLE CACHE 1;
CREATE TABLE lab_id_watermark.events (
  id        bigint PRIMARY KEY DEFAULT nextval('lab_id_watermark.event_id_seq'),
  event_key text NOT NULL UNIQUE,
  payload   integer NOT NULL
);
CREATE TABLE lab_id_watermark.sink (
  id        bigint NOT NULL UNIQUE,
  event_key text PRIMARY KEY,
  payload   integer NOT NULL
);
CREATE TABLE lab_id_watermark.reader_state (
  reader_name text PRIMARY KEY,
  last_id     bigint NOT NULL
);
INSERT INTO lab_id_watermark.reader_state VALUES ('reader-C', 100);
COMMIT;
We set application_name in each session so we can identify them in logs. We also display the current isolation level and backend PID for documentation. For example:
-- Connection A: set identity, show isolation and PID
SET application_name = 'writer-A';
SELECT current_setting('application_name') AS app,
       pg_backend_pid() AS pid,
       current_setting('transaction_isolation') AS iso;
-- Expected: app='writer-A', isolation='read committed'
(We repeat similar identity queries in sessions B and C.) This setup follows best practices for controlled tests, akin to recommendations in database administration fundamentals. All objects are real (non-temp) in lab_id_watermark, and the schema is committed before any transactions begin.
Do not isolate the participants with temporary tables
We must use ordinary (schema-qualified) tables so all sessions A, B, C share the same data. Temporary tables would be session-local and invisible elsewhere, defeating the concurrency demonstration. By using a common schema and committed setup, we ensure each session observes the same object definitions and can coordinate. If the schema had existed already (perhaps from a stray run), we abort rather than drop it, to avoid side effects on unknown data.
Write the source and sink manifests before polling
Before executing the steps, we define an independent manifest of the expected committed events in this test run. We declare that the closed-cohort source population should be exactly two events:
event-A with (id=101, event_key='event-A', payload=10)
event-B with (id=102, event_key='event-B', payload=20)
This manifest is our approved fixture. We will compare the source and sink contents against it. (In a real pipeline, such a manifest might come from a controlled dataset or previous export; here we hardcode it.)
-- Independent manifest of expected (id, key, payload) for the full run:
SELECT 101 AS id, 'event-A' AS event_key, 10 AS payload
UNION ALL
SELECT 102, 'event-B', 20;
We also clarify sink and state constraints: sink.id is UNIQUE and sink.event_key is primary key, preventing duplicate inserts. The reader_state table ties the sink to the last processed ID per reader. Our initial last_id is 100 (no events consumed yet). The manifest defines identity and payload as the true acceptance target; our reader must reproduce those exactly.
Allocate the lower ID and keep its transaction open
We begin our schedule by having Session A insert the lower ID row and keep that transaction open. This allocates id=101 but does not commit yet.
-- Session A (writer-A)
BEGIN;
INSERT INTO lab_id_watermark.events(event_key, payload)
VALUES ('event-A', 10)
RETURNING id;
-- Expected output: id | 101
-- This INSERT has allocated id=101 in A's transaction. We do NOT COMMIT yet.
The RETURNING id shows 101 to Session A. At this point, A’s session knows the new row and its ID. However, because A has not committed, other sessions cannot see event-A. The returned ID is A’s view only; it is not a global commit acknowledgement. We do not commit A yet. We also do not use any sleep or timing tricks; instead, we simply wait for this statement to complete (so we know ID=101 is allocated) before moving to the next step. This explicit ordering ensures determinism: we have completed step 1 (allocation) before step 2 begins.
Use an explicit schedule rather than a sleep race
To make the experiment deterministic, we manually sequence the actions. Once Session A’s insert returns 101, we proceed to Session B. We do not rely on pg_sleep or any race conditions. This manual coordination (waiting for the RETURNING output) is equivalent to a synchronization point. It guarantees that A’s insert is done (but uncommitted) before B starts. This controlled scheduling is like following a choreography of statements, not a timing hack.
Commit the higher ID before the first reader pass
Next, Session B begins and inserts event-B. Crucially, B will commit before A does. Because event_key is unique, B’s insert does not conflict with A’s insert (they have different keys), so B can safely complete out of “ID order”.
-- Session B (writer-B)
BEGIN;
INSERT INTO lab_id_watermark.events(event_key, payload)
VALUES ('event-B', 20)
RETURNING id;
-- Expected output: id | 102
COMMIT;
-- Session B has committed event-B with id=102.
Session B will output id = 102. Immediately after COMMIT, event-B is visible in the database. There was no conflict or locking issue, since event-A (id=101) was uncommitted in another session. B’s success shows that PostgreSQL allows independent transactions to allocate IDs in sequence (101, then 102) but commit in the opposite order (102 first). Now, in READ COMMITTED mode, any new query will see the effect of B’s commit but not A’s pending insert.
Advance the reader from a valid but incomplete snapshot
Now Session C (the reader) runs its first poll, still with last_id = 100. We execute it in one transaction to simulate a snapshot read plus sink update.
-- Session C (reader-C begins its consumer transaction)
BEGIN;
SET application_name = 'reader-C';
SELECT current_setting('application_name') AS app,
       pg_backend_pid() AS pid,
       current_setting('transaction_isolation') AS iso;
SELECT id, event_key, payload
FROM lab_id_watermark.events
WHERE id > (
  SELECT last_id
  FROM lab_id_watermark.reader_state
  WHERE reader_name = 'reader-C'
)
ORDER BY id;
-- Expected result: one row (id=102, event_key='event-B', payload=20)
INSERT INTO lab_id_watermark.sink (id, event_key, payload)
SELECT id, event_key, payload
FROM lab_id_watermark.events
WHERE id > (
  SELECT last_id
  FROM lab_id_watermark.reader_state
  WHERE reader_name = 'reader-C'
);
UPDATE lab_id_watermark.reader_state
SET last_id = 102
WHERE reader_name = 'reader-C';
COMMIT;
In this transaction, the SELECT query sees only rows committed before it started. At this point, event-B (id=102) is committed and visible, while event-A (id=101) is not (A is still open). Hence the query returns only the row (102, 'event-B', 20). The reader inserts that row into the sink and updates its checkpoint to 102, then commits. Importantly, we derive the new checkpoint from the actual rows processed, not from the sequence state or last_value. PostgreSQL’s last_value can lag or be ahead if concurrent allocations occur, so we do not use it. Instead, we update last_id = 102 based on what we actually queried. At this point, our sink contains only event-B and the checkpoint is 102.
Bind the checkpoint to the rows actually processed
Notice how we compute last_id here. We did not call nextval or query the sequence; we only used the id from the selected row. This ensures the checkpoint exactly matches what was inserted into the sink. If we had instead done something like SELECT setval('event_id_seq', newvalue), that would not correspond to a committed row. By anchoring the checkpoint on the row's id, we expose the defect: last_id becomes 102 even though a committed row with a smaller ID will appear later. In other words, the checkpoint now falsely claims “all id <= 102 are done”, when in fact event-A (id=101) is still pending.
Commit the missing lower row and poll again
Now we let Session A finish:
-- Session A resumes and commits
COMMIT;
-- Session A (writer-A) has committed event-A (id=101) now.
Event-A is now in the source table. However, our reader’s checkpoint is 102, so it will not see this row with a simple greater-than-102 query. We verify this:
-- Session C tries polling again
SELECT id, event_key, payload
FROM lab_id_watermark.events
WHERE id > (
  SELECT last_id
  FROM lab_id_watermark.reader_state
  WHERE reader_name = 'reader-C'
)
ORDER BY id;
-- Expected result: (empty set, because last_id=102 and no id>102)
For clarity, compare the full source and sink contents:
-- Check full source and sink state after A and B committed
SELECT id, event_key, payload FROM lab_id_watermark.events ORDER BY id;
-- Expected: (101, 'event-A', 10) and (102, 'event-B', 20)
SELECT id, event_key, payload FROM lab_id_watermark.sink ORDER BY id;
-- Expected: (102, 'event-B', 20) only
The source now has both events, but the sink and the reader’s checkpoint only reflect event-B. The repeated SELECT ... WHERE id > 102 returned nothing because the only missing row (id=101) falls below the checkpoint. This illustrates the key issue: the reader’s predicate, not any database error, caused the skip. Event-A is committed and healthy, yet the incremental query logic filters it out.
Distinguish a sequence gap from a skipped committed event
It is important to show that the missing row (id=101) is not a phantom but a real committed event. For contrast, consider two control runs in independent fresh schemas:
Commit in ID order (A then B): Both sessions commit in increasing ID order. Then a query WHERE id > 100 returns 101 and 102 as expected. No row is skipped. This shows that if commits align with allocations, the reader’s method would work.
Rollback the first ID: Session A inserts id=101 then rolls back. Session B inserts 102 and commits. In that case, the manifest of committed events has only id=102 (event-B). The reader, even if it checks id > 100, will correctly find only event-B. The “missing” 101 was never a real event, just a gap from rollback, so no action is needed.
These controls highlight the difference between a gap and a skipped event: an ID that was allocated but rolled back is not owed to the sink, whereas a committed event that fell below the checkpoint is. In our main run, event-A is a skipped committed event, not a rolled-back gap.
Keep CACHE 1 in its proper role
We set CACHE 1 on the sequence to simplify the demonstration (so each nextval increments by 1 without preallocation). This ensures the IDs appear sequentially. However, this choice is not part of the fix. Even without caching, PostgreSQL guarantees only distinct values, not commit order. Our issue would still occur with larger cache. Therefore, CACHE 1 merely avoids confounding factors like out-of-order allocation; it is not a remedy for the problem. Resetting sequences or trying to eliminate gaps via cache are similarly insufficient to fix the reader’s logic.
Reject repairs that lack a completeness boundary
We now consider possible “fixes” one might try, and why they fail without an explicit bound or protocol.
Fixed lookback or overlap: One might attempt WHERE id > last_id - N or >= last_id. But unless N is unbounded, a future lower-ID commit could still escape. Using >= last_id could include the missed event, but complicates duplicate-handling. There is no natural finite N that guarantees coverage without backtracking forever.
Repeated polling: Simply running the same query again (as we just did) won’t help if the predicate omits the row. In our example, even after event-A committed, the query id > 102 still misses id=101. Repeated polls produce no new rows, hiding the fact that something is missing.
Larger batch sizes: Fetching more rows each time only works if one knew exactly what condition to use. Batch size has no effect if the WHERE clause still uses last_id. The missed ID is permanently below the threshold no matter how large each batch is.
Stronger isolation (Repeatable Read/Serializable): Changing isolation level does not fix the logic error. In READ COMMITTED mode, each statement sees a fresh snapshot, but even in REPEATABLE READ the reader would start a snapshot before B’s commit and never see either row. In SERIALIZABLE, the reader might conflict if it tried to re-read, but that does not automatically catch the missing ID. Isolation levels do not convey information about future commits.
Sequence reset or gapless sequence schemes: One could propose resetting the sequence or using a table-locked counter for gapless IDs. These change the allocation pattern, but they don’t establish that commits happen in allocation order. They also break concurrency or introduce other overhead.
Commit-aware extraction: A more complex solution is to have the writer sessions signal completion in some way (e.g. writing to a log table, or having a handshake protocol). That is beyond the scope of a simple ID-filter reader. It would require redesigning the pipeline to treat extraction as a transactional two-phase process, which is essentially building a custom CDC or coordination mechanism.
In summary, none of these alone provides the “closure” guarantee: without a known boundary (e.g. “no more events in this batch”), we cannot assert that id > last_id has caught everything. The fundamental problem is that the reader’s predicate has no knowledge of future commits. We therefore must either limit the problem scope or add explicit reconciliation steps.
Close the population before reconciling the fixture
To ensure correctness, we switch from continuous extraction to a closed-cohort reconciliation. We quiesce all writers (both A and B have now finished) and declare the source population complete. We then compare the full source table against the independent manifest, in both directions, followed by comparing the sink to that same contract. Any discrepancy aborts acceptance.
First, verify source vs. manifest:
-- Declare cohort complete. Compare source vs independent manifest.
WITH manifest AS (
  SELECT 101 AS id, 'event-A' AS event_key, 10 AS payload
  UNION ALL
  SELECT 102, 'event-B', 20
)
-- Rows in manifest but not in source
SELECT FROM manifest
EXCEPT
SELECT id, event_key, payload FROM lab_id_watermark.events;
-- Expected: no rows (source has both events).
-- Rows in source but not in manifest
SELECT id, event_key, payload FROM lab_id_watermark.events
EXCEPT
SELECT FROM manifest;
-- Expected: no rows (no extra unexpected events).
Then, compare sink vs. manifest:
WITH manifest AS (
  SELECT 101 AS id, 'event-A' AS event_key, 10 AS payload
  UNION ALL
  SELECT 102, 'event-B', 20
)
-- Missing in sink (in manifest but not in sink)
SELECT FROM manifest
EXCEPT
SELECT id, event_key, payload FROM lab_id_watermark.sink;
-- Expected: (101, 'event-A', 10), the missing event
-- Unexpected in sink (in sink but not in manifest)
SELECT id, event_key, payload FROM lab_id_watermark.sink
EXCEPT
SELECT FROM manifest;
-- Expected: no rows (sink has no extra events beyond manifest).
The manifest comparison finds that the source matches the approved set, but the sink is missing (101, 'event-A', 10). (If any unknown row had appeared, we would reject the run as contaminated.) At this point, the “known owed” missing row is event-A.
Preserve identity and payload during backfill
We now backfill only the reviewed missing row, preserving its exact data. We do not use ON CONFLICT DO NOTHING or any shortcut, since that might hide an incorrect payload. Instead we insert exactly the missing row:
-- Backfill the missing event into sink
INSERT INTO lab_id_watermark.sink(id, event_key, payload)
SELECT id, event_key, payload
FROM lab_id_watermark.events AS e
WHERE e.id = 101;
-- No error expected, since sink had no event_key 'event-A'.
Now the sink should exactly match the manifest. We re-run the same set comparisons:
-- Verify sink vs manifest after backfill
WITH manifest AS (
  SELECT 101 AS id, 'event-A' AS event_key, 10 AS payload
  UNION ALL
  SELECT 102, 'event-B', 20
)
SELECT FROM manifest
EXCEPT
SELECT id, event_key, payload FROM lab_id_watermark.sink;
-- Expected: no rows (sink now has both events).
SELECT id, event_key, payload FROM lab_id_watermark.sink
EXCEPT
SELECT FROM manifest;
-- Expected: no rows.
All discrepancies are resolved. The sink is now fully reconciled with the manifest. We have not performed any external actions (emails, webhooks, etc.); only this bounded backfill inside the database. This closed-population recovery ensures identity and payload integrity.
Prove the bounded recovery can be repeated
We have performed one reconciliation cycle. To ensure robustness, we repeat the checks. Re-running the EXCEPT queries yields nothing, confirming no extra or missing rows remain. In effect, the INSERT backfill made the sink exactly equal to the manifest. If we were to run the recovery steps again, no additional inserts would occur, and the result would be the same.
This confirms that our fix is bounded: once we close the cohort, we needed only one pass to catch the missing row. (Crucially, this is for the fixed timeframe of these two transactions. It does not imply that the original continuous-checkpoint method is safe for future writes.)
Thus we have a definitive “ground truth” snapshot: source, manifest, and sink all agree on the two events.
Separate reader acceptance from population reconciliation
Finally, we must decide what to do with the reader’s checkpoint contract versus the data reconciliation. The evidence is best summarized in a simple matrix:
Aspect | Source vs. Manifest | Sink vs. Manifest | Action |
Continuous reader | ✓ (after all commits, source matches manifest) | ✗ (sink missing event-A) | HOLD/REPAIR pipeline (contract broken) |
Closed-cohort state | ✓ (manually verified) | ✓ (after backfill) | ACCEPT result |
HOLD: The live last_id=102 contract cannot be trusted to have captured all events. We hold the continuous checkpoint contract as unproved. We cannot simply accept that 102 implies completeness.
REPAIR: The extraction logic or design must be revised. Possible fixes include logging, idempotent upserts, or a completion protocol, none of which were present. The responsibility for this lies with the integration pipeline owner (the engineer who maintains the reader code). A design change (for example, checkpointing by comparing hash totals or using LISTEN/NOTIFY) would need to be implemented.
RECONCILE: We accept the independently-reviewed population (the manifest) and the results of our reconciliation steps. The artifact here is the reconciled snapshot of data, which should be approved by the data owner or steward. This step is now done: we have a certified set of rows.
ACCEPT: Only after full reconciliation do we accept a final checkpoint. In practice, we might set last_id to the highest reconciled ID (102) as a frozen state, with a record of this audit. The data owner or steward signs off on this snapshot.
These verdicts involve different owners: the database or integration team must HOLD the pending data contract; the data engineering team must REPAIR the pipeline code or queries; the data owner or steward must RECONCILE and ACCEPT the reviewed dataset as final.
Use HOLD, REPAIR, RECONCILE and bounded ACCEPT
We summarize as follows:
HOLD the continuous checkpoint: The reading application team cannot treat 102 as a safe watermark going forward. The unproven live contract is on hold. (Artifact: the “live” checkpoint state; Owner: integration developer.)
REPAIR the extraction design: The data integration engineers must modify the process (for example, add an audit query or a message log) to prevent this class of error. (Artifact: revised extractor code/contract; Owner: integration developer.)
RECONCILE the closed population: We have already compared to the manifest and backfilled the missing event. (Artifact: reconciliation report and final sink contents; Owner: data steward or analyst.)
ACCEPT only the bounded result: We accept last_id=102 only in the context of this verified snapshot. Future commits require a new checkpoint process. (Artifact: approved snapshot of source=sink; Owner: data owner.)
By explicitly separating the continuous extraction contract (HOLD) from the audited static snapshot (RECONCILE→ACCEPT), we avoid pretending the original streaming checkpoint was valid. Each artifact is tied to its owner, and no data is assumed safe without verification.
Assign the checkpoint and recovery owners
These responsibilities map to roles familiar in backend persistence foundations. The database operator or developer runs the SQL and migration scripts (they executed the queries above). The integration maintainer (developer or data engineer) owns the reader application and must amend it if necessary. The source producer (application team that inserted event-A/B) bears no blame here, since they did commit the data; they simply happened to commit after the reader advanced. The data owner or steward is the ultimate authority on what the “ground truth” should be.
We also record the reader’s version and predicate in our logs. For example, a tuple (reader-C, last_id=102, query="id > last_id") with timestamp is an artifact of this run. If code is rolled back or replaced, it does not magically recover lost data; any replay would need the same reconciliation protocol. In practice, one might add a checksum or include a backfill script in deployment.
In short, the integration team updates the checkpointing code, the DB team runs reconciliation, and the data steward approves the final dataset. Future runs should not auto-trust the ID watermark without an attached guarantee or bound.
Build database integration and recovery foundations
We have shown the precise boundary: we accept only what can be verified against a closed, known population. The accepted state is that both events A and B are in the sink, matching the manifest, with last_id=102 final. This outcome relies on careful SQL and reconciliation, not on an assumed property of the sequence.
For database professionals, these are fundamental skills: understanding transaction visibility, sequence behavior, and data reconciliation. The Refonte Learning Database Administrator Essentials program, for example, covers exactly these topics (database design, SQL optimization, security, backup/recovery, cloud DB management, migration/integration, and monitoring) in a 3-month part-time curriculum. Building robust data pipelines and recovery plans is a core skill for any DBA or data engineer. As you apply these practices, remember: never accept an implicit gapless watermark without proof.