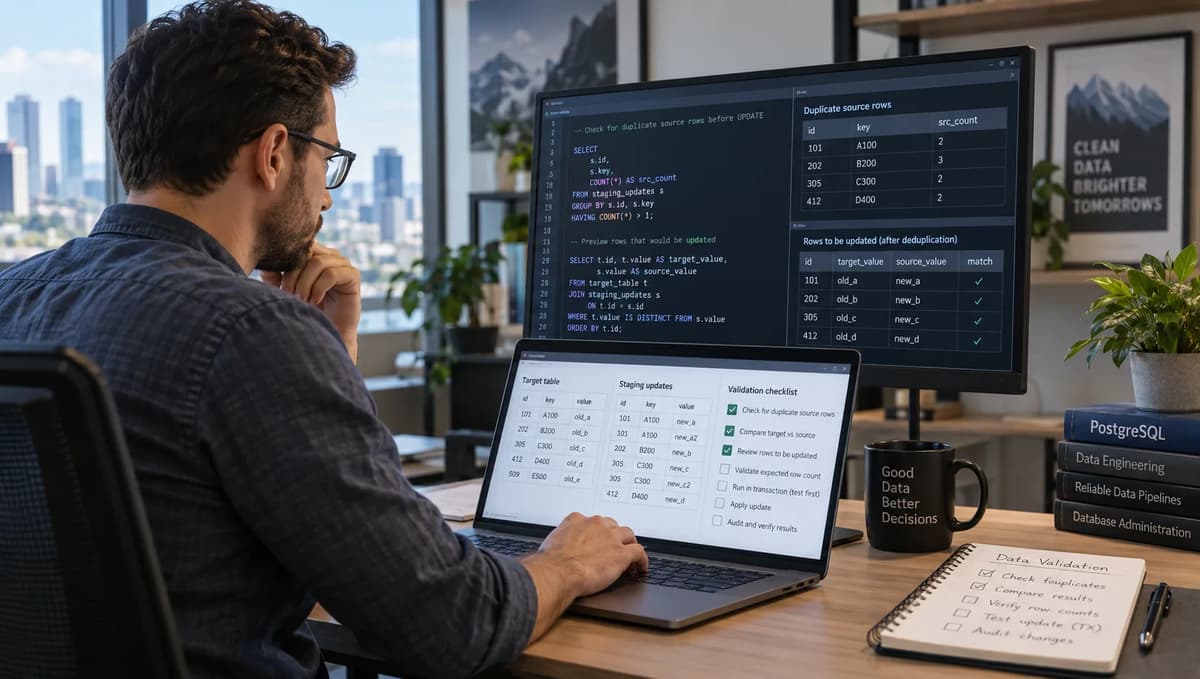
In batch data updates, a single target row might match multiple source rows with conflicting values. This creates a “count vs provenance” problem: PostgreSQL’s UPDATE ... FROM will report the expected number of rows updated, but it may apply one indeterminate source row’s values to each target when duplicates exist. The fix is an acceptance workflow: confirm that each target row has exactly one approved source, then apply the update; otherwise quarantine or rebuild the batch. We outline a playbook for safely handling a 3-row target and 3-row source scenario where target 1 is covered by two sources.
The decisions are: ACCEPT if each target has a unique, approved source and the final state exactly matches the expected manifest; QUARANTINE if any target has conflicting or duplicate source mappings; REBUILD if the source batch is ambiguous and needs corrected input; HOLD if provenance or completeness is unclear. In short, we care about provenance (unique source per target) and reconciliation (final balances exactly correct), not just raw row counts. For this target set, only targets 1 and 2 are meant to change (to 110 and 210); target 3 has no source and should remain 300.
This focus on ensuring a one-to-one source-to-target mapping complements broader backend database integration boundaries and integration testing practices. The PostgreSQL manual warns that if a target joins to multiple source rows, “only one of the join rows will be used” and which is used “is not readily predictable”. Therefore our workflow will detect that ambiguity, enforce unique staging, and only commit if the final table matches the known good values.
Define one approved source per target mutation
We establish a provenance contract: each updated target row must trace back to exactly one source row. In our example, the target table has IDs 1, 2, 3, and the raw source table has three rows: two for target 1 (source IDs “s1” and “s2” with proposed balances 110 and 120) and one for target 2 (“s3” proposing 210). We expect target 1 and 2 to update, and target 3 to remain unchanged.
The four outcome decisions are:
ACCEPT the update when exactly one source row is approved per target, and the post-update table matches the expected values.
QUARANTINE the batch if any target has multiple conflicting source rows (ambiguity in provenance), or if an orphaned source references no target.
REBUILD the batch when ambiguous or incorrect raw input needs replacement by a reviewed, unique set of source rows.
HOLD the transaction when provenance or completeness is incomplete or the source data is unstable.
These criteria emphasize provenance over mere row count. As the PostgreSQL documentation notes, an UPDATE ... FROM join only uses one matching row per target, but which one is arbitrary. We cannot accept ambiguous matches. Instead, we enforce a staging step to ensure uniqueness and then reconcile all target rows explicitly. (This is distinct from query or performance optimization concerns; query optimization is a separate concern that we address elsewhere. Here we focus solely on data integrity and auditability.)
Create the disposable PostgreSQL fixture
We work in a single session-local database for safety. First, verify we have a clean environment and log the version/isolation:
-- Connection guard: ensure our schema and temp tables won't conflict.
\echo 'Connection test:';
SELECT version() AS pg_version,
       current_setting('server_version') AS server_version,
       current_setting('transaction_isolation') AS tx_isolation;
Next, create the target and raw tables as session-local temporary tables with ON COMMIT PRESERVE ROWS (so that committing data setup does not drop them). We include explicit primary key and NOT NULL constraints for integrity:
CREATE TEMP TABLE lab_update_target (
    target_id   integer PRIMARY KEY,
    balance     integer NOT NULL
) ON COMMIT PRESERVE ROWS;

CREATE TEMP TABLE lab_update_raw (
    source_id       text PRIMARY KEY,
    target_id       integer NOT NULL,
    proposed_balance integer NOT NULL
) ON COMMIT PRESERVE ROWS;

INSERT INTO pg_temp.lab_update_target VALUES
    (1,100), (2,200), (3,300);
INSERT INTO pg_temp.lab_update_raw VALUES
    ('s1', 1, 110),
    ('s2', 1, 120),
    ('s3', 2, 210);
The initial target table has rows (1,100), (2,200), (3,300). The raw source table has (s1→1:110), (s2→1:120), (s3→2:210). Note that source_id is unique, but there are two sources (s1, s2) for target 1. By default, PostgreSQL will drop these temp tables at session end (they are not visible to other sessions). We use ON COMMIT PRESERVE ROWS so that our data remains after committing the above inserts (by default, PostgreSQL does preserve temp table rows across commits).
At this point, we have a fixed target table of 3 rows and a raw source stage of 3 rows, with a duplicate mapping for target 1. We will use this controlled fixture to test each arm (ambiguous update, scalar subquery, strict staging) under explicit transactions and savepoints. All work stays in this single session; nothing is committed to any durable shared database.
Preserve temporary data across the comparison transactions
Because these tables are declared TEMP, they only exist in our session. By default in PostgreSQL the ON COMMIT action for a temp table is PRESERVE ROWS, so our rows stay intact after DDL commits. They will be automatically dropped when the session ends. (For reference, note that the SQL standard would default a temp table to DELETE ROWS on commit, but PostgreSQL’s default is PRESERVE ROWS. We rely on the default here.)
We will use explicit transactions and savepoints to roll back partial tests, trusting that this preserves the temp table data until we end the session. (This isolation is not how a live multi-session system would behave, but it serves our lab.)
Measure the cardinality of the actual update join
Before running any updates, we check how many source rows join to each target. A handy query is:
SELECT t.target_id, COUNT(*) AS source_matches,
       array_agg(s.source_id) AS sources
FROM pg_temp.lab_update_target AS t
JOIN pg_temp.lab_update_raw AS s USING (target_id)
GROUP BY t.target_id
ORDER BY t.target_id;
The expected result is:
target 1 has 2 source rows (s1,s2),
target 2 has 1 (s3),
target 3 has 0 (no match).
We thus see target 1 has two conflicting candidates. We also explicitly check for any orphan source (a source row whose target_id does not exist in the target table):
SELECT s.source_id, s.target_id
FROM pg_temp.lab_update_raw AS s
LEFT JOIN pg_temp.lab_update_target AS t USING (target_id)
WHERE t.target_id IS NULL;
This returns none (all raw target_ids 1 and 2 do exist in the target). If there were an orphan source, it would not appear in an inner join update and hence indicate a data problem to hold.
At this point we see that target 1 is problematic: it has two inputs. We do not rely on a convenient subquery or DISTINCT, because that could hide problems if more tables were added to the UPDATE. We explicitly enumerate these join-multiplicities to drive our workflow decisions. (This explicit counting and grouping is akin to principles from advanced SQL training, but our focus here is on correctness of the data, not query tuning.)
Observe the ambiguous UPDATE FROM arm
We now perform the UPDATE ... FROM as written, to see the ambiguity. Inside a transaction, we create a savepoint, run the update with RETURNING, capture the results, then roll back to the savepoint:
BEGIN;
SAVEPOINT ambiguous_probe;

UPDATE pg_temp.lab_update_target AS t
SET balance = s.proposed_balance
FROM pg_temp.lab_update_raw AS s
WHERE t.target_id = s.target_id
RETURNING t.target_id, s.source_id, t.balance;
In SQL this returns two rows: one for target_id=1 with either source s1 or s2 (and balance 110 or 120), and one for target_id=2 with source_id='s3' and balance=210. By documentation, exactly two targets update, but which source was used for target 1 is arbitrary. For example, one run might yield:
 target_id | source_id | balance
-----------+-----------+---------
         1 | s1        |     110
         2 | s3        |     210
or another run might yield (1, s2, 120). The database provides no guarantee of first or last row. This demonstrates that our raw batch is ambiguous for target 1: it’s not clear if it should take 110 or 120.
We capture those rows (to show what happened) and then immediately restore the baseline:
ROLLBACK TO SAVEPOINT ambiguous_probe;
SELECT * FROM pg_temp.lab_update_target ORDER BY target_id;
After the rollback, the target table should again show (1,100),(2,200),(3,300). This proves the update was never committed and everything reverted. We make no assumptions about which source will be chosen; we only observe that it could be either. (Crucially, do not assert that source s1 always wins or that any fixed rule applies; the PostgreSQL documentation explicitly says it’s unpredictable.) This uncertain observation means the raw batch must be quarantined until we resolve the conflict.
Do not invent a first-row or last-row guarantee
It’s tempting to assume PostgreSQL picks, say, the first matching source by physical insert order or some plan detail. But both the official manual and experiment show that which source updates a given target when duplicates exist is not defined. We treat any single run’s result as an example outcome, not a promise. That uncertainty is exactly why we need this acceptance workflow: relying on an observed outcome would be brittle. We will proceed as though we see either possibility on the screen, but we won’t use that as a rule to fix the issue.
Restore the baseline before comparing repairs
After the ambiguous test, we must ensure we start each scenario from the unchanged baseline. We already did ROLLBACK TO SAVEPOINT ambiguous_probe above. To be explicit:
-- Ensure we have clean state
ROLLBACK TO SAVEPOINT ambiguous_probe;
Now the target table is back to [(1,100),(2,200),(3,300)]. We can verify:
SELECT * FROM pg_temp.lab_update_target ORDER BY target_id;This should show exactly the original balances. We avoid contaminating the next steps with any residual changes. If we had multiple transactions, we would need to BEGIN again, but here we remain in the same transaction (rolling back to the savepoint). We also should set up a fresh savepoint for the next arm, to isolate it similarly. (Always use explicit savepoints and rollbacks to keep the stages separate.)
At this point, none of the tests are committed, so the target remains unchanged.
Compare a scalar update that rejects multiple rows
As an alternative approach, we test a scalar subquery style UPDATE. This uses a single-row subselect in the SET clause. The SQL looks like:
SAVEPOINT scalar_probe;

UPDATE pg_temp.lab_update_target AS t
SET balance = (
    SELECT s.proposed_balance
    FROM pg_temp.lab_update_raw AS s
    WHERE s.target_id = t.target_id
)
WHERE EXISTS (
    SELECT 1 FROM pg_temp.lab_update_raw AS s
    WHERE s.target_id = t.target_id
)
RETURNING t.target_id, t.balance;
The WHERE EXISTS ensures we only try to update targets that have any matching source (otherwise the subquery would yield NULL). Because target 1 has two matching rows in lab_update_raw, this UPDATE will fail with a “more than one row” error. According to PostgreSQL’s rules for subqueries, a scalar subquery must return at most one row; if it returns multiple, it raises SQLSTATE 21000 (cardinality_violation).
We execute this expecting an error. In psql, we might disable immediate exit on error, capture the SQLSTATE, then roll back:
-- Temporarily allow errors and capture the error code
\set ON_ERROR_STOP off
SAVEPOINT scalar_probe;
UPDATE pg_temp.lab_update_target AS t
SET balance = (
    SELECT s.proposed_balance
    FROM pg_temp.lab_update_raw AS s
    WHERE s.target_id = t.target_id
)
WHERE EXISTS (
    SELECT 1 FROM pg_temp.lab_update_raw AS s
    WHERE s.target_id = t.target_id
);
-- Expect: ERROR:  more than one row returned by a subquery used as an expression
-- SQLSTATE 21000 (cardinality_violation).
ROLLBACK TO SAVEPOINT scalar_probe;
\set ON_ERROR_STOP on
We verify the captured SQLSTATE is 21000 (cardinality violation) and note that no rows were actually updated. Finally, we check the target table is still (1,100),(2,200),(3,300). (We disabled ON_ERROR_STOP just around the failing statement so we could catch its SQLSTATE; afterwards we re-enable it.) This result is distinct from the 23505 primary-key error we’ll see next: here the update itself failed, whereas in the next step the insert into a unique table fails.
Reject duplicate target keys during stage loading
To enforce that each target has only one source row, we build a strict staging table and attempt to load the raw batch into it. The stage table has a PRIMARY KEY on target_id and a UNIQUE on source_id:
SAVEPOINT stage_load;

CREATE TEMP TABLE lab_update_stage (
    source_id        text    NOT NULL,
    target_id        integer PRIMARY KEY,
    proposed_balance integer NOT NULL,
    UNIQUE (source_id)
) ON COMMIT PRESERVE ROWS;

-- Attempt to insert the original raw rows (this should violate the target_id PK)
INSERT INTO pg_temp.lab_update_stage VALUES
    ('s1', 1, 110),
    ('s2', 1, 120),
    ('s3', 2, 210);
This INSERT will fail because target_id=1 would be inserted twice, violating the primary key on that column. The SQLSTATE for unique violation is 23505. We capture that and roll back:
-- After running the above INSERT, we expect
-- ERROR:  duplicate key value violates unique constraint
-- SQLSTATE: 23505
ROLLBACK TO SAVEPOINT stage_load;
At this point, lab_update_stage (and the base lab_update_target) are unchanged; the stage table is effectively dropped (since it was inside the savepoint). Importantly, we have now detected and rejected the duplicate target mapping as unacceptable input. This differs from the scalar update failure: here the error is about duplicate keys, not the subquery output.
So far we have quarantined the ambiguous raw batch. The rejected raw data remains visible in lab_update_raw (which we treat as evidence). We will now proceed to load an approved replacement batch.
Rebuild from an explicitly approved replacement batch
We obtained a corrected batch from the data owner. This batch has exactly one source per target: only s2 for target 1 and s3 for target 2. We insert that approved data into our stage:
-- Load the reviewed batch with no conflicts
INSERT INTO pg_temp.lab_update_stage VALUES
    ('s2', 1, 120),
    ('s3', 2, 210);
This succeeds because now target_id 1 and 2 are each unique. We verify:
SELECT * FROM pg_temp.lab_update_stage ORDER BY source_id;
-- Expected stage rows: (s2, 1, 120), (s3, 2, 210).
We see two rows, with no duplicate keys or orphans. The stage table is session-private and unchanged by any commit so far.
Keep the source set frozen for the controlled update
We emphasize that lab_update_stage is a frozen, private table in our session containing only the reviewed data. This is not a multi-session or shared object: it is confined to our test and would have to be reproduced in production by the authorized process. In a real system, building this stage would typically be a separate ETL step. Here it just lives in our session to control the experiment. (Any concurrent changes in other sessions won’t affect our private table.) The goal is to use exactly these values in the update, without any hidden ordering or locking logic.
With the stage loaded and fixed, we perform the update:
SAVEPOINT unique_update;

UPDATE pg_temp.lab_update_target AS t
SET balance = s.proposed_balance
FROM pg_temp.lab_update_stage AS s
WHERE t.target_id = s.target_id
RETURNING t.target_id, s.source_id, t.balance;
Now each target row has exactly one matching s. The output rows should be:
 target_id | source_id | balance
-----------+-----------+---------
         1 | s2        |     120
         2 | s3        |     210
since s2 provides 120 for target 1, and s3 provides 210 for target 2. Target 3 has no source and is unaffected (it still has balance 300). We capture those returned tuples for record. After this update, the uncommitted state of lab_update_target is [(1,120),(2,210),(3,300)], which is what we expect.
We do not commit yet; before finalizing, we reconcile the full target set.
Reconcile the complete target state before commit
We must ensure the entire lab_update_target table exactly matches the expected manifest [(1,120),(2,210),(3,300)]. A full-state comparison is best done with a full join or an explicit check of each row. For example:
SELECT COALESCE(t.target_id, v.target_id) AS target_id,
       t.balance    AS actual_balance,
       v.balance    AS expected_balance
FROM pg_temp.lab_update_target AS t
FULL JOIN (VALUES (1,120),(2,210),(3,300))
       AS v(target_id,balance)
  ON t.target_id = v.target_id
WHERE t.balance IS DISTINCT FROM v.balance;
This query should return zero rows if every existing target has the correct final balance. In our case:
It should not list target 1 (120 vs 120), or 2 (210 vs 210), or 3 (300 vs 300) because all match. If any discrepancy or missing row existed, it would appear. Notice we include target 3 with expected 300 in the join. If we had only checked INNER JOIN or sum, we might miss the fact that target 3 was supposed to remain untouched. By doing the full join against the explicit list of expected (target_id,balance), we ensure no extra or missing rows.
Since our target table is currently (1,120),(2,210),(3,300), the above query returns zero rows, confirming a perfect match. At this point, all acceptance checks pass: one unique source per target (for 1 and 2), no missing targets, and exact balance values. We are ready to accept this update.
Now we commit the transaction:
COMMIT;
(In this disposable environment the commit does nothing visible beyond closing the transaction, but in production this would make the change permanent.)
After the commit, we could (in the same session) run:
SELECT * FROM pg_temp.lab_update_target ORDER BY target_id;to verify that the final state is committed as [(1,120),(2,210),(3,300)]. Note: because our tables are TEMP, if we started a new connection and re-ran this select, we would not see them; they exist only in this session. In a real database the table would be a persistent one.
Preserve unchanged and missing-source targets deliberately
It’s worth highlighting why we included target 3 in the reconciliation even though it had no source: by contract, missing-source targets must be preserved explicitly. Our full-join check included (3,300) in the expected list. If we had instead written the update without WHERE EXISTS, or omitted checking target 3, we might accidentally set it to NULL or overlook it. This test proves target 3 remains at 300. (As the scalar subquery test noted, omitting WHERE EXISTS would have set target 3 to NULL, violating our business rule since balance is NOT NULL. We deliberately used WHERE EXISTS to avoid that.)
Run no-op, orphan and equal-value duplicate controls
We also consider other potential control cases (not executed here, but conceptually important):
No-op batch: If an approved batch is empty (no rows), that's valid only if the expected manifest declares no changes. In code, loading an empty stage and running the update should result in 0 rows updated and an exact match to the original state. In our case, an empty batch would do nothing; such no-op acceptance should be explicitly authorized.
Orphan source: Suppose a source row pointed to a nonexistent target (e.g. source to target_id 99). This would silently do nothing in an inner join update. We treat that as a data error (and would “hold” the batch) because it means our raw data contained something outside the target set. We would catch it by noticing a source without a match (as we did in the initial join check).
Duplicate same-value: If two different source rows both map to the same target but happen to propose the identical value (say both propose 110), the target value is unambiguous (both agree). However, the lineage is still ambiguous; it’s not clear which source should be considered “the” approver of the value. By our rules, this still violates the provenance contract (two sources for one target). We would quarantine such a batch too, because provenance matters even if the values coincide. To test: if we change s2’s proposed_balance to 110 (same as s1), the regular join-update would always result in 110 at target 1 (making it look harmless), but we must still require a single source.
Unique valid source: If only one source row maps to target 1 (e.g. if s2 were absent), the update is unambiguous and should be accepted outright (the cardinality query would have shown count=1).
These controls confirm the policy: value agreement isn’t enough; exactly one source ID per target is the criterion.
Choose ACCEPT, QUARANTINE, REBUILD or HOLD
At the end of this audit, we apply our decision rules to the evidence collected:
ACCEPT: The approved stage had exactly one source per target, and the post-update table matched the expected values perfectly. We have a unique-source mapping (s2→1, s3→2) and no missing or extra targets. The evidence from the cardinality-violation check, returned rows and full-state comparison supports acceptance. We would proceed to commit this change in production.
QUARANTINE: The original raw batch had conflicting sources for target 1. The ambiguous UPDATE FROM test and the failed stage load demonstrated “multiple source rows for target 1, unpredictable choice”. As long as that ambiguity remains, the batch must not be committed. We quarantine it, meaning we do not apply it or commit it, and flag it for owner review.
REBUILD: Upon quarantining, we obtained and loaded a corrected batch of unique mappings. That replacement batch was explicitly reviewed (“approved source set”) and then applied. In practice, “rebuild” means run the workflow again with the fixed input (as we did). Only then can we move to acceptance.
HOLD: If the raw input were incomplete (e.g. if it had an orphan source or targets missing from the source manifest), or if any check had failed our reconciliation, we would hold. For instance, if target 2 were missing from the approved batch but expected, that would trigger hold. In our case, we satisfied coverage, so no hold was needed.
Importantly, we separated the pre-commit rollback from any theoretical data recovery. All updates we did were inside a transaction we ultimately rolled back or committed. In a live scenario, once the change is committed, a rollback cannot magically revert it; instead, any recovery would require logging or a compensating transaction under the organization’s change control. Our lab only shows that as long as the final check passed, the commit would preserve the correct state.
We can summarize the decision matrix (illustrative):
Condition | Evidence | Action |
One source per target, final-state OK | Unique stage, full-join empty diff | ACCEPT |
Conflict (multiple sources for target) | Ambiguous UPDATE return, failed stage insert | QUARANTINE |
Conflict resolved by new batch | Approved stage loaded successfully | REBUILD, then ACCEPT |
Missing or orphan data | Orphan source found / missing stage rows | HOLD |
Assign batch approval and database review ownership
In practice, multiple roles collaborate in this workflow. The data owner or pipeline team is responsible for the raw batch content; in our case, they produce the CSV or source rows. They must ensure (or authorize) the batch meaning: which target IDs should change and to what values. The data quality or ETL lead usually reviews the batch and performs the staging step (as we did with lab_update_stage), deciding which sources are correct. The database maintainer/DBA (our perspective) runs the actual SQL update and reconciliation. That DBA ensures every change is logged and the state is verified before and after. Finally, the release manager or whoever controls commits is responsible for performing the final commit once acceptance checks out.
Throughout, each person documents their decisions: the data approver confirms the source set {('s2',1,120),('s3',2,210)}, the SQL reviewer inspects the update script, and the DBA verifies the full-state reconciliation. If any additional joins or source lifetimes are added later (for example, if we later join more tables in the UPDATE), each party must re-validate this unique-source requirement. As with database administration and recovery context discussions, we do not assume anything outside the recorded evidence here.
It’s also crucial to distinguish in-transaction rollback from true disaster recovery. Our rollback to savepoints is only to test in a disposable environment. In production, after acceptance and commit, reverting a bad update would require logging (WAL replay, backups) and usually a separate fix/compensation under DBA guidance.
Strengthen database integrity and recovery foundations
This rigorous acceptance-and-repair process highlights core database administration skills: understanding SQL semantics, enforcing data integrity, and using transactions for safety. For those who want to deepen these foundations, including advanced SQL, constraints management, transactional recovery, and auditing, consider Refonte Learning’s Database Administrator Essentials program. Over three months (12–14 hours/week), it covers database design, SQL query optimization, backup and recovery, security, migration, and more, culminating in a Certificate of Internship (upon success). Strengthening these skills helps teams confidently enforce exactly the kind of data integrity rules demonstrated here.
By following this controlled lab process (checking cardinality, using savepoints, enforcing unique staging, and reconciling full state), we can accept only those UPDATE FROM mutations that have a uniquely determined source and fully verified outcome. This ensures that no ambiguous or unintended write slips into the database, meeting the auditability and correctness demands of critical applications.