A checkpoint can look completely healthy and still be the wrong checkpoint.
The filename can say best_epoch_07.pt. The recorded validation metric can still be the value that caused epoch 7 to win. The architecture can match. load_state_dict(strict=True) can succeed. Yet the tensors inside the eventual file can be values reached after epoch 7 if the training loop retained model.state_dict() as its “best model” and serialized that live-referencing object only after training continued.
That is not a hypothetical API interpretation. PyTorch's own saving-and-loading tutorial explicitly warns that assigning best_model_state = model.state_dict() does not create an independent best-model copy and recommends either a deep copy or serialization of the selected state. The version-selected PyTorch 2.8 Module API explains the underlying mechanism: the dictionary returned by state_dict() is shallow and contains references to the module's parameters and buffers.
The engineering decision is therefore narrower and stricter than “does this checkpoint load?” It is:
Does the artifact contain the tensor values selected at the recorded step, or later tensor values reached through a live state_dict reference?
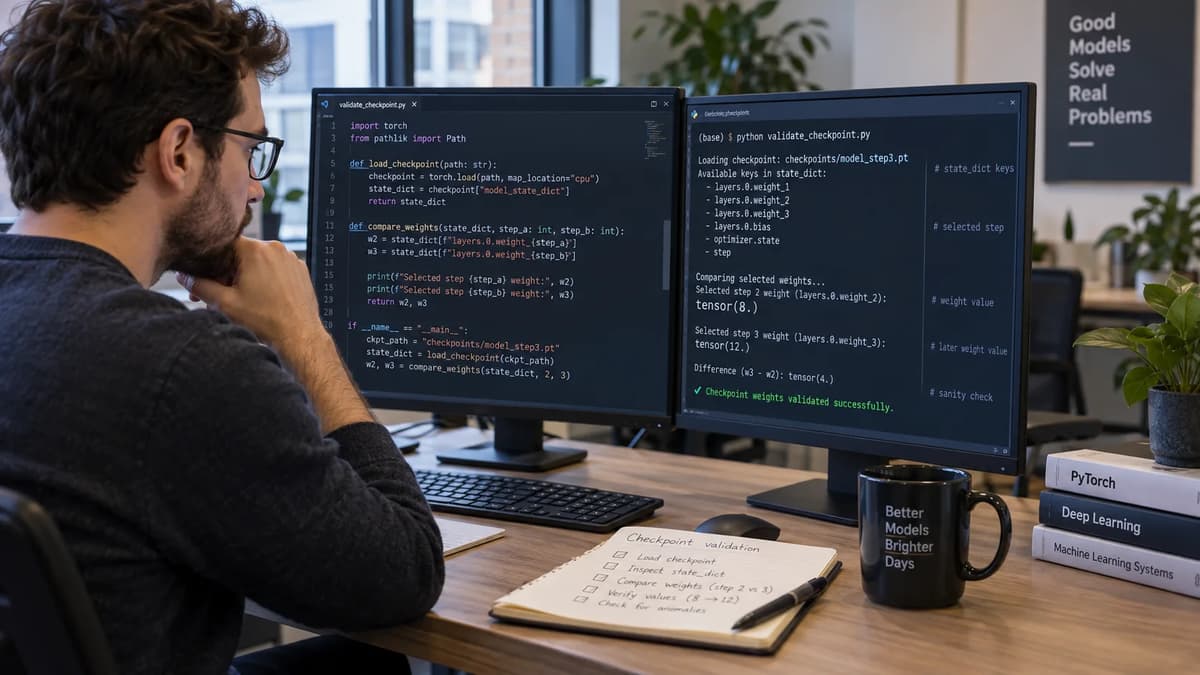
This playbook answers that question with a deliberately tiny CPU fixture. There are no datasets, pretrained downloads, optimizers, GPUs, distributed checkpoints, model registries, calibration procedures, or general evaluation-metric discussions. Weight 2, later weight 3, input 4, expected selected output 8, and later output 12 are authored test fixtures and arithmetic, not model-performance measurements.
The code below is runnable, but the tables describing its outcomes are explicitly known-answer expectations until the fixture is actually executed in the recorded environment. No terminal transcript or laboratory result is invented here.
Define the selected state before you trust the checkpoint label
A “best checkpoint” has several identities that are easy to collapse into one label:
Identity | What it answers | Why it matters |
Selection metadata | Which training step was nominated? | An epoch or metric label can remain unchanged after tensors drift. |
Model structure | Which parameter and buffer names, shapes and dtypes are expected? | Structural compatibility is necessary for loading but does not prove historical identity. |
Tensor state | Which numerical values were actually selected? | This is the state that acceptance must recover. |
Capture event | When and how were those values frozen independently of the live model? | An alias is not a historical snapshot. |
Serialization event | When were bytes actually written? | A late write can faithfully serialize already-drifted tensors. |
Artifact identity | Which exact file was tested? | A digest identifies bytes, not whether those bytes represent the selected state. |
The mistake is to let the first column stand in for all the others. epoch=7, metric=0.123, or a filename containing best is metadata. None of those strings forces the parameter storage in memory to remain at epoch 7.
That distinction belongs upstream of the wider notebook-to-production workflow. Production packaging, release controls, checksums and monitoring can faithfully preserve a wrong artifact; they cannot retrospectively recreate the tensor values that were never frozen at selection time. The adjacent Refonte workflow likewise treats reproducibility, artifact lineage and explicit acceptance evidence as separate concerns around productionization.
For this fixture, best means only “the state deliberately nominated at selected step A.” It makes no claim that weight 2 is useful, optimal, generalizable, or superior under a realistic metric. The selected-state contract is authored independently:
selected_step = "A"
expected_weight = float32([[2.0]])
known_input = float32([[4.0]])
expected_output = float32([[8.0]])
later_live_weight = float32([[3.0]])
later_live_output = float32([[12.0]])
The arithmetic oracle is independent: 2 × 4 = 8. It is not reconstructed from a saved candidate.
That independence matters. An acceptance program that computes its “expected” state by reading the candidate it is supposed to verify is circular. If the candidate has drifted to 3, such a test merely blesses 3.
The API basis is equally specific. PyTorch 2.8's state_dict() documentation says it returns the module's whole state and that both parameters and persistent buffers are included; critically, the returned object is documented as a shallow copy containing references to the module's parameters and buffers. By contrast, load_state_dict(strict=True) requires the supplied state dictionary's keys to match the module's state-dictionary keys. That is a structural contract; it does not say that matching keys establish which historical training step supplied the numerical values.
This article deliberately uses the PyTorch 2.8 API documentation as a fixed reference, not as a claim that PyTorch 2.8 is the newest release. The version-specific links identify the intended documentation baseline. The PyTorch saving-and-loading tutorial is a living document rather than a pinned runtime specification; its page records creation on August 29, 2018, an update on June 26, 2025, and verification on November 5, 2024.
The runtime lock belongs somewhere else: in the execution manifest produced by the fixture.
Pin the execution environment as evidence, not prose. A real acceptance run should record the exact installed Python version and build, torch.__version__, PyTorch's Git revision when exposed, torch.__config__.show(), operating-system details, the complete test configuration and the exact fixture source commit. Merely pointing at PyTorch 2.8 documentation is not an environment lock.
The test model is intentionally minimal:
torch.nn.Linear(1, 1, bias=False)
There is exactly one persistent model parameter: weight, shape [1, 1], dtype float32. Everything runs on CPU.
The complete fixture later in this article creates a run-specific local directory such as:
checkpointacceptance_artifacts/
└── 20260924T101530123456Z-4e8f7a12/
├── immediate_selected_state.pt
├── alias_late_write.pt
├── shallow_late_write.pt
├── deepcopy_late_write.pt
└── manifest.json
Each run gets a unique directory, and the code refuses to reuse an existing one. This separates two defects that otherwise become difficult to diagnose: memory aliasing and accidental file overwrite.
The fixture also requires a source commit. It first tries FIXTURE_COMMIT; otherwise it asks Git for HEAD. If neither produces a plausible full hexadecimal commit identifier, execution stops rather than silently recording an invented revision.
Capture four candidates at the same selected step
At selected step A, set the live model's sole weight to exactly 2.0 under torch.no_grad(). With fixed input 4.0, the independent expected output is 8.0.
Then create four candidates before any later mutation:
alias = model.state_dict()
shallow = dict(alias)
frozen = copy.deepcopy(alias)
torch.save(...immediate state..., immediate_path)
These operations look superficially similar, but they establish different ownership of tensor state.
The distinction follows directly from the PyTorch 2.8 Module.state_dict() contract: the returned dictionary is shallow and its values reference module parameters and buffers. The PyTorch tutorial turns that API fact into explicit best-model guidance: keeping model.state_dict() alone lets subsequent training updates affect the retained “best” state, while deep copying or serializing at selection time is the documented alternative.
The shallow dictionary candidate is especially important because dict(alias) can look like a reasonable defensive operation. It creates a new Python mapping container, but it does not itself deep-copy every tensor value inside that mapping. The outer dictionary is independent; the referenced tensor objects are not thereby established as independent snapshots.
The candidate model is therefore:
Candidate | Operation at step A | Independent tensor snapshot at A? | When bytes are written |
alias | model.state_dict() | No under the documented reference semantics | After later mutation |
shallow | dict(alias) | No; only the mapping container is copied | After later mutation |
frozen | copy.deepcopy(alias) | Yes, intended control | After later mutation |
immediate | torch.save(...) at selection time | Yes, serialized boundary | Before later mutation |
The last column matters. The experiment is deliberately designed so that frozen demonstrates capture now, serialize later, while immediate demonstrates serialize now. If both later reload as weight 2, they validate two independent ways of preserving the chosen state.
alias and shallow are the negative controls. They are retained in memory through a controlled later mutation and then serialized under metadata that still says selected step A.
Selection evidence must be immutable relative to all four candidates. In this fixture, it is authored separately:
SELECTION = {
"selected_step": "A",
"expected_weight": 2.0,
"known_input": 4.0,
"expected_output": 8.0,
}
The expected tensor itself is reconstructed from the literal 2.0 whenever verification runs:
def expected_state():
return {
"weight": torch.tensor([[2.0]], dtype=torch.float32, device="cpu")
}
It does not point at alias, frozen, model.weight, or a loaded checkpoint.
This separation is analogous to keeping model evaluation and baseline contracts distinct from the artifact that is being evaluated. Here the article intentionally does not select metrics or teach validation design. The narrower reliability requirement is that whatever selection rule nominated step A must remain tied to the exact tensor state that existed at A.
A metric string can survive perfectly while the underlying tensors change:
selection:
step = "A"
metric_label = "selected_fixture_state"
candidate tensors:
at selection = [[2.0]]
after live mutation through alias = [[3.0]]
The label did not “become wrong” as text. The association between that text and the model state became unsupported.
That is why provenance should distinguish at least:
• selected_at
• captured_at
• capture_operation
• mutated_live_model_at
• serialized_at
• artifact_sha256
• fixture_commit
Those timestamps answer different questions. A deep copy captured at 10:00:00 and serialized at 10:05:00 can still represent the 10:00:00 state. An alias created at 10:00:00 and serialized at 10:05:00 may represent whatever the live model contains at 10:05:00.
The filename cannot answer that question.
Continue the live model and expose why a shallow copy is not a snapshot
After all four candidates have been captured, mutate only the live module:
with torch.no_grad():
model.weight.fill_(3.0)
This is not intended to resemble a realistic optimizer update. It is deliberately simpler. The goal is to isolate one variable: what happens to candidate state when the underlying live parameter storage changes?
The live known-input arithmetic is now:
3 × 4 = 12
The selected-state arithmetic remains:
2 × 4 = 8
Under the PyTorch-documented reference semantics, the expected post-mutation state is therefore:
Candidate in memory or already serialized | Expected weight after live model becomes 3 | Reason |
Live model | 3 | Explicit controlled mutation |
alias | 3 | state_dict() values reference live model state |
shallow | 3 | New container, but referenced tensor values were not deeply copied |
frozen | 2 | Deep copy was made before mutation |
Immediate file | 2 | Serialization occurred before mutation |
The first important conclusion follows directly:
best_model_state = model.state_dict() does not, by itself, mean “the tensor values at the instant this line executed.” The current PyTorch tutorial explicitly warns against treating it that way for best-model preservation.
The second conclusion is just as important:
dict(model.state_dict()) is not a correction to that defect.
It gives you a different dictionary object, but the PyTorch API already says the state-dictionary values are references to module parameters and buffers. Copying only the surrounding mapping does not establish an independent tensor-value snapshot.
Do not generalize beyond the evidence. This playbook does not claim that every call involving.cpu(),.detach(), a new variable, or a renamed filename necessarily creates or fails to create a complete model-state snapshot. Those operations have their own semantics. The acceptance rule is simpler: use a capture method whose independence you can defend and test. For this contract, the accepted controls are the two methods PyTorch itself points toward for the best-model case: deep-copy the state or serialize it while the selected values are still live.
The same reasoning extends from this one parameter to real state_dicts. The PyTorch 2.8 API says persistent buffers are included alongside parameters. Therefore production code should freeze the whole model state required by the module, rather than selecting a hand-maintained list of “important weights” and risking omission of state the module expects.
The tiny Linear fixture intentionally avoids buffers so that storage aliasing is the only issue under test.
A useful invariant is:
Once step A is selected, continued mutation of the live training module
must be incapable of changing the candidate representation accepted as A.
A candidate that violates that invariant is not an immutable checkpoint candidate. It is a view onto evolving training state.
That interpretation also explains why waiting until the end of training and then calling:
torch.save(best_model_state, "best_epoch_A.pt")
is too late when best_model_state was only a live-referencing state_dict. Serialization can preserve the object presented to it at the write event; it cannot travel backward and reconstruct earlier tensor values that have already been overwritten.
The PyTorch 2.8 torch.save documentation describes saving an object to a disk file and also supports file-like objects. The engineering inference for this acceptance design is straightforward: the artifact boundary must be created before the state you intend to preserve ceases to exist independently.
Write the negative controls late, then reload every artifact fresh
The defect becomes operationally dangerous when selection metadata and tensor capture diverge.
After changing the live weight to 3, serialize the alias and shallow candidates while deliberately retaining the earlier step-A metadata:
selected_step = A
expected_weight = 2
expected_output = 8
Those files should be structurally plausible. Their names can contain selected_A. Their metadata can honestly report that A was the nominated step. But the tensor expected from their live references at late serialization is now 3.
The deep-copy candidate is also serialized late. Its expected tensor remains 2, because its independent state was created at A.
The immediately serialized candidate is never overwritten.
PyTorch 2.8's torch.save documentation establishes the serialization interface and also notes that PyTorch preserves storage sharing when serializing tensors. For this test, separate run-specific filenames make overwrite behavior explicit so that storage aliasing is not confused with an unrelated “we wrote the correct file and later replaced it” failure.
The four expected artifact histories are:
Artifact | Claimed selected step | Capture event | Serialization event | Expected stored weight |
immediate_selected_state.pt | A | Serialization at A | At A, before mutation | 2 |
deepcopy_late_write.pt | A | Deep copy at A | After live mutation | 2 |
alias_late_write.pt | A | Reference obtained at A | After live mutation | 3 |
shallow_late_write.pt | A | Outer mapping copied at A | After live mutation | 3 |
Again, these are fixture expectations, not claimed observations from a hidden run.
Each file must then be tested through a fresh module. Do not verify an artifact merely by looking at the old training model that produced it.
The load sequence is intentionally explicit:
payload = torch.load(
path,
map_location="cpu",
weights_only=True,
)
fresh = torch.nn.Linear(1, 1, bias=False, dtype=torch.float32)
fresh.load_state_dict(payload["model_state"], strict=True)
The version-selected torch.load documentation defines map_location as the mechanism for remapping serialized storage locations and shows CPU loading together with weights_only=True. It describes weights_only=True as restricting the unpickler to tensors, primitive types, dictionaries and permitted types.
load_state_dict(strict=True) then checks the model-state structure against the fresh module. In PyTorch 2.8, strict=True specifically requires state-dictionary keys to match those returned by the target module's state_dict().
That is useful, but it answers the wrong question if used alone.
A weight [[3.0]] and a weight [[2.0]] have:
same key: "weight"
same shape: [1, 1]
same dtype: float32
same module: Linear(1, 1, bias=False)
So a wrong historical state can be structurally compatible.
A successful strict load is therefore not proof that a file contains the tensors from the selected step. That conclusion is an engineering inference from what the documented strictness check covers and what it does not: key compatibility does not compare a candidate's numerical contents with your independent historical oracle.
After strict loading, perform per-key acceptance:
actual = fresh.state_dict()
expected = expected_state()
assert set(actual) == set(expected)
for key in expected:
assert actual[key].shape == expected[key].shape
assert actual[key].dtype == expected[key].dtype
assert torch.equal(actual[key], expected[key])
For this exact CPU/float32 fixture, torch.equal is appropriate because no tolerance, cast or approximate numerical reproduction is part of the contract. A larger application should define its own numerical acceptance policy rather than copying that choice mechanically.
Then add the fixed-input behavioral check:
x = torch.tensor([[4.0]], dtype=torch.float32)
y = fresh(x)
The known-answer expectations are:
Candidate | Expected reloaded weight | Expected output for input 4 | Selected-state check |
Immediate serialization | 2 | 8 | Pass |
Deep copy | 2 | 8 | Pass |
Alias, serialized late | 3 | 12 | Fail |
Shallow dictionary, serialized late | 3 | 12 | Fail |
The output test is deliberately secondary. 4 → 8 gives a human-readable independent check that the fresh module behaves consistently with weight 2, while 4 → 12 identifies the deliberately mutated state. It does not imply that one prediction proves a real model's general behavior.
For a larger model, per-key state comparison answers “are these the selected tensors?” A known-answer forward pass answers “does a cleanly reconstructed module produce this carefully specified reference behavior?” Those are complementary checks.
Here is the complete runnable fixture. It records environment, configuration, source commit, timestamps, digests, candidate provenance, structural checks, exact per-key equality and fresh-instance output checks. It performs no downloads and writes only beneath a run-specific local directory.
#!/usr/bin/env python3
"""
checkpoint_fixture.py
CPU-only checkpoint-capture acceptance fixture.
Contract:
- torch.nn.Linear(1, 1, bias=False)
- float32
- selected step A weight = 2
- fixed input = 4
- selected expected output = 8
- controlled later live weight = 3
- later live output = 12
All artifacts are expected to be owned/trusted local fixture material.
"""
from future import annotations
import copy
import hashlib
import json
import os
import platform
import re
import subprocess
import sys
import uuid
from datetime import datetime, timezone
from pathlib import Path
from typing import Any
import torch
ARTIFACT_ROOT = Path.cwd() / "_checkpoint_acceptance_artifacts"
CONFIG: dict[str, Any] = {
"fixture_name": "linear_state_dict_alias_acceptance",
"device": "cpu",
"dtype": "float32",
"module": "torch.nn.Linear",
"in_features": 1,
"out_features": 1,
"bias": False,
"selected_step": "A",
"selected_weight": 2.0,
"known_input": 4.0,
"selected_expected_output": 8.0,
"later_live_weight": 3.0,
"later_live_expected_output": 12.0,
}
def utc_now() -> str:
return datetime.now(timezone.utc).isoformat(timespec="microseconds")
def resolve_fixture_commit() -> str:
"""Require an exact source revision; never invent one."""
candidate = os.environ.get("FIXTURE_COMMIT", "").strip()
if not candidate:
try:
completed = subprocess.run(
["git", "rev-parse", "HEAD"],
check=True,
capture_output=True,
text=True,
)
candidate = completed.stdout.strip()
except (OSError, subprocess.CalledProcessError) as exc:
raise RuntimeError(
"No fixture commit available. Run from a committed Git "
"checkout or set FIXTURE_COMMIT to the exact commit hash."
) from exc
if not re.fullmatch(r"[0-9a-fA-F]{40,64}", candidate):
raise RuntimeError(
"FIXTURE_COMMIT must be a full hexadecimal commit identifier."
)
return candidate.lower()
def runtime_record() -> dict[str, Any]:
uname = platform.uname()
return {
"python_version": sys.version,
"python_executable": sys.executable,
"python_build": list(platform.python_build()),
"python_implementation": platform.python_implementation(),
"torch_version": torch.__version__,
"torch_git_version": getattr(torch.version, "git_version", None),
"torch_config": torch.__config__.show(),
"platform": platform.platform(),
"system": uname.system,
"release": uname.release,
"version": uname.version,
"machine": uname.machine,
"processor": uname.processor,
}
def make_model() -> torch.nn.Linear:
# Explicit CPU and float32; no dependence on default dtype/device.
return torch.nn.Linear(
1,
1,
bias=False,
device="cpu",
dtype=torch.float32,
)
def expected_state() -> dict[str, torch.Tensor]:
# Independent authored oracle: never derived from a candidate.
return {
"weight": torch.tensor(
[[2.0]],
dtype=torch.float32,
device="cpu",
)
}
def known_input() -> torch.Tensor:
return torch.tensor([[4.0]], dtype=torch.float32, device="cpu")
def expected_output() -> torch.Tensor:
# Independent literal rather than candidate-derived output.
return torch.tensor([[8.0]], dtype=torch.float32, device="cpu")
def sha256_file(path: Path) -> str:
digest = hashlib.sha256()
with path.open("rb") as handle:
for chunk in iter(lambda: handle.read(1024 1024), b""):
digest.update(chunk)
return digest.hexdigest()
def tensor_scalar(state: dict[str, torch.Tensor]) -> float:
return float(state["weight"].detach().cpu().item())
def make_payload(
,
state: dict[str, torch.Tensor],
candidate_id: str,
capture_operation: str,
captured_at: str,
serialized_at: str,
fixture_commit: str,
mutation_at: str | None,
) -> dict[str, Any]:
return {
"model_state": state,
"selection": {
"selected_step": "A",
"selected_weight": 2.0,
"known_input": 4.0,
"selected_expected_output": 8.0,
},
"provenance": {
"candidate_id": candidate_id,
"capture_operation": capture_operation,
"captured_at": captured_at,
"serialized_at": serialized_at,
"mutation_at": mutation_at or "NOT_YET_MUTATED",
"fixture_commit": fixture_commit,
},
}
def save_candidate(
*,
path: Path,
state: dict[str, torch.Tensor],
candidate_id: str,
capture_operation: str,
captured_at: str,
fixture_commit: str,
mutation_at: str | None,
) -> dict[str, Any]:
serialized_at = utc_now()
payload = make_payload(
state=state,
candidate_id=candidate_id,
capture_operation=capture_operation,
captured_at=captured_at,
serialized_at=serialized_at,
fixture_commit=fixture_commit,
mutation_at=mutation_at,
)
# Path is unique per candidate and run. No candidate is overwritten.
torch.save(payload, path)
return {
"candidate_id": candidate_id,
"path": str(path),
"capture_operation": capture_operation,
"captured_at": captured_at,
"serialized_at": serialized_at,
"mutation_at": mutation_at or "NOT_YET_MUTATED",
"artifact_sha256": sha256_file(path),
}
def verify_candidate(path: Path) -> dict[str, Any]:
# This fixture assumes path is owned/trusted local material.
payload = torch.load(
path,
map_location="cpu",
weights_only=True,
)
state = payload["model_state"]
expected = expected_state()
actual_keys = list(state.keys())
expected_keys = list(expected.keys())
key_checks: dict[str, Any] = {}
keys_equal = set(actual_keys) == set(expected_keys)
for key in sorted(set(actual_keys) | set(expected_keys)):
if key not in state:
key_checks[key] = {"status": "missing_from_artifact"}
continue
if key not in expected:
key_checks[key] = {"status": "unexpected_in_artifact"}
continue
actual_tensor = state[key]
expected_tensor = expected[key]
key_checks[key] = {
"actual_shape": list(actual_tensor.shape),
"expected_shape": list(expected_tensor.shape),
"shape_equal": actual_tensor.shape == expected_tensor.shape,
"actual_dtype": str(actual_tensor.dtype),
"expected_dtype": str(expected_tensor.dtype),
"dtype_equal": actual_tensor.dtype == expected_tensor.dtype,
"exact_value_equal": torch.equal(
actual_tensor,
expected_tensor,
),
"actual_values": actual_tensor.detach().cpu().tolist(),
"expected_values": expected_tensor.detach().cpu().tolist(),
}
fresh = make_model()
structural_load_ok = False
load_error: str | None = None
try:
incompatible = fresh.load_state_dict(state, strict=True)
structural_load_ok = (
len(incompatible.missing_keys) == 0
and len(incompatible.unexpected_keys) == 0
)
except RuntimeError as exc:
load_error = str(exc)
output_equal = False
actual_output: list[list[float]] | None = None
if structural_load_ok:
with torch.no_grad():
y = fresh(known_input())
actual_output = y.detach().cpu().tolist()
output_equal = torch.equal(y, expected_output())
all_key_values_equal = (
keys_equal
and all(
entry.get("shape_equal", False)
and entry.get("dtype_equal", False)
and entry.get("exact_value_equal", False)
for entry in key_checks.values()
)
)
selected_state_accept = (
structural_load_ok
and all_key_values_equal
and output_equal
)
result = {
"path": str(path),
"artifact_sha256": sha256_file(path),
"loaded_candidate_id": payload["provenance"]["candidate_id"],
"selection_metadata": payload["selection"],
"provenance": payload["provenance"],
"keys_equal": keys_equal,
"key_checks": key_checks,
"structural_load_ok": structural_load_ok,
"load_error": load_error,
"all_key_values_equal": all_key_values_equal,
"actual_output": actual_output,
"expected_output": [[8.0]],
"known_input_output_equal": output_equal,
"selected_state_accept": selected_state_accept,
}
del fresh
return result
def main() -> None:
fixture_commit = resolve_fixture_commit()
run_id = (
datetime.now(timezone.utc).strftime("%Y%m%dT%H%M%S%fZ")
+ "-"
+ uuid.uuid4().hex[:8]
)
run_dir = ARTIFACT_ROOT / run_id
# Refuse accidental reuse.
run_dir.mkdir(parents=True, exist_ok=False)
model = make_model()
# Establish selected step A.
with torch.no_grad():
model.weight.fill_(2.0)
selected_at = utc_now()
# Independently verify the fixture's starting condition.
assert model.weight.dtype == torch.float32
assert model.weight.device.type == "cpu"
assert torch.equal(model.state_dict()["weight"], expected_state()["weight"])
with torch.no_grad():
selected_live_output = model(known_input())
assert torch.equal(selected_live_output, expected_output())
# Capture all four candidates before subsequent live mutation.
alias_captured_at = utc_now()
alias = model.state_dict()
shallow_captured_at = utc_now()
shallow = dict(alias)
frozen_captured_at = utc_now()
frozen = copy.deepcopy(alias)
immediate_captured_at = utc_now()
immediate_path = run_dir / "immediate_selected_state.pt"
immediate_record = save_candidate(
path=immediate_path,
state=model.state_dict(),
candidate_id="immediate_serialization",
capture_operation="torch.save at selected step A",
captured_at=immediate_captured_at,
fixture_commit=fixture_commit,
mutation_at=None,
)
# Controlled stand-in for continued training.
mutation_at = utc_now()
with torch.no_grad():
model.weight.fill_(3.0)
with torch.no_grad():
later_live_output = model(known_input())
assert torch.equal(
later_live_output,
torch.tensor([[12.0]], dtype=torch.float32),
)
post_mutation_memory = {
"live_model_weight": float(model.weight.item()),
"alias_weight": tensor_scalar(alias),
"shallow_weight": tensor_scalar(shallow),
"deepcopy_weight": tensor_scalar(frozen),
}
# Late writes. All retain metadata saying selection happened at A.
alias_record = save_candidate(
path=run_dir / "alias_late_write.pt",
state=alias,
candidate_id="state_dict_reference",
capture_operation="model.state_dict() reference at selected step A",
captured_at=alias_captured_at,
fixture_commit=fixture_commit,
mutation_at=mutation_at,
)
shallow_record = save_candidate(
path=run_dir / "shallow_late_write.pt",
state=shallow,
candidate_id="shallow_dict_copy",
capture_operation="dict(model.state_dict()) at selected step A",
captured_at=shallow_captured_at,
fixture_commit=fixture_commit,
mutation_at=mutation_at,
)
frozen_record = save_candidate(
path=run_dir / "deepcopy_late_write.pt",
state=frozen,
candidate_id="deepcopy_state_dict",
capture_operation="copy.deepcopy(model.state_dict()) at step A",
captured_at=frozen_captured_at,
fixture_commit=fixture_commit,
mutation_at=mutation_at,
)
artifact_records = [
alias_record,
shallow_record,
frozen_record,
immediate_record,
]
verification = {
record["candidate_id"]: verify_candidate(Path(record["path"]))
for record in artifact_records
}
# Negative and positive controls make the fixture self-checking.
expected_acceptance = {
"state_dict_reference": False,
"shallow_dict_copy": False,
"deepcopy_state_dict": True,
"immediate_serialization": True,
}
for candidate_id, expected_accept in expected_acceptance.items():
actual_accept = verification[candidate_id]["selected_state_accept"]
if actual_accept != expected_accept:
raise AssertionError(
f"{candidate_id}: expected selected_state_accept="
f"{expected_accept}, observed {actual_accept}"
)
manifest = {
"run_id": run_id,
"run_directory": str(run_dir),
"fixture_commit": fixture_commit,
"runtime": runtime_record(),
"configuration": CONFIG,
"selected_at": selected_at,
"mutation_at": mutation_at,
"post_mutation_memory": post_mutation_memory,
"artifacts": artifact_records,
"verification": verification,
"expected_control_outcomes": expected_acceptance,
}
manifest_path = run_dir / "manifest.json"
manifest_path.write_text(
json.dumps(manifest, indent=2, sort_keys=True),
encoding="utf-8",
)
print(json.dumps({
"run_id": run_id,
"manifest": str(manifest_path),
"verification": {
cid: {
"selected_state_accept":
record["selected_state_accept"],
"structural_load_ok":
record["structural_load_ok"],
"all_key_values_equal":
record["all_key_values_equal"],
"actual_output":
record["actual_output"],
}
for cid, record in verification.items()
},
}, indent=2))
if name == "__main__":
main()
Run it only from the intended committed fixture source, or provide the exact commit explicitly:
python checkpoint_fixture.py
# Or, outside the repository checkout:
FIXTURE_COMMIT=<full-commit-hash> python checkpoint_fixture.py
Do not paste a made-up identifier merely to satisfy the check. An unknown fixture revision is evidence missing from the run, not an inconvenience to hide.
Build a capture-to-reload ledger and freeze future selections correctly
The manifest generated above is not merely a test log. It is the candidate-provenance ledger that allows another engineer to distinguish “selected at A” from “actually contains A.”
At minimum, retain these fields:
Evidence field | Acceptance purpose |
Candidate ID | Distinguishes alias, shallow copy, deep copy and immediate serialization |
Fixture commit | Identifies the exact verification/training-capture code |
Runtime versions | Records exact Python and PyTorch builds rather than relying on documentation version |
OS and PyTorch build configuration | Makes the execution environment reviewable |
Selected step | Records the nomination decision |
Independent expected state | Defines what acceptance is comparing against |
Capture operation | Establishes whether tensors were independently frozen |
Capture timestamp | Identifies when candidate state was obtained |
Mutation timestamp | Establishes the boundary after which live state changed |
Serialization timestamp | Identifies when artifact bytes were created |
SHA-256 digest | Identifies those exact artifact bytes |
Keys, shapes and dtypes | Checks structural state contract |
Per-key numerical equality | Checks selected tensor identity |
Fresh strict load | Tests reconstruction into the intended module |
Known-input output | Provides an independent behavioral cross-check |
Decision | Records accept, recovery, hold or rerun disposition |
Do not promote the file hash into a stronger property than it has. A SHA-256 digest is valuable for identifying whether you have the same bytes that were reviewed. It does not prove why those bytes were produced or whether their tensors correspond to the selected step.
Conversely, two separately serialized artifacts containing numerically equivalent model states need not be required to have identical file digests. Different metadata, archive details or provenance fields can change bytes without changing the accepted model tensors. The acceptance criterion here is numerical selected-state identity plus provenance, not accidental byte equality between independent serialization events.
The negative controls are essential. A verification suite where every candidate passes provides little evidence that the suite can detect the alias defect. In this fixture, the state_dict reference and shallow-copy artifacts are intentionally expected to fail selected-state equality after late serialization, while deep copy and immediate serialization are expected to pass.
That gives the reviewer both sides of the contract:
test detects known bad capture
AND
test accepts known good capture
The corrected capture pattern for continued training should be small enough to review at the point where the selection decision happens:
import copy
import torch
best_state = None
best_selection = None
# Inside the training/selection loop:
if selected_now:
best_selection = {
"step": current_step,
"metric": float(current_metric),
}
# Freeze the complete state at the selection transaction.
best_state = copy.deepcopy(model.state_dict())
# Training may continue and mutate model.
# Later persistence is safe with respect to model mutation because
# best_state is already independent.
torch.save(
{
"model_state": best_state,
"selection": best_selection,
},
"best_model.pt",
)
Or create the artifact boundary immediately:
if selected_now:
torch.save(
{
"model_state": model.state_dict(),
"selection": {
"step": current_step,
"metric": float(current_metric),
},
},
candidate_path,
)
The second form minimizes the interval between nomination and persistent capture. The first can be appropriate when an independently frozen in-memory snapshot must be written later. PyTorch's tutorial explicitly names deep copying and serialization as remedies for the retained-best-state reference problem.
The transactional requirement is:
selection decision
+
independent model-state capture
+
provenance record
Those operations should be coupled closely enough that the system cannot plausibly attribute later tensors to the earlier decision.
Do not freeze only a hand-selected parameter list unless your model's documented contract says that list constitutes its entire persistent state. PyTorch's state_dict() includes parameters and persistent buffers, so the safer default is to preserve the complete state dictionary expected by the module.
This playbook is deliberately not an exact-training-resumption contract. A model state_dict may be sufficient for the inference artifact being tested here, but exact continuation of a training trajectory can require optimizer state and additional state outside the model. PyTorch's saving tutorial separately describes general checkpoints for training resumption and includes optimizer state among the additional material normally persisted.
Accordingly, this fixture does not test:
• optimizer state
• scheduler state
• RNG state
• data-loader position
• sampler state
• distributed or sharded state
• gradient-scaler state
• exact minibatch continuation
Do not approve “exact resume” based on this playbook. That is a different requirement and deserves a different known-answer test.
Recover only from evidence that still contains the selected values
Recovery starts with a blunt question:
Does any surviving artifact or independent in-memory snapshot still contain weight 2?
If yes, recovery can be evidence-driven.
In this fixture, the expected survivors are:
immediate_selected_state.pt -> selected weight 2
deepcopy candidate -> selected weight 2
A surviving deep copy can be serialized, reloaded into a fresh matching model and subjected to the same per-key and known-input checks. A surviving immediate artifact can be verified directly.
Do not “recover” from the alias by rewriting its metadata. If its tensor has become 3, renaming the file to best_A_fixed.pt does not make it contain 2.
Do not infer model tensors from:
• epoch number
• validation score
• training logs
• filename
• job status
• timestamp alone
Those records can tell you which state you wanted. They do not necessarily contain enough information to reconstruct that state.
If no surviving candidate contains the approved selected values, put the claimed best checkpoint on hold. If the approved training path is reproducible from a known starting point, rerun it to produce a new independently captured candidate. That creates a new verifiable artifact; it does not magically reconstruct bytes or tensors that were lost.
The distinction matters operationally:
recover selected artifact
= selected values still survive somewhere and can be validated
rerun training
= selected values no longer survive; reproduce an approved process
and produce a new candidate
Only after artifact identity has been established should deployment readiness as a later boundary become relevant. Deployment architecture, serving efficiency and infrastructure scaling cannot answer whether the selected training state was frozen correctly.
There is also a separate trust boundary around serialized files.
The demonstration uses:
torch.load(
path,
weights_only=True,
map_location="cpu",
)
because all fixture artifacts are defined as locally owned and trusted.
The PyTorch 2.8 torch.load documentation states that weights_only=True restricts what the unpickler may construct and that map_location="cpu" directs storage loading to CPU. The same documentation warns about unsafe pickle-based deserialization when loading in unsafe modes and advises loading only trusted data.
That does not justify the broader statement “weights_only=True makes arbitrary checkpoints safe.” This article makes no such guarantee. Serialized-model risk needs provenance, access controls and deserialization policy appropriate to the environment; protecting machine-learning artifacts is a separate security concern from the selected-state identity check performed here.
Keep the two questions separate:
Question A:
May this artifact be loaded under our trust/security policy?
Question B:
After loading, do its tensors equal the independently approved selected state?
Passing A does not prove B.
Passing B does not erase the need for A.
Likewise, map_location="cpu" is a device-placement instruction in this workflow, not a provenance check. PyTorch 2.8 documents it as a way to remap serialized storage locations and specifically notes that it can be used to load checkpoint tensors onto CPU. It does not establish which training step produced those values.
Decide: accept, recapture, recover, hold or rerun, then assign ownership
Checkpoint acceptance should end with an explicit disposition, not “looks okay.”
Use the following decision matrix:
Decision | Required evidence | Meaning |
ACCEPT | Complete provenance; matching fixture/runtime contract; successful fresh structural load; every expected key, shape and dtype matches; every selected tensor equals the independent oracle; known-input check passes | This artifact is accepted as representing the nominated state under the tested contract. |
RECAPTURE FUTURE CHECKPOINTS | Alias/shallow defect is demonstrated and capture code is known to be unsafe | Correct the selection transaction for future runs. This does not repair already-lost historical tensors. |
RECOVER APPROVED ARTIFACT | A genuine deep copy or immediate serialization still contains the selected values and passes fresh verification | Restore the approved state from surviving frozen evidence. |
HOLD | Provenance is incomplete, tensors cannot be tied to the recorded selection, or evidence conflicts | Do not release the claimed best checkpoint until ambiguity is resolved. |
RERUN TRAINING | No verified selected-state survivor remains, but an approved reproducible baseline exists | Produce a new candidate through the approved training path and capture it correctly. |
A structurally valid weight-3 artifact belongs in neither ACCEPT nor RECOVER APPROVED ARTIFACT, even if it successfully loads into the model.
That is the core distinction between compatibility and identity.
For release, require a compact evidence bundle:
1. The exact fixture/training-capture commit and runtime manifest.
2. The independent selected-state oracle or an approved independently frozen reference.
3. All candidate capture and serialization timestamps.
4. Artifact digests.
5. Keys, shapes and dtype comparisons.
6. Per-key numerical selected-state equality.
7. A clean fresh-instance strict=True load.
8. The known-input check.
9. At least one meaningful negative control demonstrating the verifier detects the alias failure mode.
10. Passing independently frozen controls.
11. The final reviewer disposition.
Do not replace this bundle with “the training job was green.” A successful training process says nothing by itself about whether a later torch.save(best_model_state, ...) wrote tensors from the recorded best step.
Do not replace it with strict=True. PyTorch documents strict loading primarily in terms of state-dictionary key matching; it does not compare loaded values with your historical selection oracle.
Do not replace it with an epoch label. Metadata is useful only when its relationship to tensors is evidenced.
Ownership should follow the failure boundary.
Owner | Accountability |
Training owner | Make the selection/capture transaction atomic enough for the workflow; record selected step, independent capture and fixture revision. |
Artifact owner | Preserve the frozen candidate and manifest, prevent accidental overwrite and retain artifact identity. |
Reviewer/release owner | Reconstruct a fresh model, run structural and numerical verification, examine negative controls and record the decision. |
This is an engineering split, not a claim that every organization uses the same job titles. Refonte's broader discussion of ownership across data science and ML engineering likewise describes overlapping responsibilities across modeling and production engineering rather than a universal organizational taxonomy.
A compact handover record can look like this:
candidate_id: best-A-20260924-001
selected_step: A
selection_record_id: selection-A-001
capture:
operation: deepcopy_state_dict
captured_at: "2026-09-24T10:15:30.123456+00:00"
artifact:
serialized_at: "2026-09-24T10:27:11.654321+00:00"
sha256: "<recorded-after-write>"
fixture:
commit: "<exact-source-commit>"
python_version: "<from-manifest>"
torch_version: "<from-manifest>"
operating_system: "<from-manifest>"
acceptance:
strict_load: pass
keys_shapes_dtypes: pass
per_key_selected_state: pass
known_input_4_expected_output_8: pass
negative_alias_control: fail_as_expected
shallow_copy_control: fail_as_expected
frozen_controls: pass
decision: ACCEPT
reviewer: "<accountable-review-id>"
The timestamps and hashes above are illustrative schema fields, not claimed experimental records. A production handover must substitute actual run-generated values.
Revalidation should be triggered whenever a change can alter this contract, including:
• model persistent state
• state_dict generation
• selection or capture code
• serialization format or payload structure
• loading code
• expected dtype or device contract
• verification logic
• fixture source revision
Not every downstream change requires retraining, but a change that invalidates the identity test requires re-establishing the evidence before the artifact is released under the same acceptance claim.
The minimal review conversation should be painfully concrete:
Reviewer: Which exact tensor state was selected?
Training owner: Step A; independently specified expected state is weight 2.
Reviewer: How was it frozen?
Training owner: Deep copy at selection time / immediate serialization.
Reviewer: Did training continue afterward?
Training owner: Yes.
Reviewer: Can that continued mutation change the retained candidate?
Training owner: The negative alias controls show what would drift; the
accepted candidate is independently frozen.
Reviewer: Did a fresh module reload the artifact?
Training owner: Yes, with recorded keys/shapes/dtypes and strict loading.
Reviewer: Did its tensors equal the independent selected oracle?
Training owner: Yes.
Reviewer: What does input 4 produce?
Training owner: The acceptance record must show 8 for the selected fixture.
That is the evidence standard a “best checkpoint” label should summarize.
Strengthen the AI-engineering foundations behind checkpoint capture
Checkpoint capture sits at the intersection of model development and engineering discipline: the training code makes a selection, mutable program state continues to evolve, serialization creates an artifact boundary, and independent verification decides whether that boundary preserved what was approved.
Refonte Learning's AI Engineering program currently lists a three-month format at 12–14 hours per week and identifies neural networks, model training, AI model development and optimization, scaling and practical AI projects among its areas; its FAQ explicitly names PyTorch, TensorFlow and Keras among the tools taught. The page does not establish that this specific state_dict aliasing and checkpoint-identity laboratory is part of the curriculum, so that specialist exercise should not be implied.
For this playbook, the release rule remains independent of any course or credential:
Accept the claimed best checkpoint only when its capture provenance is complete, its fresh-loaded structure is valid, every required tensor matches the independently defined selected state, and the known-answer control confirms the expected selected-state behavior.
A late file with an early epoch label may be perfectly loadable and still contain the wrong model. The label tells you what was selected. Only frozen tensors plus verifiable provenance tell you what you actually kept.