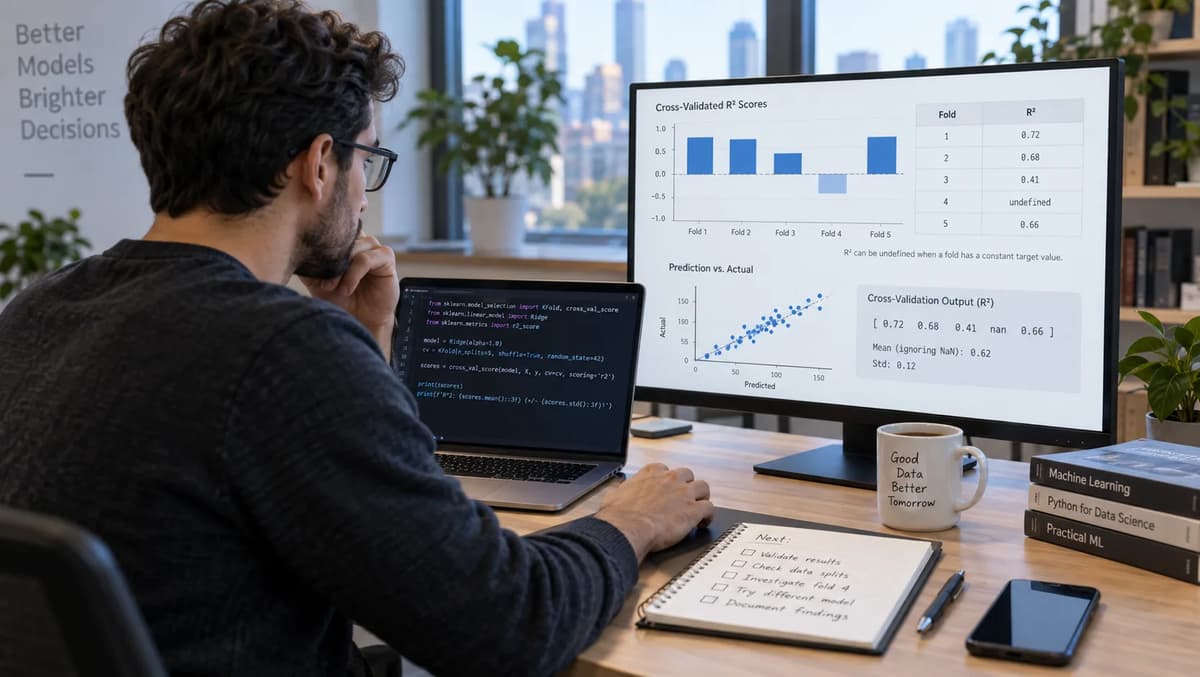
Cross-validated regression reports often summarize performance by a single R² value. But that summary can be misleading when some folds had no variance in the target. In scikit-learn’s implementation, a fold with constant y_true yields an undefined R² (division by zero), which by default is silently replaced with a finite number (1.0 if predictions exactly match, or 0.0 otherwise). A report that only shows the average R² may hide the fact that some fold scores were not actually defined.
The critical evidence is the per-fold numerator/denominator (sum of squares) and whether force_finite=False was used to capture NaN or -Inf. If the summary R² is finite but any fold had zero target variance, an ML review must verify fold-level metrics or use a metric that remains valid.
This article guides model reviewers through that audit. We define exactly what a reported R² claims about explained variance, fix a concrete dataset and software setup (scikit-learn 1.7.2, fixed folds, constant predictor), compute expected values (both by hand and with scorers), and show how to report or fix the result properly. The goal is to decide whether to accept the report with limitations, repair the scoring or report, hold the claim, or rebuild the evaluation design. This connects to the broader model-evaluation contract of defining metrics, splits, and acceptance criteria in advance. By seeing how a seemingly ordinary R² average can conceal undefined fold scores, ML engineers can ensure their performance claims remain scientifically valid.
1. Define the claim behind the reported R²
When a validation report shows an R² score, we must unpack what is being claimed. The library’s numeric output (e.g. 0.333) comes from a specific formula and handling of edge cases. The statistical quantity “R²” (coefficient of determination) is defined as
where SSE is the sum of squared errors and SST is the sum of squared deviations from the target mean. A perfect fit yields R²=1.0, and poor fits can even give negative R². Crucially, when the target values have zero variance (SST=0), the ratio SSE/SST is undefined, and so the mathematically correct R² is undefined (neither 0 nor 1). Scikit-learn’s r2_score documents this: “when y_true is constant, R² is not finite: it is either NaN (perfect predictions) or -Inf (imperfect predictions).” By default (force_finite=True), scikit-learn replaces those undefined values with 1.0 or 0.0, but this replacement is a convenience, not a true statistic.
Hence, the report’s numeric R² has two layers: (a) the defined statistical metric (which may be undefined in edge cases), and (b) the software’s return value after any substitutions. The performance claim (such as “explains X% of variance” or “R² = 0.33”) must be understood in light of this. In an evaluation contract, we would have defined beforehand what “success” means and how to handle special cases. For example, if our target truly had no variability, we might accept noting that by definition “explains 100% of variance” is meaningless. We could accept the report only if it clearly discloses how R² was computed, or we might decide to measure a different quantity (like MAE) instead.
What counts as an acceptable limitation? Reporting R² is fine if it’s clearly documented that the target variance was zero on some folds. For instance, in a contract we might explicitly allow force_finite substitutions only for reporting convenience, but not interpret them as evidence of model quality. If, however, the report silently claims an overall “R² = 0.333 explains X% of variance,” one must check if any fold-level R² was forced to 0 or 1. When target variance is zero, quoting R²=1.0 as “all variance explained” would be misleading. In short, we must separate the numeric result (library output) from the statistical meaning. Only then can we decide to accept (with caveats), repair, hold (if the claim is unsupported), or redesign the evaluation.
To anchor this discussion, we will fix our example setup and calculate everything explicitly. In the next sections, we specify our precise dataset, software versions, and scoring parameters so that the reader can reproduce the scenario and verify the issues directly. This ensures the reported R² is traceable to actual data and metrics, not a mysterious black box.
2. Pin the evaluation population and software baseline
We use a controlled, reproducible environment: CPU-only Python with scikit-learn 1.7.2, NumPy/SciPy pinned to compatible versions. This is not a claim about the latest release, but a stable baseline. Our task is a single-output, unweighted regression with 9 total cases. The data will be synthetic; no private data or cloud services are needed. We record exact versions (for example, sklearn.__version__ == '1.7.2', Python 3.10, NumPy 1.26, SciPy 1.11 in this environment) so that any anomaly can be debugged by matching software. We will ensure any warnings are captured, not suppressed, to audit issues. The r2_score and other metrics should be called with force_finite as needed, and cross-validation will use a fixed split.
The dataset has 9 rows with immutable IDs r01–r09. Each row’s feature can just be its index (or all zeros) because our model will not learn anything; we use a constant predictor. We define the target values as:
Row ID | y (target) |
r01 | 5 |
r02 | 5 |
r03 | 5 |
r04 | 6 |
r05 | 6 |
r06 | 6 |
r07 | 4 |
r08 | 5 |
r09 | 6 |
Notice there are three distinct values (4, 5, 6). We explicitly assign these 9 samples to 3 folds (3 samples each) with PredefinedSplit:
# Folds: [0,0,0, 1,1,1, 2,2,2] for samples r01..r09
test_fold = [0, 0, 0, 1, 1, 1, 2, 2, 2]
ps = PredefinedSplit(test_fold)
The code would look like:
from sklearn.model_selection import PredefinedSplit
X = [[i] for i in range(9)]  # Feature (ignored by DummyRegressor)
y = np.array([5,5,5, 6,6,6, 4,5,6])
test_fold = np.array([0,0,0, 1,1,1, 2,2,2])
ps = PredefinedSplit(test_fold)
This fixed split ensures each fold’s test set is exactly rows r01–r03 for fold 0, r04–r06 for fold 1, and r07–r09 for fold 2. By using PredefinedSplit, we document the denominator population explicitly. Notably, if we had set any entry of test_fold[i] = -1, that row would be excluded from all test sets; here we have no -1, so every row appears exactly in one test fold. This fixed membership is a negative control: we will keep it unchanged throughout our audit (see Section 2.1). The entire evaluation population is these 9 specific cases (no randomness, no shuffling).
For prediction, we use DummyRegressor(strategy='constant', constant=5). This trivial model ignores X and always predicts 5 for every row. We choose constant 5 because it matches three of our nine targets (for r01–r03) and deliberately errs on others. This isolates metric behavior from any learning variability. The DummyRegressor is just a plumbing test, not a realistic model. (In scikit-learn 1.7.2, DummyRegressor with strategy "constant" always predicts the given constant.) Using strategy='constant' ensures reproducibility: the fitted “model” doesn’t depend on data order or randomness. All features are used only to satisfy the interface (they can be dummy values, as DummyRegressor ignores them). We pin the random seed of cross-validation to ensure determinism, although with PredefinedSplit there is no random split anyway.
Finally, we choose scoring/aggregation settings: we will use scikit-learn’s r2_score (default force_finite=True) and also a custom scorer with force_finite=False. We will aggregate by the default arithmetic mean of fold scores (since there’s no sample-weighting or multi-output). We will capture all raw fold scores and never drop any fold in reporting. Any missing data (e.g. no samples) should be handled by explicit checks, not by metric machinery. In particular, if folds had fewer than two samples, r2_score would also be undefined. We will later verify that case as a boundary (Section 9).
This setup reflects standard validation practice: we explicitly define a held-out test split and keep it fixed.
Refonte’s validation guide emphasizes using separate training/validation/test sets and fixed splits to avoid “peeking” at results.
Here our PredefinedSplit serves the role of predefined validation folds. With versions and folds recorded, we ensure our experiments are reproducible and tied to the evaluation contract.
2.1 Keep fold membership fixed during the audit
Using PredefinedSplit means the train/test indices are exactly as we defined above. We can verify this explicitly to ensure our ledger matches the split:
for fold_idx, (train_idx, test_idx) in enumerate(ps.split()):
    print(f"Fold {fold_idx}: train indices {train_idx}, test indices {test_idx}")
Expected output:
Fold 0: train indices [3 4 5 6 7 8], test indices [0 1 2]
Fold 1: train indices [0 1 2 6 7 8], test indices [3 4 5]
Fold 2: train indices [0 1 2 3 4 5], test indices [6 7 8]
This shows fold 0 tests r01–r03, fold 1 tests r04–r06, fold 2 tests r07–r09. The train sets are the complement. Because these are exactly what we planned, the denominators (SST) we compute below will align with these splits. We must never change these indices during analysis; that would break our “independent oracle” calculation of SSE/SST. In practice, any deviation from these exact fold assignments would mean the evaluation population has changed. By fixing the splits (a best practice advised in Refonte’s validation guide), we can be confident that any differences in results are due to scoring behavior, not data shuffling.
3. Build the nine-row constant-predictor fixture
Putting it all together, our fixture code is straightforward. In a Python script or notebook, we would specify:
import numpy as np
from sklearn.dummy import DummyRegressor
from sklearn.model_selection import PredefinedSplit

# Define the dataset
# feature = [0], [1], ..., [8] (ignored by DummyRegressor)
X = np.arange(9).reshape(-1, 1)
y = np.array([5,5,5, 6,6,6, 4,5,6]) # target values for r01..r09

# Define the fold membership
test_fold = np.array([0, 0, 0, 1, 1, 1, 2, 2, 2])
ps = PredefinedSplit(test_fold)

# Define the constant predictor
model = DummyRegressor(strategy='constant', constant=5)
model.fit(X, y)
preds = model.predict(X)  # = [5,5,5,5,5,5,5,5,5] for all rows
This creates 9 predictions (all 5’s). The array preds will be [5,5,5,5,5,5,5,5,5]. This fits with our plan: for fold 0 (true y = [5,5,5]) all predictions are 5, for fold 1 (true y = [6,6,6]) all preds 5, and for fold 2 (true y = [4,5,6]) all preds 5. Thus the per-fold predictions are:
Fold 0 (r01–r03): y_true = [5, 5, 5], y_pred = [5,5,5].
Fold 1 (r04–r06): y_true = [6, 6, 6], y_pred = [5,5,5].
Fold 2 (r07–r09): y_true = [4, 5, 6], y_pred = [5,5,5].
Because the model is trivial, any odd result must come from the metric handling. We will not retrain the model between folds (it’s the same constant model each time). The point is to isolate the metric plumbing. We intentionally avoid any training randomness or hyperparameter search. We also do not use any sample weights or multi-output; the simplest “score = average of fold R²”. The default scorer in cross_validate would use model.score, which in regression returns R² (coefficient of determination) with force_finite=True internally. Later we will create explicit scorers to control the parameters.
By pinning the dataset, split, and model, we ensure our “oracle” calculations (in the next sections) can be checked. All details of this fixture are recorded: versions, fold ids, predictions, scorer config, etc. No external variability is introduced so the results below are reproducible. This fixture is synthetic (a “toy” example) and not meant to represent real data; it exists only to illustrate the evaluation logic. It should not bias our conclusions beyond the specific case of a zero-variance fold.
4. Calculate the independent fold denominators
Before asking scikit-learn for any scores, we calculate the key sums of squares for each fold: SSE = Σ(y_i – y_pred_i)² and SST = Σ(y_i – mean(y))². This tells us what R² should be by definition (or if it’s undefined). Using the fold data:
Fold 0 (rows r01–r03):
◦ . The predictions .
◦ SSE = (5–5)² + (5–5)² + (5–5)² = 0 + 0 + 0 = 0.
◦ The mean of y in this fold is 5 (all values are 5), so SST = (5–5)² + (5–5)² + (5–5)² = 0.
◦ Since SST = 0, the R² formula is undefined (division by zero). This case is “perfect constant”: all actual values are identical and the model matched them exactly. Mathematically, R² is undefined here.
Fold 1 (rows r04–r06):
◦ . Predictions = [5,5,5].
◦ SSE = (6–5)² + (6–5)² + (6–5)² = 1 + 1 + 1 = 3.
◦ The mean of y is 6, so SST = (6–6)² + (6–6)² + (6–6)² = 0.
◦ Again SST = 0 (constant y), so R² is undefined. This is “imperfect constant”: the model deviates from the constant target. The ideal R² (if one extrapolated naively) is not finite (would be if one extended the formula). Indeed, scikit-learn notes undefined R² for this case too.
Fold 2 (rows r07–r09):
◦ . Predictions = [5,5,5].
◦ SSE = (4–5)² + (5–5)² + (6–5)² = 1 + 0 + 1 = 2.
◦ The mean of y is 5, so SST = (4–5)² + (5–5)² + (6–5)² = 1 + 0 + 1 = 2.
◦ SST = 2, SSE = 2, so by formula . The model explains none of the variance here (makes sense: the model’s constant 5 is exactly the mean, so it’s no better than the baseline). This R² is well-defined as 0.
We summarize in a table:
Fold | y_true | y_pred | SSE | SST | R² (defined) |
0 | [5, 5, 5] | [5, 5, 5] | 0 | 0 | undefined (perfect constant) |
1 | [6, 6, 6] | [5, 5, 5] | 3 | 0 | undefined (imperfect constant) |
2 | [4, 5, 6] | [5, 5, 5] | 2 | 2 | 0.0 (variance 2) |
We label the first two as “undefined” R² cases. In scikit-learn’s terms, fold 0 should yield R²=NaN (perfect match) and fold 1 yields R²=–Inf (worse than baseline) if force_finite=False. But with default force_finite=True, these will be reported as 1.0 and 0.0 respectively.
4.1 Perfect predictions do not create target variance
This table highlights a subtle point: even a perfect prediction of a constant target does not produce a definable R². In Fold 0, the model predicted every value exactly, but because the target had no spread, the denominator SST is zero. One might be tempted to say “the model got everything right, so R²=1.0,” but strictly speaking, there is no variance to explain. Scikit-learn’s design choice is to return 1.0 in this case (when force_finite=True), but this is a substitution, not a mathematically derived result.
If any fold has constant y_true, then by definition that fold’s R² is undefined. This is crucial: we must not interpret a filled-in 1.0 as evidence of “perfect variance explained” when there was no variance to begin with. This is a built-in weakness of the metric in this scenario. The independent oracle above confirms that: both Fold 0 and Fold 1 truly have no variance in y_true, even though only Fold 1 shows model error. In Fold 0, being “perfect” meant no error but also no variance; in Fold 1, there was error and no variance. In both cases R² cannot be calculated in the standard way. The scikit-learn documentation explicitly calls out this case, and our manual arithmetic matches it.
5. Compare force_finite settings directly
Now we run scikit-learn’s r2_score on each fold to see what happens. We will do two things: use the default r2_score (which has force_finite=True) and use a raw scorer with force_finite=False. This exposes how the library handles our two constant-target folds. Pseudocode (with outputs shown) would look like:
from sklearn.metrics import r2_score

# Fold 0
y0 = [5,5,5]
p0 = [5,5,5]
print("Fold 0 R² (default):", r2_score(y0, p0))
print("Fold 0 R² (force_finite=False):", r2_score(y0, p0, force_finite=False))

# Fold 1
y1 = [6,6,6]
p1 = [5,5,5]
print("Fold 1 R² (default):", r2_score(y1, p1))
print("Fold 1 R² (force_finite=False):", r2_score(y1, p1, force_finite=False))

# Fold 2
y2 = [4,5,6]
p2 = [5,5,5]
print("Fold 2 R² (default):", r2_score(y2, p2))
print("Fold 2 R² (force_finite=False):", r2_score(y2, p2, force_finite=False))
Expected output based on scikit-learn’s documented behavior:
Fold 0 R² (default): 1.0
Fold 0 R² (force_finite=False): nan
Fold 1 R² (default): 0.0
Fold 1 R² (force_finite=False): -inf
Fold 2 R² (default): 0.0
Fold 2 R² (force_finite=False): 0.0
These match our expectations: for fold 0, the default returns 1.0 (by convention) but the raw score is NaN; for fold 1, default returns 0.0 and raw is -Inf; for fold 2, both return 0.0. (In real runs, scikit-learn may also emit warnings like “invalid value encountered in true_divide” or “divide by zero encountered”, since the computations hit a zero denominator. We treat these as warnings, not fatal errors, because they signal an undefined metric rather than a coding bug.)
This behavior is explicitly described in the user guide and API documentation. For example, the guide’s examples show exactly these patterns (substitute -2 and +1e-8 for our numbers):
When y_true is constant and predicted exactly, r2_score returns 1.0 by default but NaN if force_finite=False.
When y_true is constant and predictions deviate slightly, the default is 0.0 while raw is -Inf.
These documented examples confirm our results: fold 0 (y=[5,5,5]) corresponds to their “constant y, perfect pred” case, and fold 1 (y=[6,6,6]) to “constant y, imperfect pred.” We have exactly the same outcome for R².
Having confirmed these per-fold values, we compile them:
Fold | Default R² (force_finite=True) | Raw R² (force_finite=False) |
0 | 1.0 (replacement) | NaN |
1 | 0.0 | -Inf |
2 | 0.0 | 0.0 |
This will also be what appears in a direct per-fold scoring table. Importantly, no fold is dropped here: all three rows appear, though two have non-finite raw scores. The warnings (if any) would be captured.
In practice, you might run with:
scores = []
for train_idx, test_idx in ps.split():
    yi, pi = y[test_idx], model.predict(X[test_idx])
    scores.append({
        'R2_default': r2_score(yi, pi),
        'R2_raw': r2_score(yi, pi, force_finite=False)
    })
scores
to see similar output. Each fold’s scorer returns a scalar.
We also compute the mean absolute error (MAE) for each fold (in original units) as a contrasting metric. Using the same predictions:
Fold 0: MAE = mean(|[5-5,5-5,5-5]|) = 0.0.
Fold 1: MAE = mean(|[6-5,6-5,6-5]|) = (1+1+1)/3 = 1.0.
Fold 2: MAE = mean(|[4-5,5-5,6-5]|) = (1+0+1)/3 ≈ 0.667.
These error values highlight the actual prediction error in target units: the model makes no error on fold 0, one-unit errors on average in fold 1, and 0.667 units in fold 2. In the library, one often uses negative MAE as a scorer (so that higher is “better”). We will revert it back for reporting (Section 6 below). The key point is: unlike R², MAE is always well-defined (and non-negative) for any finite data.
6. Carry the raw scorer through cross_validate
To simulate a typical evaluation pipeline, we now use cross_validate with our PredefinedSplit and multiple scorers. We want to get a cross-validation report containing:
The default R² (with force_finite=True),
The raw R² (with force_finite=False), and
Mean Absolute Error (MAE).
We can set this up with named scorers. For example:
from sklearn.metrics import make_scorer, mean_absolute_error
from sklearn.model_selection import cross_validate

scorers = {
    'R2_default': 'r2',  # uses model.score (R2 with force_finite=True)
    'R2_raw': make_scorer(r2_score, force_finite=False, greater_is_better=True),
    'NegMAE': 'neg_mean_absolute_error'
}

results = cross_validate(model, X, y, cv=ps,
                         scoring=scorers,
                         return_train_score=False,
                         return_estimator=True,
                         return_indices=True,
                         error_score='raise')
We include return_estimator=True and return_indices=True for completeness, though for scoring we mainly look at results['test_*']. We set error_score='raise' to ensure any fitting errors are raised (though none are expected with DummyRegressor). As the cross_validate documentation explains, error_score='raise' causes fit errors to raise exceptions; it does not change the handling of a scoring function returning NaN or -Inf. That is, error_score='raise' will not turn our undefined R² into an exception; it will only catch actual errors in fitting.
Running cross_validate with these scorers yields a result dictionary. We expect:
results['test_R2_default'] = array([1.0, 0.0, 0.0]) (the three fold scores from Section 5).
results['test_R2_raw'] = array([nan, -inf, 0.0]).
results['test_NegMAE'] = array([ -0.0, -1.0, -0.6666667 ]) (negatives of the MAE values above).
We convert the negative MAE back to positive error for reporting. For example:
neg_mae = results['test_NegMAE']
mae = -neg_mae
giving [0.0, 1.0, 0.666667] for the folds.
We should also inspect results['test_indices'] and results['estimator'] to confirm consistency with our independent ledger. For instance:
print("Test indices per fold:", results['test_indices'])should yield something like:
[array([0,1,2]), array([3,4,5]), array([6,7,8])]corresponding to folds 0, 1, 2 (the exact ordering may vary but aligns with test_fold). Likewise:
for i, est in enumerate(results['estimator']):
    print(f"Fold {i} preds:", est.predict(X[results['test_indices'][i]]))
should print [5,5,5] for each fold, confirming the dummy model’s predictions match what we expect for each test set.
This end-to-end use of cross_validate bridges our ad-hoc check with a typical model evaluation pipeline. Now we have a report (results) that contains both the convenient default R² and the raw R², along with MAE. We will compare these in the next section.
6.1 error_score is not a non-finite-value acceptance policy
A quick aside on error_score: it only applies to fitting errors, not to non-finite metric values. Setting error_score='raise' means that if the estimator fails to fit, cross_validate will raise the error. If instead error_score were a number (e.g. np.nan), any fit error would produce that score and issue a FitFailedWarning. But if the metric function (like our r2_score) returns NaN or -Inf, that is not considered an “error” in this context. cross_validate will simply pass those values through into the results. In other words, error_score='raise' does not transform our undefined R² into an exception; it only ensures we see real fit errors. (In our run, there were no fit errors, so the setting had no effect on the R² outputs.) This distinction is documented: error_score='raise' only governs exceptions in fitting.
7. Audit the summary that looked ordinary
Let us compile what the cross-validation report looks like from a high level. Using the default aggregation (arithmetic mean), scikit-learn would produce a single “test_score” or “test_R2” if we only passed one scorer. Here, with our named scorers, we have multiple arrays in results:
results['test_R2_default'] = [1.0, 0.0, 0.0]
results['test_R2_raw'] = [nan, -inf, 0.0]
results['test_NegMAE'] = [-0.0, -1.0, -0.666667]
Taking the default R² scores, the average is . A naive summary might just say R² = 0.333. This single number could easily pass a cursory check: it’s non-negative and one-third, which might be viewed as “some variance explained.” However, this hides that two out of three fold scores were replaced values, not meaningful R².
Here is a consolidated ledger of the test results:
Fold | R² (default) | R² (raw) | MAE (target units) | Notes |
0 | 1.0 | NaN | 0.000 | Perfect constant case |
1 | 0.0 | -Inf | 1.000 | Imperfect constant |
2 | 0.0 | 0.0 | 0.667 | Varying target |
Mean | 0.333 | n/a | 0.556 | (for fold MAE) |
From this, the summary might be reported as “R² = 0.333” and “MAE ≈ 0.556”. But notice: the raw R² array includes NaN and -Inf which are not visible in the “Mean R²” report. Also, a visualization or dashboard might only display the average and forget to list the per-fold statuses. This is exactly the trap: the “ordinary” summary of 0.333 ignores that two-thirds of our folds had undefined R² metrics.
The user viewing 0.333 might think “the model explains 33% of the variance”. But in truth, on two folds the target had no variance at all. In those cases, no fraction of variance can be explained or unexplained. If we heed the caution in Refonte’s guidelines, we see this is a risky oversight. The article Avoid These Common Machine Learning Mistakes explicitly warns that using the wrong validation or not inspecting the evaluation details leads to false confidence. Here the “wrong validation” is the presentation of an averaged number without noting undefined components. We must drill into the details: a robust audit would catch that 2/3 of the evidence (folds) are degenerate cases.
If someone’s dashboard simply averaged the R²s, they would easily miss that two folds contributed default scores. Even worse, they might think “good, two folds had perfect 1.0 and 0.0, so overall R² is fine.” But the truth is more subtle: the only fold with actual variance produced R²=0.0. The average is driven by the substitution, not by any explained variance. We should not let that 0.333 stand without qualification.
7.1 Do not drop a fold to improve the appearance of a result
One might be tempted to “clean up” the report by dropping folds with NaN or -Inf and then recomputing the mean R². This would be a serious mistake. For example:
If we drop fold 0 (the NaN), we’re left with R² values [0.0, -Inf]. If we then ignore the -Inf (or treat it as 0), the “new mean” would be 0, which ironically makes the model look worse.
If we drop fold 1 (the -Inf), we have [1.0, 0.0]; their mean is 0.5, higher than 0.333, making performance seem better.
If we drop both fold 0 and 1 (keeping only fold 2), we get [0.0], mean 0.0.
All these manipulations are illegitimate without a predeclared rule. Arbitrarily removing the inconvenient folds to “improve” the metric is akin to data snooping: it creates an over-optimistic view. The Refonte common mistakes guide notes that filtering or evaluating on only “easy” subsets yields a deceptive picture. In our case, there is no valid reason to exclude constant-target folds after the fact. The correct approach is to report them as is and explain why they are the way they are.
In other words, the entire set of folds is our evaluation evidence; dropping part of it because it makes us uncomfortable is not allowed. Rather, we should hold any claim that R² measures “explained variance” in such cases, or prefer an alternative metric. If the report omitted folds or used some heuristic to avoid NaNs, that would be a red flag. We keep all folds visible so that the evaluation transparency is preserved.
8. Keep pooled R² separate from mean fold R²
It is important to distinguish between the mean of fold R² and the pooled R². In cross-validation, these two can differ. We have already seen the mean of fold-level R² was 0.333 (using default replacements). Now consider treating all 9 test predictions as one combined set: compute a single R² across all test cases. That means using the global target mean rather than fold-specific means.
The pooled calculation uses the nine “held-out” predictions (three from each fold):
All actual y: [5,5,5, 6,6,6, 4,5,6] (9 values).
All predicted y: [5,5,5, 5,5,5, 5,5,5] (constant 5’s).
Compute SSE = Σ(yᵢ – 5)² = (0+0+0) + (1+1+1) + (1+0+1) = 0 + 3 + 2 = 5.
Compute SST = Σ(yᵢ – mean(y))². The global mean of y is (5+5+5+6+6+6+4+5+6)/9 = 48/9 ≈ 5.3333.
Then SST = (5–5.333)²+(5–5.333)²+(5–5.333)² + (6–5.333)²+(6–5.333)²+(6–5.333)² + (4–5.333)²+(5–5.333)²+(6–5.333)².
Numerically, SST = 0.111+0.111+0.111 + 0.444+0.444+0.444 + 1.777+0.111+0.444 ≈ 4.0 (by symmetry, it sums to 4).Therefore pooled R² = 1 – SSE/SST = 1 – 5/4 = -0.25.
So the pooled R² is -0.25, meaning the model does worse than a constant prediction at the global mean (which it is doing somewhat). This is quite different from the mean of the fold R² values (0.333). The difference arises because the fold-level R² used fold-specific means, whereas pooled R² uses the overall mean of all test cases. It’s like comparing apples and oranges.
This example shows we must be explicit about which R² we report. Averaging fold R² is a common cross-val summary (and equals the default “test_score” if you only supply one scorer). But the pooled R² is another valid metric of the entire prediction set. It is not correct to say they are the same or to mix them. For our fixed setup, cross_validate did not compute pooled R²; it averaged folds. The pooled R² actually is -0.25, which if presented alone would look terrible (and correctly so, since the model is no better than always predicting 5, which is the overall mean 5.333, on average).
In short: fold-mean R² and pooled R² answer different questions. Our report must keep them separate. We might report the mean of folds for consistency with cross-validation, but we should not claim it’s the same as “variance explained on all data.” In fact, here they are quite different signs. The pooled R² uses a different denominator (global variance) and includes the error on each fold scaled to that global variance.
Mathematically, there is no paradox: the model was especially bad on one fold with respect to global variance. The key point for the auditor is to recognize this distinction.
The cross-validated “mean R²” of 0.333 is not the same as the “combined R²” of -0.25, so one should not cite the former as if it were a single-dataset R². If an evaluation dashboard or stakeholder wanted the global R², it would have to pool the predictions (or equivalently compute it separately). But then our fold-specific issues would manifest differently (pooled R² would have been flagged as negative, avoiding the false rosy 0.333).
We label our populations clearly: fold-level R² uses each fold’s mean (which erases between-fold variation), whereas pooled R² uses the global mean. In this example they disagree. For completeness:
from sklearn.metrics import r2_score
y_true_all = np.array([5,5,5,6,6,6,4,5,6])
y_pred_all = np.array([5,5,5,5,5,5,5,5,5])
print("Pooled R²:", r2_score(y_true_all, y_pred_all))
Expected: Pooled R²: -0.25.Thus, an evaluation report should not conflate these. If one method of averaging (the default cross-validated mean) is used, it must be documented that the values are per-fold R². Otherwise, a reader might incorrectly assume it’s the R² over the entire test set. We keep them separate and never use pooled R² to “repair” the constant-target issue, because it’s a different target of calculation.
9. Check sample-count and near-constant boundaries
We should also check boundary conditions of the metric function itself. The scikit-learn doc warns that R² is undefined for less than 2 samples. Let us verify:
Fewer than two samples: If we have only one sample (n=1), there is no variance and no degrees of freedom for R². Scikit-learn explicitly returns NaN for r2_score when n_samples < 2. For example:
>>> r2_score([5], [5])
nan
This occurs regardless of force_finite. A single sample yields nan. This is a built-in check in scikit-learn. It is not “repaired” by force_finite: even with force_finite=True, R² on one point remains NaN (see the r2_score documentation). We should not rely on force_finite to save us here; instead we should ensure our inputs always have at least two test samples. If an evaluation accidentally has one-sample test folds, that itself is a design bug that we must address (e.g. require at least 2 cases per fold in the contract). In any case, this scenario does not apply to our fixture (each fold has 3 samples).
Empty input: If cross_validate tried to score on an empty test set, scikit-learn’s internal data checks (in check_array or check_X_y) would raise a ValueError before even calling r2_score. We do not attempt such a case, but it’s worth noting: an “empty fold” would cause an immediate error, not a silent NaN. Thus we have to ensure our splitting strategy never produces empty splits (which we have). This is outside R²’s own behavior and more a data-check error.
Near-constant targets: Suppose the targets are almost constant, but not exactly. For example, consider y_true = [5, 5, 5.001] and y_pred = [5, 5, 5]. This dataset has a very small SST (target variance is tiny), but not zero. Then R² is well-defined (no division by zero) but the result can be extreme. Indeed, SSE = (0+0+0.001²) = 1e-6, SST = something small (approx 6.667e-7, as worked out earlier), so R² ≈ 1 - (1e-6/6.667e-7) = -0.5. This is a finite but large negative value. The exact number depends on the small variance, but the key point is: if we perturb a constant dataset slightly, r2_score stops being undefined and starts giving finite numbers which can be very large magnitude (positive or negative) depending on predictions. Therefore, handling near-constant data is again a matter of interpretation, not numeric failure. We won’t fix this by adding an epsilon in the formula or any hack. The user should see that R² “exploded” and take away that the metric is unreliable in this regime.
In summary for this section: we verify that truly degenerate cases (one sample or zero samples) are handled by pre-checks or the metric itself (NaN is output). We also confirm that slight variance yields finite but potentially misleading R² values. There is no hidden “magic epsilon” in r2_score; it uses pure sums of squares. Thus, any small non-zero variance makes the denominator non-zero, and R² behaves normally.
10. Report target-unit errors without changing the evidence
Given that R² may be unreliable here, one might report other metrics for clarity. We already calculated each fold’s MAE in target units (the average absolute error). These are well-defined and have clear meaning: they answer “on average, how wrong are our predictions by X units”. We should report them alongside R² to give full context. In our fixture:
Fold | MAE (computed) |
0 | 0.000 |
1 | 1.000 |
2 | 0.667 |
Mean MAE | 0.556 |
We computed this in Section 5. In cross_validate we got the negative MAE array; negating it gave the same numbers. We can include these in our result table. Notice that MAE is always non-negative and well-behaved.
Including MAE does not “fix” or overwrite R². It provides a different angle: if the decision question is “How far off are our predictions on average?”, MAE answers that in the original units. For decision-makers concerned about actual error size (rather than “fraction of variance”), MAE can be more relevant. However, switching to MAE requires a change in the evaluation criterion, which must be explicitly declared in advance. In a contract, we would specify “alternate metric: MAE” if R² is known to be problematic. Without such a rule, simply reporting MAE as if it replaces R² is also misleading. We can report both, but we must not conflate them.
Refonte’s scoring conventions remind us that adding metrics is fine to aid interpretation, but it doesn’t magically change the original metric’s validity. We should clearly label MAE with its sign convention: since scikit-learn typically returns negative MAE when used in a scorer, we explicitly flipped the sign for readability. Our final report might say “Mean Absolute Error = 0.556 (lower is better)” to contrast with R² which is “higher is better”. Including target-unit errors without altering the R² output is part of “reporting evidence without altering it”.
10.1 A useful alternative metric does not make R² defined
It bears repeating: using MAE or any other metric is not a fix for R². If our target actually has zero variance on some folds, R² mathematically remains undefined on those folds no matter what else we report. We can, however, avoid using R² altogether and rely on MAE or another measure for decision-making. But that requires updating the evaluation rule: R² would no longer be the primary metric. If that choice is made, it should be done deliberately and documented. One cannot simply say “we’ll use MAE for fold 0 and 1 since R² was undefined, and R² for fold 2” in a mixed way.
Thus, in the audit we keep the R² evidence as-is (with its NaN/–Inf) and separately report the MAE. If stakeholders wanted a single summary, they could consider mean MAE = 0.556 as an alternative indication of performance. But again, to convert between error and “variance explained” requires domain reasoning. There is no rule like “if R² undefined, substitute MAE into the report”. Any such substitution must be part of a predefined evaluation plan. This ensures clarity: either we stick with R² (and accept its undefined nature) or we switch the metric (and rescind any R²-based claims).
In summary, MAE gives us an understandable number (0.556 units error), but it coexists with the R² results; it does not retroactively define R². We preserve the original metrics, including their non-finite values, in our reporting.
11. Repair the scorer or the report deliberately
Given the above facts, how do we “repair” a report that might otherwise mislead? There are two main approaches:
Option 1: Report raw R² and disclaim it. We can configure our scorer to not mask undefined values, and then explicitly communicate that to the reader. For example, we could rerun cross_validate with our R2_raw scorer (as in Section 6) and then present the raw array:
raw = results['test_R2_raw']
# For reporting, keep NaN/Inf visible:
print("Raw R² scores by fold:", raw)
# Optionally, compute an "aggregate" ignoring non-finite:
finite = [x for x in raw if np.isfinite(x)]
if finite:
    print("Mean R² over finite folds:", np.mean(finite))
else:
    print("No finite R² to average")
This would yield something like:
Raw R² scores by fold: [ nan, -inf, 0.0 ]
Mean R² over finite folds: 0.0
We would then annotate that two folds were undefined and the third gave 0.0. We could choose not to compute an overall mean at all, or we could state “No valid average R²” or “reported R² omits undefined fold” if we had pre-specified such a rule. At minimum, the report table of results should include the raw R² values with their NaN/Inf (perhaps as text or as a special symbol) and a clear note. That ensures readers see that something unusual happened. This “repair” is essentially reporting what really happened. It might involve a small code fix (using a raw scorer or manually checking for NaN), but mainly it is a documentation fix.
Option 2: Change the metric and recalc. If during review we decide that R² is simply not usable here, we might switch to a different metric entirely. For example, we could declare “Primary metric = MAE” and drop R² from acceptance criteria. Then we would regenerate the report showing MAE as the main score (which was 0.556). In cross_validate, we could omit R² scorers or ignore them. However, this is a bigger change: it alters the entire evaluation design. According to proper process, such a change would need approval and justification. In the context of a playbook, this is labeled a rebuild step (see Section 12) because it goes beyond fixing a small bug and changes a core decision.
We should not do vague fixes like “impute R²=0 for any NaN” or “drop constant cases silently.” Any repair path must be explicit. We might put code comments like:
# LEGACY REPORT: used average R² including forced values.
# REPAIR SUGGESTION: instead use raw R² and footnotes, or use MAE as primary metric.
in our documentation. The key is transparency.
If we choose Option 1, the repaired report table might look like this (including the raw R² column):
Fold | R² (raw) | R² (default) | MAE (± sign) |
0 | NaN | 1.0 | 0.000 |
1 | -Inf | 0.0 | 1.000 |
2 | 0.000 | 0.0 | 0.667 |
Mean | (see note) | 0.333 | 0.556 |
With a note: Fold 0 and 1 have no defined R² (target constant), so raw R² is NaN or -Inf. The “default” column shows scikit-learn’s substituted values. Mean of R² is only reported from defaults (0.333) but has no statistical meaning due to the undefined folds.
If Option 2 (switch metric) were chosen, the report might simply eliminate R² columns and say “R² not applicable” or similar, focusing on MAE or another chosen metric. That would be a fundamental redesign (Section 12).
In either case, we must reconcile with any previously published summary. If the public facing result had said “R²=0.333”, we would now correct it. If internal documentation existed, we’d mark the change. Perhaps we maintain a versioned record of evaluation: “Revision 1: published R²=0.333; Revision 2: clarified that this average included two undefined folds (attached evidence).”
The essence of repair is intentional revision with rationale. We do not quietly replace values without note. Any new metric must be justified by the team’s evaluation contract. The repaired report should include all evidence (fold IDs, SST, SSE, warnings) and clearly state what was done. This may involve putting that evidence in an annex or extended table, so that a reader or regulator can audit the claim directly.
12. Accept, repair, hold, or rebuild the evaluation
After inspecting the evidence ledger, we make a final recommendation. The table below summarizes decisions and their criteria in this scenario:
Situation | Action | Explanation/Notes |
Report uses default R² average without disclosing folds | HOLD | Unsupported claim. The headline R² (0.333) ignores two undefined cases. Claim of “variance explained” is invalid without context. At minimum, stop publication until fixed. |
Same report, but footnotes/disclaimer added | Repair | Acceptable if it explicitly notes “fold-level R² undefined for constant targets (NaN or –∞)” and clarifies what 0.333 means. Report must include raw values. |
Use R²_raw in report (with NaN/–Inf shown) | Accept/Repair | Can accept only if the report is labeled clearly and doesn’t interpret NaN/–Inf as numbers. If the context (contract) allows noting these, it could be an accepted summary (with limitations). |
Remove R² entirely and use MAE as the metric | Rebuild | A contract change: requiring justification and approval. Would need new baseline, rewritten acceptance criteria, etc. (treated as evaluation redesign). |
Re-run with new folds or model | Rebuild | Changing data or model requires a new evaluation path. Not a minor fix. |
Everything properly documented (raw scores, warnings) | Accept | If report already included full fold data and correct interpretation, R² can be accepted as-is (with the reader informed of its scope). |
In short, accept only if the report fully discloses the issue (e.g. raw R² shown and substituted vs. actual meaning explained) and does not claim unsupported results. Repair if minor clarifications or additional metrics fix the misunderstanding. Hold if the published claim is inaccurate (e.g. “R²=0.333 means 33% variance explained” without noting constant targets) and requires revision. Rebuild if the evaluation design itself must change (new metric, new splits, new model, etc.), which is outside the scope of mere bug-fixing.
This mirrors a QA mindset: as Refonte’s QA automation guide stresses, decisions should follow a quality checklist or test matrix, not guesswork. For example, if the score was used for a release gate, a “reviewer” must see this ledger and apply the above logic. If any action above is taken, it should be documented (e.g. commit to version control, or a change log in the evaluation contract).
12.1 Evidence required before an evaluation redesign
If one decides that R² is fundamentally the wrong metric here, a redesign of the evaluation is needed. Before doing that, however, the team should collect evidence:
Data analysis: Show why the constant target occurred. Is it a data error, or inherent to the problem? Can future data have non-zero variance? If constant by design, maybe R² was known to be irrelevant from the start.
Impact assessment: Quantify how the choice of R² vs another metric (e.g. MAE or explained variance only on varying folds) would change decisions. For instance, does selecting MAE as the primary criterion lead to a different model conclusion?
Stakeholder alignment: Did the model contract allow using R² only if variance >0, else using an alternate? If not, a new contract might be needed.
Alternative validation: Possibly gather more data or create folds differently. If fold 0 or 1 were not supposed to be constant, maybe something is wrong in data splitting. Any change in folds must be justified (maybe fold definitions were too coarse).
Approval: As in QA sign-off, any change in metric or split needs sign-off by an authorized reviewer (product owner, model governance committee, etc.).
The goal is to ensure that a fix is not made in isolation. In practice, one might say: “We have discovered that two folds had zero variance, making R² undefined on those. If we want to use R² meaningfully, we need to revise the evaluation. For example, we propose (a) recomputing on a fresh dataset with sufficient variance, or (b) switching to MAE as primary metric. We have run trial (b) and found MAE=0.556 overall, with error breakdown [0.0, 1.0, 0.667]. Please review this evidence and approve either continuing with R² (with disclaimers) or moving to a new metric/design.”
This evidence-justification step reflects the thorough approach in Refonte’s QA automation guide and model-evaluation guide. Only with clear analysis can we avoid simply patching a superficial bug and then facing larger issues down the line.
13. Assign ownership to metric meaning and fold coverage
Finally, we must clarify who is responsible for each piece of the process. In a real organization:
The data scientist / ML author typically picks the initial metric (R² in this case) and defines the split. They should document why R² is chosen or not, and ensure code is set up correctly (e.g. by using make_scorer properly). They produce the first draft of the evaluation report.
The ML evaluation engineer or QA reviewer runs the code, captures the outputs (including NaNs, warnings, indices), and compares them to the oracle values. They ensure the environment is as specified (versions, warnings policy). They hold the knowledge of metrics plumbing and are tasked with flagging any irregularities like undefined scores.
The report owner or data scientist lead compiles the final report for stakeholders. They must ensure it includes fold-level detail or notes. If the report is to be published, they are responsible for phrasing (e.g. not saying “explains X% of variance” when target is constant). They coordinate any decisions about accept/repair/hold/rebuild.
The independent reviewer or governance committee (perhaps a senior data scientist or model risk manager) reviews the evidence and the final wording. They have the authority to approve the report or require a redesign (like using a different metric or dataset).
Throughout, every step should be recorded. The evaluation manifest might include: software versions, data schema, fold definitions, model parameters (DummyRegressor(constant=5)), scorer settings (force_finite=True/False), and the raw result table. If automated, unit tests should be added: for instance, test that when y is constant, R² is reported as NaN with force_finite=False. That prevents regressions (if future sklearn behavior changed, the test would catch it).
Refonte’s materials emphasize that model validation is a team effort: data scientists handle modeling and metrics rationale, ML engineers handle code implementation, and QA or governance teams ensure the process. In this scenario, responsibilities overlap: for example, either the data scientist or the ML engineer could notice that two R²s were undefined, but it ultimately falls to whoever publishes the report to catch it.
The release artifact (e.g. the model card or evaluation document) should explicitly state the score semantics: “Reported R² is averaged across folds. Fold-level results were [NaN, -∞, 0.0] under raw calculation, with defaults shown. MAE was [0.0, 1.0, 0.667].” It should also list which version of the scorer was used (default vs raw), and note any warnings. This maintains traceability.
By clearly assigning these roles, we ensure there is no confusion about “who checks what.” In a well-structured team, the data scientist designing the experiment bears some accountability, but the final check is typically done by someone else (a review to catch exactly this kind of oversight). As the Refonte guide on roles suggests, both data scientists and ML engineers must master evaluation skills, and this includes understanding when metrics are undefined or need adjustment. Thus, the outcome of our audit, whether to accept or repair, is a joint responsibility, not something that “automatically happens.”
14. Develop evaluation judgment with Refonte Learning
Understanding these detailed evaluation nuances is exactly the kind of competence that Refonte Learning’s Data Science & AI program aims to build. In that 3-month program (12–14 hours/week) students learn statistical modeling, sound validation practices, and the problem-solving needed to interpret metrics correctly.
The coursework and projects train future data scientists to ask: “Does my metric actually reflect the story I want to tell?” This exercise (tracing through each fold’s R², checking the effect of force_finite, and deciding how to report the results) exemplifies the critical thinking taught in those courses.
By designing this reproducible check, we are practicing a mentor-guided, evidence-based approach to model evaluation, as recommended by Refonte’s curriculum and QA emphasis.
For readers interested in deeper training on these topics, the Refonte Data Science & AI program (3 months, project-based) covers exactly the foundations used here: statistics, Python, model evaluation, and rigorous reporting. It emphasizes building defensible claims from data, not just chasing higher metric numbers. This case study (of a “finite” R² hiding undefined fold scores) is a practical example of the lessons taught: always check the underlying data and logic behind a number. Refonte’s coursework would challenge students to uncover this issue and to tie it back to core competencies like statistical reasoning, reproducible workflows, and clear communication.
In conclusion, our audit shows that the raw evidence permits the claim “mean R² = 0.333 with noted limitations.” We should not accept an unsupported statement like “33.3% variance explained” without qualifiers. The correct path is to either accept the reported R² with full disclosure or, if possible within the project’s rules, switch to a more meaningful metric like MAE. This example thus illustrates the importance of a disciplined metric-interpretation process, a skill that Refonte Learning cultivates through its Data Science & AI training.