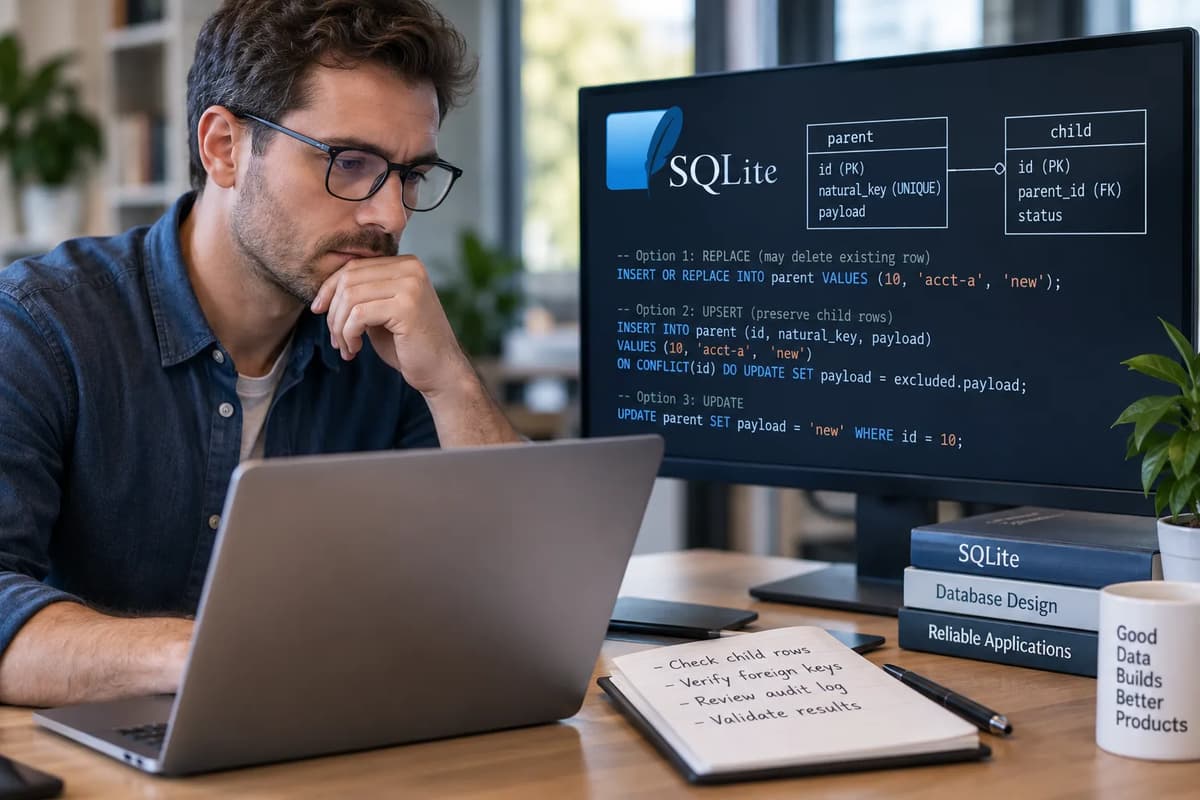
When an application helper uses INSERT OR REPLACE expecting an in-place update, a hidden delete may drop dependent rows without warning. This blog post looks at a specific write contract: we have a parent row (ID=10, natural key “acct-a”) with two approved children, and we want to change only the parent’s payload from “old” to “new” while preserving both children.
The write helper runs INSERT OR REPLACE INTO parent VALUES (10, 'acct-a', 'new') inside a transaction. Superficially, the parent still exists with ID=10, changes() returns 1, and no foreign-key errors occur. Everything seems green.
Question: Should we accept this change or not? The answer depends on evidence beyond mere transaction success. In this controlled SQLite lab (CPython 3.13.5, SQLite 3.46.1, in-memory database), we compare the actual post-write state to an authoritative manifest of rows that must remain.
We will explicitly enable PRAGMA foreign_keys=ON (outside any transaction) and set PRAGMA recursive_triggers on or off as needed. We record the recursive trigger setting for each test. The manifest is declared in our test code: parent ID=10, natural_key='acct-a', payload allowed to change, children (101,10) and (102,10) expected intact.
We then run several branches: a conflicting REPLACE, an explicit UPSERT, a plain UPDATE, and negative-control inserts. After each write, we capture SELECT changes(), the full parent/child tables, the delete-audit table (triggered on parent delete), and PRAGMA foreign_key_check. We do not rely on Python’s cursor.rowcount or any ORM behavior; instead we use documented SQLite tools (e.g. changes()) and our own manifest gate.
The findings reveal that the REPLACE variant does indeed remove the children via ON DELETE CASCADE, even though the parent ID remains. This blog demonstrates why seeing the same parent primary key is not enough evidence that the intended child rows survived. We then discuss repair: using an UPSERT or UPDATE, gating the write on an independent child-row manifest, and recovery options if a loss is committed.
SQLite’s documentation explains REPLACE semantics and UPSERT behavior, foreign key cascades, and how changes() works.
At each step we check against the declared manifest, not just row counts. In the end, we’ll summarize an evidence-first playbook: if the full content matches the contract, accept; if not yet committed, rollback or repair; if committed, only recovery from authoritative source can restore lost rows. This ensures our database is not merely “valid” but preserves the business-critical parent-child population.
State the write contract in terms of preserved rows
Our scenario begins with a declared manifest of existing data: a single parent row and its two child rows. The parent table has a primary key id=10 and a unique natural key acct-a. Its payload column initially contains "old". The child table has two rows, (id=101, parent_id=10) and (id=102, parent_id=10), both referencing the parent. We also have a delete_audit table to record when a parent row is deleted.
The only allowed change is that parent.payload should change from "old" to "new". Importantly, the parent’s ID (10) and natural key (‘acct-a’), and the two child rows, must remain exactly as they were (except for the payload update). In other words, the referential population of children is part of our contract.
Concretely, before running any write, we declare in our test code:
expected_parent = {"id": 10, "natural_key": "acct-a"}
expected_children = {(101, 10), (102, 10)}
These values are the authoritative specification, not something we will re-query after the write. We then apply the candidate SQL (e.g. INSERT OR REPLACE) and later compare the actual database rows to this manifest. If the actual rows match the declared manifest (ID=10 with payload "new", children 101,102 present), the write fulfilled the contract. If not, we must reject or repair.
This is a conscious contrast to relying on abstractions: for example, a helper function named save() or upsert() is not evidence of correctness. For both REPLACE and UPSERT, we show the actual SQL and its effects. We gate acceptance on full content, not just that the parent exists or that a single row was changed.
This approach echoes best practices in data integration: define and check an API contract for what data must result. Refonte’s article on database integration strategies stresses clear contracts between system components. In our case the contract is: “Parent ID 10, natural_key ‘acct-a’ persists, payload may change, and the two specific child rows must still be present.”
Distinguish replacement from an in-place update
SQLite’s INSERT OR REPLACE syntax suggests an update, but its semantics are different from a true UPDATE. The official doc says that on a UNIQUE or PRIMARY KEY conflict, REPLACE deletes the existing row and then inserts the new one. In contrast, an UPSERT (ON CONFLICT DO UPDATE) updates in place. Critically: REPLACE triggers cascade deletes, whereas a proper update does not.
As the docs state, the REPLACE algorithm “deletes pre-existing rows that are causing the constraint violation prior to inserting… the current row”. Those deletions activate any defined ON DELETE actions or triggers. For our child-foreign-key ON DELETE CASCADE setting, deleting the parent means all children referencing it will be deleted.
The INSERT ... ON CONFLICT DO UPDATE (UPSERT) clause, by contrast, targets a specific uniqueness constraint. For example, INSERT ... ON CONFLICT(natural_key) DO UPDATE SET payload=excluded.payload will only update the row where natural_key matches, without touching other rows. In our case, that leaves the original parent ID=10 intact (just with a new payload) and leaves its children untouched. If the conflict target is a natural key, the primary key is not forcibly changed to the new value. In summary:
1. INSERT OR REPLACE on the primary key 10 will delete and re-insert the parent, firing cascades.
2. INSERT ... ON CONFLICT(natural_key) DO UPDATE will simply update payload on the existing parent (ID stays 10).
3. UPDATE does the same as UPSERT in this scenario (update matching row). Importantly, after an INSERT OR REPLACE, the final row might have the same ID, but there was a delete-intermediate. Seeing id=10 afterward does not guarantee continuity of data. Relying on identity alone can miss the silent deletions. The analogy: REPLACE is a delete+insert, not an “edit in place.” As the SQLite UPSERT documentation emphasizes, UPSERT only intervenes for unique constraint violations and can be directed specifically by conflict target.
In the context of database operations, this is also a governance issue: if a helper blindly uses REPLACE to bypass unique constraints, it might violate our application’s data integrity expectations. That’s why database maintainers must be aware of REPLACE’s behavior, as discussed in Refonte’s database operations fundamentals blog. We will soon see how these different statements play out in practice.
Build the parent, children and audit fixture
We start by coding the fixture in Python (with SQLite in-memory) so we can run each branch cleanly. The relevant tables and trigger are:
CREATE TABLE parent (
  id INTEGER PRIMARY KEY,
  natural_key TEXT NOT NULL UNIQUE,
  payload TEXT NOT NULL
);
CREATE TABLE child (
  id INTEGER PRIMARY KEY,
  parent_id INTEGER NOT NULL REFERENCES parent(id) ON DELETE CASCADE
);
CREATE TABLE delete_audit (old_parent_id INTEGER NOT NULL);
CREATE TRIGGER record_parent_delete
AFTER DELETE ON parent
BEGIN
  INSERT INTO delete_audit VALUES (old.id);
END;
This setup ensures that if a parent row is deleted, its id is recorded in delete_audit. The child table has ON DELETE CASCADE, so child rows are deleted automatically when a parent is deleted. We then insert one parent and two children:
INSERT INTO parent VALUES (10, 'acct-a', 'old');
INSERT INTO child VALUES (101, 10), (102, 10);
Now our manifest is: parent (id=10,natural_key='acct-a',payload='old') and children (id=101,parent_id=10), (id=102,parent_id=10). We will compare this to the post-write state. For reproducibility, we do this setup fresh for each branch of the test. The Python code to establish the connection and fixture is:
import sqlite3

# Use an in-memory DB and manage transactions manually.
con = sqlite3.connect(":memory:", isolation_level=None)
cur = con.cursor()

# Enable foreign key enforcement and assert it is ON.
cur.execute("PRAGMA foreign_keys = ON;")
assert cur.fetchone()[0] == 1  # Should return 1 (ON)

# Build tables and trigger.
cur.executescript("""
CREATE TABLE parent (
  id INTEGER PRIMARY KEY,
  natural_key TEXT NOT NULL UNIQUE,
  payload TEXT NOT NULL
);
CREATE TABLE child (
  id INTEGER PRIMARY KEY,
  parent_id INTEGER NOT NULL REFERENCES parent(id) ON DELETE CASCADE
);
CREATE TABLE delete_audit (
  old_parent_id INTEGER NOT NULL
);
CREATE TRIGGER record_parent_delete
AFTER DELETE ON parent
BEGIN
  INSERT INTO delete_audit VALUES (old.id);
END;
-- Insert initial data:
INSERT INTO parent VALUES (10, 'acct-a', 'old');
INSERT INTO child VALUES (101, 10), (102, 10);
""")
We also check PRAGMA recursive_triggers explicitly. By default, SQLite leaves recursive triggers off, meaning our record_parent_delete trigger will not fire if the delete is part of the same statement (like INSERT OR REPLACE) unless we turn recursion on. In our branches below, we will run each test both with PRAGMA recursive_triggers = OFF and = ON to see the difference. Note that setting this pragma affects the entire connection, so we must reset the connection or re-issue it before each branch.
Assert the connection before starting the transaction
Before we begin any transaction, we confirm foreign_keys is indeed ON. In SQLite, foreign key enforcement is disabled by default and must be enabled per connection. We already did PRAGMA foreign_keys=ON and asserted it. We also note the default for recursive_triggers is OFF, so we’ll explicitly set it in each test. This ensures our tests are not inadvertently passing due to default settings. For example:
# Confirm foreign_keys is ON (1) and default recursive_triggers is OFF (0).
cur.execute("PRAGMA foreign_keys;"); print("foreign_keys =", cur.fetchone()[0])
cur.execute("PRAGMA recursive_triggers;"); print("recursive_triggers =", cur.fetchone()[0])
If these do not return (1,0), we abort, because our lab assumes foreign keys active and a known recursive triggers state. This setup code is run once per fresh branch, not inside the BEGIN/COMMIT below, to align with best practices (enforce constraints outside transaction).
Run REPLACE while keeping the same parent ID
Now we test Case A: the faulty INSERT OR REPLACE. We start an explicit transaction and execute:
BEGIN;
INSERT OR REPLACE INTO parent VALUES (10, 'acct-a', 'new');
SELECT changes();
SELECT  FROM parent ORDER BY id;
SELECT  FROM child ORDER BY id;
SELECT * FROM delete_audit;
PRAGMA foreign_key_check;
Key expectations: because of PRIMARY KEY=10 conflict, SQLite will delete the existing parent 10 and then insert a new parent 10. Because of ON DELETE CASCADE, both children will be deleted in that process.
We capture the outputs in code. Here is representative code (showing only the queries, not the full Python loop):
BEGIN;
INSERT OR REPLACE INTO parent VALUES (10, 'acct-a', 'new');
SELECT changes(); -- direct-change count
SELECT  FROM parent;
SELECT  FROM child;
SELECT * FROM delete_audit;
PRAGMA foreign_key_check;
Expected result (recursive_triggers=OFF):
4. SELECT changes() returns 1 (the direct INSERT of the new row). It does not count the deletions of the children or the replaced row (those are auxiliary changes).
5. parent table shows one row: (10, 'acct-a', 'new'). The parent ID still appears as 10, but note its payload is updated.
6. child table is now empty: both (101,10) and (102,10) are gone. This is the crucial silent effect: the children were cascade-deleted.
7. delete_audit is empty when recursive triggers are OFF, because the DELETE that happened as part of the REPLACE did not fire the AFTER DELETE trigger.
8. PRAGMA foreign_key_check is empty (no output), meaning no dangling references; it’s satisfied that there are no children referring to a missing parent.
9. The unambiguous sign of trouble is that the child table lost its rows.
If instead we had PRAGMA recursive_triggers = ON for the same test, everything above is the same except the trigger fires: delete_audit would have one row containing the old parent ID (10). We will show that in the next section. But even with recursive triggers off, the children are gone.
This demonstrates that although we got one change, saw the parent still (with ID=10), and no foreign-key complaints, the actual business data (the two child rows) did not survive. A naive check that “the parent is present and no constraint was violated” would falsely approve this write.
The final parent key can look unchanged
Notice that after INSERT OR REPLACE, the final parent has id=10 just like before. A quick identity check (parent ID equals old ID) would say “the parent is still there”. But that is insufficient. The REPLACE strategy deleted the original parent row (ID 10) and replaced it, so any delete hooks or cascades took place. The ID value coincidentally matches, but the row is actually new.
Thus, tests must go beyond key equality. As we see, changes() = 1 only counted the inserted row. It did not reveal that two deletes happened to the child table. We will cement this lesson: the identity continuity was illusory, because the children were lost.
Explain why the usual green checks still pass
Why did our initial sanity checks appear to succeed? Let’s enumerate the checks that might be performed after a write:
10.SQL executed without error. That’s true; SQLite didn’t return an error on the REPLACE.
11.Parent row exists and key matches. We see (10, ..., 'new') in parent. The primary key 10 is present as expected.
12.changes() equals 1. We got exactly 1, which matches the number of parent rows changed. That matches the heuristic “one row changed.”
13.PRAGMA foreign_key_check returns nothing. Indeed, there are no orphaned references left.
All these signals are “green flags,” but they do not detect the missing children. Why not? As SQLite’s C API docs explain, changes() only counts direct changes caused by that statement. It explicitly excludes “auxiliary changes caused by triggers, foreign key actions or REPLACE.” Thus, the cascading deletes of two child rows are not counted.
Likewise, foreign_key_check only reports violations; in our case, there are none because the cascade cleaned up orphans automatically. So it reports zero issues, giving a false sense of security.
In short, there is a gap between referential validity and our business rule. The database remained referentially valid (no orphans, foreign key satisfied), but it failed our preservation contract. The children were removed to maintain integrity silently. This is by design: REPLACE enforces uniqueness by deletion, and cascade enforces referential integrity by deletion. But our application needed those children to persist.
This illustrates that checking only that some valid state exists is insufficient. We need to check the exact population of rows we care about. In our lab, we will do a manifest comparison for that. For now, note the documented behavior: “Only changes made directly by the INSERT… are counted”, so the 2 cascaded deletions are invisible to changes().
Also, REPLACE’s special behavior is that it does not invoke the update hook for replaced rows nor increment the change counter, further reinforcing that deletion is hidden.
Therefore, relying on these implicit counters is dangerous. We must explicitly query the tables. In the next section, we will break apart what is counted and what triggers fire.
Separate cascading actions from delete-audit visibility
We now vary the recursive_triggers setting to see how it affects our audit table. First, we repeat Case A with PRAGMA recursive_triggers = OFF (the default). We already saw the results above: parent exists, children gone, no audit row.
Next, we reset the database and do Case A again with PRAGMA recursive_triggers = ON before beginning. The SQL is the same:
BEGIN;
PRAGMA recursive_triggers = ON;
INSERT OR REPLACE INTO parent VALUES (10, 'acct-a', 'new');
SELECT * FROM delete_audit;
Now, the cascade delete (the parent-deletion part of REPLACE) will fire the record_parent_delete trigger, because recursive triggers allows a statement-triggering trigger to itself fire other triggers. As a result, the delete_audit table will contain one row (10) after the statement. However, apart from that, the situation is identical: both children were still cascade-deleted.
We summarize:
14.With recursive_triggers = OFF: after REPLACE, delete_audit is empty, but children are gone. No record of the delete in user code.
15.With recursive_triggers = ON: after REPLACE, delete_audit has (10), showing the old parent was deleted, and children are also gone. The audit row provides extra evidence of the deletion.
Neither setting can substitute for our manifest check. When OFF, no audit row might suggest (incorrectly) nothing happened. When ON, the audit row reveals the parent’s deletion. But in both cases, the children are removed. Therefore, absence of an audit entry is not proof that no delete occurred; it may simply mean recursive triggers were disabled. We must not rely on trigger logs alone.
No audit row is not proof of no delete. SQLite’s conflict-resolution documentation says delete triggers fire only if recursive triggers are enabled, and default behavior is OFF. That means application code could miss a delete.
We will therefore always do the manifest check (comparing exact child IDs) rather than trust the audit table. In practice, an application could enable recursive triggers so it does get a log of deletes, but it still should verify actual data.
Triggers and hooks (like the update hook or total_changes) are auxiliary and might change in future releases, but manifest comparison is future-proof.
We should also note: the sqlite3_update_hook and sqlite3_total_changes() are irrelevant here. The docs explicitly say REPLACE does not invoke the update hook for replaced rows, and does not increment the change counter. We have not used those, relying only on changes() and direct queries. Our approach is robust: we inspect the actual rows, not a hook count.
Use an explicit UPSERT that leaves the stored key alone
To fix the problem, we switch to a proper upsert on the natural key. Starting from the same initial fixture, do:
BEGIN;
INSERT INTO parent VALUES (20, 'acct-a', 'new')
ON CONFLICT(natural_key) DO UPDATE SET payload = excluded.payload;
SELECT changes(), FROM parent, FROM child, * FROM delete_audit, PRAGMA foreign_key_check;
Here we attempted to insert a parent with id=20 but the same natural_key='acct-a'. SQLite sees a UNIQUE constraint conflict on natural_key, so it performs the DO UPDATE clause. Crucially, it updates the row that currently has natural_key='acct-a' (which is the original parent 10), setting payload='new'. It does not insert a new row 20, and it does not change the id; the original parent ID=10 remains.
Expected outcome:
16.changes() will be 1 (the one row updated). No delete happened, so delete triggers do not fire.
17.parent table ends up (10, 'acct-a', 'new'). The stored ID is still 10.
18.child table still has (101,10) and (102,10) intact. No cascade was triggered.
19.delete_audit is empty (we did not delete parent).
20.foreign_key_check is empty (still valid).
This preserves exactly the intended manifest. The difference from Case A is subtle but crucial: by targeting the natural key, the UPSERT did not induce a delete. If our code had instead written UPDATE parent SET payload='new' WHERE natural_key='acct-a', the effect would be identical. Thus, both UPSERT and a direct UPDATE work for this contract.
This exemplifies API contract design: the database action matches the intended contract. We explicitly chose a conflict target (natural_key) to reflect our business identity.
One more subtlety: some might think adding excluded.id in the UPSERT (e.g. DO UPDATE SET id=excluded.id, payload=...) would unify the IDs, but that would in fact be an attempt to change the primary key, and is not supported by simple UPSERT (and would break foreign keys). In any case, our UPSERT left the stored key alone as we wanted.
Compare ordinary UPDATE and legitimate new insertion
As a control, we run a plain UPDATE to show that it similarly preserves children:
BEGIN;
UPDATE parent SET payload = 'new' WHERE natural_key = 'acct-a';
SELECT changes(), FROM parent, FROM child;
The result is identical to our UPSERT case: parent is updated in place, children survive. This confirms that the issue was not a general SQLite bug, but specifically the delete-then-insert behavior of REPLACE.
Next, we test the insert path of UPSERT for a truly new key. We reset and do:
BEGIN;
INSERT INTO parent VALUES (20, 'acct-b', 'fresh')
ON CONFLICT(natural_key) DO UPDATE SET payload = excluded.payload;
SELECT FROM parent; SELECT FROM child;
Since 'acct-b' is not yet in parent, this just inserts a new parent row (20,'acct-b','fresh'). The original parent (10,'acct-a','old') remains (though we may have updated it in a previous branch, so we reset), and children (101,10),(102,10) stay attached to parent 10.
After this, the DB has two parents. If an ORM had blindly done this thinking to reuse the parent, it would have instead created a duplicate natural key but different ID, which might be legitimate if 'acct-b' is really new. But in our use case, only one parent should exist for that key.
We also want to “inspect the SQL your abstraction actually emits.” In practice, an ORM or helper might produce either of the forms above. The lesson: Check what SQL is actually run. A function named save() might hide an INSERT OR REPLACE inside. We recommend logging or capturing the raw SQL when debugging these integrity issues. SQLite’s EXPLAIN or the DB abstraction’s logging can help here.
Reconcile the full mutation set before COMMIT
Before we commit any change that affects both parent and children, we implement a verification gate. We compare the actual state against our declared manifest. In code, this means doing:
expected_children = {(101, 10), (102, 10)}
cur.execute("SELECT id, parent_id FROM child ORDER BY id")
actual_children = set(cur.fetchall())
missing = expected_children - actual_children
extra = actual_children - expected_children
cur.execute("SELECT id, natural_key, payload FROM parent")
parent_row = cur.fetchone()
We then examine:
21.If parent_row[0] equals 10 and payload is 'new'.
22.If missing or extra are non-empty.
If any discrepancies appear (e.g. missing = {(101, 10), (102, 10)} after the REPLACE), we report them. For example, a simple output could be:
Parent expected ID=10, found ID=10, payload='new'.
Children missing: {(101,10), (102,10)}; extra: set().
This clearly shows the children we expected did not appear. A count check (len(actual_children)) is necessary but not sufficient: e.g. if one child was replaced by another, the count would be 2 but IDs wrong. By listing the actual tuples, we catch wrong IDs too.
We could package this into a function. The key point: the gate compares full tuples, not just counts. It returns a structured discrepancy if not empty. Only if missing and extra are both empty do we say “write is correct.” This approach matches the “evidence-first” mindset: we gather specific differences as evidence. If evidence is missing, we do not commit.
In effect, the gate enforces the declared contract exactly. This is analogous to acceptance testing of database state. It should run before commit (and indeed under the same transaction) so that if it fails, the bad write can be rolled back completely.
Prove rollback while the transaction is still open
Let’s demonstrate that if we catch the discrepancy before committing, we can recover simply by rolling back. In our REPLACE test (Case A), after capturing the failing evidence, we call ROLLBACK.
The sequence is:
cur.execute("ROLLBACK");
Then we re-query:
SELECT FROM parent;
SELECT FROM child;
SELECT * FROM delete_audit;
We should see the original state: parent (10,'acct-a','old'), children back (101,10),(102,10). Also, delete_audit should be back to empty. Indeed, because the parent deletion, cascade, and any trigger insert were all part of the aborted transaction, they are undone. The manifest is fully restored.
Important: We captured the failing state before rollback into separate variables (actual_children_pre, parent_row_pre, audit_pre) so we could include them in the report if needed. After rollback, we again capture (actual_children_post, etc.) to confirm restoration.
This proves that while the transaction was still open, we had all the evidence and could safely cancel the change. It also shows that rollback undoes deletes, inserts, and trigger effects as expected. (We verify that delete_audit is empty again, which means the trigger insertion was undone by rollback too.)
We note that in SQLite, an explicit ROLLBACK with an open transaction always undoes all changes in that transaction. We rely on that: the bad REPLACE is never committed. After rollback, it’s as if the REPLACE never happened.
Handle a committed loss without inventing children
What if we missed the gate and committed the loss? We simulate this by repeating Case A on a new connection and issuing COMMIT instead of rollback. The SQL:
BEGIN;
INSERT OR REPLACE INTO parent VALUES (10, 'acct-a', 'new');
COMMIT;
SELECT FROM parent;
SELECT FROM child;
Now the children are permanently gone (unless we have backup). Even if we afterwards call ROLLBACK, it will do nothing useful, because we are no longer in an open transaction (SQLite returns to autocommit mode after commit). The database is in a consistent state, but not our desired one. changes() and foreign_key_check remain green. We have a committed divergence from the contract.
The only remedy here is recovery from an authoritative source: for example, restore the parent and children from a backup or upstream log. We cannot “guess” child data from having two rows originally: the count is two, but their IDs and content mattered. We emphasize: one cannot reconstruct lost rows just by count. Our manifest gate demonstrated why a count check is insufficient. We must have true backup of every row we might need to restore, or alternate data source.
In practice, this means our application might set up a compensating action or alert. Perhaps the write helper would record the deleted rows somewhere, or we would have a separate journal table. But best practice is to never commit unless you know the state is correct.
As SQLite transactions docs note, after COMMIT the changes are final (barring journaling/WAL recovery, which is outside our scope). We see that ROLLBACK after commit is a no-op; it cannot time-travel.
So the difference in ownership is: after rollback, the write is still pending (application or DB reviewer can fix and retry). After commit, the responsibility shifts to data recovery personnel. We would document that parent 10’s children are missing and must be restored from the last good dataset or fixed by hand. This division is part of our decision matrix (see below).
Test wrong identities, not only wrong counts
We add some negative-control tests to reinforce that only checking row count or existence is not enough. For example, consider this scenario: somehow the child rows were replaced by two other rows (perhaps by a faulty migration script) but the count remains 2.
23.Start with a fresh fixture.
24.Manually delete the original children and insert new ones with the same count:
DELETE FROM child;
INSERT INTO child VALUES (201, 10), (202, 10);
25.Now the database has two children (201,10 and 202,10) instead of (101,10) and (102,10).
26.Run our manifest comparison.
Even though SELECT COUNT(*) FROM child returns 2 (the same count), the manifest check will find extra = {(201,10),(202,10)} and missing = {(101,10),(102,10)}. We report “children mismatch.” This is an equal-count/wrong-ID negative control.
We could also test an “unexpected extra child” by adding a third child, or an “altered parent link” by changing a parent_id. Each of these creates a discrepancy that our manifest gate catches.
We also test the situation where no conflict occurs: e.g. INSERT INTO parent VALUES (20,'acct-a','new') without an ON CONFLICT clause would error on unique key, or with DO NOTHING. For instance:
BEGIN;
INSERT INTO parent VALUES (20, 'acct-a', 'new')
ON CONFLICT(natural_key) DO NOTHING;
SELECT changes(), * FROM parent;
Since 'acct-a' exists, DO NOTHING means no change: changes()=0, parent still ID=10 with old payload. Our gate would see that payload didn’t change to 'new' and flag it. This helps ensure that the write operation did what we intended.
The purpose of these branches is to underline: matching tuple-by-tuple matters. A code reviewer should not simply say “2 children is correct”; they must check which two. This reinforces the warning in SQLite’s change-count documentation: direct counts or hooks are not guarantees.
Assign acceptance and repair ownership
Based on our experiments, we define four possible decisions when a candidate write is tested:
27.ACCEPT THE IN-PLACE WRITE. The manifest gate found no discrepancies: the parent row (ID=10) has the updated payload, and all expected child rows (IDs 101,102) are present. In this case the application engineer or write helper can safely COMMIT the transaction. The database state matches the contract. This is the happy path, and the owner is typically the Application Code: the code issued the write and now accepts it because evidence is clean.
28.REPAIR THE CONFLICT STATEMENT. If the write failed due to conflict in a wrong way (e.g. we used INSERT OR REPLACE and lost children), we must modify the SQL. The owner here is the Database Developer/Reviewer. The fix might be to change INSERT OR REPLACE to an UPSERT or UPDATE, or to adjust the conflict target or key columns so no silent delete happens. Once code is fixed, the write can be retried. Note: this does not recover lost rows; it only prevents future occurrences. We may treat the rollback of the faulty attempt as part of this step (see decision 3).
29.ROLLBACK THE UNCOMMITTED CHANGE. If the test fails before commit (like our Case A example), with children missing or wrong data, we abort. We call ROLLBACK to undo all changes (as shown above), and do not commit. This decision can be made by the Application Layer or DB Transaction Manager. It’s often triggered automatically by the gate failing. The final state reverts to before the write. This is the ideal fail-fast approach: do not propagate a bad write.
30.HOLD AND RESTORE FROM AUTHORITATIVE DATA. If the faulty write somehow slipped through and was committed, then detection comes later (or from an external check), and simple rollback is no longer an option. At this point, the data is corrupted relative to the manifest. The owner of resolution is Data Recovery / DBA Team. The remedy is to restore the missing child rows from a backup, a change log, or by reconciling with an authoritative source (e.g. application-memory state or a full reload). We cannot “invent” the children from the commit. This is costly and beyond the application code’s immediate control; it requires separate incident procedures.
We can tabulate this decision matrix with evidence criteria:
Outcome | Evidence needed | Action | Owner |
Accept | Parent ID=10 with new payload; child IDs {101,102} present; changes() and foreign_key_check normal. | COMMIT transaction | App Code/DB writer |
Repair statement | Parent ID changed to wrong value, or natural_key mismatch, or children missing in test. | Fix SQL (use UPSERT/UPDATE) | DB Developer/Reviewer |
Rollback pending | Manifest mismatch detected before commit (e.g. missing children). | ROLLBACK transaction | Transaction Manager |
Restore needed | Manifest mismatch found after commit. | Load from backup/authoritative | DBA/Recovery Team |
For example, in Case A with REPLACE, our evidence (missing children) would trigger a rollback. In Case B (UPSERT), evidence matches and we accept. After fix, if someone had applied REPLACE and committed (violating contract), we would need step 4 to manually restore data.
This division of roles is akin to the “backend ownership across data boundaries” principle in Refonte’s Master Backend Development 2026 guide: application code owns statement correctness, DB administrators own schema and integrity, and data teams own recovery of corruption.
Practice database changes with an evidence-first approach
In summary, preserving relational validity (no orphaned rows) is necessary but not sufficient for correctness. We also need to preserve the exact business population of related rows. By enforcing an independent manifest gate, we treat database writes like any contract test: know exactly what must survive, and verify it explicitly. This avoids silent data loss when using conflict-resolution features like REPLACE.
For developers and DBAs, this means prioritizing data evidence over convenience. Before using a write helper, check what SQL it emits. After a write, check more than “no error.” Compare actual rows to your expected outcome. If a quick identity or count check is insufficient (as we saw), add more thorough checks or hooks.
This also underlines the value of practicing with realistic scenarios. Refonte Learning’s Database Administrator Essentials program covers such topics as backup and recovery, integrity constraints, and transaction management. For those seeking structured practice in database design and recovery, consider their coursework. By learning these concepts in depth, engineers can avoid pitfalls like silent cascade deletes and ensure their systems remain correct.
For structured practice in database design and recovery, explore Refonte Learning’s Database Administrator Essentials program. Each section above included only minimal example code; try extending it in a lab or course setting to solidify your understanding.