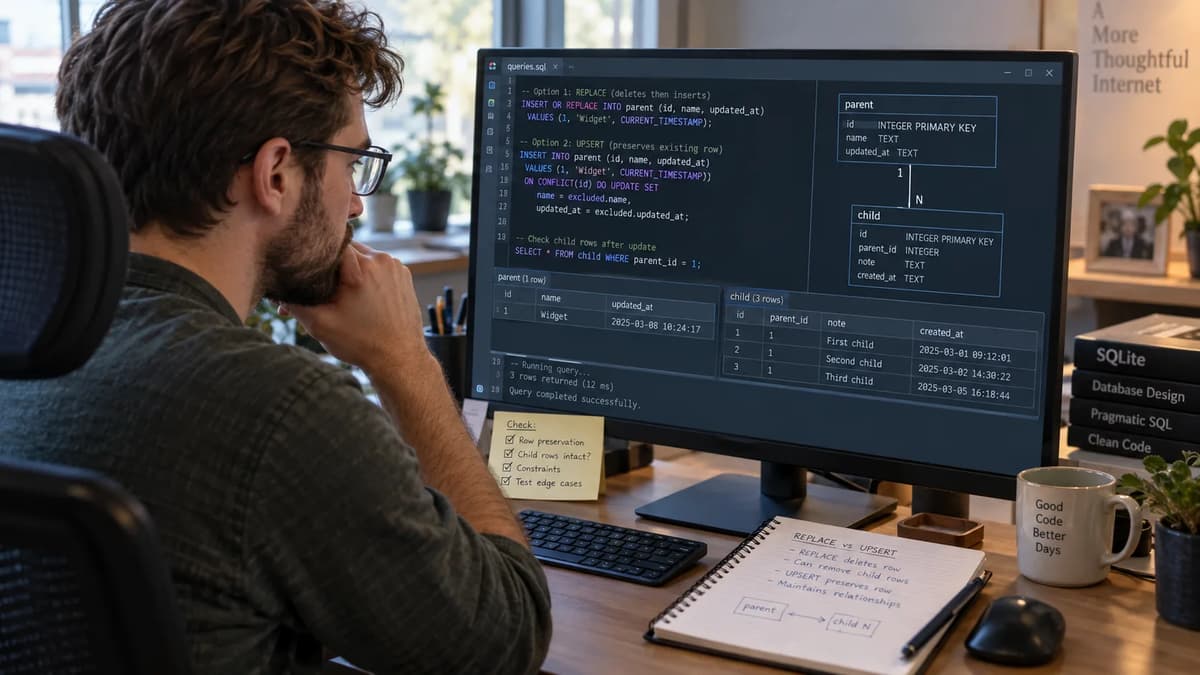
A backend developer updating a parent record in SQLite might instinctively try INSERT OR REPLACE thinking it simply “updates” the row. However, as we’ll demonstrate, this can silently delete related child rows because REPLACE deletes the conflicting parent then reinserts it. In our example fixture, the parent row with id=101 has two child rows (id 11 and 12). The business intent is to change only the parent’s label to “new” while keeping the same parent ID, its revision, and both child rows intact.
Any SQL we run must satisfy that preservation contract: after the update, the parent should still have id=101, external_key='acct-17', and revision=7, and the children should still exist (child count 2, with amount values summing to 100). We treat this as a statement-level semantics check, not a backup or concurrency issue. We will explicitly read all parent columns and the ordered list of child rows to verify the result, because a mere count of child rows is too weak a test (it could hide a change in values or IDs). By defining these invariants up front, we establish the criteria that any candidate SQL must meet before we accept the write.
In practice, articulating the relational contract and constraints (ID, unique key, foreign-key relations, default values, etc.) is part of solid backend integration. This aligns with clear backend database-integration boundaries to ensure application logic and database semantics match.
Write the preservation contract before choosing SQL
Before running any SQL, we declare what the update is allowed to do. In our fixture:
• Allowed change: Parent’s label may change from "old" to "new".
• Invariants: Parent’s id remains 101, external_key remains 'acct-17', and revision remains 7. Both child rows must still exist with the same id (11 and 12) and the same amount values (30 and 70). The parent’s unique key and identity must survive the write. In short, after the write the parent–child relation should still look exactly like the expected final state (parent row (101, acct-17, new, 7) and children (11, 101, 30) and (12, 101, 70)). Any deviation is a violation.
These requirements are independent of how we implement the SQL. We are not just counting rows. For example, checking only that there are two children doesn’t catch if those child rows were somehow replaced by others with different IDs or values. We will select and compare each column in parent and each ordered row in child to ensure the data matches the oracle. Only such a detailed check truly proves the intended effect; a numeric row-count or a successful statement is insufficient to confirm that the original child data survived.
Pin one SQLite connection and its enforcement settings
We perform all tests on one writable SQLite connection (simulating a single application session). First, capture the environment:
-- Check SQLite version and defaults
SELECT sqlite_version();  -- e.g. "3.53.4"
PRAGMA journal_mode;      -- default is usually "delete" (durable)
PRAGMA foreign_keys;      -- returns 0 (off by default)
PRAGMA foreign_keys = ON; -- enable enforcement
PRAGMA foreign_keys;      -- should now return 1
PRAGMA recursive_triggers;    -- default 0 (off)
PRAGMA recursive_triggers = ON; -- enable triggers if any
PRAGMA recursive_triggers;    -- should return 1
On our test machine we’re using a maintained SQLite build (for example, SQLite 3.53.4 (2026) compiled with default options), with the default journal mode (DELETE for durability). The important detail is that foreign key enforcement is disabled by default; we must explicitly turn it on before any transaction so that ON DELETE CASCADE will actually delete child rows when a parent is deleted. We do this outside any explicit transaction (PRAGMA changes take effect immediately) to ensure our test mimics production behavior. We also enable recursive_triggers to ensure any cascaded deletes fire as expected (though in this scenario we have no user-defined triggers, it’s good practice when using cascade actions).
We verify the settings: if PRAGMA foreign_keys still returns 0 (disabled), we stop here because our test would not be valid without enforcement. Similarly, if PRAGMA journal_mode were OFF, SQLite documentation warns that ROLLBACK behavior becomes undefined, so we stick to a normal journal mode.
With the connection pinned and settings verified (foreign_keys=ON, recursive_triggers=ON, journal_mode=DELETE), we can safely begin transactions knowing that constraint enforcement will work as expected. At this point an implicit transaction would auto-start with any statement, but we will use explicit BEGIN blocks for clarity and control. In SQLite, any executed statement outside a BEGIN is effectively in its own transaction (auto-commit). We plan to use explicit BEGIN...COMMIT/ROLLBACK or SAVEPOINT blocks so that we can roll back uncommitted work if it violates our contract. This lets us distinguish reversible test runs (before commit) from irreversible committed changes.
Build the parent–child fixture and an exact oracle
With the environment set up, we create our test schema and seed data. We will hard-code the expected post-update state so we can compare to it. First, build the tables and initial rows:
-- Build the parent–child schema
BEGIN;
CREATE TABLE parent(
    id INTEGER PRIMARY KEY,
    external_key TEXT NOT NULL UNIQUE,
    label TEXT NOT NULL,
    revision INTEGER NOT NULL DEFAULT 0
);
CREATE TABLE child(
    id INTEGER PRIMARY KEY,
    parent_id INTEGER NOT NULL REFERENCES parent(id) ON DELETE CASCADE,
    amount INTEGER NOT NULL
);
-- Seed initial data
INSERT INTO parent(id, external_key, label, revision)
VALUES (101, 'acct-17', 'old', 7);
INSERT INTO child(id, parent_id, amount) VALUES (11, 101, 30);
INSERT INTO child(id, parent_id, amount) VALUES (12, 101, 70);
We commit this setup so it becomes the base state. To confirm the fixture, we can SELECT:SELECT FROM parent;
-- Expected output: id=101 | external_key='acct-17' | label='old' | revision=7
SELECT FROM child ORDER BY id;
-- Expected output: id=11 | parent_id=101 | amount=30
-- id=12 | parent_id=101 | amount=70Oracle (Expected): After a valid label update, we expect:
• Parent table: (101, 'acct-17', 'new', 7), with the same id and revision and the label changed to "new".
• Child table: still two rows (11, 101, 30) and (12, 101, 70). The parent’s unique key (external_key) is unchanged, and both child rows remain attached to parent 101 (sum(amount)=100).
These are the exact values we will compare against, regardless of which SQL statement we run. We’ll reset to this fixture before each scenario, ensuring a clean slate.
Run REPLACE and inspect every affected relation
Now we test the negative case: using INSERT OR REPLACE. We deliberately use the same parent ID to focus on semantics. We keep id=101 in the INSERT so SQLite doesn’t generate a new row ID that might mask the issue. We do this in a transaction and inspect results before committing:
BEGIN;
INSERT OR REPLACE INTO parent(id, external_key, label)
VALUES (101, 'acct-17', 'new');
SELECT changes() AS direct_changes,  FROM parent;
SELECT  FROM child ORDER BY id;
ROLLBACK;
• We use id=101 in both cases (the old row and the INSERT) so that the new row’s ID equals the old one. This forces a conflict on the external_key unique index, invoking REPLACE.
• After the INSERT OR REPLACE, SQLite deletes the existing row causing the conflict and then inserts a new row. Because our table has ON DELETE CASCADE on the foreign key, deleting the old parent causes both child rows to be deleted. The new parent row is inserted with label='new', but with default values for any omitted columns (here, revision is not specified, so it defaults to 0).
• The SELECT changes() shows how many rows the statement itself changed directly (likely 1 here), but importantly it does not include the cascade deletions, so it hides the full impact.
After running the above, we examine the output before rollback:
direct_changes | id  | external_key | label | revision
---------------|-----|--------------|-------|---------
             1  | 101 | 'acct-17'    | 'new' | 0

Child table (ordered by id):
(no rows)
We see the parent row (id 101) still exists with the updated label, but revision is now 0 (lost the original 7). Critically, the child table is now empty: both child rows are gone. This clearly violates our contract. We expected revision 7 and two children summing to 100; instead we have revision 0 and zero children.
SQLite’s documentation confirms this outcome: under REPLACE, “the algorithm deletes pre-existing rows that are causing the constraint violation prior to inserting or updating the current row”. In our case, the conflicting parent row was deleted (triggering the cascade) and a new row inserted. The children are deleted by the cascade and not restored. We highlight that no integrity or change-count checks would have caught this: changes() returned 1 (the insertion), and PRAGMA foreign_key_check would show no error since no orphans remain, but that’s misleading. The lesson: the old parent row was removed and children lost before the new one appeared.
Keep the same parent key in the failing case
By explicitly using id=101 in the REPLACE, we ensure the replaced row has the same primary key as before. This prevents any confusion that the issue is merely an ID shift. The contract was that parent ID 101 must survive; using the same ID shows that even though the row looks like it has the same ID after REPLACE, it is actually a different row.
Because the original row was deleted and a new one inserted, any deletes tied to that deletion (the cascade) are real, not just cosmetic. This rules out false assumptions like “maybe SQLite just changed the rowid”; it genuinely removed the old tuple and replaced it. We saw above that the new parent row has a different revision because default values applied on insertion, another subtle side effect of REPLACE. In summary, INSERT OR REPLACE with the same key is not an in-place update: it’s a delete-then-insert, which failed our child-preservation contract.
Explain the delete-and-insert boundary narrowly
The key difference is precisely how SQLite handles the unique-key conflict. With REPLACE on (external_key) UNIQUE, SQLite’s documented behavior is to delete the existing parent row before inserting the new one. This deletion invokes ON DELETE CASCADE, removing the child rows. The new parent row is then inserted from scratch. Nothing in this process re-links or re-creates the children. Even though the new parent has the same ID, it is a new tuple as far as SQLite is concerned, so the cascade effect is final.
Put simply: REPLACE maps a uniqueness conflict to a delete of the old record plus an insert of a new record. During the delete phase, any cascade rules fire, in our case removing all rows in child that referenced parent 101. After that, the INSERT stage just creates a fresh parent row. The delete triggers (SQLite calls them delete “cascades” via the foreign key) have already executed. Thus, the new parent row cannot undo or resurrect the children that were removed.
We emphasize: this is different from an “update” of the existing row. SQLite’s REPLACE is not equivalent to UPDATE. Other conflict algorithms (IGNORE, ABORT, etc.) behave differently, but for our scenario the relevant point is: REPLACE deletes then inserts. We will not delve into the full catalogue of conflict actions here; the documents are clear that REPLACE’s special action is to delete the old row (triggering cascades if any).
Replace the mutation with a targeted UPSERT
To meet the preservation contract, we switch to using INSERT ... ON CONFLICT ... DO UPDATE, commonly called UPSERT. This syntax lets us update only specific columns on conflict, rather than delete and recreate. We use the external_key as the conflict target, and set only the label:
BEGIN;
INSERT INTO parent(id, external_key, label)
VALUES (101, 'acct-17', 'new')
ON CONFLICT(external_key) DO UPDATE
  SET label = excluded.label;
SELECT  FROM parent;
SELECT  FROM child ORDER BY id;
ROLLBACK;
• This statement attempts to insert (101, 'acct-17', 'new'). The conflict target external_key is met (the key 'acct-17' exists), so instead of inserting a new parent, SQLite does an UPDATE on the existing row.
• The DO UPDATE SET label=excluded.label clause tells SQLite exactly which column to change: set label to the would-be-inserted value (excluded.label). We do not mention revision or id in the SET clause, so those fields remain unchanged.
• Because we’re updating the existing row in place, no DELETE occurs and no cascade is triggered. The existing parent’s revision (7) stays intact, and the children remain untouched.
After running this UPSERT, the results are:
Parent table:
id=101 | external_key='acct-17' | label='new' | revision=7

Child table (ordered by id):
id=11 | parent_id=101 | amount=30
id=12 | parent_id=101 | amount=70
This matches the contract: the parent’s label changed, id and revision stayed the same, and both children are still present. We deliberately omitted revision in the assignment list, so the original value 7 was preserved, confirming that UPSERT updates only what we tell it to.
This behavior aligns with SQLite’s UPSERT semantics: it only triggers on UNIQUE/PK conflicts and performs the specified UPDATE instead of delete. Because our conflict target was the unique external_key, it correctly identified the row to update. (Had we instead used ON CONFLICT(id) it would have similar effect here, but using the unique key makes the intent clear.) The docs describe UPSERT as causing the INSERT to act like an UPDATE on conflict. They also illustrate how excluded. references the new values, exactly what we used for label.
Preserve omitted fields intentionally: Note that the revision column was not listed in either the INSERT columns or the UPDATE SET clause. SQLite applies its default (0) only on a fresh INSERT; in this UPSERT path, since no insert occurred, revision stayed at 7. This confirms that UPSERT does not implicitly reset omitted columns; it respects the existing tuple except for the listed changes. In contrast, our earlier REPLACE route did insert a new row and so the default 0 was applied.
Test the create path separately from the update path
To complete coverage, we test the non-conflicting create path. We insert a parent with a new, unused key and ID to see the effect on default values and children. For example:
BEGIN;
INSERT INTO parent(id, external_key, label)
VALUES (102, 'acct-99', 'new');
SELECT  FROM parent;
SELECT  FROM child;
ROLLBACK;
Since external_key='acct-99' doesn’t exist, this runs as a normal INSERT (no UPSERT trigger). We should see a new parent row (102, 'acct-99', 'new', 0). The revision column will be 0, because we didn’t supply it and the default is used on insert. The original children for parent 101 remain unaffected. For completeness, if this had been an UPSERT with ON CONFLICT(external_key), it would simply insert (no update).
The outcome: a new parent (id 102) is added with revision=0, and the two original children are still present (both referencing id 101). This confirms that the insertion path is allowed by our application. In particular, it shows that setting revision=0 is expected on new rows, reinforcing that only an existing row’s revision should be 7. We don’t infer anything about the update path from this (except that 0 is default). The key point is that creation of new parent keys is acceptable, but using INSERT OR REPLACE on an existing key was not. This separate check just verifies that new inserts work and apply defaults as expected.
Check the evidence that can look correct after data loss
Now consider an already-committed scenario. Suppose someone ran the bad REPLACE and committed it. How can we tell, and what checks might mislead us? After commit, the only way to “see” loss is by querying the tables, but let’s list typical sanity checks and what they would show:
BEGIN;
INSERT OR REPLACE INTO parent(id, external_key, label)
VALUES (101, 'acct-17', 'new');
COMMIT;

-- Checks after commit:
SELECT changes() AS changed;             -- number of rows changed by last statement
SELECT COUNT(*) AS parent_count FROM parent;
SELECT COUNT(*) AS child_count FROM child;
SELECT  FROM parent;
SELECT  FROM child;
PRAGMA integrity_check;
PRAGMA foreign_key_check;
If we ran this (on the same fixture), after commit we would observe:
• changed = 1 (as reported by changes() from the last statement). This only counted the new parent insert; it does not count the deleted children or the deleted parent. So changed=1 could easily be misinterpreted as “one row updated, so probably fine,” missing the hidden deletes.
• parent_count = 1 (still one row, id 101, so on the surface it looks like one parent, as expected).
• child_count = 0 (now zero children, contrary to the expected 2).
• SELECT * FROM parent would show (101, 'acct-17', 'new', 0).
• SELECT * FROM child would show nothing (no rows).
• PRAGMA integrity_check returns “ok” because the database structure is fine (no corruption).
• PRAGMA foreign_key_check returns no errors, since there are no children violating constraints. This check only reports when child references have no parent; it says nothing about children that were deleted correctly.
So all these indicators except for the direct content query are misleadingly normal. A naive observer might see “parent count is 1” and “integrity ok” and think the update was successful. Only by explicitly querying the children (or checking the expected sums) do we see the data loss. In other words, structural checks don’t capture semantic invariants.
This underlines that no automatic check (changes count, counts, FK_check, integrity_check) will flag that something is wrong; only a direct audit of the relation contents reveals that the two children are missing. As SQLite docs note, sqlite3_changes() (and the SQL changes()) only reflect the direct INSERT/DELETE/UPDATE, not cascades or triggers. Therefore, even a clean PRAGMA integrity_check does not prove that children were preserved; it just means there are no constraint violations in the current state. The fact that the parent ID 101 still exists does not guarantee its children are intact.
Since the transaction has been committed, ROLLBACK is no longer an option at this point. The database state has irrevocably lost those child rows. Any fix now requires an external source: a trusted backup or the original data source to re-create the missing children. This scenario emphasizes that once committed, the only remedies are recovery from backup or manual reconstruction, not something SQLite can do on its own.
Do not substitute a direct-change count for a child audit
In summary of this section: do not rely on client-reported row counts. For example, SELECT changes() after the mutation would be 1 (only the inserted row). One might incorrectly think “one change means one row updated.” Instead, always verify the child table contents explicitly. The clause ON DELETE CASCADE removed rows invisibly to changes(), but our invariant is about those very rows. The remaining child rows (or lack thereof) is the definitive evidence.
Reject a bad candidate before COMMIT
To avoid accidentally committing loss, implement a guarded protocol: perform the mutation inside a transaction or savepoint, check the invariants, and only then commit. For example:
BEGIN;
SAVEPOINT check_update;
INSERT OR REPLACE INTO parent(id, external_key, label)
VALUES (101, 'acct-17', 'new');
-- Check invariants:
SELECT id, external_key, label, revision FROM parent WHERE id=101;
SELECT COUNT(*) AS child_count, SUM(amount) AS child_total
FROM child WHERE parent_id=101;

-- Pseudocode for application logic:
-- if (revision != 7 OR child_count != 2 OR child_total != 100) THEN
--     ROLLBACK TO check_update;
--     -- report error / reject update
-- else
--     RELEASE check_update;
--     COMMIT;
In words, after the INSERT OR REPLACE but before commit, we verify:
• The parent row read (SELECT ... FROM parent WHERE id=101) should show revision=7 and label='new'.
• The child aggregate (count=2 and sum=100) should match the original two children. If any of these checks fails, we do ROLLBACK TO check_update (undoing the REPLACE) and then ROLLBACK the transaction or otherwise abort the operation. This ensures the database returns exactly to the state before the attempted update.
After rolling back, we can re-query to confirm the pre-update state is intact. For example:
ROLLBACK TO check_update;
SELECT FROM parent;
SELECT FROM child;
-- Should see the original parent (label 'old', revision 7) and the two children again.
This pattern (using SAVEPOINT and conditional rollback) effectively enforces the invariant on the SQL level. It makes the decision immediate: we do not commit unless the database state matches our contract. This form of error propagation (failing the transaction if invariants fail) is a practical defense-in-depth.
The SQLite documentation notes that SAVEPOINT allows nested transactions, and ROLLBACK TO can undo changes up to that point without ending the outer transaction. We use that to “preflight” the write. If all invariants pass, we release the savepoint and commit; otherwise we abort. This explicit check and controlled rollback ensures we never leave the transaction in a bad state.
Handle a loss discovered after COMMIT
If the bad REPLACE was already committed and only discovered later, the situation is different: the changes are permanent in that database snapshot. The first step is to quarantine that write path and prevent any further execution of the faulty statement. Preserve any evidence (log files, SQL statements, dumps) that show the pre-commit state. Immediately notify the team that a critical violation occurred.
Since the transaction has been committed, simply rolling back is impossible. We must restore the lost children from an independent source. This means recovering from a trusted backup of the database taken before the errant update, or reloading the data from some authoritative system of record. In essence, the child rows did not magically exist elsewhere; they must be reconstructed from an external canonical dataset.
This scenario underscores that SQLite has no built-in undo past a commit. The only way to “recover” is to replace the current state with a previous snapshot (e.g. a backup file) or manually re-insert the missing rows (with carefully verified values). If we have to do that, it’s essential that the restoration is authorized by the data owners or application logic; we’re not free to guess the missing values. In practice, we would involve the data governance or DBA team to approve the reconstruction plan (for example, “restore child rows for parent 101 from archived records in the source system”).
We emphasize separating two issues: ROLLBACK after a committed transaction is a no-op; it won’t bring back deleted rows. Recovery always involves an external process. The safest course of action is to plan ahead: use point-in-time backups, write-ahead logs, or replayable event logs that allow bringing the database back to just before the damaging statement. Otherwise, once the COMMIT happens, the irreversible boundary is crossed, and you are left holding an incomplete dataset.
Separate rollback from reconstruction
It’s important to note that rollback cannot fix a commit. If we have a known good pre-state (e.g. backup.db or a recent snapshot), we could “roll forward” from that source. But the act of applying a backup or manual inserts is a distinct recovery step, not a continuation of the original transaction. In code review or runbook terms, the fix is not to ROLLBACK the original code (it’s already done) but to restore data. This often involves downtime or running repair scripts. While a detailed backup system (WAL shipping, for example) is beyond scope here, the key point is: commit = loss final, recovery = external effort.
This incident should also lead to a broader response: the write path that caused it should be disabled or corrected, further writes should be paused, and the SQL itself should be refactored or replaced (as we did with UPSERT). The decision matrix below will formalize how to handle each case (reject before commit vs. recovery after commit).
Add regression cases that protect the relation
Based on these experiments, we can codify regression tests or pre-commit checks to prevent recurrence. The suite should include at least:
• Update path test: Using INSERT ... ON CONFLICT DO UPDATE (UPSERT) with an existing key (external_key='acct-17') should succeed with no data loss. Verify parent’s ID and revision preserved and children intact. (This asserts correct behavior for the fix.)
• Insert (create) path test: Inserting a new parent ID/key (non-conflicting) should set defaults (revision=0) and not affect existing children. (This confirms creation works as expected, separate from updates.)
• Omitted-field preservation: Specifically test that updating only the label column leaves revision unchanged. For example, ON CONFLICT DO UPDATE SET label=excluded.label should not reset revision. (This guards against SQL that inadvertently overwrites defaults.)
• Child invariants: After either operation, always check that COUNT(child) = 2 and SUM(amount) = 100 for parent_id = 101. Include this as an assertion.
• Foreign key enforcement precondition: A test that fails early if PRAGMA foreign_keys is not ON. (If foreign keys aren’t active, all cascade logic is moot.) In practice, we might script: PRAGMA foreign_keys; and abort the test if it’s 0. The absence of this precondition should be considered a test failure, not an alternative logic path.
These tests should run against each new version of the schema or code. If, for instance, a migration adds another unique constraint or changes defaults, the above invariants must be revisited. The goal is to keep these tests green if and only if the parent–child preservation contract is actually satisfied. Failure of any of these cases indicates a broken invariant.
Record the acceptance and repair decision
Finally, in our code review or QA workflow, we formalize the result of these tests into a decision matrix. For each candidate change, we consider:
• Accept (approve): The UPSERT approach (or any update statement) meets all invariants. Evidence: SELECT queries confirm parent.id = 101, revision = 7, and both child rows present with correct data. Owner: Dev/Reviewer. Next action: merge change, add to regression tests, no data loss.
• Refactor (reject): The INSERT OR REPLACE or any harmful SQL fails invariants (child count < 2 or revision wrong). If not yet committed, we roll back as shown. Evidence: pre-commit checks fail or regression tests fail. Owner: developer must rewrite SQL (use UPSERT). Next action: require code change.
• Uncommitted rollback: If a wrong statement was executed in a transaction, we abort it and report. The “owner” here is the transaction script or DBMS (it self-rollbacks the savepoint). The developer notices the test failure or error and stops. Next action: correct SQL before retry.
• Recovery hold (post-commit): If a harmful write is discovered after commit, commit=done. Evidence: missing children detected only post-commit. Owner: Database Administrator or Data Steward. Next action: notify stakeholders, restore data from backup (child rows), disable/repair faulty write path, and review backup/recovery processes.
In a table form, this might look like:
Scenario | Decision | Owner | Evidence/Check | Next Action |
UPSERT used, ID & revision preserved, children intact | Accept update | Dev/QA | SELECT confirms invariants satisfied | Approve change, add test; safe to deploy |
INSERT OR REPLACE used (detected before commit) | Reject/change | Dev/Reviewer | Pre-commit audit failed (revision or children wrong). Do not rely on direct-change counts. | Replace with UPSERT, re-run tests |
Faulty UPDATE committed, data loss detected | Recovery needed | DBA / Data Owner | Post-commit query shows missing children | Restore children from backup, fix write process |
Non-conflicting insert of new key | Accept insert | Dev/QA | Parent added with default revision=0; original children unchanged | Approve (creation path is fine) |
Foreign-keys disabled (precondition fail) | Fail precondition | DevOps/QA | PRAGMA foreign_keys=0 | Enable enforcement, rerun tests |
The key point in documentation is that our acceptance is not just “the SQL ran without error,” but “we saw the right data”. Changes to the SQL code or schema must come with updated reviews of the conflict target and assignments. As one reviewer might note, “Is the conflict on external_key or id? Are all non-updated columns intentionally omitted? We should always verify foreign_keys is ON so cascade rules apply.” In other words, the code review must include a relational sanity check: the conflict target and SET list should match the invariant contract, with explicit checks of REPLACE behavior and direct-change counts rather than just the absence of SQL errors.
Make relational evidence part of code review
In practice, this means: every PR or patch that changes write SQL should include explicit checks of the relevant tables. For example, a reviewer should run the statements in a test database and query the parent and child tables before accepting the change. They should note which columns the UPSERT will match on (external_key here) and which columns it updates (only label). The reviewer must ask: “Does this cover all the business fields? Are any defaults being overwritten?” By doing so, the reviewer makes the relational impact visible. It’s not enough to read the code; one must examine the actual rows.
This approach is in line with a broader database audit practice: treat DML changes as you would critical configuration changes. Link the conflict-handling logic and the cascade rules in one reasoning chain. If a code review or automated check highlights “this statement will delete the old row and thus cascade-delete children,” that warrants attention. Embedding such a test into your CI pipeline ensures that the relational evidence (actual table contents) is as important as a successful compilation or a passing build.
In short, review the SQL with the same rigor as data audits: consider the foreign key schema, the unique index, the default values, and the transaction boundary together, rather than relying only on direct-change counts.
Assign ownership for write compatibility
Finally, we clarify responsibilities. Ensuring such migrations and writes adhere to invariants is a cross-team task. The application developers and product owners define what the update should do (the semantics and invariants). The database team (DBAs or architects) ensures the schema constraints (like unique keys and foreign keys) correctly enforce those invariants, and that any change to DML is reviewed for safety. The release or review manager should require a checklist: “Has this change been tested against the parent-child contract?”
Meanwhile, the incident ownership (should something go wrong) lies with the data governance team. They maintain the backup/recovery plan and authorize any emergency restores. Involving them is crucial if an irreversible change is committed, as they decide how and when to roll back data. All parties should agree on an approval workflow: when schema or key columns change, revalidate all existing write scripts. This mirrors how in larger systems, “database auditing and recovery ownership” is defined: the DBA ensures consistency, developers own application logic, and data owners sign off on any replay or fix.
In a nutshell, write-compatibility is a shared concern. Each change to how we write the database should trigger a mini-audit: “will this break our invariants?” That responsibility spans developers (who write the code), DBAs (who understand the constraints), and product/data stewards (who own the business rules). All should sign off before deployment, especially after a schema or SQL logic change.
Practice database administration with explicit invariants
The scenario above illustrates why disciplined testing and recovery planning are central to real-world DBA work. A database professional must explicitly state and test invariants like we did with the parent–child count, not assume row counts or integrity checks are enough. These habits are exactly what the Database Administrator Essentials program emphasizes. It is a 3-month (12–14 hours per week) training curriculum covering topics such as SQL, database design, backup/recovery, performance tuning, and security.
For example, the program explicitly includes Database Backup and Recovery and Disaster Recovery Strategies in its competencies. By practicing checks like the ones shown here (verifying actual table contents, handling unexpected deletes, planning rollbacks), a DBA builds the kind of rigor needed in modern data pipelines (similar to a “pipeline data-quality practice” of verifying ETL jobs).
With explicit invariants and regression tests in place, you turn these kinds of bugs into recoverable issues or, better yet, non-issues. Continuous learning through hands-on labs and mentorship, as in Refonte’s program, reinforces these behaviors. In sum, never push a change without first verifying every aspect of the relational contract, and always have a recovery plan ready. That discipline is what separates reliable systems from accidental data loss.