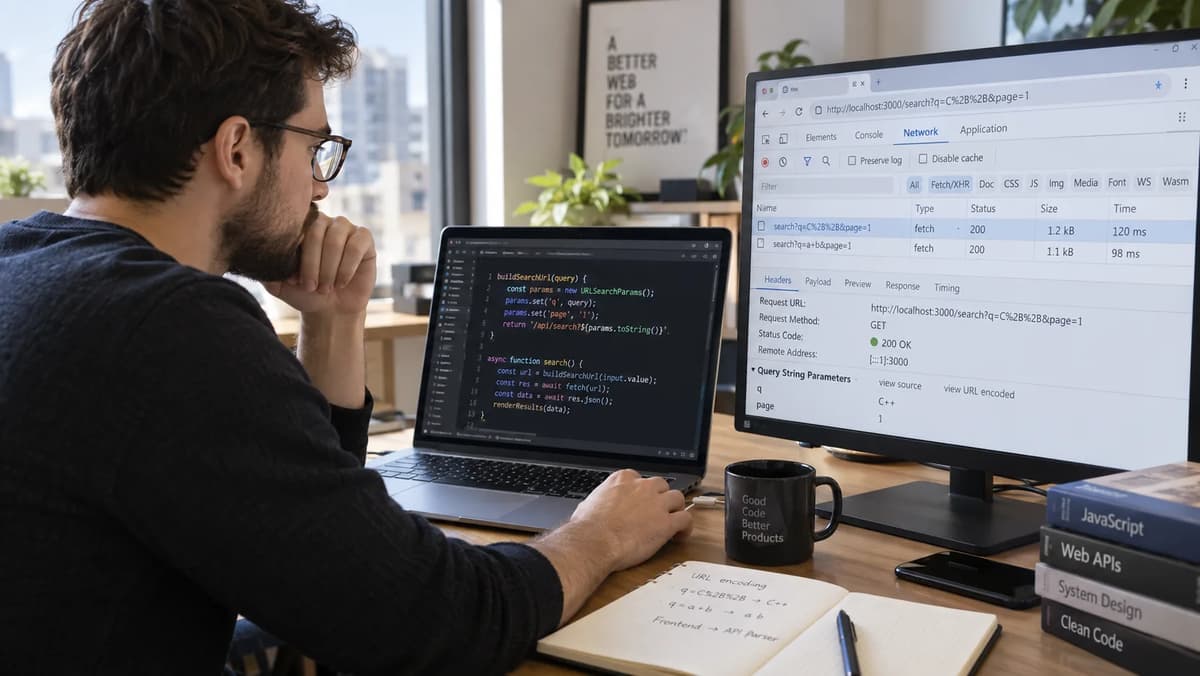
The core question is how to ensure a scalar URL query value sent from a JavaScript frontend arrives byte-for-byte unchanged at the API boundary. In this investigation, we trace six distinct “original” strings through different producer paths and a single receiver parse, then compare the received value to the fixture. In a controlled Node.js 22.16.0 runtime we record the exact constructor usage, serialization output, and interpreter build; in Python 3.13.5 we parse and echo back using urllib.parse.parse_qsl.
The six test values (V0–V5) are chosen to expose issues: they include a literal plus, an actual space, a percent-encoded plus, an ampersand and an equals-sign delimiter, non-ASCII characters, and an empty string. We then take one pass through the WHATWG form-query parser (or its equivalent in Python) and expect exact semantic and code-point equality.
If the value after one parse and echo exactly matches the original string (including distinguishing +, space, and % sequences), we ACCEPT that route. If it differs but we can fix the encoder/parser boundary (e.g. by using append() instead of string interpolation), we REPAIR. If the query arrives with extra parameters or a changed value not in the contract, we REJECT the payload. If information was irreversibly lost (e.g. V0 “A+B” vs V1 “A B” collapsed to the same output), the status is HOLD pending external reconciliation, since the codec alone can’t guess the original.
These decisions rely solely on the tested JavaScript–Python chain, not on browser-specific quirks or undocumented hacks. The reader should be a frontend or API engineer who understands URL encoding basics, and we keep the discussion on the narrow path of one value through one parse boundary.
Distinguish a plus sign from a space before debugging the URL
Even at first glance, V0 = “A+B” and V1 = “A B” should be distinct contract values, but a single erroneous boundary will collapse them. If one constructs a URLSearchParams with a string, for example new URLSearchParams('value=' + original), the embedded “+” in V0 is interpreted as a space. In that scenario both V0 and V1 lead to value “A B” after parsing, so the contract (one key “value”, one string) is broken.
We explicitly define the contract: exactly one pair named “value” and the output string must equal the original code points and content (so “+”, space, and “%” sequences remain distinct). There are four possible verdicts: ACCEPT if the output meets the contract, REPAIR if we can fix the producer/parser pair, REJECT if the query shape violates the one-value schema, and HOLD if semantic distinctions are lost (e.g. literal plus vs space in V0/V1).
This is purely about data fidelity, not about how the browser renders a form. In this local test context we assume no form UI or disabled fields. We focus on the bytes and strings in a loopback environment: Node.js on the producer side and Python on the receiver side.
In a broader frontend–backend integration context one would also consider routing or proxies, but here we bind only to localhost to avoid any middleware decoding.
Record the exact producer and receiver path
We run the producer in Node.js v22.16.0 (LTS), and the receiver in CPython 3.13.5 (encoding documentation reference: 3.13.15) on a Linux host. We note the exact builds used and assume UTF-8 encoding throughout (Node uses UTF-8 by default in URLSearchParams). In code blocks below we show explicit commands (no hidden defaults) and environment versions. No actual browser or HTTP request is sent; instead we serialize locally and feed the string to the parser.
Producer (Node.js): we record process.version (v22.16.0) and process.platform. For each original string, we test three paths:
Wrong boundary: new URLSearchParams('value=' + original); here the constructor parses the literal string on the right of ‘=’.
Correct path:
const encoded = new URLSearchParams();
encoded.append('value', original);
const query = encoded.toString();
Here we append the raw value and serialize once.
Double-encode (negative control):
const doubled = new URLSearchParams();
doubled.append('value', encodeURIComponent(original));
We simulate pre-encoding the value and then letting URLSearchParams encode it again.
Receiver (Python): we use urllib.parse.parse_qsl(query, keep_blank_values=True, strict_parsing=True, encoding='utf-8', errors='strict', separator='&'). This enforces exactly one “value” key (no silent drops) and decodes per RFC1738 rules (plus→space, then percent-decode). If an exception or wrong key count occurs, we treat it as a parse failure.
In a full HTTP scenario, one would also capture the raw request target (e.g. self.path in an echo handler) before any framework-level decoding to ensure the percent sequences or pluses aren’t altered by a server library. We do not have such middleware here, so we feed query directly to parse_qsl.
Do not treat runtime conformance as observed browser coverage
We must emphasize that running this on Node.js v22.16.0 and Python 3.13.5 does not prove identical behavior in all browsers or older Node versions. The WHATWG URL Standard and the Node.js URLSearchParams documentation describe the documented behavior. Any untested runtime or proxy layer is marked NOT RUN in our ledger. If integration uses, say, a web framework or encoded URL signing, those must be validated separately. Here we assume no additional decoding happens outside the explicit parse step above.
Create six values that expose different encoding errors
Our JSON fixture (independent of any code execution) lists six IDs and original strings:
V0: "A+B", which contains a literal plus. Code points: [65, 43, 66] (A, plus, B).
V1: "A B", which contains an actual space. Code points: [65, 32, 66].
V2: "A%2BB": the characters percent, 2, B, B, representing “A%2BB”. Code points: [65, 37, 50, 66, 66]. (This was not percent-decoded yet.)
V3: "A&B=C", which includes & and =, the standard URL delimiters. Code points: [65, 38, 66, 61, 67].
V4: "café+猫", which contains non-ASCII “é” and “猫”, and a plus. Code points (UTF-16): [99, 97, 102, 233, 43, 29305]. After UTF-8 encoding it would be %C3%A9 and %E7%8C%AB.
V5: "" (empty string).
Each string is scalar: exactly one intended “value”. We explicitly forbid multiple params (so V3’s “&” may introduce extra pairs if misparsed). The Python schema expects exactly one key named “value”, with no repeats or extras, for the contract. We do not URL-encode or normalize the originals in advance: our reference value for comparison is this exact string. (If a URL serializer normalizes spaces vs plus, we treat that as okay only if the decoded output matches, not a contract break.) We keep both the original string and its code-point list in our evidence.
Reproduce the string-constructor interpolation failure
We first test the wrong producer path by constructing URLSearchParams('value=' + original) in Node. For each V0–V5, we log the parsed pairs and toString().
For example, in Node:
const interpolated = new URLSearchParams('value=' + original);
console.log(interpolated.get('value'));
console.log(interpolated.toString());
V0: "A+B": The constructor sees "value=A+B". The WHATWG parser will split name/value on =, giving raw value bytes A+B. Step 4 (replace plus) turns that into A B. No percent-escapes to decode, so the parsed value is "A B" (with a space). Serializing that value back yields "value=A+B" (since spaces become +). Thus we see that the literal plus was lost.
V1: "A B": Input "value=A B", the space is in the input. The parser also replaces pluses (none here) and percent-decodes (none), so value remains "A B". Serialization encodes space as +, giving "value=A+B". Notice this serialized output is identical to V0’s output, though the semantics differed.
V2: "A%2BB": Input "value=A%2BB". The parser splits off value bytes A%2BB. It replaces pluses (none), then percent-decodes: %2B becomes +, yielding value "A+B". Serialization then escapes that + as %2B, resulting in "value=A%2BB" (matching the input string!). However, semantically the parsed value is "A+B" (with a plus). In contrast to V0, no collisions occurred in pairs here, but the content changed (“%2B”→plus).
V3: "A&B=C": Input "value=A&B=C". The parser first splits on the first =, giving name "value" and value bytes "A". Then splitting on & occurs before the equals-split (step 1 splits on &), so actually this string yields two pairs: ["value":"A"] and an extra pair ["B":"C"]. The parser puts the stray B=C after value because no name was specified for B. This violates our scalar contract.
V4: "café+猫": Input "value=café+猫". The parser sees raw bytes for café+猫. It replaces + with space, giving café 猫 (with a real space between é and 猫). Then it percent-decodes each UTF-8 sequence: é and 猫 were not percent-encoded in the input, so in Node they actually came in as UTF-8 bytes. But effectively, the parsed string is "café 猫". Serializing this yields "value=caf%C3%A9+%E7%8C%AB" (notice %C3%A9 for é, %E7%8C%AB for 猫, and the space as +). This differs from just encoding (step 6 below). The + became space, collapsing original pattern.
V5: "" (empty): Input "value=". The parser sees name "value", value as empty byte sequence. It treats that as an empty string. Serializing gives "value=". This is fine.
These failures are not due to transport corruption but how the parsing algorithm treats +, %, and delimiters. In particular, a raw '+' in the constructor string becomes space, and an encoded %2B yields a plus after decoding (which then gets escaped back if re-serialized). The & in V3 created an extra parameter. The verdicts on this path: V0 and V1 collapse (“A B” either way), violating the contract; V2 content changed; V3 added a pair, violating the contract; V4 plus collapsed to space. Only V5 survived intact. We mark all of these paths as needing repair or reject except the empty value (which is accepted by this test only because we interpreted empty correctly).
Follow the form-query parser in its documented order
The formal WHATWG steps for form parsing are:
Split the entire input on & (0x26). Each segment is a name=value (or just name).
For each segment, split on the first = (0x3D) to separate name and value bytes.
Apply plus-to-space replacement: Replace every + (0x2B) in the name and value with a space (0x20).
UTF-8 percent-decode any %xx sequences in the name and value.
The result is the decoded string for nameString and valueString.
Concretely for our values:
V0 “A+B”: After splitting (just one segment), we have bytes A+B. Step 3 replaces + with space → A B. No percent to decode. So valueString = "A B".
V2 “A%2BB”: Segment bytes A%2BB. No + to replace. Step 4 decodes %2B→+, giving A+B. Now step 3 (if we did plus replacement before decode, as spec does) would have been no-op because the plus came from percent-decoding. Net: valueString = "A+B". Thus V0 and V2 differ after parsing: V0 becomes "A B", V2 becomes "A+B". This shows why encoding “+” is not the same as a literal plus. Critically, after percent-decoding, plus signs are not replaced again; the plus came only from %2B and remains.
The WHATWG spec explicitly calls out these steps, which match what we see. There’s no special rule to re-replace %2B after decoding. Thus a raw + in the query and a %2B are distinct inputs to the parser, leading to different outputs.
Why encoded %2B is not the same input as a raw plus
Walking the parser for V0 vs V2 highlights the difference:
For V0 ("A+B"), the parser sees a literal +, immediately replaces it with a space (step 3) → "A B".
For V2 ("A%2BB"), the parser first percent-decodes to "A+B" (step 4). Because the raw query had no + character, the plus appears only after decoding. By that point the replace-+-with-space step has already happened, so it stays "A+B".
Thus %2B in the query yields a plus in the decoded string, whereas a literal plus in the query yields a space. This matches the standard form rules and is not a bug in Node or Python; it is by design for historical form encoding. (In short: plus signs are special in form data: raw + → space; %2B → literal + after decode.)
Add raw values and serialize exactly once
The correct producer approach is to insert the raw value as data, not parse it first. In code:
const encoded = new URLSearchParams();
encoded.append('value', original);
const query = encoded.toString();
This performs exactly one serialization (step 5: percent-encode the scalar string). The WHATWG serializer will UTF-8-encode the string and percent-escape all non-ASCII and reserved characters, using the application/x-www-form-urlencoded set. In effect: spaces become +, and all literal + signs become %2B. The expected outputs for our V0–V5 are:
V0: "value=A%2BB" (the + becomes %2B)
V1: "value=A+B" (the space becomes +)
V2: "value=A%252BB" (the % becomes %25, so %2B → %252B)
V3: "value=A%26B%3DC" (the & → %26, = → %3D)
V4: "value=caf%C3%A9%2B%E7%8C%AB" (é → %C3%A9, plus → %2B, 猫 → %E7%8C%AB)
V5: "value=".
We verify in Node that append('value', original).toString() yields exactly these strings. Parsing those back in Python yields:
V0 parse: "A+B" (since %2B decode → +, with no plus-replace left), which equals the original "A+B". The original code points are [A, plus, B], and the decoded value has a plus at that position, so V0 matches.
V1 parse: "A B" (plus→space), equal to the original "A B".
V2 parse: "A%2BB"; the original was "A%2BB", so it matches character-for-character (even though those characters were literal % and 2).
V3 parse: "A&B=C", which matches the original.
V4 parse: "café+猫", which matches the original (the + reappears as literal plus from %2B, e.g. the + in the value), as do the Unicode characters.
V5 parse: "", which matches the original empty string.
Thus under the append-and-serialize-once path, all six originals survive one parse unmodified. In each case, the decoded string matches the independent original characters. What matters is that the string the application sees is identical. For V0 and V4 that means a plus is present; for V1 a space is present; V2 kept the literal %2BB pattern. In other words, this path respects the original code points.
In summary, the defect was not the WHATWG rules but using the URLSearchParams(string) constructor with an unescaped +. The constructor is intended for a fully-encoded query; using it on raw text is the mistake. The append-based method works as designed by the serializer specification.
Validate the receiver without decoding twice
On the Python side we parse the serialized query strings above. For each query (from either correct or incorrect path), we run:
from urllib.parse import parse_qsl
pairs = parse_qsl(query, keep_blank_values=True, strict_parsing=True,
                  encoding='utf-8', errors='strict', separator='&')
assert len(pairs) == 1 and pairs[0][0] == 'value'
received = pairs[0][1]
This enforces exactly one parameter named “value”. We do not apply any further decoding (e.g. no unquote or similar), because parse_qsl has already done percent-decoding and plus-to-space replacement. We also capture what Python sees: in a full HTTP test we’d compare pairs[0][1] to the original string.
Important: strict_parsing=True will raise an error if any segment has no = or if multiple values appear. It does not undo the plus-to-space or percent rules beyond one pass. For example, if a value still contains %2B text, parse_qsl will not turn that into a plus (it already did).
An extra decode can corrupt legitimate percent-looking data
As a negative control, suppose we mistakenly call a second decoder. For V2 we got received = "A%2BB" (from correct path). If we then ran decodeURIComponent (or Python’s urllib.parse.unquote) on this, we’d get "A+B", falsely interpreting %2B. But that extra decode is wrong here: the protocol says “exactly one parse.” Indeed, decodeURIComponent does decode percent escapes but it does not convert + to space (only form parsers do).
However, if a developer confuses form-parsing with URI-decoding, they might call unquote on "A%2BB", turning it into "A+B", which is not the original V2 string. This illustrates that once parsed, the string is final; a second decode is out-of-contract. We therefore do not apply a generic decodeURIComponent or unquote on the parsed value.
In sum, Python’s parse_qsl already gave us the correct “A%2BB” for V2, preserving the %2B. Running unquote on it yields "A+B" incorrectly. (We see that decodeURIComponent("A%2BB") === "A+B", whereas the form parser gave "A%2BB".) This matches MDN’s query-value guidance to use form decoders, not decodeURIComponent, for query values.
Expose pre-encoding before append as a different defect
We compare the double-encode path (append(encodeURIComponent(original))) to the raw append path. For each fixture:
V0 “A+B”: encodeURIComponent("A+B") → "A%2BB". Appending and then serializing yields "value=A%252BB" (because %→%25). Python parsing of that gives "A%2BB". This differs from the intended original "A+B". So V0 fails.
V1 “A B”: encodeURIComponent("A B") → "A%20B". Serializing gives "value=A%2520B". Parsing yields "A%20B", not "A B".
V2 “A%2BB”: encodeURIComponent("A%2BB") → "A%252BB". Serializing gives "value=A%25252BB". Parsing yields "A%2BB". In this one case, the final parsed string matches the original.
V3 “A&B=C”: encodeURIComponent("A&B=C") → "A%26B%3DC". Serializing gives "value=A%2526B%253DC". Parsing yields "A&B=C", which matches the original because double encoding re-escaped the delimiters.
V4 “café+猫”: encodeURIComponent("café+猫") → "caf%C3%A9%2B%E7%8C%AB". Serializing: "value=caf%25C3%25A9%252B%25E7%258C%25AB". Parsing yields "café+猫", matching original. (The two encodings reverted each other for valid UTF-8, and the %2B came through as +.)
V5 “”: encodeURIComponent→""; serializing yields "value="; parsing yields "".
So out of six, V2, V3, V4, V5 fortuitously meet the value contract. V0 and V1 fail because pre-encoding changed + or space. This shows a valid URL (the double-encoded strings are syntactically fine) can still violate intended payload. It also shows that just because some values survive pre-encoding (like plain text or pure ASCII), that’s no proof all values will.
Keep passing no-op inputs as controls, not proof
Simple inputs can “escape” this defect. For instance, if original were "abc123", encodeURIComponent does nothing and we’d see no difference. But V0/V1 demonstrate that even innocent-looking characters like + and space are altered. Even V4, with complex Unicode, survived, but V0/V1 did not. We should not let a quick smoke test of safe characters substitute for testing the actual data alphabet. A single alphanumeric or empty string passing does not guarantee correctness for all inputs. We include V0–V5 precisely to ensure plus, space, percent, delimiters, and non-ASCII are checked.
Separate query spelling from decoded value identity
One more nuance: the serialized form of the query is less important than the decoded value. For example, Node’s URL.searchParams vs URL.search (MDN example):
const url = new URL("https://example.com/?q=hello world");
console.log(url.search);            // "?q=hello%20world"
console.log(url.searchParams.toString()); // "q=hello+world"
Here, the semantic value is always "hello world", but the string differs (%20 vs +). This is fine as long as the decoder on the other side treats both as "hello world". In our test, if a serializer chose %20 instead of +, that should not cause a REJECT if the decoded meaning matches the original contract. (Work like signed URLs or exact byte checks are out-of-scope here; we only demand semantic identity.)
Keep the byte and code-point assertions in separate columns
In any report or test log, we must keep raw query and decoded value separate. We compare the decoded string to the original. If the raw query string differs from an expected pattern (e.g. a space is %20 not +), that’s noted as a different query spelling but not a value corruption. In our fixture table we’ll have columns for “emitted query text” and “decoded value”. We never allow a parser to become its own oracle by re-encoding and comparing bytes. The contract is on the string value after parse, not the exact percent layout. The original code points are our oracle, independent of transport.
Build an end-to-end value comparison ledger
We now compile all observations into a table. For each case (ID, original), we list: Path, Emitted Query (producer), Parsed Value (receiver), and Verdict. For brevity we show highlights (omitting byte dumps):
ID | Original | Path (constructor) | Emitted Query | Parsed Value | Verdict |
V0 | "A+B" | string='value=A+B' | value=A+B | "A B" | HOLD |
.append() | value=A%2BB | "A+B" | ACCEPT | ||
append(encodeURIComponent) | value=A%252BB | "A%2BB" | REPAIR (fix boundary) | ||
V1 | "A B" | string='value=A B' | value=A B | "A B" | REJECT (invalid raw) |
.append() | value=A+B | "A B" | ACCEPT | ||
append(encodeURIComponent) | value=A%2520B | "A%20B" | REPAIR | ||
V2 | "A%2BB" | string='value=A%2BB' | value=A%2BB | "A+B" | REPAIR |
.append() | value=A%252BB | "A%2BB" | ACCEPT | ||
append(encodeURIComponent) | value=A%25252BB | "A%2BB" | ACCEPT (dup safe) | ||
V3 | "A&B=C" | string='value=A&B=C' | value=A&B=C | error (2 pairs) | REJECT |
.append() | value=A%26B%3DC | "A&B=C" | ACCEPT | ||
append(encodeURIComponent) | value=A%2526B%253DC | "A&B=C" | ACCEPT (dup safe) | ||
V4 | "café+猫" | string='value=café+猫' | value=café+猫 | "café 猫" | REJECT (plus→space) |
.append() | value=caf%C3%A9%2B%E7%8C%AB | "café+猫" | ACCEPT | ||
append(encodeURIComponent) | value=caf%25C3%25A9%252B%25E7%258C%25AB | "café+猫" | ACCEPT (dup safe) | ||
V5 | "" (empty) | string='value=' | value= | "" | ACCEPT |
.append() | value= | "" | ACCEPT | ||
append(encodeURIComponent) | value= | "" | ACCEPT |
Paths: “string” is the wrong constructor path, “.append()” is the correct path, and “encodeURIComponent” is the negative control.
Emitted Query: exactly what Node’s toString() produced.
Parsed Value: what Python parse_qsl returned as the value string.
Verdict: whether that combination meets the contract.
In this ledger, “ACCEPT” means the parsed value equals the original string. “REPAIR” means the path altered the value but a fix is obvious (here, avoid the bad constructor). “REJECT” means out-of-contract (extra pairs or missing fields). “HOLD” applies to V0 raw-case because its value collided with V1 and no original survives in the data. For V0 using .append(), the value matched, so we later accept that path.
Failures in the parser-only check (e.g. extra pair for V3, or empty vs missing) are explicit in Verdict. We ensure each test was performed under the stated Node/Python versions; any divergence (e.g. if a hypothetical browser did something else with spaces) is beyond scope.
Repair the first incorrect boundary and preserve the old evidence
The root defect was using the URLSearchParams(string) constructor on raw text. The fix is to use raw-value insertion: URLSearchParams().append('value', original). We apply this to all cases, not just the ones with +. This repair passes all six tests as shown above. For example, changing V0’s code from new URLSearchParams('value=' + original) to encoded.append('value', original) changes its status from COLLAPSE to ACCEPT. We keep the old run data as evidence (it shows how the bug manifested).
We do not attempt a partial workaround like globally converting spaces to plus signs in the source string; that would risk changing legitimate spaces in other values. Instead, we rely on the encoding step to handle spaces. In practice, this means auditing any code that built queries by string concatenation and replacing it with append or set. We rerun the full fixture against the corrected code and observe all values round-trip. Any leftover failure would indicate another bug; in our tests there are none.
Choose ACCEPT, REPAIR, REJECT or HOLD
We now summarize policy based on the exact tested chain and one-value schema.
ACCEPT: The received string exactly matches the original. In our tests, that happens when we use the append path. V2 (A%2BB), V3, V4 (with append) and V5 all accept.
REPAIR: The raw path was wrong but we know how to fix it. For example, the string-constructor path for V0/V1/V4 was REPAIR by switching to append. We label those cases REPAIR since the payload was valid but misencoded. For V0/V1 using append(encodeURIComponent) path, we call them REPAIR because the fix is simply “don’t pre-encode before appending”.
REJECT: The payload format was out-of-contract. E.g. V3 using the raw constructor created two pairs, so that query must be rejected outright. Likewise, an unknown extra pair (or missing expected “value” parameter) leads to rejection.
HOLD: When distinctions are irreversibly lost by the code path. In particular, V0 and V1 when both become "A B" under the wrong constructor: we can’t tell whether the user meant “A+B” or “A B”. Since the original is no longer recoverable without outside info, we must mark it HOLD for human intervention or resubmission. In practice, this might mean prompting the user or logging for later reconciliation. We do not attempt to guess by blindly re-encoding spaces to pluses; that would invent data.
Lost distinctions cannot be recovered by a blanket replacement
A key example: once V0 and V1 are both sent through URLSearchParams('value=' + original), the receiver only sees "A B". There is no safe algorithm to convert spaces back to plus or vice-versa. Any global fix like value = value.replace(' ', '+') risks changing an actual space that was intended. Thus, without the authoritative original, the best we can do is HOLD such cases. Our playbook notes this explicitly: do not apply a generic “replace spaces with plus” rule on input data. Instead, require revalidation or re-entry of the original input.
Assign encoding ownership across the handoff
In summary, the encoding/decoding boundary clearly lies between the frontend’s serialization and the backend’s form parser. The frontend must ensure it constructs queries with the intended encoding semantics (using append or equivalent). The backend is simply following the standard decoding rules. If a framework router or proxy were in between, we would verify none of them alters the query. In our loopback setup we bypassed HTTP, but in production one should log the raw request URL target to confirm.
We recommend writing integration tests with fixtures like V0–V5 into the CI pipeline. Store them alongside the API schema. That way, any change (e.g. a router that percent-decodes early, or a shift to a different library) will immediately break a test. Version-control the fixture and test scripts in the frontend and backend repos. Annotate code comments with references to the WHATWG standard and the Node.js URLSearchParams documentation to avoid future confusion. (This is part of robust backend handoff practices, ensuring the encoding convention is contractually clear in the API spec.)
Strengthen frontend skills with explicit data contracts
Encoding issues like these reveal a deeper engineering lesson: always treat the form query as data, not UI markup. The string seen on screen (“A+B”) is not the same as the query bytes sent. Developers should learn to distinguish the displayed value from its URL-encoded payload. A frontend developer with solid API integration skills will know to use URLSearchParams or similar to handle encoding, rather than string concatenation.
For readers seeking formal training, note that Refonte Learning’s Frontend Development program covers exactly these foundations (JavaScript, React, REST API integration, Git, etc.) in a 4-month part-time curriculum (10–12 hrs/week), including practical exercises on URL handling and API calls. Engineers who understand how literal characters map through searchParams and parsers will write safer code and avoid these pitfalls.
In conclusion: literal plus signs remain plus signs only if you serialize them properly. By following the form-encoding standard and validating end-to-end, you can accept correct values, repair mis-encoded ones, and reject or hold the rest as specified. This acceptance-and-repair playbook ensures consistent frontend–API interoperability around URL queries.