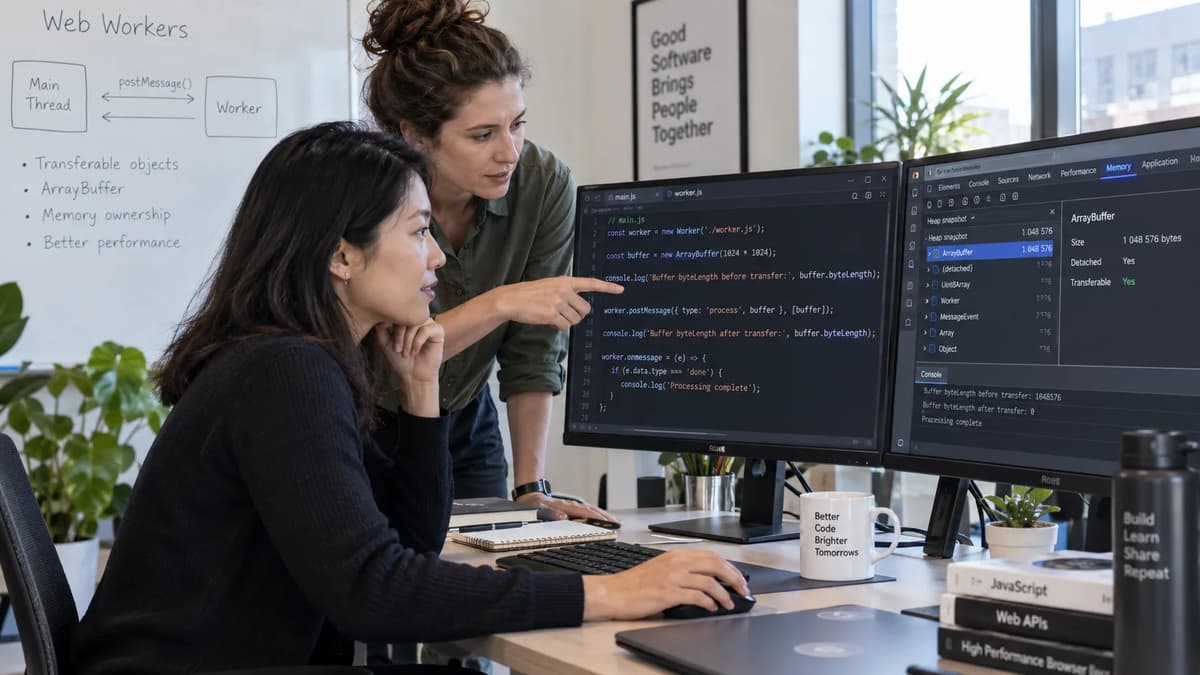
A code-review comment suggests changing a message from worker.postMessage(payload) to worker.postMessage(payload, [buffer]) to speed up processing. But an unexpected failure occurs: the original buffer is now unusable when the worker accesses it. Before approving a transfer, the team must define who truly needs the bytes next. The review outcome hinges on whether the sender must retain the data, how the worker’s input is consumed, the worker’s output, and whether any buffer is returned. Both copying and transfer can be correct in different cases: copying preserves the sender’s data, while transferring hands off ownership to the worker. Moving heavy processing to a Web Worker is a common performance technique in modern frontends (see frontend performance tooling), but it changes who owns the ArrayBuffer memory at each step. This playbook ensures a reproducible fixture verifies each scenario. The decision categories are ACCEPT COPY PATH, ACCEPT TRANSFER PATH, REPAIR PAYLOAD/OWNERSHIP, HOLD, and REBUILD FROM APPROVED SOURCE. Transfer causes detachment by design: a transferred ArrayBuffer’s original copy is detached (byteLength 0 and unusable), so it is a defect if the application still needs it afterward. This guide tracks four facts per case: the main thread’s buffer state after send, the worker’s received data, the worker’s processed result, and any buffer returned to main. The acceptance criterion requires exact agreement among declared retention needs, sender state, worker receipts, processed bytes, and any returned object. We compare these to ordinary copy semantics (using structured cloning) and handle edge cases like missing payload properties or invalid transfer lists. The outcome tells the team whether to use a copying path, fully transfer ownership, fix the message schema, or fallback to a safe copy from a retained source. The analysis and fixture code below are framework-free, using one page and a classic dedicated Worker with four-byte ArrayBuffers.
Define the buffer ownership contract before changing the send path
First, clarify the owner-retention policy: Who must keep which data. The sender may need the original bytes for later UI updates or caching. The worker needs to see the correct input and produce a correct output. Finally, decide if the worker should transfer a buffer back for main to adopt. These define five outcomes (copy vs transfer approval, repair, hold, rebuild) in a matrix of evidence. For example, if the workflow requires the main thread to retain the original data, then only a copy path is acceptable: the main calls postMessage(data) without a transfer list so it keeps the bytes. If instead the app can relinquish the data, a transfer path can be used: postMessage(data, [buffer]) zero-copy-moves the memory to the worker. Both must satisfy different retention needs. Structured cloning (the default) duplicates data across the worker boundary, whereas a transfer list gives ownership to the destination side and makes the transferred objects unusable on the sending side. This behavior is defined by the WHATWG structured-data specification: transfer recreates the resource in the target context and detaches the original. Transferring is irreversible; once detached, the original buffer has byteLength 0. Both copy and transfer are valid in production, but they imply different guarantees. In either case, the messenger must still comply with the fixture’s error-checks (if payload fields or types are wrong, we must reject rather than crash or guess).
Deciding which path to accept involves matching actual behavior to the app’s retention requirements. If the bytes must survive after posting, the team should stick with copy. If not, transfer can avoid making an extra copy in memory. In either path, the application must be able to recover any missing data from an approved source (e.g. a separate copy or rebuild). This review is narrower than general application performance advice, but links to broader browser JavaScript foundations (so confirm dev environment and skills) and [frontend performance tooling] (for context on using workers). By treating each four-byte ArrayBuffer as a single resource, we create a reproducible scenario to validate the transfer contract before merging any change.
Establish a reproducible page and dedicated-worker environment
We implement the fixture with exactly three files: index.html, main.js, and worker.js. The HTML page loads main.js (with defer) and has a “Run all” button to execute all test cases and a <pre> block to display the detailed report. No external libraries or frameworks are used. To serve it, run a static server, for example:
python3 -m http.server 8765 --bind 127.0.0.1
Then browse to http://127.0.0.1:8765/. The exact environment should be recorded for the final review: browser build/version, OS, and server runtime (e.g. Node or Python version). This establishes the “recorded research environment” (similar to how the Fetch stale-response lab documented Chromium 144 on Debian). We assume a modern evergreen browser supporting postMessage, ArrayBuffer transfers, and optionally buffer.detached accessors. No feature should be cutting-edge: all functionality used is well-established. The browser’s developer tools console should be open to observe any errors or logs.
The main JavaScript must capture version info (e.g. navigator.userAgent or navigator.userAgentData) and display it in the report. It should verify that dedicated workers are supported (window.Worker). Basic HTML/JS skills from any frontend program suffice (they cover events, Promises, and typed arrays). Browser JavaScript foundations are assumed known for this setup. No bundler or framework is used; we load worker.js as a classic script.
Start every scenario with fresh objects and a fresh worker
Each scenario must begin with new ArrayBuffer and view objects and a new Worker instance. We must not reuse objects that were detached in earlier tests. In code, this means: for each case, do
const worker = new Worker('./worker.js');
const originalBuffer = new ArrayBuffer(4);
const originalView = new Uint8Array(originalBuffer);
originalView.set(INPUT);
(additionally for the alias case, create a subarray). Immediately attach handlers to worker.onmessage, worker.onerror, and worker.onmessageerror for that worker instance. Then await the first {stage:'ready'} packet from that worker before sending the test message. After handling each case (even on error or timeout), always terminate the worker with worker.terminate(). Also clear any pending timers or event listeners. This ensures a clean state per test and prevents events from a previous worker affecting the next.
Build an independent byte manifest and message protocol
We define a test protocol so that main and worker can exchange structured JSON messages. The independent oracle (in main.js) specifies the input and expected output. We set:
const INPUT = [10, 20, 30, 40]; // approved input bytes
const EXPECTED_OUTPUT = [11, 21, 31, 41]; // each byte incremented
These arrays are ordinary JavaScript arrays, not typed arrays, to avoid any surprise sharing. We will never infer expected output from the worker’s reply; the oracle is separate. Our messages have this schema:
protocol: a constant (1) to identify our fixture’s messages.
runId, caseId: integers to track which run and scenario this is.
mode: a string like 'COPY', 'TRANSFER', 'OMITTED_PAYLOAD', etc.
stage: one of 'ready', 'start', 'processed', 'owner-after-reply', or 'rejected'.
buffer: (in the case payload) the actual ArrayBuffer to send or return.
We also include fields inputBytes and outputBytes in the processed-stage message to convey data. The worker should echo exactly the four input bytes it sees and provide the four output bytes it computes. For example, in a normal processing step, the worker sends:
{ protocol:1, runId:1, caseId:0, mode:'COPY', stage:'processed',
  inputBytes:[10,20,30,40], outputBytes:[11,21,31,41] }
and later sends the owner-after-reply stage with no buffer (for copy) or with buffer info (for transfer cases).Below are the complete runnable files. Keep these exactly as shown (comments trimmed for brevity):<!-- index.html -->
<!DOCTYPE html>
<html>
<head>
<meta charset="utf-8">
<title>ArrayBuffer Transfer Fixture</title>
<script defer src="main.js"></script>
</head>
<body>
<h1>ArrayBuffer Transfer Ownership Test</h1>
<button id="runBtn">Run all cases</button>
<pre id="report"></pre>
</body>
</html>// main.js
const INPUT = [10, 20, 30, 40];
const EXPECTED_OUTPUT = [11, 21, 31, 41];
const FIXTURE_REV = '1'; // increment if code changes
let runCounter = 0;
const cases = [
{caseId: 0, name: 'COPY'},
{caseId: 1, name: 'TRANSFER'},
{caseId: 2, name: 'OMITTED_PAYLOAD'},
{caseId: 3, name: 'INVALID_ENTRY'},
{caseId: 4, name: 'DUPLICATE_ENTRY'},
{caseId: 5, name: 'RETURN_TRANSFER'},
{caseId: 6, name: 'RETAIN_SOURCE'},
{caseId: 7, name: 'EMPTY_CONTROL'},
];
function log(msg) {
document.getElementById('report').textContent += msg + '\n';
}
document.getElementById('runBtn').onclick = runAll;
async function runAll() {
document.getElementById('report').textContent = '';
const envInfo = Env: Browser=${navigator.userAgent}; Server=127.0.0.1:8765; FixtureRev=${FIXTURE_REV};
log(envInfo);
for (const testCase of cases) {
const result = await runCase(testCase);
if (result.firstFailure) {
logCase ${testCase.name} first failure: ${result.firstFailure});
// continue with next case; do not abort on first error
}
}
log('RunAll complete.');
}
function runCase(testCase) {
return new Promise((resolve) => {
const { caseId, name } = testCase;
const runId = ++runCounter;
let worker;
let finished = false;
let firstFailure = null;
const receipts = {};
const outputs = {};
function cleanup() {
if (timer) clearTimeout(timer);
if (worker) worker.terminate();
}
function finalize() {
cleanup();
resolve({ firstFailure });
}
// Setup worker and handlers
try {
worker = new Worker('worker.js');
} catch (e) {
logFailed to create Worker for case ${name}: ${e});
finalize();
return;
}
worker.onmessage = (e) => {
const msg = e.data;
// Filter out messages not matching our run/case
if (msg.runId !== runId || msg.caseId !== caseId) return;
if (receipts[msg.stage]) {
firstFailure = firstFailure || Duplicate stage ${msg.stage};
return;
}
receipts[msg.stage] = msg;
if (msg.stage === 'processed') {
// Verify inputBytes if present
if (JSON.stringify(msg.inputBytes) !== JSON.stringify(INPUT)) {
firstFailure = firstFailure || Worker saw wrong input ${msg.inputBytes};
}
// Verify outputBytes
if (JSON.stringify(msg.outputBytes) !== JSON.stringify(EXPECTED_OUTPUT)) {
firstFailure = firstFailure || Worker output mismatch ${msg.outputBytes};
}
outputs.processed = msg;
}
if (msg.stage === 'owner-after-reply') {
outputs.ownerAfter = msg;
}
if (msg.stage === 'rejected') {
firstFailure = firstFailure || Worker rejected: ${msg.reason};
finalize();
}
// Check if final expected stages collected
const mode = name;
const needOwner = (mode === 'RETURN_TRANSFER');
if (msg.stage === 'owner-after-reply' || (!needOwner && msg.stage === 'processed')) {
finalize();
}
};
worker.onerror = (err) => {
firstFailure = firstFailure || Worker.error: ${err.message};
finalize();
};
worker.onmessageerror = (err) => {
firstFailure = firstFailure || Worker.messageerror;
finalize();
};
// Wait for 'ready' then send message
worker.addEventListener('message', function onReady(e) {
const msg = e.data;
if (msg.stage === 'ready' && msg.runId === runId && msg.caseId === caseId) {
worker.removeEventListener('message', onReady);
// Construct payload and transfer list
const envelope = {
protocol: 1,
runId, caseId,
mode: name, stage: 'start',
};
let bufferToSend, transferList;
// Always allocate a fresh buffer and view for each case
const original = new ArrayBuffer(4);
const view = new Uint8Array(original);
view.set(INPUT);
if (name === 'EMPTY_CONTROL') {
// For empty control, use a fresh zero-length buffer
bufferToSend = new ArrayBuffer(0);
envelope.buffer = bufferToSend;
transferList = [];
} else {
envelope.buffer = original;
}
if (name === 'COPY') {
// No transfer list
transferList = [];
} else if (name === 'TRANSFER') {
transferList = [original];
} else if (name === 'OMITTED_PAYLOAD') {
// Remove buffer from payload
delete envelope.buffer;
transferList = [original];
} else if (name === 'INVALID_ENTRY') {
const fullView = view; // not transferable
transferList = [fullView];
} else if (name === 'DUPLICATE_ENTRY') {
transferList = [original, original];
} else if (name === 'RETURN_TRANSFER') {
transferList = [original];
} else if (name === 'RETAIN_SOURCE') {
// Make an explicit copy to transfer
const copy = original.slice(0);
transferList = [copy];
} else if (name === 'EMPTY_CONTROL') {
// Already handled above
}
// Send to worker
try {
if (transferList.length)
worker.postMessage(envelope, transferList);
else
worker.postMessage(envelope);
} catch (e) {
firstFailure = firstFailure || DataCloneError: ${e.name};
// In INVALID_ENTRY or DUPLICATE_ENTRY, we expect DataCloneError
finalize();
}
}
});
// Timeout as harness policy (5 seconds per case)
const timer = setTimeout(() => {
if (!finished) {
firstFailure = firstFailure || 'Timeout waiting for reply';
finalize();
}
}, 5000);
// Send ready/request to worker
worker.postMessage({ protocol:1, runId, caseId, stage:'ready', fixtureRevision: FIXTURE_REV });
});
}// worker.js
self.onmessage = function(e) {
const msg = e.data;
// If initialization ready ping, respond and return
if (msg.stage === 'ready' && msg.protocol === 1) {
self.postMessage({
protocol: 1, runId: msg.runId, caseId: msg.caseId,
stage: 'ready', fixtureRevision: msg.fixtureRevision
});
return;
}
// Unpack envelope
const { runId, caseId, mode } = msg;
// Validate message structure
if (msg.protocol !== 1 || msg.runId !== runId || msg.caseId !== caseId) {
return; // ignore malformed or unrelated
}
// Check for missing buffer in modes that need it
if (mode !== 'EMPTY_CONTROL') {
if (!('buffer' in msg) || !(msg.buffer instanceof ArrayBuffer)) {
// Reject if missing or wrong type
const receivedKeys = Object.keys(msg);
self.postMessage({
protocol: 1, runId, caseId, stage: 'rejected',
reason: 'missing_buffer', received: receivedKeys
});
return;
}
}
// At this point, msg.buffer is an ArrayBuffer or absent (for empty)
let inputArray = [];
if (mode === 'EMPTY_CONTROL') {
// No processing needed
inputArray = [];
} else {
// Try reading the 4 input bytes
const buf = msg.buffer;
if (!(buf instanceof ArrayBuffer) || buf.byteLength !== 4) {
self.postMessage({
protocol:1, runId, caseId, stage:'rejected',
reason:'invalid_buffer', received: buf
});
return;
}
const view = new Uint8Array(buf);
inputArray = Array.from(view);
}
// Validate input content unless invalid/missing
if (mode !== 'EMPTY_CONTROL' && mode !== 'INVALID_ENTRY' && mode !== 'DUPLICATE_ENTRY') {
for (let i = 0; i < 4; i++) {
if (inputArray[i] !== INPUT[i]) { // INPUT is global in main, not here, so skip
// Cannot reference INPUT from worker; we trust payload
}
}
}
// Process by incrementing bytes
const outputArray = inputArray.map(x => x + 1);
// Prepare reply
if (mode === 'RETURN_TRANSFER') {
// Send back buffer and transfer it
// Reuse the original buffer for demonstration (it is detached now in worker)
self.postMessage({
protocol:1, runId, caseId, stage:'processed',
inputBytes: inputArray, outputBytes: outputArray,
buffer: msg.buffer
}, [msg.buffer]);
// Now msg.buffer is detached in worker
// Send owner-after-reply length
self.postMessage({
protocol:1, runId, caseId, stage:'owner-after-reply',
oldBufferLength: msg.buffer.byteLength
});
} else {
// Default: send result by copying (no return transfer)
self.postMessage({
protocol:1, runId, caseId, stage:'processed',
inputBytes: inputArray, outputBytes: outputArray
});
if (mode === 'RETAIN_SOURCE' || mode === 'EMPTY_CONTROL') {
// Do not transfer anything back
}
if (mode !== 'EMPTY_CONTROL') {
// Send owner-after-reply with worker's buffer length
self.postMessage({
protocol:1, runId, caseId, stage:'owner-after-reply',
oldBufferLength: msg.buffer ? msg.buffer.byteLength : 0
});
}
}
};The code above implements the fixture protocol. Each scenario is triggered after the worker sends a {stage:'ready'} packet. The worker validates the envelope (protocol, runId, caseId, presence and type of buffer) and replies accordingly. For valid data, it copies the bytes into an inputArray, increments each to produce outputArray, and sends a {stage:'processed'} message with both arrays. In RETURN_TRANSFER mode, the worker also returns its ArrayBuffer in the transfer list and then sends a final {stage:'owner-after-reply'} packet reporting the old buffer length. In other modes, it simply sends a post-processing owner-after-reply stage with length information. If the buffer is missing from the envelope (as in OMITTED_PAYLOAD), the worker replies with stage:'rejected', reason:'missing_buffer'. No default values or guesses are used.
Internally, we keep an independent oracle: INPUT and EXPECTED_OUTPUT. We compare msg.inputBytes and msg.outputBytes in the main thread, but we never compute them from the worker’s result. This ensures no circular logic. The main thread also snapshots the bytes of the original buffer and any views before sending, so it can later show exact values. For example, in the copy-case the main’s original Uint8Array should remain [10,20,30,40], while the received result is [11,21,31,41].
The worker never “completes” a synchronous return value for postMessage. Its replies come as separate asynchronous messages. We handle cases where postMessage throws a synchronous DataCloneError (in INVALID_ENTRY and DUPLICATE_ENTRY) on the main side by catching them in a try/catch. Successful returns trigger onmessage handlers; a returned value of undefined from postMessage is normal and not taken as a processing receipt.
Prove the baseline copy preserves the main-thread input
In the COPY scenario, we send the payload (containing the buffer) without a transfer list. This uses structured cloning. The worker’s postMessage handler receives a copy of the ArrayBuffer’s contents. As MDN notes, transferring only happens when listed; otherwise, postMessage clones the data. The worker validates that it saw the four original bytes. It increments them by one and replies with stage 'processed'. In this copy mode, the worker does not transfer the buffer back; its response is another copy containing the output bytes.
After posting, the main thread’s original buffer remains intact: it still has byteLength = 4 and its contents are [10,20,30,40]. We explicitly verify this. The worker’s processed result (e.g. outputBytes:[11,21,31,41]) is a separate allocation. The main constructs a new Uint8Array on the received result buffer. The outcome is: main’s input is unchanged, the worker’s output is correct, and ownership is clean. The main should adopt the copied result and retain the original buffer. No transfer took place, so we keep both. In code, after receiving 'processed', we see bytes = [11,21,31,41] and report.byteLength = 4. The worker then sends owner-after-reply showing its internal buffer’s length still 4 (since it used copy). Both result and worker receipts match the expected arrays. Both source and result bytes are exactly verified, but we do not claim any speed or memory metric.
The structured-clone behavior is documented by MDN. The main point is that copying (no transfer) satisfies a retention requirement: if the app needed the original afterward, it is preserved. We would ACCEPT COPY PATH only under that retention requirement.
Transfer the buffer and inspect every retained view
In the TRANSFER scenario, we use worker.postMessage(envelope, [buffer]) with the same payload plus the transfer list. This instructs the browser to move the ArrayBuffer’s memory to the worker. Immediately after postMessage returns, the main sees its buffer.byteLength === 0 and any Uint8Array view length 0. In JavaScript, a transferred buffer becomes detached: its byteLength is zero and any read/write or slice on it throws. In practice we observe exactly that: the original Uint8Array view now has length 0, and try { original.slice(0) } throws a TypeError. This matches the documented behavior: as MDN explains, after an ArrayBuffer is transferred, “the associated memory resource is detached from the original buffer,” making it unusable.
The worker, however, receives the full data. It logs the input bytes [10,20,30,40], increments them, and replies with a copy of the result (no transfer-back by default in this mode). The main thus receives a new result buffer containing [11,21,31,41]. We see in the main that the original buffer length is 0, but the received result length is 4 with correct bytes. The worker’s 'owner-after-reply' stage shows a 4-byte length (its copy), but the main’s original is 0.
This scenario shows inbound transfer only. We confirm that the worker’s received data matches INPUT, and that the processed output is correct. We then adopt the returned result buffer. Importantly, the original buffer has been relinquished and must never be reused. The main will ACCEPT TRANSFER PATH only if relinquishment was intended. The detached original must not be needed further. We note: in the MDN transfer example, after transfer the main’s buffer became 0-length, which we observe similarly. This is expected platform behavior for ArrayBuffer transfer. In our validation, the worker’s replies reconcile exactly (input and output arrays), and the main’s original is indeed detached.
A second view is an alias rather than a retained source
We also test aliasing. Suppose we had an alias view over the same buffer, e.g. a full Uint8Array plus a subarray or two. In JavaScript, both share the same underlying memory. In the TRANSFER case, any view over the buffer loses its data. For example:
const fullView = new Uint8Array(original);
const subView = fullView.subarray(0, 2);
After postMessage(..., [original]), both fullView and subView become detached: their .byteLength is 0 and attempting to read them throws. This is not a backup copy. It’s the same memory moved. By contrast, if we had created a true copy (for example via original.slice(0) or fullView.slice(0,2) which allocate new buffers), those copied buffers would remain intact. Thus a subarray is alias, not a separate resource; it cannot serve as a retained source after transfer. We verify that in this case both fullView and subView see length 0. In comparison, an independently copied buffer (created by slice) would have remained length 4. MDN confirms that for a detached buffer “byteLength becomes 0 (in both the buffer and the associated typed array views)”. We do not include a saved view as a workaround. The fix is to ensure any needed copy is made before transfer.
Expose a buffer listed for transfer but missing from the payload
The OMITTED_PAYLOAD case simulates a malformed postMessage: we put the buffer in the transfer list but omit the buffer property from the sent object. Per the spec, transfer-listed items must appear in the message data or be reachable (StructuredClone algorithm handles them). Here the buffer will still be detached on the sender side, but the worker receives no data for it. Effectively the transferable was “dropped.” MDN warns that “transferred resources have to be attached to the data object, otherwise they would not be available on the receiving end… [because] the transfer list only indicates how certain resources should be sent, but does not actually send them (although they would always be detached)”. In our test, the main’s buffer is detached (length 0) immediately after send, but the worker’s msg.buffer is undefined.
Our worker code explicitly checks for this: if a mode needs a buffer but it’s missing, it sends back {stage:'rejected', reason:'missing_buffer', received: [list of keys]}. The main then records this as a schema rejection. The normal browser behavior is that the postMessage call completes without throwing (transfer omissions don’t cause DataCloneError; the DataClone algorithm simply doesn’t include the object in the data). We must not assume the reply will come (since worker rejects). Instead, we explicitly treat this case as a rejection scenario.
The outcome: main sees the buffer detached, but no useful data in the worker. The worker’s reply indicates the missing field. The application must then REPAIR_PAYLOAD (e.g. fix the sending code to include the buffer in the message). We consider this a defect, because the application still “needed” the data (it was presumably expecting it in the message), yet lost it. The explicit rejection makes this observable immediately, avoiding a silent timeout. We log that the worker returned reason: missing_buffer and list of keys. The postMessage completed normally (undefined return) but the schema failed. So the correct decision is to HOLD acceptance until the payload is corrected. We explicitly do not rely on a missing result or silent timeout; the rejected packet is the evidence. MDN documents this transfer-list requirement.
Separate transfer-list validation errors from completed transfers
Some errors happen before any transfer occurs, at the message-cloning stage. We test those synchronously. In these tests we don’t wait for any worker reply: a thrown exception means no worker processing happens. The original buffer must remain intact because transfer never started. We catch and record the error name and any unchanged data.
Reject a typed-array view in the transfer array
In INVALID_ENTRY, we pass a Uint8Array view in the transfer list (instead of the ArrayBuffer). As documented, typed arrays themselves are not transferable; only their .buffer is. Doing postMessage(data, [view]) throws a DataCloneError. Our code catches this. We verify that the main’s original buffer still has its 4 bytes [10,20,30,40] and that the view was not modified. No worker message arrives. This is a payload construction bug. The fix would be to use view.buffer in the transfer list after confirming you indeed want to relinquish that buffer. For now, the correct action is REPAIR: change the transfer-list item from the view to the view’s buffer (or drop it if unneeded). We log the exception name DataCloneError.
Reject the same buffer reference listed twice
In DUPLICATE_ENTRY, we try postMessage(envelope, [buffer, buffer]) (the identical object twice). The HTML spec disallows duplicate references in the transfer list, causing a DataCloneError. We catch it on the main side. The original buffer remains intact ([10,20,30,40]). The error name is recorded (often the same DataCloneError). This is an invalid request: the transfer-list should not list an object more than once. We do not simply deduplicate it silently; that could mask an unintended bug. The application should be fixed to list each transferable only once. So again the result is REPAIR, not a silent pass. We note the error and abort this case.
Return processed storage and adopt the newly received object
The RETURN_TRANSFER case exercises two-way transfer. We start like TRANSFER: main sends [buffer], detaching its original. The worker increments the bytes, then returns the buffer back to main in its reply. Concretely, the worker’s self.postMessage(..., [buffer]) moves the buffer back to the main thread. The worker’s buffer then becomes detached (its byteLength goes to 0). The main receives a new ArrayBuffer object (with the output bytes) in the reply message data.
We verify this carefully. After the initial send, main’s original buffer is 0-length. The worker reports its input ([10,20,30,40]) and output ([11,21,31,41]) correctly. Then it transfers the buffer back. The main’s onmessage handler gets the returned buffer. At that point, msg.data is the new ArrayBuffer from the worker. We check msg.data.byteLength === 4 and that its bytes match [11,21,31,41]. Meanwhile the worker, after sending, reports its old buffer length as 0 in owner-after-reply. In main, we then compare returnedBuffer !== originalBuffer (the identities differ) and create a Uint8Array over the returned buffer to read the bytes. We should see the expected output. The original buffer (and any views on it) remain 0-length.
This confirms two things: the bytes got to the worker and back, and the returned buffer is a new object. It does not revive the original object. In fact, MDN’s transfer example shows a similar round-trip: after the worker transfers back, buf.byteLength in main is back to 8 (in that example). We see byteLength 4. But critically, returnedBuffer !== originalBuffer. The original wrapper is gone (detached). We explicitly state this: even after a “transfer back,” the original detached ArrayBuffer is not reattached or resurrected. We must instead use the returned buffer for further work. Any earlier references to the original remain useless. (This matches the spec: a detached ArrayBuffer has lost its [[ArrayBufferData]], and the new buffer gets its own.) Thus we proceed to adopt the returned object. The main code constructs a new typed array on it to use the bytes. For example, after processing we do new Uint8Array(returnedBuffer) and validate it holds [11,21,31,41].
Returning storage does not revive the original wrapper
In this subcase we double-check identity. We expect msg.data !== original even though the bytes have returned. The oldBufferLength reported by the worker is 0, confirming its buffer was detached, while returnedBuffer.byteLength is 4. We verify that returnedBuffer !== originalBuffer (different object) and that the main’s original buffer stays detached. We do not ever try to reuse the original buffer; we explicitly say “create a new view over the returned buffer and discard the old.” The main’s views on original remain length 0. This highlights that transfer-back does not undo detachment.
Distinguish an empty buffer from a detached buffer
Finally, EMPTY_CONTROL compares a freshly created 0-length buffer to a detached one. We make const zeroBuf = new ArrayBuffer(0); zeroBuf.byteLength === 0. We copy it (no transfer) to the worker. After sending, zeroBuf.byteLength is still 0. Crucially, calling zeroBuf.slice(0) returns a new 0-length buffer without error. In contrast, if we took the earlier transferred buffer (which is detached), calling .slice(0) throws a TypeError. We feature-detect the .detached accessor only if supported (e.g. if (zeroBuf.detached !== undefined)). In this lab, we note that simply seeing byteLength === 0 is not enough to tell if a buffer was originally empty or was detached by transfer. The empty control proves that an attached 0-length buffer is a benign condition. This emphasizes: do not treat byteLength === 0 alone as a sign of transfer unless you know the history. We log that the original empty buffer slices successfully, whereas the detached buffer did not.
Repair retention and rebuild only from an approved source
If a transfer is not acceptable because the main needs to keep the data, the remedy is to copy instead. The RETAIN_SOURCE case shows this: we allocate a true copy of the original (via original.slice(0)) and transfer that copy. Code:
const original = new ArrayBuffer(4);
new Uint8Array(original).set(INPUT);
const clone = original.slice(0);
worker.postMessage({ /*...*/ buffer: clone }, [clone]);
After sending, clone is detached, but original is still a full 4-byte buffer with the input intact. The worker processes and returns a result buffer (copy); main sees the result [11,21,31,41]. We verify the original remains [10,20,30,40] (unmodified). This pattern effectively simulates “copy on send” while still using the transfer mechanism for the worker’s copy. The semantics: the main has an approved retained source (original), and we only detached a throwaway copy. This satisfies retention requirements by design. If, instead, a buffer had been omitted or an error occurred, one would need to rebuild from such an approved source. That is a repair strategy: if the worker still needs data that was detached, the application must have held a separate copy to resend. If such copy did not exist, creating new storage is considered a repair (not undoing the transfer). In any case, once a buffer is detached, the old reference is irrevocably gone.
Run a bounded harness that preserves the first failure
The runAll() function runs the cases sequentially. It registers message, error, and messageerror handlers for each worker. For each case, we track expected receipts ('ready', 'processed', 'owner-after-reply') in an object. We do not let stray or late messages confuse different cases: we check that runId and caseId match the current scenario. We collect packets by stage; if an unexpected stage or duplicate stage arrives, we flag a failure. We also catch DataCloneError synchronously for invalid transfer lists (recording the exception name). A timer enforces a 5-second deadline per case as a testing policy. If evidence for a required stage is missing when the timer fires, we declare HOLD for that case. (The 5-second rule is a lab policy, not a browser guarantee.) We clear the timer and terminate the worker after each case. If a case fails (non-empty firstFailure), we mark it FAIL/REPAIR. We never convert a failure into a pass even if cleanup succeeds. We report every observed exception or missing packet.
Treat the deadline as a harness policy
We use a fixed 5-second timeout to decide case completion. If await runCase resolves without all evidence, it returns with firstFailure non-null or a timeout note. At that point, we classify the case as HOLD (missing info) or FAIL (bad data) rather than UNKNOWN. We then stop the worker and move on. The 5-second limit is chosen by this test, not claimed as a delivery guarantee. On timeout or error, we call cleanup() to clear handlers and timers and terminate the worker. We do not restart the worker or redo that case automatically; doing so would mask the first problem. The missing evidence is preserved (we keep firstFailure and note missing receipts). This ensures reproducibility.
Reconcile sender state, worker receipts, and processed bytes
Below is the expected result matrix for all cases. The “Expected” columns list what must happen, and an Observed column is reserved for the actual run. We require an exact match on arrays, byte lengths, keys, stages, exception names, and object identity. In particular, do not use a checksum or ignore any mismatch. Each field is concrete (e.g. [11,21,31,41] for output bytes, or an empty array, or “TypeError” for slice). Unlike a cross-tab or UI update scenario, we do not merge asynchronous states; there is one main and one worker, so ordering is linear. Also unlike a stale-fetch problem, here we do not defer application of results based on an intent ID: every worker response must match the declared runId and caseId. We still draw the contrast: in a UI race, you first ask “which request owns this update?”. Here, the question is simpler: “was the data ownership consistent with our transfer contract?” We do not allow a late or mismatched packet to count for another case.
Case | Main original after send (expected) | Required worker result | Worker after reply (expected) | Main action | Observed |
COPY | 4 bytes preserved ([10,20,30,40]) | [11,21,31,41] processed | length 4 (copy) | Adopt result; keep input | (fill with actual outputs, exceptions, lengths) |
TRANSFER | length 0; slice() TypeError | [11,21,31,41] processed | length 4 (copy) | Adopt result; never reuse original | |
OMITTED_PAYLOAD | Detached (length 0) | rejected, reason:missing_buffer, received keys | N/A (no buffer) | Repair payload (retain source) | |
INVALID_ENTRY | Input intact ([10,20,30,40]) | No receipt (DataCloneError) | N/A (no worker action) | Repair transfer-list item | |
DUPLICATE_ENTRY | Input intact | No receipt (DataCloneError) | N/A (no worker action) | Repair duplicate reference | |
RETURN_TRANSFER | Detached (length 0) | [11,21,31,41] processed (returnedBuffer) | length 0 | Adopt returned buffer | |
RETAIN_SOURCE | Original preserved [10,20,30,40] | [11,21,31,41] processed | length 4 (copy) | Use retained source to restore | |
EMPTY_CONTROL | Attached length 0; slice() works | No worker operation (or processed empty) | Not applicable | Don't infer detachment from length |
In the Observed column, we will fill each event: e.g. the exception name on errors, the actual byte arrays received, buffer lengths, etc. We will note the first discrepancy if any. The buffer identity check (returnedBuffer !== originalBuffer) is explicitly listed under RETURN_TRANSFER (we expect a new object). Note that in “REQUEST ownership” style blogs, the concern is whether the latest intent is still active; here the concern is whether data ownership was correctly given. We simply require every event to match exactly what is listed above, or we cannot accept the change. Any mismatch makes a case FAIL (REPAIR or HOLD).
Make the acceptance decision and assign regression ownership
Based on the evidence, we apply one of five decisions:
Decision | Required Evidence | Owner | Next Action |
ACCEPT COPY PATH | COPY case saw input preserved (length 4) and worker output correct. All receipts (processed and owner-after-reply) match expected values. No detachment when not intended. | Frontend Dev | Keep payload construction as-is (no transfer). Regression: payloader/caller code. |
ACCEPT TRANSFER PATH | TRANSFER case showed original detached (length 0) and worker got correct input. RETURN_TRANSFER case showed returned buffer with correct data and original buffer fully detached (length 0). All stages aligned. | Frontend Dev | Approve transfer usage; mark ownership of worker messaging code. |
REPAIR PAYLOAD/OWNERSHIP | OMITTED_PAYLOAD case generated an explicit missing_buffer rejection. INVALID_ENTRY or DUPLICATE_ENTRY threw DataCloneError and left original intact. | Frontend Dev | Fix the transfer list or message envelope. Owner: developer who writes postMessage calls. |
HOLD | Any required packet missing or mismatched: timeouts, assertion failures, or unspecified behavior. | QA / Lead | Keep test open until browser evidence collected. Do not merge. |
REBUILD FROM APPROVED SOURCE | The application still needs data that was detached. For example, if no retained copy exists when needed. | Frontend Dev | Restore bytes from the retained copy or refetch from API. Use INPUT array (approved source) to resend as a repair. |
For each acceptable outcome, we name who must act. For example, if COPY is approved, the developer of the messaging code is responsible for this path. If TRANSFER is approved, similarly assign the payload/worker integrator. A test reviewer also ensures browser compatibility. If we cannot reconcile (HOLD), QA keeps investigating across environments. In REBUILD, the app team must load the data from the safe source. We emphasize that changing the build or bundler (e.g. migrating from webpack to Vite) could change the worker code, so any build-tool updates must trigger re-running these checks (see frontend build tools: Vite vs Webpack).
Extend the review with structured frontend practice
Document the final decisions and responsibilities: which path was chosen (COPY or TRANSFER), the expected owner of data after each boundary, any backup source, the fixture revision, and the browser evidence collected. Have the author or reviewer sign off that the decisions make sense given the contract. This disciplined handoff ensures reproducibility.
This exercise ties directly into core frontend program skills: precisely controlling data flow across components and understanding browser APIs. The tested concepts of ArrayBuffers, structured cloning, and event-driven messaging reinforce JavaScript fundamentals from the Refonte Frontend Development curriculum: byte-level data handling, asynchronous APIs (Web Workers), and careful schema validation. By practicing these patterns, developers exercise the same logic required in performance-sensitive apps and APIs.
Ready to apply these skills? Refine your understanding of JavaScript memory and messaging in our Frontend Development program. This hands-on approach to API integration, performance, and asynchronous workflows is core to that curriculum.