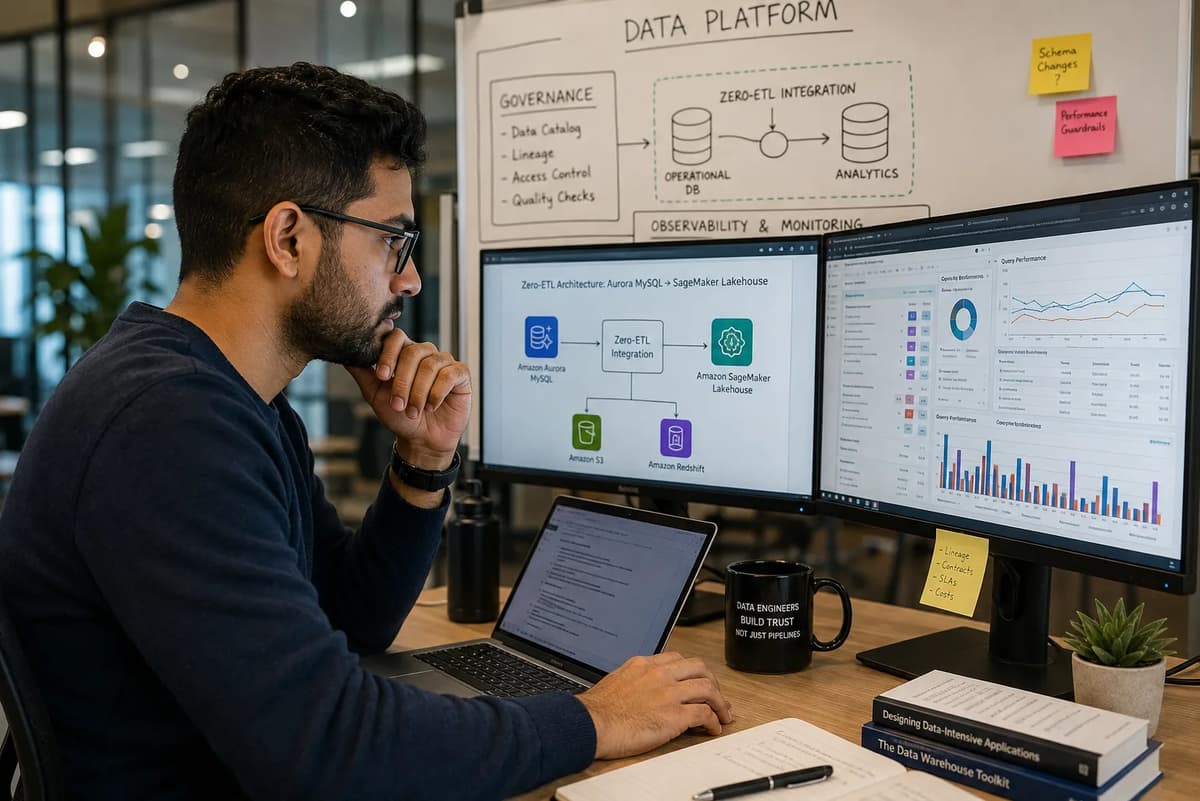
I have been building production data pipelines long enough to know that the most expensive sentence in data engineering is usually some variation of: “We won’t need to maintain that anymore.”
That was the pitch around zero-ETL. Connect the operational database directly to the analytics platform, let the cloud provider handle synchronization, delete a pile of extraction jobs, and stop paying engineers to babysit plumbing. On the architecture slide, it looked beautiful.
Then an application team changed a source schema.
Nothing dramatic happened at first. The managed integration continued doing exactly what it was designed to do, but a downstream model had encoded assumptions about the old column contract. A dashboard was still refreshing, just incorrectly; another consumer failed later, far enough away from the source change that the first hours of debugging went into the wrong system.
That is the part of zero-ETL data engineering the original sales pitch tended to skip.
The useful question behind the search phrase zero-ETL architecture 2026 is no longer “Can zero-ETL work?” It clearly can. AWS has shipped multiple production zero-ETL integrations, including the general availability of Aurora MySQL and Amazon RDS for MySQL integration with Amazon SageMaker on June 30, 2025.
The question in 2026 is more mature: which part of the pipeline disappeared, which responsibilities merely moved somewhere else, and who owns them now?
That distinction matters to engineers planning their careers as much as it matters to architects selecting platforms. The Refonte Learning Data Engineering Program, for example, teaches pipeline design alongside data governance, compliance, storage, security, and big-data processing. Those latter skills become more, not less, important as managed integrations take responsibility for basic data movement. Refonte’s live program page lists a three-month format at 12–14 hours per week and explicitly includes data governance and compliance controls among its competencies.
This article separates the production reality from the zero-ETL slogan: what the architecture actually does, what AWS really shipped, where schema drift and governance still hurt, why “zero-copy” and “zero-ETL” should not be treated as synonyms, and why the data engineer role change in 2026 looks much more like a move from pipeline builder to data platform architect than the disappearance of data engineering.
The Pitch: Zero-ETL as the End of Pipelines
The marketing version of zero-ETL is easy to understand because traditional ingestion genuinely carries operational baggage.
A conventional operational-database-to-warehouse workflow might include a source connector, credentials, extraction scheduling, incremental-watermark logic, retries, backfills, schema mappings, staging storage, monitoring, orchestration, destination loading, and someone on call when one of those components stops agreeing with another. Every component becomes another surface where a certificate can expire, an API can change, an offset can be lost, or a retry can duplicate data.
Zero-ETL attacks a real problem.
AWS itself uses relatively careful wording: its definition says zero-ETL is a set of integrations that minimizes the need to build ETL pipelines rather than claiming that all extraction, transformation, loading, governance, and modeling work vanishes. That wording is considerably more accurate than the “no more pipelines” shorthand that often appears once the architecture reaches an executive presentation.
What leadership may hear | What the architecture actually means |
“No pipelines” | No separately operated ingestion pipeline for supported source-target combinations |
“No ETL” | Data movement is managed; transformation may still happen downstream |
“Real time” | Usually near-real-time replication or query-time access, with implementation-dependent latency |
“No maintenance” | Less connector and scheduler maintenance; more attention to schemas, contracts, permissions, cost, and integration health |
“No copies” | Only true for some federation/virtualization patterns; several zero-ETL products replicate data |
“No data engineers” | Engineers shift toward governance, contracts, observability, performance, access design, and platform architecture |
That last distinction is the heart of the story.
Serena Monroe’s March 10, 2026 DataFuseAI analysis, “Zero-ETL Architecture Limitations: What Vendors Don’t Say,” makes essentially the same distinction: zero-ETL can remove a dedicated ingestion layer for certain source-target combinations, but it does not remove transformation, schema management, data quality, governance, or the engineering required when source systems evolve. DataFuseAI sells ETL technology and therefore has a commercial point of view, but the architectural distinction itself aligns with AWS’s narrower official definition.
Mochammad Arie Nugroho reached a similar conclusion in his February 24, 2026 practitioner essay “Zero ETL Is Not Magic: How Direct Integrations Are Reshaping Data Engineering in 2026.” His framing is particularly relevant for career planning: less time is spent building ingestion plumbing, while more engineering moves toward data contracts, quality controls, semantic layers, cost management, and governance.
Khushbu Shah’s January 19, 2026 article “Zero ETL Is the Reality Check Every Data Engineer Needs in 2026,” published by AWS in Plain English, an independent publication rather than an official AWS product announcement, frames the resulting role as closer to a platform designer or platform architect than a logistics operator.
That is exactly what production experience suggests.
When I remove a hand-built extractor, I may eliminate 500 lines of connector code and one Airflow DAG. I do not eliminate the question of whether customer_id still means the same thing, whether finance is allowed to read the replicated table, whether deletion semantics satisfy policy, whether a type change will break a BI model, whether latency is within the service-level objective, or whether a 20-table analytical join should be running through this access path at all.
And that is why zero-ETL sits at a different architectural layer from Airflow vs. Dagster vs. Prefect for data orchestration. Orchestrators coordinate work; zero-ETL attempts to make one category of data-movement work unnecessary or provider-managed. Refonte Learning’s orchestration comparison remains relevant when transformations, quality checks, cross-cloud workflows, or other jobs still require scheduling and dependency management.
The honest pitch should therefore be narrower:
Zero-ETL can eliminate substantial ingestion plumbing for supported workloads. It does not eliminate the data lifecycle surrounding that ingestion.
That is less exciting on a sales deck. It is much more useful in an architecture review.
What Zero-ETL Actually Is, Technically
“Zero-ETL” is not one single mechanism.
Depending on the product, it can mean provider-managed change data capture and replication, database-native integration, a zero-copy logical reference, federated querying, or a combination of metadata virtualization and managed storage. Treating all of those as equivalent leads directly to bad assumptions about latency, source-system load, failure modes, and governance.
Pattern commonly called zero-ETL | Does data physically move? | Where queries execute | Main engineering trade-off |
Managed CDC replication | Yes | Analytical destination | Replication health and schema coupling |
Lakehouse replication | Yes | Lakehouse/analytics engines | Storage, catalog, permissions, schema evolution |
Federation | Usually no full analytical copy | Across/against source systems | Query latency, pushdown, source dependency |
Virtualization/shortcuts | Often no new managed copy | Consuming platform with remote references | Availability and performance coupling |
Shared open-table access | Existing files remain in place | Multiple engines | Catalog, compatibility, authorization |
This distinction is especially important when discussing the AWS zero-ETL integration family.
AWS’s June 30, 2025 release for Amazon Aurora MySQL-Compatible Edition and Amazon RDS for MySQL to Amazon SageMaker is a managed replication architecture. AWS says it automatically extracts and loads MySQL table data into a SageMaker Lakehouse environment for near-real-time analytics and makes the synchronized data compatible with Apache Iceberg standards.
The detailed AWS Database Blog implementation shows what “zero” looks like in practice. RDS for MySQL needs binary logging configured with binlog_format=ROW and binlog_row_image=full; the SageMaker Lakehouse target uses an AWS Glue managed catalog backed by Amazon Redshift Managed Storage, with IAM and Lake Formation permissions required around the environment.
Once the integration becomes active, AWS captures database changes and continuously replicates them into the Glue-managed destination. Engineers can also apply data filters controlling which databases and tables participate.
In simplified form, the architecture looks like this:
Aurora/RDS MySQL → transaction/binlog changes → AWS-managed zero-ETL replication → Glue catalog/Redshift managed storage → SageMaker Lakehouse analytics engines
Notice what is missing: your custom extraction service, your hand-managed CDC connector, your load scheduler, and much of the glue code around incremental movement.
Now notice what is still present: source configuration, destination storage, catalogs, IAM, Lake Formation permissions, filtering, monitoring, analytics engines, downstream schemas, business transformations, quality controls, cost controls, and consumers.
That is zero-ETL.
It is not zero architecture.
AWS documentation also makes another point that should be printed on every zero-ETL design document: for Redshift zero-ETL integrations, source data is replicated as-is rather than being transformed during replication; transformations can be performed afterward in Redshift. In other words, for many workloads the pattern is conceptually close to a highly automated form of ELT: load first, transform in the analytical environment later.
The DynamoDB story illustrates another implementation.
On December 3, 2024, AWS News Blog author Donnie Prakoso announced DynamoDB zero-ETL integration with Amazon SageMaker Lakehouse. AWS said it enables analytics and machine-learning workloads without consuming DynamoDB table capacity, while SageMaker Lakehouse provides a unified analytics layer across S3 data lakes and Redshift data warehouses.
For DynamoDB-to-S3 lakehouse integration, AWS documentation describes Apache Iceberg as part of the target table architecture, while AWS’s broader SageMaker Lakehouse design uses the Glue Data Catalog to expose data to multiple engines.
That nuance matters because “SageMaker Lakehouse zero-ETL” should not be reduced to “everything is magically one Iceberg table.” Storage and catalog behavior varies by integration and target, even though Iceberg compatibility is an increasingly important interoperability layer.
The simplest technical definition I use with teams is this:
Zero-ETL replaces engineer-operated data movement with platform-native integration wherever the vendor can own both ends of the contract, or provide a virtual access path between them.
That definition explains both the benefit and the boundary.
The vendor can automate remarkably well when it understands the source log format, destination storage model, authentication model, catalog, metadata, and replication semantics. The further your architecture gets from that supported path, whether through multiple clouds, unusual transformations, regulated workflows, custom sources, or unstable schemas, the faster the “zero” starts accumulating engineering work around its edges.
This Isn't a 2026 Invention: The Maturation Phase
Zero-ETL did not arrive in 2026.
AWS publicly introduced its Aurora-to-Redshift zero-ETL direction at re:Invent in November 2022. The Aurora MySQL-to-Redshift integration later reached general availability on November 7, 2023, after its public preview in June 2023.
AWS widened the zero-ETL story during re:Invent 2023, announcing additional integration work around databases and analytics. DynamoDB-to-SageMaker Lakehouse followed in December 2024, and Aurora/RDS for MySQL-to-SageMaker became generally available on June 30, 2025.
Milestone | Date | Why it matters |
AWS announces Aurora/Redshift zero-ETL direction | November 2022 | Establishes that the idea predates the 2026 discussion |
Aurora MySQL → Redshift GA | November 7, 2023 | Moves the idea into a generally available production service |
Broader AWS zero-ETL announcements | November 2023 | Shows zero-ETL becoming a product family rather than one connector |
DynamoDB → SageMaker Lakehouse | December 3, 2024 | Extends the pattern into lakehouse analytics and ML |
Aurora/RDS MySQL → SageMaker GA | June 30, 2025 | Brings managed near-real-time MySQL replication into SageMaker Lakehouse |
Practitioner critique accelerates | January–April 2026 | Discussion shifts from capability to production trade-offs |
So what is genuinely new about zero-ETL architecture in 2026?
Experience.
By 2026, engineers have had enough time with production-grade implementations to ask better questions than “How quickly can I connect this source?”
The critique appearing across Khushbu Shah’s January 2026 essay, Mochammad Arie Nugroho’s February article, and Serena Monroe’s March analysis is strikingly consistent on the broad point: removing ingestion infrastructure does not remove engineering responsibility. Instead, the hard work tends to reappear around contracts, governance, downstream transformations, observability, costs, and platform boundaries.
Some of the most specific warnings actually predate 2026. Matillion’s Ian Funnell argued in June 2025 that zero-ETL and zero-copy approaches can introduce difficulties around complex-query performance, operational-source effects, schema drift, governance, lineage, and security. Matillion is itself a data-integration vendor, so its criticism should not be treated as neutral research, but those concerns provide useful categories against which to test vendor-native implementations.
This distinction between evidence and hype is important.
There is no reliable vendor-neutral Gartner or IDC zero-ETL-specific adoption percentage that I could verify for 2026. Gartner publishes material on the broader data-integration-tools market, but searches conducted for this article did not surface a dated Gartner or IDC figure measuring zero-ETL adoption itself.
That means claims such as “60% of companies now use zero-ETL” should be treated skeptically unless the methodology and population are clearly documented.
Product GA dates are evidence. Public technical documentation is evidence. Named practitioner reports are evidence.
An unattributed adoption percentage is not.
That is why 2026 is better described as zero-ETL’s maturation phase, not its invention year. The technology has crossed the point where saying “it works” is interesting; teams now need to understand how it fails, where it fits, and what controls have to surround it.
Where Zero-ETL Delivers on Its Promise
After all those caveats, I do not want to swing too far in the opposite direction.
Zero-ETL is useful.
Very useful, in the right topology.
AWS’s Aurora/RDS MySQL-to-SageMaker integration removes a meaningful amount of custom ingestion engineering. Once configured, source changes can be continuously replicated into the analytical environment without a team writing and operating its own CDC pipeline.
The DynamoDB integration has an even clearer benefit: AWS explicitly says analytical and ML workloads can use the synchronized lakehouse data without consuming DynamoDB table capacity. That is the kind of architectural separation I want when my production key-value store exists to serve customers, not analysts.
The strongest zero-ETL use cases usually share a few characteristics:
The source and target combination is directly supported by the platform vendor.
Data needs to become analytically available quickly, but not necessarily with transactional sub-second consistency.
Raw or lightly interpreted source data is useful before heavy business transformation.
Downstream compute can operate on a replica or managed analytical target rather than stressing the production database.
The organization is comfortable implementing transformation, contracts, observability, and governance outside the ingestion mechanism.
AWS also supports filtering which source databases and tables are replicated. That is not a trivial feature: filtering unnecessary operational tables reduces data exposure, target storage, and analytical clutter while giving platform teams a clearer boundary around what the integration is supposed to serve.
For a straightforward operational-analytics use case, compare the old path with the managed path.
Traditional path | Managed zero-ETL path |
Choose and configure CDC connector | Enable supported vendor integration |
Run connector infrastructure | Provider manages data movement |
Track offsets/checkpoints | Integration manages replication state |
Write destination loading logic | Managed target synchronization |
Maintain connector upgrades | Provider owns implementation lifecycle |
Build retry/recovery behavior | Integration provides managed status/recovery mechanisms |
Still manage transformations | Still manage transformations |
Still manage data quality | Still manage data quality |
Still manage governance | Still manage governance |
Those first five rows are not fake savings. I have seen teams spend enormous amounts of engineering time on exactly that plumbing.
Where I push back is when those savings are extrapolated into “the whole data platform just became simpler.”
The ingestion layer became simpler.
The system may or may not become simpler, depending on how much complexity moves into access policy, metadata, downstream SQL, schema contracts, and troubleshooting across vendor-managed boundaries.
Another benefit is organizational velocity. A supported integration can let an analytics or ML team begin working with fresh operational data without waiting for a data-platform team to design, deploy, and operationalize a bespoke ingestion service. AWS presents this reduced engineering effort as a central benefit of its zero-ETL integrations.
That matters.
But velocity is only an advantage if the team also knows who owns what happens on day 40, when an upstream developer drops a column that six models considered permanent.
That is where the zero-ETL limitations begin to matter more than the demo.
Where Zero-ETL Breaks: Governance, Performance, Schema Drift, and Source Load
The phrase “the first thing that breaks” is slightly unfair because modern zero-ETL products do include security and governance capabilities.
AWS’s June 2025 announcement, for example, explicitly highlights fine-grained access controls, and its implementation requires IAM, Glue Data Catalog configuration, and Lake Formation permissions around SageMaker Lakehouse data.
The problem is not “zero-ETL has no governance.”
The problem is that end-to-end governance stops being embodied in one inspectable pipeline.
A traditional pipeline can give you one logical execution boundary: source A was read, transformation version B ran, quality rule C passed, destination D received N rows. You may hate maintaining that system, but it can create an explicit place to put contracts, validations, lineage metadata, reconciliation logic, and audit records.
With zero-ETL, governance may be distributed across source-database privileges, IAM roles, a managed integration, Glue or another catalog, Lake Formation, warehouse permissions, transformation projects, semantic models, and BI access policies. AWS supplies controls for several pieces, but somebody still has to make the pieces represent one coherent policy.
Failure mode | What zero-ETL removed | What the engineer now has to control |
Fragmented governance | Central custom ingestion job | Cross-system access boundaries and catalog policy |
Lost business context | Transformation at ingestion | Data contracts and semantic definitions |
Schema drift | Pipeline schema checkpoint | Automated contract testing and consumer impact checks |
Query variability | Predictable staged dataset path | Workload placement, pushdown, compute and partitioning |
Source coupling | Decoupling extract layer | Source availability and performance guardrails |
Hard recovery | Explicit replay/backfill jobs | Integration-specific resync/recreation procedures |
Cost surprise | Visible pipeline compute | Replication, analytical compute, storage and remote-query cost |
Governance and lineage are harder because technical lineage and semantic lineage are not the same thing.
Knowing that orders.total_amount replicated from Aurora to a Glue catalog is useful. Knowing whether total_amount includes refunded transactions, which teams are allowed to use it for financial reporting, which transformation certifies it as recognized revenue, and what happens when the application team changes its type is a different problem.
Serena Monroe’s March 2026 critique calls this a governance blind spot: removing the separately executed pipeline can also remove an obvious integration-layer audit boundary. Her strongest compliance claims should be evaluated against the controls of the specific platform rather than generalized to every implementation, but her larger point is sound: managed replication does not automatically produce your organization’s required business lineage and governance model.
The query performance problem depends on which kind of zero-ETL you bought
This is one area where architecture discussions often become sloppy.
If your zero-ETL implementation replicates operational data into Redshift Managed Storage, an analytical join does not need to run against the production Aurora primary. AWS’s Aurora/RDS-to-SageMaker architecture is explicitly built around creating an analytical replica in the lakehouse target.
That does not mean query performance becomes automatic.
A complex join across large replicated tables still depends on analytical engine capacity, table layout, partition pruning, statistics, data distribution, concurrency, SQL quality, and workload management. The difference is that the performance problem has moved to the analytical platform rather than necessarily hammering the OLTP database.
Federation and virtualization are different.
Databricks’ own 2026 architectural guidance distinguishes query federation from physical data movement and explicitly notes that eliminating movement through federation can come at the cost of query performance. That is the trade-off I want teams to write down before calling a federated design “pipeline elimination.”
A local analytical copy gives the optimizer and platform more control over storage and execution. A remote table leaves part of performance dependent on network paths, source capabilities, pushdown behavior, remote concurrency, and the condition of another system.
Those are not implementation details.
They determine whether the architecture survives the first dashboard that goes from 30 users to 3,000.
Schema drift is where “zero maintenance” usually meets reality
AWS’s zero-ETL tooling can automatically propagate many source schema changes. That is an advantage over primitive CDC systems where every added column becomes an incident.
But automatic propagation and downstream compatibility are two completely different guarantees.
Suppose an application team adds a nullable column. Replication propagates it correctly. Nothing breaks.
Now suppose the team renames a field that a finance model expects, changes a numeric type, drops an identifier after migrating application logic, or changes an enum’s meaning without changing its physical type. The zero-ETL integration may faithfully deliver the new reality faster than your old nightly pipeline ever could.
Congratulations: your broken contract now propagates in near real time.
That is the central schema drift zero-ETL problem.
A transformation pipeline often provided an accidental but useful blast wall. Source changes hit explicit mappings, schema checks, compilation failures, or quality tests before reaching curated consumers. Remove that boundary and you must deliberately rebuild the useful safeguards somewhere else.
AWS documentation also shows that not all schema and table behavior is transparently survivable. Aurora zero-ETL integrations have documented unsupported objects, data types, and table behaviors, while AWS troubleshooting material describes conditions that can require resynchronization or otherwise move integrations or tables into problem states.
For some SageMaker Lakehouse zero-ETL failure scenarios, AWS documentation states that refresh/resync is not supported and the integration may need to be deleted and recreated.
That is production engineering.
A slide saying “no pipeline maintenance” does not make recovery procedures disappear.
AWS Glue zero-ETL documentation adds other concrete limits, including restrictions around table and field characteristics, schema size, and the number of columns supported in certain Iceberg targets. These are the exact details I want discovered during architecture review, not during an incident.
My minimum guardrail for a zero-ETL production system is therefore a data contract outside the replication mechanism.
For critical datasets, validate expected columns, types, nullability, keys, freshness, volume ranges, and business invariants. Run those validations even when the managed integration says ACTIVE, because “replication succeeded” and “the data product is still valid” answer different questions.
Databricks’ 2026 data-engineering guidance makes a similar case for explicit schema validation: detect upstream changes before they silently propagate into downstream dependencies.
Analytical load on operational systems is not a universal zero-ETL problem
Another recurring zero-ETL warning deserves qualification.
When a “zero-copy” or federated architecture queries source tables directly, analytics can become coupled to the availability and performance characteristics of the operational system. A badly designed federated workload can compete for resources or become unpredictable when the source is busy. Practitioner and vendor analyses have repeatedly raised that concern.
But do not copy that warning blindly onto every AWS zero-ETL design.
AWS specifically says DynamoDB-to-SageMaker analytics do not consume DynamoDB table capacity, and its June 2025 Aurora/RDS announcement describes maintaining a lakehouse replica for analytics rather than asking every analytical query to execute against the source database.
That gives us a better operational checklist:
Replication architecture: monitor replication lag, log/change-capture pressure, destination compute, target freshness, and resync behavior.
Federated architecture: monitor remote-query latency, pushdown, source CPU/I/O/connections, concurrency, network behavior, and timeout rates.
Either architecture: monitor schema contracts, data quality, access policy, cost, and downstream consumer failures.
Warning signs are equally pattern-specific.
If source CPU or connection utilization rises with BI traffic, remote-query latency suddenly tracks production peaks, or analytical timeouts disappear when source traffic falls, investigate federation/source coupling. If the source looks healthy but dashboard freshness degrades while integration lag rises, investigate replication health instead.
That is the kind of distinction senior engineers are paid to make.
“Zero-ETL” is a product category.
Incidents happen to actual architectures.
How Microsoft Fabric's Approach Compares
Microsoft Fabric complicates the terminology further because 2026 industry coverage uses “zero-ETL” for a more virtualization-oriented model.
In a March 2, 2026 buyer’s guide, InfoWorld reported that Fabric could virtualize data from Snowflake, Databricks, and Amazon S3 so that users could see and query external tables without physically moving the underlying data.
I am deliberately assigning medium confidence to that exact cross-platform “zero-ETL” product characterization.
I found supporting evidence for parts of the interoperability model, including Snowflake documentation published around January 2026 describing interoperability between Snowflake-managed Iceberg data and Microsoft Fabric. Industry technical coverage also describes OneLake shortcuts as logical references that allow Fabric workloads to reach external storage rather than duplicating every dataset.
However, I did not independently verify a primary Microsoft announcement that matched InfoWorld’s exact 2026 wording, “zero-ETL” virtualization across Snowflake, Databricks, and S3, as a single newly announced capability.
Dimension | AWS Aurora/RDS → SageMaker example | Fabric approach reported by InfoWorld |
Core pattern | Managed CDC-style replication | Virtualized/logical access |
New analytical copy | Yes, synchronized lakehouse representation | Potentially no physical move for referenced data |
Source transaction changes | Captured and replicated | Data may remain external |
Query dependency | Primarily analytical target | Potentially remote/external data path |
Source-load concern | Reduced by analytical replica architecture | More relevant where execution depends on remote source |
Main operational issue | Replication lag, schema compatibility, target governance | Remote performance, authorization and availability coupling |
Confidence | High: AWS primary documentation | Medium for exact 2026 “zero-ETL” label: industry report, partial primary corroboration |
This is why I resist architecture meetings where someone says, “Vendor A has zero-ETL, Vendor B has zero-ETL, so these are equivalent.”
They are not.
One vendor may mean “we copy changes for you.”
Another may mean “we let you query the data without copying it.”
Those two decisions have opposite implications for duplication, source isolation, failure domains, and query performance.
There is also a storage-format layer underneath some of these interoperability stories. Apache Iceberg increasingly makes it possible for multiple engines and catalogs to work around open analytical tables without every engine owning a proprietary copy. Refonte Learning covers that separate topic in the Apache Iceberg table format wars in 2026.
Do not conflate the layers.
Iceberg is a table format and interoperability mechanism. Zero-ETL is a data-access/integration pattern. Orchestration coordinates executable workflows. A modern data architecture may use all three.
For platform architects, the better comparison is therefore not “Who has zero-ETL?”
Ask:
Where does the data physically live? Who owns the catalog? Where does compute execute? What happens when the source disappears? Where are permissions evaluated? What is replicated versus referenced? What mechanism catches incompatible schema changes?
Those answers tell you more about production behavior than the product label ever will.
From Pipeline Builder to Platform Architect: The Real Job Shift
I do not see zero-ETL eliminating the data engineer.
I see it eliminating some of the least differentiated work data engineers used to spend too much time doing.
Writing yet another incremental extractor is rarely the highest-value thing a senior engineer can contribute to a company. Neither is maintaining 40 variations of “copy this database table over there every five minutes.”
When cloud platforms make that work reliable and boring, let them.
The mistake is assuming that those extraction jobs were the reason the company needed data engineering.
Pipeline-builder-heavy role | Platform-architect-heavy role |
Build source connectors | Select integration patterns and boundaries |
Schedule ingestion | Define freshness objectives |
Retry failed loads | Engineer recovery and failure-domain strategy |
Map source fields | Define and enforce data contracts |
Maintain connector infrastructure | Govern managed integrations |
Optimize individual jobs | Optimize end-to-end workload placement |
Own warehouse loads | Own source-to-consumer reliability |
Encode access inside pipelines | Design cross-platform access controls |
Fix schema failures | Prevent schema changes from breaking consumers |
Monitor job success | Monitor platform health and data correctness |
This data platform architect vs pipeline builder shift is the most consequential part of the zero-ETL story.
Khushbu Shah’s January 2026 framing explicitly points toward platform design; Mochammad Arie Nugroho’s February piece similarly argues that engineers spend less time on ingestion and more on data contracts, governance, quality, semantics, and cost.
In my view, five responsibilities become more valuable.
First, data contracts. Somebody must define what downstream systems are entitled to assume about names, types, keys, nullability, semantics, freshness, and change policy.
Second, governance architecture. Managed integration means permissions and lineage span more systems, not fewer conceptual responsibilities. Engineers need to understand identity, encryption, catalogs, row/column controls, retention, classification, and compliance boundaries.
Third, observability. “Integration active” is not enough. Platform teams need freshness SLOs, replication-lag monitoring, schema-change alerts, volume anomaly detection, quality tests, consumer-level checks, and recovery playbooks.
Fourth, workload architecture. Engineers must know when to replicate, when to federate, when to cache, when to materialize, and when a workload still deserves an explicit pipeline.
Fifth, cost engineering. Removing a pipeline bill does not make the workload free; it changes where spending occurs. Replication, storage, analytical compute, remote querying, retained historical data, and concurrency all require guardrails.
That creates a practical decision framework for when zero-ETL is the right call and when it is not.
Requirement | Zero-ETL fit |
Supported same-platform source and analytical target | Strong |
Near-real-time operational analytics | Strong |
Stable source schema | Strong |
Minimal pre-load transformation | Strong |
Analytical replica isolates OLTP | Strong |
Cross-cloud movement | Usually weak; explicit integration remains necessary |
Complex transformation before exposure | Weak |
Frequent breaking schema changes | Requires substantial contract controls |
Strict custom audit workflow | Requires careful design/compensating controls |
Need deterministic replay/backfills | Verify product recovery semantics first |
Unsupported source/target | Traditional ETL/ELT still required |
Federated queries against latency-sensitive production source | Evaluate very carefully |
Notice what I am not recommending: “replace every pipeline with zero-ETL.”
A good data platform will be hybrid.
Use provider-managed replication where it removes undifferentiated plumbing without weakening your guarantees. Keep explicit pipelines where transformation, portability, complex quality controls, cross-cloud movement, replayability, or regulatory evidence make the pipeline itself useful.
That means the skills list for 2026 changes, but it does not collapse.
SQL remains fundamental because transformations and analytical debugging do not disappear. Python remains useful for automation, tests, integrations, metadata tooling, and everything outside supported zero-ETL paths.
Distributed processing still matters when datasets and transformations justify Spark-class systems. Data modeling arguably matters more because making raw operational tables available quickly is not the same thing as creating trustworthy analytical products.
Cloud architecture becomes increasingly important. A data engineer working with the AWS zero-ETL stack may need to understand RDS/Aurora configuration, transaction logs, Glue, Redshift storage, SageMaker Lakehouse, IAM, Lake Formation, KMS, Iceberg compatibility, monitoring, and failure recovery even though they wrote less ingestion code.
For engineers planning that broader foundation, Refonte Learning’s data engineering roadmap to a $120K salary covers the more general progression across SQL, Python, distributed data processing, pipelines, and cloud-oriented engineering. That roadmap and this zero-ETL discussion serve different purposes: one builds the career foundation; this article explains how one particular architecture trend changes where that foundation gets applied.
What does the data engineer salary picture look like in 2026?
Salary data needs the same skepticism as architecture marketing.
A 2026 Glassdoor snapshot cited a broad range of $84,740–$215,566, roughly $108,702 in average base compensation, and approximately $134,196 when bonus or extra compensation was included. Those exact figures could not be independently reproduced on Glassdoor’s live U.S. Data Engineer page on August 18, 2026, so they should be treated as a dated snapshot rather than current live data.
Glassdoor’s live U.S. page on August 18, 2026 instead reported approximately $134,238 in total annual pay for a U.S. Data Engineer. Salary aggregators update dynamically, which likely explains at least part of the discrepancy; the older snapshot should not be presented as the current live figure.
ZipRecruiter is directionally close. Its live U.S. page on August 17, 2026 reported an average of $129,716 per year, with the middle 50% spanning $114,500 to $137,500.
Source | 2026 figure | Context |
Glassdoor, dated 2026 snapshot | $84,740–$215,566; ~$108,702 base; ~$134,196 incl. bonus | Not reproducible on the live page on Aug. 18 |
Glassdoor live U.S. page | ~$134,238 total annual pay | Live result on Aug. 18 |
ZipRecruiter, Aug. 17, 2026 | $129,716 average | Live result |
ZipRecruiter middle 50% | $114,500–$137,500 | 25th–75th percentile |
The useful takeaway is not that every data engineer should expect $130,000. Geography, seniority, specialization, employer, and methodology matter enormously.
What the two current aggregators do suggest is that their central U.S. figures are reasonably close rather than wildly contradictory: Glassdoor’s current total-pay estimate is in the mid-$130,000s, while ZipRecruiter’s average is just under $130,000.
More interesting for career planning is what earns leverage.
The engineer who knows how to write a connector is useful.
The engineer who can determine whether that connector should exist at all, replace it safely with a managed integration, design the contract around the new system, establish access boundaries, quantify its failure modes, prevent source impact, and explain the trade-off to security and finance is much harder to replace.
That is the data engineer role change 2026 worth preparing for.
Building This Expertise: The Refonte Learning Data Engineering Program
The worst way to prepare for zero-ETL is to learn only zero-ETL.
Tools change too quickly.
The durable skill is understanding why pipelines exist in the first place: ingestion, transformation, durability, isolation, quality, governance, security, reproducibility, and analytical serving. Once you understand those responsibilities, you can intelligently decide which ones a managed service has truly absorbed and which ones still belong to your platform team.
Refonte Learning’s live Data Engineering Program page describes a curriculum that begins with an introduction to data engineering, moves through data warehousing and ETL, and then covers big-data technologies and data-pipeline design using technologies including Hadoop and Spark.
The page also lists competencies in real-time data processing, data pipelining, big-data analytics, visualization, storage provisioning, encryption, and data governance and compliance controls.
Program detail | Verified information as of August 18, 2026 |
Format | 3 months |
Weekly commitment | 12–14 hours |
Core curriculum | Introduction to Data Engineering; Data Warehousing and ETL Processes; Big Data Technologies and Data Pipeline Design |
Named technologies | Hadoop and Spark |
Relevant platform skills | Real-time processing, pipelines, storage, encryption, governance and compliance |
Mentor | PhD Matthias Schmidt |
Mentor experience | 16 years; senior data engineer with banking/finance, big-data, regression and quantitative-risk background |
Prerequisite | Working toward a bachelor’s degree or higher |
One-time fee | $300 |
Installments | $204 + $98 |
Listed price/discount | $387 list price; page displays 30% off |
Program marketing claims | $100K+ starting career figure; roughly 94K annual jobs; “Low–High” competition indicator |
These details come directly from the program page. Matthias Schmidt is described there as a senior data engineer with a 16-year computer-science background and expertise spanning banking and financial services, big-data solutions, regression analysis, financial econometrics, and quantitative risk forecasting.
The fee page currently shows $300 as the one-time enrollment cost, with installment payments of $204 and $98. The site’s Data Engineering listing displays a $387 comparison price and 30% discount.
The career numbers require a different level of confidence.
Refonte’s own listing advertises a $100,000+ starting salary, approximately 94,000 annual job opportunities, and a “Low–High” market-competition indicator. Those are Refonte Learning’s marketing claims and were not independently verified for this article, so they should not be confused with the Glassdoor or ZipRecruiter salary data discussed above.
There is another limitation worth stating plainly: the published curriculum does not currently name zero-ETL, AWS zero-ETL integrations, or SageMaker Lakehouse as specific subjects. The curriculum names general ETL/data warehousing, Hadoop, Spark, pipelines, real-time processing, security, and governance.
That does not make the program irrelevant to this shift.
Quite the opposite: its governance and compliance component maps directly to the part of the job that becomes more important when ingestion is abstracted away. Its pipeline-design curriculum provides the conceptual baseline you need before you can sensibly decide when not to build a pipeline.
That is the skill I would optimize for.
Do not become the engineer whose only value is remembering how to configure yesterday’s connector.
Become the engineer who can walk into an architecture review and ask:
What guarantee did the old pipeline provide that this managed integration does not?
What does schema evolution do to downstream contracts?
Are we replicating data or querying it remotely?
·Where does analytical compute actually execute?
How do we detect correct replication of incorrect data?
What is our backfill and recovery strategy?
Where are lineage and access decisions recorded?
Which workloads should deliberately not use zero-ETL?
Those questions survive product cycles.
Zero-ETL has already moved from a 2022 announcement to multiple production integrations. AWS’s June 2025 Aurora/RDS-to-SageMaker GA milestone shows the architecture is no longer an experiment, while the practitioner writing that followed into 2026 shows that production teams are beginning to distinguish genuine automation from magical thinking.
The job is not disappearing.
The lowest-value part of the job is being automated.
For data engineers who understand systems rather than just pipeline syntax, that is good news. There is less reason to spend a career rebuilding data movement that cloud providers can operate better at scale, and more reason to become the person who knows how data should be governed, contracted, observed, secured, modeled, and served once the pipeline is no longer standing in the middle.
That is what zero-ETL data engineering looks like after the hype phase.
Zero pipelines was never the real destination.
Better architecture was.
For learners building that foundation, the Refonte Learning Data Engineering Program’s verified emphasis on pipeline design, real-time processing, storage, security, and data governance provides a relevant starting point for the broader platform-engineering responsibilities zero-ETL is pushing to the foreground, even though the published curriculum does not yet teach zero-ETL tooling by name.