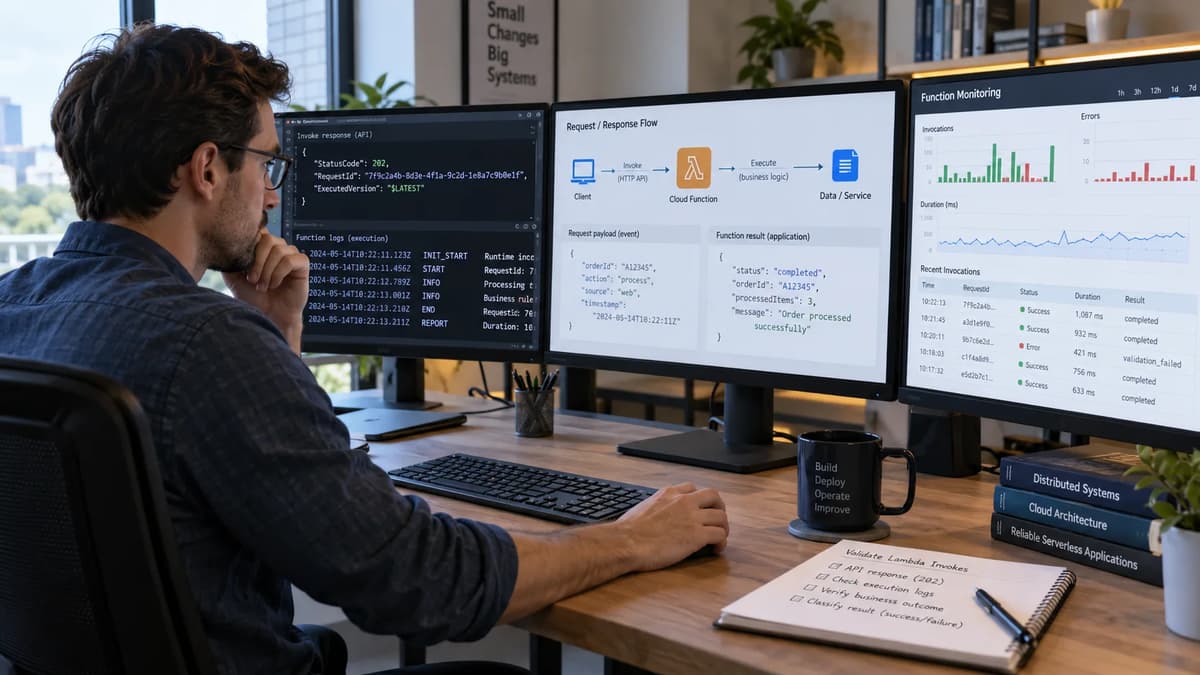
A synchronous Lambda invocation returning HTTP 200 can be misleading. AWS’s API only signals that the invoke call succeeded, not that your function succeeded. The real function error (if any) is reported separately via the X-Amz-Function-Error header and response payload. In other words, a 200 status code tells you that AWS ran your function, but it does not guarantee that the function’s code or business logic completed successfully. For example, AWS documentation notes: “If Lambda was able to run the function, the status code is 200, even if the function returned an error.”
To avoid blind acceptance of false success, we adopt a strict validation procedure. We require three distinct layers of success before ACCEPTED:
Invocation-layer success: The AWS CLI exited 0 with InvocationType=RequestResponse, yielding HTTP status 200 in the metadata.
Function-layer success: No unhandled error occurred. In AWS’s response metadata, there must be no FunctionError field, and the ExecutedVersion header must match the intended published version.
Application-layer success: The returned payload must parse as JSON, match our expected schema, and indicate an ok: true business result. In our fixture, we require the returned receipt to be an object with an explicit boolean ok, the exact request_id we sent, and the expected data value. Any deviation (missing fields, wrong types, a non-200 field in payload, etc.) is classified as a failure mode.
In cloud development, we recognize that only when all three layers agree should a caller accept the result. Similar to broader cloud application operating practices, we never conflate an API 200 with business success. We also fix the request parameters (published version and request ID) in advance, so only a response matching those can be accepted. If any check fails, the caller cannot safely assume success. Instead we REPAIR the caller or HOLD/RECONCILE pending further investigation.
Define what success means at each response layer
We break validation into three separate assertions: first, the API exchange completed normally; second, the function execution succeeded (no crash); third, the function’s returned business receipt is correct. For example, the AWS CLI invoke command will print metadata like:
{"ExecutedVersion": "$LATEST", "StatusCode": 200}The command also writes the function’s JSON output to a file (here response.json). By AWS design, StatusCode: 200 merely means “Lambda ran the function”. We explicitly check that StatusCode is 200 and the invocation type was RequestResponse; Event and DryRun invocations (202 and 204 respectively) trigger NOT_EXECUTION_PROOF. A different status for RequestResponse triggers UNEXPECTED_STATUS. Then we check the function execution: if the metadata includes "FunctionError", AWS documentation says “if present, indicates that an error occurred during function execution”. Our classifier catches this and returns FUNCTION_ERROR. We also verify that the ExecutedVersion in metadata equals the version we intended to invoke. A mismatch means the wrong code ran (classification WRONG_EXECUTED_VERSION) and we hold.
Finally we parse the payload. The payload must be a JSON object matching our schema: a boolean "ok", the exact "request_id", and the expected value. If parsing fails or the structure is wrong, we classify INVALID_PAYLOAD. If ok is false, we classify APPLICATION_REJECTED (the function completed normally but business logic declined). If all checks pass, we return ACCEPTED. This strict policy prevents an invalid result from slipping through.
In summary: ACCEPTED means all layers passed. Any deviation (transport error, wrong status, function error, schema issue, wrong version/ID, etc.) leads to repair/handoff rather than silently accepting success. This fail-closed approach follows robust cloud-development guidance: validate every layer of the response, not just the network call.
Pin the local classifier and the separate AWS run
We developed a Python harness (lambda_classifier_lab.py) to formalize these checks and to distinguish between synthetic unit tests and a real AWS invocation. The classify() function takes four inputs (CLI return code, invocation type string, metadata bytes, payload bytes) plus the expected request ID and version, and returns one of the above status codes. The code performs the layered checks exactly as described. Below is the core of the classifier logic:
import json

def classify(
    returncode: int, invocation_type: str, metadata: bytes, payload: bytes,
    expected_id: str, expected_version: str,
) -> str:
    # Check CLI invocation
    if returncode != 0:
        return 'TRANSPORT_OR_API_ERROR'
    if invocation_type != 'RequestResponse':
        return 'NOT_EXECUTION_PROOF'
    # Parse metadata JSON
    try:
        meta = json.loads(metadata)
    except (ValueError, UnicodeDecodeError):
        return 'INVALID_METADATA'
    # Validate metadata contents
    if not isinstance(meta, dict) or type(meta.get('StatusCode')) is not int:
        return 'INVALID_METADATA'
    if meta['StatusCode'] != 200:
        return 'UNEXPECTED_STATUS'
    if 'FunctionError' in meta:
        # A present, nonempty string indicates a function error.
        return (
            'FUNCTION_ERROR'
            if isinstance(meta['FunctionError'], str) and meta['FunctionError']
            else 'INVALID_METADATA'
        )
    if meta.get('ExecutedVersion') != expected_version:
        return 'WRONG_EXECUTED_VERSION'
    # Parse payload JSON
    try:
        receipt = json.loads(payload)
    except (ValueError, UnicodeDecodeError):
        return 'INVALID_PAYLOAD'
    # Validate application receipt
    if not isinstance(receipt, dict) or type(receipt.get('ok')) is not bool:
        return 'INVALID_PAYLOAD'
    if receipt.get('request_id') != expected_id:
        return 'WRONG_RECEIPT_ID'
    if receipt['ok'] is False:
        return 'APPLICATION_REJECTED'
    if receipt.get('value') != 7 or type(receipt.get('value')) is not int:
        return 'WRONG_RECEIPT_VALUE'
    return 'ACCEPTED'
The Lambda handler belongs in the same file for the integration fixture. The handler inspects event['mode'] (one of "ok", "raise", "reject") and either returns the expected receipt or throws an error. This allows deterministic synthetic tests.
Because this harness is local-only, it prints a JSON line per test case. In the reported local test run (Python 3.13.5 on Linux), all 13 synthetic cases passed, and the summary line shows "aws_invocations": 0 indicating no real AWS calls were made. This separates the unit test (classification logic) from any live Lambda. The following pseudocode outlines all 13 synthetic cases. Ellipses represent omitted fixture fields, so this outline is not an executable test harness:
cases = [
    ('ok', 0, 'RequestResponse', {...}, {...}, 'ACCEPTED'),
    ('raised', 0, 'RequestResponse', {..., 'FunctionError': 'Unhandled'}, {...},
        'FUNCTION_ERROR'),
    ('caught', 0, 'RequestResponse', {...}, {..., 'ok': False},
        'APPLICATION_REJECTED'),
    ('bad_json', 0, 'RequestResponse', {...}, b'{', 'INVALID_PAYLOAD'),
    ('wrong_id', 0, 'RequestResponse', {...}, {..., 'request_id': 'q2'},
        'WRONG_RECEIPT_ID'),
    ('api_error', 254, 'RequestResponse', b'', b'', 'TRANSPORT_OR_API_ERROR'),
    ('event', 0, 'Event', {'StatusCode': 202}, b'', 'NOT_EXECUTION_PROOF'),
    ('dry_run', 0, 'DryRun', {'StatusCode': 204}, b'', 'NOT_EXECUTION_PROOF'),
    ('wrong_version', 0, 'RequestResponse', {..., 'ExecutedVersion': '8'}, {...},
        'WRONG_EXECUTED_VERSION'),
    ('payload_http_code', 0, 'RequestResponse', {...}, {'statusCode': 500,
        'body': 'failed'}, 'INVALID_PAYLOAD'),
    ('truthy_not_bool', 0, 'RequestResponse', {...}, {'ok': 'true', ...},
        'INVALID_PAYLOAD'),
    ('missing_version', 0, 'RequestResponse', {'StatusCode': 200}, {...},
        'WRONG_EXECUTED_VERSION'),
    ('null_error_field', 0, 'RequestResponse', {..., 'FunctionError': None},
        {...}, 'INVALID_METADATA'),
]
Each synthetic envelope labels its classification (e.g. ACCEPTED, FUNCTION_ERROR, etc.) with source synthetic-local-fixture. We will discuss each below. Importantly, nothing above contacts AWS; it just validates our logic.
A unit test is not an AWS integration test
The Python harness ensures our classifier logic is correct, but it does not invoke AWS. All results are artificial, coming from JSON we constructed in code. We do not run the AWS CLI in this phase. In the summary output, you’ll see "aws_invocations": 0, indicating zero live calls. This makes clear the distinction: we first validate the decision logic locally. The separate integration procedure below uses actual AWS invocations (in an owned non-production account) to test real behavior. Until that point, we label expected AWS outcomes but do not claim actual observations.
Capture metadata and payload without conflating them
A common mistake in wrappers is to merge or ignore parts of the Lambda response. The AWS CLI invoke command actually produces four artifacts: its stdout JSON (the metadata), the payload file (the function’s output), any stderr text, and the CLI’s exit code. By default, --output json writes the metadata (status code, version, etc.) to stdout, while the payload is written to a file (payload.json in our script). For example, invoking a successful function might print:
{"ExecutedVersion":"$LATEST","StatusCode":200}The command also saves the function’s JSON result in payload.json. A shell script must capture all these: stdout (metadata), stderr, exit code, and the payload file.
One pitfall: a zero exit code and StatusCode 200 alone are not enough evidence of success. AWS explicitly states that “if Lambda was able to run the function, the status code is 200, even if the function returned an error”. In practice, this means the CLI exit code is 0 and prints StatusCode: 200 on stdout, but there could still be a FunctionError. If a script only checks the exit code or ignores the FunctionError field, it will erroneously treat a crash as success. We avoid that by always reading the metadata JSON for FunctionError.
The shell command captures the output streams separately:
aws lambda invoke \
  --function-name "$FUNCTION_ARN" --qualifier "$FUNCTION_VERSION" \
  --invocation-type RequestResponse \
  --cli-binary-format raw-in-base64-out \
  --payload "file://$bundle/request.json" \
  --output json --no-cli-pager "$bundle/payload.json" \
  > "$bundle/metadata.json" 2> "$bundle/stderr.txt"
This explicitly sends metadata to metadata.json and payload to payload.json. We also record $? in cli-status.txt. These four pieces are kept distinct. For example, if a function throws an exception, the CLI still exits 0, metadata.json contains "FunctionError":"Unhandled", and payload.json contains an error object. A naive check of exit status would miss that.
We illustrate the separation with the synchronous invocation example from AWS docs: it shows metadata on stdout, and implies a separate file for the actual response. Our script captures these exactly. Any function error or unexpected payload is then detected by our classifier rather than by the shell’s exit code.
Reproduce HTTP 200 with a function execution error
Next we simulate a real function exception and confirm our classifier catches it. In the synthetic test ('raised', ...), we added a FunctionError field in metadata and an error payload. The classifier returned FUNCTION_ERROR, as expected.
In the documented behavior, the AWS CLI invocation for the “raise” case would also yield HTTP 200. For example, if lambda_classifier_lab.handler raises a RuntimeError, AWS sets:
StatusCode: 200 in the invoke response (since the function did run).
An X-Amz-Function-Error: Unhandled header, which our CLI would include as "FunctionError":"Unhandled" in metadata.
The payload file containing JSON with {"errorMessage":"deliberate fixture error",...}.
We treat this as a function failure. Our classifier logic is clear: as soon as we see a nonempty string in FunctionError, we return FUNCTION_ERROR. We do not accept an empty string or null; if FunctionError is present but not a nonempty string, it’s classified as INVALID_METADATA (see the synthetic null_error_field case).
This behavior contrasts with SQS batch retry patterns (see Refonte’s SQS per-record failure recovery). In a batch, you might retry individual records. Here, a single Invoke call has one response to classify; a function error means the request must be handled as a whole. This does not establish that its side effects were atomic. Importantly, AWS promises no automatic retry for this case, so our invocation is the final verdict unless we choose to retry manually.
Do not let the CLI exit status erase FunctionError
It’s tempting to write a shell wrapper that checks if [ $? -eq 0 ], then proceeds to parse output. But that pattern is dangerous here. Even after an exception, aws lambda invoke exits 0. The key check is in metadata:
# Example pseudocode after aws invoke:
if [ "$EXIT_CODE" -ne 0 ]; then
  echo "Network, CLI, or API error."
elif grep -q FunctionError metadata.json; then
  echo "Lambda function error!"
fi
If we did not look at metadata.json, we would miss the exception. AWS documentation confirms: StatusCode:200 simply means "invoke succeeded". The actual function error is only visible in the headers/payload. In our classifier, we explicitly check whether 'FunctionError' is present in meta and do not treat a missing error field as success. In short, always read the FunctionError field before deciding.
Treat a caught business rejection as an application result
In some cases, the Lambda function might handle an input but respond with a domain-specific error, e.g. {'ok': False, 'reason': '...'}. This is a business rejection, not a crash. In AWS terms, the invoke call still succeeded normally, with no FunctionError header. The payload is a valid JSON we expect, but with ok: false. Our classifier returns APPLICATION_REJECTED in that scenario.
This is not a trigger to retry the function. We have seen (caught case) that a synchronous return with ok=false yields StatusCode:200, no FunctionError, and payload {"ok":false,...}. We accept it as a valid function response, but a failed application result. This might map to domain logic (e.g. request was invalid, or business rule failed). The caller’s action here depends on policy: perhaps log and stop, but do not automatically retry. We consider it ACCEPTABLE in terms of the API contract, albeit unsuccessful business-wise.
We also watch out for misinterpretations: for example, an API Gateway proxy might produce JSON like {"statusCode": 500, "body": "..."} inside the payload. Our classifier treats any payload that does not follow our schema as INVALID_PAYLOAD. Specifically, a top-level statusCode does not substitute for the required receipt fields, and the string "true" does not substitute for a boolean. For instance, in the synthetic payload_http_code case, the payload is flagged INVALID_PAYLOAD because it lacks a valid ok field. Similarly, a truthy string is invalid. We require a boolean, True or False in Python terms.
In summary, a normal function return (even ok=false) is a business outcome (APPLICATION_REJECTED), not a function error. We validate the receipt structure strictly. If it matches and ok is false, we record it as an application-level rejection; otherwise schema errors are INVALID_PAYLOAD.
Make the caller classifier fail closed
Our validation order ensures that the first anomaly encountered determines the classification. This makes the caller conservative. The allowed result is very specific: a dictionary with ok: True, the correct request_id, and expected data. Any deviation yields a non-ACCEPTED result. In practice this means:
Type strictness: We do not coerce or trust incidental fields. A missing ExecutedVersion is WRONG_EXECUTED_VERSION. A string "true" instead of boolean true for ok is INVALID_PAYLOAD. A None FunctionError is INVALID_METADATA.
Exact matching: The request_id and data value must exactly match what we sent/expected. Mismatches become WRONG_RECEIPT_ID or WRONG_RECEIPT_VALUE.
Error precedence: We only check the payload if the metadata was perfectly valid (StatusCode=200, no FunctionError, correct version). Errors in metadata short-circuit before inspecting payload. For example, a function error yields FUNCTION_ERROR even if the returned payload also had a bad schema.
By failing on the first mismatch, we produce a clear diagnostic. We also preserve the raw JSON metadata and payload (in files) alongside the classification. This allows an operator to audit exactly what was returned. We do not “fixup” missing data; if evidence is missing, the result is HOLD.
Absence of an error field is not a valid application receipt
A common mistake would be to assume “no news is good news.” If neither FunctionError nor ok:false is present, we still require the explicit ok:true to accept. In other words, the absence of an error indicator does not imply success. For example, a payload with {'value':7,'request_id':'q1'} missing ok entirely fails schema validation (INVALID_PAYLOAD). Likewise, incidental HTTP-like fields in payload (statusCode, body, etc.) do not count. We demand the declared fields. This avoids accepting malformed or partial data as a success.
Keep Event and DryRun out of synchronous acceptance
Lambda’s invoke supports InvocationType=Event (async) and DryRun, which we must handle specially. For an async Event call, the API response is just a 202 and that response does not establish a function execution result. The response looks like: StatusCode:202 with no payload. A DryRun returns 204. Both invocation types are documented: 202 means the event is queued, 204 just validated permissions. In our classifier, if invocation_type is not RequestResponse, we immediately return NOT_EXECUTION_PROOF. Synthetic tests confirm this: ('event', ..., 'StatusCode':202) classifies as NOT_EXECUTION_PROOF, as does ('dry_run', 'StatusCode':204).
We do not accept these as successes because they provide no execution proof. They belong to other workflows (queue processing or permission checks). If one of these appears, the caller should hold or ignore it as inappropriate for this context. This keeps us focused: only a true RequestResponse invoke enters this synchronous acceptance workflow.
Bind the invocation to the intended code version
To prevent confusion, we require that the invocation use an explicit published version qualifier. In our AWS test, we package lambda_classifier_lab.py into a zip and deploy it to the owned non-production function, then publish-version. For example:
zip lambda_classifier_lab.zip lambda_classifier_lab.py
aws lambda update-function-code --function-name "$FUNCTION_ARN" \
  --zip-file fileb://lambda_classifier_lab.zip
aws lambda publish-version --function-name "$FUNCTION_ARN"
We note the resulting version number (FUNCTION_VERSION) and the code SHA256 from aws lambda get-function-configuration. This locks down exactly what code will run.
When invoking, we use --qualifier "$FUNCTION_VERSION" to ensure we call that fixed version. We then capture its ExecutedVersion in metadata. It should match FUNCTION_VERSION. An alias or $LATEST could point to different code; for that reason, an alias is not sufficient evidence by itself. (We explicitly avoid that here.) SnapStart uses snapshots of versions, but our focus is not on that lifecycle. As with the SnapStart reinitialization example, we want to see the real function output from our version, unambiguous.
If, for some reason, the ExecutedVersion header does not match our expected version, we classify WRONG_EXECUTED_VERSION. For example, if we invoked an alias or the configured qualifier changed, this indicates a deployment mismatch. In that case the caller should hold and not accept the result. The caller can then verify function identity (e.g. via code hash) before retrying on the correct version. This ensures that we never accept output from unintended code.
An alias name is not the executed version
Invoking by alias can be tricky: even if you pass --qualifier myAlias, AWS resolves it to a numeric version before execution, and that numeric version is what ExecutedVersion returns. We explicitly do not use an alias in this lab; we call the numeric version directly. If you did use an alias, you must still check that ExecutedVersion matches the version you intended. An alias by itself is just a name, not immutable evidence of code. By using the published numeric version, we remove this ambiguity.
Run the complete synthetic response matrix
Let us review all 13 synthetic cases and their classifier outcomes. Each case is listed as case: classification. (Source "synthetic-local-fixture" indicates the test harness.)
ok: ACCEPTED (normal path). Metadata StatusCode:200, no FunctionError, correct version, payload ok:true leads to ACCEPT.
raised: FUNCTION_ERROR. Metadata had FunctionError:'Unhandled'; we report function failure.
caught: APPLICATION_REJECTED. Function returned ok:false; metadata had no FunctionError, so we treat it as a valid but rejected receipt.
bad_json: INVALID_PAYLOAD. Payload was { (malformed JSON); metadata was okay but payload parse fails.
wrong_id: WRONG_RECEIPT_ID. Payload had the wrong request_id; schema was fine otherwise.
api_error: TRANSPORT_OR_API_ERROR. The CLI returned code 254 (nonzero), simulating a network/API failure. We classify as transport error.
event: NOT_EXECUTION_PROOF. InvocationType=Event with StatusCode 202; the response provides no synchronous execution result.
dry_run: NOT_EXECUTION_PROOF. InvocationType=DryRun with StatusCode 204; only a permission check, not an invocation.
wrong_version: WRONG_EXECUTED_VERSION. Metadata had ExecutedVersion:'8' versus expected '7'.
payload_http_code: INVALID_PAYLOAD. Payload had HTTP-like keys (statusCode:500) not our schema; metadata was fine.
truthy_not_bool: INVALID_PAYLOAD. Payload had "ok":"true" (string) instead of a boolean; fails schema.
missing_version: WRONG_EXECUTED_VERSION. Metadata missing ExecutedVersion entirely; we cannot verify version.
null_error_field: INVALID_METADATA. Metadata had FunctionError: null; since we expect a string or absence, this is treated as invalid.
These synthetic results confirm that exactly one case (ok) reaches ACCEPTED. All other cases fall into a failure classification. This detailed matrix would be a single green check if all outcomes match expectations. It shows how our classifier handles the scenarios covered by this bounded synchronous Invoke matrix.
Perform the owned AWS integration check separately
Finally, we describe how to verify this logic with a real AWS Lambda invocation. We assume an already owned non-production account and function. We do not execute these steps here, but they are the documented procedure. The function must have handler = lambda_classifier_lab.handler, use the code we packaged, and be published to version $FUNCTION_VERSION. Its role should only have basic Lambda execution rights.
Deployment steps (to be done once):
zip lambda_classifier_lab.zip lambda_classifier_lab.py
aws lambda update-function-code --function-name "$FUNCTION_ARN" \
    --zip-file fileb://lambda_classifier_lab.zip
aws lambda publish-version --function-name "$FUNCTION_ARN"
After publishing, note the function’s configuration (especially CodeSha256 and the published version number). This captures the exact code. The AWS CLI version used (e.g. aws --version) should also be recorded in the evidence bundle.
Invoking the function: For each mode (ok, raise, reject), we create a new temporary bundle directory (to avoid reusing stale files). For example, for mode "ok":
mkdir bundle_ok && {
  printf '%s\n' '{"mode":"ok","request_id":"q1"}' > bundle_ok/request.json
  if aws lambda invoke \
    --function-name "$FUNCTION_ARN" --qualifier "$FUNCTION_VERSION" \
    --invocation-type RequestResponse \
    --payload fileb://bundle_ok/request.json \
    --cli-binary-format raw-in-base64-out --output json --no-cli-pager \
    bundle_ok/payload.json \
    > bundle_ok/metadata.json 2> bundle_ok/stderr.txt
  then
    cli_status=0
  else
    cli_status=$?
  fi
  printf '%s\n' "$cli_status" > bundle_ok/cli-status.txt
}
Repeat similarly for mode:"raise" and mode:"reject", each time in a fresh directory. This captures metadata.json, payload.json, stderr.txt, and exit code in cli-status.txt.
Expected AWS results, not live observations: Based on the documentation and fixture behavior, we expect:
ok: metadata.json will show "StatusCode":200 and "ExecutedVersion": "<FUNCTION_VERSION>", no FunctionError. payload.json will contain {"ok":true,"request_id":"q1","value":7}. Classification should be ACCEPTED.
raise: metadata.json should show "StatusCode":200, "FunctionError":"Unhandled", "ExecutedVersion":"<VERSION>". payload.json will have an error JSON with the RuntimeError message. Classification: FUNCTION_ERROR.
reject: metadata.json should show "StatusCode":200, no FunctionError. payload.json will contain {"ok":false,"request_id":"q1","reason":"fixture rejection"}. Classification: APPLICATION_REJECTED.
We label these as “documented expected behavior” since we have not executed them for this article. In practice, the actual evidence bundle would contain the real bytes of these files. A new execution might show slight differences (e.g. actual version number instead of synthetic “7”). The key is that when classified, the outcomes match what our unit tests predicted. Until such real evidence exists, these remain expected results.
Use a fresh output bundle for each real invocation
It is crucial that each AWS invocation uses a new directory (bundle). The AWS CLI will create or overwrite payload.json if present. If one reused the same path, a failed invocation (which may not produce a payload file) could leave the previous payload sitting there, leading to a wrong classification. By isolating each run, we ensure the metadata and payload files are correctly paired. Use a new bundle_ok/, bundle_raise/, or bundle_reject/ directory for each run; do not reuse a directory from an earlier invocation. The example uses mkdir without -p so an existing directory stops the sequence instead of silently reusing stale files.
Investigate possible effects before retrying a failed call
After classification, the caller must decide what to do. We frame four possible decision categories: ACCEPT, REPAIR, HOLD, or RECONCILE. The right choice depends on what went wrong and what is known about side effects. Critically, if the function might have done something externally, never retry without checks. AWS warns that a retried direct invoke can cause duplicate side effects; “your function’s code might have run completely, partially, or not at all”.
TRANSPORT_OR_API_ERROR (rc!=0): This indicates a network or AWS API failure. We cannot assume the Lambda function ran at all, but we also cannot know for sure. Action: HOLD and manually investigate (check logs or ledger). If no execution occurred, a retry might be safe, but if AWS received it just before failing, the function may have executed. Thus RECONCILE by checking a ledger or state system is needed before retry.
FUNCTION_ERROR: The function had an unhandled exception. Again, AWS did not auto-retry, so this may have side effects. We should HOLD and investigate prior to any retry. For example, check an audit log or transaction ID for the input event. If the function performed a partial commit before error, blindly retrying could cause duplication.
APPLICATION_REJECTED: The function ran fine but business logic refused the input. This is effectively a valid (though negative) result. We ACCEPT this outcome as final, though downstream code might handle it as needed. No retry of the Lambda is appropriate, since it’s not an execution error.
INVALID_METADATA or INVALID_PAYLOAD: These indicate an unexpected metadata or payload structure, which may reflect a parsing, capture, or application-contract problem. The remedy is to REPAIR the caller code (fix parsing/validation). After correcting the wrapper, reassess the retained evidence and reconcile possible effects before retrying the operation.
WRONG_EXECUTED_VERSION: We invoked the wrong version. This is a deployment/configuration error. Action: REPAIR by updating to the correct version (or publishing a new version), then reconcile possible effects before deciding whether to retry. Keep evidence of the mismatch for auditing.
WRONG_RECEIPT_ID: This indicates a possible mismatch in event routing or replay of a stale response. It should not happen normally. We HOLD and investigate (check if somehow we sent the wrong ID or an old response was mixed in). Possibly the request was duplicated or misattributed.
NOT_EXECUTION_PROOF: We used Event or DryRun, so we have no synchronous execution result. This is a policy violation in our synchronous flow. Treat it as HOLD and fix the invocation type. Event may still lead to asynchronous execution and side effects; DryRun only validates the request and permissions.
The matrix below summarizes these decisions:
Classification | Decision | Next Step/Owner | Required Evidence |
ACCEPTED | ACCEPT | Caller (proceed to use result) | Metadata & payload validate fully |
APPLICATION_REJECTED | ACCEPT (business) | Caller or App Logic (handle as error) | Metadata valid; payload indicates handled rejection |
FUNCTION_ERROR | HOLD / RECONCILE | Caller / Ops (investigate) | Check external logs/audit for partial effects |
TRANSPORT_OR_API_ERROR | HOLD / RETRY | Caller / Ops (investigate) | Network error; confirm function not executed |
INVALID_METADATA/PAYLOAD | REPAIR | Caller Developer (fix code) | Wrapper parsing or schema issue |
WRONG_EXECUTED_VERSION | REPAIR / HOLD | DevOps (correct version) | Mismatch in deployed version |
WRONG_RECEIPT_ID | HOLD | Caller (investigate ID source) | Check for duplicate or misrouted request |
NOT_EXECUTION_PROOF | HOLD | Caller (fix invocation type) | InvocationType was Event/DryRun |
A few points on implementation: when choosing REPAIR, retain all old metadata/payload files and logs. After fixing the caller, you can rerun the invocation in test, but never overwrite the old evidence. On a real system, maintain an audit trail (correlation IDs, CloudWatch logs, etc.) outside of this classifier. Deciding to retry or compensate an operation belongs to business logic, not the classifier itself. The classifier’s role is only to flag that something unusual occurred; actual resolution (retrying, rollback) requires external state.
Keep retry ownership distinct from response classification
Finally, note that our classifier does not make the retry decision. It merely labels the response. Deciding how to handle retries, including ensuring idempotency or deduplication, is a separate concern. The AWS guidance reminds us that after a direct invocation, any retry is on the caller to manage. In other words, even if we classify something as FUNCTION_ERROR, we might still need a mechanism (database transaction ID, ledger, etc.) to ensure reprocessing is correct. That logic sits in the application layer.
This principle aligns with general API best practices: keep transport-level error handling separate from application-level error handling. Our wrapper can stop the retry from happening prematurely, but it cannot by itself guarantee exactly-once execution. A durable record (for example, writing the request_id to DynamoDB before invoking) is needed to coordinate effects.
Choose ACCEPT, REPAIR, HOLD or RECONCILE
In summary, the caller must pick one of four actions based on classification:
ACCEPT: The invocation is fully confirmed. For ACCEPTED, we proceed. For APPLICATION_REJECTED, we accept the function’s response (just marked as a business failure) and move on. No retry is done.
REPAIR: The caller code or invocation parameters need fixing. For INVALID_* or WRONG_* errors, we should correct the issue (validation logic or version mismatch) and reconcile possible effects before reissuing the request. Evidence (captured metadata/payload) should be logged for post-mortem.
HOLD: We lack enough evidence to decide. This includes transport errors, id mismatches, wrong invocation type. We pause and ask for human intervention or automated reconciliation.
RECONCILE: This is needed when the function might have taken action externally (e.g. on a function error or ambiguous case). We check logs, state, or a transaction record to figure out whether to retry or roll back.
Implementing these policies means the Lambda caller is robust. It never “assumes success” on thin evidence, and it preserves raw outputs for audit. This approach complements common cloud development practices such as strong input/output validation and explicit error-handling.
Connect invocation review to cloud-development practice
Reviewing Lambda invocation results in this disciplined way is an example of the cloud-native operational mindset. It ties directly into skills emphasized in cloud engineering practice. For instance, courses and guides on cloud-native development focus on tracing requests end-to-end, using unique IDs, and designing idempotent operations. Our exercise has shown that even a simple synchronous call requires careful validation at multiple layers.
For developers and teams, adopting these patterns, including checking FunctionError, validating payload schemas, and correlating requests, is part of building reliable serverless applications. The Refonte Cloud Development Program provides hands-on training in exactly these foundational areas (cloud architecture, deployment practices, DevOps operations) alongside internships to practice them. It covers concepts like cloud APIs, event-driven design, and error handling. If you’re looking to formalize your skills, consider the Cloud Development Program as one resource to deepen your expertise in these critical topics.
In conclusion, by treating each synchronous Lambda invoke with skepticism and clear decision branches, we build a caller that fails closed and preserves evidence. Before retrying any apparently failed call, we reconcile by checking independent records to avoid unintended duplicate effects. These methods ensure that “Lambda Invoke” remains a reliable contract, but only if we don’t mistake HTTP 200 for business success.