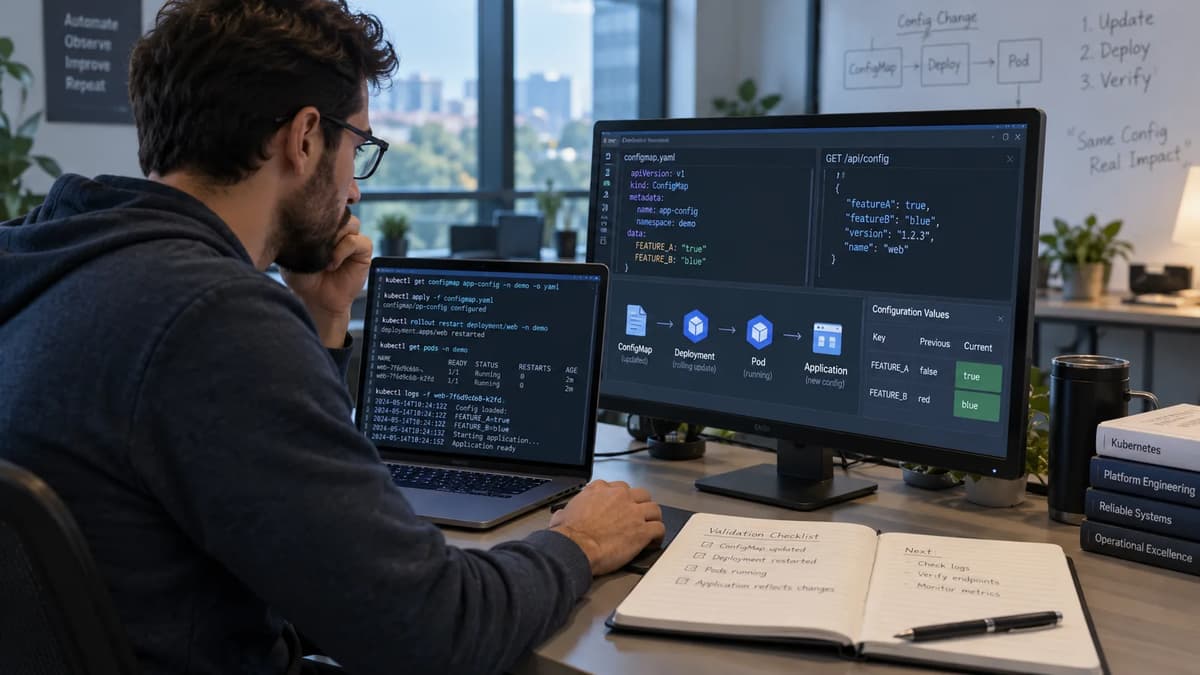
kubectl accepts a ConfigMap update. A subsequent kubectl get shows the new value. The Deployment is healthy. The Pod is Running. Yet a request sent to the same application process still produces behavior associated with the old configuration.
That is not one state; it is several states that happen to be discussed under the single word “configuration.”
For reliable acceptance, separate four boundaries: the ConfigMap object stored through the Kubernetes API, the value exposed through each delivery surface, the value retained or reread by the application process, and the value that actually determines externally observable behavior. Kubernetes deliberately gives these surfaces different update semantics. A normal ConfigMap volume is eventually refreshed, ConfigMap-backed environment variables are not changed inside an existing Pod, and a subPath ConfigMap mount does not receive later ConfigMap updates. Even when a mounted file changes, software that loaded it only during startup continues using its cached state. The Kubernetes ConfigMaps documentation and Updating Configuration via a ConfigMap describe these boundaries explicitly.
The controlled fixture below begins with harmless text value A, changes only the ConfigMap to B, and asks one question at every boundary: which revision is here now?
This is a reproducible acceptance protocol, not a transcript of an executed laboratory. Commands marked for observation must capture real values when the exercise is run; example result tables describe expected patterns, not measured results.
Define the configuration claim the application must satisfy
Before changing a ConfigMap, write the application configuration contract. Without one, seeing B somewhere in a Pod does not tell you whether the change should be accepted.
For this fixture, the approved semantic revisions are deliberately simple:
Contract item | Cache implementation | Live-read comparison |
Initial approved value | A | A |
Requested update | B | B |
Allowed values | A, B | A, B |
Authoritative runtime source | startup-loaded normal volume | freshly opened normal-volume file |
Expected adoption method | Pod replacement | live reread |
Effective behavior for A | configured-A | configured-A |
Effective behavior for B | configured-B after replacement | configured-B after file propagation |
Invalid value | startup rejection | controlled HTTP error |
The local propagation observation deadline will be 180 seconds, with observations every two seconds. Those are authored test parameters, not Kubernetes guarantees. Kubernetes documents eventual updating of projected ConfigMap volume keys and explains that propagation depends on kubelet synchronization and its change-detection strategy.
The distinction matters operationally. If the application contract says configuration is immutable for the lifetime of a process, an unchanged response from the unchanged Pod is not evidence of a broken reload mechanism; replacement is the required adoption operation. Conversely, if the contract promises live configuration adoption from the normal volume, returning configured-A after that pathname can freshly be read as B is an application-adoption failure.
That acceptance problem starts after the deployment mechanics covered by Kubernetes CI/CD foundations. The question here is narrower: not whether an object was delivered, but whether the intended running process adopted its approved value.
The scope is intentionally local and disposable. It excludes production access, Secrets, external secret managers, reload-controller products, GitOps controller design, probe tutorials, sidecars, distributed atomic changes, scheduling policy, drain behavior and unrelated storage or security topics.
Record the cluster, image and process baseline
Make the experiment reproducible enough that another engineer can distinguish Kubernetes behavior from a changed fixture.
At the September 25, 2026 research cutoff, kind’s documented installation examples use v0.33.0, and its documentation recommends selecting Kubernetes through a specific kindest/node image with a SHA-256 digest rather than relying only on a tag. Kubernetes 1.37 is the current documentation branch used for this protocol.
Use this declared fixture:
cluster name: cfg-adoption
cluster system: kind v0.33.0
Kubernetes server: v1.37.0 fixture target
namespace: cfg-lab
ConfigMap: cfg-contract
Deployment: cfg-adoption
replicas: 1
application port: 8080
local port-forward: 127.0.0.1:18080
application source: committed local fixture
application build: Go 1.27.1
observation limit: 180 seconds
poll interval: 2 seconds
Go’s official release archive lists Go 1.27.1 and its per-platform checksums at the research cutoff. The runtime is still recorded from the built application rather than inferred from the source specification.
Create an evidence directory and the owned cluster. The node-image digest below is a pinned fixture input; if that published image is intentionally changed later, treat it as a substantive lab-version change and revalidate the exercise.
set -euo pipefail
export CLUSTER="cfg-adoption"
export NAMESPACE="cfg-lab"
export KIND_EXPERIMENTAL_PROVIDER="docker"
export KUBECONFIG="$PWD/evidence/kubeconfig"
mkdir -p evidence
kind create cluster \
--name "$CLUSTER" \
--image "kindest/node:v1.37.0@sha256:a1ed56cfb0e7b93589bdf97c8cd566405a265939e3620fc4f5de89adff580ae5" \
--wait 120s \
--kubeconfig "$KUBECONFIG"
Do not replace evidence with assumptions. Record what is actually installed:
{
date -u +"capture_utc=%Y-%m-%dT%H:%M:%SZ"
printf '\n== kind ==\n'
kind version
printf '\n== kubectl/client/server ==\n'
kubectl version -o yaml
printf '\n== Docker provider ==\n'
docker version
printf '\n== Go toolchain ==\n'
go version
printf '\n== host kernel ==\n'
uname -a
printf '\n== host OS ==\n'
cat /etc/os-release 2>/dev/null || true
} | tee evidence/environment.txt
kubectl get nodes -o json \
| jq '.items[] | {
node: .metadata.name,
kubelet: .status.nodeInfo.kubeletVersion,
runtime: .status.nodeInfo.containerRuntimeVersion,
osImage: .status.nodeInfo.osImage,
kernel: .status.nodeInfo.kernelVersion,
architecture: .status.nodeInfo.architecture
}' \
| tee evidence/node-runtime.json
Capture the effective kubelet configuration if the local distribution exposes it:
NODE="$(kubectl get nodes -o jsonpath='{.items[0].metadata.name}')"
if kubectl get --raw "/api/v1/nodes/${NODE}/proxy/configz" \
> evidence/kubelet-configz.json 2>evidence/kubelet-configz.err; then
jq '.kubeletconfig
| {
syncFrequency,
configMapAndSecretChangeDetectionStrategy
}' evidence/kubelet-configz.json
else
printf '%s\n' \
"kubelet config unavailable; effective sync/cache settings UNKNOWN" \
| tee evidence/kubelet-config-status.txt
fi
Kubernetes documents Watch, Cache and Get as the ConfigMap/Secret change-detection strategies, with Watch documented as the default; the kubelet configuration API separately documents a one-minute default syncFrequency. Those defaults are documentation facts, not evidence that this cluster is running those values. If configz cannot establish the effective settings, the ledger must say unknown.
This baseline complements Helm and the wider DevOps toolchain: rendering or installing workload objects is useful delivery evidence, but it is not evidence about a particular process's adopted configuration.
Expose one ConfigMap key through three delivery paths
Keep the application code inside its image. The ConfigMap contains exactly one harmless configuration key, not a script or executable program.
The application below deliberately exposes both diagnostics and effective behavior. os.ReadFile is called on the normal and subPath paths for every request, so the diagnostic path uses a fresh pathname open rather than retaining an already-open file descriptor.
// app.go
package main
import (
"encoding/json"
"errors"
"fmt"
"log"
"net/http"
"os"
"runtime"
"strings"
"time"
)
var fixtureCommit = "uncommitted"
const (
normalPath = "/config-normal/value.txt"
subPathFile = "/config-subpath-value"
)
type State struct {
Timestamp string json:"timestamp"
PodUID string json:"pod_uid"
PID int json:"pid"
ProcessStartedAt string json:"process_started_at"
GoRuntime string json:"go_runtime"
FixtureCommit string json:"fixture_commit"
Mode string json:"mode"
EnvironmentValue string json:"environment_value"
NormalValue string json:"normal_volume_value,omitempty"
SubPathValue string json:"subpath_value,omitempty"
StartupCached string json:"startup_cached"
EffectiveValue *string json:"effective_value"
ResponseToken string json:"response_token"
ReadError string json:"read_error,omitempty"
ValidationError string json:"validation_error,omitempty"
}
func readValue(path string) (string, error) {
b, err := os.ReadFile(path)
if err != nil {
return "", err
}
value := strings.TrimSpace(string(b))
if value == "" {
return "", errors.New("configuration value is empty")
}
return value, nil
}
func valid(value string) bool {
return value == "A" || value == "B"
}
func main() {
mode := os.Getenv("APP_MODE")
if mode != "cache" && mode != "live" {
log.Fatalf("APP_MODE must be cache or live")
}
podUID := os.Getenv("POD_UID")
if podUID == "" {
log.Fatalf("POD_UID is required")
}
envValue := os.Getenv("CONFIG_ENV")
if envValue == "" {
log.Fatalf("CONFIG_ENV is required")
}
startupCached, err := readValue(normalPath)
if err != nil {
log.Fatalf("startup configuration read failed: %v", err)
}
if !valid(startupCached) {
log.Fatalf("invalid startup configuration: %q", startupCached)
}
pid := os.Getpid()
started := time.Now().UTC().Format(time.RFC3339Nano)
http.HandleFunc("/state", func(w http.ResponseWriter, r *http.Request) {
if r.Method != http.MethodGet {
http.Error(w, "GET required", http.StatusMethodNotAllowed)
return
}
normal, normalErr := readValue(normalPath)
sub, subErr := readValue(subPathFile)
state := State{
Timestamp: time.Now().UTC().Format(time.RFC3339Nano),
PodUID: podUID,
PID: pid,
ProcessStartedAt: started,
GoRuntime: runtime.Version(),
FixtureCommit: fixtureCommit,
Mode: mode,
EnvironmentValue: envValue,
NormalValue: normal,
SubPathValue: sub,
StartupCached: startupCached,
}
status := http.StatusOK
if normalErr != nil || subErr != nil {
status = http.StatusInternalServerError
state.ReadError = fmt.Sprintf(
"normal=%v; subPath=%v", normalErr, subErr,
)
state.ResponseToken = "configuration-read-error"
} else if mode == "cache" {
effective := startupCached
state.EffectiveValue = &effective
state.ResponseToken = "configured-" + effective
} else if !valid(normal) {
status = http.StatusServiceUnavailable
state.ValidationError = "allowed values are A and B"
state.ResponseToken = "configuration-error"
} else {
effective := normal
state.EffectiveValue = &effective
state.ResponseToken = "configured-" + effective
}
w.Header().Set("Content-Type", "application/json")
w.WriteHeader(status)
_ = json.NewEncoder(w).Encode(state)
})
server := &http.Server{
Addr: ":8080",
ReadHeaderTimeout: 2 * time.Second,
}
log.Fatal(server.ListenAndServe())
}
Build a static binary with the fixture commit embedded, and use scratch so the application container has no distribution userspace whose version could be mistaken for the kind node OS:
# Dockerfile
FROM scratch
COPY configprobe /configprobe
USER 65532:65532
EXPOSE 8080
ENTRYPOINT ["/configprobe"]
Commit the fixture before building it, then record both source and image identity:
git add app.go Dockerfile go.mod manifest.yaml
git commit -m "config adoption fixture"
FIXTURE_COMMIT="$(git rev-parse HEAD)"
GOARCH="$(go env GOHOSTARCH)"
CGO_ENABLED=0 GOOS=linux GOARCH="$GOARCH" \
go build \
-trimpath \
-ldflags="-buildid= -X main.fixtureCommit=${FIXTURE_COMMIT}" \
-o configprobe ./app.go
APP_IMAGE="config-adoption:${FIXTURE_COMMIT}"
docker build --pull=false --no-cache -t "$APP_IMAGE" .
docker image inspect "$APP_IMAGE" \
--format '{{.Id}}' \
| tee evidence/application-image-id.txt
printf '%s\n' "$FIXTURE_COMMIT" \
| tee evidence/fixture-commit.txt
kind load docker-image "$APP_IMAGE" --name "$CLUSTER"
The Kubernetes task documentation shows both ConfigMap-backed environment variables and ConfigMap volumes; the concepts documentation establishes their differing update semantics.
Use this manifest, substituting only the recorded fixture commit:
apiVersion: v1
kind: Namespace
metadata:
name: cfg-lab
---
apiVersion: v1
kind: ConfigMap
metadata:
name: cfg-contract
namespace: cfg-lab
data:
value.txt: "A"
---
apiVersion: apps/v1
kind: Deployment
metadata:
name: cfg-adoption
namespace: cfg-lab
spec:
replicas: 1
revisionHistoryLimit: 5
strategy:
type: Recreate
selector:
matchLabels:
app: cfg-adoption
template:
metadata:
labels:
app: cfg-adoption
spec:
containers:
- name: app
image: config-adoption:__FIXTURE_COMMIT__
imagePullPolicy: Never
env:
- name: APP_MODE
value: "cache"
- name: CONFIG_ENV
valueFrom:
configMapKeyRef:
name: cfg-contract
key: value.txt
- name: POD_UID
valueFrom:
fieldRef:
fieldPath: metadata.uid
ports:
- name: http
containerPort: 8080
volumeMounts:
- name: config
mountPath: /config-normal
readOnly: true
- name: config
mountPath: /config-subpath-value
subPath: value.txt
readOnly: true
securityContext:
runAsNonRoot: true
runAsUser: 65532
runAsGroup: 65532
allowPrivilegeEscalation: false
capabilities:
drop: ["ALL"]
volumes:
- name: config
configMap:
name: cfg-contract
items:
- key: value.txt
path: value.txt
Render and apply it:
sed "s/__FIXTURE_COMMIT__/${FIXTURE_COMMIT}/g" \
manifest.yaml > evidence/rendered-manifest.yaml
kubectl apply -f evidence/rendered-manifest.yaml
kubectl rollout status \
--namespace "$NAMESPACE" \
deployment/cfg-adoption \
--timeout=120s
Keep Pod identity stable while testing propagation
A Deployment or Service-level request is the wrong observer for this experiment because it can hide a replacement behind a stable logical endpoint. Resolve one Pod and forward directly to it:
POD="$(
kubectl get pods \
-n "$NAMESPACE" \
-l app=cfg-adoption \
-o jsonpath='{.items[0].metadata.name}'
)"
BASELINE_UID="$(
kubectl get pod "$POD" -n "$NAMESPACE" \
-o jsonpath='{.metadata.uid}'
)"
BASELINE_RESTARTS="$(
kubectl get pod "$POD" -n "$NAMESPACE" \
-o jsonpath='{.status.containerStatuses[0].restartCount}'
)"
kubectl port-forward \
-n "$NAMESPACE" \
"pod/${POD}" \
18080:8080 \
--address 127.0.0.1 \
>evidence/port-forward.log 2>&1 &
PF_PID=$!
trap 'kill "$PF_PID" 2>/dev/null || true' EXIT
Every A-to-B observation must continue to report BASELINE_UID, and the Kubernetes restart count must equal BASELINE_RESTARTS. A different UID or restart count invalidates the live-propagation comparison; it does not prove successful live adoption.
Separate diagnostic reads from the effective response
The JSON intentionally keeps normal_volume_value, subpath_value, environment_value, startup_cached and effective_value separate.
That distinction prevents a common false positive: a diagnostic endpoint freshly opens /config-normal/value.txt, sees B, and then the tester assumes the service is using B. The cache implementation instead computes response_token from startup_cached. Thus it can truthfully report normal-volume B while returning configured-A.
The comparison implementation changes only that consumer policy: in live mode, the effective value comes from the freshly read and validated normal-volume value. The diagnostic observation and business decision therefore remain independently inspectable.
Capture the initial A revision before changing anything
Do not begin an update experiment with an ambiguous baseline. All surfaces must first agree on A.
Capture the ConfigMap as an API object:
kubectl get configmap cfg-contract \
-n "$NAMESPACE" \
-o json \
| tee evidence/configmap-A.json
jq '{
resourceVersion: .metadata.resourceVersion,
value: .data["value.txt"]
}' evidence/configmap-A.json
Treat metadata.resourceVersion as Kubernetes object-version evidence, not a business configuration number. Kubernetes defines an object's metadata.resourceVersion as identifying the resource version at which that instance was last modified. The semantic labels A and B in this fixture come from the application contract, not from interpreting the resourceVersion string.
Preserve the recovery inputs before mutation:
cp evidence/configmap-A.json evidence/approved-configmap-object.json
printf 'A\n' > evidence/approved-value.txt
kubectl get deployment cfg-adoption \
-n "$NAMESPACE" \
-o json \
> evidence/approved-deployment-object.json
kubectl get deployment cfg-adoption \
-n "$NAMESPACE" \
-o jsonpath='{.spec.template.spec.containers[0].image}{"\n"}' \
> evidence/approved-image-reference.txt
Now query the fixed process:
curl --fail-with-body \
--silent \
http://127.0.0.1:18080/state \
| tee evidence/state-A.json \
| jq .
Because this brief did not execute the lab, no UID, resourceVersion, image digest or timestamp is fabricated here. The required expected baseline pattern is:
Evidence | Required initial value |
ConfigMap data | A |
environment | A |
normal-volume fresh read | A |
subPath fresh read | A |
startup cache | A |
effective value | A |
response token | configured-A |
HTTP status | 200 |
Pod UID | actual recorded UID |
restart count | actual recorded count |
Refuse the run if any configuration value is already different. Also refuse it if pod_uid returned by the application differs from the UID obtained from the API. That is wrong-observer evidence, and proceeding would corrupt the adoption ledger.
Finally record the running image identity reported by Kubernetes and reconcile it to the local immutable image ID:
kubectl get pod "$POD" -n "$NAMESPACE" \
-o jsonpath='{.status.containerStatuses[0].imageID}{"\n"}' \
| tee evidence/running-image-id.txt
Only after configuration, image, process identity and initial behavior have a clean baseline should the A-to-B clock start.
Update to B and observe each surface independently
Change only the ConfigMap key:
MUTATION_UTC="$(date -u +%Y-%m-%dT%H:%M:%S.%NZ)"
printf '%s\n' "$MUTATION_UTC" \
| tee evidence/mutation-B-utc.txt
kubectl patch configmap cfg-contract \
-n "$NAMESPACE" \
--type merge \
-p '{"data":{"value.txt":"B"}}'
kubectl get configmap cfg-contract \
-n "$NAMESPACE" \
-o json \
| tee evidence/configmap-B.json
At this point, the API object can already contain B while the Pod has not adopted anything. Updating this external ConfigMap does not alter Deployment.spec.template, so it does not itself trigger a Deployment rollout. Kubernetes states that a Deployment rollout is triggered when its Pod template changes.
Poll the same Pod for at most the declared 180 seconds:
DEADLINE_SECONDS=180
POLL_SECONDS=2
START_EPOCH="$(date +%s)"
mkdir -p evidence/cache-B-observations
while true; do
NOW_EPOCH="$(date +%s)"
ELAPSED="$((NOW_EPOCH - START_EPOCH))"
TS="$(date -u +%Y%m%dT%H%M%S)"
CURRENT_UID="$(
kubectl get pod "$POD" -n "$NAMESPACE" \
-o jsonpath='{.metadata.uid}'
)"
CURRENT_RESTARTS="$(
kubectl get pod "$POD" -n "$NAMESPACE" \
-o jsonpath='{.status.containerStatuses[0].restartCount}'
)"
if [ "$CURRENT_UID" != "$BASELINE_UID" ] ||
[ "$CURRENT_RESTARTS" != "$BASELINE_RESTARTS" ]; then
printf '%s\n' "INVALID: Pod identity/restart state changed" >&2
exit 3
fi
HTTP_CODE="$(
curl --silent --show-error \
--output "evidence/cache-B-observations/${TS}.json" \
--write-out '%{http_code}' \
http://127.0.0.1:18080/state
)"
printf '%s elapsed=%ss http=%s uid=%s restarts=%s\n' \
"$TS" "$ELAPSED" "$HTTP_CODE" "$CURRENT_UID" "$CURRENT_RESTARTS" \
| tee -a evidence/cache-B-observations/index.txt
jq '{
timestamp,
environment_value,
normal_volume_value,
subpath_value,
startup_cached,
effective_value,
response_token
}' "evidence/cache-B-observations/${TS}.json"
NORMAL="$(
jq -r '.normal_volume_value' \
"evidence/cache-B-observations/${TS}.json"
)"
[ "$NORMAL" = "B" ] && break
if [ "$ELAPSED" -ge "$DEADLINE_SECONDS" ]; then
printf '%s\n' "HOLD: B not observed on normal volume before local deadline"
break
fi
sleep "$POLL_SECONDS"
done
The expected steady pattern for the unchanged cache-mode Pod is intentionally mixed:
Surface | Expected after B reaches normal mount |
ConfigMap object | B |
environment | A |
normal directory volume, fresh open | B |
subPath, fresh open | A |
startup cache | A |
effective value | A |
response | configured-A |
That expectation follows two Kubernetes behaviors and one authored application behavior. Kubernetes documents that normal ConfigMap volume projection is eventually updated, while environment variables require a new Pod and a ConfigMap mounted via subPath does not receive updates. The application itself deliberately retains its startup value.
This is not evidence of a defective ConfigMap update. It is evidence that different consumers currently hold different revisions.
Interpret propagation latency with its configuration limits
Do not replace observation with sleep 60 or another folklore interval.
The ConfigMap concepts page explains that a kubelet periodically checks whether a mounted ConfigMap is fresh and that propagation delay depends on synchronization plus the configured cache/change-detection behavior. The application tutorial says its example can appear to update almost immediately, but it also acknowledges kubelet synchronization as part of the delay. Those statements describe different aspects of the mechanism; the tutorial's observation should not be converted into a universal service-level promise.
Record:
mutation timestamp
first observation of B on normal volume
observed elapsed time
effective kubelet settings, if actually retrievable
Pod UID throughout
restart count throughout
If the normal mount still shows A at 180 seconds, the correct decision for this test is HOLD and investigate. It is not valid to conclude from one bounded timeout that Kubernetes' documented eventual update semantics are false.
Identify stale process state after the file changes
The strongest negative control occurs when all of these facts are simultaneously true:
ConfigMap data B
normal-volume fresh read B
Pod UID unchanged
restart count unchanged
startup_cached A
effective_value A
response_token configured-A
At that point, the projected file has done its part. The application contract is the remaining boundary.
This classification should be written as stale application cache, not “ConfigMap failed to reload.” Kubernetes' own update tutorial makes this distinction: changing a mounted file does not make a process that loads configuration only on startup notice the new value.
That wording is operationally useful because it determines the repair owner. Platform engineers can prove that B reached the pathname. Application owners must then prove either that live rereading is implemented or that process replacement is the intended adoption mechanism.
Compare a deliberate reread implementation
Do not mutate the original process from cache mode to live mode and continue the same timeline. That would destroy the negative control.
Instead, reset the fixture to A, intentionally create a new run, and record its new Pod identity:
kill "$PF_PID" 2>/dev/null || true
trap - EXIT
kubectl patch configmap cfg-contract \
-n "$NAMESPACE" \
--type merge \
-p '{"data":{"value.txt":"A"}}'
kubectl set env deployment/cfg-adoption \
-n "$NAMESPACE" \
APP_MODE=live
kubectl rollout status deployment/cfg-adoption \
-n "$NAMESPACE" \
--timeout=120s
Changing APP_MODE changes the Deployment's Pod template, so a Deployment rollout is expected for this transition between test runs. That is distinct from the earlier ConfigMap-only update.
Resolve the newly created live-mode Pod, record its UID and restart count, port-forward directly to it, and require the complete A baseline again. Only then patch the ConfigMap from A to B and run the same 180-second observation loop.
The expected evidence after normal-volume propagation is:
Surface | Expected live-mode B observation |
ConfigMap | B |
environment | A |
normal fresh read | B |
subPath fresh read | A |
startup cache | A |
effective value | B |
HTTP status | 200 |
response token | configured-B |
Pod UID/restarts | unchanged through this run |
Nothing about the environment variable or subPath has become “more live.” Only the application's consumer policy changed. The app rereads /config-normal/value.txt, validates the result, and uses that validated value to form the response.
Acceptance therefore depends on the contract. If the contract identifies the normal projected volume as the authoritative live-reload source, stale diagnostic copies in the environment and subPath are expected controls, not grounds to reject the implementation. If the contract instead says the environment variable itself must become B inside the existing Pod, the contract conflicts with documented Kubernetes semantics and should be repaired.
The key comparison is process-stable in both runs: cache mode demonstrates file=B, behavior=A; live mode is expected to demonstrate file=B, behavior=B.
Reject invalid configuration without inventing reload behavior
Live rereading adds another obligation: validation. “Always use whatever appeared in the file” is not an adequate configuration contract.
The fixture permits only A or B. After establishing the live-mode B state, introduce C deliberately:
kubectl patch configmap cfg-contract \
-n "$NAMESPACE" \
--type merge \
-p '{"data":{"value.txt":"C"}}'
Hold Pod UID and restart count stable and observe until either the normal volume freshly reads C or the 180-second local deadline expires.
Once C reaches the normal path, this implementation is designed to return an HTTP 503 response like the following pattern:
{
"mode": "live",
"environment_value": "A",
"normal_volume_value": "C",
"subpath_value": "A",
"startup_cached": "A",
"effective_value": null,
"response_token": "configuration-error",
"validation_error": "allowed values are A and B"
}
This JSON is an expected shape, not captured execution output. The real run must include its actual timestamp, Pod UID, process identity, Go runtime and fixture commit.
The important property is that the application does not silently substitute A while claiming successful adoption of C. A fallback can be a legitimate product policy, but then the API must disclose the fallback and the acceptance procedure must classify the requested revision as rejected rather than adopted.
For this fixture, 503 configuration-error is intentional and bounded. It demonstrates that a live-reading application can notice a new file without accepting that file as valid configuration.
Restore a valid state immediately after the negative control:
kubectl patch configmap cfg-contract \
-n "$NAMESPACE" \
--type merge \
-p '{"data":{"value.txt":"B"}}'
Do not generalize this single-key validation test into claims about atomic multi-file configuration. Kubernetes' ConfigMap projection behavior and an application's semantic consistency policy are different questions; distributed or multi-file atomic changes are explicitly outside this playbook.
Reconcile the object-to-behavior timeline
The acceptance artifact is not a screenshot of kubectl get, a green Deployment status or one application request. It is an adoption ledger joining the four evidence boundaries by Pod and timestamp.
A useful schema is:
Time | Run / Pod UID | CM RV / data | Env | Normal | subPath | Startup cache | Effective | HTTP / token | Classification |
<t0> | cache / <uid-cache> | <rv-A> / A | A | A | A | A | A | 200 / configured-A | baseline |
<t1> | same UID | <rv-B> / B | A | A | A | A | A | 200 / configured-A | propagation pending |
<t2> | same UID | <rv-B> / B | A | B | A | A | A | 200 / configured-A | stale app cache |
<t3> | live / <uid-live> | <rv-A2> / A | A | A | A | A | A | 200 / configured-A | live baseline |
<t4> | same live UID | <rv-B2> / B | A | B | A | A | B | 200 / configured-B | adopted live |
<t5> | same live UID | <rv-C> / C | A | C | A | A | null | 503 / configuration-error | invalid config |
Every bracketed value is a placeholder that must be replaced by recorded execution evidence. The table states the expected causal pattern, not a claimed result.
The classification vocabulary should remain precise:
Propagation pending means the API object is current but the normal projected file has not yet been observed current within the still-open deadline.
Expected stale surface applies to environment variables or subPath in a continuing Pod because Kubernetes documents that those paths do not receive the ConfigMap change in the way the normal mount does.
Stale application cache means a fresh authoritative file read has the requested valid revision while effective behavior remains tied to previously held process state.
Invalid configuration means the requested content reached the consumer but failed the application's declared validation policy.
Wrong-Pod evidence means the observer reached another UID, or a replacement/restart occurred during a test that required process continuity.
This ledger is deliberately more specific than general monitoring evidence and tooling. Metrics, logs and dashboards can help locate a problem, but acceptance here requires evidence about the exact process and exact configuration revision under test.
Make the negative controls able to fail acceptance
A test is weak if every observation can be interpreted as success.
Suppose the service contract requires live adoption through the normal projected volume. The following state must fail:
normal_volume_value = B
startup_cached = A
effective_value = A
response_token = configured-A
It fails even if:
kubectl get configmap -> B
Pod phase -> Running
Deployment available -> 1
restart count -> unchanged
Deployment health establishes controller/workload state, not application configuration semantics. Kubernetes' Deployment documentation describes rollout completeness in terms of requested replicas and availability; it does not claim that an application has semantically consumed an independently changed external ConfigMap.
The inverse negative control matters too. If the response says configured-B but the returned Pod UID is not the UID bound to the port-forward evidence, reject the observation. A convincing response from the wrong process does not certify the target process.
Bound claims to the observed consumers
A single-replica run proves only what was observed for that one Pod/process under the recorded fixture.
For a multi-replica system, coverage would begin by enumerating every Pod behind the workload:
kubectl get pods \
-n cfg-lab \
-l app=cfg-adoption \
-o jsonpath='{range .items[*]}{.metadata.name}{"\t"}{.metadata.uid}{"\n"}{end}'
Each Pod would then receive an individually bound kubectl port-forward pod/<name> ..., with its own ledger rows. That extension preserves the same evidence model; it does not turn one single-replica experiment into a claim of fleet-wide atomicity.
This article intentionally stops there. Coordinating distributed configuration adoption, availability budgets and multi-replica rollout sequencing is a separate operational problem.
Choose rereading or replacement as an explicit repair
Once the ledger locates the stale boundary, repair that boundary instead of issuing a ritual restart.
For the live-reread contract, the application owns the repair. A suitable design must freshly obtain the designated configuration source, parse and validate it, expose the accepted revision, and make externally observable behavior depend on the accepted value. The live fixture demonstrates the minimum form: fresh open, allow-list validation, then effective_value = normal_volume_value.
For the startup-only contract, replacement is the correct adoption mechanism. The same is true when the authoritative configuration is injected as an environment variable; Kubernetes documents that ConfigMap-derived environment values are not updated automatically in an existing Pod. A subPath ConfigMap mount likewise does not receive later ConfigMap updates.
After first proving that the object contains the desired value, a controlled replacement can be requested with:
kubectl rollout restart deployment/cfg-adoption \
-n cfg-lab
kubectl rollout status deployment/cfg-adoption \
-n cfg-lab \
--timeout=120s
The ConfigMap update and rollout restart are two separate operations. The former changes an external object. The latter causes a Pod-template change and replacement. Kubernetes ties Deployment revisions and rollouts to changes in the Pod template.
Do not write “restart successful, therefore B adopted.” Resolve the replacement Pod and create a fresh ledger row:
NEW_POD="$(
kubectl get pods \
-n cfg-lab \
-l app=cfg-adoption \
-o jsonpath='{.items[0].metadata.name}'
)"
kubectl get pod "$NEW_POD" -n cfg-lab \
-o jsonpath='{.metadata.uid}{"\t"}{.status.containerStatuses[0].restartCount}{"\n"}'
Port-forward that exact new Pod and require the effective response to be configured-B.
For a replacement started after the ConfigMap contains B, the expected new-process pattern is environment=B, normal=B, subPath=B, startup_cached=B, effective=B. Only the executed observation can promote that expectation to accepted evidence.
Repair therefore means one of two things: make the application honor its live-reread contract, or deliberately replace the process whose configuration contract is startup-bound. Do not blur those models.
Pair workload and configuration revisions for recovery
Configuration recovery fails when teams preserve only half of the executable state.
Kubernetes records Deployment revisions when its Pod template changes, and its documentation explicitly says that rolling back to an earlier Deployment revision rolls back the Pod-template portion. An independently mutated ConfigMap is outside that history. Therefore kubectl rollout undo deployment/... cannot by itself restore mutable ConfigMap content.
The minimum recovery record for this fixture is a pair:
Approved workload
fixture commit
immutable/local image ID
Deployment Pod template
application mode
Approved configuration
ConfigMap name
exact value
API resourceVersion observed at approval
semantic revision label: A
Before mutation, the exercise already saved approved-value.txt, the ConfigMap object, Deployment object, image reference and fixture commit. The resourceVersion proves which API-object state was observed; it does not replace the saved content.
A bounded restoration of the main one-ConfigMap fixture can therefore set the content back explicitly:
APPROVED_VALUE="$(cat evidence/approved-value.txt)"
[ "$APPROVED_VALUE" = "A" ] || {
echo "unexpected approved value" >&2
exit 4
}
kubectl patch configmap cfg-contract \
-n cfg-lab \
--type merge \
-p '{"data":{"value.txt":"A"}}'
If the approved application's contract is startup-bound, that content restoration must be followed by controlled Pod replacement and behavioral verification.
For systems that need stronger revision pairing, a proposed operating design is to create separately named configuration objects such as cfg-contract-rA and cfg-contract-rB and make the Deployment template reference the intended name. This is a naming and release policy, not magic supplied by arbitrary ConfigMap names. Changing the reference changes the Pod template and makes the workload/configuration association explicit. The main laboratory deliberately retains one mutable ConfigMap so that the propagation behavior remains visible.
Whichever design is chosen, one owner must preserve both halves of the approved pair.
Test the rollback using the same behavioral oracle
A recovery is not complete when an old ReplicaSet appears or when kubectl get configmap once again prints A.
Restore the approved pair and then rerun the same evidence chain.
First establish the desired external object:
kubectl get configmap cfg-contract \
-n cfg-lab \
-o json \
| tee evidence/restored-configmap.json
test "$(
jq -r '.data["value.txt"]' evidence/restored-configmap.json
)" = "A"
Then restore the workload fields that were part of the approved pair. For the original cache fixture:
kubectl set env deployment/cfg-adoption \
-n cfg-lab \
APP_MODE=cache
kubectl rollout restart deployment/cfg-adoption \
-n cfg-lab
kubectl rollout status deployment/cfg-adoption \
-n cfg-lab \
--timeout=120s
Where the exact image reference also changed during a broader repair exercise, restore the recorded approved image before accepting the rollout:
APPROVED_IMAGE="$(cat evidence/approved-image-reference.txt)"
kubectl set image deployment/cfg-adoption \
-n cfg-lab \
"app=${APPROVED_IMAGE}"
Because replacement is intended in this recovery path, the accepted rollback evidence should contain a new Pod UID. A new UID is not itself success; it merely proves the replacement boundary occurred.
Port-forward the new Pod specifically and require:
ConfigMap content A
environment A
normal-volume fresh A
subPath fresh A
startup cache A
effective value A
response configured-A
application image approved image identity
fixture commit approved fixture commit
The Deployment documentation warns against conflating rollback history with external state: Deployment rollback addresses its Pod template. The external configuration must therefore be restored independently and tested.
Preserve the evidence before cleanup:
kubectl get all -n cfg-lab -o yaml \
> evidence/final-namespace-workloads.yaml
kubectl get configmap cfg-contract -n cfg-lab -o yaml \
> evidence/final-configmap.yaml
Only after the acceptance exercise is complete should the owned disposable cluster be removed:
kind delete cluster --name cfg-adoption
That cleanup is deliberately scoped to the named local kind cluster; the protocol requires no production cluster access.
Decide accept, repair, replace, hold or restore
The decision must follow the configuration contract and the observed boundary, not whichever command last returned zero.
Evidence pattern | Meaning | Decision | Required next evidence |
Object B; normal still A; deadline open | propagation not yet observed | Hold/observe | same-Pod observations until B or deadline |
Object B; normal still A after local deadline | unresolved delivery | Hold | kubelet/settings/platform investigation |
Normal B; cache A; effective A; live B required | consumer stale | Repair | corrected app rereads/validates and behavior becomes B |
Environment A in continuing Pod; B required | expected startup-bound surface | Replace | new Pod shows env B and behavior B |
subPath A in continuing Pod; B required | documented stale surface | Replace | new Pod shows subPath B and behavior B |
Normal B; env/subPath A; live app effective B | intended mixed state | Accept, if normal mount is authoritative | identity, validation and scope checks complete |
Normal C; validation rejects it | bad requested configuration | Hold/restore | authorized valid revision restored |
Pod UID changed during supposed live test | comparison invalid | Hold | rerun from clean baseline |
restart count changed unexpectedly | process continuity lost | Hold | rerun from clean baseline |
B everywhere after replacement, effective B | replacement adoption proven | Accept | ledger and revision pair retained |
requested pair known bad, approved A pair available | recovery authorized | Restore | same behavioral oracle proves A |
The subtle case is the mixed but correct live state. An unchanged environment variable and unchanged subPath file do not necessarily block acceptance after B if the contract says the normal projected file is authoritative and the effective behavior has demonstrably moved to B. Those stale values are then negative controls confirming that the test can distinguish delivery paths. Kubernetes documents precisely those differences.
Likewise, never classify normal=B, effective=A as accepted when the contract promises live B. The file projection succeeded, but the requested service behavior did not.
“Replace” is also stronger than “request a restart.” kubectl rollout restart is an action. A new Pod UID is replacement evidence. environment=B or startup_cached=B is delivery/process evidence. configured-B is the behavioral oracle. All four are distinct.
“Restore” has the same discipline. A rollback command is an action, not proof. An old ReplicaSet becoming active proves controller state, not ConfigMap content. A familiar ConfigMap name proves neither content nor application adoption. The restored pair is accepted only after configuration, process and external behavior converge on the approved contract.
The default decision for incomplete evidence should be HOLD, not optimistic acceptance. An explicit unresolved state is more reliable than manufacturing certainty from a green Kubernetes status.
Assign platform and application ownership separately
Configuration incidents are easier to repair when ownership follows the evidence boundary.
The platform owner owns proof that the intended ConfigMap object exists with the intended content, the correct Pod references it, the normal projected volume reaches the expected value within the declared investigative scope, and an explicitly requested replacement creates the intended new Pod. The platform owner also records Kubernetes, kind, kubelet-visible settings, node/runtime builds and Pod identity.
The application owner owns parsing, validation, startup caching, rereading policy and the mapping from accepted configuration to observable service behavior. If /config-normal/value.txt freshly reads B while the application deliberately continues using a parsed A object, that is no longer a volume-delivery question.
The reviewer or release owner owns the contract, coverage and acceptance decision: which surface is authoritative, whether live adoption or replacement is expected, which semantic revision is approved, whether the observed Pod set is sufficient, and who may authorize restoration.
This separation complements broader shared delivery and security ownership, but it should remain concrete enough that “shared” does not mean “unowned.”
Revalidate the playbook when any assumption that defines the evidence chain changes: Kubernetes version, local distribution or kubelet configuration; ConfigMap mount path or switch between normal and subPath mounting; environment-variable use; application parsing/caching/reread policy; container image/runtime; Deployment controller or Pod-template behavior; or the recovery naming strategy. Kubernetes' current documentation makes the delivery-path distinctions explicit, but an application's own consumer contract is outside Kubernetes and must be tested independently.
The ownership test is simple: the person responsible for a boundary must be able to produce its evidence, not merely point at the next team's dashboard.
Build the DevOps foundations behind configuration evidence
This exercise depends on Kubernetes object modeling, container builds, delivery discipline and observability rather than on a special “reload” command. Readers building those foundations can also review Refonte Learning's Kubernetes application-development learning paths.
Refonte Learning's DevOps Engineering page, verified for this article on September 25, 2026, lists a three-month program at 12–14 hours per week and names Linux and scripting, Git/GitHub, CI/CD, Docker and Kubernetes, Terraform, cloud platforms, monitoring/logging and project work in its published curriculum. Those are useful foundations for understanding this workflow; the published page should not be read as a promise that this specific ConfigMap adoption laboratory is included.
The operational standard remains independent of coursework: prove the API-object revision, prove what reached each delivery surface, prove what the process retained or reread, and finally prove which revision generated the behavior you are accepting.