At 2:17 a.m., the order existed in Postgres, the Redis entry said it did not, and the background worker had no reliable record of whether it had been told to do anything.
I have spent enough years designing backend services to know what happens next. Nobody debugs “the application”; you debug three different consistency models, three dashboards, three retry mechanisms, three sets of timestamps, and a request ID that somehow disappeared between the database transaction and the queue producer.
The frustrating part is that none of the individual technologies has to be broken. Postgres can be healthy, Redis can be healthy, and RabbitMQ, SQS, or another message queue can be healthy while the system is wrong because the handoffs between them failed.
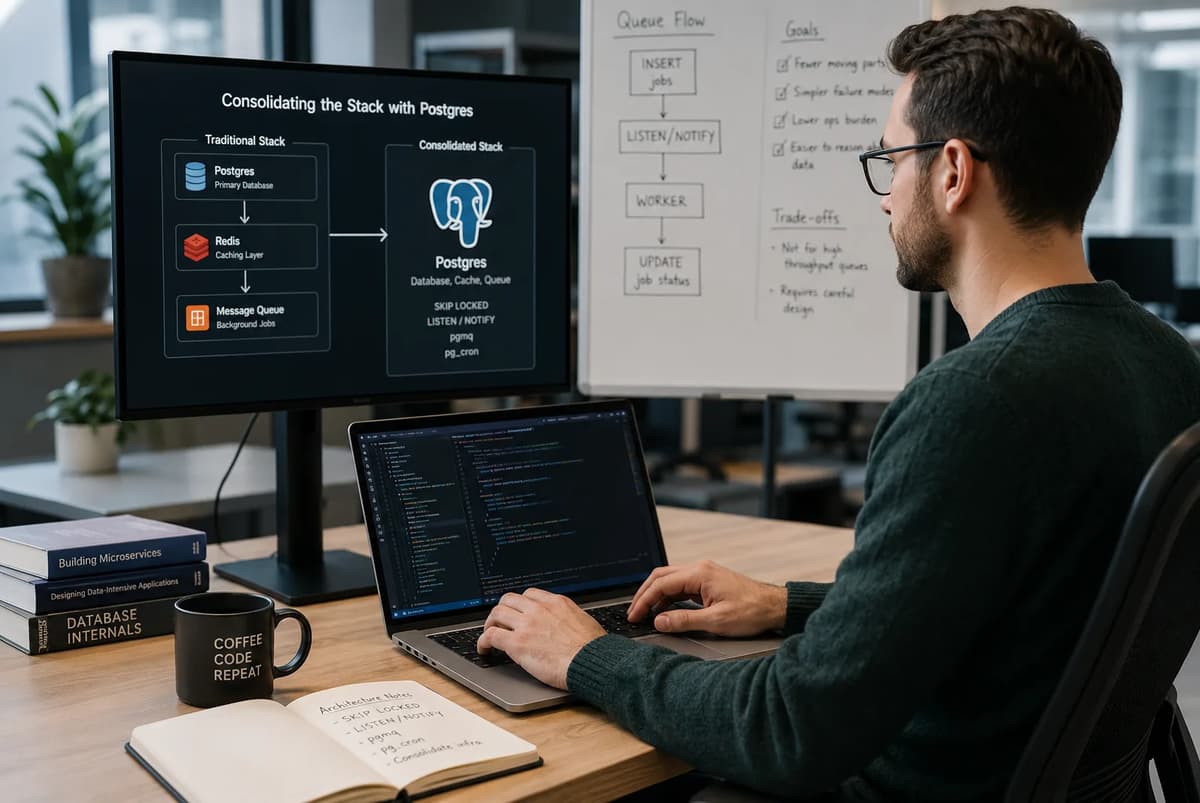
That is the architectural argument behind using Postgres instead of Redis for some workloads and Postgres as a message queue for others. It is not a claim that PostgreSQL suddenly became an in-memory cache or Kafka competitor in 2026; it is a database consolidation backend architecture strategy that asks whether every specialized service is earning the operational complexity it adds.
The underlying queue technique is established rather than new: Crunchy Data was documenting a native PostgreSQL queue based on row locking and SELECT ... FOR UPDATE SKIP LOCKED on September 1, 2021. PostgreSQL's own current documentation explicitly describes SKIP LOCKED as useful for multiple consumers accessing a queue-like table.
Since then, the ecosystem has become easier to consume. Supabase now offers a Postgres-native durable queue built on pgmq, while pg_cron schedules recurring work inside PostgreSQL; those tools make an old idea substantially less DIY.
That distinction matters for the Refonte Learning Backend Development Program: this article extends beyond the program page's database fundamentals into an architectural decision experienced backend developers increasingly need to evaluate, without claiming the published curriculum already teaches PostgreSQL extensions or Postgres-specific queueing. The live curriculum currently names “Database Management: MongoDB & SQL,” not PostgreSQL, Redis, pgmq, or queue internals.
The On-Call Week Caused by Three Systems That Had to Agree
The failure pattern usually begins with a perfectly reasonable architecture diagram.
Postgres owns durable business state. Redis makes reads fast. A queue moves slow work such as email delivery, billing reconciliation, search indexing, webhook fan-out, or report generation out of the request path.
Then one user operation becomes three writes:
Commit the business transaction in Postgres.
Invalidate or update the corresponding Redis key.
Publish a job or event to the message broker.
The trouble is that those operations do not automatically share a transaction.
Imagine an endpoint that changes a customer's subscription. The database commit succeeds, the Redis invalidation times out, and the queue publish returns an ambiguous network error; now the API does not know whether retrying will repair the system or duplicate work.
System | What I need to know during the incident | Failure that creates ambiguity |
Postgres | Did the transaction commit? | Client timed out after server commit |
Redis | Was stale state removed? | Invalidation failed or raced another writer |
Queue | Was the job accepted? | Producer lost acknowledgement |
Worker | Did side effects happen? | Job ran but acknowledgement failed |
This is the uncomfortable truth about distributed systems: adding components can improve scalability or specialization while simultaneously creating more states that the application must reconcile.
The transactional outbox pattern exists largely because this “database plus broker” dual-write problem is real. Debezium describes the outbox approach as a way to avoid inconsistencies between application state and events consumed by other services by recording the business change and outbound event in the database transaction together.
That is also why I am suspicious when someone calls deleting Redis or a queue an infrastructure-cost optimization first. Cost can matter, but my first question is usually more operational: how many independent pieces of state do we have to reason about at 2 a.m.?
With one transactional boundary, I can answer “did the order and its job exist?” using SQL against the same durable system. With three systems, that answer often becomes archaeology.
The Case for Fewer Moving Parts in a Backend Stack
The phrase reducing infrastructure complexity backend teams use can sound like a preference for minimal diagrams. That undersells it.
A new stateful service does not merely add one rectangle to an architecture drawing. It brings authentication, networking, credentials, client libraries, connection behavior, metrics, alerting, backups or persistence settings, failover procedures, capacity planning, upgrades, incident knowledge, local-development behavior, and another set of semantic edge cases.
Redis itself illustrates the point well because it is far more capable than the stereotype of “just a cache.” Its current documentation covers automatic eviction policies, persistence modes, replication, Sentinel, Cluster, streams, sorted sets, and other data structures; those capabilities are valuable, but they are also a separate operational domain your team must understand.
Architecture choice | Main benefit | Hidden tax |
Postgres + Redis + broker | Specialization and independent scaling | Cross-system consistency and three operational surfaces |
Postgres + broker | Keeps robust messaging specialization | Database/broker dual-write still needs handling |
Postgres + Redis | Excellent cache primitives | Cache invalidation and duplicate state remain |
Mostly Postgres | One transactional system and familiar tooling | More workload contention and lower specialist ceilings |
The consolidation argument is therefore not “one database is technically superior at every task.” It is that a specialized system should clear a meaningful burden-of-proof threshold before a small or medium backend team accepts the new boundary.
For a product doing hundreds or a few thousand ordinary asynchronous jobs per second, for example, raw queue throughput may not be the dominant constraint. Engineer time, consistency bugs, deploy complexity, or the number of systems one person must understand during an outage may matter more.
I use a simple architecture-review question: what measured requirement makes the specialist mandatory?
If the answer is “we always use Redis” or “every backend needs a queue,” I want data before approving another service. If the answer is “our distributed rate limiter needs predictable sub-millisecond decisions on every request” or “we have an event stream with long retention and independent consumer groups,” the specialist already has a much stronger case.
My confidence levels on the broader 2026 story are deliberately uneven:
Claim | Confidence | Why |
Native Postgres queueing is established | High | Crunchy Data documented the pattern in September 2021 |
Supabase has productized Postgres queueing | High | Current Supabase Queues documentation explicitly says it uses pgmq |
Consolidation has a real operational rationale | High | Transactional boundaries and reduced state synchronization follow directly from the design |
A 2026 industry-wide Redis-to-Postgres migration wave is measurable | Not established | I could not independently confirm a robust 2026 adoption statistic or company migration dataset specific to this switch |
That last row deserves emphasis. As of August 19, 2026, targeted research surfaces 2026 opinion pieces and personal write-ups about replacing Redis with PostgreSQL, but I could not independently confirm a freshly dated organizational case study or adoption statistic that quantifies a broad Redis-to-Postgres migration trend.
The credible framing is therefore resurfacing boring technology, not “the hot new database trend of 2026.”
The Technique Behind This: SKIP LOCKED and LISTEN/NOTIFY
A useful skip locked postgres queue is built around a surprisingly small concurrency primitive.
Suppose a jobs table contains pending work. Multiple workers need to claim jobs concurrently without two workers taking the same row and without every worker waiting behind whichever transaction happened to lock the first candidate.
PostgreSQL provides exactly the relevant behavior:
SELECT id, payload
FROM jobs
WHERE status = 'pending'
ORDER BY created_at
FOR UPDATE SKIP LOCKED
LIMIT 10;
FOR UPDATE locks the selected rows. SKIP LOCKED tells a competing transaction not to wait on rows another worker already holds; instead, it can continue to other eligible work.
PostgreSQL's own documentation is unusually explicit about the intended use: SKIP LOCKED produces an inconsistent view unsuitable for ordinary querying, but can be useful to avoid lock contention when multiple consumers access a queue-like table.
Crunchy Data demonstrated the same behavior in its September 2021 queue article: one backend locks the first batch, while another using SKIP LOCKED can immediately obtain a different batch rather than hanging behind it.
Primitive | Job-queue role |
FOR UPDATE | Prevents another worker from concurrently claiming the same row |
SKIP LOCKED | Lets other workers continue to different jobs |
Transaction | Makes claiming/state changes atomic |
Indexed status/schedule columns | Finds ready work efficiently |
LISTEN/NOTIFY | Wakes sleeping consumers so they do not have to poll aggressively |
A production design often changes the row's state while it is being claimed rather than holding a database transaction open while a ten-minute external task executes. Long transactions are exactly what I try to keep out of queue workers.
One common pattern is to atomically mark work as running and return it:
WITH next_jobs AS (
    SELECT id
    FROM jobs
    WHERE status = 'pending'
      AND run_at <= now()
    ORDER BY run_at, id
    FOR UPDATE SKIP LOCKED
    LIMIT 20
)
UPDATE jobs AS j
SET status = 'running',
    locked_at = now(),
    attempts = attempts + 1
FROM next_jobs
WHERE j.id = next_jobs.id
RETURNING j.*;
Your application commits that claim quickly, performs the external work, and then marks the job complete. A visibility-timeout design can make abandoned work eligible again if the worker disappears.
LISTEN and NOTIFY solve a different part of the problem. A postgres listen notify queue should normally treat notifications as wake-up signals while the durable truth stays in a table.
PostgreSQL documents NOTIFY as an asynchronous interprocess communication mechanism and specifically suggests storing larger or structured information in database tables and sending a key through the notification. Notifications generated inside a transaction are not delivered unless that transaction commits, which is precisely what you want when “new work exists” must not fire for rolled-back inserts.
That gives you a useful hybrid:
BEGIN;

INSERT INTO jobs (type, payload, status)
VALUES ('send_receipt', '{"order_id": 8472}', 'pending');

SELECT pg_notify('jobs_ready', 'send_receipt');

COMMIT;
The durable job is the row. NOTIFY merely tells a listener, “stop sleeping and query the queue.”
Do not mistake LISTEN/NOTIFY for a durable broker by itself. PostgreSQL notes that listening registrations disappear when a session ends, notifications are delivered to sessions that are listening, and notification payloads are limited to less than 8,000 bytes under the default configuration.
Why This Isn't New, and Why That's a Good Thing
September 1, 2021 is the date that matters here, not 2026.
Crunchy Data's “Devious SQL: Message Queuing Using Native PostgreSQL” walked through SELECT ... FOR UPDATE, the blocking problem, SKIP LOCKED, concurrent batches, and a SQL approach to deleting and returning claimed rows years ago.
That is reassuring.
I do not want the synchronization mechanism behind invoices, emails, or fulfillment jobs to have been discovered six weeks ago because it trended on social media. For infrastructure primitives, “old enough that people understand its failure modes” is a feature.
The renewed relevance comes from packaging and ecosystem maturity rather than invention. pgmq gives Postgres an SQS-like queue abstraction, pg_cron packages scheduling, pgvector provides vector search, and TimescaleDB extends Postgres for time-series workloads; these are different workloads, but collectively they expand the set of architectural boxes teams can at least evaluate before adding another database product.
That does not prove every extension should run in your primary production cluster. It changes the default architecture-review conversation from “which new service do we add?” to “can the database we already operate meet the requirement safely?”
From Manual SQL to a Real Extension: pgmq and Supabase Queues
Hand-written queue tables are educational, but queue semantics accumulate requirements quickly.
You need visibility timeouts, acknowledgement behavior, retries, archiving, observability, batch reads, empty-queue handling, permissions, and a reliable answer to what happens when a consumer dies halfway through processing.
This is where pgmq Supabase Queues becomes more interesting than another SKIP LOCKED blog demo.
Supabase's current documentation describes Supabase Queues as a durable Postgres-native message queue built on the pgmq extension. It exposes durable storage, archival, queue management, authorization, and a visibility-window model entirely through Postgres.
pgmq's own documentation shows the lifecycle clearly:
A consumer reads a message with a visibility timeout.
The message becomes temporarily invisible to competing consumers.
Successful consumers delete or archive it.
If it is not deleted or archived before the timeout, it becomes visible again.
The wording around “exactly once” deserves senior-engineer skepticism. Supabase and pgmq document exactly-once delivery to a consumer within the visibility window, but a message can become visible again after that window, so external side effects should still be designed idempotently.
If a worker charges a card and crashes before acknowledging the job, the queue cannot magically uncharge the card. Use an idempotency key at the payment boundary.
That distinction between message delivery and business-side-effect execution is one of the first things I look for when reviewing any queue, whether it runs on Postgres, Redis, SQS, or RabbitMQ.
Using Postgres for Scheduled Jobs: pg_cron in Practice
A queue answers “what work is waiting?” Scheduled work answers “when should new work start?”
pg_cron moves a useful slice of that scheduling into the database. The project's current documentation describes it as a cron-based PostgreSQL scheduler running as an extension, backed by a background worker that tracks jobs in cron.job.
For example:
SELECT cron.schedule(
    'expire-old-cache-rows',
    '*/5 * * * *',
    $$
      DELETE FROM app_cache
      WHERE expires_at < now();
    $$
);
Or a nightly maintenance task:SELECT cron.schedule(
'archive-completed-jobs',
'0 2 * * ',
$$
INSERT INTO archived_jobs
SELECT
FROM jobs
WHERE status = 'done'
AND completed_at < now() - interval '30 days';
$$
);A useful safety behavior is built in: pg_cron can run different jobs in parallel, but the documentation says only one instance of a specific job runs at once; if the next invocation arrives before the previous one finishes, it waits.
Supabase also productized this layer as Supabase Cron in December 2024, explicitly building on the Citus pg_cron extension and supporting database functions, SQL, Edge Functions, and webhooks.
For me, pg_cron scheduled jobs are one of the lowest-risk consolidation candidates. If the job is fundamentally database maintenance, expiry cleanup, report materialization, or periodically inserting work into a durable queue, keeping its schedule beside the data can be substantially simpler than maintaining another scheduler.
Using Unlogged Tables as a Cache Layer
Replacing Redis for caching is the part of this architecture that deserves the most careful wording.
Postgres can act as a cache. That does not mean Postgres is an in-memory cache.
One interesting tool is an UNLOGGED table:
CREATE UNLOGGED TABLE app_cache (
    cache_key   text PRIMARY KEY,
    value       jsonb NOT NULL,
    expires_at  timestamptz NOT NULL,
    created_at  timestamptz NOT NULL DEFAULT now()
);

CREATE INDEX app_cache_expires_at_idx
    ON app_cache (expires_at);
PostgreSQL does not write changes to unlogged tables into the write-ahead log. Its documentation says this can make them considerably faster than ordinary tables, with two major consequences: unlogged tables are not crash-safe and their contents are not replicated to standby servers.
For durable application state, those properties would be alarming. For a disposable cache that can be reconstructed, they may be exactly the point.
Property | Regular table | Unlogged cache table |
WAL logged | Yes | No |
Crash-safe contents | Yes | No |
Replicated to standby | Yes | No |
Suitable for source of truth | Yes | No |
Suitable for rebuildable cache | Sometimes | Potentially |
The biggest conceptual advantage over a separate Redis cache is not raw speed. It is that the cache and source data can participate in the same database transaction.
Suppose a product update changes the canonical row and invalidates its cached representation:
BEGIN;

UPDATE products
SET price = 12900,
    updated_at = now()
WHERE id = 42;

DELETE FROM app_cache
WHERE cache_key = 'product:42';

COMMIT;
There is no network hop between database commit and cache invalidation. Either the business update and invalidation commit together, or neither does.
That eliminates one entire class of “database says X, cache says Y because invalidation failed” incidents.
Expiry is straightforward too:
SELECT value
FROM app_cache
WHERE cache_key = $1
  AND expires_at > now();
A periodic pg_cron job can clean expired rows, although you should still design queries so expired entries are treated as misses even if physical deletion lags.
There is also a less obvious operational benefit: SQL lets you inspect the cache using the same access controls, query tooling, tracing conventions, and database expertise your team already uses.
But there is a major counterweight. Cache traffic is often intentionally disposable, bursty traffic; pushing it into your primary database means that traffic now competes with the workload you were originally caching to protect.
Where This Genuinely Doesn't Replace Redis
I would not delete Redis simply because I can reproduce GET, SET, and TTL-like behavior in SQL.
Redis has first-class memory-pressure eviction. Its documentation lets operators configure policies that automatically remove keys once a configured memory limit is exceeded, including LRU- and LFU-oriented strategies.
A Postgres cache table does not become a Redis-style memory manager because you added an expires_at column.
Redis also has purpose-built structures and operations that are genuinely useful at high frequency. Its sorted sets support patterns such as sliding-window rate limiting, while its rate-limiting documentation describes centralized distributed request decisions using atomic counters and expirations.
Keep Redis in serious contention when you need:
Extremely hot counters or request-by-request rate limiting.
Automatic memory-bounded eviction as a core requirement.
High-frequency ephemeral state where additional Postgres load would threaten durable workloads.
Redis-specific data structures such as sorted sets, streams, or probabilistic structures that materially simplify the problem.
A cache deliberately isolated so a traffic spike cannot consume primary-database capacity.
Redis Streams further complicates any blanket replacement claim. Current Redis documentation supports ordered streams, multiple consumer groups, horizontal consumers, at-least-once processing, historical replay, and retention controls.
The right question is therefore not “Can SQL imitate this?”
It is: Does Postgres satisfy the latency, throughput, isolation, eviction, and semantics our actual application requires with less total complexity?
That is a much harder question, and it is the useful one.
The Neon Case Study: A Parallel Example, Not Direct Proof
A strong named consolidation example is Neon's July 17, 2025 Vecstore case study.
It is also easy to misuse.
Vecstore had relational data in AWS RDS and vector search in Pinecone. Neon reports that the company consolidated both into Postgres with pgvector, reducing the number of database systems and, in its reported workload, lowering latency from roughly 200 ms to 80 ms.
What the Neon case supports | What it does not prove |
Fewer data systems can reduce integration overhead | PostgreSQL beats Redis as a cache |
Cross-system network calls can dominate observed latency | SKIP LOCKED beats dedicated queues at scale |
Small teams can value one operational model | Every specialist database should be removed |
Postgres extensions expand consolidation options | Redis-to-Postgres migration is a 2026 industry trend |
The Vecstore founder described separate databases as creating cost, performance, and developer-experience friction, and Neon says the consolidated approach removed synchronization paths between relational and vector data.
That is directly relevant to the philosophy of database consolidation backend architecture.
It is not direct evidence for caching or background jobs.
I would reject an architecture document that cited “Vecstore replaced Pinecone” as proof that our Redis rate limiter should move into Postgres. Those are different workloads with different ceilings.
The defensible inference is narrower: when a specialized system causes integration and operational overhead, it is rational to test whether a capability in the database you already operate satisfies the requirement well enough.
That is the same decision framework applied to a different box.
What You're Actually Trading Away
Deleting infrastructure is not free. You are trading specialization for consolidation.
Redis is optimized around in-memory data structures and has built-in eviction behavior. Dedicated message systems can offer combinations of routing, consumer groups, dead-letter policies, delayed delivery, partitioning, replay, independent scaling, and managed durability that a home-grown queue table does not automatically acquire.
Postgres gives you something else: transactions, SQL, constraints, familiar backup/restore procedures, one data model, and the ability to make business-state changes and queue/cache mutations part of the same database transaction.
You gain | You give up or concentrate |
One transactional boundary | Workloads compete for database resources |
Fewer credentials and clients | Bigger blast radius when Postgres is unhealthy |
Fewer state-sync paths | Less independent scaling |
SQL observability | Specialist queue/cache features |
Simpler local development | Greater responsibility for schema/index maintenance |
Potentially fewer managed services | More pressure on Postgres connection and I/O capacity |
This is why “boring technology” should not mean “primitive technology.”
A boring architecture is one whose failure modes the team can explain. A naïvely consolidated architecture that pounds the primary database with cache churn, queue polling, and business queries is not boring; it is a resource-contention incident waiting for a Friday evening.
Another tradeoff is organizational. When Redis or the queue is separate, different workload classes naturally have capacity boundaries; once everything lands in Postgres, engineers must recreate those boundaries through connection pools, worker concurrency limits, schemas, indexes, resource sizing, replicas, or even separate Postgres instances.
There is also a category error worth avoiding. Whether your API uses REST or GraphQL has little to do with whether the infrastructure beneath that API should use Redis, Postgres, or a queue.
Refonte already has a separate guide to GraphQL vs. REST for API architecture, published around an API-layer decision. That article discusses request and data-fetching semantics; the decision here is the persistence, caching, and background-processing architecture under those endpoints.
Keeping those layers conceptually separate prevents this piece from turning into another generic “choose your backend stack” roundup.
Where This Fits Alongside the Site's Existing Vector-Database Story
Refonte Learning already published the Postgres vector database consolidation story on August 14, 2026.
That article covers the vector-database market: pgvector, Pinecone, Weaviate, Qdrant, LanceDB, acquisitions, vector support becoming available across established data platforms, and the circumstances in which a specialized vector database must justify another architectural boundary.
This article is deliberately not that article.
Here the competing boxes are Redis-like cache infrastructure and background-job/message-queue infrastructure. The technical mechanisms are unlogged/cache tables, transactions, SKIP LOCKED, LISTEN/NOTIFY, pgmq, and pg_cron.
There is conceptual overlap, but repeating the vector-market story would cannibalize an existing Refonte topic while failing to answer the backend operator's actual question.
Same Database, Two Different Consolidation Arguments
The two articles share one principle:
Before adding a specialized stateful service, prove that the workload requires specialization.
The implementation arguments are otherwise distinct.
Existing vector article | This caching/queueing article |
Vector embeddings | Cached application state |
Approximate nearest-neighbor search | Fast key-based reads |
pgvector | Unlogged tables / SQL |
Pinecone and vector specialists | Redis and cache infrastructure |
AI retrieval workload | General backend workload |
Separate AI Engineering CTA | Backend Development foundation |
Vector indexing tradeoffs | Queue, cache, locking, and transaction tradeoffs |
That distinction also mirrors Neon's case study correctly. Vecstore is a parallel demonstration of consolidation economics and developer experience, not a Redis or queue migration case.
The distinction matters because “Postgres for everything” is useful only while the word everything remains subject to measurements.
Performance Ceilings: When Postgres Genuinely Isn't Enough
Every consolidation strategy eventually runs into the reason specialist systems exist.
Redis's rate-limiter documentation, for example, describes every service instance consulting a shared Redis store for an allow/deny decision and characterizes the target path as sub-millisecond. It combines atomic operations such as increment and expiration specifically for this kind of high-frequency ephemeral state.
That is not the workload where my first recommendation would be “put another write into the primary relational database.”
Likewise, if you need a durable event log that many independent consumer groups replay on their own timelines, a simple jobs table is solving a different problem. Redis Streams itself already supports multiple independent consumer groups and historical replay, while dedicated streaming platforms take those requirements much further.
Requirement | Postgres-first fit | Specialist likely justified |
Email/report jobs at moderate volume | Strong | Not automatically |
Transactionally enqueue after DB write | Strong | Broker may still be downstream |
Disposable cache for modest workload | Plausible | Measure first |
Request-path rate limiter | Weak to workload-dependent | Redis often compelling |
Massive fan-out/replay event log | Weak | Streaming platform |
Cache requiring automatic eviction under memory pressure | Awkward | Redis |
Workload needing independent horizontal scaling | Limited by chosen PG architecture | Specialist often clearer |
Business and queued state must commit atomically | Excellent | Otherwise use outbox/coordination |
Postgres queues also generate database work that real brokers avoid in different ways: row updates, index churn, dead tuples, vacuum activity, connection usage, and contention around hot queue indexes.
SKIP LOCKED prevents workers from serializing behind one another, but it does not suspend the laws of storage-engine maintenance.
Cache tables have similar economics. Every miss that repopulates Postgres and every invalidation that updates or deletes a cache row consumes the same broad database resources needed for durable transactions.
That is why I do not evaluate postgres instead of redis using a microbenchmark that runs both on a laptop and declares a winner based on median latency.
I care about the workload envelope: peak request rate, p95 and p99 latency, cache hit ratio, queue depth, jobs per second, write amplification, vacuum behavior, database CPU, I/O, connections, recovery characteristics, and what happens during failover.
Signs You've Actually Hit the Ceiling
Architecture should graduate to a specialist because measurements force the decision, not because a diagram “looks scalable.”
Signals I would take seriously include:
Queue lag rises even after worker concurrency, indexes, claim batching, and database sizing are tuned.
Cache traffic is a material fraction of primary database CPU or I/O and threatens transactional SLOs.
Connection demand from listeners and workers crowds out application traffic.
Required latency is consistently below what the Postgres path can deliver at peak load.
The application needs replay, routing, fan-out, ordering, or consumer semantics that are becoming awkward custom SQL.
A Redis workload depends heavily on automatic eviction, sorted sets, streams, or very hot atomic counters.
The key phrase is after measurement.
If a team can run the application reliably on one Postgres service and the busiest queue has twelve jobs waiting, introducing a distributed streaming platform “for future scale” is usually not architecture maturity. It is prepaying complexity.
The reverse is equally true. If the queue has millions of pending events, dozens of independently replaying consumer groups, and strict partition ordering, refusing to leave Postgres because “fewer moving parts” sounds elegant is architecture ideology.
Migration Path: How Teams Actually Make This Switch
Do not migrate Redis, your scheduler, and your queue in one release.
The safest consolidation work I have seen behaves like a strangler migration: choose one low-risk workload, instrument both sides, establish rollback, and move the next component only after the first has boring operating history.
For queueing, first classify what the “queue” actually does. Background jobs, domain-event distribution, webhook buffering, durable streams, and asynchronous RPC are frequently lumped together even though their requirements differ.
A useful inventory looks like this:
Question | Why it matters |
How many jobs per second at peak? | Determines throughput requirement |
How long can work wait? | Establishes acceptable queue latency |
Must messages be replayed? | Separates job queue from event log |
Can jobs run twice? | Drives idempotency requirements |
Is ordering required? | Changes claim and partition design |
What is the retry policy? | Must be reproduced before cutover |
Are there dead-letter workflows? | Avoids losing operational tooling |
Does enqueue need to be atomic with DB state? | Strong argument for Postgres |
Build the Postgres queue beside the existing broker first. Do not immediately send real side effects through two independently executing consumers unless duplicate execution is harmless.
For cross-system migration, a transactional outbox can also provide a safe bridge. Debezium's documentation describes storing an event in an outbox as part of the same transaction as application state and then relaying it asynchronously, specifically to avoid unsafe database-plus-broker dual writes.
For caching, use shadow measurement rather than ideological cutover.
Read from the existing Redis cache, compute what the Postgres cache would have returned, compare hit behavior and latency, and measure database impact. Only then move a percentage of traffic.
Scheduled jobs are often simpler. Replace one low-risk external cron task with pg_cron, verify execution history and alerting, then proceed to another.
The migration goal is not “delete infrastructure by Friday.” The goal is to make every deletion reversible until the simplified architecture has proven itself.
What to Move First, and What to Leave Alone
My default order is intentionally conservative.
Move first:
Database housekeeping and simple pg_cron scheduled jobs.
Low-volume background jobs already tightly coupled to database state.
Rebuildable caches whose latency requirement is modest.
Jobs for which atomic database-and-enqueue behavior removes a known failure mode.
Leave alone initially:
High-traffic distributed rate limiters.
Redis workloads built around sorted sets or streams.
Event buses with many independent consumers and replay.
Latency-sensitive caches protecting an already saturated database.
Anything you cannot currently benchmark or roll back.
The order matters because infrastructure consolidation should reduce operational risk during the migration, not temporarily triple it.
I also keep the old service available through at least one meaningful peak cycle unless infrastructure cost makes that impossible. A queue architecture that works Tuesday morning and collapses during month-end reconciliation has not passed validation.
Operational Tradeoffs: One Database to Monitor, One Database to Break
Consolidation removes failure boundaries and expands another one.
With Postgres, Redis, and a broker, Redis can fail while the durable database survives. With Postgres doing all three jobs, a Postgres incident can affect canonical data access, cache operations, scheduled work, and background processing simultaneously.
That is a genuine downside, not a footnote.
Operational dimension | Three-system stack | Consolidated Postgres stack |
Number of systems to monitor | Higher | Lower |
Cross-system consistency risk | Higher | Lower |
Failure isolation | Better by default | More concentrated |
Backup/recovery expertise | Multiple systems | Mostly one |
Capacity isolation | Natural | Must be engineered |
Credential/network complexity | Higher | Lower |
Postgres blast radius | Smaller | Larger |
The counterargument is that three independent systems also create three independent failure modes. During an outage, simplicity can be powerful because one connection test, one transaction history, and one queryable source of truth answer more questions.
The architectural move I like is logical consolidation before reckless physical consolidation.
You can standardize on PostgreSQL-backed mechanisms without insisting every workload compete on the exact same undersized instance. A high-volume queue can ultimately have its own Postgres deployment while preserving familiar SQL and queue semantics; at that point you have surrendered some cost simplicity but kept operational standardization.
Connection management becomes especially important. LISTEN uses a persistent session, workers need database connections, API requests need connections, and scheduled work adds more execution demand; a queue migration that ignores connection budgets can fail long before disk or CPU becomes the bottleneck.
Observability should therefore be part of the design, not an afterthought.
For queues, I monitor ready depth, oldest-ready age, processing duration, attempt count, timeout/requeue count, failure count, and completed throughput. For caches, I care about hit ratio, lookup latency, rows/bytes, expiry backlog, database CPU impact, and whether cache writes materially increase vacuum pressure.
The senior-engineer lesson is that deleting Redis from a Terraform file does not delete the responsibilities Redis was handling. You either discover that those responsibilities were unnecessary, or you deliberately re-home each one.
Backend Developer Salaries in 2026
The architectural skill in this article is also a good example of why senior backend work is more than writing endpoints.
As of August 9, 2026, Indeed's U.S. backend developer salary 2026 page reports an average base salary of $161,746 per year, based on approximately 3,600 salaries from job postings over the previous 36 months. Indeed lists a low of $99,747 and a high of $262,281.
Those numbers should not be confused with an entry-level guarantee, global salary expectation, or the Refonte program's own marketing figure.
Figure | Source | What it represents |
$161,746/year | Indeed, updated Aug. 9, 2026 | U.S. average base salary in Indeed's dataset |
$99,747–$262,281 | Indeed | Reported low-to-high range |
~$3,600 salary records | Indeed | Job-posting salary sample over 36 months |
$74,500+ | Refonte program page | Program's cited starting salary figure |
Refonte's Backend Development page markets a $74,500+ starting salary and roughly 105,000 annual job openings for the program's career path. Those are the site's own marketing claims; they are not the same statistic as Indeed's U.S. market average, and I would not present the difference as evidence that one source is “wrong.”
A starting-salary figure and a market-wide average across experience levels answer different questions.
The more relevant career takeaway is qualitative: architecture decisions such as deciding when a cache or queue deserves its own distributed system are part of the judgment that separates “I can build an endpoint” from “I can own this service in production.”
Building This Foundation: The Refonte Learning Backend Development Program
Nobody starts by debating SKIP LOCKED visibility semantics.
You first need to understand server-side execution, SQL, data modeling, transactions, APIs, authentication, testing, deployment, and debugging well enough that the consolidation tradeoff makes sense.
That is the honest connection to the Refonte Learning Backend Development Program.
As verified on the live program page on August 19, 2026, the program runs for three months at 10–12 hours per week. Its eight published curriculum areas are Introduction to Backend Development; Node.js & Express; Database Management: MongoDB & SQL; RESTful APIs & Microservices; Authentication & Authorization; Testing & Debugging; deployment with Docker and cloud platforms; and a Capstone Project.
Program detail | Verified live-page information |
Format | 3 months, 10–12 hours/week |
Database module | MongoDB & SQL |
Backend stack | Node.js & Express |
Architecture module | RESTful APIs & Microservices |
Operations | Testing, debugging, Docker, cloud deployment |
Mentor | MSc Sophia Johnson |
Career outcomes listed | Backend Developer, API Developer, Database Administrator |
One-time fee | $300 |
Installments | $204 + $98 |
Prerequisites | Basic programming knowledge; working toward bachelor's degree or higher |
The page names MSc Sophia Johnson as the educational mentor and describes her background in software engineering, backend frameworks, databases, and cloud infrastructure. It lists a $300 one-time enrollment cost, with installment payments of $204 and $98; the Backend Development program card shows $300 against a $387 list price and a 30% discount.
Prerequisites need equally precise wording. The program specifics state a basic understanding of programming concepts, while the admissions section says applicants must be working toward a bachelor's degree or higher-level degree.
The curriculum gap is worth saying plainly: the published database module says MongoDB & SQL. I found no mention on the live curriculum of PostgreSQL specifically, SKIP LOCKED, LISTEN/NOTIFY, pgmq, pg_cron, Redis replacement, or Postgres-native queue design.
So the responsible CTA is not “take this program and you will learn the architecture in this article.” It is that database fundamentals, backend service behavior, APIs, testing, debugging, and deployment are the foundation from which developers become capable of evaluating this architecture themselves.
That distinction is especially relevant to this topic because the whole postgres instead of redis argument is about judgment rather than syntax.
You can memorize FOR UPDATE SKIP LOCKED in thirty seconds.
The harder skill is knowing why two consumers do not claim the same work, why handlers still need idempotency, why NOTIFY should wake a durable queue rather than become the durable queue, why an unlogged table's crash behavior can be acceptable for cache data, why putting cache churn into the primary database can become dangerous, and when a specialized Redis or messaging deployment has finally earned its place.
After more than a decade around backend architectures, that is the pattern I trust most: start with the simplest system that honestly satisfies the requirements, measure it, and add specialized infrastructure only when reality gives you a reason.
Postgres did not suddenly become Redis, RabbitMQ, SQS, and every other backend component in 2026. The core native queue pattern was publicly documented by Crunchy Data in September 2021, Supabase later made Postgres-native queues a first-class product through pgmq, and the 2025 Neon Vecstore case offers a parallel, but not directly equivalent, example of the operational motivation for consolidation.
And as of August 19, 2026, I could not independently confirm a robust newly published 2026 case study or adoption statistic proving a broad Redis-to-Postgres migration wave.
That actually makes the architecture more interesting.
It is not a news-cycle bet. It is an old backend question becoming easier to ask again: does this service solve a problem large enough to justify one more system that has to agree with everything else at 2:17 a.m.?