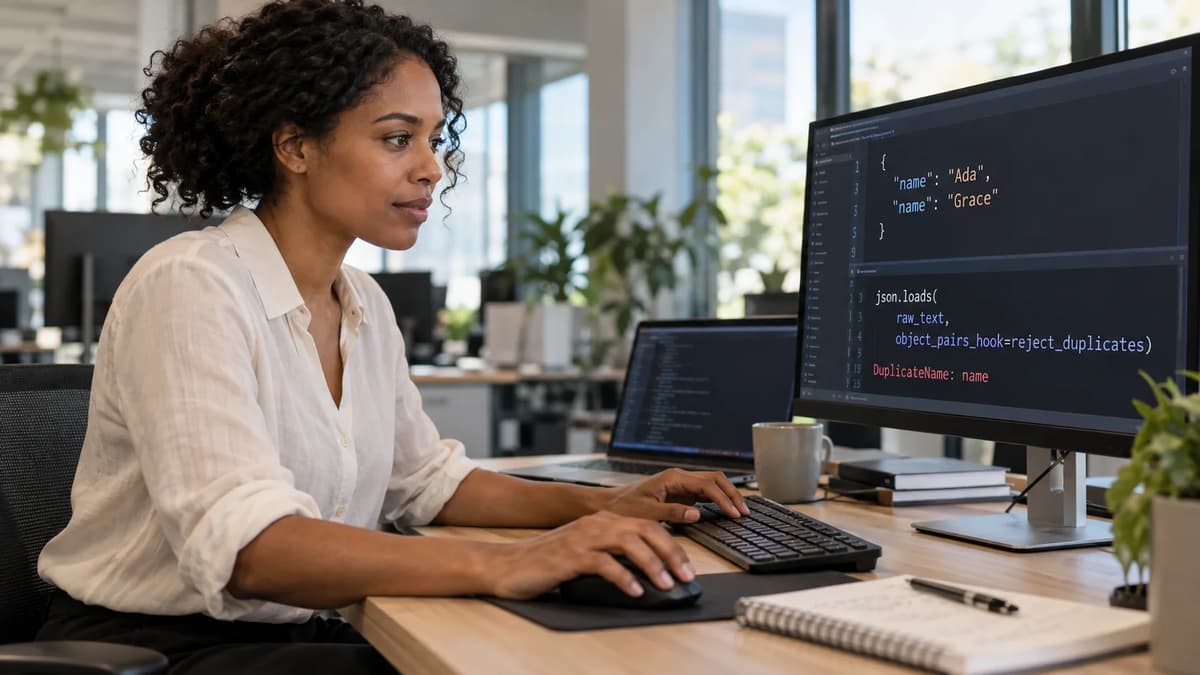
Consider the harmless JSON text {"name":"Ada","name":"Grace"}. Python’s json.loads will parse it without error, yielding the dict {"name": "Grace"}. To a later validation step (for example, a JSON Schema or business-rule check on the “name” field), the value looks valid (Grace) and unique. However, the raw text had a duplicate key “name”, which the application cannot now detect. In other words, a representation gap exists: two different inputs produce the same ordinary dict.
This article declares a duplicate-name policy at the API boundary and tests it locally: either reject repeated keys early, document the chosen alternative behavior, or accept the limitation that the original text’s duplicates are irrecoverably lost. We implement a Python decoder using object_pairs_hook (a feature present since Python 3.1) to catch duplicates in each object.
The full test driver (embedded below) ran successfully on CPython 3.12.14 (documentation shows 3.12.15) with run ID 382841187b6b4ef7ba7115aedd366fd7. The laboratory confirms exactly which JSON texts pass under the “no duplicate keys in one object” policy and shows that after json.loads, any evidence of the duplicate key is already gone.
Define the request-name policy before choosing a decoder
Our declared policy is: reject any repeated member name within a single JSON object. It doesn’t matter if the values are equal; the moment an object literal has the same key twice, we treat it as invalid. (By contrast, repeating the same value in an array or in separate objects is allowed under this policy.)
This mirrors best practices: RFC 8259, the current JSON spec, “SHOULD” keep names unique to avoid ambiguity. The I-JSON profile (RFC 7493) goes further, requiring no duplicates at all: “Objects in I-JSON messages MUST NOT have members with duplicate names. … duplicate means that the names, after processing any escaped characters, are identical”.
We don’t assume all clients follow I-JSON, but an API contract owner must explicitly pick a stance: either allow duplicates (unpredictable), or reject them. In an API-first approach, the owner defines this contract rule and enforces it in the decoder, not as an implicit Python default. (Our hook enforces the policy early; without a hook, json.loads silently collapses duplicates.)
Separate duplicate names from repeated business data
It’s crucial to isolate the notion of a “duplicate name” from business-data repetition. For example, a request with two objects {…},{…} each having a “name” field is fine if those fields appear only once per object.
The hook resets its local storage for each object parsed. By policy, uniqueness is checked per object, not across the whole document or across array elements. We do not treat an array of events as a key-unique set; duplication of values in an array is independent of this policy.
Locate the information loss in ordinary decoding
Ordinary JSON decoding does three steps: tokenizing the raw text, building an intermediate (ordered) list of member pairs per object, and finally merging that list into a mapping (a Python dict). At that merge step, duplicate keys are collapsed. In CPython’s default behavior, the last name/value pair for a given key wins. Thus json.loads('{"name":"Ada","name":"Grace"}') yields {"name": "Grace"}. (As RFC 8259 notes, many implementations do this, though any behavior on duplicates is unpredictable.)
The original count of “name” in the text is no longer in the result. This is an example of representation loss: the parsed object is unambiguous, but different raw inputs could have produced it.
We can link this to the same theme as preserving numeric precision: just as converting 2^53+1 to a float loses the original integer, parsing duplicates loses which value was first or second. See our related discussion on preserving JSON identifier precision. But we return to member names specifically: after json.loads, the application only sees one “name” string. It cannot tell if the original had one or more.
Explain why strict=True does not select this policy
One might wonder if Python’s strict flag covers duplicates. It does not. The strict parameter in json.JSONDecoder only controls whether control characters (e.g. unescaped tabs or newlines) inside strings are allowed. Setting strict=True (the default) disallows bare control chars, whereas strict=False allows them in strings.
Nothing in strict addresses duplicate keys. In fact, both json.loads(raw) and json.loads(raw, strict=True) will collapse duplicates identically (we verify this with our controls). The duplicate-sensitive hook is needed explicitly.
In other words, “strict” mode is not a master switch for all rigorous JSON rules. It won’t prevent the last-wins behavior; it only affects string content validation.
Freeze the raw fixtures and local runtime
We implement the experiment purely locally. The Python version was CPython 3.12.14, built with Clang 22.1.3 (documentation says 3.12.15, but the actual interpreter used is 3.12.14). We did not rely on any third-party libraries or web services, only the standard json module.
The JSON documents under test must be given as raw str literals so that duplicates remain in the raw text. (Generating them from a Python dict with json.dumps first would lose duplicates.) We fix our test corpus of 11 JSON texts (shown below) as UTF-8 strings; each has its SHA-256 hash recorded.
We save the driver code as a script json_duplicate_preflight.py in our working directory and run it directly. Each execution prints a unique output path and writes a JSON report file beside the script. The code is careful: it initializes the report status to “FAIL” and appends each case row before decoding. It only reaches "PASS" at the end if every require-check for verdict and object equality succeeded. This ensures incomplete or aborted runs still preserve partial evidence in the report file (written in a finally block).
For reproducibility, we do not use Python assert (which could be optimized away); instead we use explicit require() checks that raise on failure. The driver’s logic and fixtures (below) are the exact source used in research.
Run the complete eleven-case decoding driver
"""Small local research probe; no HTTP server or framework integration."""
import hashlib
import json
import platform
import sys
import uuid
from datetime import datetime, timezone
from pathlib import Path

CASES = [
    (
        "unique",
        '{"name":"Ada","enabled":false}',
        "ACCEPT",
        {"name": "Ada", "enabled": False},
    ),
    (
        "different_duplicate",
        '{"name":"Ada","name":"Grace"}',
        "DUPLICATE",
        None,
    ),
    ("equal_duplicate", '{"name":"Ada","name":"Ada"}', "DUPLICATE", None),
    (
        "reversed_duplicate",
        '{"name":"Grace","name":"Ada"}',
        "DUPLICATE",
        None,
    ),
    (
        "nested_duplicate",
        '{"settings":{"mode":"safe","mode":"fast"}}',
        "DUPLICATE",
        None,
    ),
    (
        "array_object_duplicate",
        '{"items":[{"id":"A"},{"id":"B","id":"C"}]}',
        "DUPLICATE",
        None,
    ),
    (
        "escaped_name",
        r'{"name":"Ada","\u006eame":"Grace"}',
        "DUPLICATE",
        None,
    ),
    (
        "separate_objects",
        '{"left":{"name":"Ada"},"right":{"name":"Grace"}}',
        "ACCEPT",
        {"left": {"name": "Ada"}, "right": {"name": "Grace"}},
    ),
    (
        "repeated_array_values",
        '{"tags":["x","x"]}',
        "ACCEPT",
        {"tags": ["x", "x"]},
    ),
    (
        "case_sensitive_names",
        '{"Name":"Ada","name":"Grace"}',
        "ACCEPT",
        {"Name": "Ada", "name": "Grace"},
    ),
    ("malformed", '{"name":"Ada",}', "SYNTAX_ERROR", None),
]


class DuplicateName(ValueError):
    pass


def reject_duplicates(pairs):
    result = {}
    for name, value in pairs:
        if name in result:
            raise DuplicateName(name)
        result[name] = value
    return result


def require(condition, message):
    if not condition:
        raise RuntimeError(message)


def main():
    run_id = uuid.uuid4().hex
    output = Path(__file__).parent / (
        "json-duplicate-preflight-" + run_id + ".json"
    )
    report = {
        "run_id": run_id,
        "runtime": sys.version,
        "implementation": platform.python_implementation(),
        "started": datetime.now(timezone.utc).isoformat(),
        "status": "FAIL",
        "stage": "initial",
        "cases": [],
        "controls": {},
    }
    try:
        for case_id, text, expected, expected_object in CASES:
            report["stage"] = case_id
            row = {
                "id": case_id,
                "raw": text,
                "sha256": hashlib.sha256(text.encode("utf-8")).hexdigest(),
                "expected": expected,
                "downstream_calls": 0,
                "status": "FAIL",
            }
            report["cases"].append(row)
            try:
                decoded = json.loads(
                    text, object_pairs_hook=reject_duplicates
                )
            except DuplicateName as exc:
                row["outcome"] = "DUPLICATE"
                row["duplicate_name"] = str(exc)
            except json.JSONDecodeError as exc:
                row["outcome"] = "SYNTAX_ERROR"
                row["error"] = {
                    "type": type(exc).__name__,
                    "line": exc.lineno,
                    "column": exc.colno,
                }
            else:
                row["outcome"] = "ACCEPT"
                row["object"] = decoded
                row["downstream_calls"] += 1
            require(row["outcome"] == expected, case_id + ": wrong verdict")
            require(
                row["downstream_calls"] == int(expected == "ACCEPT"),
                case_id + ": wrong admission count",
            )
            if expected == "ACCEPT":
                require(
                    row["object"] == expected_object,
                    case_id + ": wrong object",
                )
            row["status"] = "PASS"
        raw = '{"name":"Ada","name":"Grace"}'
        report["stage"] = "controls"
        default = json.loads(raw)
        strict = json.loads(raw, strict=True)
        hooks = []

        def record_object(obj):
            hooks.append(dict(obj))
            return obj

        after_hook = json.loads(raw, object_hook=record_object)
        report["controls"] = {
            "default": default,
            "strict_true": strict,
            "object_hook_result": after_hook,
            "object_hook_received": hooks,
            "serialized_after_loss": json.dumps(default),
        }
        require(
            default == strict == after_hook == {"name": "Grace"},
            "last-wins control mismatch",
        )
        require(
            hooks == [{"name": "Grace"}],
            "object_hook was not post-collapse",
        )
        require(
            [row["id"] for row in report["cases"]]
            == [
                "unique",
                "different_duplicate",
                "equal_duplicate",
                "reversed_duplicate",
                "nested_duplicate",
                "array_object_duplicate",
                "escaped_name",
                "separate_objects",
                "repeated_array_values",
                "case_sensitive_names",
                "malformed",
            ],
            "wrong case coverage",
        )
        require(
            all(row["status"] == "PASS" for row in report["cases"]),
            "case failed",
        )
        report["status"] = "PASS"
        report["stage"] = "complete"
    except Exception as exc:
        report["failure"] = {
            "type": type(exc).__name__,
            "message": str(exc),
        }
        raise
    finally:
        report["finished"] = datetime.now(timezone.utc).isoformat()
        with output.open("x", encoding="utf-8") as handle:
            json.dump(report, handle, indent=2, ensure_ascii=False)
            handle.write("\n")
        print(output)


if name == "__main__":
    main()
The code’s logic: it iterates each case, tries to parse with object_pairs_hook=reject_duplicates. If a duplicate key is found, reject_duplicates raises DuplicateName; if the JSON syntax is malformed, json.JSONDecodeError is caught as "SYNTAX_ERROR". Otherwise, outcome is "ACCEPT", storing the decoded object.
The downstream_calls counter is incremented only for ACCEPT cases, simulating that only accepted inputs reach the (mock) business logic.
The script uses require() to check that outcomes match expectations and saves the report file. Notice that even if a failure happens mid-loop, the finally block still writes out the partial report.
Prove what downstream inspection can still see
What do downstream validators (schema, business logic) actually see? In our controls, for the two-name input raw '{"name":"Ada","name":"Grace"}', the defaults produced only {"name": "Grace"}. Using strict=True yielded the same. With object_hook=record_object, the callback received {"name": "Grace"} too. The report logs: default = {'name': 'Grace'}, strict_true = {'name': 'Grace'}, and the object_hook output is the same dict; its hooks list contains just [{"name": "Grace"}].
Re-serializing default gives the string {"name": "Grace"}. After the parse, every operation (iterating keys, counting them, dumping again) shows only one “name”: the second value. There is no trace left of the duplicate key.
Thus a validator seeing only the resulting mapping cannot determine whether the original had one or two “name” fields. It might assume uniqueness by default, but that assumption has no evidence. The only way to know would have been to hook into the parse before collapse. We emphasize: the successful decode boundary must remain clear; we mark accepted vs rejected here, and then hand off the clean dict for further validation.
Keep the successful return boundary explicit
Our driver simulates handing the parsed object to “downstream” code by incrementing downstream_calls on ACCEPT. DUPLICATE or SYNTAX_ERROR cases leave downstream_calls = 0. This explicitly models that on rejection (either duplicate-name or syntax error), the application logic never sees the object. (We do not pretend to make an HTTP response in this lab.)
The counter simply shows whether the object was returned by json.loads. No business action is performed, but this clear boundary ensures we don’t confuse “JSON parsed but invalid” with “JSON valid and passed to business logic.” Any framework would similarly stop processing on error.
This clarity also matters for observability: an API should log or categorize a syntax error differently from a contract violation. We link API security and observability foundations to note that errors (invalid inputs) should be traced carefully without leaking raw sensitive values. (In production, one should avoid echoing client data in error messages; our report is internal evidence only.)
Reject nested repetition within the correct object
Our custom reject_duplicates hook runs on every JSON object literal, including nested ones and those in arrays. It creates a fresh local dict result for each object. If a nested object has a repeated name, the hook will catch it just the same.
For example, in the nested_duplicate case, the inner {"mode":"safe","mode":"fast"} triggers a DuplicateName on the second “mode”. As soon as any duplicate is found in an object, an exception aborts the parse of that object (and propagates out). Thus, if the duplicate is in a nested object, the whole load fails and no further objects or top-level values are returned.
This keeps scope local: a duplicate in one object does not affect other objects, since each object’s dict is separate. (We do not try to collect all duplicates in a doc; we stop at the first.)
The important point is that duplicates are detected exactly where they occur, even deep in the structure. If such a DuplicateName is raised, earlier object pairs remain partially added, but the final outcome is that json.loads never returns, so no partially-filled data leaks out.
Compare decoded names rather than their escape spelling
Our policy enforces uniqueness on the JSON names after decoding escapes, consistent with I-JSON’s definition. For instance, "\u006eame" in JSON is equivalent to the string "name" (since \u006e is n).
In the escaped_name case, the raw input is r'{"name":"Ada","\u006eame":"Grace"}'. Python first decodes "\u006eame" into "name" and "Ada"/"Grace" remain strings. Now the two keys are both "name", so the hook rejects it. (If we naively compared raw strings, we might think “name” and “\u006eame” differ, but the actual JSON string values are the same.) This matches the I-JSON rule that compares after escape processing.
Our test reports "duplicate_name": "name" in that case: it shows the decoded key. We do not regenerate or normalize the input; the SHA256 in the report is of the original UTF-8 text (it’s not the Unicode sequence hash). This preserves the exact input in evidence.
Preserve the literal escape in the test input
Our fixture for escaped_name literally includes the \u006e sequence in the JSON string (because it’s a raw literal in our Python code). In the report, row["duplicate_name"] will be the Python string "name". But the SHA-256 hash and the raw string printed under "raw" still contain "\u006eame".
We did not transform the input. The hook’s exception reports the logical name, but the saved raw text (and its hash) confirm exactly what was sent. Don’t try to recover the \u006e; it is expanded during parse. The key point: duplicate detection is based on logical equality, not textual equality.
Keep legitimate repetition inside the acceptance set
Some inputs contain repetition that is not a duplicate-name violation under our rules. Our test cases for separate_objects, repeated_array_values, and case_sensitive_names illustrate this. In separate_objects: "name" appears in each of two different objects (left and right), but that’s fine, since uniqueness is per object.
In repeated_array_values, the array ["x","x"] has repeated value “x” but no object member is repeated. In case_sensitive_names, the keys "Name" and "name" differ by case; Python (and JSON) treats keys case-sensitively, so they are distinct names.
All three of these cases are ACCEPTED. We double-checked that the decoded objects match our expectations. This underscores that the hook only enforces exact key-name uniqueness, without any normalization. If an application wanted to treat "Name" and "name" as a conflict (for example by lowercasing all keys), that would be an additional policy outside our scope. By default we do not alter case or apply Unicode normalization.
Likewise, even if two keys had the same value string, we still reject it: {"name":"Ada","name":"Ada"} is DUPLICATE. Equal values do not make the names “different”.
Apply schema checks after unambiguous decoding
Once json.loads succeeds without triggering our DuplicateName, we have a clean object with unique keys. At that point, any ordinary validation (schema, type checks, business rules) can proceed unmodified. For instance, a JSON Schema might check that "enabled" is a boolean and "name" is a string or one of an enum. We emphasize that this article is about the decoding step only. In practice, you would now pass the decoded object to your schema validator or other checks.
For example, see Refonte Learning’s article on JSON Schema object-contract validation, which shows how to use Draft 2020-12 validators for “allOf” rules, additional/unevaluated properties, etc. That piece focuses on absence or presence of allowed fields in the object. Here, we simply ensure the input meets the data model requirement of no duplicate properties.
The remaining validations (required fields, types, business enums) are separate and unchanged. An object that is “ACCEPT” under our test might still fail a schema check; our counter would then be incremented (or an error thrown), but that’s beyond this decoder’s concern.
State what a mapping-level validator cannot prove
A schema validator (or any code working only with the final dict) cannot retroactively detect the duplicate. If your JSON parser or framework has already converted the body to a dict, it has lost that information.
The JSON Schema draft itself does not define behavior for duplicate-key input (it assumes the instance is an object with unique property names). So a schema-based approach alone cannot enforce “no duplicate keys were in the raw text,” unless the JSON parser it uses already rejected them.
Some libraries or custom schema loaders do reject duplicates, but this is not guaranteed. The only way to apply the rule reliably is at the parser boundary. Otherwise, a downstream validator would see an object with one “name” entry and have no basis to complain. Validating the mapping level is necessary but insufficient to prove the original text had no duplicates.
Classify rejection at the stage that produced it
In our result report, we distinctly label each kind of error by stage. A raised DuplicateName in the hook yields "outcome": "DUPLICATE". A parse error (caught JSONDecodeError) yields "SYNTAX_ERROR". Any other exception would be a harness failure, not an expected category. This distinction helps with observability: a duplicate-key error is a data-contract violation, whereas a JSON syntax error is a different issue.
In an actual API, you might turn "DUPLICATE" into a 400 Bad Request with a message about “duplicate JSON field names not allowed,” while "SYNTAX_ERROR" might result in 400 with “malformed JSON”. We do not prescribe the HTTP status or format (that’s up to the API). We only record structured evidence.
As best practice (see API security and observability foundations), raw input should not be logged to clients; our report is private. For example, the report might log the specific duplicate field name internally, but an HTTP error response could be generic (“Invalid request format”) to avoid data leakage.
Reconcile all expected cases before calling the run complete
After all cases, the report shows exactly which inputs were accepted or rejected. In our research run, all eleven cases behaved as expected under Python 3.12.14 with this code. The summary matrix is:
Case | Expected outcome | Downstream calls |
unique | ACCEPT | 1 |
different_duplicate | DUPLICATE | 0 |
equal_duplicate | DUPLICATE | 0 |
reversed_duplicate | DUPLICATE | 0 |
nested_duplicate | DUPLICATE | 0 |
array_object_duplicate | DUPLICATE | 0 |
escaped_name | DUPLICATE | 0 |
separate_objects | ACCEPT | 1 |
repeated_array_values | ACCEPT | 1 |
case_sensitive_names | ACCEPT | 1 |
malformed | SYNTAX_ERROR | 0 |
The first column is the test ID, the second is the policy verdict, and the third is whether the mock “application” logic ran (1 for yes, 0 for no). In that run, each row’s status was PASS. This only reflects our fixed test set; a different Python version or code change would have to be retested.
If any case had failed (or been missing), the report would show "status": "FAIL" for that row and the entire run would end with status FAIL. We do not ignore partial runs or substitute results; the unique run_id and output file capture exactly what happened.
A reported PASS means “under these specific inputs and environment, the behavior was as declared.” It is not a universal certificate; future changes need fresh reports.
Preserve incomplete and failed-run evidence
All evidence is recorded: run ID, Python version, each case’s raw text, hash, expected vs actual outcome, and the exception type and message on failure. This ensures auditability of the test.
We do not automatically remove or overwrite a failed report. If a new test run fails unexpectedly, that failed report remains as evidence of the mismatch (and would need investigation). The pass/fail in the report is authoritative for that run. Thus, any discrepancy in a case indicates a true difference from expectation, not just a logging quirk.
Move enforcement before an adapter discards the pairs
In a real API, this decision point is key: who parses the JSON? If you control the parsing step (for example in a Flask/Django view with json.loads), you should call json.loads(raw_text, object_pairs_hook=reject_duplicates) before handing the data off.
If you are using a framework that by default consumes request.get_json() or similar, you may need to replace or customize that adapter. If the adapter itself has already built the dict (discarding duplicates), then it’s too late to detect repeats; you have lost the information.
In that case, you can only rely on the claim that the client must have followed the no-duplicates rule, but you cannot prove it. We do not recommend trying to replay or repair the request (for example, taking the last value and adding a duplicate key later would change semantics).
The safest approach is: ensure the raw body is decoded under the duplicate-aware policy. (Note: unlike the Protobuf relay problem, we aren’t reconstructing unknown fields; we’re explicitly refusing to let duplicates through.)
If the client must sometimes send duplicates by legacy need, a new contract should be negotiated. But if the policy is to forbid them, an invalid request must be corrected by the sender.
Assign the parser boundary and rollout decision
The choice of duplicate policy is an API owner decision, and it must be clearly communicated to clients. Likewise, the integration or middleware owner must decide where to put the duplicate-aware parser, essentially, which function call marks the JSON boundary. Quality assurance owns the test corpus and verifies the report.
If you change from “lenient” to “strict” (reject duplicates), client requests that formerly passed might start failing. That is a breaking change. Therefore, document this change in release notes, consider a compatibility shim or versioning (for example, a new minor API version), and test actual framework adapters.
Keep this rule separate from other JSON concerns (size limits, depth limits, special number formats). This hook only addresses key uniqueness. It does not validate numeric ranges, enforce UTF-8, nor check application-specific requirements. Those remain downstream.
Build API testing habits around explicit request contracts
Always validate the literal request contract as early as possible. Use tools (including custom hooks) to catch structural issues before business logic or schema enforcement. In our example, we explicitly check for duplicate names while the parser still has the list of pairs. After that, we let a schema or code validate the resulting object normally. This disciplined approach builds confidence by decoding under a strict contract and then checking fields.
For further learning on API testing, error handling, and practical development, see Refonte Learning’s APIs Developer Fundamentals program. It covers API design and testing competencies like schema validation, error-handling best practices, and more in hands-on projects.
By applying these habits (explicit contracts, clear error classification, and thorough tests), you help ensure your API behaves predictably and safely at the parsing boundary.