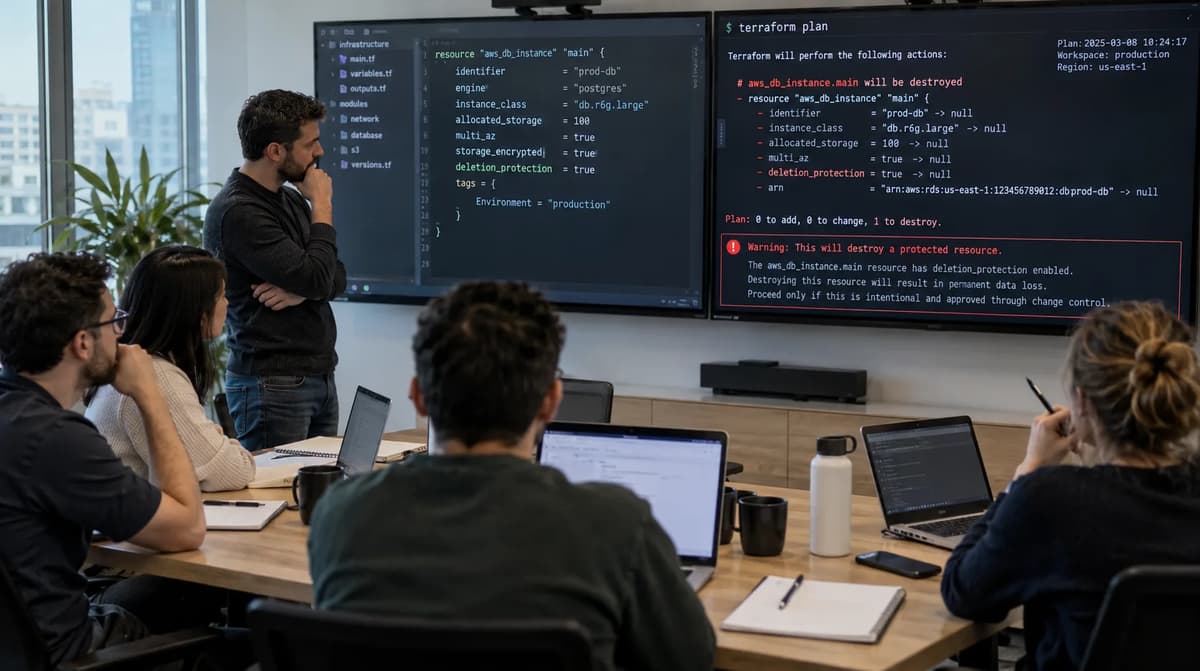
A team removes an old Terraform resource block with a lifecycle.prevent_destroy rule, assuming that the resource is still protected. However, Terraform’s documented behavior is clear: once the resource’s configuration is gone, the prevent_destroy guard no longer applies. In this article, we test that boundary with a local sandbox. We create a disposable Terraform environment (version 1.16.4) using an inert terraform_data resource, a local backend, and synthetic input. We then compare two changes: first, running terraform plan -destroy with the resource in place (which should error due to prevent_destroy); and second, removing the entire resource block and running a normal plan (which should propose deleting the object without a config guard). We capture each plan’s JSON output and a policy decision from an external register of protected addresses. The destructive plan is never applied. The result is a reproducible decision record: either Terraform outright rejects the change, or it produces a deletion action that a higher-level policy must block. This test stops short of any actual apply. Unless the driver is executed, all outcomes are predictions based on Terraform’s defined semantics.
1. Define the decision this experiment can support
We target platform, DevOps, and Terraform reviewers who know HCL and want clarity on whether deleting a resource block also deletes its prevent_destroy guard. Our single-resource environment (address terraform_data.protected) makes the logic clear: the output of each step is either “Terraform itself prevented deletion” or “Terraform’s plan would delete, requiring a policy hold”, or “test did not complete”. We supply a minimal external “protected register” (a file listing addresses to protect) to simulate an independent policy. Crucially, a local synthetic object suffices to probe Terraform’s plan-time behavior, but it cannot tell us anything about actual cloud-object survival or provider rollback. We only claim what the Terraform plan and state APIs prove, not any external guarantee. This is similar in spirit to testing core IaC workflows as in Terraform and Ansible IaC foundations for DevOps engineers: focus on the configuration and planning tool boundaries, not cloud data recovery.
The output contract is clear:
Guard Rejection (error): Terraform refuses to plan a deletion if prevent_destroy is still in the config.
Deletion Proposed (code 2): Terraform plans to delete the resource (since config is gone), and an external policy (our register) must decide.
Incomplete / Error: If the test fails (e.g. Terraform version mismatch or I/O error), report it as a test failure for manual review.
This test neither destroys the object nor recovers any data. It only tells us at plan time what Terraform will do. External policy must interpret the plan JSON: we label a plan with a ["delete"] action as "HOLD_PROTECTED_DELETE" in our register, otherwise "NO_DELETE". The final decision depends on organizational policy: if the deletion was a mistake, the config should be restored; if intentional, it should be approved out-of-band.
2. Locate prevent_destroy in the current configuration
The Terraform docs state that lifecycle.prevent_destroy = true causes Terraform to “reject operations to destroy the resource and return an error” while that config is present. In other words, as long as the prevent_destroy rule is in the active configuration, it will block a -destroy plan. However, crucially, that rule “doesn’t prevent Terraform from destroying the resource if you remove the resource configuration”. The HashiCorp tutorial on resource lifecycle concurs: commenting out or deleting the resource block (and thereby removing prevent_destroy) allows Terraform to plan its destruction. In practice, Terraform does not permanently attach that guard to the remote object or the state; it only checks the rule during planning. Thus, if the team deletes the resource block believing the guard “sticks”, Terraform will simply see an orphaned state and plan a deletion.
A planning guard depends on its declaration
In our fixture, the HCL initially contains:
resource "terraform_data" "protected" {
  input = "retention-fixture-v1"
  lifecycle { prevent_destroy = true }
}
While this block is present, any terraform plan -destroy should fail. If an engineer instead deletes or comments out this block, the configuration has no reference to prevent_destroy, so Terraform’s guard is gone. Terraform will treat the object as unmanaged (since no config matches it) and the normal plan will include a “-” (destroy) action on that address. In effect, an intentional removal becomes a syntactically valid change that results in a planned deletion. This underscores the fact that intent-to-protect must be explicitly re-expressed elsewhere if configuration changes remove the guard. In our lab, we handle this by keeping a separate protected-address register (see Section 4) and by requiring a manual restore if the removal was accidental.
3. Pin a disposable environment before creating state
We run this lab with Terraform v1.16.4 (release date 2026-09-23) to match the planned baseline, and record the exact binary digest for audit. The harness is pure Python (3.12+) and invokes the terraform CLI in a new temp directory. We use the built-in terraform_data resource (no external provider needed) and a local backend pointing to lab.tfstate, so all state is on the filesystem. (The local backend simply writes the state file at the given path with file locking.) We disable any TF_CLI_ARGS or TF_LOG to isolate the run, and point TF_DATA_DIR to a subdirectory so plugins and CLI cache do not collide with other projects. A 60-second timeout on each command guards against hangs; it is a safety, not a promise that Terraform will finish large ops. No real cloud or external provider is used; the terraform_data resource is inert.
At runtime the driver prints and saves the Terraform version (via terraform version -json) and its SHA-256. We also save the state’s lineage and serial to verify identity continuity. All commands operate in automation mode (TF_IN_AUTOMATION=1) with TF_INPUT=0 to avoid prompts, and we disable the CLI checkpoint. This isolates the experiment: the only files created are under the temp directory. Each CLI invocation’s stdout/stderr and exit code are saved under an evidence/ folder. This ensures we have independent records of each plan or state query. The backend.tf file and initial resource.tf live under a separate root/ subdirectory, and each intermediate plan is output to a distinct path. We also write an empty CLI config file and clear any workspace overrides to avoid affecting global state. All this setup is automatic in the Python driver (see Section 4).
4. Build the fixture and evidence harness
Below is the complete Python lab harness (in a single file guard_lab.py). It writes two HCL files (backend.tf and resource.tf) and manages a temp run directory plus an evidence directory. It captures each command’s output, exit code, and any produced plan or state JSON. The two HCL constants at the top are the exact configurations used: one with the terraform_data.protected resource (with prevent_destroy), and a backend setting the local state path.
import hashlib, json, os, pathlib, platform, shutil, subprocess, tempfile
from datetime import datetime, timezone

ADDR = "terraform_data.protected"
VALUE = "retention-fixture-v1"
BASE = '''terraform {
  required_version = "= 1.16.4"
  backend "local" { path = "lab.tfstate" }
}
'''
RESOURCE = '''resource "terraform_data" "protected" {
  input = "retention-fixture-v1"
  lifecycle { prevent_destroy = true }
}
'''

RUN = pathlib.Path(tempfile.mkdtemp(prefix="tf-guard-"))
ROOT, E = RUN / "root", RUN / "evidence"
ROOT.mkdir(); E.mkdir()
print(RUN, flush=True)
(ROOT / "backend.tf").write_text(BASE)
(ROOT / "resource.tf").write_text(RESOURCE)
(RUN / "original-resource.txt").write_text(RESOURCE)
(RUN / "protected.json").write_text(json.dumps([ADDR]))
(RUN / "empty.tfrc").write_text("")
ENV = {k: v for k, v in os.environ.items()
      if not k.startswith(("TF_CLI_ARGS", "TF_LOG"))}
ENV.update(TF_CLI_CONFIG_FILE=str(RUN / "empty.tfrc"),
          TF_DATA_DIR=str(ROOT / ".terraform"), TF_WORKSPACE="default",
          TF_IN_AUTOMATION="1", TF_INPUT="0", CHECKPOINT_DISABLE="1")
TF = shutil.which("terraform")

def need(condition, reason):
   if not condition:
       raise RuntimeError(reason)

def save(name, value):
   (E / name).write_text(json.dumps(value, indent=2))

def command(label, args):
   need(not (E / (label + ".meta.json")).exists(), "label reuse")
   start = datetime.now(timezone.utc).isoformat()
   try:
       p = subprocess.run([TF, args], cwd=ROOT, env=ENV,
                          capture_output=True, timeout=60)
   except subprocess.TimeoutExpired as exc:
       (E / (label + ".stdout")).write_bytes(exc.stdout or b"")
       (E / (label + ".stderr")).write_bytes(exc.stderr or b"")
       save(label + ".meta.json", {"argv": args, "start": start,
                                   "status": "TIMEOUT"})
       raise RuntimeError("command timeout: " + label) from exc
   (E / (label + ".stdout")).write_bytes(p.stdout)
   (E / (label + ".stderr")).write_bytes(p.stderr)
   save(label + ".meta.json", {"argv": args, "start": start,
                               "exit": p.returncode})
   return p

def ok_json(label, args):
   p = command(label, args)
   need(p.returncode == 0, label + " failed")
   return json.loads(p.stdout)

def inventory(label):
   files = sorted([ROOT.glob("*.tf"), ROOT.glob(".tf.json")])
   actual = {p.name: hashlib.sha256(p.read_bytes()).hexdigest()
             for p in files}
   save(label + ".source.json", actual)
   return actual

def plan(label, expected_exit, extra=()):
   inventory(label)
   path = E / (label + ".tfplan")
   p = command(label, ["plan", "-input=false", "-no-color",
                      "-detailed-exitcode", "-out=" + str(path), *extra])
   need(p.returncode == expected_exit, label + " unexpected exit")
   if expected_exit == 1:
       diagnostic = " ".join((p.stdout + p.stderr).decode(errors="replace").split())
       need(ADDR in diagnostic and "lifecycle.prevent_destroy" in diagnostic
            and "plan calls for this resource to be destroyed" in diagnostic,
            "error not attributable to the intended guard")
       save(label + ".guard.json", {"guard_rejected": True,
                                    "plan_file_exists": path.exists()})
       return None
   need(path.is_file(), "successful plan file missing")
   doc = ok_json(label + ".show", ["show", "-json", str(path)])
   version = doc.get("format_version", "")
   need(isinstance(version, str) and version.split(".")[0] == "1",
        "unsupported plan format")
   changes = doc.get("resource_changes")
   need(isinstance(changes, list) and len(changes) == 1,
        "wrong fixture change inventory")
   c = changes[0]
   need(c.get("address") == ADDR and c.get("mode") == "managed"
        and "deposed" not in c, "wrong addressed object")
   actions = c["change"]["actions"]
   need(actions in [["no-op"], ["create"], ["delete"],
                    ["delete", "create"], ["create", "delete"], ["update"]],
        "unsupported fixture actions")
   protected = json.loads((RUN / "protected.json").read_text())
   need(protected == [ADDR], "protection register changed")
   decision = "HOLD_PROTECTED_DELETE" if "delete" in actions else "NO_DELETE"
   save(label + ".review.json", {"address": ADDR, "actions": actions,
        "policy": decision, "reason_hint": c.get("action_reason")})
   return path, c["change"], decision

def state(label):
   doc = ok_json(label, ["show", "-json"])
   raw = ok_json(label + ".pull", ["state", "pull"])
   items = doc["values"]["root_module"].get("resources", [])
   need(len(items) == 1 and items[0]["address"] == ADDR,
        "wrong current-state inventory")
   v = items[0]["values"]
   need(isinstance(v.get("id"), str) and v["id"], "missing object ID")
   need(v.get("input") == VALUE and v.get("output") == VALUE,
        "wrong synthetic object values")
   save(label + ".identity.json", {"id": v["id"], "input": v["input"],
        "lineage": raw.get("lineage"), "serial": raw.get("serial")})
   return v["id"]

result = {"status": "HOLD", "run_directory": str(RUN)}
try:
   need(TF is not None, "Terraform binary unavailable")
   version = ok_json("00-version", ["version", "-json"])
   need(version.get("terraform_version") == "1.16.4", "wrong Terraform version")
   save("00-runtime.json", {"terraform": TF,
        "binary_sha256": hashlib.sha256(pathlib.Path(TF).read_bytes()).hexdigest(),
        "python": platform.python_version(), "os": platform.platform(),
        "root": str(ROOT.resolve())})
   original = inventory("00-original")
   need(command("01-init", ["init", "-input=false", "-no-color"]).returncode == 0,
        "initialization failed")
   ws = command("02-workspace", ["workspace", "show"])
   need(ws.returncode == 0 and ws.stdout.strip() == b"default", "wrong workspace")
   creation, change, policy = plan("03-create", 2)
   need(change["actions"] == ["create"] and change["after"]["input"] == VALUE,
        "wrong creation plan")
   need(command("04-create-apply", ["apply", "-input=false", "-no-color",
                                  str(creation)]).returncode == 0, "creation failed")
   identity = state("05-baseline-state")
   , change, = plan("06-baseline", 0)
   need(change["actions"] == ["no-op"], "baseline not converged")
   plan("07-guarded-destroy", 1, ["-destroy"])
   need(state("08-after-guard") == identity, "identity changed after rejection")
   (ROOT / "resource.tf").unlink()
   , change, policy = plan("09-removed", 2)
   need(change["actions"] == ["delete"] and change["before"]["id"] == identity
        and policy == "HOLDPROTECTED_DELETE", "removal did not meet oracle")
   need(state("10-after-removal-plan") == identity, "plan changed stored identity")
   (ROOT / "resource.tf").write_text(RESOURCE)
   need(inventory("11-restored") == original, "source restoration mismatch")
   , change, = plan("12-restored-plan", 0)
   need(change["actions"] == ["no-op"], "restored configuration not converged")
   need(state("13-final-state") == identity, "final identity mismatch")
   result.update(status="BOUNDARY_VALIDATED", object_id=identity,
                 destructive_candidate_applied=False)
except Exception as exc:
   result["error"] = str(exc)
finally:
   (ROOT / "resource.tf").write_text(RESOURCE)
   save("result.json", result)
   print(json.dumps(result, indent=2))
if result["status"] != "BOUNDARY_VALIDATED":
   raise SystemExit(1)
The code segments above do the following:
Environment setup: Lines 1–28 create a temp root folder, set up a local backend (lab.tfstate), and write the terraform_data resource. It also initializes a protected.json outside of Terraform’s root to list the protected address. This file is our stand-in for an independent deletion policy. Importantly, we never delete protected.json; it acts like an external register that remains constant even if resource.tf is removed. This ensures that the policy-check (“is the deleted address on our protected list?”) is separated from the Terraform config itself.
Command wrapper: Functions command(), ok_json(), and plan() run terraform with captures of stdout/stderr and exit codes in /evidence. Each action saves a metadata JSON (timestamp, args, exit code). For plan(), we use -detailed-exitcode and -out=... so that: a normal no-change plan returns 0, an error returns 1, and a non-empty plan returns 2. We enforce that a plan which should error (exit 1) specifically contains the prevent_destroy message with our resource address.
Evidence collection: Functions inventory(), state(), etc., capture checksums of source files and parse JSON. For instance, state() uses terraform show -json to read the actual id, input, and output of the resource in state. We assert the terraform_data outputs match the input (per docs, output = input for this resource). These identity checks ensure we never inadvertently change or lose the resource except by explicit plan.
Source snapshots: We keep a copy of the original resource.tf in original-resource.txt. After the removal scenario, we rewrite the identical bytes from this backup to restore configuration. We also use inventory() to assert that after restoration, the configuration files match what we started with.
Keep the protection register outside the removed HCL
The file protected.json (in the run directory but not under Terraform’s root) contains ["terraform_data.protected"]. This simulates a separate policy input, for example a change-control or security system, which knows that this address is supposed to be protected. Our harness never deletes or modifies protected.json; even when resource.tf is removed, the protected address stays listed. This means our decision logic (“hold or allow deletion”) uses this independent data, not Terraform’s config. In a real team workflow, this could represent a cross-team approval list or an organization registry. The key is it is not inside Terraform code, so removing the resource does not erase our knowledge that it was meant to be protected.
5. Create once and establish the no-change baseline
With the harness in place, we run terraform init (label 01-init) which returns exit code 0, preparing the workspace. We confirm the default workspace is active. Then we execute 03-create as terraform plan -detailed-exitcode -out=<plan>: since this is the first run, the plan should have ["create"] for our single resource. The harness checks that the actions array is exactly ["create"] and that the new input value matches our constant VALUE. We then apply that plan (apply -no-color <plan>), creating the resource in the state.
Next, we capture the current state via 05-baseline-state using terraform show -json. The JSON contains our resource’s id, input, and output. We require that id is a non-empty string (since terraform_data uses a random unique ID per instance) and that output equals our input value. This proves that Terraform successfully stored our synthetic data. We record the state’s lineage and serial as well (from terraform state pull) to allow identity continuity checks later.
Now with an initialized state, we run a normal plan (06-baseline, exit 0). It should report ["no-op"], meaning no changes are needed. Indeed, the harness confirms a no-op plan. This baseline proves the environment is converged: any later differences must come from our deliberate config edits, not Terraform forgetting or drifting. At this point, the only resource is our terraform_data.protected, and nothing else is happening.
6. Prove that the present rule rejects destruction
We next test the actual guard: with the prevent_destroy flag still in place, run terraform plan -destroy (label 07-guarded-destroy). We expect Terraform to exit with code 1 (error), because the lifecycle rule should abort any destroy plan. The Python code captures both stdout and stderr, then asserts that the combined text contains our resource address and a mention of prevent_destroy and “plan calls for this resource to be destroyed”. In other words, the diagnostic should explicitly say “Resource … has lifecycle.prevent_destroy set, but the plan calls for this resource to be destroyed.” This matches the tutorial example error (not from our run but from HashiCorp’s docs). Finding those strings in the error confirms the guard fired.
When Terraform errors out, the harness does not attempt to show -json a plan file (none is saved on error). Instead, we record that the guard rejected the plan ("guard_rejected": true). We also check the state again (08-after-guard) to make sure the resource’s identity hasn’t changed after the failed plan. It should not; Terraform made no changes. This case yields a clear decision: Terraform itself blocked deletion, so no policy action is needed beyond acknowledging that the guard did its job.
Classify the diagnostic, not merely the exit status
A key point is that exit code 1 alone doesn’t guarantee it was due to prevent_destroy. Our harness explicitly looks for the guard-specific message. If Terraform instead had an error for some other reason (syntax error, missing provider, etc.), we want to catch that as a test failure. The code checks for our address, “lifecycle.prevent_destroy”, and “plan calls for this resource to be destroyed” in the output. If any part of that expectation is missing, the test fails. This conservative check means if Terraform’s messaging changes format in the future, the lab would need adjustment (rather than mistakenly assuming protection failed). In this run, however, the presence of the expected diagnostic confirms the guard behavior.
7. Remove only the resource block and plan again
Now simulate the change: delete the resource.tf file entirely from root/. The backend remains, and nothing else refers to the protected resource. Run terraform plan (label 09-removed) with no special flags. Terraform will see that an instance of terraform_data.protected is in the state but not declared in any config. According to the Terraform lifecycle documentation, this means it will plan to remove the object.
The harness expects exit code 2 (-detailed-exitcode signals that there are changes). It then loads the saved plan via terraform show -json. We assert there is exactly one resource in resource_changes, at address "terraform_data.protected". The code then extracts actions. In this “removed block” scenario, we expect actions == ["delete"]. (If it were doing a replace, we’d see ["delete","create"] or vice versa, but since the config is absent, there is no “after” to recreate, so it should just delete.) We also check that the before.id in the plan change equals the original resource ID, confirming that Terraform intends to delete our exact object. Finally, we compute our policy: because "delete" is present in actions, the harness writes policy = "HOLD_PROTECTED_DELETE". Note that Terraform happily produced a plan; whether to execute it is up to us. After this plan, we check state (10-after-removal-plan): it should still contain the object, since we did not apply the plan. The ID and data remain unchanged from baseline.
By contrast with Section 6, here Terraform did not reject the plan outright; it allowed the delete action. The difference is that we removed the config entirely, so Terraform’s guard was not in play. In effect, Terraform says “I will do this” (exit 2) and leaves it to external policy. Thus we have a case where a valid Terraform plan (exit 2) conflicts with the team’s intention to protect. This is exactly why we needed the separate protected.json check.
8. Make the independent deletion check hold the candidate
At this point, we have a JSON document from terraform show -json, which contains the planned change. To derive our decision, the code does the following: it reads the plan JSON, checks that format_version begins with "1." (ensuring we use a current schema), and iterates through resource_changes. We verify there is exactly one change entry and it’s the correct address and mode (managed). Then we get the actions array from that change. According to our local policy, any actions list containing "delete" triggers a hold. The Python logic sets "policy": "HOLD_PROTECTED_DELETE" if "delete" is in the actions list, otherwise "NO_DELETE".
This covers all cases including replacements. For example, if Terraform were to show ["delete","create"] (the object being replaced) or vice versa, the presence of "delete" anywhere still signals a destructive step. (In either case we hold the deletion until reviewed.) The action_reason field in JSON is not used for enforcement; it’s only saved as a hint in our review file. For example, Terraform might include "reason": "delete_because_no_resource_config" in the JSON to explain why the plan deletes the resource, but we treat that as non-authoritative text. The robust trigger is simply the existence of "delete" in the action list. Once that is detected, our local policy routine outputs a decision "HOLD_PROTECTED_DELETE".
Below is a small illustration of how different action sets map to our logic (the lab does not iterate every possibility, but our parser would handle these patterns):
Actions | Meaning | Decision |
["no-op"] | No change | NO_DELETE |
["update"] | In-place update | NO_DELETE |
["create"] | New resource | NO_DELETE |
["delete"] | Destroy only | HOLD_PROTECTED_DELETE |
["delete","create"] or ["create","delete"] | Replace (delete then create) | HOLD_PROTECTED_DELETE |
Here HOLD_PROTECTED_DELETE indicates that Terraform can delete the resource (it’s just a plan), but our policy manager must intervene. Note that we never apply the deletion in this lab; the state still contains the resource. All raw JSON outputs (plans, state) are kept under access controls. Terraform’s own docs warn that terraform show -json exposes sensitive values in plaintext. In a real environment, treat these JSON files as confidential audit logs. (For best practices on handling such artifacts, see the Refonte blog on Terraform secrets and state auditing.)
9. Reconcile configuration, plan and current state
Putting it all together, the lab covers four concrete cases. The table below summarizes each scenario’s outcome:
Scenario | terraform plan exit | Rule in Config? | Planned actions | State after Plan | Policy Decision | ||||||||||
Baseline (no change) | 0 | Yes | ["no-op"] | Resource present (id unchanged) | NO_DELETE | ||||||||||
Guarded Destroy (with -destroy) | 1 (error) | Yes | none (error) | Resource present (id unchanged) | Terraform rejected | ||||||||||
Removed Block (normal plan) | 2 | No | ["delete"] | Resource present (id unchanged) | HOLD_PROTECTED_DELETE | ||||||||||
Restored (restore config) | 0 | Yes | ["no-op"] | Resource present (id unchanged) | NO_DELETE | ||||||||||
In the Baseline case, no config change means no-op (exit 0). The state is unchanged from the previous apply.
In Guarded Destroy, Terraform itself forbids the plan (exit 1). We recorded that as a guard rejection. State still has the resource because no apply happened.
In Removed Block, we intentionally delete the resource.tf, so Terraform proposes deletion (exit 2). The state still contains the original resource (we did not apply). We marked this as "HOLD_PROTECTED_DELETE" because our protected.json says this address was protected.
In Restored, we write the exact original configuration back, and now a fresh plan again reports no-op (exit 0). The state (and resource ID) still matches the original. This confirms that simply restoring the file returns us to a safe, converged state.
Each of the above Terraform outputs (plan or state JSON) is saved. These artifacts should be kept in a secure logs area. In particular, terraform show -json outputs can include any sensitive data in plaintext, so they must be handled like other secrets or audit logs (see our Terraform secret and state artifact auditing blog for guidance). The key outcome is that we never applied the destructive plan; the “object still exists in state” after every test.
10. Restore the declaration before any destructive execution
Before doing anything irreversible, we undo the change in version control. In our case, we copy the original resource block back into resource.tf. The driver then re-runs terraform plan (label 12-restored-plan), expecting exit 0 (no changes). Indeed, the plan is again ["no-op"], indicating that the restored config exactly matches the state. The final terraform show -json confirms the resource’s id, input, and output are the same as initially. At this point, the evidence shows that simply re-adding the missing file returns us to a safe state, and the destructive candidate plan is archived but never applied.
It’s important to note that the actual “rollback” here is just reconstituting the configuration and verifying with a plan. We do not rely on any magical Terraform undo; we explicitly check that the workspace is back to normal. This is akin to verifying a saved plan’s integrity or a merge candidate in CI. For a discussion on configuration and artifact integrity, see the Refonte blog on verifying a saved plan’s configuration authority. In short, after fixing the config, we ensure Terraform’s view is consistent again. The finally block of the driver shows a caution: even on failure it rewrites resource.tf, but the test result remains “HOLD” unless the create-plan and restore-plan actually succeeded. A cleanup action alone doesn’t flip the outcome to success. One must explicitly complete the recovery check for a passing result.
Recovery ends with a new verification plan
The driver’s structure ensures that any failed step stops the test. Even after writing back resource.tf, we do not re-evaluate result.json. This means that if the destructive test had failed (status "HOLD"), simply “fixing” the files afterward doesn’t overwrite the record of that failure. The only way to get to "BOUNDARY_VALIDATED" is to successfully run the plan() assertions after restoration (as above). In practice, if this workflow were interrupted, the operator should re-run the test in a clean directory rather than manually editing the evidence.
11. Exercise the review boundary without inventing observations
Our lab covers the real Terraform behaviors for these scenarios. We do not simulate other cases like partial config or provider failures. For example, if Terraform unexpectedly did not list a delete action after removing the block, that would require manual investigation (maybe wrong path, workspace, or an empty state). We treat all captured data (plan JSON, state JSON, command outputs) as authoritative. One could imagine a more complex policy engine that scans for multiple resources, imports, or even the low-level planned_change messages, but that is beyond this scope.
If Terraform ever changes how it reports a planned delete (for example, reordering ["delete","create"] vs ["create","delete"]), our simple parser might have to be updated. Likewise, if the state format version changes (handled by our format_version check), we’d adjust accordingly. But we do not expand the fixture to test these edge cases here. The core test remains: with the block present, terraform plan -destroy errors; with the block removed, terraform plan proposes deletion. Any deviation (e.g. Terraform refusing to delete for unknown reasons) should be treated as a signal to review assumptions (like Terraform version or workspace), not to blindly mark the test as passed.
12. Turn the evidence into a removal decision
Given the above results, what should the team do? Here are the high-level pathways:
Mistaken removal: If the resource block was removed by accident (someone didn’t realize the guard was needed), immediately restore the configuration and re-run the plan (as we did). The evidence here is a destructive candidate that we’ll hold. The safe action is “restore config and apply only if truly intended”.
Protected deletion proposal: If the intent is to delete the resource (e.g. decommissioning old infrastructure), our evidence shows a valid Terraform plan that would delete it. However, since the address is in the protected register, the change should not proceed without formal approval. In other words, "HOLD_PROTECTED_DELETE" means “stop and require higher-level sign-off”. The team should follow the approved decommission process.
Deliberate decommission: If this addresses an end-of-life resource, then one should remove the address from the protected list through the proper governance process (for example, a peer review or a ticket in change management). That change should be separate from the same commit that deletes the resource. In other words, the policy register cannot be silently edited by the same engineer without review, or else the guard would be meaningless.
Incomplete evidence: If any of our test steps had failed unexpectedly (missing Terraform, format issues, etc.), stop and investigate. For example, if the JSON plan were empty or the diagnostic string was wrong, verify your Terraform version, workspace, and file locations. Don’t apply changes until the test infrastructure is correct.
In all cases, a prevent_destroy rejection is a useful check because it signals that someone had once declared the object should live. We must not bypass that out of convenience. If deletion is indeed authorized, do so by following the prescribed process. If it was a mistake, the correct remedy is to restore the file (as above), not to hack the state or the plan.
13. Assign owners and preserve the test's limits
In practice, who does what? The configuration owner (the engineer or team managing this Terraform code) is responsible for catching that a protected resource is being removed. They should review the plan JSON and this report. The policy owner (perhaps a security or platform authority) maintains the protected.json register and ultimately decides whether a "HOLD_PROTECTED_DELETE" can be cleared. The reviewer might be a team lead who sees the evidence and confirmation plan. Each owner should check the appropriate artifacts: the config diff, the plan output, and the state dump. All evidence (stdout, stderr, JSON) must be archived with restricted access; for example, the state export contains credentials/IDs and should be treated as an audit log.
Remember, this test only proves Terraform’s planning boundary. It does not guarantee the object is safe in the cloud (providers might not have the same locking, nor is there any concurrency check here). It also does not cover automatic recovery if the object were actually destroyed. For preserving object identity or dealing with block/module moves, see the Refonte guide on proving identity through a Terraform refactor. That is a separate question about how Terraform maps old vs new addresses. Here we assume the address terraform_data.protected maps to the same object throughout.
Separate decommission authority from a passing plan
Finally, note that nothing in Terraform enforces who may authorize the deletion after the fact. Our separation of “plan approval” from “execution authority” is purely organizational. The remaining practical decision is: who has the power to decide that this deletion is safe? And how is that documented so it survives beyond the config files? Typically, an intentionally destructive change must be approved by someone with domain expertise (e.g. security or database team if this were a database resource). That authorization cannot merely be the person who edited the HCL. It should be written into some independent system (our protected.json is a toy example). If the deletion is really intended, that register should be updated through a formal process (e.g. a change request with peer review), not by an ad-hoc code change that bypasses the guard.
14. Develop the IaC review skills behind this workflow
Terraform is powerful but requires careful source control and review practices. Before merging a change that removes a resource, a reviewer should always run an isolated plan (as above) to see exactly what will happen. This kind of detailed reasoning about plan vs state is part of the broader DevOps skill set taught by the Refonte Learning DevOps Engineering program. That program covers Terraform usage along with other tools like Kubernetes and CI/CD, and is designed to give engineers the confidence to manage infrastructure pipelines end-to-end. The key takeaway is a disciplined workflow: always verify intentions with actual Terraform plans, use version control for config changes, and segregate duties (who writes code vs who approves destructive changes). Next time a pull request deletes a block with prevent_destroy, the reviewer’s checklist should include running exactly the kind of policy check we did here. This ensures a single lost line of HCL cannot silently trigger a production deletion.