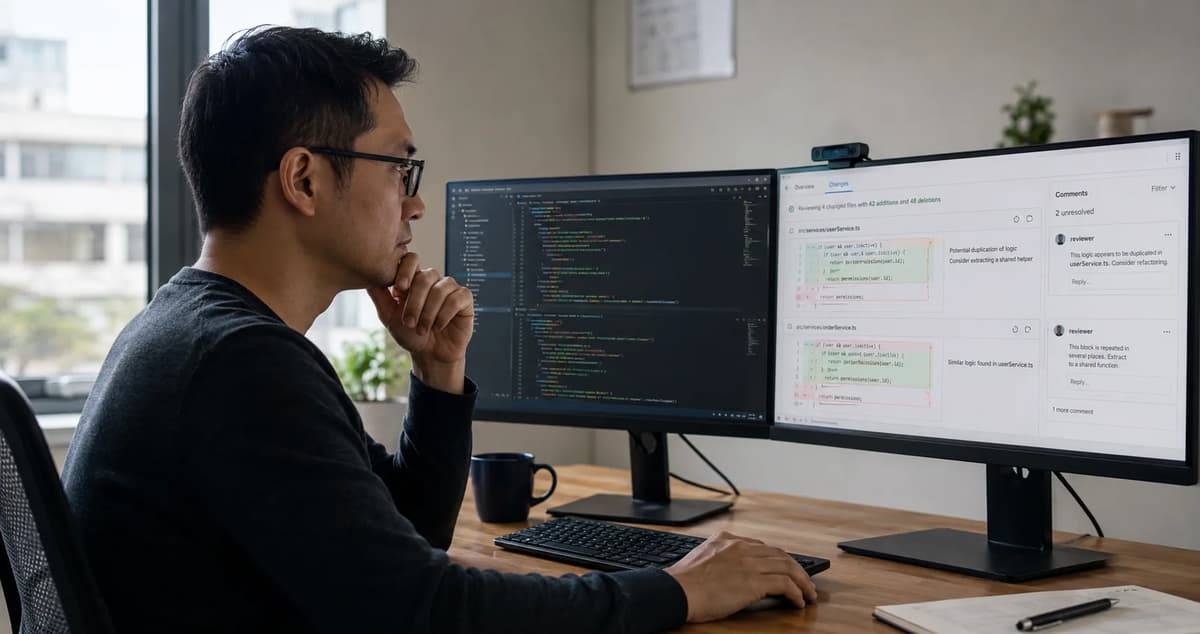
I still remember the day I approved that AI-generated pull request. It looked clean: a chunk of logic, pulled right out of an AI assistant, with passing tests. We merged it into main. Within a month, almost the same code was copied into three other files, unchanged.
No one had refactored the logic into a shared function; nobody wanted to touch the code. As a senior engineer, I knew why: copying the working snippet was faster than stopping to design a reusable abstraction. That scenario is not unique. New data suggests it is part of a larger pattern.
GitClear's 2021–2024 code-quality research and its June 2026 Maintainability Gap report find code duplication rising while purposeful refactoring declines. Other studies show that AI pull requests can be far larger than human-authored ones while still being merged more often. Developer surveys find that people are writing code faster, but some are also feeling the strain.
In this article, we will walk through the numbers and what they mean for code quality. We will present the findings side by side: large productivity claims alongside steep debt warnings, without hiding the contradictions. The point is not to condemn or glorify AI coding assistance, but to show how it changes the way teams must review and maintain code.
With AI tools producing more lines than ever, seasoned judgment in code review and refactoring is more valuable, not obsolete. The Refonte Learning Software Engineering Program includes modules on performance optimization, application security, and scalable software solutions that align with this need. By the end, you will have a balanced view of AI code’s hidden costs and how to manage them.
Approve an AI-written change… then watch near-identical lines show up elsewhere.
Copy/pasted code in our team’s repo rose as refactoring fell, exactly what GitClear data found.
We will break down GitClear’s original and 2026 findings, plus other studies on AI pull requests, churn, trust, and developer experience, step by step.
The Pull Request That Kept Getting Copied, Not Reused
I want to set the stage with a concrete scene. Imagine that a senior engineer, in this case me, merges an AI-generated pull request into the codebase. It contains a neat function that fixes a bug. I assume others will reuse that fix by calling the new function.
A week later, I see three developers paste the same logic into their own branches and merge it independently. No one creates a shared function or refactors the original code. Nobody even files a refactoring ticket. The code is considered “done,” so the fastest path is to copy it.
This scenario may sound hypothetical, but it mirrors the data. Senior developers trust AI tools to crank out code, but in practice, that code often gets duplicated rather than reused. The pattern here is:
Approved AI change leads to clones: An AI assistant gives us a chunk of code. We merge it. But teammates still copy it later instead of refactoring.
Fear of changing golden code: The approved PR feels stable, so developers hesitate to touch it. Instead they paste it and risk going off the original.
Hasty fixes accumulate debt: Each pasted copy is a maintenance time bomb; fix in one place, and you have to fix the others (if anyone notices them).
This is not an argument against AI; those pull requests merged easily. It is a cautionary tale. It highlights a key GitClear insight: as AI-produced code volume rises, purposeful “move” refactoring is being neglected. We saw this on our team, and GitClear’s data identifies the pattern at scale.
Our companion article on Cursor vs. GitHub Copilot adoption numbers shows that both tools are widely used, but raw usage does not guarantee maintainable code.
Quick pull request merges and productivity gains can mask a different reality: AI code arrives faster, but it can require more careful review and consolidation. As code churn rises, a developer’s judgment in refactoring and technical-debt management matters more than ever.
The Original GitClear Finding: Copy/Paste Overtakes Refactoring
GitClear’s landmark 2021–2024 analysis covered 211 million changed lines of code across big tech repos (Google, Microsoft, Meta, and enterprise projects). It found a stark trend: the share of changed lines labeled as “refactoring” plummeted, while the share labeled “copy/paste” climbed. Specifically:
Refactoring fell sharply. In 2021, roughly 25% of changed lines were “moved” code (a sign of deliberate refactoring). By 2024 that had fallen to under 10%.
Copy/paste rose sharply. In the same window, lines classified as direct copy/paste rose from 8.3% to 12.3% of all changed lines.
Copy overtook move in 2024. For the first time, GitClear observed that AI-era commits showed more copy/pasted code than refactored code. The 2024 data were the first on record where within-commit duplication exceeded “moved” code.
Put plainly, pre-AI developers often moved or refactored code, while teams in 2024 pasted code blocks far more often. This aligns with the opening scenario: more duplicate-snippet changes and fewer deliberate refactoring changes. The shift is clearer when the two signals are placed side by side:
2020–2024 data: Across 211 million changed lines, the share associated with refactoring fell from about 25% to under 10%, while copy/pasted changes rose from 8.3% to 12.3%.
First-time overtake: 2024 marked the tipping point: within a commit, copy/paste changes (12.3%) eclipsed moved or refactored changes for the first time.
Commit patterns: This was not just an edge case. Commits containing any duplicated block rose roughly 10× over two years.
These figures describe aggregate repository behavior during the rise of AI coding tools. They do not prove that every duplicated snippet is buggy, and they do not establish AI use as the sole cause. They do suggest a change in how code is integrated: generated output can be merged quickly while similar logic continues to spread instead of being consolidated.
The 2026 Update: “The Maintainability Gap”
GitClear’s June 2026 “Maintainability Gap” report enlarged the lens. Analyzing 623 million changes from 2023–2026, it tracked eight code-quality signals: four “risk” behaviors (duplication, copy/paste, error-masking, churn) and four “reuse” behaviors (refactoring, connectivity, legacy updates). The headline: Maintainability signals are sliding backward as AI output grows. Key findings include:
Refactoring declined 70%: GitClear reported that refactoring line moves were down 70% from 2022 levels. In practical terms, developers were relocating or improving existing code far less often.
Legacy maintenance declined 74%: Long-term updates that touched code older than a year fell 74% from the report’s comparison baseline. Older code was increasingly left unchanged, allowing features to age without consolidation.
Code duplication increased 81%: Code-block duplication increased 81% from 2023 to mid-2026, while copy/paste within individual commits increased 41%. Every additional duplicate expands the surface area a team must maintain.
Error-masking increased 47%: Patterns that hide errors, such as catching and ignoring exceptions, rose 47%. More code may therefore silently absorb failures instead of revealing them.
Short-term churn also increased: Two-week code churn, meaning newly merged code revisited soon afterward, increased 15%. In separate earlier research, GitClear reported about nine times more churn among heavy AI-tool users than among non-users.
These signals present a mixed picture: throughput is high, but many maintainability indicators are moving in the wrong direction. GitClear’s metaphor is that AI can feel like free throughput, delivering happy-path code for a closed ticket while the hidden tax on code health rises. In practical terms, the bill is not due today; it arrives in year two or three, when dozens of duplicated fragments need updates.
For transparency, the reported 70% refactoring decline, 81% duplication increase, 47% error-masking increase, and the later 4–10× durable-code and 9× churn figures are GitClear’s own findings. They were carried over from automated summaries of GitClear’s published reports and were not independently re-derived from the underlying raw data.
Let’s illustrate one of those risk signals: error-masking.
What “Error-Masking” Code Actually Looks Like
When GitClear talks about “error-masking,” think of code patterns that catch exceptions or errors and then do nothing (or swallow errors) rather than properly handling them. For example:
Empty catches. A developer (or AI) might wrap a block in try/catch or except and leave the catch body empty, as if “I assume no errors will happen.” This makes failures invisible.
Silencing returns. Code that logs an error and still returns success can hide downstream bugs.
Catch-all exceptions: Code catches broad types such as Exception or Throwable rather than specific errors, then ignores them.
These patterns tend to multiply technical debt: a suppressed error might bubble up later as a mystery bug. The GitClear report notes a 47% rise in such constructs. In practice, a reviewer might now see more blocks of code with empty or catch-all error handling, which we should scrutinize more than ever.
The Contradiction at the Center of This Data
At first glance, some of these facts seem at odds. On one hand, studies show AI coding agents driving higher merge rates and productivity; on the other hand, the maintainability picture is grim. It is tempting to pick a side (“AI is a boon” or “AI is a bust”), but the truth is both are happening. Consider:
Faster merges versus bigger changes: Popescu et al. reported that Claude-generated pull requests were roughly six times larger than human-authored pull requests, while Copilot-generated pull requests were roughly three times larger. In the same dataset, one agent category reached an 87.5% merge rate, compared with 75.1% for human-authored pull requests. The size gap and the higher merge rate are both true in the data.
Productivity improved while experience became mixed: In a six-month tracking study, 84% of participants reported productivity gains from AI tools. At the same time, the share reporting a worse developer experience on at least one dimension rose from 14% to 27%. Developers could ship faster while also carrying more frustration or cognitive load.
Trust vs. use. The Stack Overflow 2025 Developer Survey highlights another gap: only 3.1% of developers highly trust AI-generated code accuracy, even though 47% use AI daily. Overall, 33% trust AI outputs while 46% distrust them. AI tools are widely used and can support productivity, but most developers remain cautious about code quality.
We have to present both sides. Productivity findings coexist with worrying code signals such as duplication and churn. The contradiction is the story. AI tools can save time without automatically enforcing sound engineering practices.
The technical debt still needs active management. Faster code generation changes the bottleneck: architecture, consolidation, verification, and long-term maintenance demand more attention after the first draft is produced.
AI accelerates the code-generation stage, but architecture and maintenance remain team responsibilities. The organization receives more raw material, which makes the quality-control step more important. That is why reviewing for duplication, not just correctness, becomes a core practice.
To navigate this, no one is arguing for abandoning AI. The message is to use AI while strengthening code review and refactoring discipline. This is not an either/or choice. The following sections show how teams can combine AI productivity with lower maintenance risk.
What the Autonomous Agent PR Data Actually Shows
Let us examine the April 2026 paper Investigating Autonomous Agent Contributions in the Wild. Popescu and co-authors analyzed about 110,000 open-source pull requests created by autonomous coding agents. Several statistics stand out:
AI pull requests are much larger: In the study’s dataset, Claude-generated pull requests were about six times larger than typical human-authored pull requests, while Copilot-generated pull requests were about three times larger. These were aggregate change-size findings, not a claim about every pull request.
Merge rates can remain high: Despite the size gap, one agent category reached an 87.5% merge rate, compared with about 75.1% for human-authored pull requests. The result comes from the study’s open-source sample and should not be treated as a universal rate for every agent or repository.
Long-term maintainability is a separate question: The pull request study establishes size and merge-rate differences; it does not, by itself, prove the long-term quality of those changes. GitClear’s separate analysis reported about nine times more churn among heavy AI-tool users, so the datasets should be read together without being conflated.
Both central pull request findings are true: AI-agent changes were larger, and an agent category achieved a higher merge rate than human-authored pull requests. The evidence does not require choosing one result and ignoring the other. It shows that bulk changes can clear review gates, while leaving open the separate question of how costly they will be to maintain.
Our guide to GitHub Copilot agent mode explained describes how agent mode can propose complete pull requests. Here, the important outcome is that more code is being accepted. The size-versus-merge pattern is nuanced: the pull requests are larger, and they are accepted more often. Teams should not cherry-pick one fact; both shape the review burden.
In practical terms, a team may find itself reviewing very large diffs generated with limited codebase context. A change can be good enough to merge while still demanding close inspection for duplication, security issues, and performance pitfalls. That review burden also affects developer experience.
Bigger PRs, Higher Merge Rates: Both True at Once
The study’s central pull request signals can be separated cleanly:
Change size: Claude-generated pull requests were about six times larger than human-authored pull requests, while Copilot-generated pull requests were about three times larger.
Merge rate: One agent category reached an 87.5% merge rate, compared with 75.1% for human-authored pull requests. The paper does not support assigning that same rate to every agent category.
Together, the findings change the review calculus:
Bigger changes require more context: A large generated diff can span many files and abstractions. Reviewers need enough time and domain knowledge to understand the whole change rather than approving a sequence of locally plausible lines.
A merge is not a maintainability verdict: The high merge rate shows that agent-authored work can satisfy project requirements and review gates. It does not establish that the code is optimally factored, easy to extend, or inexpensive to maintain.
Implication: Prepare for a heavier review burden and guard against acceptance bias. Do not assume that more code automatically means worse code, because these pull requests do merge. Still, rigorous checks matter because a missed issue can be repeated across a much larger change.
AI-agent pull requests can be larger and still be accepted at high rates. Both findings matter. They show that agents can deliver substantial changes, while reinforcing the need for review practices that examine structure and maintainability as closely as immediate correctness.
The Churn Number That Complicates the Productivity Story
Another pair of statistics from GitClear complicates the productivity story. Its January 2026 report, AI Coding Tools Attract Top Performers: But Do They Create Them?, reported both higher durable-code output and much higher churn among heavy AI-tool users:
Four to ten times more “durable code”: By GitClear’s measure, developers with heavy AI usage produced four to ten times more durable code than non-users. GitClear uses “durable” to describe code that remains unchanged for longer.
Nine times more churn: The same heavy AI-tool users also produced about nine times the code churn of non-users. They generated more code that persisted while also revisiting or modifying code much more often.
This pair does not resolve into a simple verdict. Heavy AI-tool users may be more active overall, producing more lasting code and more revisions simply because they change more code. That is a plausible interpretation, not a conclusion the two headline metrics prove. Teams should therefore treat velocity and churn as separate signals rather than using either one as a complete quality measure.
From a team perspective, high AI usage and high velocity should signal both opportunity and caution. More durable code can represent meaningful output, while nine times more churn can indicate extensive iteration or rework. Raw productivity statistics do not show whether the team is converging on a clean design or repeatedly patching generated changes.
What Developers Themselves Report: Productivity vs. Experience
Repository analytics only go so far; what do developers themselves report? The Impact of AI Coding Assistants on Software Engineering: A Longitudinal Study, by Annie Vella and Kelly Blincoe, followed a matched cohort of 95 professional developers across two survey points six months apart. Two findings emerged:
Productivity perceptions are strongly positive. 84% of participants reported improved productivity after adopting AI tools, both at the 3-month mark and at 6 months. Developers felt they wrote code faster or got more done.
But many reported worsened experience. The proportion of engineers reporting worse developer experience on at least one dimension nearly doubled, from 14% at 3 months to 27% at 6 months. Issues cited included breakdowns in flow state, increased cognitive load, or frustration with AI mismatches.
A productivity–experience paradox emerged: most developers felt more productive, yet a significant and growing minority felt that at least one part of their work experience had degraded. AI helped them deliver, but it also introduced new verification and debugging friction. More output did not guarantee a better day-to-day experience.
Tasks such as boilerplate and documentation can move much faster, but the saved typing time may be replaced by the mental effort of validating suggestions. A developer can complete the first draft quickly and still spend substantial attention checking whether it fits the surrounding system.
Do not assume that a smooth merge or a completed ticket means the developer experience was smooth. The data suggest that many developers enjoy the speed gains while also absorbing verification costs that clutter their day. Team leads should watch this closely: even when delivery metrics improve, developer well-being can decline.
Why a Growing Minority Reports It Getting Worse
Why might nearly a third of developers be reporting a worse experience with AI tools over time? Based on the study’s qualitative feedback:
Trust overhead: Only 3.1% of respondents in the Stack Overflow 2025 Developer Survey reported high trust in AI-generated code accuracy. That does not mean everyone else distrusts every suggestion, but it does mean teams should expect verification rather than blind acceptance.
Fragmented focus: An AI completion can finish one task and immediately create another: checking the generated logic line by line. That context switch can interrupt flow even when the final result is useful.
Error debugging complexity: If AI code introduces a subtle bug, the developer has to debug an extra layer (figuring out if the logic or the integration is wrong). That can feel like extra work.
Team coordination: More duplicated code means reviewing multiple copies of the same logic separately. In the opening scenario, each developer had to validate a copied snippet, work that would have been unnecessary if the logic had been centralized.
These factors help explain how productivity can rise while developer experience worsens for a growing minority. The improvement is not universal, and side effects exist. Teams should monitor developer experience alongside delivery metrics as they expand AI-assisted development.
The Trust Gap Nobody’s Resolved
Developer trust in AI code remains low. The Stack Overflow 2025 Developer Survey reports that only 3.1% of developers highly trust the accuracy of AI-generated code; overall, 33% trust it and 46% distrust it. At the same time, 47% reported daily use. That gap between usage and confidence underlines why review and refactoring remain critical.
Low trust is consistent with the need to double-check generated output, but it does not explain high merge rates or duplication on its own. A pull request can pass tests and receive approval while reviewers still remain uncertain about its long-term structure. Teams need evidence-based confidence, not an assumption that acceptance equals maintainability.
The key for teams is to narrow this gap by building justified confidence: experienced engineers should review AI outputs, automated tests should be robust, and lessons about recurring AI failure modes should be shared. CI/CD and testing frameworks matter even more when trust continues to trail usage.
Why This Isn’t an Argument Against Using These Tools
It is easy to read these findings and conclude that AI coding tools are simply bad news. None of the studies supports banning them, and the evidence is more nuanced. The practical message is:
AI speeds up many tasks. Our earlier article on how AI and automation are helping developers work smarter presents the optimistic productivity case, including reported gains such as a 45% boost and acceptance rates as high as 85%. The longitudinal developer study also found that 84% perceived a productivity improvement.
Code quality needs new guardrails. The challenge is that AI does not automatically refactor or optimize; it generates a fix, and then stops. It is up to humans to spot duplication, enforce DRY, and optimize performance or security.
AI is a tool, not a codebase owner: A model may not understand the architecture, conventions, operational history, or constraints of a specific system unless that context is supplied and used effectively. Plausible syntax is not the same as sound system design.
Human judgment remains decisive: Senior engineers’ ability to spot duplication, recognize weak abstractions, and manage technical debt becomes more valuable as the volume of generated code increases.
None of the data says teams should stop using AI. It says the process must adapt. The goal is to use AI’s code-generation speed while proactively managing the maintenance cost. A policy that requires one source of truth for shared logic, for example, should be enforced before duplicate implementations spread.
That is not a criticism of the tool; it is a workflow change. The team remains responsible for deciding when generated code should become a reusable abstraction rather than another local patch.
The decision is no longer simply whether to use AI, but how to use it responsibly. Adoption and trust data do not identify a universally better tool, and they do not substitute for code-quality evidence. The practical question is how teams preserve the speed while containing the maintenance cost.
What Changes About Code Review in This Environment
What should change in code review? Historically, reviews emphasize correctness, style, security, and test coverage. In an environment of higher generated-code volume, duplication and hidden maintenance cost need to become explicit review criteria.
Consider adding these review points to every AI-assisted PR (or really any PR with AI-generated content):
Check for redundant logic: Scan the diff for code that looks familiar or repetitive. Even if the snippet works, ask: “Does this logic already exist elsewhere? Should it be refactored into a common function or module?”
Validate error handling: Look for those error-masking patterns (empty catches, broad exception swallows) mentioned earlier. AI often generates generic error-handling. Make sure you’re not silently hiding problems.
Security review: AI may produce code that looks correct while omitting validation or sanitization. When a change touches input, APIs, databases, or user interfaces, review it for injection risks, cross-site scripting, authentication weaknesses, authorization gaps, and unsafe data handling.
Performance check: If the PR is large or does heavy computation, consider efficiency. AI might not choose the most efficient data structures or algorithms for your codebase.
Consistency with architecture: Ensure the new code fits the application’s architecture and the team’s conventions. For a large one-off implementation, decide whether it should become a reusable pattern or be reshaped to match an existing one.
These questions make the review checklist actionable:
Duplication: “Is this code conceptually the same as something else we have?” If yes, refactor to reduce duplicates.
Error-Masking: “Do we catch exceptions without handling them?” Fix by logging or rethrowing intelligently.
Security/Performance: “Would this code introduce new vulnerabilities or slowdowns?” Apply safeguards as needed.
Ownership and context: “Who understands this code?” If only the AI knows, rewrite for clarity and comment where needed.
Reviewing these questions alongside the usual checks helps contain the risks identified in the research. A pair-review approach can work well: a developer who understands the feature walks through the generated change with the reviewer and explains how it fits the wider system.
Reviewing for Duplication, Not Just Correctness
It is particularly important to catch duplication during review because once code is merged, it is easy to forget. Start by asking whether the pull request duplicates logic already in the main branch. When it does, prioritize consolidation before merging. GitClear reported an 81% duplication increase, so addressing the pattern early can prevent substantial maintenance debt.
Static-analysis tools, IDEs, and code-review platforms can flag similar blocks, but tools do not replace architectural judgment. Review large diffs with an explicit question in mind: “Does this already exist in another form?” In the opening scenario, recognizing the duplicate fix only after it appeared in three places was too late; the review stage was the cheaper point to centralize it.
Rebuilding Refactoring Into the Workflow Deliberately
Given how much refactoring has dropped (down 70% from 2022 levels), teams may need to schedule refactoring as a first-class task rather than an afterthought. Some ideas:
Allocate refactoring work: When consolidation cannot be completed safely in the current pull request, create a clearly scoped follow-up task such as “Refactor: Consolidate [feature] logic,” assign an owner, and schedule it promptly.
Planning and review meetings: Include refactoring tasks in sprint planning, backlog refinement, or technical review. Maintenance work is easy to overlook unless it is visible on the board and competes for capacity like feature work.
Definition of Done: Expand the criteria so that merging a fix also includes checking for and updating duplicates. A simple checklist is: write tests; update documentation; handle errors; refactor duplicated logic.
Three practices help keep that maintenance work visible:
Plan for “perpetual V1” cleanup: GitClear warns that ignoring refactoring creates many frozen v1 components. Make a conscious effort to revisit and evolve them.
Use code ownership: If certain features or modules have an owner, empower them to refactor when AI changes go in. They know where related code lives.
Automate detection: Use linters, static analysis, or CI checks to flag duplicate blocks and other maintainability signals. GitClear describes this as putting a “tripwire” on duplicated code so that a rising trend becomes visible early.
Refactoring in an AI era is not about occasional, large rewrites; it is continuous maintenance. By rebuilding these steps into routine reviews and sprints, teams can counteract the decline in purposeful refactoring.
Metrics Worth Tracking on Your Own Team
To keep an eye on these issues, here are some metrics you might start tracking:
Pull request size and merge rate: Measure lines changed per pull request and compare AI-assisted and non-AI-assisted work where classification is reliable. Track merge rate separately so that a larger diff is not automatically labeled a failure.
Refactoring versus copy/paste ratios: Use repository analytics to compare moved or refactored code with copied code over time. A rising copy/paste share combined with a falling refactoring share is a stronger signal than either metric alone.
Code duplication count: Use static analysis to count duplicated functions, classes, or blocks that appear in multiple locations. A sustained increase should trigger targeted cleanup and architecture review.
Review effort: Track review time, requested changes, and the number of reviewers involved. Large generated pull requests may increase review workload even when they merge successfully.
Churn rate: Track how often recently merged code is changed again, especially after AI-assisted work. High short-term churn can indicate experimentation, incomplete context, weak initial design, or ordinary iteration; it should prompt investigation rather than an automatic verdict.
Each metric provides an early warning. GitClear reported an 81% increase in code-block duplication; a similar movement inside one codebase would deserve attention. The broader lesson is to measure structure, not only volume. Even a simple dashboard for duplication, refactoring, review effort, and churn can reveal a rising maintenance risk before it becomes a crisis.
What to Measure Before You Have a Problem
Ideally, set up these monitors now:
AI-assisted pull request labeling: Tag pull requests that developers or approved tools identify as AI-assisted. Then compare size, merge rate, review effort, and churn with non-AI pull requests.
Pull request health: Track review comments, change requests, and re-opened discussions. An increase can reveal rework or ambiguity that raw merge counts hide.
Manual code audits: Periodically, pick an AI-generated feature and do a mini-audit for duplicates and hidden bugs. Use it as a learning exercise.
Measurement turns intuition into evidence. A team may not notice a decline in refactoring because nobody has counted it; establishing a baseline shows when to intervene. GitClear’s broader point is that these trends are measurable and therefore manageable.
Software Engineer Salaries in 2026
The market still places a premium on software engineering judgment. According to Indeed’s U.S. Software Engineer salary data dated August 10, 2026, the average base salary was $135,396 per year. The reported range was $80,018 to $229,101, with an average cash bonus of $5,000 per year.
Indeed based those figures on approximately 39,100 salaries collected from job postings over the preceding 36 months. The range reflects differences in experience, location, employer, and specialization. As the role changes, strong judgment in code quality and architecture is likely to remain commercially valuable.
Building This Judgment: The Refonte Learning Software Engineering Program
Engineers who can keep codebases maintainable in the AI era will stand out. The curriculum does not claim to teach AI-code-debt management or the GitClear findings specifically. It does, however, build foundations in performance, application security, scalable systems, and architecture that support the code-quality judgment discussed throughout this article. The three-month program requires 12–14 hours per week and covers eight modules:
Foundations of Software Engineering: Establishes the base for reasoning about maintainable software and disciplined engineering practice.
Frontend & Backend Development: Builds full-stack context for understanding how a local change affects the wider application.
Cloud Architecture & Microservices: Develops architectural context for services, deployment boundaries, and scalable systems.
Real-Time Data Processing: Adds experience with systems where error handling, performance, and data flow require careful review.
Performance Optimization: Supports the judgment needed to identify inefficient generated or human-written implementations.
Application Security: Builds the security judgment needed to identify vulnerabilities and unsafe assumptions in generated or human-written code.
Scalable Software Solutions: Connects immediate implementation choices with long-term growth and maintainability.
Capstone Project: Provides a practical setting in which to apply the program’s modules to an integrated project.
The mentor is MSc Oskar Eriksson, who has more than 10 years of experience across full-stack development, cloud computing, and DevOps. The goal is not simply to code faster, but to reason about maintainability, security, performance, and scalability as systems evolve.
Program logistics: The program lasts 3 months at 12–14 hours per week. Career outcomes listed on the program page include Software Engineer, Full-Stack Developer, and Cloud Engineer. Tuition is $300 as a one-time payment, reflecting a 30% discount from the $387 list price, or two installments of $204 and $98. Applicants should be pursuing or hold a bachelor’s degree in computer science, engineering, mathematics, or a related field.
The Refonte Learning Software Engineering Program develops practical foundations in performance optimization, application security, scalable architecture, full-stack development, cloud architecture, real-time data processing, and project work. Those modules do not replace an organization’s own AI code-review standards, but they can strengthen the engineering judgment needed to apply those standards responsibly.