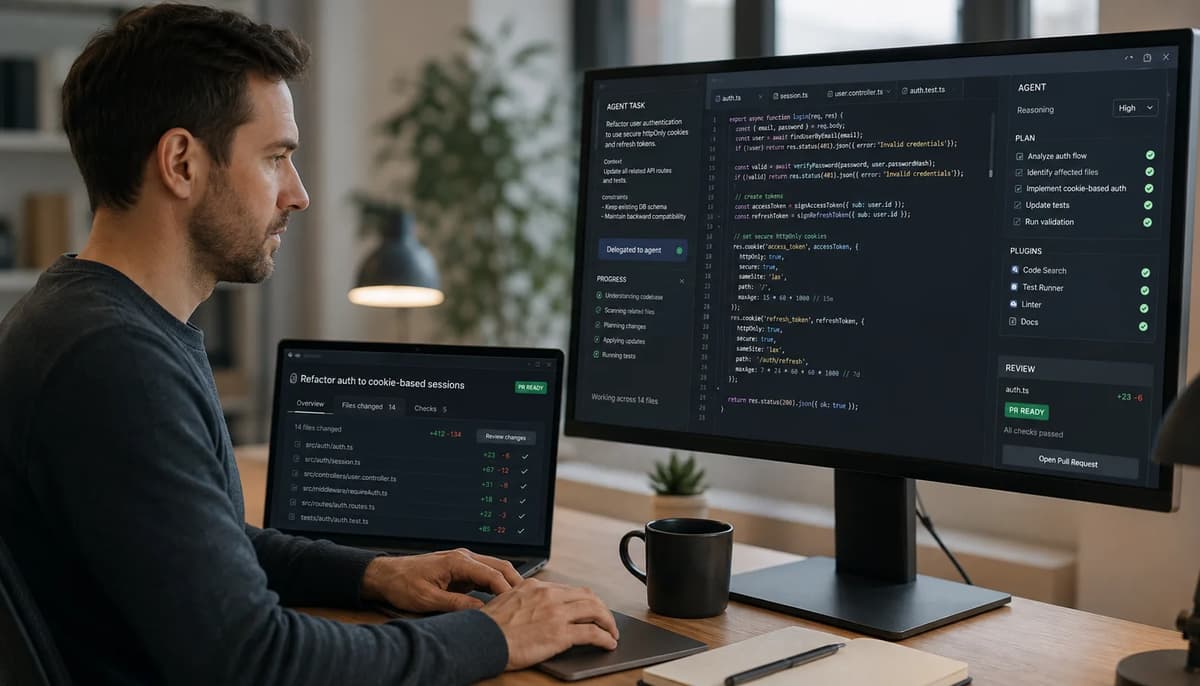
For a lot of developers, GitHub Copilot still means ghost text: you start typing a function, Copilot predicts the next line, and you press Tab. That mental model now describes only one layer of the product. GitHub still supports inline suggestions, but its 2026 agentic stack can also inspect a codebase, change multiple files, execute tools, run tests, work on a branch in an ephemeral GitHub Actions environment, and turn delegated work into a pull request.
There is one terminology point worth getting right immediately. GitHub Copilot agent mode in an IDE and the Copilot cloud agent are not technically the same feature: GitHub's documentation explicitly distinguishes local IDE agent mode, which edits your local development environment, from the cloud agent, which works autonomously in a GitHub Actions-powered environment and can create a branch and pull request.
That distinction matters because developers searching for what does Copilot agent mode do often mean the entire agentic workflow rather than one UI mode. In practice, the interesting 2026 story spans both surfaces: local multi-file agent work, cloud delegation, selectable reasoning depth, agent extensibility, automated code review, multiple model providers, CLI sessions, and enterprise measurement.
The August 2026 release sequence makes the shift unusually concrete. GitHub added task-level reasoning controls to its cloud agent on August 3, made Copilot code review effort levels generally available on August 7, added ROI-oriented agent-adoption reporting that day, shipped Kimi K3 and enterprise MCP governance on August 6, added MAI-Code-1.1-Flash and Ollama-related JetBrains support on August 11, and brought Agent Plugins 1.0 to major Copilot surfaces on August 12.
This is therefore not another overview claiming that AI is changing software development. It is a mechanism-level look at GitHub Copilot agent mode 2026: what happens when you delegate work, where the agent runs, how reasoning depth changes the run, what plugins and MCP servers add, how the review loop works, what GitHub now measures, and where you still need human engineering judgment.
From Autocomplete to Autonomous Agent: How Copilot Changed in 2026
GitHub did not suddenly invent agentic coding in August 2026. Agent mode was already rolling through VS Code in 2025, where GitHub described it as a mode that could analyze a codebase, make edits across files, run terminal commands, detect compilation or lint failures, and iterate on its own changes.
What changed by 2026 is the completeness of the workflow around that agent. The product now gives you separate local and cloud execution paths, model choice, task-level reasoning controls, MCP-based tools, installable agent plugins, AI code review depth, CLI concurrency and rollback, plus enterprise reporting that explicitly classifies developers by how deeply they have adopted agentic surfaces.
Old Copilot mental model | Copilot's 2026 agentic stack |
Suggests code while you are already typing | Can take a described task and autonomously decide which files need work |
Interaction happens line by line | IDE agent mode can make multi-file edits and execute tools in your local environment |
Developer performs the entire workflow | Copilot cloud agent can work on a branch in an ephemeral GitHub Actions-powered environment |
No task-level reasoning-depth decision | Supported models expose configurable reasoning levels, including for cloud-agent tasks |
Review means a human reads the change from scratch | Copilot code review offers Lite and Balanced effort levels, while human merge controls remain |
“Copilot” implies one AI model | Current Copilot documentation lists models from OpenAI, Anthropic, Google, Microsoft, Moonshot AI, xAI and other GitHub-defined model options |
Extensions are client-specific | Agent Plugins 1.0 standardizes packaging of agent skills and MCP servers across participating vendors |
The comparison is grounded in GitHub's current feature documentation and August 2026 releases.
Why the old “autocomplete on steroids” description is now outdated. An earlier Refonte Learning article on how AI and automation are already speeding up developer workflows in 2026 uses that older metaphor for Copilot. It captured the experience of predictive code completion, but it does not describe the mechanics of current agent workflows.
The practical difference is initiation. Autocomplete responds to code you have already started writing; an agent can start from a task such as “add request tracing to these API endpoints, update the tests, and keep the public API unchanged,” inspect the repository context, determine an implementation path, edit files and validate the result. GitHub itself says its cloud agent performs best when you give it a clear problem, complete acceptance criteria, and directions about the files involved.
For me, that changes the engineering question from “Is the next suggestion correct?” to “Have I specified this task tightly enough that another actor can execute it safely?” That is a much closer analogy to delegating an issue to another developer than accepting autocomplete.
The distinction between IDE agent mode and the cloud agent also determines how much supervision you provide. In IDE agent mode you remain close to the loop: GitHub says the agent determines what to change and can propose edits and terminal commands while iterating toward the task. In the cloud workflow, GitHub describes developers letting the agent work in the background on GitHub, reviewing what it did afterward, and deciding whether to open or merge the resulting pull request.
That second pattern is what makes the phrase AI coding agent 2026 materially different from “AI code generator.” Generation is an operation; delegation is a workflow involving scope, context, tool access, execution, validation, a review artifact and an accountable human decision.
What Happens When You Delegate a Task to Copilot's Cloud Agent
Suppose you have an issue: “Increase test coverage for the checkout retry path. Cover timeouts and duplicate payment callbacks. Do not change the public payment API.” With Copilot cloud agent, the useful mental model is not that a giant autocomplete process writes the answer all at once; GitHub gives the agent a dedicated environment in which it can inspect the repository, plan work, make changes, run validation and build a branch-backed artifact for review.
GitHub currently describes that development environment as ephemeral and powered by GitHub Actions. Inside it, Copilot can explore code, modify files, execute automated tests and linters, while repository setup instructions can preinstall the dependencies and tooling it needs.
A typical delegated run therefore looks like this:
Stage | What actually happens | Your responsibility |
Task definition | You supply an issue or prompt with the desired outcome | Define scope, constraints and acceptance criteria |
Context gathering | Copilot researches repository code and relevant GitHub context | Make important conventions discoverable |
Model/reasoning choice | Where supported, you select a model and reasoning level | Match model/depth to task complexity and budget |
Planning | Agent determines an implementation path | Review a plan first when architectural judgment matters |
Execution | Agent modifies files in its GitHub Actions-powered environment | Ensure required build/test tooling is available |
Validation | Agent can run tests, linters and built-in security checks | Do not confuse automated checks with business correctness |
Branch/PR | Copilot writes changes to its permitted branch and can open a draft PR | Review diff, CI output and behavior |
Iteration | You can provide feedback and have the agent revise the work | Give precise review feedback |
Merge | A human completes the review and merge | Own the final production decision |
GitHub documents repository research, planning, branch changes, pull-request creation and iterative feedback as cloud-agent capabilities; it also requires human review before a cloud-agent draft PR can merge.
The security boundaries matter. GitHub says the cloud agent normally gets push access only to one branch; when it is not working on an existing PR branch, GitHub creates a new copilot/ branch. Copilot cannot mark its own cloud-agent PR “Ready for review,” approve it, or merge it, and GitHub normally requires a write-authorized human to approve GitHub Actions workflows before they run on agent-created code.
GitHub also runs security validation on agent-generated changes by default. Its documented controls include CodeQL scanning, checks on newly introduced dependencies against the GitHub Advisory Database, secret scanning, restricted internet access, signed Copilot commits and session/audit logs that let teams trace agent activity.
Those protections are reasons to delegate more safely, not reasons to stop reviewing. GitHub's own risk documentation begins from the premise that the autonomous agent has access to code and can push changes, which means unvalidated code, sensitive information and prompt injection remain risks that require controls.
Reasoning levels: trading cost for depth. On August 3, 2026, GitHub shipped reasoning-level customization for supported models used by Copilot cloud agent. You choose a reasoning level along with the model when starting the task, and that level applies during the run. GitHub Changelog, 2026
GitHub describes the control as changing how deeply the model reasons before generating a response. Higher reasoning levels can improve results on complex problems, but they process more tokens and therefore consume more AI credits; GitHub's current model documentation recommends regular reasoning by default and higher reasoning for tasks that justify it.
That makes reasoning depth an engineering resource decision, not a quality slider you should pin permanently at maximum.
Task | Sensible reasoning posture | Why |
Routine configuration update | Default/regular | The implementation path should be narrow |
Mechanical dependency bump | Default/regular | Validation matters more than prolonged deliberation |
Add tests around documented behavior | Usually regular | Acceptance criteria can constrain the solution |
Multi-module refactor with compatibility constraints | Consider higher reasoning | The agent must weigh interacting changes |
Architectural change with multiple valid implementations | Consider higher reasoning plus human plan review | More reasoning cannot supply missing business intent |
Security-sensitive authentication change | Higher reasoning may help, but human specialist review remains mandatory | Model deliberation is not a security approval |
The last row is the critical one. Increasing reasoning depth changes how much computation the model devotes to the problem; it does not add undocumented product knowledge, confer accountability or turn probabilistic output into a formal correctness proof. GitHub's requirement for a human to review cloud-agent pull requests remains in place regardless of model selection.
The most effective prompt resembles a well-written engineering issue. GitHub's own best-practice guide asks for a clear problem statement, complete acceptance criteria and guidance about which files need to change, while its organizational pilot guidance recommends tasks such as increasing test coverage, fixing bugs or flaky tests, and updating configuration or documentation.
That is why a concrete brief such as “add timeout tests to payment_retry_test.py, preserve the public interface, and make pytest tests/payments pass” usually gives an agent a better operating envelope than “improve payments.” The agent cannot infer the missing definition of “improve” from reasoning effort alone.
Agent Plugins 1.0 and the Multi-Model Copilot Marketplace
One of the more consequential August releases is not a new model at all. On August 6, 2026, AWS, Anysphere, Microsoft, OpenAI and Vercel published Agent Plugins 1.0, while Google joined the effort as a core maintainer; on August 12, GitHub announced general availability of the standard in VS Code, Copilot CLI, the GitHub Copilot SDK and the Copilot app across Copilot plans. GitHub Changelog, 2026
The important mechanism is packaging. Agent Plugins defines an open format that can bundle agent skills and Model Context Protocol servers into one installable plugin instead of forcing every agent client to invent a separate distribution structure. GitHub describes the specification as independently governed, while Vercel and AWS separately describe it as an open, vendor-neutral format.
Google's developer announcement confirms that it joined the core-maintainer group when version 1.0.0 was published. That makes the participant list unusually notable: companies that compete directly in AI development tooling are collaborating on the packaging layer.
Date | 2026 change | What it changes mechanically |
August 6 | Agent Plugins 1.0 published | Skills and MCP servers gain a shared installable packaging specification |
August 6 | Kimi K3 begins GA rollout in Copilot | Adds Moonshot AI's open-weight model to Copilot's model choices |
August 6 | Enterprise MCP allowlists GA | Administrators can centrally allow or deny MCP servers |
August 11 | MAI-Code-1.1-Flash added | Adds Microsoft's coding model to Copilot model selection |
August 11 | Ollama provider support in JetBrains | JetBrains users can configure Ollama through Copilot's BYOK provider flow |
August 12 | Agent Plugins 1.0 GA in major Copilot surfaces | Shared plugin packages become usable across VS Code, CLI, SDK and Copilot app |
These releases come from GitHub's dated August changelogs.
The strategic implication is bigger than “Copilot now has plugins.” My reading is that once GitHub/Microsoft, Cursor's Anysphere, OpenAI, AWS, Vercel and Google converge on a common packaging layer, plugin format itself becomes a weaker point of differentiation; vendors have more incentive to compete on agent execution, model routing, planning quality, security controls, context management and developer experience. That is an inference from the shared standard and its membership, not a statement those vendors jointly made.
Agent Plugins is also not the same thing as MCP. MCP gives models and agents a standardized way to connect to tools and sources of context; the plugin standard packages capabilities, including MCP server definitions and agent skills, into something that compatible clients can install. GitHub's August 12 announcement specifically recommends pairing plugin MCP configurations with MCP allowlists in governed environments.
That governance layer matters at enterprise scale. On August 6, GitHub separately made enterprise MCP allowlists generally available, introducing allowedMcpServers and deniedMcpServers managed-setting keys that can match remote URLs, local commands and server names; GitHub currently enforces those controls in the Copilot app, Copilot CLI and VS Code.
Do not merge that fact with Kimi K3, even though both shipped on August 6. Kimi K3 is a Moonshot AI model hosted by GitHub on Fireworks AI, while MCP allowlists are an independent enterprise-management feature.
Copilot is now multi-model, not a single-model product. GitHub's current supported-model documentation lists offerings from OpenAI, Anthropic, Google, Microsoft, Moonshot AI and xAI, among others, and states explicitly that different models trade speed, cost efficiency, accuracy, reasoning and multimodal capability differently.
Kimi K3 became generally available in Copilot beginning August 6, with access through surfaces including VS Code, Copilot CLI, Copilot cloud agent, the Copilot app, GitHub.com and additional IDEs. GitHub says Business and Enterprise administrators must explicitly enable the model because it is off by default for those plans.
On August 11, GitHub added MAI-Code-1.1-Flash, a Microsoft coding model, and separately added Ollama support to GitHub Copilot for JetBrains through the Bring Your Own Key/provider configuration experience.
The broader landscape of AI code generators and developer tools in 2026 is useful context, but the mechanism-level change here is more specific: “Which AI model does Copilot use?” no longer has a single answer.
Selection question | What a developer should evaluate |
Is this a quick mechanical edit? | Latency and AI-credit efficiency |
Is this a long-horizon refactor? | Reasoning capability and context handling |
Does the task include visual input? | Whether the selected model supports the required modality |
Does policy restrict providers/models? | Organization and enterprise model policies |
Is code locality important? | Whether a supported BYOK/local-provider workflow fits the client |
Is the agent deciding automatically? | Which models participate in Auto selection and what policies constrain them |
GitHub cautions that model availability depends on the Copilot plan and client and can change over time. That volatility is another reason to think of Copilot as a model-access and agent-execution layer rather than equating the entire product with whichever foundation model happens to be selected this month.
Code Review, ROI, and the New “Agent-First” Adoption Model
Delegating implementation creates an obvious second problem: somebody, or something, still has to inspect the result. GitHub's August 7 release of Copilot code review effort levels makes review depth itself configurable rather than treating every pull request as an identical AI-review job. GitHub Changelog, 2026
The two generally available levels are Lite and Balanced, renamed from the “Low” and “Medium” terminology used during preview. GitHub positions Lite for straightforward changes and Balanced for more complex or sensitive changes requiring deeper analysis from a higher-reasoning model; organizations can establish a default that repositories inherit, while repository or individual settings can override it.
Review scenario | Better starting level | Engineering rationale |
Typo or documentation cleanup | Lite | Small, low-risk diff |
Simple dependency update with passing CI | Lite | Narrow behavioral surface |
Business-rule modification | Balanced | More interactions to reason about |
Shared library/API change | Balanced | Higher downstream impact |
Authentication or authorization logic | Balanced plus human security review | AI depth does not replace security ownership |
High-risk production migration | Balanced plus domain-owner review | Business and operational context remain human responsibilities |
GitHub's own product guidance says Lite is designed for straightforward work while Balanced gives deeper attention to more complex or sensitive changes.
The useful part is not merely that one AI setting is “better” than another. Teams can encode an explicit review-cost policy: do not spend maximum analysis on a harmless text edit, but do not run the shallowest available review against authentication code simply because the button is convenient.
What you should not do is conclude that Balanced review has replaced a human reviewer. GitHub's cloud-agent security model explicitly requires a human to review and merge draft pull requests generated by the cloud agent, and the agent cannot approve or merge its own PR.
That guardrail reflects a fundamental division of responsibility. AI review can examine syntax, code patterns, repository context and machine-detectable risks; a human still owns questions such as “Does this implement the product rule finance approved?”, “Can we operate this safely during a partial outage?” or “Is changing this authorization boundary acceptable?”
The impact dashboard now measures agent adoption separately. On August 7, GitHub added a “Potential return on investment” section to the Copilot impact dashboard that compares earlier Copilot-adoption behavior with what it calls agent-first behavior, showing estimated AI cost per developer per month, AI cost as a percentage of payroll, and pull requests per month. GitHub Changelog, 2026
There is an important precision issue in the cohort labels. The dashboard groups “Passive users” and Phase 1 against the more agent-heavy Phase 2 and Phase 3 groups, but GitHub's formal adoption taxonomy says Phase 1 can include code completions and/or IDE agent mode; Phase 2 means engagement with one GitHub-based agent surface such as cloud agent, code review or Copilot CLI; Phase 3 means two or more GitHub-based agent surfaces or engagement with the Copilot app.
GitHub adoption classification | Defined behavior |
Phase 0: No cohort | User does not meet engagement criteria for an adoption phase |
Phase 1: Code first | Uses code completion and/or IDE agent mode |
Phase 2: Agent first | Uses one GitHub-based agent surface such as cloud agent, code review or CLI |
Phase 3: Multi-agent | Uses at least two GitHub-based agent surfaces, or the Copilot app |
These are GitHub's current cohort definitions, and GitHub versions the classification logic so it can change the methodology without erasing historical context.
That is a more interesting enterprise signal than raw seat count. GitHub can now distinguish an organization that bought Copilot licenses from one where developers actually incorporated GitHub-based agent surfaces into their development process.
It also means “Copilot adoption” has stopped being a sufficiently precise metric. A developer accepting completions, another delegating issues to the cloud agent, and a third combining cloud delegation, AI review and the CLI may all hold the same product family license while operating with very different workflows.
Do not overread the ROI dashboard, though. GitHub calls the section potential ROI and describes its calculations as estimates intended for directional modeling; the existence of higher or lower PR counts in a cohort does not, by itself, prove that agent usage caused the difference.
That caveat is important for engineering leaders. PRs per month can be an output metric, but a flood of tiny PRs is not automatically better than fewer high-value changes, and no dashboard can infer product correctness, incident risk or architectural quality from volume alone.
The best use of these measurements is therefore comparative and diagnostic. You can ask whether teams paying for advanced Copilot capability have actually reached Phase 2 or Phase 3 workflows, what the AI-credit cost looks like, how PR activity changed, and whether those changes correspond to the outcomes your engineering organization actually values.
Copilot CLI, Cursor, Devin, and the 2026 Agent Competition
Agentic development is also escaping the chat panel. GitHub's August 7 weekly release added a Sessions sidebar to Copilot CLI for concurrent sessions, an experimental /worktree command for isolated parallel work and /rewind, which can restore the conversation and files Copilot changed without depending on Git while preserving subsequent edits.
That combination is more important than it sounds. Multiple agents modifying a repository create a coordination problem; worktrees isolate changes, sessions give you multiple active work streams, and rewind lowers the recovery cost when an agent takes the wrong path.
Copilot CLI feature | Mechanism | Why I would use it |
Sessions sidebar | Navigate/manage multiple concurrent agent sessions | Keep unrelated delegated tasks separate |
/worktree | Creates an isolated worktree and separate conversation | Parallelize changes without mixing working trees |
/rewind | Restores the conversation and files changed by Copilot | Undo a poor agent direction with less Git ceremony |
Tool-call durations | Shows how long tool operations take | Diagnose where an agent run is spending time |
GitHub announced those CLI changes in its August 3 weekly release, published August 7.
/rewind addresses a surprisingly practical trust issue. Developers hesitate to grant broad write access when recovery feels expensive; a purpose-built ability to roll back agent changes makes experimentation easier because you are not forced to reconstruct every modification from Git history.
That does not mean you should abandon Git. Version control remains the authoritative engineering record; rewind is a low-friction interaction primitive for agent sessions, not a substitute for commits, branches, reviews and repository policy.
GitHub Copilot vs Cursor agent is consequently no longer a comparison between “Copilot autocomplete” and “Cursor agent.” Both products now operate across agentic local/cloud workflows, multiple models and extensibility, and Anysphere, the company behind Cursor, is one of the organizations that co-published Agent Plugins 1.0 with Microsoft, OpenAI, AWS and Vercel.
Cursor's 2026 release cadence shows direct overlap. On August 3, Cursor announced Google Workspace plugins that let its coding agents work with Gmail, Google Drive and Google Calendar; on July 28 it launched Cursor Start, a ₹649-per-month tier for developers in India that includes always-on cloud agents and plugin/MCP/skill support.
On July 22, Cursor also released Cursor Router for Teams and Enterprise. Cursor says its router classifies requests using signals including query, context, task complexity and domain, then directs work toward an appropriate model, with Intelligence, Balance and Cost modes controlling the tradeoff.
Cursor publishes its own A/B-test and cost-savings results for that router, but those are vendor-reported measurements rather than an independent head-to-head benchmark. The safer comparison is architectural: Cursor is explicitly investing in routing requests among models, while GitHub gives Copilot users model selection/Auto selection and, for supported models, configurable reasoning depth.
Dimension | GitHub Copilot in 2026 | Cursor in 2026 |
Local agent workflow | IDE agent mode and client-specific agent surfaces | Cursor editor agents |
Background/cloud work | GitHub cloud agent with branch/PR workflow | Always-on/cloud agents |
Repository workflow | Deep GitHub issue, branch, PR and Actions integration | Git workflows plus Cursor's agent surfaces |
Model strategy | Multi-provider model picker/Auto selection, reasoning controls on supported models | Multi-model environment plus Cursor Router for Teams/Enterprise |
Plugin standard | Agent Plugins 1.0 | Agent Plugins 1.0 co-publisher |
External tool/context integrations | MCP, plugins and GitHub-native context | MCP/plugins plus integrations such as Google Workspace |
Differentiation | GitHub-native lifecycle, governance, review and metrics | Editor experience, router, cloud-agent UX and broader workspace integrations |
The table summarizes documented capabilities rather than declaring a universal winner; which product fits better depends on repository host, enterprise policy, preferred editor workflow and the tasks you delegate.
The fact that Copilot and Cursor now share an agent-plugin standard is particularly telling. It reduces the value of asking “which proprietary extension format wins?” and increases the value of asking “which agent plans better, uses context better, recovers from errors more safely, and fits our engineering controls?”
Refonte Learning already covers how Google and Meta now handle AI-assisted coding interviews, where Copilot and Cursor appear in a different context. Here, the competitive point is strictly production workflow: task execution, model routing, tool access, isolation, review and organizational control.
What happened to Windsurf? There is an observable redirect today: opening the Windsurf changelog resolves to Cognition's Devin Desktop changelog.
However, as of August 13, 2026, that redirect is not merely circumstantial evidence that Windsurf was folded into Devin branding. Cognition published an official June 2, 2026 announcement titled “Windsurf is now Devin Desktop,” describing Devin Desktop as the next generation of Windsurf and a command center for local and cloud agents.
So the most accurate formulation differs from an earlier, more cautious reading of the redirect: the redirect itself is an observed technical fact, while the branding transition is also independently confirmed by Cognition's own announcement.
That leaves the 2026 competitive landscape with three useful design patterns to watch: GitHub is connecting cloud agents tightly to repository lifecycle and enterprise measurement; Cursor is investing in an agent-oriented editor, cloud execution and model routing; Devin Desktop positions itself as a command center where multiple local and cloud agents can coexist.
What Agent Mode Still Can't Do: The Skills That Matter
The easiest way to misuse an AI coding agent in 2026 is to confuse autonomy with understanding. Copilot can autonomously execute steps once it has context and a goal, but GitHub's own guidance says cloud-agent results improve when tasks are clear, well scoped, include complete acceptance criteria and tell the agent which files should change.
That is not generic prompting advice. It describes the boundary of delegation: an agent can reason through a specified software problem, but it cannot reliably reconstruct business facts your organization never wrote down.
Take the request “fix checkout so retries work correctly.” A senior engineer may know that “correctly” means “a customer must never be charged twice, but asynchronous callbacks can arrive for 24 hours, and the legacy merchant integration cannot accept an idempotency header.” None of that exists in the prompt unless you supply it or make it available through repository/context tooling.
Higher reasoning does not repair missing requirements. GitHub describes higher reasoning levels as giving supported models more depth on complex problems while consuming more tokens and AI credits; it does not describe them as a way to discover undocumented organizational intent.
The most useful delegation skills therefore look like this:
Priority | Skill |
Must | Writing a task description specific enough for an agent to act on correctly |
Must | Knowing when higher reasoning is justified and when regular reasoning is sufficient |
Should | Reviewing agent-generated pull requests critically instead of merging on trust |
Should | Understanding Copilot code review effort levels well enough to set sane defaults |
Good | Familiarity with MCP and Agent Plugins 1.0 |
Good | Comfort choosing among models in a multi-model agent environment |
The priority order follows directly from GitHub's well-scoped-task guidance, reasoning recommendations, human-review requirement and growing plugin/model surfaces.
Task-description writing belongs at the top because every downstream mechanism depends on it. A stronger model, deeper reasoning setting, MCP server and Balanced AI review can all operate perfectly while solving the wrong problem.
For a production task, I would include at least four pieces of information before delegating: the desired observable behavior, constraints that must remain true, acceptance tests, and relevant repository boundaries. That mirrors GitHub's recommendation for a clear description, acceptance criteria and file-level direction.
For example:
Add idempotency handling to webhook retries. Duplicate events with the same provider event ID must produce one ledger entry. Preserve the existing public API, add unit tests for duplicate callbacks and timeouts, and limit changes to the payments service unless a shared utility is strictly required.
That prompt still gives the agent room to reason about implementation while closing the expensive ambiguity gaps.
The limits worth knowing before you trust a multi-file task are equally concrete.
Copilot can write code that introduces vulnerabilities; GitHub runs mitigations because that risk exists.
Cloud-agent access to repository code and other sensitive information creates data-handling risk, so GitHub restricts external network access and documents prompt-injection concerns.
A passing unit-test suite proves the tested properties, not that the agent interpreted an undocumented requirement correctly.
A deeper reasoning level spends more computation on the available problem definition; it cannot supply absent product context.
AI code review can reduce the amount of undifferentiated manual inspection, but GitHub still requires human review before cloud-agent pull requests merge.
The most revealing limitation is the last one. GitHub has shipped automated security checking, agent-generated draft PRs and configurable AI review depth, yet its own architecture deliberately leaves final merge authority with humans.
Common mistake: treating reasoning-level selection as set-and-forget. GitHub explicitly recommends regular reasoning for normal use and higher reasoning when complexity warrants the additional token and AI-credit cost. Leaving every task at the deepest setting wastes resources on mechanical work; leaving every task at regular depth can underserve long-horizon work.
The better habit is to classify the task first. Dependency bumps, formatting migrations and narrow test additions usually benefit from clear acceptance criteria more than maximal deliberation; a compatibility-sensitive refactor across packages gives a higher-reasoning model more meaningful tradeoffs to analyze.
Common mistake: skipping code review because “the agent already checked it.” This fails for two separate reasons: automated validation cannot evaluate undocumented product intent, and GitHub itself prevents the cloud agent from approving or merging its own draft pull request.
Use Lite and Balanced as triage tools. A one-line low-risk change and a modification to authorization logic do not deserve identical AI effort, but a Balanced review on the latter still does not absolve the engineer responsible for that subsystem.
Common mistake: optimizing for PR count instead of engineering outcomes. GitHub's impact dashboard makes PRs per month visible by adoption cohort, but GitHub labels its ROI model directional; teams should pair throughput with quality, incident, rework and product metrics rather than treating PR volume as the target.
This is also why the skill set around agents is broader than “prompt engineering.” Understanding what an AI Developer role actually involves in 2026 gives useful adjacent context, but developers using coding agents specifically need enough model literacy to understand context, reasoning, tool use, evaluation and deployment, not merely the syntax of a good chat prompt.
The practical senior-engineer stance is simple: delegate execution aggressively when the task boundary is clear; retain judgment aggressively where the requirement boundary is not.
Self-Study vs. the Refonte Learning AI Developer Program
You can learn to operate GitHub Copilot agent mode quickly from GitHub's documentation. You do not need a three-month AI course to assign a well-scoped issue, choose a model, inspect a pull request or type /rewind.
The harder learning objective is understanding what sits underneath the interface: why additional reasoning consumes more tokens, why models differ by task, how natural-language systems process context, how neural models get evaluated, why deployment architecture matters, and why an autonomous tool still needs guardrails. GitHub's current documentation itself exposes those concerns through model selection, configurable reasoning, AI-credit consumption, MCP access, ephemeral execution environments and security controls.
That creates a real distinction between using an agent and understanding an agentic AI system well enough to reason about its behavior.
Factor | Self-study | Structured AI Developer Program |
Getting started with Copilot agent workflows | Can happen directly from product documentation | Not the program's stated purpose |
AI foundations | Depends on the resources you assemble | Dedicated Foundations of Artificial Intelligence module |
Machine-learning depth | Varies by chosen material | Dedicated Machine Learning Algorithms module |
Neural networks | Easy to study selectively | Dedicated Building Neural Networks module |
NLP foundations | Requires choosing a coherent learning path | Natural Language Processing Techniques module |
TensorFlow/PyTorch | Depth varies by personal curriculum | Dedicated Deep Learning Frameworks module |
Deployment | Often optional in a self-designed path | Dedicated Deploying AI Models module |
Portfolio structure | You define scope yourself | Defined Capstone Project |
Schedule | Open-ended | Fixed three-month program |
Formal program outputs | None unless separately pursued | Training Certificate and Certificate of Internship on successful completion |
Refonte's current program page lists those modules, certificates and the three-month duration; there is no defensible universal “self-study takes X months” number, because previous engineering experience, mathematics and weekly study time vary substantially.
That last point is worth correcting rather than manufacturing an SEO-friendly statistic. A working backend engineer with ML experience and a computer-science student learning Python for the first time do not have the same self-study timeline.
For someone already shipping software, self-study has a strong advantage: you can focus immediately on the gap you actually have. GitHub's documentation covers task scoping, cloud-agent setup, reasoning controls and security in detail, so a senior engineer can learn the mechanics without waiting for a formal program.
A structured program solves a different problem. It creates a fixed sequence through foundations, machine learning, neural networks, NLP, deep-learning frameworks, ethics, deployment and a capstone rather than requiring you to decide which foundational gaps you have before you know enough to identify them.
The Refonte Learning AI Developer Program, in concrete terms
The Refonte Learning AI Developer Program is a three-month Training & Internship Program with a stated commitment of 12–14 hours per week and an online/virtual-internship format. Its current curriculum focuses on AI and machine-learning foundations rather than teaching GitHub Copilot, Cursor, Windsurf or another AI coding assistant by name.
That is the honest connection to an article about Copilot. The program's Foundations of Artificial Intelligence, Natural Language Processing Techniques and Deploying AI Models modules cover concepts that make an LLM-driven coding agent easier to reason about, but the program page does not claim that students receive product-specific Copilot agent-mode training.
The nine curriculum modules currently listed are:
Foundations of Artificial Intelligence
Machine Learning Algorithms
Building Neural Networks
Natural Language Processing Techniques
Deep Learning Frameworks: TensorFlow & PyTorch
AI Ethics and Fairness
Deploying AI Models
AI for Robotics and Automation
Capstone Project
The page explicitly identifies Python, TensorFlow and PyTorch in its program description and discusses R, Java and Keras among the languages/frameworks relevant to its AI-development learning path.
Program detail | Current published information |
Duration | 3 months |
Weekly commitment | 12–14 hours/week |
Format | Training/internship program; virtual format |
Core technologies named | Python, TensorFlow, PyTorch, R, Java, Keras |
Mentor | Dr. John Anderson, Senior AI Engineer at Refonte Learning |
Mentor experience | 17-year career |
Main outcomes | AI Developer, Machine Learning Engineer, Data Scientist |
Admission | Pursuing or completed bachelor's-level study in a relevant field |
Completion credentials | Training Certificate + Certificate of Internship |
Additional recognition | Letter of Recommendation and Certificate of Appreciation for outstanding performers; top-performer prizes |
Published one-time price | $300 |
Published installments | $204 + $98 |
The live program page supports the curriculum, prerequisites, certification and payment details.
The mentor listed is Dr. John Anderson, identified by Refonte Learning as a Senior AI Engineer with a 17-year career. The page describes his background in data science and AI development and presents him as the program's educational mentor.
On successful completion, Refonte says students receive both a Training Certificate and a Certificate of Internship. Students with outstanding performance may receive a Letter of Recommendation and Certificate of Appreciation, while the page says top performers can receive additional prizes.
The published fee deserves one practical clarification. The program page lists a $300 one-time enrollment cost, while its installment section separately lists $204 and $98; those two installment figures mathematically total $302, so prospective students should verify the current checkout amount rather than assuming the installment total equals the one-time price.
For career context beyond the course itself, Refonte Learning also maintains the 2025 AI engineering salary guide. The program page currently identifies AI Developer, Machine Learning Engineer and Data Scientist among its intended career outcomes.
The connection back to Copilot is conceptual rather than product-specific. Once you understand how machine-learning systems process input, how NLP models work, what deployment constraints look like and why evaluation matters, controls such as context windows, reasoning levels, model choice, tool permissions and agent validation stop looking like magic settings and start looking like engineering tradeoffs.
Explore the Refonte Learning AI Developer Program for the current curriculum, enrollment requirements and published fees.
FAQ: People Also Ask
Question area | Core distinction |
Agent mode | Local autonomous IDE editing |
Cloud agent | Background GitHub-hosted task execution |
Reasoning levels | Adjustable model deliberation on supported models |
Agent Plugins 1.0 | Cross-vendor packaging for agent capabilities |
Code-review effort | Lite vs Balanced AI review depth |
Cursor comparison | Shared standards, different execution/product layers |
What is GitHub Copilot's agent mode?
GitHub Copilot agent mode lets Copilot take a development task, determine which files need changing, make edits, use tools such as terminal commands and iterate toward a result rather than merely proposing the next inline completion. In GitHub's precise terminology, IDE agent mode works in your local development environment.
The related Copilot cloud agent is a separate execution mode. It works autonomously in a GitHub Actions-powered environment, can research a repository, create a plan, make changes on a branch and optionally produce a pull request.
What are reasoning levels in Copilot's cloud agent?
Reasoning levels control how deeply a supported model reasons about a task before producing its response or actions. GitHub shipped task-level reasoning customization for Copilot cloud agent on August 3, 2026, for paid plans that include cloud-agent access: Pro, Pro+, Business, Enterprise and Max. GitHub Changelog, 2026
Higher reasoning can help on complex tasks but processes more tokens and therefore consumes more AI credits. GitHub recommends regular reasoning for normal work and increasing it when the task's complexity warrants the additional consumption.
What is Agent Plugins 1.0?
Agent Plugins 1.0 is an open cross-vendor specification for packaging agent capabilities, including agent skills and MCP servers, into an installable plugin. AWS, Anysphere, Microsoft, OpenAI and Vercel published version 1.0 on August 6, 2026, and Google joined as a core maintainer that day.
On August 12, GitHub announced general availability of Agent Plugins 1.0 support in VS Code, Copilot CLI, the GitHub Copilot SDK and the Copilot app across Copilot plans. GitHub Changelog, 2026
Does effort-leveled code review replace human review?
No. Copilot code review effort levels, Lite and Balanced, let teams vary the depth of AI analysis according to the complexity or sensitivity of a pull request, and organizations can set inherited defaults. They reached general availability on August 7, 2026. GitHub Changelog, 2026
GitHub separately requires human review before draft pull requests created by Copilot cloud agent can merge. The cloud agent cannot mark its own PR ready for review, approve it or merge it, so effort levels should function as review triage rather than a substitute for engineering ownership.
How does Copilot's agent mode compare to Cursor?
Both now operate in the same broad agentic-development category, and Anysphere, the company behind Cursor, is a co-publisher of Agent Plugins 1.0 alongside Microsoft and other maintainers. That means the two products can converge on an extensibility format while continuing to compete on execution, model strategy, context management, editor experience, cloud-agent workflows, governance and pricing.
GitHub's 2026 stack emphasizes GitHub-native cloud execution, branch/PR controls, configurable reasoning on supported models, code-review effort levels and adoption analytics. Cursor has separately released features including Google Workspace plugins, always-on cloud-agent access in its India-specific Cursor Start tier and Cursor Router for Teams and Enterprise.
Does the Refonte Learning AI Developer Program teach GitHub Copilot specifically?
No product-specific Copilot training is stated on the current AI Developer Program page. Its named curriculum focuses on AI foundations, machine learning, neural networks, natural language processing, TensorFlow and PyTorch, ethics, AI-model deployment, robotics/automation and a capstone project.
That makes the defensible connection foundational rather than tool-specific: the program builds AI/ML concepts that help you understand why agent systems use models, context, reasoning and deployment infrastructure, but it should not be represented as a course in GitHub Copilot, Cursor or Devin.
Bottom line:
· GitHub Copilot agent mode in 2026 is a genuine departure from the old autocomplete mental model. IDE agent mode performs autonomous local edits, while Copilot cloud agent supports delegated GitHub-hosted work, and supported models now expose configurable reasoning depth.
Agent Plugins 1.0 is a notable structural shift. AWS, Anysphere, Microsoft, OpenAI and Vercel co-published a shared packaging standard, Google joined its core maintainers, and GitHub made it GA across major Copilot surfaces on August 12.
GitHub now measures agent adoption separately from simpler Copilot usage. Its Phase 2 and Phase 3 classifications identify developers using GitHub-based agent surfaces, while the impact dashboard models potential ROI by adoption pattern; the ROI figures remain directional rather than causal proof.
No reasoning level removes the need for judgment. GitHub recommends clearly scoped tasks, documents security risks inherent in autonomous code changes and still requires a human to review and merge cloud-agent pull requests.
The real change is therefore not that Copilot writes larger chunks of code. It is that you can now treat parts of software delivery as delegatable units of work with a model, reasoning budget, tools, isolated execution environment, review policy and measurable organizational adoption. That makes task specification and human review more important, not less.
For developers who want the AI/ML foundation that makes systems like Copilot's agent stack understandable rather than mysterious, the Refonte Learning AI Developer Program provides a structured three-month starting point in AI foundations, neural networks, NLP, deep-learning frameworks and model deployment.