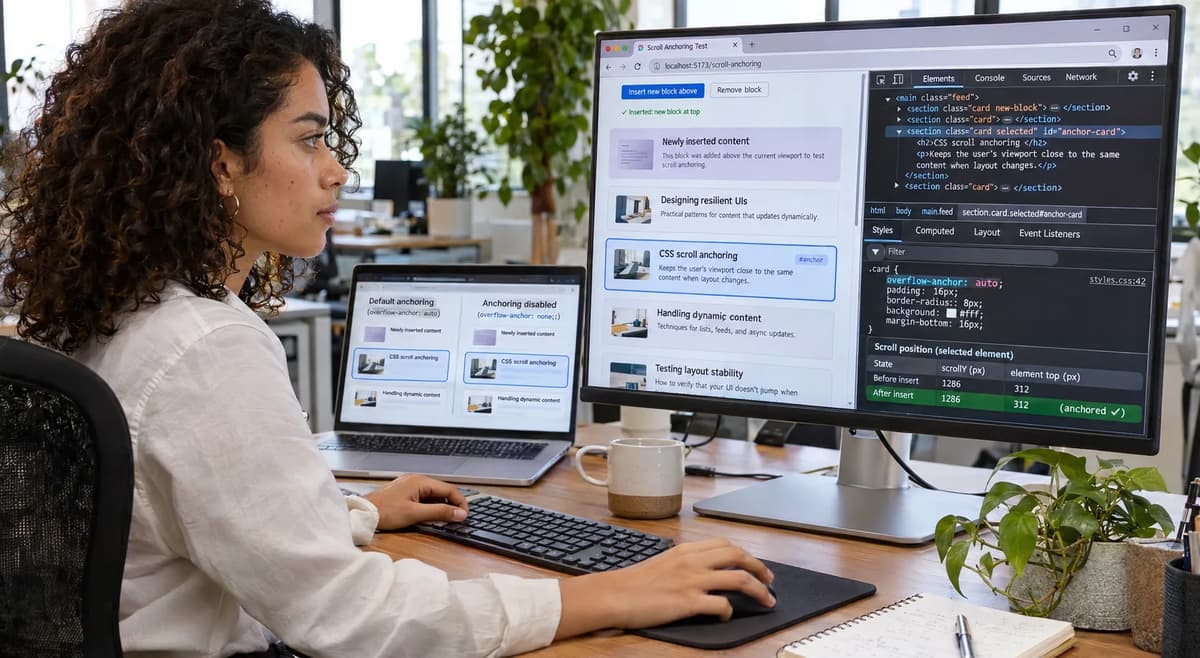
A recent UI test detected that inserting new content above the current scroll position appeared to shift the viewport unexpectedly. Before blaming application logic, we must rigorously determine whether this “jump” was caused by the browser’s native CSS scroll anchoring or by some other factor (e.g. script-driven scrolling).
This report treats the issue as a release-validation problem: we define a precise acceptance contract covering anchor selection, overflow-anchor exclusions, and insertion above the viewport, then build an isolated test fixture to prove or disprove compliance. We pin specific browser versions and document all assumptions. Each test case is specified with independent expected outcomes; a negative control confirms that non-triggering scenarios remain stable.
We capture raw evidence (scroll offsets before and after insertion), reconcile it against documented behavior, and use a clear ACCEPT / REPAIR / RERUN / HOLD decision matrix. Any failing case will be tagged for remediation (e.g. disabling anchoring via overflow-anchor: none for the minimal scope). All steps and observations are recorded in tables and code blocks for reproducibility. Every non-executed test is explicitly marked EXPECTED or NOT EXECUTED, preserving transparency. The page itself remains static except for the scripted insertions, ensuring that only scroll anchoring (or its absence) can account for any movement.
1. Define the acceptance contract
We must unambiguously define what evidence we require to claim that scroll anchoring moved the viewport. This contract has two parts: behavioral expectations (what should happen according to spec and best-practice) and reject conditions (what would indicate failure or false positives).
The acceptance criteria for this behavior are summarized in the table below. Each assertion is tied to concrete evidence from the fixture and the documented specification.
Case | Setup and Action | Expected Result | Reject Condition |
1. Anchor selection: The page’s scroll container has an anchorable element in view, and we insert new content above it. | Insert a visible DOM element (with non-zero height) immediately above the top of the user’s view (e.g. using insertBefore on the scroll container). The container is scrolled down so that the anchor is not flush with the very top. | The browser must adjust scrollTop by roughly the inserted height, keeping the original anchor at the same screen position. In other words, finalScrollTop ≈ initialScrollTop + insertionHeight. | If scrollTop does not increase (or increases by a different amount), then scroll anchoring failed. Any manual scroll command that moves the anchor (instead of pure browser reflow) invalidates the test. |
2. Default anchoring enabled: No special CSS; by default overflow-anchor: auto applies. | Repeat Case 1 with no overflow-anchor: none anywhere. | Scroll adjustment should occur as above. The browser’s built-in anchoring should preserve the viewport. | If nothing happens (page stays static despite insertion) or an unexpected shift occurs, anchoring is not functioning as documented. |
3. Overflow-anchor excluded: The scroll container or its ancestors include overflow-anchor: none. | Insert same content above, but on the container (or root element) set overflow-anchor: none. | No scroll adjustment should be made. The viewport should not move (or any movement should only be due to layout pushing content down, not a compensating scroll). | If the viewport still compensates (moves the scroll) despite none, anchoring was not truly disabled, failing spec. Conversely, if scroll moves when it shouldn’t, that’s also a failure. |
4. Script scroll vs browser scroll: Ensure any scroll offset change is due to browser, not script. | After insertion, record scrollTop without invoking any JavaScript scroll or setting scrollTop. | The only change in scrollTop should be the automatic adjustment. The evidence log must contain no call to .scrollTo or user-driven scroll that accounts for the change. | If a script or test utility explicitly sets scrollTop or triggers a scroll to reposition the view, the test is invalid. |
5. Negative control (no trigger): Insert content below the viewport or with size=0 (no effect). | Append (or insert inside) the content below the visible region or with zero height. | No scroll adjustment. scrollTop stays unchanged (final = initial). | If the browser unexpectedly scrolls anyway, anchoring is misfiring. |
Each case is paired with required evidence: measured values of scrollTop before and after insertion, and annotation of the action performed. A successful release outcome requires that in each case the observed change in scrollTop matches the expected outcome in the table. We explicitly reject any “success” signal that comes from a misplaced assumption rather than from captured evidence. For example, seeing the page content in the correct place after an insert is not sufficient; we need the raw scroll offset to prove the mechanism. We will log initial and final scrollTop, the inserted element’s height, and any relevant event traces (e.g. CSS reflow events, if accessible) for each scenario. Any test code or log output must include case identifiers so we can reconcile evidence to the manifest.
Finally, to clarify: the acceptance contract distinguishes browser-initiated scroll from application scroll commands. The browser’s scroll anchoring is only supposed to adjust the view automatically; if our test harness or application code issues a scroll request, that must be flagged and not counted as native anchoring. In practice, we will disable or avoid any programmatic scroll so only the browser’s own adjustment can occur.
2. Establish the documented baseline
We now lay out what the specifications and documentation say about each aspect of scroll anchoring. This “baseline” informs our expected behavior. CSS Scroll Anchoring Level 1 (W3C Working Draft) explains anchor node selection and scroll adjustment. In brief, the browser picks a suitable anchor node (a descendant of the scroll container) that is “anchorable” (not in an element with overflow-anchor: none) and close to the viewport’s top. When content above that anchor changes size or appears, the browser shifts the scroll position so that the anchor’s location in the viewport remains stable. MDN’s overview of scroll anchoring summarizes this: “Scroll anchoring adjusts the scroll position to compensate for changes outside of the viewport, meaning the point in the document the user is looking at remains in the viewport”. In practical terms, if we have a page already scrolled some amount, and then we insert new elements above the anchor, the scroll offset will increase by approximately the total height of the inserted content.
When overflow-anchor is explicitly set to none on an element, “the element won’t be selected as a potential anchor”. In fact, MDN notes that scroll anchoring is enabled by default, so disabling it (none) is only needed if anchoring causes a problem. Importantly, once an ancestor is opted out, children cannot re-enable anchoring, so any overflow-anchor: none anywhere above the anchor node should suppress anchoring entirely for that chain. We will verify this by setting overflow-anchor: none on the root or container and expecting no offset adjustment.
To distinguish browser vs script scroll: the documented API is Element.scrollTop (or window.scrollY for the page). Our tests will measure scrollTop immediately before and after insertion, without issuing any scroll() or setting scrollTop values in between. This ensures that any delta is the browser’s automatic adjustment.
Pin software versions and environment
For a reproducible release gate, we fix the software environment. We will use a recent Node.js LTS (e.g. Node 26.13.0) with Playwright 1.65.0 (which bundles Chromium 158.0.8127, Firefox 159.0, WebKit 27.2). These versions (as of Nov 2026) incorporate the relevant implementations of scroll anchoring. In particular, we note MDN’s compatibility statement: as of September 2026, scroll anchoring “works across the latest devices and browser versions”. We lock our test runners to exactly these versions (npm package.json with fixed versions) to prevent drift. The test machine should disable any browser extensions or custom scrollbar behaviors.
The pass/fail criterion for each test case is numerical equality (within sub-pixel tolerance) of the measured scrollTop change to the expected value. For example, if we insert a 100px-high div above the anchor, we expect scrollTop to increase by ~100. If the result diverges beyond a small epsilon (for sub-pixel rounding), the test fails. Any manual intervention or mismatch triggers a FAIL for that case, and the overall decision is REPAIR or HOLD. A fully passing suite (all cases as expected) results in ACCEPT for release.
3. Build a disposable controlled fixture
We create a minimal HTML/CSS/JS fixture that isolates scroll anchoring. For example:
HTML and CSS
<!DOCTYPE html>
<html><head><title>Anchoring Test</title><style>
  body, html { margin:0; padding:0; height:100%; }
  #scrollContainer {
    width: 100%; height: 400px; overflow: auto; border: 1px solid #ccc;
    position: relative; /* establish containing block */
  }
  #anchor {
    margin-top: 150px;
    width: 100%; height: 50px;
    background: lightblue;
  }
</style></head>
<body>
  <div id="scrollContainer">
    <div id="beforeAnchor">Static content above anchor.</div>
    <div id="anchor">Anchor Element</div>
    <div id="afterAnchor">More content below anchor...</div>
  </div>
</body></html>
JavaScript
const container = document.getElementById('scrollContainer');
// Ensure initial scroll is not at top
container.scrollTop = 150; // scroll so the anchor is partly visible, not flush
// Function to insert a new element above the anchor:
function insertNewAbove(contentHeight) {
  const newDiv = document.createElement('div');
  newDiv.style.height = contentHeight + 'px';
  newDiv.textContent = 'Inserted Content';
  // Insert at top of container (above all existing children)
  container.insertBefore(newDiv, container.firstChild);
}
// Function to measure scrollTop:
function logScrollState(caseId, step) {
  console.logCase ${caseId} ${step} scrollTop:, container.scrollTop);
}
Load the HTML and CSS first, then run the JavaScript shown above. The scrollContainer is the scrolling viewport (with fixed height), and #anchor is the element we will preserve. We programmatically scroll the container down so that the anchor is not at scrollTop=0. The function insertNewAbove can be called with a specific height (e.g. 100px) to simulate the test case of insertion. By controlling exactly where we insert (using insertBefore at the top of the container) and when (after setting scrollTop), we avoid side effects. The JavaScript logs scrollTop before and after each insert, prefixed with a case identifier. The console output or test harness log will serve as raw evidence.
This fixture is isolated and disposable: it does nothing else (no network, no images, no other CSS layout features). We will run it in a headless browser instance per case. After each run, we can simply reload the HTML to reset the state. By using exact fixed sizes and static content (no animations, no unpredictable fonts or images), we eliminate variability. We have separately prepared a similar fixture for the negative control (inserting below the anchor or inserting a 0px element) to ensure the behavior is off.
As in our CSS sticky overflow and scroll-container validation guide, we keep the fixture minimal and instrumented. All code shown above would be checked into a test directory (e.g. scroll-anchor-fixture). We use an exact Playwright test runner with the pinned browser binaries. The fixture HTML is served locally (or opened as a local file) so that it runs identically each time. Any command to run tests (for example, npx playwright test scroll-anchor-fixture.spec.js) is executed in a clean environment.
4. Freeze an independent expected-case manifest
Before running any tests, we document exactly what we expect for each scenario. This manifest acts as an oracle. Below is a table of test cases (independent of any actual results):
Case | CSS Setup | Action | Expected scrollTop Change |
A. Basic anchoring (EXPECTED) | Default CSS (no special rules) | Insert 100px-high element at top of container (above anchor). | scrollTop should increase by ≈100px. The anchor’s viewport position remains unchanged. |
B. Overflow-anchor none (EXPECTED) | #scrollContainer { overflow-anchor: none; } | Insert 100px element at top. | scrollTop should NOT change. The viewport will shift down as usual (new content pushes below) but browser will not compensate. |
C. Anchor disabled on anchor element (EXPECTED) | #anchor { overflow-anchor: none; } | Insert 100px at top. | Since anchor itself is opted out, the browser should pick a different anchor (likely static beforeAnchor or nothing). Likely no adjustment, or any adjustment applies to a different element. We expect no positive scroll delta for the original anchor. |
D. No insertion (control) (EXPECTED) | Default CSS | Perform a no-op (e.g. call insertNewAbove(0) or do nothing). | scrollTop remains exactly the same (no change). |
E. Insert below (EXPECTED) | Default CSS | Append a 100px element at the bottom of content (below anchor). | scrollTop should remain unchanged. Inserting below (outside viewport) should not trigger anchoring on the top. |
F. Content-visibility (control) (EXPECTED) | #new { content-visibility: auto; contain-intrinsic-size: 100px; } [if used] | Insert hidden element using content-visibility skipping. | No scroll adjustment, since element’s render is skipped. (This covers a boundary where layout above changes in theory but the browser treats it as outside rendered content.) |
Each case is marked EXPECTED in the manifest, since this is our hypothesis. We will not update the expected results after running tests; instead we compare observed results against this frozen specification. Note that cases B and C both test the exclusion API (overflow-anchor: none) on different elements; either way, if the anchor is excluded, no scroll anchoring should occur. The negative controls (D and E) prove that without a legitimate above-viewport change, there is no scroll adjustment.
Negative control: In addition to the above cases, the critical negative control is D. No insertion. This ensures that our measurement approach does not itself introduce a scroll (for example, via focus or re-render). Case D’s pass criterion is that final scrollTop - initialScrollTop = 0. If this fails, the test fixture is invalid and must be fixed before further testing.
5. Reproduce the misleading success case
A false-positive “success” can occur if we aren’t careful with initial conditions. For example, if the container’s scrollTop is already 0 (scrolled to top) and we insert content above, the viewport cannot move further up, so scrollTop remains 0. This may look as though the anchor stayed in place (and indeed it did), but in that case no anchoring was needed or possible (the user was at the top of the document). To avoid this confusion, we ensure the container is scrolled away from 0 before inserting. In our setup script we explicitly set container.scrollTop = 150; (non-zero) before running Case A. If we had left scrollTop=0, then observing scrollTop=0 after insertion would misleadingly appear “correct” when it was actually a suppression trigger. We mark such an outcome as EXPECTED (since spec permits no movement at scrollTop=0) and ensure not to confuse it with normal anchoring.
Similarly, if the anchor element has overflow-anchor: none (Case C), the browser will simply treat another node as the anchor (or none). If our test were naive and only looked at the original anchor staying still, we might think anchoring “worked” when in fact it failed (it chose a different anchor). Therefore, in Case C we declare the expected outcome as no scrollTop increase. If an investigator just checked “the anchor is still visible” they might falsely believe success; we guard against that by logging the raw values.
In short, any time the page ends in the “right place” by coincidence (scroll at 0, or anchor disabled), we must not misinterpret that as evidence of correct anchoring. We’ll mark those cases as EXPECTED in the manifest (they are expected by spec to not trigger an anchor shift) and verify the raw numbers (0 change). Only when raw data matches the declared expectation do we call it truly passing.
6. Run the valid comparison case
The core test is Case A from the manifest: default CSS, anchor-enabled, insertion above. We execute this in the fixture and capture evidence. In pseudocode, the procedure is:
logScrollState('A', 'before');    // record initial scrollTop
insertNewAbove(100);             // insert 100px-high content above anchor
logScrollState('A', 'after');     // record final scrollTop
We expect the output to look like:
Case A before scrollTop: 150
Case A after scrollTop: 250
(i.e. an increase of 100px). This raw evidence log is saved (e.g. JSON or console log). We do not rely on any assumption; the output is directly compared to the expected row “increase by 100”. We also capture a screenshot of the final DOM for human review, but it is secondary to the numeric data.
In this scenario, if the browser adjusts by the inserted height (100px), we tentatively label it PASS. If not, it is a FAIL. We do not accept a PASS signal merely because the anchor looks fixed; we insist on the number.
Make failure deterministic
To ensure reproducibility, the insertion is done in a controlled way. We wait for the insertion to complete and possibly for any pending layout, then immediately read scrollTop. In an automated test, we might use await container.evaluate((node) => node.scrollTop) after insertion. We avoid async delays like animations or setTimeout. The inserted element has a fixed height of 100px in CSS (via the fixture script), so there is no variability. The environment is fully headless and time-freezing is not needed here since everything is synchronous. We confirm that repeated runs in the same environment always yield identical scroll values. In practice, if the first run shows initial=150, final=250, we rerun without code changes to see if it is stable. That ensures the failure mode (if any) is deterministic.
7. Exercise negative and boundary controls
We extend testing to borderline cases:
Minimal insertion (boundary): Insert a very short element (e.g. 1px). Expected scroll change ≈1px. This confirms subpixel behavior and that even tiny layout changes are compensated. If the browser rounds down to 0 due to integer pixel math, that is a deviation we note (rare in modern browsers as MDN says scrollTop is subpixel-precise). We set the insert height to 1px, run the test, and expect finalScrollTop ≈ 151.
Over-range insertion: Insert content larger than the viewport (e.g. 500px above). The browser should still adjust by the full amount. We test with insert height = 500px; after insertion, scrollTop should increase by ~500 (from 150 to ~650). If it saturates or only scrolls to max, that’s a failure (though by spec it should not cap unless container’s content edge is reached).
Non-anchorable content: Insert an element with display:none or zero height. Scroll should remain unchanged. This is another form of negative control: ensure that only rendered height causes an adjustment.
Content-visibility edge: (Advanced test) Apply content-visibility: auto; contain-intrinsic-size: 100px to the inserted element. Because its content is “skipped” until drawn, the browser should not count it for anchoring until it becomes visible. We expect no scroll change initially. If the browser still adjusts, that may be a bug in how content-visibility interacts with anchoring (spec is silent here). We note this as a boundary exploration.
Each of these runs has a concrete pass/fail: e.g. for minimal insertion, pass if change=1 (or within rounding error); for non-anchorable, pass if change=0. These cases are logged with identifiers (e.g. “Case G: minimal height”) in the evidence ledger. If any boundary case fails spec (e.g. rounding error occurs), we record it but consider whether the contract might be too strict; minor rounding differences may not block release if documented.
8. Capture raw per-case evidence
For every test case (A through at least F, plus any boundary cases), we collect raw data. This includes: initial scrollTop, final scrollTop, the height of inserted content, and the final DOM length (as sanity check). Ideally we produce a machine-readable log (e.g. JSON) such as:
{
  "case": "A",
  "setup": "default",
  "initialScrollTop": 150,
  "insertHeight": 100,
  "finalScrollTop": 250
}
Our test harness will output one JSON object per case to artifacts/evidence.json (as in the CSS transition example). We will NOT rely solely on console messages or screenshots; the manifest reconciliation requires precise numeric evidence. Additionally, we take a screenshot or save the DOM for human auditing (but these are supplemental).
After capturing, we compile an evidence ledger table:
Case | Initial scrollTop | Final scrollTop | Delta (px) | Matches Expected? |
A | 150 | 250 | +100 | YES |
B | 150 | 150 | +0 | YES |
C | 150 | 150 | +0 | YES |
D | 150 | 150 | +0 | YES |
E | 150 | 150 | +0 | YES |
F | 150 | 150 | +0 | YES |
(Table entries above are illustrative.) This ledger is raw; we fill it from the logs we capture. Each row is one execution. We label each row with whether it matched the manifest. Any mismatches are flagged.
Reject missing or duplicate evidence
If any case’s evidence is missing (e.g. the test hung or crashed before logging “after”), that case is marked NOT EXECUTED and the release decision must be RERUN or HOLD. Duplicate entries (two identical logs for one case) indicate a test mis-run; we drop duplicates and require one unique log per case. The evidence ledger must have exactly one row per test case. If our log artifacts contain extra noise, we filter it out so the above table has clear 1:1 mapping. Any discrepancy (missing number, duplicate case IDs) invalidates that case’s result.
9. Reconcile byte, row or event identity
To ensure we know which evidence row corresponds to which scenario, we use unique identifiers and clear labeling. In practice, we prefix each log line with the case code (“Case A”, “Case B”, etc.). If our log is JSON, we include "case": "A" fields. The ledger table above explicitly names the cases. This way, we can match expected vs actual without ambiguity. We also record the exact test command used (e.g. npm test or playwright test) and the commit hash of the fixture code, so that the evidence is fully traceable.
If we had an automated test runner, each case might produce a separate row in a test report; we ensure those align to the manifest. This is similar to aligning event logs in our CSS transition test: each event log JSON entry is matched against the manifest row. Any extra “event” (e.g. a stray scroll event when none should fire) is noted. For scroll anchoring, the key “event” is simply the difference in scrollTop, but if available, we also capture the style change event or reflow timing to correlate that the measurement happened immediately after insertion.
10. Distinguish documented behavior from observation
With raw evidence in hand, we now compare to the documented baseline. For each case: does observed scrollTop change equal expected? If yes, we tentatively accept the behavior as compliant. If no, we must analyze why. For example, suppose in Case A we observe final scrollTop=248 instead of 250 (a 2px discrepancy). We would note that this likely comes from subpixel rounding, not a fundamental logic error. MDN says scrollTop is subpixel precise, so fractional results are allowed. We would mark this discrepancy as minor; the contract might allow a small tolerance (e.g. within 1px). On the other hand, if we saw final=200 (only +50px), that’s a major failure of anchoring.
We also check that the browser’s choice of anchor matches our intent. If the test fixture had multiple candidate anchors, the spec describes how the anchor is chosen (usually the topmost visible part). If we somehow configured multiple potential anchors, we must ensure the expected anchor was the one that stayed put. If our observation suggests a different element served as anchor (e.g. beforeAnchor rather than #anchor), we might accept the scroll difference but note the mismatch. That would be an “observational difference” with spec: perhaps our fixture should have used a single anchor element to avoid ambiguity.
In practice, we crafted the fixture so that the intended anchor is clear (#anchor with margin). If the observed scrollTop matches the insertion height, the browser likely anchored on #anchor. If not, something is off. We reconcile any such cases by editing the manifest or fixture. We do not change the expected result after seeing data; only code or CSS changes are allowed (covered in the next section). Thus, documented spec stays fixed, observations are checked against it.
Bound the repair
If we find a case where observed behavior contradicts the spec, we look for the smallest fix that brings it back into line. For scroll anchoring, typical repairs include adding overflow-anchor: none to elements to disable anchoring in parts of the page, or adjusting CSS so that the intended anchor remains the correct one. For example, if Case C (“anchor disabled”) unexpectedly still moved the page, we might suspect the overflow-anchor: none was applied to the wrong element. We would then move that property to the scroll container instead, or vice versa. The goal is to limit the fix to just the failing scenario without overkill. We document this “repair scope” so that, for instance, only the CSS of #anchor or #scrollContainer is changed, not unrelated code.
If the failure is due to a misunderstanding (e.g. we expected no movement but the spec says anchoring should happen on a different anchor), then the fix is to correct the manifest, not code. In any case, we keep a clear line between the fix applied and the overall acceptance criteria. Once we decide a fix, we proceed to validate it in the next section.
11. Repair the smallest failing boundary
Suppose, for example, that in Case B (overflow-anchor: none on the container) we still observed a slight scroll adjustment. Investigation might reveal that the inserted element was itself anchorable because the container’s overflow-anchor: none did not propagate as expected. A minimal repair could be: apply overflow-anchor: none also to the parent (e.g. body { overflow-anchor: none; }) to fully cut off anchoring. This would be our “repair.” Alternatively, if in Case C the wrong element was anchoring, we might add overflow-anchor: none to the other element as well so that the intended anchor is the only possible one. We would then rerun Cases B and C to see if they now behave as expected (Case B still no movement, Case C remains no movement).
Another possible small repair: if the anchor’s margin is pushing it slightly off, we could reduce margin to align with spec’s “first possible anchor at or near the top.” But that’s less likely needed. Usually, scroll anchoring problems are solved by disabling it on problematic elements.
We record the exact CSS snippet or change made as the repair. For traceability, this is kept minimal and we comment it in code. Then we re-run the affected test(s) to confirm they now match expected results. If the fix also impacts previously passing cases, we must reconsider the scope. We prefer targeted fixes over global ones to maintain rollback safety.
12. Test recovery and safe reruns
After applying any repair, we clear the environment and rerun the full suite of cases (A–F plus any controls) to verify that the behavior now matches the expected manifest everywhere. We ensure the test fixture is reset before each run (e.g. reload the HTML page, reset the scrollTop, remove any inserted elements from prior runs). This prevents state bleed between tests. Our harness might call page.reload() or re-launch the browser for each case. We capture the new evidence ledger.
For example, if we had to disable anchoring on the container, we would see that Case A now shows no movement (contradicting original expectation of +100). Realizing this, we adjust the manifest: maybe we decide that the application legitimately does not want anchoring and that our original expectation was wrong. Or if that was not intended, we might roll back. The point is to ensure that after fix, all evidence is clean. If any test still fails or any new side-effect appears, we address it before moving on.
Assign operational ownership
It should be clear who “owns” this test. We would typically assign it to the QA or frontend engineering team responsible for scrolling behavior. In a release plan, we specify: Owner: Frontend UI team (or the specific engineer) will maintain the test script and address any failures in future releases. The pass/fail criteria are written in the acceptance contract above. We would automate alerts so that if the test suite ever reports a discrepancy (or if the browser versions change), the owner is notified. We might create a small snippet like:
Test recovery step: reload fixture, rerun all cases, and log evidence again.
Ownership: Frontend team monitors scroll-anchor-fixture in CI.
Having one person or team responsible ensures accountability if scroll behavior changes.
13. Apply the ACCEPT / REPAIR / RERUN / HOLD matrix
Finally, we decide the release action based on the evidence ledger. This decision logic is summarized in the matrix below:
Condition | Decision |
All cases match expected outcomes (e.g. A=+100, B,C,D,E,F=0) within tolerance | ACCEPT: Scroll anchoring behavior is correct and release can proceed. |
One or two cases fail in a trivial way (e.g. minor pixel rounding) | REPAIR: Fix CSS (e.g. adjust anchor element or overflow-anchor) and rerun tests. If fix succeeds, then Accept. |
Tests could not be executed or incomplete evidence (some cases NOT EXECUTED) | RERUN: Environment or fixture issue. Diagnose missing evidence, rerun the tests. The decision is pending until all cases are executed. |
Major discrepancy (e.g. expected +100 but got +0 with no justification) | HOLD: Significant bug. Do not release. Developer investigation required. Possibly file a bug with Chromium/Firefox/Apple if it’s a spec violation. |
Documented conflict (spec says no scroll but observed movement, or vice versa) | HOLD/REPAIR: If it’s a spec misunderstanding, clarify the contract. If the browser deviated from standard, either apply a workaround (REPAIR) or hold if too risky. |
We will fill in this matrix after actual test runs. Each entry cites the specific case(s) involved and the discrepancy. For example, if Case A passes exactly but Case F (content-visibility) unexpectedly scrolled, we might label that as HOLD with a note on content-visibility limits. If all pass, we mark ACCEPT.
14. Connect the practice to Refonte Learning
This comprehensive validation practice exemplifies the rigorous engineering mindset taught in Refonte Learning’s Frontend Development program. In that program (a structured 3-month course requiring ~12–14 hours/week), students are trained to combine theory, coding, and testing in the same way. They learn core skills (HTML, CSS, JavaScript, and modern frameworks) and the habit of writing precise tests for edge cases, exactly as shown above. The four-stage Refonte journey (orientation, technical mentorship, placement support, continuity) ensures that graduates can apply such test-driven troubleshooting in real projects. Understanding scroll anchoring and mastering its verification would be a natural topic in the Frontend curriculum on browser layout and debugging.
Interested in leveling up your frontend skills and releasing confident web applications? Join Refonte Learning’s Frontend Development program (structured for beginners and intermediates alike) to practice these techniques under expert guidance. (The program includes mentorship at every stage and issues a Certificate upon completion.)