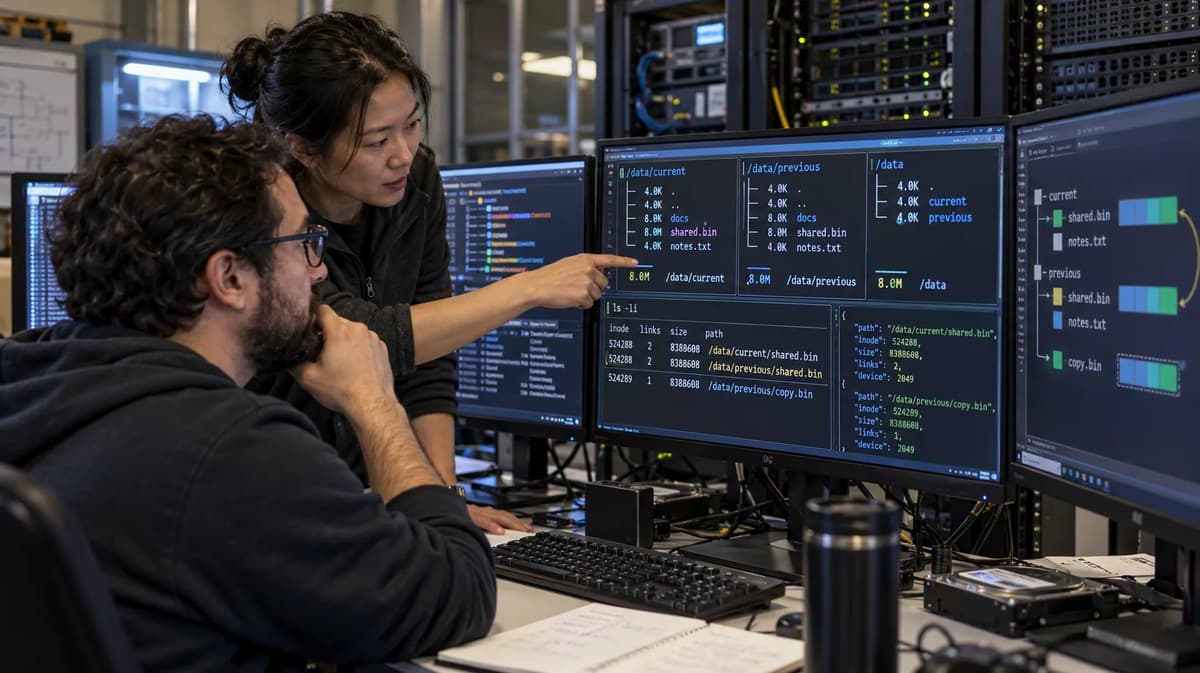
Why Separate du Totals Double-Count Hard-Linked Files
Both directory scans finish successfully. Each produces a plausible byte total, the reporting job adds them, and the dashboard publishes the sum as unique allocated space. Yet the two trees contain names for the same regular file. The arithmetic is correct for the collected numbers; the report’s interpretation has not survived the boundary between measurement processes.
This playbook qualifies that interpretation with a small Linux laboratory. A file under current also appears through a hard link under previous. A third file contains identical bytes but has an independent identity. An allocation ledger collected with stat supplies the expectations before the candidate totals are evaluated. The experiments separate one invocation from separate invocations, then vary argument order, link-counting policy, size metric and pathname input.
The approval target is narrow: allocated bytes attributed to unique filesystem objects in a declared, stable scope, including directory allocation when directory objects belong to that scope. Apparent length and deliberate per-name accounting answer different questions. None of these measurements establishes how many physical storage bytes removing a directory would recover.
The resulting evidence supports a concrete report decision. Accept a reconciled unique scope, relabel a verified per-name measurement, repair a divided scan boundary, rerun an unstable inventory, or hold an unsupported reclamation claim. The laboratory performs no transfer or deletion. Its intentionally unsuitable separate-scan total remains visible so that a successful diagnostic run cannot conceal a failed reporting policy.
Specify the capacity number the report is supposed to mean
Write the metric contract before collecting numbers. Identify the pathname set, whether operands are regular files or directory trees, the collection interval, exclusions and unit. A label such as “backup usage” leaves the essential accounting decisions unstated. Two collectors can produce different, internally consistent answers while both believe they measured that label.
For unique-object allocation, resolve the declared names to object identities and add each object’s reported allocation once. In this laboratory, identity means the device/inode pair and allocation means the product of the two relevant stat block fields. When the scope consists of the two directories, include those directory objects as well as their contents.
For apparent length, add the logical byte lengths of the unique regular-file objects in the selected file scope. For per-name accounting, charge each declared regular-file name its object’s allocation, even when several names identify one object. State whether any directory charges are also included.
Reclaimable physical storage is a separate proposed outcome of a future operation. A present allocation report does not establish that outcome. Keep it outside this approval.
Make scope exclusions reviewable: this fixture excludes the laboratory parent, the independent copy’s parent directory, evidence files and everything outside the selected operands. Avoid overlapping parent/child operands. Require the report to carry its metric and scope together; a bare integer cannot preserve either decision when copied into a spreadsheet or dashboard.
Distinguish shared object identity from equal content
Call the names a, b and c. The fixture writes a under current, creates b under previous as a hard link to a, and separately writes c under copy. All three contain the same authored byte sequence. Their content equality is deliberately unhelpful for deciding how many objects belong in the allocation sum.
The GNU explanation of hard links describes another name for the same inode and the restriction against crossing filesystem boundaries. That relationship lets the experiment vary the number of names without manufacturing a second regular-file object for b. It does not eliminate the directory entry or every possible metadata cost associated with another name.
Refonte’s adjacent treatment of hard-linked backup identity and content protection considers whether historical bytes survive an update. Here, the names remain unchanged throughout measurement. Their shared identity is evidence for accounting; this workflow neither creates a backup nor repairs one.
One inode can have two names without two allocations
An inode number alone is an incomplete key because the identity belongs to a filesystem. Keep the reported device number with it. The ledger must group a and b under one pair and keep c under another. Names remain attached to those groups as evidence of scope membership, rather than becoming the deduplication keys.
The link count supplies a useful precondition. The controlled shared regular file must report two links, while the separately written copy has its own identity. However, a link count is not a list of pathnames. Outside this laboratory, seeing two links would not tell the collector where the other name resides or whether it belongs to the report’s declared set.
Require records grouped under one identity to agree on the allocation being charged. If two aliases produce conflicting allocation fields during an audit, choosing the smaller value is not deduplication. The conflict is evidence that the collector has not established a coherent object record.
Review identity and content as separate columns. The expected content comes from the script’s fixed byte construction. The expected object grouping comes from the explicit link operation and checked device/inode relationships. If content matches but the supposed copy shares the same identity, the negative control is invalid. If the two intended hard links have different identities, the main experiment is invalid. Neither problem can be repaired by changing the expected total until it matches the output.
Freeze a same-filesystem fixture and explicit output units
The supplied October 20, 2026 preflight used CPython 3.13.5 and GNU du/stat 9.7. A new execution for this article started at 07:16:11 UTC on October 20, 2026, using CPython 3.12.14 and GNU du/stat 9.4. Both reported nine passing cases. These are separate execution records; neither version is presented as the newest release.
The reference contracts appear in the GNU Coreutils 9.7 manual source. The corresponding 9.4 definitions also support the options used in the additional run. The linked HTML manuals are living references, so retain the tested build versions with the evidence. Documented behavior supplies the contract; each recorded execution supplies observations for its own environment.
Use an owned scratch working directory and an ordinary local filesystem that supports hard links. The driver creates its own temporary root, three child directories and two independently written regular files. Its link operation and subsequent identity checks establish the intended relationship. A failed link or zero reported allocation for the shared regular file invalidates the fixture instead of becoming an alternative expected success.
This qualification is for GNU tools on Linux. BSD/macOS du options and output are outside its contract. The controlled objects contain no symlinks, and the audit introduces no symlink traversal, distributed filesystem, transfer operation or storage optimization. Keep those exclusions attached to any reuse of the findings.
No privileged command is needed. The driver accepts no production pathname argument. Keep its output redirection in the owned working directory, outside the measured trees. After setup, it reads the selected objects for the audit; it later writes evidence under the laboratory parent. “Read-only measurement” refers to the absence of content and namespace changes by the measuring code, not a claim that every access-related metadata field remains untouched.
The GNU block-size rules distinguish display units from filesystem block sizes and explain environment-controlled defaults. The fixture uses LC_ALL=C and --block-size=1 on every candidate du invocation. This makes its displayed quantities byte counts without guessing an allocation quantum.
Record source identity alongside runtime identity. The supplied script’s SHA-256 is c43d0a6412c8145fc99bcb8060a332116c3f75b27db78f7e397c4cd4412acc9e; the unchanged source used in the new execution matched it. That digest identifies code, not shared filesystem objects.
Treat this preparation as part of system administration capacity responsibilities: a repeatable number needs a stated question and a known collection environment. Retain the actual versions, scope and evidence together so that a later change can be investigated without guessing which command or laboratory produced the earlier report.
Build the complete independent accounting harness
Save the following complete source as du_probe.py in the owned working directory. Run it there with the command shown. It uses Python’s standard library and the GNU executables available through PATH; there are no undisclosed input files or packages.
python du_probe.py > du-results.json
from pathlib import Path
import hashlib
import json
import os
import platform
import subprocess
import tempfile
def require(ok, message):
if not ok:
raise AssertionError(message)
root = Path(tempfile.mkdtemp(prefix="du-hardlink-"))
a, b, c = [root / x / "asset.bin" for x in ("current", "previous", "copy")]
for p in (a, b, c):
p.parent.mkdir()
content = bytes(range(256)) * 32
for p in (a, c):
with p.open("wb") as f:
f.write(content)
f.flush()
os.fsync(f.fileno())
os.link(a, b)
env = dict(os.environ, LC_ALL="C")
commands = []
def invoke(argv, stdin=None):
r = subprocess.run(argv, input=stdin, capture_output=True, env=env, timeout=10)
require(r.returncode == 0, f"failed: {argv}: {r.stderr!r}")
commands.append({"argv": argv, "rc": r.returncode, "stdout_hex": r.stdout.hex(),
"stderr": r.stderr.decode()})
return r.stdout
def stat(p):
v = list(map(int, invoke(["stat", "--printf=%d %i %h %s %b %B", "--", str(p)]).split()))
dev, inode, links, size, blocks, block_unit = v
return {"dev": dev, "inode": inode, "links": links, "size": size,
"blocks": blocks, "block_unit": block_unit, "allocated": blocks * block_unit}
def du(paths, extra=(), stdin_list=False):
argv = ["du", "--null", "--summarize", "--block-size=1", *extra]
stdin = None
if stdin_list:
argv += ["--files0-from=-"]
stdin = b"".join(os.fsencode(p) + b"\0" for p in paths)
else:
argv += ["--", *map(str, paths)]
output = invoke(argv, stdin)
pairs = []
for line in output.split(b"\0"):
if line:
amount, name = line.split(b"\t", 1)
pairs.append({"bytes": int(amount), "path": os.fsdecode(name)})
return {"total": sum(x["bytes"] for x in pairs), "rows": pairs}
before = {str(p): stat(p) for p in (a, b, c, a.parent, b.parent)}
sa, sb, sc = [before[str(p)] for p in (a, b, c)]
require((sa["dev"], sa["inode"]) == (sb["dev"], sb["inode"]), "hard-link identity")
require((sa["dev"], sa["inode"]) != (sc["dev"], sc["inode"]), "copy identity")
require(sa["links"] == 2 and sa["allocated"] > 0, "fixture allocation/link precondition")
require(a.read_bytes() == b.read_bytes() == c.read_bytes() == content, "content precondition")
allocated = sa["allocated"]
rows = []
def record(case, observed, expected, note):
require(observed["total"] == expected, f"{case}: {observed['total']} != {expected}")
rows.append({"case": case, "expected_total": expected, "note": note, **observed})
record("D1", du([a]), allocated, "single regular-file operand")
record("D2", du([a, b]), allocated, "one invocation deduplicates shared inode")
separate = [du([a]), du([b])]
record("D3", {"total": sum(x["total"] for x in separate), "parts": separate},
2 * allocated, "separate processes do not share seen-inode state")
reverse = du([b, a])
record("D4", reverse, allocated, "reversing arguments changes attribution, not union total")
require(reverse["rows"][0]["path"] == str(b), "reverse attribution")
record("D5", du([a, b], ["--count-links"]), 2 * allocated, "per-name accounting requested")
record("D6", du([a, c]), allocated + sc["allocated"], "equal bytes do not imply shared inode")
record("D7", du([a, b], ["--apparent-size"]), len(content), "apparent-size union, not allocation")
dir_union = du([a.parent, b.parent])
dir_separate = du([a.parent])["total"] + du([b.parent])["total"]
expected_dirs = allocated + before[str(a.parent)]["allocated"] + before[str(b.parent)]["allocated"]
record("D8", dir_union, expected_dirs, "directory allocation included in independent oracle")
require(dir_separate - dir_union["total"] == allocated, "directory split double count")
rows[-1]["separate_directory_total"] = dir_separate
record("D9", du([a, b], stdin_list=True), allocated, "NUL manifest, one invocation")
require({str(p): stat(p) for p in (a, b, c, a.parent, b.parent)} == before,
"fixture identity, size or allocation changed during read-only measurements")
report = {"status": "PASS_9_CASES", "python": platform.python_version(),
"du": invoke(["du", "--version"]).decode().splitlines()[0],
"stat": invoke(["stat", "--version"]).decode().splitlines()[0],
"source_sha256": hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
"root": str(root), "stat_before": before, "rows": rows, "commands": commands}
(root / "evidence.json").write_text(json.dumps(report, indent=2))
print(json.dumps({k: v for k, v in report.items() if k != "commands"}, indent=2))
The fixed input is 8,192 authored bytes: all byte values repeated 32 times. Two writes are flushed and synchronized before linking and measurement. require stops the run on a failed precondition, command or expected relationship. Each subprocess has a ten-second timeout. A failure calls for investigation; it does not authorize weakening an assertion or substituting production data.
Do not infer completion merely from the redirected JSON file’s existence. Require a successful driver exit and a parseable final report with the expected status. Reports and the temporary root are printed only after successful checks; failure can leave the accumulated command log unwritten. Retain the terminal error. Empty output is not a valid zero measurement.
For successful subprocess calls, invoke retains argument arrays, return codes, hexadecimal stdout and stderr. du parses NUL-terminated records and separates the amount from the pathname at the first tab only. It aggregates the selected summary rows; no grand-total option is present. Its total field is therefore a harness calculation whose aggregation rule can be inspected.
Multiply stat blocks by the reported block unit
The GNU file-format directives for stat define %d, %i, %h, %s, %b and %B as device, inode, link count, byte length, allocated block count and the byte unit of that count. Multiply %b by %B; do not substitute an assumed 4,096-byte block size or an I/O transfer hint. These are file-status directives, without stat -f.
The raw JSON preserves a record per pathname. For object accounting, group those records by device/inode. The following independent ledger shows that grouping for the new execution; the displayed identities are local observations, not portable fixtures.
Device/inode key | Names relative to the laboratory | Links | %s bytes | %b × %B | Allocated bytes |
27:395168 | current/asset.bin, previous/asset.bin | 2 | 8,192 | 16 × 512 | 8,192 |
27:395169 | copy/asset.bin | 1 | 8,192 | 16 × 512 | 8,192 |
27:395165 | current directory | 2 | 4,096 | 8 × 512 | 4,096 |
27:395166 | previous directory | 2 | 4,096 | 8 × 512 | 4,096 |
The supplied code implements a fixed-scope oracle through identity assertions and these independent allocation fields; it is not a generic recursive group-by scanner. None of its expected totals comes from another candidate du total. The final comparison rereads the selected stat fields and requires them to match the initial records.
The report prints the temporary root and writes evidence.json there after the checks. Standard output omits the command log, so preserve both it and the full evidence file. The exact source and recorded root reconstruct D9’s input; the command log itself does not capture stdin bytes. Keep that distinction when handing off the run.
The 512-byte stat unit in the displayed ledger is independent of du’s one-byte display unit. Multiplication converts allocation to bytes; the display option prevents additional unit rounding from obscuring comparison. Retain the known owned laboratory until the necessary evidence has been preserved, and restrict any later housekeeping to that identified laboratory.
Measure a shared inode in one invocation
D1 establishes the smallest allocation relationship: pass only a and compare the result with its independently measured allocation. Call that allocation A. In the supplied preflight, A was 8,192 bytes. The new execution also measured 8,192. The assertion uses the current run’s stat value, so agreement does not depend on preserving that particular number across filesystems.
D2 passes a and b to one process. The GNU du hard-link accounting contract normally counts the shared file once and allows argument order to affect both charges and printed entries. D2’s expected union is therefore A, with two names mapped to one identity.
The new run printed one D2 row, attributed to current/asset.bin. It did not print an additional row for previous/asset.bin. This observation matters for parsers: a request containing two names need not yield two summary records. The independent identity check and successful process result explain the omitted duplicate charge. Output row count alone would be an inadequate inventory check.
The complete case ledger below keeps expectations separate from observations. C means the copy’s stat allocation, Dc and Dp the two directory allocations, and L the authored regular-file length. The first observed column reproduces the supplied preflight; the second comes from the retained execution performed for this article. Agreement between them is evidence from these records, not a portable output promise.
Case | Measurement | Independent expected relationship | Supplied 9.7 preflight bytes | New 9.4 run bytes |
D1 | a alone | A | 8,192 | 8,192 |
D2 | a, b jointly | A | 8,192 | 8,192 |
D3 | Separate a and b scans, summed | 2 × A | 16,384 | 16,384 |
D4 | b, a jointly | A | 8,192 | 8,192 |
D5 | a, b with --count-links | 2 × A | 16,384 | 16,384 |
D6 | a, independent c | A + C | 16,384 | 16,384 |
D7 | a, b with --apparent-size | L | 8,192 | 8,192 |
D8 | current, previous jointly | A + Dc + Dp | 16,384 | 16,384 |
D9 | a, b through NUL stdin | A | 8,192 | 8,192 |
Read D1 and D2 together as a controlled comparison. The reported allocation is unchanged when the second name enters the same accounting domain. The file scope contains one object, and the candidate measurement reconciles with the object ledger. That establishes the mechanism needed for the later directory report, without importing directory costs into the file-only baseline.
If D1 disagrees with the independent allocation record, investigate that baseline before interpreting the multi-name cases. A later ratio between two candidate outputs cannot repair a missing allocation foundation. Keep the distinction between checking a number against the oracle and comparing two numbers that might share the same measurement defect.
Preserve the actual rows as well as their sum. A downstream transformation that manufactures one full charge for every requested name would undo the verified behavior after collection. A display may list all scoped names, but it must distinguish inventory membership from a newly chargeable object. The reconciliation belongs to the complete collection-and-report path, including transformations after du exits.
Split the measurement and reproduce the doubled total
D3 changes the process boundary while retaining the same two names. The driver calls du([a]), calls du([b]), then adds the two returned totals. Each subprocess completes successfully and each reports 8,192 bytes in both recorded runs. Their sum is 16,384. The intended unique regular-file scope still contains the single shared identity.
Do not diagnose this result merely by noticing that D3 differs from D2. The independent ledger establishes A, and the authored case definition predicts that each isolated measurement charges that object. D3 is therefore 2 × A; the unique-scope expectation remains A. The excess is exactly one independently measured allocation, which identifies the accounting error more precisely than a general complaint about inconsistent totals.
Nothing in this comparison indicates changed file content or failed I/O. The selected identity and allocation fields matched in the before and after checks. The defect is in composing results whose scopes overlap in object identity. Correct component measurements can become an incorrect union report when the aggregator assumes those scopes are disjoint.
A shell loop or batching boundary can reset deduplication
A collector organized as one process per directory has the same conceptual boundary as D3. Running those processes sequentially, concurrently or through a scheduler does not supply them with a shared inventory of already-accounted objects. Repeating the individual commands can reproduce the same unsuitable aggregate reliably.
Repair the collection boundary when the requested metric is a union. Supply the declared operands to one invocation, or use the NUL input mechanism demonstrated later to preserve that invocation when the pathname set is long. Then reconcile the new measurement against the independently collected identity ledger. Merely subtracting the last observed excess would encode a temporary fixture relationship as a permanent correction.
For a broader scope, an object could appear in several separately scanned trees and have several names within each tree. The sum of default scans would reflect which processes encountered it, while each scan could suppress its own duplicate links. Consequently, separate totals are not automatically a consistent per-name measure either. D3 equals D5 numerically because this controlled case presents one name to each isolated scan.
This is distinct from rsync transfer selection as a separate contract, where the question is which destination bytes a transfer policy admits. A transfer option cannot repair a report assembled from overlapping measurement scopes. Preserve that separation when assigning the correction: the collector’s invocation boundary is the relevant change here.
Reverse arguments and inspect attribution
D4 supplies b before a. Its independently authored expectation is still A: reversing a list changes neither the set of names nor their device/inode grouping. The harness checks that the union total remains correct and that the first printed row names b. This is an attribution control, with a separate assertion beyond total equality.
In the new execution, D2’s single row named current/asset.bin; D4’s single row named previous/asset.bin. Each carried 8,192 bytes. The ledger before and after the measurements remained unchanged in the selected fields. Nothing was moved between directories, copied into another inode or removed. Only the order of the two operands changed.
This prevents a tempting report interpretation. The path printed beside the charge is where this ordered scan accounted for the shared object. It does not establish exclusive physical ownership by that directory, and the absence of a second charge does not make the other name independent of the file. The names retain their shared identity regardless of which one appears first.
Suppose a dashboard compares per-directory contributions from two runs whose operand order differs. A changed contribution could look like growth in one tree and shrinkage in another even when the object union is unchanged. In this laboratory the order control supplies a concrete explanation for that possibility. A reviewer should inspect collection order before treating attributed contributions as evidence of moved capacity.
Choose a stable operand order if consistent presentation matters. Record that order with the command, because an unordered pathname set is insufficient to reproduce the attribution. Stable order makes the report easier to compare; it does not convert attribution into a filesystem property or settle a business allocation policy.
If different teams need costs assigned to different directory owners, establish that reporting policy separately. The local experiment supplies a union allocation and an explanation of overlapping names. It does not choose which team should receive the charge. Avoid quietly using first occurrence as a business rule simply because the command already emits that layout.
Treat a changed union after reversing this fixed, stable scope as a failed reconciliation. Inspect the exact operands, options, raw output, identity records and selected allocation fields. Do not dismiss every mismatch as an order effect: the tested effect is a changed charged path with an unchanged union. The independent oracle gives the reviewer a boundary between an expected attribution change and a result that needs investigation.
Compare intentional per-name counting and equal-content copies
D5 explicitly requests --count-links. The GNU definition of this option includes a file’s size again when another hard link is encountered. The expected value for the two declared file names is 2 × A. Both executions reported 16,384 bytes, and the new run retained two separate 8,192-byte output rows.
That result is useful when the report deliberately charges every declared name. It is unsuitable for the unique-object contract. Qualification therefore depends on a label and an approved purpose as well as arithmetic. A reviewer may choose RELABEL_PER_NAME_METRIC for the verified D5 result when the scope owner actually wants that metric.
Do not use relabeling to conceal D3’s aggregation defect. Its agreement with D5 is a property of the small fixture, not evidence that arbitrary separate directory totals implement per-name accounting. Confirm that the collector intentionally counts the selected names under one consistent policy before changing the report’s meaning.
D6 supplies a and independently written c to one invocation. The two device/inode pairs differ, so the expected allocation is A + C. The oracle uses c’s own stat allocation rather than assuming every equal-length file has the same allocation. In both recorded executions, C happened to be 8,192, producing 16,384 bytes.
Do not use checksums as a replacement identity key
The byte comparison passes for all three names: a, b and c match the authored content exactly. Nevertheless, the object ledger groups only a and b. This is the negative control that prevents a content-based deduplication rule from appearing correct simply because the main pair also contains equal bytes.
A collector that collapsed equal-content files into one ledger entry would understate D6’s measured object allocation. A collector that treated every pathname as a distinct allocation would overstate D2. Both errors can survive a content check, because content equality answers neither the identity question nor the intended multiplicity of a charge.
The source hash serves a different purpose again: it records which experiment was executed. It should never be reused as a model for identifying shared data objects. Keep code provenance, content verification and object identity as separate evidence fields, with an explicit reason for each.
The independently written copy establishes a separate inode and reported allocation in this experiment. It does not inspect physical extents or prove that every underlying storage layer stores identical bytes independently. That additional proposition lies outside the inode accounting metric approved here.
Separate apparent size from allocated space
D7 keeps the a/b file scope and selects --apparent-size. Its expected result is the length of the authored content: 8,192 bytes, counted once for the shared regular-file identity. The expected value comes from len(content), while the earlier allocation expectations came from stat blocks multiplied by their reported unit.
In both recorded executions, D7 equaled D2 numerically. The regular file’s logical length and reported allocation were each 8,192 bytes. That coincidence is a useful control because it forces the report definition to do work that the number alone cannot do. Changing the measurement method can leave an integer unchanged while changing its meaning.
A report column should therefore say whether it contains unique regular-file apparent bytes or unique-object allocated bytes. Keep the selected mode in the collection record. If a wrapper changes options but leaves a generic “bytes” column unchanged, a later reviewer cannot establish that two historical points measure the same quantity merely because they are close.
The GNU apparent-size option definitions also make --bytes equivalent to apparent-size accounting with one-byte display units. It is not a substitute for the fixture’s allocation-preserving --block-size=1. D7 qualifies only its regular-file scope; it does not establish a general directory apparent-size policy.
This experiment does not manufacture a sparse file or establish a universal allocation-to-length ratio. Its purpose is to keep two valid quantities from becoming interchangeable by accident. The copy control likewise does not authorize assuming that equal apparent lengths imply equal allocated sizes on another run.
When reviewing an apparent-size result, reconcile the selected regular-file identities and their lengths. When reviewing allocation, reconcile the selected object identities and allocation fields, including directories where specified. Retain both measurements if both questions matter, but keep their expectations and labels distinct.
Use separate report fields for metric, unit and value. That representation makes a mode change visible even when the two recorded byte counts happen to match exactly.
A successful allocation audit does not approve an apparent-length report automatically, and an apparent-length match cannot rescue an allocation mismatch. If the requested metric is unclear, have the scope owner define it before acceptance. If the collector selected the wrong mode, correct that choice and rerun the declared scope instead of treating the observed equality in this laboratory as permission to substitute metrics.
Reconcile directory totals without hiding metadata overhead
D8 changes the scope from two regular-file names to their two containing directories. This is the shape closest to the original reporting problem. Each directory contains one name for the shared file. The scope now includes the current directory object, the previous directory object and the shared regular-file object once.
The independent allocation expectation is A + Dc + Dp. The supplied preflight’s 16,384-byte union implies 8,192 bytes of combined directory allocation after subtracting the shared file. In the new run, stat reported 4,096 for each directory, again yielding a 16,384-byte union. Another filesystem or directory representation may report different values; the harness derives its expectation from the corresponding stat records.
The new joint scan attributed 12,288 bytes to current and 4,096 to previous. The first contribution includes its directory allocation and the shared file. The second includes its directory allocation without charging the file again. Both directory names remain in the output even though the earlier file-only control omitted the already-counted second file operand.
The new run’s separate directory scans produced 12,288 bytes each, totaling 24,576. The supplied preflight also recorded that aggregate. Subtract the joint result and the excess is 8,192, equal to the independent shared-file allocation. The directory costs occur in both sides of this reconciliation and cancel from the difference. That algebra identifies the duplicate regular-file charge without pretending the directories have no cost.
A file-content sum would expect only 8,192 and misdiagnose the valid directory union. Conversely, adding a guessed metadata allowance would weaken the oracle. Keep the two directory records explicit, with their own identities and reported allocations. This accounts for the directory objects measured here, not every filesystem metadata structure or underlying-device overhead.
Do not add a printed grand total to its own components
The fixture does not request --total. If a reporting wrapper later enables it, choose one aggregation level: use the printed grand total, or sum the intended component summary rows. Never add that total to the components it already represents. A parser that blindly sums every numeric record would introduce a second accounting defect unrelated to hard links.
Make the row-selection rule part of review. Identify which entries are scope components, which are presentation totals and whether any parent row already includes descendants represented elsewhere. For this fixture, the only D8 components are the two disjoint directory-root rows. The laboratory parent, copy directory and evidence file are excluded. An aggregation change needs reconciliation against that same declared object set before the revised report is accepted.
Keep a complete NUL-delimited manifest in one accounting domain
D9 returns to the a/b file scope but delivers the names through standard input. The driver constructs one byte sequence containing a, a NUL terminator, b and another NUL terminator. One du process receives it through --files0-from=-. The independent expectation remains A, and both recorded executions produced 8,192 bytes.
The GNU --files0-from interface accepts NUL-terminated names and uses standard input when the source is -. It avoids placing a long pathname set in the command’s argument list. The accounting requirement is that the complete declared set reaches the same invocation.
NUL framing preserves pathname boundaries without treating embedded line breaks as new records. On output, the driver also requests NUL termination and splits each record only at its first tab. The amount is parsed numerically; the remaining bytes represent the name. Input framing and output parsing are separate parts of the evidence path.
The fixed fixture uses simple generated names. It demonstrates the selected transport and parser structure, not an exhaustive filename test suite. Preserve its exact source when reproducing the nine cases. If a production collector accepts a wider pathname population, qualify that collector’s path handling separately while retaining the same declared accounting policy.
Keep manifest completeness distinct from command completion. A successful process can measure precisely the names it received while the upstream inventory omitted an intended tree. Record the ordered scope, its origin, exclusions and collection interval. The manifest should identify the report’s inputs rather than depend on an undocumented shell expansion whose result is lost after execution.
The unchanged driver constructs D9’s manifest in memory and does not write a standalone manifest file. Its source, root and fixed relative names reconstruct the exact input. For an operational collector handling an externally assembled set, retain the actual NUL-delimited input alongside the command and output. Do not claim that recording --files0-from=- alone preserves what arrived on stdin.
This is a narrow application of repeatable system-administration automation: make the measurement contract survive automation boundaries. The important repair is to keep the complete scope in one accounting process and retain enough evidence to reproduce it.
A NUL manifest solves pathname delivery, not source stability. Names can resolve to changed objects between inventory creation and measurement. One invocation also does not remove resource limits or make a changing tree atomic. D9 earns approval only together with the identity, allocation and stability evidence supporting the same scope.
Handle unstable inventories and unsupported storage claims
The final assertion rereads five known paths and compares their selected device, inode, link-count, size and allocation fields with the initial records. That is a useful rejection check for this privately controlled laboratory. It is not proof that every possible metadata field stayed unchanged or that no transient change occurred between the two observations.
A live changing tree is not an atomic snapshot. A name could be replaced, an allocation could change or an entry could appear while a collector proceeds through its operands. Two endpoint checks might miss a change that was reversed before the second observation. Strong reconciliation therefore requires a controlled source, or an appropriately stable source view supplied through a separately qualified process.
Choose RERUN_UNSTABLE_INVENTORY when the scope cannot be established or the selected identity/allocation evidence changes during the audit. Preserve the failed measurements and the field differences. Obtain a stable collection condition, then recollect both the independent ledger and the candidate result. Mixing a new ledger with an old total would combine evidence from different inventories.
Record the inventory and measurement intervals together. Their relationship matters because a manifest prepared earlier can describe names whose present identities require fresh verification at collection time.
Do not infer stability merely from matching content. The independent copy already shows why equal bytes cannot identify a shared object. Likewise, a successful return code establishes that the particular command completed, not that every name represented the same object throughout an independently running inventory.
Unique-inode allocation is not a deletion-savings guarantee
The GNU discussion of underlying-device limitations warns that operating-system allocation reports can diverge from physical storage consumption, including with copy-on-write, compression and network storage. The present acceptance concerns the reported allocation attributed to unique identities, under the laboratory’s narrow assumptions.
Reflinks, storage-layer deduplication, snapshots and open-unlinked files introduce questions this ledger does not answer. Even without those mechanisms, finding a name under one directory does not prove that directory exclusively controls the corresponding object’s lifetime. A remaining hard link outside a proposed removal scope is enough to make exclusive ownership an unsupported assumption.
Use HOLD_RECLAIM_CLAIM when a report turns the reconciled allocation into promised deletion savings. Ask for a separate storage-specific analysis of references, retention and the storage layer that would actually return capacity. The correct response is to hold that claim while retaining the valid inode-accounting evidence. This laboratory supplies no deletion commands and does not extend into storage administration, quotas or a comprehensive diagnosis of free-space reports.
Accept, relabel, repair, rerun or hold the report
Assign three responsibilities. The scope owner defines what the number means and which paths belong. The collector preserves that scope, executes the selected measurement and retains evidence. The capacity-report reviewer reconciles the independent object ledger with the published metric and records the decision. A passing subprocess cannot discharge all three responsibilities.
Decision | Required evidence | Responsible next action |
ACCEPT_UNIQUE_SCOPE | Stable declared scope; one invocation; device/inode grouping, explicit units and directory overhead reconcile | Reviewer approves the specific metric and scope |
RELABEL_PER_NAME_METRIC | Deliberate, verified per-name policy such as D5; scope owner wants that meaning | Owner approves the label; collector preserves the policy |
REPAIR_SCAN_BOUNDARY | Separate-process aggregation over shared identities fails the unique-scope contract | Collector supplies the union to one invocation and reconciles again |
RERUN_UNSTABLE_INVENTORY | Scope, identity or allocation changes, or stability cannot be established | Collector obtains stable input and recollects both evidence sets |
HOLD_RECLAIM_CLAIM | Claimed deletion savings exceed the available accounting evidence | Reviewer holds the claim pending separate storage-specific analysis |
D2, D4 and D9 support the unique regular-file scope; D8 supports the directory union after its two directory allocations are included. D5 supports an intentional per-name interpretation. D6 protects the identity rule, and D7 validates the distinct apparent-length comparison. D3 remains the demonstrated unsuitable union candidate even though its diagnostic assertion passes.
When correcting an already published number, preserve both raw measurements. Keep the original scope, command, output and label, then attach the corrected collection and reconciliation. State whether the correction changed process boundaries, units, the object set or the meaning of the metric. Otherwise a lower revised number can be mistaken for newly freed storage.
Apply decisions to specific claims. One report can contain an accepted allocation measurement and a held reclamation assertion. Relabeling also requires a real change in the owner’s requested meaning: if the owner still requires unique allocation, a correctly collected per-name result remains unsuitable. The collector should repair the measurement instead of redefining the request unilaterally. Record that choice so a later reviewer can distinguish a corrected implementation from an intentionally different capacity question.
For the recorded directory case, the correction is specifically from a 24,576-byte sum of separate scans to a 16,384-byte joint allocation report. The shared object’s independent 8,192-byte allocation explains the difference. The experiment records no intervening deletion.
These ownership and evidence practices connect directly with systems-administration monitoring and maintenance skills. Carry the decision, responsible reviewer and retained evidence into routine reporting so that later changes to the collector or scope trigger a deliberate reassessment.
Develop wider Linux capacity and troubleshooting practice
A useful capacity report lets another administrator reconstruct what was counted, why each object contributed and where the measurement’s authority ends. This exercise makes those requirements concrete. The shared file, independent equal-content copy, reversed operands and directory ledger each remove a different ambiguity that a successful command alone would leave unresolved.
The operational habit is to keep the requested metric connected to its evidence. Define the scope before collecting, preserve object identities across aggregation, express units explicitly and reconcile against an independent ledger. When the measurement disagrees with the intended contract, change the collector or the approved interpretation and retain the comparison that explains the correction.
That discipline makes the narrow acceptance useful beyond the laboratory without turning it into a universal storage claim. A reviewer can approve the reported unique allocation for the measured object union, explain why a separately summed number was unsuitable, and identify exactly which further question remains unanswered.
To connect this audit with wider Linux, backup and troubleshooting practice, review the System Administration Program. Its detailed program section lists six months at 10–12 hours per week, while its recommendation card states three months. Confirm the current duration and applicable admission requirements with the provider before enrolling.