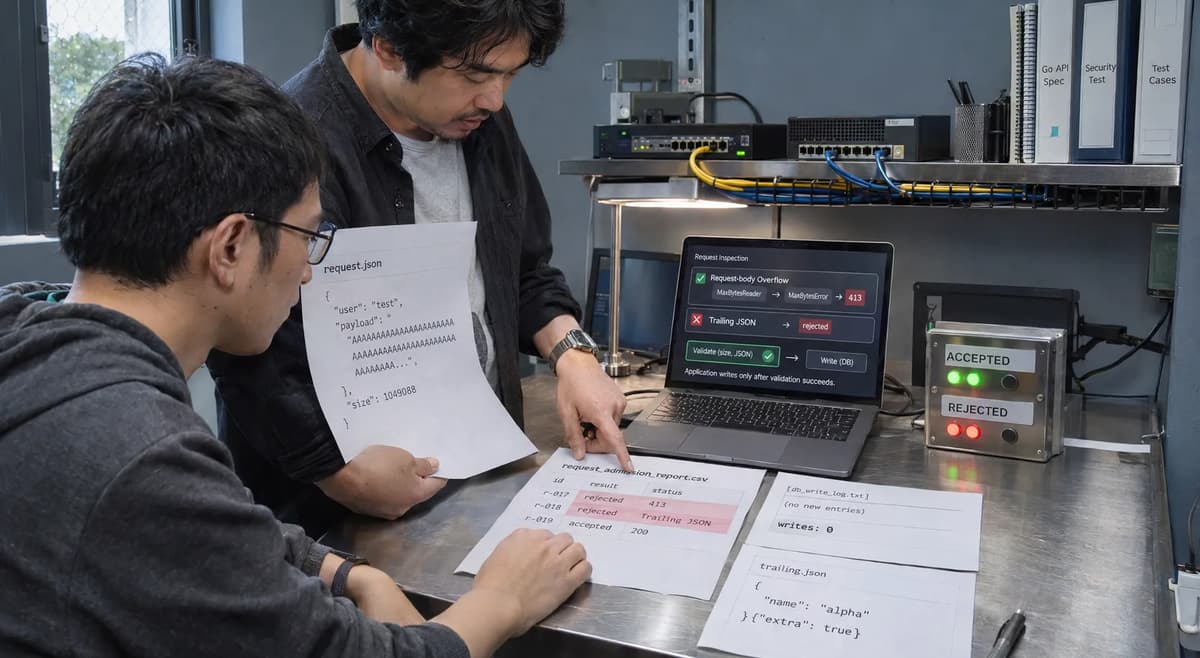
A common failure mode in Go HTTP handlers is assuming that a successful Decode or write call implies the entire request body was accepted under the application’s policy. In reality, Go’s http.MaxBytesReader enforces a request-body limit, and json.Decoder.Decode by itself only reads the next JSON value. The true contract of a single-object JSON endpoint is: “Exactly one JSON object of at most N bytes, with no trailing data, must be admitted before any side effects occur.” The review decision must be based on evidence about what actually happened at runtime, not just success flags. Was the write (or other side effect) correctly withheld if the body was too large or had extra data? We answer that by running isolated tests, comparing outcomes to the documented contracts, and checking if the observed state matches the intended state. The final choice is not “did the function return success?” but “should we ACCEPT, REPAIR, RERUN or HOLD this release candidate given the evidence?”
1 Define the exact admission contract
First, write down exactly what the endpoint is supposed to accept before looking at the code. For example: “This endpoint requires a single JSON object with a non-blank request_id string. No other top-level value is allowed. The object must contain no unknown fields (we will use Decoder.DisallowUnknownFields), and the entire request body must be ≤ 128 bytes. Only after all these checks pass may the handler perform its first side effect (e.g. writing to a database).” Put another way, the contract is application-level: a single well-formed JSON object (matching our struct) and no extra data or excessive size. Anything violating that should be rejected before mutating state.
Go’s documentation makes clear that these are not automatic: MaxBytesReader only limits raw bytes read, and json.Decoder.Decode only reads one JSON value. A successful Decode does not guarantee the entire body was consumed or within limits. For example, the RFC 8259 JSON spec defines a JSON text as one value (whitespace*), but it says nothing about enforcing body size or application schema. We impose that in policy.
Concretely:
Root shape: only a JSON object (not array or primitive). We check Decode(&obj) into a struct.
Schema rules: object must have a request_id field that is non-empty. We use struct tags and DisallowUnknownFields for strict matching.
Max size: wrap r.Body with http.MaxBytesReader(w, r.Body, 128). According to Go docs, this returns a ReadCloser with an internal 128-byte cap; any read beyond 128 bytes produces a non-nil *http.MaxBytesError. That error type carries the Limit.
No trailing data: after the first Decode into our struct, we must call Decode again and expect exactly io.EOF. If we get any other error or value, it means extra non-whitespace bytes were present. The only acceptable “extra” is EOF.
Use errors.Is(err, &http.MaxBytesError{}) or errors.As to detect a MaxBytesError explicitly. That distinguishes “body was too large” from syntax errors. Document these decisions before reading code: the reviewer should answer “what shape, size, suffix, and position of side-effect” from policy. With that, nothing about the code can retroactively change whether the policy was met.
The adjacent Refonte playbook on JSON trailing data emphasizes exactly this separation of concerns: “Treat three artifacts as different: the decoded value, the object contract, the request envelope. A handler that proves only the first two can still admit a body that violates the third”. We focus strictly on the admission gate: until both the JSON object and the suffix+size checks pass, no write should occur.
2 Capture baseline versions and state
Before running tests or writing code, record all relevant environment details as evidence. Example steps:
Record the toolchain: run
go version
go env GOOS GOARCH
uname -srmo
For example, note go version go1.23.2 linux/amd64 and Linux 6.x x86_64 GNU/Linux in your lab. This is execution evidence for this fixture. Don’t confuse it with the version of the pkg.go.dev docs. In fact, the Refonte JSON validation playbook notes that on October 20, 2026 they used Go 1.23.2 for testing, but the pkg.go.dev pages were on Go 1.27.3. We do the same: pin our test runtime (e.g. with GOTOOLCHAIN=local) and record its identity. Also record GOEXPERIMENT=nojsonv2 if relevant, etc.
Document library versions: Note which Go std packages we consult. For example, http.MaxBytesReader and MaxBytesError were added in Go 1.19; JSON Decoder has long existed. However, the official documentation pages might be at a newer Go version. Distinguish them: e.g., “According to pkg.go.dev under Go 1.27.4 (Nov 2026), httptest.NewRequest creates a server request and ResponseRecorder captures writes. Meanwhile, our runtime is Go 1.23.2.” This dual identity is key: implementation observations belong to the pinned runtime; API claims come from the cited docs.
Check baseline behavior of related APIs: For completeness, you might note that httptest.NewRequest produces an incoming server http.Request and httptest.NewRecorder is a ResponseWriter that records what the handler writes. This ensures we stay in memory. Also note any relevant HTTP default (content type, default remote address) per docs.
Rejection condition: If any tool or package is missing or new (e.g. an absent http.MaxBytesError type), pause. If go version or httptest behavior changes (like HTTP/2 vs HTTP/1.1), that could require re-running tests.
Capture all this metadata (stdout, OS info, exact git commit of code) and save it alongside results. Per Refonte guidance, each run’s environment snapshot is part of the evidence. A mismatch in the environment is a signal to RERUN the test under the correct conditions (see decision section later).
Pin environment and versions
Use a fixed Go release (e.g. 1.23.2) and record go version and system info.
Note the versions of net/http, encoding/json, and net/http/httptest docs you consulted (for example, pkg.go.dev pages under Go 1.27). These are documented claims, not runtime evidence.
Only proceed if the runtime matches what you intend to approve. If not, hold and retry with the correct runtime.
3 Build a disposable isolated fixture
Construct a small Go test harness that encapsulates the scenario without side effects on any external system. For example, we can use httptest.NewRequest and httptest.NewRecorder so every case runs entirely in memory. The handler under test should: wrap the incoming r.Body with http.MaxBytesReader(w, r.Body, 128), use a json.NewDecoder on it, perform the two-step decode, and only then do the write (side effect) if checks pass. An example handler skeleton might be:
func myHandler(w http.ResponseWriter, r *http.Request) {
    // Apply 128-byte limit on the request body
    r.Body = http.MaxBytesReader(w, r.Body, 128)
    dec := json.NewDecoder(r.Body)
    dec.DisallowUnknownFields()
    var reqData struct{RequestID string json:"request_id"}
    // First decode (object)
    if err := dec.Decode(&reqData); err != nil {
        // If limit exceeded, err is *http.MaxBytesError; else JSON error
        if errors.Is(err, &http.MaxBytesError{}) {
            http.Error(w, "Payload too large", http.StatusRequestEntityTooLarge)
        } else {
            http.Error(w, "Bad request", http.StatusBadRequest)
        }
        return
    }
    // Second decode (check for EOF)
    var extra any
    if err := dec.Decode(&extra); err != nil {
        if err != io.EOF {
            // Not EOF (there was extra non-whitespace data)
            http.Error(w, "Multiple JSON values", http.StatusRequestEntityTooLarge)
            return
        }
    }
    // All checks passed: perform the side effect (here simulated by a 204)
    w.WriteHeader(http.StatusNoContent)
}
Then write a small main or test function that calls this handler via httptest:
req := httptest.NewRequest("POST", "/test", strings.NewReader(jsonBody))
w := httptest.NewRecorder()
myHandler(w, req)
res := w.Result()
// Record res.StatusCode and possibly w.Body or other side effects.
Use this fixture to run all cases. Since it has no external connections or persistent storage, we can run it any number of times without cleanup. Having a separate handler instance (or even no persistent state) ensures isolation. Do not run this handler against a real server or DB; every interaction should use httptest.
The Refonte example specifically says: “The harness uses httptest.NewRequest and httptest.NewRecorder, so every case remains in memory.” We do exactly that to prevent any production mutation.
4 Create an independent expected-case manifest
Before executing anything, list each test case and its expected outcome according to the contract. This “manifest” is written entirely from policy and documentation, independent of the code under review. For example:
Case | JSON Body (string) | Expected HTTP Status | Expected Writes (side-effects) | Expected Error Class |
G01 | {"request_id":"abc"} | 204 (No Content) | 1 (side effect applied) | nil (no error) |
G02 | {"request_id":"abc"} (whitespace only) | 204 (No Content) | 1 | nil (whitespace is OK) |
G03 | {"request_id":"abc"}x (extra byte) | 413 (Req Too Large) | 0 (no side effect) | SyntaxError (unexpected value) |
G04 | (valid object but body >128 bytes) | 413 (Req Too Large) | 0 | MaxBytesError (limit hit) |
G05 | (valid small object, then ≥1 byte beyond 128) | 413 (Req Too Large) | 0 | MaxBytesError (limit hit) |
G01: Single valid object under 128 bytes. Should succeed (204 No Content) and trigger one side effect.
G02: Object + trailing whitespace (spaces/newlines) under 128. JSON allows trailing whitespace, so still one value; expect 204 and one write.
G03: Object followed by a non-whitespace byte (e.g. x). After the object, dec.Decode(&extra) will return a syntax error (not EOF), so treat as rejection (we use 413 here per policy). No write.
G04: The JSON object itself is longer than 128 bytes (for example a 130-byte string field). MaxBytesReader will trigger on the read of the object. The first Decode will return a *MaxBytesError, so we return 413 and no write.
G05: Object is small but the trailing part pushes the read beyond 128 (e.g. 120 bytes of JSON plus 10 bytes of trailing). The first Decode will succeed (object parsed) but the second Decode will trigger *MaxBytesError because reading for the suffix exceeded the limit. So we return 413 and no write.
Also include negative controls:
N01 (empty body): No JSON at all. Decode returns EOF or error; treat as bad request (400). No write.
N02 (JSON null or non-object): If policy forbids null or non-object, we return 400. No write.
N03 (first byte invalid JSON): Syntax error 400.
Each expected result is derived from the contract: a 204 indicates “pass all checks, do side effect”; a 413 or 400 means rejection. Importantly, ANY rejection case should have zero writes.
Preserve a negative control
As a negative control, we test an input that should unambiguously fail early. For example, an empty body or a body of non-JSON. We assert the handler returns 400 Bad Request and w.WriteHeader was never called for a success. If the handler writes on a clearly invalid input, that violates the contract. In our expected manifest, N01/N02 are such controls. We will check after testing that for N01/N02 the side-effect counter is 0. The “oracle” here is simple: if the request contains no valid JSON object, reject immediately. Rejection condition for each negative test is documented.
5 Reproduce the misleading success
Now simulate the original (buggy) handler that only does the first Decode and then writes immediately. This is the “misleading success” path: it might pass the JSON object check but fail to check the suffix. For example:
// Faulty handler (for demonstration)
r.Body = http.MaxBytesReader(w, r.Body, 128)
dec := json.NewDecoder(r.Body)
dec.DisallowUnknownFields()
var obj RequestData
if err := dec.Decode(&obj); err != nil {
    // (error handling as before)
}
// MISSING: second Decode for EOF check!
// Side effect occurs too early:
w.WriteHeader(http.StatusNoContent)
In particular, consider case G05 (valid small object, trailing beyond limit). The faulty handler will decode the object, ignore the extra trailing bytes, and immediately send 204. That yields a misleading success (204, side effect happened) even though the body was too large. In contrast, the correct logic (with second decode) would detect the extra bytes and return an error. Refonte’s example calls this the “first-only candidate” and contrasts it with the guarded candidate. We emulate the faulty path and confirm it does the wrong thing for G05 (writes=1, status=204). This proves that without the suffix check, the handler would incorrectly treat G05 as acceptable.
The presence of a trailing-value bug is exactly why we need the suffix test.
6 Run the comparison case
Now run both the faulty (first-decode-only) and the fixed (with second Decode) handlers on the key case with trailing input, and compare. For example:
Faulty handler on G05 yields Status=204, writes=1.
Fixed handler on G05 yields Status=413, writes=0 (the MaxBytesError is surfaced on the suffix read).
Also consider case G04 (first object oversize): both handlers will error on the first decode. We expect 413/0 in both cases. For G01-G03 (no overflow or valid one-value), both handlers behave the same (204/1 for G01/G02; 400/0 for G03 if we treat x as syntax error). The difference only shows up on trailing-length cases like G05.
A useful way to present this is a table:
Case | Faulty Path (first-only) | Guarded Path (with second Decode) | Desired Outcome? |
G01 | 204 / 1 (pass) | 204 / 1 | ACCEPT (good) |
G05 | 204 / 1 (incorrect!) | 413 / 0 | REJECT (only guard is correct) |
Refonte notes that for G12 (their name for small obj + trailing), “the first-only candidate returns 204/1; the single-value gate returns 413/0”. Those are our G05 results. Thus our manifest for G05 says the correct behavior is 413/0, and we now have evidence that only the guarded code meets that.
Detect missing or duplicated evidence
After running the test suite, ensure all expected cases appeared exactly once in the results. For example, if we aggregate results into a slice or JSON report, check that its length equals the number of cases. If any case is missing or appears twice, that indicates a test setup bug (e.g. accidentally skipping a case or double-running it). In a typical fixture we might have an assertion like:
if len(report.Cases) != expectedCount {
    panic("case inventory mismatch")
}
All expected case IDs (G01, G02, …) should be present, and their inputs should map to a single row each. No test case should silently skip or duplicate. (In the Go LimitReader validation example, a similar check was must(len(rows)==12, "case inventory mismatch").) We also verify that each row’s “pass” status corresponds exactly to the expected side-effects count (writes) and error class. If, for example, two cases produced the same status but we expected different, that discrepancy must be investigated. Essentially, we reconcile “one row per case” as part of the ledger completeness check.
7 Test negative and boundary controls
Beyond the main cases, exercise edge and negative inputs to ensure the handler cannot be tricked. Examples:
Empty body (N01): Input = "" (empty string). Our handler’s Decode will likely return io.EOF immediately. This should result in a 400 Bad Request and no write, as the object is missing.
Null or wrong type: Input = null or 123 or []. These are valid JSON values but not allowed by our contract (we wanted an object with request_id). We expect 400 with no write. (With DisallowUnknownFields and a struct pointer, Decode into a struct will return an error for these cases.)
Exact-size limit: Construct a JSON body that is exactly 128 bytes long. For instance, {"request_id":" + 120-byte string + "} yields around 128 bytes. If properly calculated, reading up to the closing brace hits the limit exactly. In Go, hitting the limit exactly may not trigger an error (it might require one more byte to overflow). Document what happens: if it does return successfully, we should accept it (204/1); if it triggers MaxBytesError, the handler should reject as 413/0. Either way, it will be consistent.
One byte over: Take the exact-size JSON and append a space or any character. This will definitely exceed 128 bytes and should produce 413/0.
Each of these is in the Expected-Case Manifest as separate rows (or we note them verbally). The key is: we must check behavior right at the limit boundary and ensure “just over the limit” fails cleanly.
8 Collect per-case raw evidence
Capture the raw output for each case in an “evidence ledger.” For instance, your test code might print a JSON report like:
{
  "cases": [
    {"id":"G01","status":204,"writes":1,"error":null},
    {"id":"G02","status":204,"writes":1,"error":null},
    {"id":"G03","status":400,"writes":0,"error":"*json.SyntaxError"},
    ...
  ]
}
In practice, record each case’s ID, HTTP status code, number of side effects (write count), and the error type (if any). If using a programmatic reporter, save its stdout and stderr, as well as the exit status. All this output is your raw evidence. For example, after running your Go harness (go run /path/to/fixture.go > result.json), preserve result.json, stdout, and stderr.
All unexecuted test cases are marked as EXPECTED / NOT EXECUTED according to the documented contract.
Important: Don’t edit the test code to force a pass. Record whatever the code actually does. If some path fails or panics, capture that in stderr. An empty output, partial JSON, or nonzero exit code indicates a problem (as the Refonte JSON validation playbook notes, no output or a panic should be treated as HOLD).
Check the actual state after failure
In a real-world handler this step might involve inspecting the database or other state to ensure no side effect slipped through. In our fixture, the “side effect” is simply that we would have written a 204 or incremented a counter. Thus, we verify from the response recorder that for every expected “no-write” case (G03, G04, G05, N01, etc.), the handler indeed never called WriteHeader(204) or wrote any body. If our test code had a counter, it should be zero. If using httptest, ResponseRecorder.Result() should show the proper status code (and an empty or nil body for write-less cases). In short, for each rejection case we confirm exactly zero side effects. Any exception (e.g. a write sneaked through) would fail this check.
9 Reconcile identities and counts
Now merge the manifest and the evidence ledger. For each case ID, verify that the observed outcome matches the expected outcome. Check that each row is unique and corresponds to a distinct case. For example, ensure there are exactly as many result rows as test cases (including controls). Record that mapping in a table or annotated log. An example reconciliation summary:
Count Check: There should be 5 unique cases (G01-G05) plus any negatives. If some row is missing or extra, that’s a test error.
Status Identity: G01, G02 should appear with 204 and writes=1. G03, G04, G05 should appear with 413 (or 400 for G03) and writes=0.
Error Identity: The error types for G03 (syntax error) vs G04/G05 (MaxBytesError) should match what was logged. This distinguishes “wrong type of failure” from no failure.
Source vs Runtime ID: Attach a source SHA for the fixture code and runtime info (go version) to each row, so an auditor knows exactly what code produced these outputs.
In short, we ensure “case inventory, error classes, and destination snapshots” are fully aligned. If any case’s output deviates (e.g. status 204 instead of 413), note that discrepancy. For a proper release, there should be no mismatches: every row in “observed” must agree with the “expected” contract. Discrepancies are logged and will drive the decision.
This step parallels the Refonte practice: “a reviewer can reconcile the contract, source identity, runtime identity, case inventory, error classes, and destination snapshots”. We are doing exactly that reconciliation.
10 Explain documented behavior and limits
Interpret the results in light of Go’s documentation. For example:
MaxBytesReader semantics: The docs say MaxBytesReader is like io.LimitReader but instead of silently returning EOF at the limit, it returns a *MaxBytesError when you read too far. In our test G04/G05, the decoder attempted one extra read past 128 bytes and got that error. Note that MaxBytesReader may actually consume one extra byte internally to detect the overflow; it does not guarantee that the underlying connection stops exactly at 128. That’s why reaching the limit raises an error rather than hiding it as EOF. This behavior is crucial: if MaxBytesReader simply returned EOF at 128, we couldn’t tell “did the client actually end at 128, or did we cut it off?” The error preserves that distinction. We see that in G05: the trailing whitespace pushed us to read past 128, causing a MaxBytesError.
Decoder behavior: The json.Decoder may read more than the first value into its buffer. However, it only returns from Decode after producing one value. Only by calling Decode again and getting io.EOF do we know “no more JSON in the input”. Our test confirmed that: without the second call, trailing data was ignored. The documentation states this explicitly: “Decode reads the next JSON-encoded value… it does not by itself certify the entire request as a single JSON text”.
Suffix vs size coupling: Our experiments (especially G05) show that proving “only whitespace (or nothing) followed” is intertwined with reading past the first value. The second decode both checks for extra JSON and triggers the limit error if needed. That matches the doc’s implication that the decoder has its own buffering. In short, we did exactly what the docs recommend: use Decode again for the suffix.
Summary: The observed outcomes align with documented contracts: size limit produces MaxBytesError, and a well-formed single JSON value followed by EOF is accepted. Any deviation would indicate a misunderstanding of these docs. Our evidence shows consistency: only with the second-decode fix did the handler’s behavior match the intended semantics.
Bound the repair to the contract
Crucially, applying the suffix check should not change anything else about the contract. We must not inadvertently reject valid inputs or change field semantics. For instance, we do not turn the endpoint into a “JSON stream” or NDJSON handler; we still only accept a single object. We must also keep using MaxBytesReader as before (so the 128-byte cap is still in place). Refonte warns: “Keep the existing first decode, byte wrapper, unknown-field rule, root check, and request_id policy … to preserve the review surface”. In other words, our only change is the extra check, not any other relaxation or tightening of the JSON schema. This bounds the fix strictly to the trailer-detection gap. If, for example, someone suggested changing MaxBytesReader to a larger number or removing DisallowUnknownFields, that would be out of scope for this contract. We explicitly avoid that.
11 Apply the smallest safe repair
Implement the minimal code change: after the first successful decode, immediately do a second decode to catch any extra input. For example:
// After first Decode into reqData:
var extra any
if err := dec.Decode(&extra); err != io.EOF {
    // If err is nil (meaning we actually got a value), or err!=EOF, it’s a violation.
    if err == nil {
        err = errors.New("extra top-level JSON value")
    }
    // Here we reject (using same response as above, could be 413 or a custom error).
    http.Error(w, err.Error(), http.StatusRequestEntityTooLarge)
    return
}
// Now safe to apply side effect
w.WriteHeader(http.StatusNoContent)
This snippet (adapted from the prior discussion) ensures that we only accept the request as a single value and EOF. We reuse the same MaxBytesReader wrapper so the limit still applies consistently. We do not alter the client-visible API (status codes or JSON error messages) beyond what we already used for size and syntax errors. In other words, we have not loosened or over-constrained anything; the check only narrows the acceptance to the original intent. If we had instead implemented a wholesale new JSON parser or changed the structure, that would be too big.
Refonte’s recommended fix is exactly this second Decode(&extra) check. We keep the surrounding code (byte limit, DisallowUnknownFields, etc.) the same. This preserves the contract and only closes the one remaining gap (trailing data).
12 Test rollback and rerun safety
Before finalizing, consider the rollout implications. If this fix fails in production, can we safely roll back? The fix is purely in code with no schema changes, so it should be straightforward: revert to the old handler. There is no shared state written before the fix, so a rollback would restore the first-decode-only behavior. However, note that if any clients were relying (intentionally or not) on the old behavior of permitting trailing data, they might see new rejections. That’s a compatibility issue, not a system failure.
To be thorough, rerun safety means we should run our test suite on the fixed handler multiple times and/or in parallel to ensure deterministic results. Our test harness being in-memory is idempotent: it has no persistent state, so each run is clean. (If the handler had done database writes, we would need transactions or cleanup between tests.) In this case, just re-running go run fixture.go should yield the same PASS inventory every time. Also verify that no panic or leftover state remains after an error: e.g. if a MaxBytesError occurs, the Go HTTP server’s MaxBytesReader closes the body, but in our test we’re done after error anyway. If we had a real DB, we’d ensure any transaction was rolled back on error.
Note: In a larger system, we would tag this fix with zero downtime procedures. Here, “rerun safety” boils down to “the test results are reproducible and can be re-validated under the exact same environment”. We should archive the source code SHA, the fixture run results, and environment metadata so the process can be replayed if needed.
Assign operational ownership
Even though this is primarily a code fix, someone should “own” the gate in production. Typically, this would be the API or backend team responsible for this endpoint. They should monitor error rates (e.g. spikes in 413 after deployment might indicate clients sending bigger bodies) and be ready to investigate. The ownership of running this test should belong to the CI/CD or QA team for backend code, since it’s a release criterion. If other teams produce clients against this API, those product owners should be informed of the contract check. Assigning clear ownership ensures that if something goes wrong, the right team “calls the shots” on rollback or client communication. For example, the API owner would decide if a mass client update is needed or if the endpoint’s documentation should be updated. (If the endpoint is deprecated or moved, the DevOps team should also be aware, but that’s outside the immediate scope.)
13 Decide ACCEPT, REPAIR, RERUN or HOLD
Based on the evidence and our contract, we apply a structured decision:
ACCEPT: The candidate implementation passed all tests and met the documented contract exactly. Concretely, that means the fixed handler produced 204/1 only for G01/G02 (and other valid controls) and 413/0 for G04/G05 (with correct error types), and no 204 where it shouldn’t be. In this case, the evidence table shows “guarded candidate matches G01–G05; only G01/G02 are 204/1; G04/G05 are 413/0; all invalid cases are 400/0”. If all that holds and the source SHA and environment are recorded, we mark ACCEPT and can release this candidate.
REPAIR: The candidate fails the admission contract. For instance, if there is any case where a write occurred (writes=1) when the contract said no side effect, that’s a bug. In our comparison above, that happened with the faulty handler on G05. If a candidate build (or current code) shows a first-decode-only path, that triggers REPAIR. In practice, our test with only first-decode did show 204/1 on G05, so that path would be flagged REPAIR. The fix (second decode) should be applied and re-tested.
RERUN: This applies if something about the test execution was inconclusive. For example, if we see one result “unexpected” that might be caused by an unpinned runtime, an intermittent read error, or an environment mismatch, we rerun. The evidence was incomplete or inconsistent. In such a case, do not clear a failure into “pass”; instead retry the exact fixture (and if needed debug). In practice, if all our code is deterministic, RERUN is unlikely. It would happen only if, say, the JSON library behaved differently under different GOEXPERIMENT flags, or if an external factor (like a random input) impacted the outcome.
HOLD: Use this if a requirement is unclear or if the evidence reveals a deeper policy question. For example, if tests pass but we realize some client should have been allowed two JSON objects (thus the single-value contract is in question), we would HOLD for clarification. Another HOLD scenario is if the test passes but we have incomplete source control records or a missing environment spec. Lastly, if in reconciling evidence we find an unexplained discrepancy (say a missing case), we might hold the build until that’s resolved.
In the Refonte JSON validation playbook, a decision table is given: “ACCEPT if Guarded candidate matches G01–G14; REPAIR if first-decode-only path; … HOLD if…”, etc. We adapt that pattern. In short: our final decision is ACCEPT only if every evidence row matches the expected contract; any counterexample forces REPAIR (code change) or HOLD (for unresolved issues). Only after a pass-with-proof can the API owner authorize this release.
14 Develop related skills with Refonte Learning
Refonte Learning’s Backend Development program trains engineers in exactly these kinds of practices. In a 3-month (10–12 hr/week) part-time curriculum, you learn server-side design, robust API patterns, and testing. Technologies covered include Node.js with Express, REST/Microservices, MongoDB and SQL databases, authentication, and Docker, all complementing the Go skills used here. The program offers hands-on projects and a virtual internship, with mentors like industry software engineers guiding best practices. Graduates earn both a Training Certificate and, if qualified, an Internship Certificate. (A background in coding or a related degree is recommended.)
If you want to build confidence in API correctness, testing, and release protocols like the above, check out Refonte Learning’s Backend Developer Program. It covers HTTP internals, error handling, and many other backend skills in depth. Enroll in the Backend Development Program to strengthen the foundations that made this playbook possible.