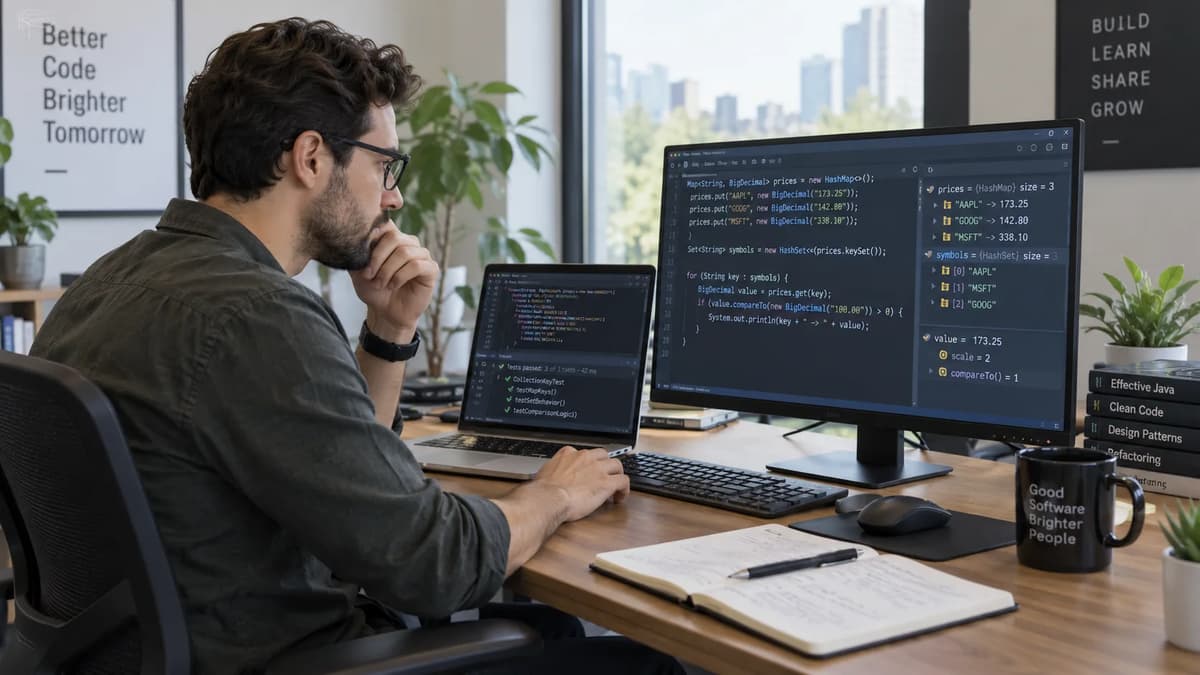
When migrating keys between hash-based and sorted collections, subtleties of BigDecimal identity can cause some entries to vanish or overwrite others unexpectedly. Consider three routing entries: E1=("2.0", route-A), E2=("2.00", route-B), E3=("3.0", route-C). On OpenJDK 21.0.11 we observe that inserting these exact decimal keys into a HashMap yields three entries, but inserting them into a TreeMap yields only two. This playbook explains how to recognize and prevent such losses. It guides you to define whether your application’s key identity is representation-sensitive (value+scale) or purely numeric (value only), to test how hash-based vs ordered collections behave under each policy, and to ensure that no payload is lost or silently overwritten. All inputs here are decimal strings (not double-literals), and we use a standalone Java SE 21 test harness.
Our narrow success criteria are: the final map must implement the chosen key contract and include every original entry’s payload exactly once. We rely on documented Java contracts (e.g. BigDecimal’s equals vs compareTo) and repeatable experiments in our controlled environment for evidence. Based on our findings, the migration outcome will be one of: ACCEPT (new map meets the policy), REPAIR (fix key normalization/comparator), HOLD (conflicts unresolved), or REBUILD (start over from source with approved policy). Each step below is supported by code and references.
Declare what a decimal key identifies
An important practice is to keep the raw string as the primary identifier (in line with the advice to preserve identity before consuming parsed values). Our Entry record has fields (id, raw, payload), so we never drop the original text form or the EntryID when converting to BigDecimal. This ensures we can always recover which source record produced which payload.
If the domain calls for representation-sensitive keys (value + scale), then "2.0" and "2.00" are distinct keys. We would follow BigDecimal.equals, which requires equal numerical value and equal scale. According to the API, new BigDecimal("2.0").equals(new BigDecimal("2.00")) is false since their unscaled values or scales differ. In this design, E1, E2, E3 are three separate keys, and the scale is part of the business key identity.
If the domain wants numeric key identity, then any values that compareTo as equal share one key. BigDecimal’s natural ordering ignores scale, so new BigDecimal("2.0").compareTo(new BigDecimal("2.00")) == 0. Under this policy, E1 and E2 map to the same group, while E3 is separate. In that case we regard the numeric value 2 as the key, and store the raw strings only for reference.
We explicitly declare both possibilities (not relying on one to emerge by accident): representation-groups {E1}, {E2}, {E3}, and numeric-groups {E1, E2}, {E3}. We do not generate these by inserting into a collection. This mirrors the principle that application identity can differ from storage equality; the key contract is an explicit policy, not a mystery to be discovered.
Pin a dependency-free Java laboratory
We perform all tests with OpenJDK 21.0.11 (Java SE 21) on a clean project. First, confirm the environment:
$ java -version
openjdk version "21.0.11" 2026-05-04
OpenJDK Runtime Environment (build 21.0.11+9-LTS)
OpenJDK 64-Bit Server VM (build 21.0.11+9-LTS, mixed mode)
$ javac -version
javac 21.0.11
The code is in a single file DecimalKeyContract.java with public static void main(String[] args). We define an assertion helper:static void require(boolean cond, String msg) {
if (!cond) throw new AssertionError(msg);
}
record Entry(String id, String raw, String payload) {}
public class DecimalKeyContract {
public static void main(String[] args) {
System.out.println("Using " + System.getProperty("java.vendor") + " " +
System.getProperty("java.version"));
System.out.println("All checks passed.");
}
}This setup is dependency-free (no Maven, only Java SE APIs). We compile and run:$ javac DecimalKeyContract.java
$ java DecimalKeyContract
Using OpenJDK 21.0.11
All checks passed.The program prints the JVM info and any assertion failures. If all require(...) checks succeed, it exits normally (status 0). Any failure throws an AssertionError (nonzero exit), which our CI pipeline will detect. This ensures we never skip a broken assumption.
Keep raw text and record identity outside the key
We populate entries like:
List<Entry> entries = List.of(
new Entry("E1", "2.0", "route-A"),
new Entry("E2", "2.00", "route-B"),
new Entry("E3", "3.0", "route-C")
);
Here raw preserves the exact decimal string. We only call new BigDecimal(raw) when we use it as a map key, so the original format is never lost. This means if two entries collapse into one key later, we can still tell they were distinct inputs. Our tests treat this list of entries as the single source of truth for verifying final results.
Write the equality oracle before choosing a collection
We first confirm the key relationship in our fixture. For E1 and E2:
BigDecimal bd1 = entries.get(0).key(); // 2.0
BigDecimal bd2 = entries.get(1).key(); // 2.00
require(bd1.equals(bd2) == false, "2.0.equals(2.00) should be false");
require(bd1.compareTo(bd2) == 0, "2.0.compareTo(2.00) should be 0");
require(bd1.scale() == 1 && bd2.scale() == 2, "scales should be 1 and 2 respectively");
Indeed, BigDecimal’s contract says that 2.0 is not equal to 2.00 under equals, but their compareTo is 0. For E3 (3.0) both equals and compareTo distinguish it from E1/E2 (as its numeric value differs). Based on these facts, we independently declare the expected identity groups: representation groups {E1}, {E2}, {E3}, and numeric groups {E1,E2}, {E3}. (We do not derive them from a single collection run, to avoid circular logic.) As one might note from database key design, application identity can differ from storage equality. We explicitly list both cases to guide testing.
Distinguish numeric equality from substitutability
A key point: numeric equality does not mean entries are interchangeable in all operations. For example, the BigDecimal documentation illustrates that dividing 2.0 vs 2.00 by 3 yields different results (0.7 vs 0.67). So even though compareTo says 2.0 and 2.00 are the same value, their representation can affect calculations. We do not claim they are substitute keys for every use; only that one policy treats them as the same lookup key.
Compare HashSet and TreeSet membership
Next we test collection membership with the parsed keys. Using the three entries’ keys:
Set<BigDecimal> hashSet = new HashSet<>();
Set<BigDecimal> treeSet = new TreeSet<>();
for (Entry e : entries) {
hashSet.add(e.key());
treeSet.add(e.key());
}
require(hashSet.size() == 3, "HashSet should have 3 entries");
require(treeSet.size() == 2, "TreeSet should have 2 entries");
A HashSet uses the key’s hashCode() and equals() for uniqueness, so it treats 2.0 and 2.00 as distinct and ends up with 3 entries. The TreeSet is a sorted set (backed by a TreeMap) using compareTo, so it merges 2.0 and 2.00 into one. We also test membership explicitly:
BigDecimal testKey = new BigDecimal("2.000");
require(hashSet.contains(testKey) == false,
"HashSet should not contain 2.000 (no equal)");
require(treeSet.contains(testKey) == true,
"TreeSet should contain 2.000 (compareTo==0)");
This confirms that a HashSet sees no duplicate (no collision) while TreeSet sees 2.0 and 2.00 as the same element. These results are expected from the documented behavior of Java collections: HashSet provides no order guarantee and relies on equals, whereas TreeSet is defined by natural ordering. Here the ordering is not consistent with equals (as the docs warn), which is why the TreeSet silently treated them as duplicate entries.
Expose the payload lost in a map conversion
Now consider a HashMap<BigDecimal,String> to TreeMap migration. First, a HashMap<BigDecimal,String> built from all entries:
Map<BigDecimal,String> hashMap = new HashMap<>();
for (Entry e : entries) {
    hashMap.put(e.key(), e.payload);
}
require(hashMap.size() == 3, "Initial HashMap holds 3 entries");
All three entries are stored. Next, create an empty TreeMap<BigDecimal,String> (natural order) and insert one by one:Map<BigDecimal,String> treeMap = new TreeMap<>();
String prev;
prev = treeMap.put(new BigDecimal("2.0"), "route-A"); // insert E1
System.out.println(prev); // null
prev = treeMap.put(new BigDecimal("2.00"), "route-B"); // insert E2
System.out.println(prev); // prints "route-A"
prev = treeMap.put(new BigDecimal("3.0"), "route-C"); // insert E3
System.out.println(prev); // null
System.out.println(treeMap.size()); // should be 2The key observations: treeMap.put("2.00","route-B") returned "route-A", meaning E2 replaced E1. After all insertions, treeMap.size() == 2. The final map contains one key for 2.x (with payload "route-B") and one for 3.0. If we reverse the order (insert 2.00 then 2.0), the same happens but "route-A" wins instead. In both cases the map ends up with 2 keys and one of the payloads is lost. Thus the simple migration collapsed {E1,E2} into a single entry, arbitrarily keeping one of the routes. This is exactly the behavior the TreeMap documentation predicts: because keys compare equal by compareTo, the second insert overwrote the first. There is no contractual guarantee whether the surviving key object is the one for 2.0 or 2.00; only the value survives.
We log this behavior: in a run with forward insertion the console might show:
null
route-A
null
2
This indicates that on inserting 2.00, route-A was returned and replaced. A reversed run would show route-B returned instead. These outputs confirm that the TreeMap “chose” one payload. Critically, the key count remains 2, meaning one source entry was effectively removed. In our test harness, we do not assert which route wins (it’s unspecified), but we do detect that an overwriting occurred.
Audit collisions before building the replacement map
Before doing the destructive TreeMap insertion, we perform a collision audit on the source entries. For numeric grouping, for example:
Map<BigDecimal,List<Entry>> groups = new TreeMap<>(BigDecimal::compareTo);
for (Entry e : entries) {
    groups.computeIfAbsent(e.key(), k -> new ArrayList<>()).add(e);
}
require(groups.values().stream().mapToInt(List::size).sum() == entries.size(),
        "Grouping should cover all source entries");
for (List<Entry> group : groups.values()) {
    Set<String> payloads = group.stream().map(Entry::payload).collect(Collectors.toSet());
    if (payloads.size() > 1) {
        System.err.println("Conflict group for key " + group.get(0).key() +
            ": payloads " + payloads);
        System.exit(1); // HOLD migration
    }
}
This non-destructive ledger groups entries by numeric key (using a TreeMap comparator). We check that all 3 entries appear once, then detect any group with multiple different payloads. In our case there will be one group [E1, E2] (both numeric key 2) with payloads {route-A, route-B}, triggering a conflict. Because we find a conflict, we must HOLD the migration. We do not proceed to actually build the new map. (If we blindly did treeMap.putAll(hashMap), we would overwrite data without noticing, so this audit is essential.) The audit preserves each EntryID, and flags precisely which source payloads would collide, requiring a domain decision before moving on.
Choose a coherent numeric or representation-sensitive design
Depending on the outcome, we implement the chosen contract consistently:
• Numeric identity design: We pick a canonical-key function. One common choice is BigDecimal.stripTrailingZeros(), which removes redundant scale information (e.g. 600.0 → 6E+2). We then always insert and lookup using the canonical form. For example:
BigDecimal keyNorm = key.stripTrailingZeros();
treeMap.put(keyNorm, payload);
We similarly normalize lookup keys. Alternatively, we can use BigDecimal::compareTo as the comparator in a TreeMap of BigDecimal (though then equals is ignored, but that’s fine for ordering). In numeric mode we must apply the same normalization or comparator for both insert and get, otherwise lookups will fail or duplicate. The raw representation (payload) is kept separate if we need it.
• Representation-sensitive design: We either use BigDecimal directly or create an explicit key class containing (unscaledValue, scale). The equals/hashCode of BigDecimal already treats scale as part of identity, so new BigDecimal("2.0") and "2.00" are distinct keys in a HashMap. If we need sorted order, we must supply a comparator that is consistent with that identity. For example:
Comparator<BigDecimal> repComp = (a, b) -> {
    int cmp = a.compareTo(b);
    if (cmp != 0) return cmp;
    return Integer.compare(a.scale(), b.scale());
};
SortedSet<BigDecimal> repSet = new TreeSet<>(repComp);
This comparator returns 0 only if both value and scale match, so it respects BigDecimal’s equals. Using this in a TreeMap ensures that 2.0 and 2.00 remain two keys, ordered perhaps by scale.
In all cases, the collection operations (insert, remove, get) must use the same logic. If we choose numeric, all keys must be canonicalized before using. If representation, we keep BigDecimal as-is. Mixing them would be a bug. We do not rely on any hidden conversion; the policy is explicit. As a Refonte design principle says, we must make the consumer contract explicit (in other words, clearly define what map.get means in terms of raw and normalized values).
Make the collision policy an explicit input
In particular, note that even after normalization, the conflict {route-A, route-B} remains unresolved: numeric normalization by itself doesn't “choose” between them. The domain must decide what to do with both values. For example, the policy could be to reject one, merge them, or store multiple. We cannot just silently use last-write-wins or drop one. Our fixture intentionally used different payloads so that normalization alone isn’t sufficient. If a single-valued map is required, an approved resolution (e.g. “prefer A over B” or “error out”) must be specified by the domain owner. Without an explicit rule, we HOLD the migration rather than hiding the conflict.
Test normalization without silently changing the value
We verify candidate normalizations do what we expect. Compare stripTrailingZeros() vs setScale(2, RoundingMode.UNNECESSARY) on sample inputs:
Input | x.stripTrailingZeros() (canonical) | x.setScale(2, UNNECESSARY) |
0.0 | 0 | 0.00 |
0.00 | 0 | 0.00 |
600.0 | 6E+2 (i.e. 6×10², scale -2) | 600.00 |
2.000 | 2 | 2.00 |
1.234 | 1.234 |
This shows they behave differently: stripTrailingZeros() collapses zeros (even yielding negative scale for 600.0), while setScale(2, UNNECESSARY) pads/trims to two places and throws if rounding is needed (as expected by BigDecimal’s scaling specification). All outputs remain numerically exact to the original. We do not interchange these methods carelessly.
We also test idempotence: applying the canonical function twice yields the same as once. For example:
BigDecimal c1 = new BigDecimal("2.0").stripTrailingZeros(); // 2
BigDecimal c2 = c1.stripTrailingZeros(); // still 2
require(c1.equals(c2), "stripTrailingZeros should be idempotent");
Finally, we ensure lookup uses the same function. If we build a map with normalized keys:Map<BigDecimal,String> normMap = new HashMap<>();
normMap.put(new BigDecimal("2.0").stripTrailingZeros(), "route-A");
normMap.put(new BigDecimal("2.00").stripTrailingZeros(), "route-B");
// normMap now has one key (2) with value "route-B"
require(normMap.get(new BigDecimal("2.000").stripTrailingZeros()).equals("route-B"),
"Lookup with normalized key must succeed");
require(normMap.get(new BigDecimal("2.000")) == null,
"Lookup without normalizing should fail (as a test)");The harness asserts that canonical lookup succeeds and that an unnormalized lookup does not accidentally find the wrong entry. We include symmetric removal tests similarly.
Reconcile EntryID and payload ownership end to end
We build a reconciliation ledger of what happened to each original entry under the chosen policy (numeric in our example). For forward insertion (2.0 then 2.00), we get:
EntryID | Raw | (Unscaled, scale) | Canonical Key | Intended Group | Actual Map Key | Final Payload | Insertion Return |
E1 | 2.0 | (20, 1) | 2 | G1 | 2.0 (or 2.00)* | route-B | null (first put) |
E2 | 2.00 | (200, 2) | 2 | G1 | 2.0 (or 2.00)* | route-B | "route-A" |
E3 | 3.0 | (30, 1) | 3 | G2 | 3.0 | route-C | null (new) |
*The actual BigDecimal instance left in the map (either 2.0 or 2.00) depends on insertion order.
This table shows that both E1 and E2 were intended to form a numeric group G1. In the actual map, only one key with payload "route-B" exists for that group. Entry E1’s payload "route-A" was overwritten (as indicated by the insertion return for E2). Entry E3 remained alone (G2) and its payload stayed. The code asserts that the final map size is 2, contains the key 3.0, and that treeMap.get(new BigDecimal("2.0")) returns "route-B". If any original payload is missing (as "route-A" is here) without explanation, that violates our contract. In this example the payload from E1 is unaccounted, so we do not accept this result (see next section). We will either require a fix or rebuild.
Handle rejected precision and unsupported identities
We also include negative controls for bad data. For a malformed key:
try {
    new BigDecimal("not-a-number");
} catch (NumberFormatException e) {
    System.err.println("Malformed input: " + e.getClass().getSimpleName());
}
This catches invalid strings. Similarly, for a value like 1.234 when forcing a scale:try {
new BigDecimal("1.234").setScale(2, RoundingMode.UNNECESSARY);
} catch (ArithmeticException e) {
System.err.println("Rejected scale: " + e.getClass().getSimpleName());
}We assert the exception types but never replace the data with a dummy. Each failed Entry remains in our records for manual review. For example, as expected, setScale(2, UNNECESSARY) throws ArithmeticException on 1.234. We do not coerce it to 0 or null. Importantly, once a payload is overwritten in the TreeMap, no further normalization can recover it. For example, if E1 is gone after the map rebuild, trying to re-normalize the key will not restore E1’s data. The only remedy is to rebuild from the original entry list.
Rebuild from the original entries rather than the collapsed map
If a policy is approved, we rebuild the candidate map from the original entries. For instance:
Map<BigDecimal,String> candidate = new TreeMap<>();
for (Entry e : entries) {
BigDecimal k = e.key().stripTrailingZeros(); // or other policy
candidate.put(k, e.payload);
}
This re-applies the chosen identity. In our example, rebuilding with numeric normalization yields the same 2-entry map (losing one payload) unless we implement a special merge. The point is to test the final candidate map, not try to “unwind” the previous one. Note that even converting the old treeMap back into a HashMap and reinserting wouldn’t restore the lost data. Only replaying the original list can.
Package a migration regression harness
All checks above are implemented as executable tests. We test forward and reverse insertion orders, we verify exact source coverage (no missing or extra EntryID), and we check lookups and removals. For example, we permute the order of entries and ensure the reconciled ledger is correct in each case. Any assertion failure causes an immediate nonzero exit, so that a CI build would catch it (following the practice to keep regression failures visible in CI). We include a negative-control branch that attempts the naive conversion (e.g. TreeMap.putAll(hashMap)) and assert that it fails our consistency criteria. In short, our harness is a standalone program: if it exits 0, all identity rules hold; if not, it prints the failure. This keeps any errors explicit and prevents silent data loss in the migration.
Choose accept, repair, hold or rebuild
We now apply a decision matrix:
• ACCEPT: The chosen identity contract has been consistently implemented and all groups reconciled (no payload missing). In that case, we accept the new map as correct.
• REPAIR: If we detect an inconsistency between how keys are inserted vs looked up (for example, we see that HashMap vs TreeMap were using different notions of equality), we must repair the code. Typically this means adding the canonicalization or consistent comparator so that equals vs compareTo don’t mismatch. Essentially, we fix the collection usage to match the declared identity.
• HOLD: If any collision group had conflicting payloads with no resolution policy, we hold the migration. The harness would have already aborted, and we report that domain input is needed (no default “last-write-wins”).
• REBUILD: If we have chosen an identity and provided conflict-resolution, we reconstruct the target map from all source entries and rerun tests. The candidate map passes the same checks. Only after this do we deploy the change.
We also note that simply rolling back to the old code (e.g. using HashMap again) addresses only part of the issue: it restores the original behavior for surviving entries but does not magically resurrect any lost payloads. If we lost data in the attempted migration, a code rollback must be accompanied by data recovery from backup or source. Therefore, we keep code rollback (i.e. removing the new sorting code) as a separate action from data restoration.
Keep a code rollback separate from data restoration
In practice, if we decide this migration was a mistake, reverting the code to use HashMap (for example) will prevent further loss, but it does not recover anything already overwritten. A proper reversal requires reloading the original entries from a safe source. Our report and tests make these steps clear and distinct.
Assign ownership of the key contract
Responsibility for the key identity and collision policy lies with the domain (data/product) owner: they must define what equality means and how to resolve duplicates. The library or code owner (developer) must implement that policy correctly (using the appropriate key class, comparator, and normalization) and ensure equals/hashCode or comparator match the policy. The reviewer should inspect the reconciliation ledger to confirm every source EntryID is accounted for. The deployment or release manager should only enable the change once all tests pass. Whenever the comparator, data model, or runtime changes, the entire suite should be rerun (to catch any change in key behavior). We do not assume concurrency or distributed consistency here, since this is a single-process laboratory exercise.
Strengthen the software-engineering foundations behind safe refactors
This exercise highlights the value of explicit contracts and automated tests in refactoring. By defining the key identity contract up front and validating it with code, we avoid sneaky bugs. These practices, including clear contracts, lossless refactoring and regression harnesses, are core software-engineering skills. Refonte Learning’s Software Engineering Program covers precisely these fundamentals. It’s a three-month, part-time curriculum (about 12–14 hours/week) for learners pursuing or holding a bachelor’s degree in CS, engineering, or math. Graduates earn a Training Certificate (and a Certificate of Internship) upon completion. The program includes software engineering foundations, backend development, performance, scalable design, and more. It does not promise a job or formal degree accreditation, but it reinforces the kind of disciplined, contract-driven approach we’ve used here. For those interested, follow the recommended programming learning path that guides you through these core topics.