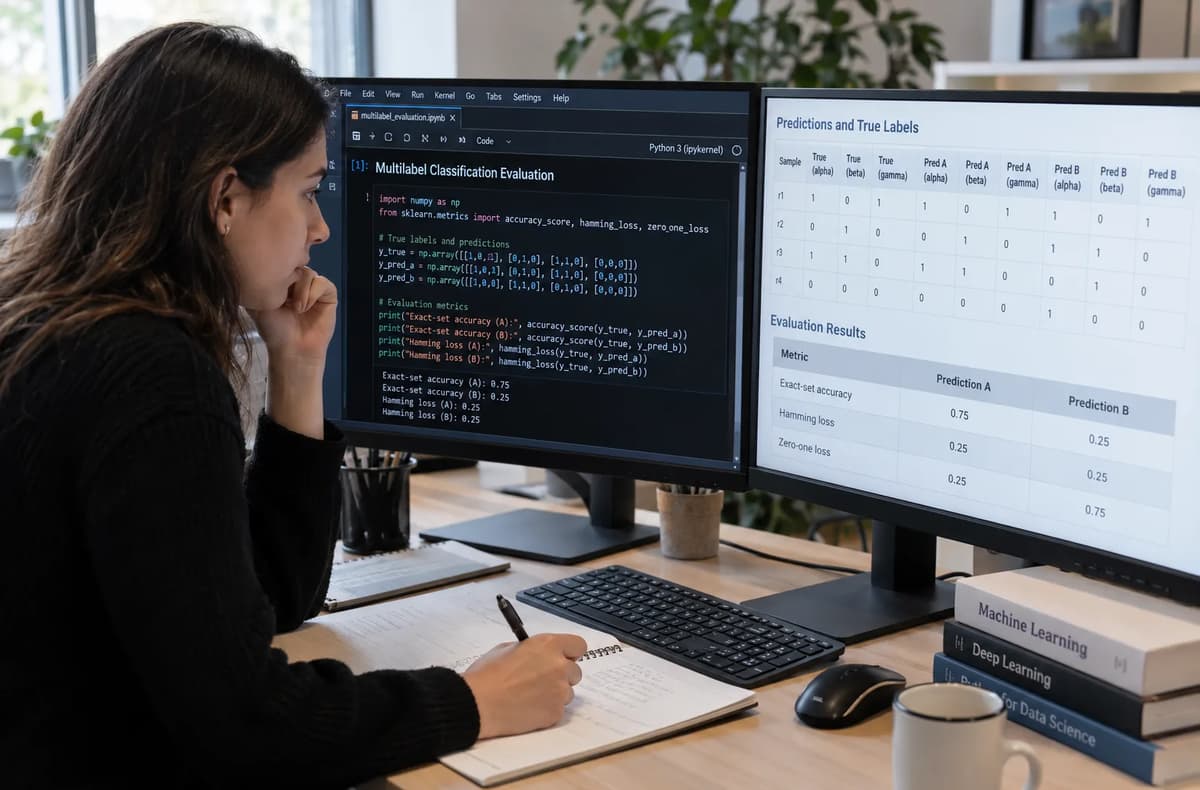
Two prediction matrices each contain three wrong label decisions out of twelve. Yet one receives an exact-set accuracy of 0.75, while the other receives 0.25. Both calculations can be correct because the metric applies a sample-level all-labels-match predicate rather than counting correct cells. In the supplied synthetic execution, matrix A concentrates all three errors in one sample; matrix B distributes them across three samples. Three rows are exact in A, but only one is exact in B.
That difference follows the scikit-learn 1.8.0 accuracy_score contract: for a multilabel indicator matrix, the set of labels predicted for a sample must exactly match the corresponding truth set. Correct decisions in only part of the row do not make that sample exact.
Hamming loss asks a different question: how many individual binary decisions are wrong? The two matrices therefore share the same cell-error fraction while having different exact-set accuracies. These are observations from fixed synthetic predictions, not claims about a trained model.
This laboratory keeps four sample identities and three ordered labels visible throughout its core comparisons. Eight cases cover exact matches, concentrated and distributed errors, complete inversion, a correct additional zero column, flattening, and two rejected inputs. Every number is reconciled with independently authored counts.
The review objective is not to find the most flattering percentage. It is to accept a correctly named measurement, repair a misleading report, reject an unsupported input, or hold a claim whose intended unit cannot be established.
Name the unit before interpreting an accuracy value
A sample here is one complete row identified by r1, r2, r3, or r4. Its label universe is the ordered sequence alpha, beta, gamma. The row [1,0,1] therefore records three binary decisions belonging to one sample, not three interchangeable samples.
An exact-set question asks: Did every decision in this row match? A cell-level question asks: Did this particular sample–label decision match? Both questions can be meaningful, but they have different counting units. In the baseline fixture, the first has four opportunities for success; the second has twelve.
Write that distinction into the report before calculating anything. For example, “exactly correct samples / evaluated samples” identifies one numerator and denominator. “Correct binary label decisions / evaluated binary label decisions” identifies another. A heading that merely says “accuracy” leaves the reader to supply a meaning that the implementation may not share.
Refonte Learning's model evaluation foundations provide broader context for interpreting evaluation results. This exercise narrows that discussion to measurement accounting: the predictions are fixed, and the reporting unit is the object under review.
Keep the population visible as well. All four source samples participate in the core comparisons. A change from four rows to twelve flattened entries does not discover eight additional source samples; it changes what one evaluated observation represents. Likewise, an added label column introduces new decisions without introducing new sample identities.
A practical contract should name the metric, its success or failure predicate, the numerator, the denominator, the sample manifest, and the label universe. Treat the reported decimal as the last field to inspect, not the first. This ordering makes it possible to distinguish a calculation error from an interpretation error without changing the source predictions.
The denominator needs membership as well as size. “Four samples” gives a count; r1 through r4 identify which samples contributed. Retain both so that a reviewer can connect each success flag to its source row.
Read the multilabel metric contracts precisely
The accuracy_score API reference defines the multilabel result as subset accuracy: one sample succeeds only when its predicted label set matches completely. The relevant predicate is whole-row equality, not the proportion of matching entries within that row.
The hamming_loss API reference defines Hamming loss as the fraction of labels predicted incorrectly. In this unweighted, fixed-width, dense binary-indicator fixture, that is the number of mismatching cells divided by all cells. A correct zero contributes a correct decision just as a correct one does.
The zero_one_loss API reference supplies the sample-level loss comparison. In multilabel classification, the whole label set must match; otherwise that sample incurs a loss of one. With normalize=False, the function returns the number of misclassifications.
The scikit-learn 1.8.0 metrics and scoring guide places those definitions in the indicator-matrix setting and identifies each cell as the presence or absence of one label for one sample. That distinction is the context needed here; no broader metric survey is required.
This is a specific application of defining an evaluation contract: decide what the report claims before comparing numbers.
Separate normalized values from counts
Let G be entirely correct rows, F failed rows, E wrong cells, N samples, and L labels. For the admitted fixture pairs:
Exact-set accuracy is G/N; accuracy_score(normalize=False) returns G.
Zero-one loss is F/N; zero_one_loss(normalize=False) returns F.
Hamming loss is E/(N*L); its complement is correct-cell accuracy.
In this unweighted fixture, the first two raw API results are sample counts, not cell counts. Normalized exact-set accuracy and zero-one loss sum to one because every row is either exact or imperfect.
Do not confuse turning normalization off with flattening the inputs. The former removes division while retaining the sample-level predicate for an indicator matrix. The latter changes the observations supplied to the function. Neither operation requests partial credit within the original exact-set calculation.
For B, the resulting accounting is G=1, F=3, E=3, N=4, and L=3. Thus 1/4 is exact-set accuracy, 3/4 is zero-one loss, and 3/12 is Hamming loss. Showing those fractions beside decimals prevents the shared numeral three from disguising different units.
Freeze four samples and three label identities
Use these exact records. Within every vector, positions mean alpha, beta, and gamma, in that order.
Sample ID | Truth Y | Prediction A | Prediction B |
r1 | [1,0,1] | [0,1,0] | [0,0,1] |
r2 | [0,1,0] | [0,1,0] | [1,1,0] |
r3 | [1,1,0] | [1,1,0] | [0,1,0] |
r4 | [0,0,0] | [0,0,0] | [0,0,0] |
The identities and baseline label meanings are immutable parts of the experiment's contract. The Python lists below are not language-level immutable objects; the driver simply does not revise their original contents. M5 constructs extended lists explicitly, leaving the baseline matrices available for comparison.
The supplied commissioning execution used CPython 3.13.5, NumPy 2.3.5, and scikit-learn 1.8.0, on Linux-6.18.44-x86_64-with-glibc2.41. It was CPU-only. No estimator was fitted, no model was downloaded, and no external evaluation data was involved.
Documentation and execution need separate version records. The versioned scikit-learn 1.8.0 pages cited here document the contracts under review, while the commissioning record identifies the runtime that produced the supplied results. Neither source supports a blanket compatibility claim across releases.
Use the public definitions to identify the intended contract and the attributed execution to describe the observed cases. A future rerun needs its own environment and result record; a matching package name alone is not evidence that the same experiment ran.
For background on the array-oriented foundations, see numerical tools for data scientists. Here, the important discipline is deliberately small: retain each row's identity, preserve the three original label meanings, and make any change to the measurement universe visible. The fixture is small enough that a reviewer can check every decision without relying on a summary score.
Run the complete eight-case metric-unit laboratory
Save the following complete driver as multilabel_fixture.py. Start with CPython 3.13.5 available as python. In a fresh Linux virtual environment, these commands install the two named reproduction pins and run the file:
python --version
python -m venv .venv
. .venv/bin/activate
python -m pip install numpy==2.3.5 scikit-learn==1.8.0
python multilabel_fixture.py
These commands request the named NumPy and scikit-learn versions. They are reproduction pins, not recommendations for the latest available releases or a complete dependency lock. The script records the versions actually imported but does not enforce them against fixed strings. Check the resulting environment fields rather than assuming the installation command proves what ran.
"""Fixed predictions, hand-authored counts, no fitting or model-quality claim."""
import hashlib
import json
import platform
import tempfile
from datetime import datetime, timezone
from pathlib import Path
import numpy as np
import sklearn
from sklearn.metrics import accuracy_score, hamming_loss, zero_one_loss
Y = [[1,0,1], [0,1,0], [1,1,0], [0,0,0]]
A = [[0,1,0], [0,1,0], [1,1,0], [0,0,0]]
B = [[0,0,1], [1,1,0], [0,1,0], [0,0,0]]
IDS = ['r1', 'r2', 'r3', 'r4']
LABELS = ['alpha', 'beta', 'gamma']
def inspect_pair(truth, prediction):
    t, p = np.asarray(truth), np.asarray(prediction)
    if t.ndim != 2 or t.shape != p.shape or min(t.shape) == 0:
        raise ValueError('Expected equal nonempty two-dimensional arrays')
    if not np.isin(t, [0,1]).all() or not np.isin(p, [0,1]).all():
        raise ValueError('Expected binary indicator values')
    exact = [all(x == y for x, y in zip(rt, rp)) for rt, rp in zip(truth, prediction)]
    wrong = sum(x != y for rt, rp in zip(truth, prediction) for x, y in zip(rt, rp))
    return dict(exact_rows=exact, exact_count=sum(exact), wrong_cells=wrong,
                cells=int(t.size), accuracy=float(accuracy_score(t,p)),
                exact_count_api=int(accuracy_score(t,p,normalize=False)),
                hamming=float(hamming_loss(t,p)), zero_one=float(zero_one_loss(t,p)),
                failed_rows_api=int(zero_one_loss(t,p,normalize=False)))
if **name** == '\_\_main\_\_':
    dest = Path(tempfile.mkdtemp(prefix='multilabel-run-', dir=Path(\_\_file\_\_).parent))
    report = {'fixture':'multilabel-units-v1','status':'FAIL','cases':[],
              'python':platform.python_version(),'platform':platform.platform(),
              'numpy':np.\_\_version\_\_,'sklearn':sklearn.\_\_version\_\_,
              'ids':IDS,'labels':LABELS,'truth':Y,
              'started_utc':[datetime.now](http://datetime.now)(timezone.utc).isoformat(),
              'source_sha256':hashlib.sha256(Path(\_\_file\_\_).read_bytes()).hexdigest()}
    try:
        specs = [
            ('M1',Y,Y,4,0,12,[True,True,True,True]),
            ('M2',Y,A,3,3,12,[False,True,True,True]),
            ('M3',Y,B,1,3,12,[False,False,False,True]),
            ('M4',Y,[[1-x for x in r] for r in Y],0,12,12,[False]*4),
            ('M5',[r+[0] for r in Y],[r+[0] for r in B],1,3,16,[False,False,False,True]),
        ]
        for identity, truth, pred, good, bad, cells, matches in specs:
            row={'id':identity,'status':'FAIL','prediction':pred}
            report['cases'].append(row)
            out=inspect_pair(truth,pred)
            row['observed']=out
            if (out['exact_count'],out['wrong_cells'],out['cells'],out['exact_rows']) != (good,bad,cells,matches):
                raise AssertionError('Independent oracle mismatch: '+identity)
            if out['accuracy'] != good/4 or out['exact_count_api'] != good:
                raise AssertionError('Wrong sample denominator')
            if out['hamming'] != bad/cells or out['zero_one'] != (4-good)/4 or out['failed_rows_api'] != 4-good:
                raise AssertionError('Wrong loss denominator')
            row['status']='PASS'
        row={'id':'M6','status':'FAIL'}
        report['cases'].append(row)
        flat=float(accuracy_score(np.array(Y).ravel(),np.array(B).ravel()))
        row['flattened_accuracy']=flat
        if flat != .75 or flat == report['cases'][2]['observed']['accuracy']:
            raise AssertionError('Flattening control missing')
        row['status']='PASS'
        for identity,t,p in [('M7',Y,B[:-1]),('M8',Y,[[.5,0,1]]+B[1:])]:
            row={'id':identity,'status':'FAIL'}
            report['cases'].append(row)
            try:
                inspect_pair(t,p)
            except ValueError:
                row\.update(status='PASS',observed='REJECT_INPUT')
            else:
                raise AssertionError('Invalid input accepted')
        if len(report['cases']) != 8:
            raise AssertionError('Incomplete case inventory')
        report['status']='PASS_8_CASES'
    except BaseException as error:
        report['error']={'type':type(error).__name__,'message':str(error)}
        raise
    finally:
        report['finished_utc']=[datetime.now](http://datetime.now)(timezone.utc).isoformat()
        path=dest/'results.json'
        path.write_text(json.dumps(report,indent=2,allow_nan=False)+'\n',encoding='utf-8')
        print(path)
The supplied commissioning record reports multilabel-units-v1 with status PASS_8_CASES. It started at 2026-10-13T07:37:42.026032+00:00 and finished at 2026-10-13T07:37:42.058556+00:00. These timestamps identify one run; they are not a performance benchmark.
Its recorded source SHA-256 is fb4599a027218968739ec30abd6766f47a31302f7461d4d90b2e73a744042861. The driver computes a digest from its own saved bytes, so preserve the source alongside the report. Editing whitespace or line endings can change the fingerprint even when the intended calculations remain the same. A digest identifies bytes; it does not certify their correctness.
On a successful reproduction, the expected behavior is to print the path of a new results.json beneath a multilabel-run- directory beside the script. The directory name and timestamps will belong to that rerun. Do not copy the commissioning timestamps into fresh evidence or treat the printed path itself as a passing result.
Read the top-level status and the complete case inventory. M1–M5 include predictions, row flags, ordinary counts, API counts, and normalized metrics. M6 records the flattened accuracy. M7 and M8 record REJECT_INPUT when their expected ValueError occurs. A test case marked PASS therefore does not necessarily describe an input admitted for measurement: the last two tests pass by rejecting their inputs.
The failure path matters too. A case is appended with status FAIL before its checks run, and completed cases remain in the report. Exceptions inside the guarded block are recorded and re-raised, while finally attempts to write the available evidence. This supports diagnosis of which checks completed before failure; it is not a guarantee of durable output after import failure, setup failure, an unwritable destination, or abrupt process termination.
The sequential inventory is important: if an early case raises, later cases were not run. Treat those later cases as unexecuted, not passed or failed. The final eight-case status is assigned only after the comparisons and both rejection checks complete. An isolated successful case or an incomplete report is not evidence of an eight-case result.
The driver is intentionally bounded. It records the main versions and platform, not a complete dependency lock or a general evaluation schema. Its sample denominator of four is deliberate fixture knowledge. Its global label list describes the baseline universe; the explicit M5 construction documents the added coordinate. Preserve those distinctions when interpreting the JSON.
Use an independent counting oracle
The expected values in specs are authored before calling the metrics: exact-row count, wrong-cell count, total cells, and the expected row flags. For example, M2 requires 3,3,12 with [False,True,True,True]; M3 requires 1,3,12 with [False,False,False,True]. Those requirements are not calculated from accuracy_score.
Inside inspect_pair, ordinary iteration checks complete row matches and counts pairwise mismatches. The shape and domain checks happen first. Consequently, the demonstrated unequal-shape case is not silently reduced to the common prefix by zip. The resulting ordinary counts must match the literal expectations before the library values are accepted.
Next, the API outputs must reconcile with those counts using the appropriate denominators. Two API calls agreeing would not, by themselves, constitute independent proof: both could reflect the same misunderstood definition. The independent evidence is the known matrix content and its separately specified ledger.
This also explains why the fixture tests both raw and normalized results. A correct decimal could be paired with a wrong description of what the raw count represents. Checking exact_count_api and failed_rows_api against independently specified sample counts makes that interpretation testable. The suite qualifies these eight cases, not every possible array, representation, or downstream use of a score.
Keep the perfect and completely wrong controls
M1 compares Y with itself. Every decision matches, giving the exact-row flags [True,True,True,True]. There are four exact samples, zero failed samples, twelve correct cells, and zero wrong cells. Exact-set accuracy is 4/4=1; Hamming loss is 0/12=0; zero-one loss is 0/4=0.
The raw API checks strengthen that statement. The unnormalized accuracy count is four, not twelve. The unnormalized zero-one loss count is zero. Even at a perfect result, the numerator's unit must remain visible; otherwise “all predictions correct” can conceal whether the report means samples or cells.
M4 supplies the opposite control by replacing every binary value x with 1-x. Its prediction rows are [0,1,0], [1,0,1], [0,0,1], and [1,1,1]. Each row has three mismatches, so the flags are [False,False,False,False]. Exact-set accuracy is 0/4=0, Hamming loss is 12/12=1, and zero-one loss is 4/4=1.
These controls establish the fixture's endpoints. They also catch a reversed interpretation of success and loss: complete agreement belongs at accuracy one and loss zero, while complete disagreement belongs at accuracy zero and loss one.
However, endpoints alone cannot distinguish the two accuracy units. Both sample-level accuracy and correct-cell accuracy equal one in M1 and zero in M4. A report that incorrectly substitutes cell accuracy could still pass both controls. The partially wrong matrices are essential for detecting that mistake.
Pay particular attention to r4. Its truth row [0,0,0] is not an absent record. It says that none of the three named labels is present for this sample. Matching that row satisfies the fixture's complete-set predicate; predicting [1,1,1] fails all three decisions. Removing the row would alter the declared four-sample population and its denominator.
Keep r4 in the ledger even though its selected-label set is empty. The empty set is the content of the prediction question, not permission to discard the sample carrying it.
Concentrate three errors in one sample
M2 uses prediction A. Compare its first row with Y: truth is [1,0,1], while prediction is [0,1,0]. All three positions disagree. The remaining rows match completely.
The resulting ledger separates the units without asking the reader to infer them from a percentage:
Sample | Wrong cells in its three labels | Entire row exact? |
r1 | 3 | False |
r2 | 0 | True |
r3 | 0 | True |
r4 | 0 | True |
The literal exact-row flags are [False,True,True,True]. Three samples succeed, giving accuracy_score(Y,A)=3/4=0.75. Three label decisions fail, giving Hamming loss 3/12=0.25. One sample fails, giving zero-one loss 1/4=0.25. The corresponding raw sample counts are three exact and one failed.
Nothing was fitted or optimized to obtain these values. A is a hand-authored control whose error concentration is deliberately easy to inspect. Its role is to test the reporting interpretation, not to represent a recommended pattern of model behavior.
Count a sample once even when several labels are wrong
For exact-set accounting, r1 contributes one failure. It cannot contribute three failed samples because it is still one sample. For Hamming accounting, the same row contributes three errors because it contains three wrong decisions. The API contracts distinguish those two predicates rather than disagreeing about the matrix.
M2 also contains a useful reporting trap. Its correct-cell accuracy is 9/12=0.75, numerically identical to its exact-set accuracy of 3/4=0.75. A test that checks only the decimal could therefore miss a mislabeled output or an unintended flattening operation.
Likewise, its Hamming loss and zero-one loss both equal 0.25, although one counts three wrong cells and the other counts one failed sample. Equality in this case does not make the definitions interchangeable.
Preserve the row ledger beside the aggregate. The coincidence then becomes transparent: all errors occupy one completely wrong row, leaving the other three untouched. A different placement of those same three wrong cells will break the numerical coincidence without changing their total.
Distribute the same three errors across three samples
M3 uses prediction B. Its first row [0,0,1] differs from truth only at alpha. Its second row [1,1,0] also differs only at alpha, but for a different sample. Its third row [0,1,0] again differs only at alpha. The final row remains [0,0,0] and matches completely.
The error ledger is now:
Sample | Wrong cells in its three labels | Entire row exact? |
r1 | 1 | False |
r2 | 1 | False |
r3 | 1 | False |
r4 | 0 | True |
The exact-row flags become [False,False,False,True]. Only one sample is entirely correct, so exact-set accuracy is 1/4=0.25. Three samples have at least one error, so zero-one loss is 3/4=0.75. The raw sample counts are one exact and three failed.
Hamming loss remains 3/12=0.25. Correct-cell accuracy remains 9/12=0.75. The cell totals are identical to M2, but the sample outcomes are not. That is how the fixture produces the same Hamming loss with different accuracy values.
Compare the two row-error vectors directly: A has [3,0,0,0]; B has [1,1,1,0]. Summing either vector produces three. Counting its zero entries produces three exact rows for A and one for B. Summation has discarded the distribution information needed by the second operation.
There is also a simple arithmetic bound. Each failed row in this three-label fixture contains between one and three wrong cells. If F is failed rows and E is wrong cells, then F <= E <= 3*F. With E=3, between one and three rows can fail. A and B realize the endpoints of that range; a Hamming total alone cannot tell which endpoint occurred.
The contrast is not caused by a changed denominator: both comparisons contain four samples and twelve cells over the same label universe. The difference comes entirely from where the three mismatches occur within those retained rows.
This inference does not require another execution. It follows from the row width and the supplied counts. Nor does it establish that one error distribution should be preferred for a particular application. That judgment belongs to the previously declared measurement purpose. The review finding is narrower: a report cannot translate the shared cell loss into an exact-set success rate without retaining row-level information.
Add a correct zero column without fixing an existing error
M5 starts from Y and B, then appends one zero to every truth row and every prediction row. There are still four source samples, but each now contains four binary label decisions. The matrices therefore have sixteen cells instead of twelve.
Every original decision is unchanged. The same three original mismatches remain in r1, r2, and r3. The added coordinate matches for every sample, so it introduces four correct cells and no new wrong cells.
The exact-row flags remain [False,False,False,True]. A failed row does not become exact merely because one additional decision is correct. The already exact r4 stays exact because its added decision also matches. Exact-set accuracy consequently stays 1/4=0.25, and zero-one loss stays 3/4=0.75.
Cell accounting changes. Hamming loss becomes 3/16=0.1875, compared with 3/12=0.25 in M3. Correct-cell accuracy becomes 13/16=0.8125, compared with 9/12=0.75. These new fractions describe the extended matrix accurately. They do not demonstrate that any original prediction was repaired.
This is why an all-zero label-padding control is useful. A more favorable label-level number can arise solely from adding universally correct decisions to the denominator. The unchanged wrong-cell count exposes what actually happened.
Preserve the label-universe revision
Keep the baseline universe alpha, beta, gamma separate from the extended universe containing those labels plus the audit-only zero coordinate. The fourth coordinate is deliberately additional; it is not evidence about a previously evaluated label.
The exact driver leaves its top-level LABELS list at the baseline three names. M5's explicit construction and sixteen-cell count document its extension in the source. Do not describe that top-level metadata as a complete four-label manifest. For a reusable report format, attach a case-specific universe revision and an explicit identity for the added coordinate.
That per-case metadata is a proposed reporting improvement, not a field secretly emitted by the supplied driver. Retaining the source keeps the present fixture interpretable without overstating what its JSON contains.
Use REPAIR_REPORT when a comparison presents M5's lower loss as improvement on the unchanged baseline question. Repair the universe description and the comparison, not the source errors. M5 is acceptable as a clearly identified padding control; it is not interchangeable with the original three-label measurement.
Show why flattening answers a different question
M6 passes np.array(Y).ravel() and np.array(B).ravel() to accuracy_score. In the supplied execution, the returned value is 0.75. The unflattened comparison in M3 returned 0.25.
The arithmetic is straightforward. Flattening presents twelve binary observations to the call. Nine corresponding entries match and three do not, so the result is 9/12=0.75. In M3, the question was whether each of four complete rows matched, giving 1/4=0.25.
Every original cell remains represented, and every source sample still contributes its three decisions. The semantic change is the observation unit. The flattened call no longer evaluates four complete label sets. It evaluates twelve individual entries under the one-dimensional accuracy contract.
For these arrays, the flattened value also equals 1 - 3/12, the complement of their Hamming loss. That agreement follows from counting the same correct and incorrect cells. It does not make the flattened result another implementation of exact-set accuracy.
Flattening can be valid when the declared question is explicitly cell-level. A suitable description is “correct binary label decisions across the four-by-three population: 9 of 12.” It is a reporting error to present that number as “samples with an entirely correct label set: 75%.” The latter description claims three exact samples, but B has only one.
The distinction is related to the habit behind why finite regression scores need context: a plausible number still needs an identified meaning. This laboratory is different, however. Its compared scores are defined, all four source samples remain represented, and no regression or fold interpretation is needed.
There is a practical evidence boundary in the driver. M6 records flattened_accuracy; it does not call the helper again to produce a second row ledger. Its original-row context comes from M3, which uses the same Y and B. When presenting both values together, identify that relationship instead of implying M6 independently emitted every supporting count.
Flattening is therefore neither automatically forbidden nor automatically corrective. It is an explicit change of question that must be named before the result can be accepted.
Reject unsupported input rather than guessing an interpretation
M7 supplies Y and B[:-1]. Their shapes differ: truth has four rows and three columns; prediction has three rows and three columns. The helper raises ValueError with the message Expected equal nonempty two-dimensional arrays before computing its ordinary counts or calling the metrics.
The supplied execution records this case as REJECT_INPUT. That is the intended outcome. Scoring whichever rows happen to be available would not fulfill the declared paired-matrix contract. The helper does not invent the missing prediction or silently revise the population.
M8 supplies a prediction containing 0.5. The shapes match, but the entry is outside the binary value domain. The helper raises ValueError with Expected binary indicator values, and the commissioning record again reports REJECT_INPUT.
No threshold is inferred. The fixture requires decisions already expressed as zeros and ones; interpreting an arbitrary score is a different task. Replacing 0.5 with a binary value merely to obtain a metric would change the supplied prediction and need a separate, explicit contract.
The admission rule requires equal, nonempty, two-dimensional arrays with binary indicator values. The code checks values, not an integer-only dtype requirement. Its dimensionality and nonemptiness guards express additional input requirements, but the recorded negative controls specifically demonstrate unequal shape and the nonbinary 0.5 case. They are not a claim that every invalid representation was exercised.
Keep input admission separate from model-quality approval
Passing these guards permits this helper to calculate the declared comparisons. It does not establish that the source truth is authoritative, that the retained population represents an application, or that a model is suitable for release.
The helper receives numeric pairs, not sample IDs or label names. Those identities belong to the surrounding fixture contract; the function does not authenticate them. A reusable workflow should verify the manifests before invoking it, rather than attributing identity checks to code that has no such inputs.
Sparse matrices, ragged representations, sample weights, and arbitrary score arrays remain outside this demonstrated contract. Do not infer broader support from the underlying libraries or from two passing rejection tests. Here, a negative-control PASS means the expected boundary held, not that a usable evaluation result was produced.
Reconcile all eight cases with their denominators
The following table reconciles the supplied eight-case manifest. T means True and F means False, always in r1–r4 order. M6's original-row figures are carried from M3 as source context; M6 itself records only flattened accuracy.
Case | Exact rows: flags and count | Wrong cells | Total cells | Exact-set accuracy | Hamming loss | Reporting decision |
M1 | TTTT; 4/4 | 0 | 12 | 4/4 = 1 | 0/12 = 0 | ACCEPT_NAMED_METRIC |
M2 | FTTT; 3/4 | 3 | 12 | 3/4 = 0.75 | 3/12 = 0.25 | ACCEPT_NAMED_METRIC |
M3 | FFFT; 1/4 | 3 | 12 | 1/4 = 0.25 | 3/12 = 0.25 | ACCEPT_NAMED_METRIC |
M4 | FFFF; 0/4 | 12 | 12 | 0/4 = 0 | 12/12 = 1 | ACCEPT_NAMED_METRIC |
M5 | FFFT; 1/4 | 3 | 16 | 1/4 = 0.25 | 3/16 = 0.1875 | REPAIR_REPORT for baseline substitution |
M6 | FFFT; 1/4, source | 3, source | 12 | 1/4 = 0.25, source; flattened accuracy = 9/12 = 0.75 | 3/12, source | REPAIR_REPORT for unit substitution |
M7 | N/A | N/A | N/A | N/A | N/A | REJECT_INPUT |
M8 | N/A | N/A | N/A | N/A | N/A | REJECT_INPUT |
For M1–M5, the raw exact-sample API counts are [4,3,1,0,1]; the failed-sample API counts are [0,1,3,4,3]. Their normalized zero-one losses are respectively 0/4, 1/4, 3/4, 4/4, and 3/4. Each pair of raw sample counts sums to four.
M2 and M3 expose equal cell loss with different complete-row outcomes. M5 changes the label universe; M6 changes the observation unit. Their repair decisions apply when those changes are presented as baseline improvements or replacements. A correctly named padding control or cell-level report can instead be accepted under its explicitly revised contract.
Archive this reconciliation with the source and JSON as QA evidence for a regression gate. Preserve the distinctions between observed API outputs, independently specified counts, and workflow decisions; collapsing them into a single green status would discard much of the test's value.
Accept a named report or repair an ambiguous one
A report is acceptable when its value and its description agree with the declared unit, denominator, sample population, and label universe. For the baseline B comparison, a suitable reporting statement is:
Multilabel exact-set accuracy: 1 entirely correct sample out of 4, or 0.25. Population: r1, r2, r3, r4. Ordered label universe: alpha, beta, gamma. Predictions: B against truth Y.
Under the supplied fixture contract, that statement supports ACCEPT_NAMED_METRIC. It identifies what was counted and leaves an auditable route back to the matrices. Acceptance is not contingent on the number being large; the entirely wrong M4 result can also be reported correctly.
Use REPAIR_REPORT when the calculation is available but its presentation answers the wrong question. Examples include naming exact-set accuracy as label-level accuracy, presenting M6 as an improved exact-set result, or comparing M5's expanded denominator with the baseline without disclosure. Repair may require relabelling, recomputing, or separating incomparable report entries.
Use REJECT_INPUT when the helper's input contract fails, as in M7 and M8. Do not create a headline metric for those rejected pairs. Use HOLD when the intended unit, original predictions, or identifying manifests cannot be established. A finite number cannot resolve missing provenance by itself.
These decisions form a proposed reporting workflow around the demonstrated calculations. They do not replace domain review or authorize a model release.
Do not choose the metric merely because its number is larger
For B, 0.75 cell accuracy and 0.25 exact-set accuracy describe the same original predictions. Selecting the larger value after seeing both does not repair the lower one. It substitutes a different claim.
Approve the question first, then calculate and name its answer. When repairing an existing report, preserve the previous statement and explain the correction. That includes M2, where relabelling can matter even though the decimal stays 0.75. A numerically unchanged repair can still correct a consequential misunderstanding about what counted as success.
Recover historical reports and assign metric ownership
Begin recovery from retained truth and prediction matrices, not from a preferred replacement percentage. Locate the sample manifest, label universe, original reporting code, and relevant environment record. Establish whether the historical call received a two-dimensional indicator matrix, a flattened vector, or an explicitly extended universe.
Then recompute the named measurements without silently revising the original predictions. Preserve the old report, the corrected report, and the reason for the change. Distinguish a wrong calculation from a correct calculation carrying the wrong label; those failures require different explanations even when both lead to REPAIR_REPORT.
A Hamming summary alone cannot restore the missing row ledger. Even knowing exactly Hamming=0.25, N=4, and L=3 establishes three wrong cells but does not distinguish A from B. The supplied matrices demonstrate why exact-set accuracy cannot be reconstructed from that total. Without sufficient source evidence, keep the exact-set claim on HOLD rather than inventing its distribution.
If a historical percentage was rounded, even recovery of the exact cell-error total may be uncertain. Keep the displayed precision separate from retained integer counts, and do not manufacture an exact count from an ambiguous rounded summary.
Assign ownership explicitly. The evaluation owner defines the measurement unit and report schema. Domain reviewers approve whether that unit serves the intended question. QA retains the fixed-case suite and checks it after library or reporting changes.
Do not rewrite the literal expected counts merely to make a changed implementation pass. Investigate a discrepancy against the preserved matrices and contract first. A new execution should retain its own source digest, versions, timestamps, and case results. That creates a traceable correction history without treating one successful synthetic run as evidence for every future environment.
Build reliable evaluation habits with data-science foundations
The useful habit is to move fluently between Python arrays, explicit counts, and the sentence a report asks its reader to believe. NumPy and scikit-learn supply the computational setting here; statistical reasoning supplies the discipline of defining an observation before interpreting its aggregate.
For structured work on those foundations, explore Refonte Learning's Data Science & AI program. The official page lists a three-month period and 12–14 hours per week. Its competencies include Python Data Science, Statistical Modelling, Machine Learning and Predictive Modelling, and Application to Industry Projects; its FAQ explicitly names NumPy and scikit-learn. These are program descriptions, not confirmation that this exact laboratory or these package versions are taught.
Bring the immediate review action back to the next report: read the unit before interpreting the number. Ask which samples and labels were evaluated, what counted as success, and which denominator produced the value. Keep the raw counts available. Accept a named measurement when those answers agree; repair or hold the claim when they do not.