I’ve been writing pandas code since before pandas had a 1.0 release. In January 2026, upgrading to pandas 3.0 felt like slamming into a brick wall: dozens of my old one-line patterns no longer did what they used to. Simple commands I ran yesterday, such as filtering a DataFrame and then assigning to a column, suddenly had no effect on the original data. In real codebases, that produced silent logic failures: the pipeline ran and some tests passed, but the results were wrong.
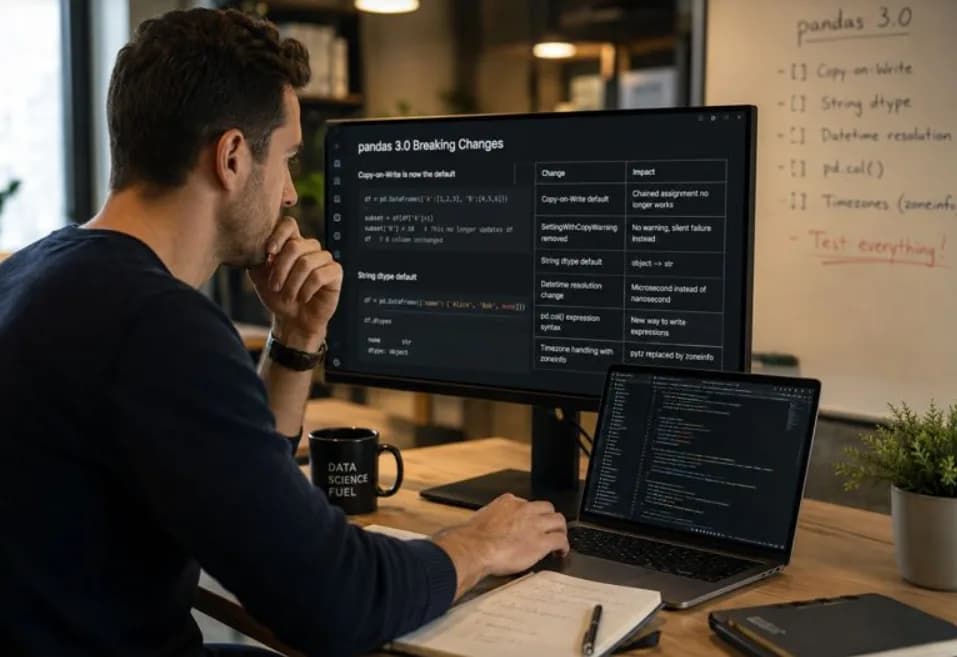
What happened? pandas 3.0, released January 21, 2026, made a handful of long-promised changes mandatory rather than optional. As the official “What’s New in 3.0.0” release notes explain, Copy-on-Write is now the only mode, so an object produced by indexing cannot mutate its parent through a chained assignment. The old SettingWithCopyWarning is gone, text columns now infer a dedicated str dtype instead of generic object, and datetime parsing can preserve or infer a coarser resolution such as microseconds rather than forcing nanoseconds.
All of these changes can break code that has been considered “known good” for years. This article walks through each change, explains why it affects established patterns, and shows how to adapt a real codebase. The Refonte Learning Data Science & AI Program names Pandas as a core tool in its Python Data Science module, which provides the foundation needed to understand migrations like this.
This is a migration guide written from experience, not a changelog summary. I had to repair production transformations and investigate queries that returned plausible but incorrect results. By the end, you will know what changed in pandas 3.0 and how to update your muscle memory, tests, and pipelines.
The Code That Worked Yesterday and Doesn't Today
If you’ve used pandas since the 2010s, chances are high that code like these once worked for you:
· df[df['condition']]['col'] = new_val (filter then assign)
· subset = df['col']; subset[...] = something (modify subset)
· df.loc[mask]['col'] = value (chained slicing)
· df['col'].replace(x, y, inplace=True) on a sliced Series.
All of these patterns involve chained indexing, where you select data in multiple steps. For years, pandas would issue a SettingWithCopyWarning for these, because sometimes the change would silently fail (only warning you). Many tutorials and answers on StackOverflow even used these idioms without a second thought.
In pandas 3.0, these patterns no longer update the original object. Each indexing step produces an intermediate object under Copy-on-Write, so df[df['A'] > 0]['B'] = 5 cannot change df. The old SettingWithCopyWarning is gone; an attempted chained set may instead emit ChainedAssignmentError, while the original data remains unchanged. I hit this in a project where a filtered assignment was supposed to create a flag column, but downstream grouping logic saw no flag.
If this scenario sounds familiar, you’re not alone. Even with diligent testing, I had to audit dozens of lines of code. Some were obvious chain-assignment patterns, others less so (e.g. using .apply() on a slice). If you want to avoid the stress, start by searching your code for any time you do more than one indexing or [] in a single expression. Convert each case to a single .loc or .iloc assignment instead. We’ll cover examples below.
The Data Science & AI program at Refonte Learning teaches Pandas from the ground up and introduces safe indexing patterns. Upgrading to pandas 3.0 means changing habits, not abandoning the library.
What Pandas 3.0 Actually Changed, in Brief
Pandas 3.0 turned several optional features into defaults. The short list of breaking changes is:
· Copy-on-Write (CoW) mode is mandatory. Every selection follows CoW semantics, so changes made through a chained assignment never modify the original object.
· SettingWithCopyWarning removed. Pandas no longer uses the old warning because chained assignment is structurally unable to update the parent. An attempted chained set can emit ChainedAssignmentError, so migration work should look for both data differences and this newer warning class.
· String columns use a dedicated str dtype by default. Reading or inferring text now yields pandas’ default string dtype rather than generic object. The dtype accepts strings and missing values; assigning incompatible non-string values raises an error. Replace dtype == object checks with is_string_dtype where the intent is to detect text.
· Datetime and timedelta resolution is inferred. Parsing no longer forces every result to nanoseconds. A Series may now be datetime64[us], and converting that array to integers yields values about 1,000 times smaller than the same moments stored as datetime64[ns]. Any code that assumes nanosecond integers needs an explicit unit.
· New pd.col() expression syntax. Column expressions can replace some lambdas, for example df.assign(z=pd.col('x') + pd.col('y')) or df.loc[pd.col('speed') > 105]. It is optional, but it is a new idiom in .assign(), .loc[], and related expression-aware operations.
· Time zones now use zoneinfo, not pytz, by default. A time-zone-aware object typically exposes a zoneinfo.ZoneInfo instance, and ambiguous or nonexistent local times now raise standard ValueError exceptions. pytz is no longer a required dependency, so projects that import it directly must declare it themselves.
· Minimum Python 3.11. pandas 3.0 dropped support for earlier Python releases. Upgrade the interpreter and validate the rest of the dependency stack before installing pandas 3.x. See the Python 3.11 minimum-version note for the official requirement.
· Arrow interoperability expanded. pandas 3.0 adds DataFrame.from_arrow() and related Arrow PyCapsule interoperability. Patch releases also matter: pandas 3.0.5 corrected a wheel-build problem in 3.0.4 that could lead to crashes on affected installations.
The important point is that these changes were documented in pandas’ release notes and summarized by community coverage such as InfoQ. Copy-on-Write and Arrow-backed string support already existed in pandas 2.x as opt-in features. The breaking change in 3.0 is that key behaviors became defaults or the only supported mode, so code written under older assumptions needs deliberate review.
To avoid confusion, pandas 2.0, released in April 2023, introduced Copy-on-Write and PyArrow-backed dtypes as optional groundwork. pandas 3.0 did not invent those features; it made the new model unavoidable in normal operation. The migration therefore targets habits built under the old defaults.
Copy-on-Write Is No Longer Optional
Starting in pandas 1.5 and 2.x, the library offered a Copy-on-Write (CoW) mode to eliminate ambiguity between views and copies. In pandas 3.0, CoW is the only mode. From the user’s perspective, selecting a column or slicing a DataFrame produces an object whose later mutation cannot affect the parent. That predictability removes accidental cross-object updates, but it invalidates code that relied on them.
What this means for your code: if you do any multi-step indexing, pandas will effectively insert a copy step, so the original DataFrame or Series remains untouched. For example, consider:
subset = df['col'] # a Series extracted from df
subset.iloc[0] = 5 # modify the subset
In older pandas, subset might have been a view of df, so changing it could also change df. In pandas 3.0, subset is independent for mutation purposes, so df stays unchanged. This removes the old view-versus-copy uncertainty.
· Indexing does not propagate side effects. A selection follows Copy-on-Write semantics, so mutating it does not mutate its parent. To update the original DataFrame, assign through a single .loc or .iloc operation on that DataFrame.
· Chained assignment fails. df[mask]['col'] = value modifies only a temporary intermediate and never updates df. pandas may emit a ChainedAssignmentError warning, but the behavioral rule is the same: use .loc on the original object.
· The old Copy-on-Write toggle no longer changes behavior. Settings such as pd.options.mode.copy_on_write cannot restore the pre-3.0 model. Copy-on-Write is always active.
· Defensive copying is often unnecessary. Code that called .copy() only to silence SettingWithCopyWarning can usually be simplified. Keep .copy() when you intentionally need an independent object to mutate or retain.
Predictability improved, but old shortcuts stopped working. You can now be sure that you modify only the object you target explicitly. The standard repair is to replace chained indexing with one assignment against the original DataFrame.
# Old (now broken):
df[mask]['col'] = 0
# New:
df.loc[mask, 'col'] = 0 # does update correctly
Or combine operations:
# Old:
subset = df['col']
subset[subset > 5] = 10
# New:
df['col'] = df['col'].where(df['col'] <= 5, 10)
Before the final upgrade, run your suite on pandas 2.3 with pd.options.mode.copy_on_write = "warn". The pandas 2.3 Copy-on-Write migration guide describes this compatibility mode, which identifies operations whose behavior changes under Copy-on-Write. Treat it as an audit aid, then rewrite affected assignments before moving to pandas 3.0.
Why Chained Assignment Stopped Working
Let me give a concrete example that tripped me up. Suppose I have:
df = pd.DataFrame({'A':[1,2,3],'B':[10,20,30]})
df[df.A > 1]['B'] = 99
print(df)
Before pandas 3.0, this could appear to work, fail silently, or trigger SettingWithCopyWarning depending on whether the intermediate behaved like a view. In 3.0, the condition creates an intermediate DataFrame and the assignment cannot update the original df; df.B remains [10, 20, 30]. The old warning is gone, and the attempted chained set may emit ChainedAssignmentError. The durable fix is a single .loc assignment.
I encountered a frustrating scenario in a data pipeline: an imputation step tried to fill missing values with something like
filtered = df[df.category == 'X']
filtered['value'] = filtered['value'].fillna(mean_val)
None of the missing values got filled in df after upgrading to 3.0. The fix was to do it in one go: df.loc[df.category=='X', 'value'] = df.loc[df.category=='X', 'value'].fillna(mean_val). That pattern (combining mask with column) always works because .loc operates on the original object.
In short, whenever you have df[...] [ ... ] = ..., rethink it. Use df.loc[...] or restructure the operation so there’s only one indexing step on the left side.
What Happened to SettingWithCopyWarning
This brings us to the end of the infamous SettingWithCopyWarning. Long-time pandas users saw it after patterns such as df2 = df[df.X > 0]; df2['Y'] = 3, where pandas could not guarantee whether the assignment targeted a view or a copy. pandas 3.0 removes that warning because Copy-on-Write makes the parent-update outcome deterministic: chained assignment cannot update the parent.
The official release notes explain that SettingWithCopyWarning is no longer needed because chained assignment consistently cannot work. Code that caught, filtered, or suppressed that warning must be revised. For direct chained sets, pandas can emit ChainedAssignmentError, but tests must still verify the data outcome rather than treating a warning filter as protection.
For example, imagine I had:
df = pd.DataFrame({'x':[1,2,3]})
df2 = df[df.x>1]
df2['y'] = 0
In pandas 2.x, this pattern often produced SettingWithCopyWarning. In 3.0, df2['y'] = 0 legitimately adds a column to the separate DataFrame df2, while df remains unchanged. No warning is required in this two-statement example because the code is modifying df2 itself. The migration question is whether the original df was supposed to change; when it was, rewrite the operation against df with .loc.
Key takeaway: SettingWithCopyWarning is gone, but chained assignment still never updates the parent. Attempted chained sets may emit ChainedAssignmentError, while ordinary mutation of an explicitly stored subset may be valid but isolated. Audit the intent of every assignment, not just the presence or absence of a warning.
The New Default String Dtype
In pandas 2.x, inferred text data usually used generic object dtype, while the dedicated string extension dtype was optional. In pandas 3.0, the new default string dtype is used when pandas infers text. A column that once reported object may now report str, and missing values use NaN semantics.
For many workloads this is an improvement: a dedicated text dtype gives pandas clearer semantics and can use an efficient backend. The migration risk sits in code that inspected dtype identity, mixed strings with other Python objects, or depended on a particular missing-value sentinel.
· Dtype differences. The big change is that df['col'].dtype will often be 'string' or "str" instead of "object". Any code that checks dtype == object to identify string columns will no longer work. For example:
ser = pd.Series(["a", "b", "c"])
print(ser.dtype == "object") # was True on pandas 2.x
In pandas 3.x this prints False, because ser.dtype is str. For compatibility, use pd.api.types.is_string_dtype, which identifies text without assuming generic object storage.
· Missing values become NaN. Under the old object-dtype strings, pandas would preserve None as a missing sentinel. With the new str dtype, all missing values are represented as np.nan. So code that does something like:
ser = pd.Series(["a","b", None], dtype="object")
used to show None in the output and ser[2] would literally be None. In pandas 3.0, None gets converted to NaN for a string column. Practically, most pandas methods (like .isna()) treat them the same, but if your code was explicitly checking == None on a column, that may behave differently now. Always use pd.isna(x) to check for missing rather than comparing to None.
· Assignment rules. The new string dtype only holds strings (or missing). Assigning anything else will error. For example, in pandas <3.0 you could do:
ser = pd.Series(["a","b"], dtype="object")
ser[1] = 42 # replaces with int 42
This was fine and ser.dtype remained object. In pandas 3.0:
ser = pd.Series(["a","b"], dtype="str")
ser[1] = 42
raises a TypeError: Invalid value '42' for dtype 'str'. So if your code ever does df.loc[row,'col'] = some_non_string on a string column, it will now break. The solution is either to convert the column to object first (df['col'] = df['col'].astype('object')) or ensure only strings go into it.
· Hardcoded dtypes in code. pd.Series(data, dtype="object") still forces generic object storage. In pandas 3.0, dtype="str" requests the new string dtype rather than acting as an alias for object. Be explicit about whether the column is text-only or intentionally heterogeneous.
· String accessors and methods. Operations such as .str.lower() and .str.contains() remain available, but missing-value behavior can differ because the default string dtype uses NaN. Review tests around the na= argument instead of deleting it mechanically.
If your code inspects dtypes, search for dtype == object in production code and tests. Also review .str.contains() calls whose expected missing-value behavior was implicit. Use is_string_dtype when your intent is to identify textual data across pandas versions.
What Breaks When object Becomes str
Beyond the bullet points above, here are concrete things to check when string columns flip type:
· Dtype checks: replace df[col].dtype == object with is_string_dtype(df[col].dtype) when you mean “is this text?” The old equality check no longer identifies all string columns.
· NumPy dtype functions: a pandas string dtype is not a NumPy object_ dtype, so np.issubdtype checks can fail or return a different result. Use pandas’ type predicates for pandas extension dtypes.
· Copying and conversion: astype({"col": "object"}) still opts into generic Python-object storage, while astype("str") now opts into the dedicated string dtype. Choose based on the intended data contract rather than using either spelling by habit.
· Storage of non-strings: assigning 3.14 into a str column raises an error. Convert to object only when mixed values are a genuine requirement; otherwise normalize incoming values to strings before assignment.
· Missing-value checks: replace identity checks such as value is None with pd.isna(value) when values come from an inferred string column. The new dtype may normalize missing text values to NaN.
In practice, most pandas methods (sorting, grouping, visualization, etc.) don’t care whether it’s object or string dtype. The main issues are in custom code that treats string columns specially.
The Datetime Resolution Change Nobody’s Code Was Ready For
This is the most dangerous break in many data pipelines: datetime64 resolution. Older pandas code often assumed parsing would produce datetime64[ns]. pandas 3.0 preserves or infers a suitable resolution, and parsed values commonly use microseconds (datetime64[us]) when nanoseconds are not required. The timestamp represents the same moment, but the integer count uses a different unit.
For ordinary comparisons, arithmetic, grouping, and resampling, a microsecond timestamp is still precise. The danger appears when code reads or stores the backing integer. A microsecond count is 1,000 times smaller than the equivalent nanosecond count.
The official datetime and timedelta resolution migration notes warn that integer conversion can produce values 1,000 times smaller after the upgrade. I found this in a pipeline that serialized timestamp arrays as nanosecond integers: after migration, the numbers were valid integers but in microseconds. Nothing raised an exception; charts and downstream joins simply used the wrong scale.
· Check integer casts. Search for .astype("int64"), .astype(int), .to_numpy(dtype="int64"), and any serialization of datetime or timedelta arrays. When the downstream contract requires nanoseconds, normalize explicitly with .as_unit("ns") before converting.
· Review parsed datetime columns. read_csv(parse_dates=...), to_datetime(), and constructors can produce a unit that reflects the input. Assert the expected dtype or normalize it at the boundary where a storage or API contract requires a specific unit.
· Specify units for integer epochs. Arithmetic and resampling usually continue to work, but bare integers are ambiguous to readers and integrations. Use pd.to_datetime(values, unit="ns"), unit="us", or the actual source unit instead of relying on an inherited assumption.
The dangerous part is that most of these cases do not raise an error. The values remain valid, but their scale changes. Search for datetime-to-integer conversions and any downstream code that assumes nanoseconds.
Why This One Fails Silently, Not Loudly
Unlike a chained assignment attempt, which can trigger a warning and leaves the original unchanged, the datetime issue often looks completely successful. pandas returns valid datetimes and valid integers. The error appears only when another component interprets those integers in the wrong unit.
dates = pd.to_datetime(["2026-01-01 00:00:00"])
print(dates.dtype)
print(dates.astype("int64")[0])
With datetime64[ns], the integer is 1767225600000000000; with datetime64[us], it is 1767225600000000. Both encode the same date, but the unit differs by a factor of 1,000. A test that checks only “is this an integer?” will pass while a downstream consumer reads the wrong scale.
If a contract requires nanoseconds, normalize before conversion: dates.as_unit("ns").astype("int64"). If the consumer supports multiple units, pass the dtype’s unit alongside the values and decode it explicitly. Do not multiply by 1,000 blindly, because some inputs may already be nanoseconds.
Introducing pd.col(): A New Way to Write Transforms
This is a new feature rather than a mandatory migration step. pandas 3.0 introduces pd.col(), a column-expression helper that can replace many lambdas. For example:
# old way
df = df.assign(full_name=lambda d: d["first_name"] + " " + d["last_name"])
# new way
from pandas import col
df = df.assign(full_name=col("first_name") + " " + col("last_name"))
Under the hood, pd.col("first_name") returns an expression that supports arithmetic, comparisons, and namespace accessors such as .str and .dt. The expression can be evaluated in supported contexts such as .assign() and .loc[]. For example:
fast = df.loc[pd.col("speed") > 105]
df = df.assign(name_upper=pd.col("name").str.upper())
The equivalent lambda form remains valid. pd.col() is syntactic sugar that removes repeated lambda d: d[...] boilerplate and makes column dependencies easier to read.
Key points about pd.col():
· It is optional: no migration requires you to replace existing lambdas. Use it where the expression is clearer than a callable.
· It works in expression-aware contexts: including .assign(), .loc[], and supported getitem or setitem operations. Check the API documentation before assuming that an arbitrary method accepts a column expression.
· It supports namespace accessors: pd.col("name").str.upper() can build a string transformation without capturing the outer DataFrame.
· It reduces accidental closure: the expression does not capture a stale outer DataFrame variable, but it does not change the underlying data semantics.
You will increasingly see pd.col() in pandas 3.x examples and code reviews. Adopt it for readability, not because the upgrade forces a wholesale refactor. Existing lambda expressions continue to work.
What Changed With Timezones and pytz
pandas 3.0 changed its default timezone representation from pytz to Python’s standard-library zoneinfo implementation. Here is what that means in practice:
· ts.tz is typically a zoneinfo.ZoneInfo. After localizing a timestamp with a named zone, code that inspects the timezone object will see ZoneInfo rather than a pytz class. Code that only converts or compares timestamps is usually unaffected.
· Parsing offsets still works. pd.to_datetime("2026-08-26 12:00+0300") preserves the offset, while named zones use the new representation.
· Error handling changed. Ambiguous or nonexistent local times now raise ValueError rather than pytz-specific exception classes. Update exception handling around daylight-saving transitions.
· pytz is no longer a required dependency. Projects that import it directly must list it in their own requirements. zoneinfo obtains time-zone data from the operating system or the tzdata package, depending on the environment.
Existing calls such as df[col].dt.tz_convert("America/New_York") still work, but code that checks for a specific pytz class will fail. Prefer the common tzinfo interface or zoneinfo.ZoneInfo only when the concrete type matters. Replace catches for pytz.AmbiguousTimeError or pytz.NonExistentTimeError with ValueError around pandas localization operations.
The pytz-to-zoneinfo Migration Path
Most code does not need a large rewrite. If your application imports and uses pytz directly, that code remains yours to maintain; pandas simply stops providing pytz objects by default. Remove unnecessary concrete-type checks, add pytz explicitly when an older dependency still requires it, and test daylight-saving boundaries. The Python requirement is already aligned because pandas 3.0 requires Python 3.11 or later.
Auditing Your Own Codebase for These Breaking Changes
Use the checklist below to find affected code systematically, starting with the patterns most likely to change data.
A Practical Search-and-Replace Checklist
· Chained indexing and assignment: search for two indexing operations on the left side, such as df[mask]["col"] = value, df.loc[mask]["col"] = value, or a Series extracted and then mutated. Rewrite the intended parent update as one .loc[...] = ... or .iloc[...] = ... operation.
· Warning suppression and defensive copies: search for SettingWithCopyWarning, warning filters, and .copy() calls added only to silence that warning. Keep copies that express real ownership, and remove ritual copies that no longer serve a purpose.
· String dtype checks: replace dtype == "object" with is_string_dtype where the intent is to detect text. Keep explicit object checks only when generic Python-object storage is genuinely required.
· Constructor dtypes: review dtype="object" and dtype="str" in Series, DataFrame, and I/O code. Confirm that each column is meant to be heterogeneous or text-only.
· String conversions: audit .astype(str), .astype("str"), and .astype("object"). Add tests for missing values and incompatible assignments.
· Datetime and timedelta integers: search for .astype(int), .astype("int64"), .view("int64"), .to_numpy(dtype=...), integer epoch serialization, and hardcoded scale factors. Normalize with .as_unit(...) or pass an explicit unit at the boundary.
· Timezone assumptions: search for pytz, concrete timezone type checks, and catches for pytz exception classes. Test ambiguous and nonexistent local times with zoneinfo behavior.
· Extension dtype handling: review NumPy type predicates and custom schema code that receives pandas dtypes. Use pandas type predicates when extension dtypes are possible.
· Helper functions and loops: inspect functions that receive a slice or Series and mutate it internally. A helper may now update only its local object even though the call site expected the parent DataFrame to change.
· Third-party dependencies: run integration tests for libraries that inspect pandas dtypes, accept timezone objects, or exchange Arrow data. Upgrade adapters before blaming pandas for a downstream incompatibility.
Some failures are loud, such as assigning a number into a str column. Others are silent in the business sense: datetime integers keep their type but change scale, and a stored subset can mutate without affecting its parent. Run a comprehensive suite under pandas 3.0, compare full outputs, and add assertions around dtype, unit, and row-level effects.
Migrating a Real Project Through the Upgrade
I ran this gauntlet on an actual data analytics pipeline. Here is a step-by-step summary of how I would recommend doing it in practice:
· Step 1: Prepare your environment. Make sure you have a test environment where you can install Python 3.11+ and pandas 3.0 without breaking production. Ideally, clone your repo and create a branch or new Docker environment.
· Step 2: Upgrade Python if needed. Pandas 3.0 requires Python 3.11+, so update your interpreter or virtualenv first. Fix any syntax or dependency issues from Python upgrade.
· Step 3: Install a current pandas 3.0 patch. Pin pandas==3.0.5 for a reproducible migration baseline, or choose a later vetted 3.0.x patch when available. Record the exact build in your lockfile and deployment image.
· Step 4: Run the existing test suite. Treat exceptions, warnings, snapshot differences, and unchanged data as migration signals. A green suite is not enough if it never asserts the transformed values.
· Step 5: Fix behavioral failures first. Rewrite chained assignments, repair dtype assumptions, and make datetime units explicit. Keep each change small enough to review against a known input and output.
· Step 6: Search for risky patterns. Grep for SettingWithCopyWarning, chained brackets, .astype("int64"), dtype == "object", .astype("str"), pytz, and warning filters. Apply the audit checklist consistently across Python modules and notebooks.
· Step 7: Validate data contracts. Spot-check timestamp scales, string missing values, column dtypes, and transformations that modify filtered rows. Compare representative output files with the pre-upgrade baseline.
· Step 8: Test end to end. Run full pipelines, notebooks, model feature generation, exports, and reporting jobs. Investigate every unexplained difference rather than assuming it is harmless.
· Step 9: Adopt new syntax selectively. Use pd.col() where it improves readability, but keep the migration focused on behavior and correctness. Syntax cleanup should not obscure functional fixes.
· Step 10: Deploy with a controlled version range. Pin the tested patch or a narrow compatible range, rebuild every environment, and monitor data-quality checks after deployment. Do not let test and production environments drift between pandas 2.x and 3.x.
Notebook choice does not change pandas semantics. The Marimo vs. Jupyter: Reactive Notebooks Compared article compares reactive and conventional notebook environments, but pandas 3.0 behaves the same in either one. Restart the Python kernel after upgrading so the session does not retain objects or imports from the previous environment.
When behavior looks like a regression rather than an intentional change, check the official pandas 3.0.5 release notes and issue tracker. Version 3.0.5 repaired wheels from 3.0.4 that had been built against an incompatible NumPy version and could crash on affected Python 3.14 and datetime code paths. Patch-level fixes are another reason to pin and record the exact build you tested.
Common Mistakes Teams Make During This Migration
Even with a checklist, migrations can get rocky. Some frequent mistakes I’ve seen:
· One-and-done deployment: Upgrading in production with minimal testing because “it’s just a patch” can backfire. 3.0 is a major release with major behavior changes. Always test thoroughly.
· Ignoring warnings in 2.x: If you had warnings about chained assignment or dtype, suppressing them in 2.x means you were unprepared. Instead of silencing warnings, take them as signposts to fix code before upgrading.
· Assuming nothing changed: Some teams mistakenly believe that because “pandas should be backwards compatible,” they can skip reading the release notes. That’s not true for 3.0. Read the “What’s New” and follow the guide above.
· Forgetting to check data correctness: In some cases, test suites passed but the business output was subtly wrong (e.g., messed up aggregate). Always do a sanity-check on real data flows.
· Mis-scoped fixes: Sometimes devs fix one place where a warning showed up, but there are many similar places. Grepping for patterns (e.g. df[...] [ ... ]) globally is better than fixing only the examples you’ve noticed.
· Neglecting dependencies: pandas 3.0 requires Python 3.11 or later and a compatible NumPy stack. Verify C extensions, Arrow integrations, and downstream libraries under the same interpreter and lockfile.
· Mismatched environments: Running pandas 3.0 in one environment (test) and 2.x in another (prod) inadvertently can cause “it works on my machine” confusion. Containerize or venv everything to keep versions consistent.
· Confusing migration with tool choice: breaking changes can prompt a reflexive “switch to Polars” discussion. Library selection is a separate architecture decision. Teams that remain on pandas still need to migrate their existing code deliberately.
How This Differs From the Pandas vs. Polars Decision
This migration is distinct from the “Pandas vs. Polars” debate. The comparison article focuses on tool choice, performance, and syntax, while this article focuses on behavior changes inside a library you already use. pandas 3.0 is not an argument for or against Polars; it is a version migration problem for pandas codebases.
· Different scope: Pandas vs. Polars: A Performance Comparison helps readers compare libraries. This guide assumes pandas remains part of the stack and explains how to upgrade existing code safely.
· Different audience: a team evaluating Polars is making an architecture and skills decision. A team upgrading pandas needs to repair .loc usage, dtype assumptions, datetime units, and timezone handling.
· Different content: the comparison does not cover pandas 3.0’s Copy-on-Write-only model, default string dtype, datetime resolution, or pd.col() migration implications. Reading a benchmark does not replace a version-specific audit.
· Different outcome: a tool comparison may lead to adoption, coexistence, or rejection of another library. A pandas 3.0 migration should end with tested behavior, explicit data contracts, and a reproducible environment.
Treat these as separate decisions. A team may explore Polars while still maintaining pandas pipelines, and those pipelines must be migrated correctly.
Data Scientist Skills and Salaries in 2026
Pandas fluency remains a core data-science skill, but salary figures need careful attribution. The Refonte Learning Data Science & AI Program page markets a “$105,000+ starting salary” and roughly “21,000+ jobs annually” for data scientists. Those numbers are the program’s own marketing copy, not independently verified labor statistics.
Independent salary sites use different methodologies and should be read as directional snapshots rather than directly comparable measures:
Source | Average Data Scientist Salary | Notes |
Refonte Learning (marketing) | $105,000+ per year | Program-page claim: “starting salary” |
$150,000 per year | Average displayed in the research snapshot used for this article | |
$122,738 per year | Average in the August 2026 snapshot; 25th to 75th percentile: $98,000 to $136,000 |
Glassdoor and ZipRecruiter estimates vary by sample, location, seniority, and job-title definition, so they should not be used to validate a single guaranteed salary. The Data Scientist Salary guide discusses compensation as a separate career topic. For this migration, the practical takeaway is simpler: employers pay for reliable data work, and reliability includes knowing when a library upgrade changes semantics.
The program page lists Data Scientist, AI Engineer, ML Engineer, Data Analyst, and Prompt Engineer as potential career outcomes. Keeping current with pandas 3.0 is one example of the maintenance discipline those roles require.
Building This Skill Set: The Refonte Learning Data Science & AI Program
The Refonte Learning Data Science & AI Program combines part-time training with mentor-guided practice in core data and AI skills.
· Duration: 3 months at 12 to 14 hours per week.
· Curriculum highlights: AI and Generative AI, Prompt Engineering, Python Data Science, Statistical Modelling, Deep Learning, EDA and Data Visualization, ML and Predictive Modelling, and Model Optimization.
· Tools named on the program page: Python, Jupyter Notebook, Pandas, NumPy, Matplotlib, scikit-learn, and TensorFlow. These tools support data exploration, modeling, visualization, and machine learning workflows.
· Mentor: Dr. John Anderson, Senior AI Engineer, is presented with 17 years of experience in quantitative modeling and scalable AI systems.
· Career outcomes listed by the program: Data Scientist, AI Engineer, ML Engineer, Data Analyst, and Prompt Engineer. These are stated outcomes on the program page, not employment guarantees.
Upgrading to pandas 3.0 is part of working responsibly with a changing data stack. The Refonte Learning Data Science & AI Program names Pandas as a core tool in its Python Data Science curriculum and can help learners build the foundational fluency this migration guidance assumes. The live page does not specify pandas 3.0, Copy-on-Write, or version-specific migration coverage, so treat this article as an advanced update layered on top of that foundation.