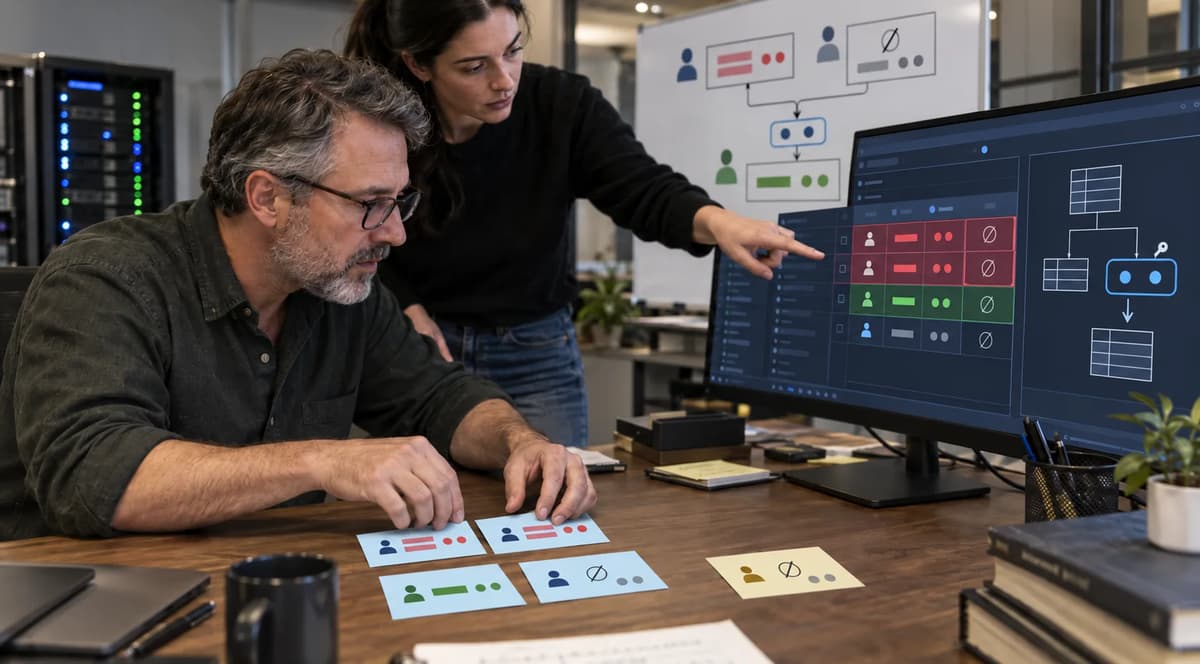
In the authored baseline, tenant 7 has two configuration rows whose scope is null. Both rows are called the tenant's default configuration by the application, yet the table also has UNIQUE (tenant_id, scope). That state is not evidence that PostgreSQL ignored the constraint. Under PostgreSQL's default unique-key null treatment, the two null-bearing composite keys are not duplicates for enforcement purposes, even though the product policy treats them as the same default identity.
The repair therefore starts with policy, not syntax. The intended uniqueness rule allows at most one default for each non-null tenant, plus at most one row for any particular named scope within that tenant. This playbook freezes the original rows, demonstrates the mismatch, attempts the stronger rule before editing data, applies one explicitly authorized correction, installs UNIQUE NULLS NOT DISTINCT, and then tests inserts, an update, catalog state, and the complete final ledger.
The protocol targets a fresh disposable PostgreSQL 18 session and ends in ROLLBACK. The supplied SQL was statically reviewed but was not executed by the commissioning editor because no PostgreSQL server or client was available. Every case result in this article is therefore an expectation grounded in the PostgreSQL 18 documentation, not observed output. A real run must record the actual server patch, client version, logs, digest, and exit status before any bounded acceptance decision.
Define the default configuration key before changing SQL
A nullable key component needs an explicit meaning. In this fixture, tenant_id is NOT NULL, while a null scope deliberately identifies the default configuration for that tenant. It is not an unspecified identity. The policy permits at most one such default; uniqueness alone does not require every tenant to have a default row. Any requirement to create or retain a default needs separate application or data-policy checks.
The business key is the pair (tenant_id, scope). The surrogate id remains the stable row identifier used to preserve membership and payloads during the repair, but it does not answer whether two configurations represent the same business object. Likewise, scope alone is not the key. Tenant 7 may have a named us scope while tenant 8 also has us; those rows are independent because their tenant components differ.
Write the rule as an equivalence relation before touching the constraint: two rows conflict when their tenants are equal and their scopes are either the same non-null value or both null. That wording protects both halves of the policy. It prevents a second default inside one tenant without turning every tenant's null into a single global slot. It also leaves different named scopes such as us, eu, and apac legitimate within the same tenant.
That definition also identifies the repair boundary. The change concerns the constraint's treatment of one nullable key component; it does not authorize changes to payload contents, tenant ownership, surrogate IDs, or the meaning of named scopes. Keeping those non-goals explicit prevents a narrow integrity correction from becoming an unreviewed data redesign.
This is a schema-design decision, not a generic instruction to collapse nulls. Reviewers who need the wider context can use database design and DBA foundations as a supporting learning resource, while keeping this article focused on the nullable composite key itself.
Read the null policy that UNIQUE actually enforces
The PostgreSQL 18 constraints documentation defines a multicolumn unique constraint over the combination of its listed columns. It also states that, by default, two null values are not considered equal for this uniqueness comparison. Consequently, the rows (7, NULL) and (7, NULL) can coexist under UNIQUE (tenant_id, scope): the tenant values match, but the nullable component is treated as distinct for the constraint.
The unique-index documentation exposes the enforcing mechanism more directly. PostgreSQL creates a unique B-tree index for a unique constraint, and a multicolumn unique index rejects a pair only when all indexed components compare as equal under that index's null policy. The non-null declaration on tenant_id does not somehow make scope non-null. One nullable component is enough for the default null-distinct behavior to admit both default rows.
This is the practical issue behind the phrase PostgreSQL UNIQUE NULL values: a nullable composite unique constraint can be syntactically valid while its null equivalence differs from the product's identity rule. Here, PostgreSQL NULLS NOT DISTINCT is the bounded mechanism that aligns the declared tenant scope unique key with one null scope per tenant.
A primary key on id proves only that rows 101 and 102 are distinct stored rows. It does not prove that they are distinct default configurations under the application's declared key. This distinction is central to diagnosis: the database can enforce every declared constraint correctly while the declaration still fails to encode the business identity.
Keep constraint equivalence separate from general SQL equality
NULLS NOT DISTINCT changes the null treatment of this unique key. It does not redefine SQL equality throughout the session. The PostgreSQL 18 comparison-predicate reference explains that ordinary comparison operators yield null when an input is null and that IS NOT DISTINCT FROM provides a null-aware comparison when both-null values must be treated alike. That predicate is appropriate for an independent audit oracle; scope = NULL is not.
The composite boundary remains intact. With UNIQUE NULLS NOT DISTINCT (tenant_id, scope), (7, NULL) conflicts with another (7, NULL), but it does not conflict with (8, NULL) because the tenant values differ. The clause therefore enforces at most one default per tenant, not a table-wide limit of one null scope. It also leaves unrelated CHECK semantics and other expressions unchanged.
Freeze a four-row baseline and a nine-case manifest
The qualification begins with four authored rows. Two are competing defaults for tenant 7, one is tenant 7's named us configuration, and one is tenant 8's default. The IDs and payloads are intentionally simple because they serve as an independent identity ledger during repair.
ID | tenant_id | scope | payload |
101 | 7 | NULL (default) | A |
102 | 7 | NULL (default) | B |
103 | 7 | us | C |
201 | 8 | NULL (default) | D |
lab_original copies this baseline before any correction. A fresh disposable database and a fresh psql session are mandatory because temporary names, search paths, existing objects, and client startup files can otherwise contaminate the evidence. The run must record psql --version, plus the server's full version() string and server_version_num returned by the driver. The phrase PostgreSQL 18 is a protocol baseline, not a substitute for those actual values.
The nine cases must be declared before execution so that a surprising outcome cannot be reclassified after the fact.
Case | Expected evidence |
P1 | The default constraint admits IDs 101 and 102 as two tenant 7 defaults; all four baseline rows remain. |
P2 | A fresh-ID duplicate of tenant 7 / us is rejected by lab_default_unique with SQLSTATE 23505. |
P3 | Adding the stronger constraint over unchanged data is rejected; no failed constraint survives. |
P4 | The fixture-authorized correction changes only row 102 scope to eu and preserves identity and payload. |
P5 | The strict constraint is installed and its exact index is unique, valid, and nulls-not-distinct. |
P6 | A second tenant 7 default is rejected by lab_strict_unique. |
P7 | A second tenant 7 / us row is rejected by lab_strict_unique. |
P8 | Tenant 9 / default and tenant 7 / apac are accepted. |
P9 | Updating row 103 into tenant 7 default is rejected, and the complete six-row ledger matches. |
Identify a collision without choosing its winner
The grouped audit is expected to report tenant 7, null scope, row IDs [101,102], and count 2. Grouping is useful here because both null scopes belong to one group for the same tenant, matching the deliberately chosen default policy. This null-aware uniqueness audit does not select a winner, infer recency from the ID, or authorize deletion. It identifies the stored membership that conflicts with the stated policy.
Later, P4 assigns row 102 to eu because that fact is authored into this synthetic fixture. In real data, two competing defaults may represent different customer choices, stale copies, or an undocumented merge. When no product or configuration owner can authorize a resolution, the correct decision is HOLD_DATA_DECISION, not an improvised rename designed only to make DDL pass.
Run the complete transactional qualification protocol
Save the complete SQL below as postgresql_nullable_unique_fixture.sql, using UTF-8, LF line endings, and a final newline. Its SHA-256 is f7f2ffab238a1821d1667553e7f02e2e2fb3e2017b3858ae59761a0a4b42d62e, matching the supplied driver digest. Preserve indentation and blank lines when copying from Word. A changed comment, line ending, or whitespace sequence requires a new digest and review; matching a digest does not prove execution.
Configure the disposable target through reviewed connection settings, such as PGHOST, PGPORT, PGUSER, and PGDATABASE. Save this capture block as a shell script and run it in a fresh evidence directory containing the SQL file. The documented psql startup and error-handling options keep startup files out and stop on uncaught errors. The block checks the digest and captures stdout, stderr, and process status without a pipeline.
#!/bin/sh
stem=postgresql_nullable_unique_fixture
expected=f7f2ffab238a1821d1667553e7f02e2e2fb3e2017b3858ae59761a0a4b42d62e
psql --version >"$stem.client-version.txt" \
  2>"$stem.preflight.stderr.txt" || exit "$?"
sha256sum "$stem.sql" >"$stem.sha256.txt" \
  2>>"$stem.preflight.stderr.txt" || exit "$?"
printf '%s  %s\n' "$expected" "$stem.sql" \
  >"$stem.expected.sha256" || exit "$?"
sha256sum --check "$stem.expected.sha256" >"$stem.digest-check.txt" \
  2>>"$stem.preflight.stderr.txt" || exit "$?"
if psql -X -v ON_ERROR_STOP=1 -f postgresql_nullable_unique_fixture.sql \
  >"$stem.stdout.txt" 2>"$stem.stderr.txt"; then
  status=0
else
  status=$?
fi
printf '%s\n' "$status" >"$stem.exit.txt" || exit 1
exit "$status"
The first SQL query records the server build and numeric version. Expected uniqueness failures become ledger entries; unexpected error classes escape. The completion text precedes ROLLBACK, so require the ending rollback acknowledgement and a zero process exit as well. A completion line alone is neither a full execution record nor evidence that the commissioning editor ran the protocol.
Treat environment qualification as a gate. The target is PostgreSQL 18 with a compatible psql client, and actual versions must be recorded. The SQL reports server_version_num but does not assert the major version: reviewers must confirm 18 before accepting results. An unsupported version, rejected syntax, unsafe connection target, or incomplete environment record requires HOLD_EVIDENCE, not a partial pass.
Keep the SQL file, its calculated digest, the capture script and exact invocation, client-version record, digest-check result, stdout, stderr, and exit-status file together. Retain only connection details that are safe to disclose. The digest identifies the proposed SQL source; tying that source to a particular output also requires a documented collection process. A file hash is not proof of when or where commands ran.
Caught negative controls are reported through lab_results, not necessarily as client errors on stderr. Normal protocol completion should return zero, but zero alone is insufficient: require all nine case IDs, the catalog checks, and the literal final-row match. An uncaught uniqueness error, timeout, permission denial, syntax error, or evidence-file failure must remain visible and lead to HOLD_EVIDENCE.
Complete proposed PostgreSQL 18 driver (not executed by the commissioning editor):
-- P1: the default UNIQUE rule admitted two defaults for tenant 7.
SELECT pg_temp.check_lab(
 (SELECT array_agg(id ORDER BY id) FROM lab_config WHERE tenant_id = 7 AND scope IS NULL) = ARRAY[101,102], 'P1: wrong collision');
SELECT pg_temp.check_lab(
 (SELECT count(*) FROM lab_config) = 4, 'P1: lost baseline row');
INSERT INTO lab_results VALUES ('P1', 'two defaults admitted', '{"ids":[101,102]}');
SELECT tenant_id, scope, array_agg(id ORDER BY id) AS row_ids, count(*)
FROM lab_config GROUP BY tenant_id, scope HAVING count(*) > 1;
-- P2: a fresh ID prevents a primary-key failure from impersonating the control.
SELECT pg_temp.reject_unique('P2',
$q$INSERT INTO lab_config VALUES (104,7,'us','duplicate')$q$,
'lab_default_unique');-- P3: building the stricter constraint must reject the existing collision.
SELECT pg_temp.reject_unique('P3',
$q$ALTER TABLE lab_config ADD CONSTRAINT lab_strict_unique UNIQUE NULLS NOT DISTINCT (tenant_id, scope)$q$, NULL);
SELECT pg_temp.check_lab(NOT EXISTS (
SELECT FROM pg_constraint WHERE conrelid = 'lab_config'::regclass
AND conname = 'lab_strict_unique'), 'P3: failed constraint survived');
SELECT pg_temp.check_lab((SELECT count(*) FROM lab_config) = 4, 'P3: failed DDL changed the rows');-- P4: fixture-only business decision: row 102 belongs to scope eu, not default.
UPDATE lab_config SET scope = 'eu' WHERE id = 102;
SELECT pg_temp.check_lab((SELECT scope FROM lab_config WHERE id = 102) = 'eu', 'P4: approved correction missing');
SELECT pg_temp.check_lab(NOT EXISTS (
SELECT id, tenant_id, payload FROM lab_original
EXCEPT SELECT id, tenant_id, payload FROM lab_config), 'P4: source identity lost');
SELECT pg_temp.check_lab((SELECT count(*) FROM lab_config) = 4, 'P4: unexpected membership');
INSERT INTO lab_results VALUES ('P4', 'approved scope correction', '{"id":102,"scope":"eu"}');-- P5: install the reviewed rule before removing the weaker duplicate index.
ALTER TABLE lab_config ADD CONSTRAINT lab_strict_unique UNIQUE NULLS NOT DISTINCT (tenant_id, scope);
ALTER TABLE lab_config DROP CONSTRAINT lab_default_unique;
SELECT pg_temp.check_lab((
SELECT i.indnullsnotdistinct AND i.indisunique AND i.indisvalid
FROM pg_constraint c JOIN pg_index i ON i.indexrelid = c.conindid
WHERE c.conrelid = 'lab_config'::regclass AND c.conname = 'lab_strict_unique'
), 'P5: catalog did not confirm the reviewed index');
INSERT INTO lab_results VALUES ('P5', 'stricter constraint installed', '{"nulls_not_distinct"}');
SELECT pg_get_constraintdef(oid) AS definition FROM pg_constraint
WHERE conrelid = 'lab_config'::regclass AND conname = 'lab_strict_unique';SELECT pg_temp.reject_unique('P6',
$q$INSERT INTO lab_config VALUES (104,7,NULL,'duplicate default')$q$,
'lab_strict_unique');SELECT pg_temp.reject_unique('P7',
$q$INSERT INTO lab_config VALUES (105,7,'us','duplicate named')$q$,
'lab_strict_unique');-- P8: another tenant's default and another scope remain authorized.
INSERT INTO lab_config VALUES (301,9,NULL,'E'), (104,7,'apac','F');
SELECT pg_temp.check_lab(
(SELECT array_agg(tenant_id ORDER BY tenant_id) FROM lab_config WHERE scope IS NULL) = ARRAY[7,8,9],
'P8: null was restricted globally instead of per tenant');
INSERT INTO lab_results VALUES ('P8', 'new tenant and scope admitted', '{"ids":[104,301]}');-- P9: the constraint must also reject an UPDATE into an occupied default slot.
SELECT pg_temp.reject_unique('P9',
$q$UPDATE lab_config SET scope = NULL WHERE id = 103$q$, 'lab_strict_unique');
SELECT pg_temp.check_lab((
SELECT jsonb_agg(jsonb_build_array(id,tenant_id,scope,payload) ORDER BY id)
FROM lab_config
) = '[[101,7,null,"A"],[102,7,"eu","B"],[103,7,"us","C"],[104,7,"apac","F"],[201,8,null,"D"],[301,9,null,"E"]]'::jsonb,
'P9: final membership, scope or payload mismatch');
SELECT pg_temp.check_lab((SELECT array_agg(id ORDER BY id) FROM lab_results)
= ARRAY['P1','P2','P3','P4','P5','P6','P7','P8','P9'], 'Incomplete case ledger');
SELECT FROM lab_results ORDER BY id;
SELECT FROM lab_config ORDER BY id;
SELECT 'EXPECTED_PROTOCOL_COMPLETE_IF_ALL_CHECKS_PASSED' AS protocol_result;
ROLLBACK;
-- The transaction intentionally persists neither fixture data nor constraints.Show the default rule accepting and rejecting different keys
P1 and P2 are a matched diagnostic pair. P1 is designed to confirm that lab_default_unique admits IDs 101 and 102 even though both represent the application key (7, NULL). It also checks that four baseline rows remain. That expected outcome is consistent with the documented null-distinct rule, but by itself could be misread as evidence that uniqueness is inactive.
P2 removes that ambiguity. It uses fresh ID 104 and attempts another tenant 7 / us row. Because row 103 already owns that complete non-null pair, the expected PostgreSQL duplicate key SQLSTATE 23505 must come from lab_default_unique. PostgreSQL's error-code reference maps that code to unique_violation. Reusing ID 103 would also fail, but a primary-key failure would not prove anything about the tenant/scope constraint.
Read together, the expected cases demonstrate an active constraint with a narrower equivalence rule than the product expects. Named duplicates are rejected, while two null scopes for the same tenant are admitted. That is the precise mismatch supporting REPAIR_RULE; it is not a reason to describe the original constraint as broken or disabled.
Keep the four-row baseline visible while interpreting both results. Removing either tenant 7 default before P1 would erase the mismatch. Omitting the tenant 8 default would remove the control showing that another tenant's pre-existing default survives the correction. Every baseline row has an evidentiary purpose; the later acceptance inserts do not replace preservation checks on original rows.
An exception handler must not conceal the wrong failure
A generic 'statement failed' message is insufficient. Permissions, syntax, connection loss, timeout, primary-key reuse, and the intended business-key violation can all prevent success. pg_temp.reject_unique catches only unique_violation. Its stacked error diagnostics record the reported constraint and check the expected name for P2, P6, P7, and P9. Other errors propagate; uncaught script errors stop psql with ON_ERROR_STOP enabled.
P3 deliberately omits the constraint-name assertion for the creation attempt. It records whatever constraint field the server reports, while still requiring unique_violation, or SQLSTATE 23505. The test does not depend on localized message text or a presumed creation-path name. In this fresh fixture, its statement is specifically the attempted stronger constraint over the unchanged baseline.
Attempt the stronger constraint before editing the collision
P3 runs ALTER TABLE ... ADD CONSTRAINT ... UNIQUE NULLS NOT DISTINCT while IDs 101 and 102 are still tenant 7 defaults. The expected uniqueness violation would show that the stronger rule recognizes the existing collision before a corrective edit can hide it. The PostgreSQL 18 ALTER TABLE reference explains existing-row validation and limits NOT VALID to foreign-key, CHECK, and not-null constraints, not UNIQUE.
The PL/pgSQL error-handling rules give the exception block a controlled rollback boundary. A caught failure rolls back database changes made inside that block while allowing execution after it. P3 then checks that lab_strict_unique is absent from pg_constraint and the row count remains four. Unexpected catalog state, an unexpected exception, or a wrong count requires HOLD_EVIDENCE.
The guide to why a CHECK rollout has a different contract provides a useful contrast, not a template to copy. A CHECK can be added NOT VALID and validated later under its documented rules. This unique-key repair cannot invent UNIQUE NOT VALID to postpone the collision decision, and the disposable lab makes no claim about lock duration or a production rollout sequence.
Attempting the strict definition before P4 is also an evidence-preservation choice. If the protocol corrected row 102 first and then added the constraint, the final DDL could succeed without proving that the original state was incompatible. P3 captures that causal link: the unchanged four-row baseline is rejected specifically when the null equivalence becomes stricter.
Read the checks in sequence rather than treating a count as identity proof. P3 immediately checks catalog absence and cardinality; it does not compare all four rows field by field. P4 subsequently checks the original ID, tenant, and payload triples, while P9 checks the complete approved state. All of those checks are needed before row preservation supports acceptance.
Apply only the explicitly authorized scope correction
P4 changes row 102 from null scope to eu. That edit is acceptable only because the fixture explicitly states that row 102 belongs to the eu scope. The protocol does not derive the answer from payload B, from the larger ID, from insertion order, or from a database timestamp. In a real review, evidence outside this lab must authorize which identity is correct.
P4 compares lab_original with the current table using (id, tenant_id, payload). With the primary key and four-row count intact, this preserves the four original triples. A separate assertion requires row 102 to have scope eu. However, these P4 assertions do not themselves check the other rows' scopes, because scope is omitted from the source comparison. That remaining value check belongs to P9's literal final ledger.
Do not generalize this repair into a recommendation to rename any duplicate default. If both rows are genuine defaults, if one belongs to an unknown scope, or if the application has already referenced both as default, the database engineer lacks authority to choose. Keep the collision visible and return HOLD_DATA_DECISION until the responsible owner supplies a documented resolution.
An authorized correction should name the affected row, the old identity, the new identity, the evidence for the change, and the approver. That record belongs beside the migration evidence. A bare SQL statement may show what changed, but it cannot show why the organization was entitled to change it.
Preserve row identity while resolving a policy mismatch
A count of four could survive unacceptable substitutions: a different ID, a changed payload, or a reassigned tenant. The source comparison catches those changes to the original triples. It does not prove that every scope is unchanged except on 102, nor does a final-state comparison establish physical row history. The narrowly targeted update and the later full-state oracle must be reviewed alongside this preservation check.
The related discussion of application identity versus database comparison rules addresses a different boundary, where Unicode normalization and collation can disagree with an application's name policy. This PostgreSQL fixture imports none of that remediation. Its identity rule is narrower: null has an intentional default meaning, and the approved correction is an authored fixture fact rather than text normalization.
Install the reviewed key and inspect its actual index
After authorized reconciliation, P5 adds lab_strict_unique with UNIQUE NULLS NOT DISTINCT (tenant_id, scope) before dropping lab_default_unique. Within this fixture, that order retains the weaker tenant/scope rule until the stronger one is installed. Dropping a constraint also drops its underlying index, as the ALTER TABLE drop rules explain; the strict constraint's own index remains. This ordering is not an online-migration qualification.
A name printed by psql is insufficient. The query resolves the temporary relation with 'lab_config'::regclass, selects its lab_strict_unique constraint, follows the supporting-index OID in pg_constraint.conindid, and inspects the PostgreSQL 18 pg_index catalog. The asserted flags are indnullsnotdistinct, indisunique, and indisvalid, all true. A missing result fails check_lab rather than silently passing as null.
The pg_get_constraintdef function reconstructs the constraint definition; it does not reproduce the original SQL text. Inspect the printed result for UNIQUE NULLS NOT DISTINCT (tenant_id, scope): the three-flag assertion alone does not verify the key-column list. The CREATE INDEX syntax reference independently documents the index-level null-policy options. Definition review and flag assertions complement the write probes rather than replacing them.
Following conindid avoids two common catalog mistakes. First, an index name is not a globally reliable identity when temporary schemas or unrelated relations can contain similarly named objects. Second, inspecting every unique index on the table can accidentally accept the primary key or the weaker constraint's index. The join starts from the reviewed constraint on the exact relation and reaches only its enforcing index.
The flags answer different questions: indisunique identifies a unique index, indnullsnotdistinct records its null policy, and indisvalid records validity for query use. PostgreSQL warns that an invalid unique index cannot be assumed to have its uniqueness property. Here, the successful normal build, exact definition, flags, and expected writes together support a bounded claim, not a general index-health or deployment guarantee.
Test rejected duplicates and permitted independent scopes
P6 retries the original policy violation with a fresh row: tenant 7, null scope, payload duplicate default. The pair is expected to conflict with ID 101 and raise SQLSTATE 23505 from lab_strict_unique. P7 repeats the method for (7, 'us'), already owned by ID 103. Those expected rejections exercise both default and named identities under the reviewed composite rule.
P8 supplies the equally important acceptance controls. Tenant 9 receives its own null-scoped default, and tenant 7 receives a new apac scope. Both inserts must succeed. The null-scope tenant array must then be exactly [7,8,9], demonstrating that null was constrained per tenant rather than globally.
These acceptance controls distinguish the intended key from an over-restrictive UNIQUE NULLS NOT DISTINCT (scope), which would allow only one null-scoped row across the table and make named scopes globally unique. Plain UNIQUE (scope) would still allow multiple nulls by default, so it would not repair this default collision. Making scope NOT NULL would instead remove the chosen default representation. Each alternative encodes a different rule.
Negative controls alone can reward over-restriction: a rule that rejects every insert would appear effective if the test asks only for failures. P8 proves retained capability. Qualification requires both sides of the boundary, including rows that must remain legal after repair.
The IDs make the probes independently diagnosable. P6 uses 104, but its caught rejection leaves that ID available for P8's apac insert. P7 uses 105 and is also expected to leave no row. If a rejection probe unexpectedly succeeds, check_lab(caught, ...) raises an uncaught exception immediately: the driver stops rather than proceeding to collect an apparently complete ledger.
The named-scope tests also prove symmetry. The constraint does not reserve special treatment only for null: us remains unique within tenant 7, while apac is accepted because it is a distinct scope. The repaired rule is one composite identity policy with an explicit null interpretation, not two unrelated enforcement mechanisms.
Check updates and the final row ledger
P9 tests a write path that insert-only checks miss. Row 103 currently represents tenant 7 / us. The protocol attempts to set its scope to null, which would move it into the default slot already occupied by row 101. The strict constraint must raise SQLSTATE 23505 from lab_strict_unique, and the statement-level rollback must leave row 103 as us with payload C.
The final JSON comparison checks all six rows and every material value: 101/7/default/A, 102/7/eu/B, 103/7/us/C, 104/7/apac/F, 201/8/default/D, and 301/9/default/E. A separate assertion checks the complete P1-through-P9 result ledger. The literal oracle makes unexpected substitutions visible instead of accepting whatever rows happen to print at the end.
The related guide on preserving identity when reviewing database writes studies ambiguous UPDATE FROM source matches, which are outside this fixture. Its relevant lesson is the need to prove what a write targeted and preserved. Here, the update source is simple; the risk is moving an existing row into an occupied nullable business-key slot.
Do not let a row count substitute for the approved state
Six rows are expected after P8, but six is not the acceptance oracle. A six-row table could still contain the wrong tenant, a changed payload, an unauthorized null, a missing original ID replaced by a new one, or a duplicate named scope. The ordered JSON ledger fixes the exact approved state and detects each of those outcomes.
Reconciliation should be read as an inventory equation: the four baseline identities remain, row 102 has only the authorized scope change, and two intentional inserts add IDs 104 and 301. P9 adds no row and changes no row because its update is rejected. Any other membership, value, or ledger entry leads to HOLD_EVIDENCE, even when the number of exceptions or rows looks plausible.
The explicit ORDER BY id inside JSON aggregation makes the serialized row sequence deterministic. PostgreSQL's aggregate-ordering documentation explains that order-sensitive aggregates otherwise have unspecified input order. The same correct rows could then produce a different array order and a mismatch. Keeping order explicit allows reviewers to investigate actual value differences rather than dismissing every discrepancy as formatting.
Separate rollback of the laboratory from production recovery
The final ROLLBACK is an intentional cleanup boundary: PostgreSQL discards changes made by the current transaction. Here, the temporary tables, functions in pg_temp, rows, and constraints are all created inside that transaction, so those authored objects and data are expected not to persist. This is not a claim that rollback generally drops temporary tables created before a transaction began.
The shell captures output while psql runs and records its exit status after the process ends. Those external files are not undone by SQL rollback. Retain client version, digest, logs, and process status together. The completion text appears before the final rollback command; require its acknowledgement too. A missing completion line, nonzero exit, absent acknowledgement, or truncated log prevents acceptance.
This laboratory boundary is not production recovery. A deployed change may coexist with separately committed application writes or external effects such as delivered job messages and cache updates. Rolling back this isolated SQL transaction does not demonstrate recovery of those effects. Dropping the stricter constraint after a committed change would remove enforcement, but would not automatically restore a corrected scope or reverse its authorization.
The lab answers a narrower question: given the authored baseline and authorized correction, does the proposed PostgreSQL 18 constraint enforce the intended tenant-scoped identity and preserve the approved rows inside one transaction? Recovery planning for a deployed change requires its own inventory and authorization.
Temporary objects reduce cleanup risk, but they do not make an unsafe connection harmless. The operator must still confirm the target database before running the file. BEGIN and ROLLBACK protect transactional database changes; they do not protect against connecting with excessive privileges, exposing sensitive connection strings in logs, or overwriting evidence files in the shell.
For a production change, document the forward data decision and any proposed reverse action separately. Re-adding the old constraint would restore weaker null treatment, not decide whether reversing a scope correction is legitimate. Retained original state can help design a reversal, but the data owner must still authorize it. Preserve that reasoning rather than inferring a recovery plan from rollback syntax alone.
Make the accept, repair or hold decision explicit
A database error can be successful diagnostic evidence, while a green script can still be operationally unacceptable if the wrong policy was tested. Use a decision matrix that separates the schema judgment, the data decision, and the evidence quality.
Decision | Trigger | Required interpretation |
REPAIR_RULE | The declared key admits two rows that the approved tenant/default policy treats as one identity. | Replace the weaker nullable-key rule with the reviewed composite NULLS NOT DISTINCT rule, subject to authorized data resolution. |
HOLD_DATA_DECISION | Competing default rows are proven, but no owner can authorize which row is default or which alternative scope is correct. | Do not delete, rename, or merge data merely to satisfy the new constraint. Keep the collision visible. |
ACCEPT_BOUNDED | Recorded versions, digest, full logs, exit status, P1-P9 ledger, final rows, reviewed constraint definition, and index flags all match the bounded protocol. | Accept only the demonstrated fixture behavior and defined input domain, not an online-production or authorization claim. |
HOLD_EVIDENCE | A result is unexpected, PostgreSQL 18 behavior is unsupported in the actual environment, or logs, cases, catalog checks, or inventory are incomplete. | Stop the operational claim, preserve artifacts, investigate, and rerun with a complete evidence set. |
The PostgreSQL documentation supports the expected mechanism even though this commissioning run was not executed. It does not authorize writing PASS into an execution record. Until a real environment supplies actual versions and complete output, the honest status is a documented and statically reviewed expected-results playbook.
Keep business authorization separate from constraint acceptance
A passing protocol would prove that the reviewed equality rule behaves as expected on this fixture. It would not prove that null is the right representation for every product, that row 101 is the legitimate default, that row 102 truly belongs to eu outside the authored case, or that tenant authorization is enforced. Those are separate product, data-governance, and security decisions.
Constraint acceptance therefore needs an explicit boundary: a non-null tenant component, a nullable scope whose null meaning is intentional, at most one default per tenant, named scopes unique within their tenant, and the tested insert and update paths. It does not require every tenant to have a default. Changes outside that domain reopen the review.
Assign ownership of the next schema change
The product or configuration owner defines what a default means and authorizes any collision resolution. The database owner translates that policy into the exact constraint, plans the data change, records versions and catalog evidence, and refuses unsupported shortcuts such as a fictional UNIQUE NOT VALID phase. QA owns the P1-P9 manifest, complete artifact capture, independent row oracle, and regression checks for every write path that can alter the key.
Reopen qualification when the key columns change, null acquires a different meaning, tenants become nullable, scope normalization is introduced, the PostgreSQL major version changes, or a new bulk-load, upsert, import, or update path can write the configuration table. A previous pass is evidence for its recorded protocol, not permanent approval for a different contract.
A reviewed process should keep the driver, digest, expected manifest, actual outputs, decision record, and schema change together. The broader practice of repeatable database administration can help teams maintain that discipline, but tool automation does not replace the product decision about competing defaults or the database proof of the actual constraint.
Before a nullable unique constraint migration is approved, the team should validate composite business key behavior with both rejection and acceptance cases. The handoff should also state what was not tested: concurrent writers, deployment locks, replicas, application retries, authorization, and external side effects. Naming exclusions prevents a bounded fixture result from being promoted into a production-readiness claim by someone who did not review the original scope.
Build constraint-review skills through structured practice
The bounded conclusion is direct: ordinary UNIQUE (tenant_id, scope) is valid PostgreSQL but mismatched to this default-identity policy. Repair the rule only after authorized data reconciliation, then accept it only when row, write, catalog, version, digest, and log evidence are complete. The proposed demonstration remains an expected-results protocol until a real run supplies that evidence.
For learners building broader operational judgment, Refonte Learning's Database Administrator Essentials program lists a three-month schedule at 12-14 hours per week and competencies including database design, SQL optimization, backup and recovery, performance tuning, security, migration and integration, and monitoring. The page also describes successful completion in terms of a Training Certificate and a Certificate of Internship, while presenting internship participation as potential rather than a guaranteed placement. Use structured practice to strengthen the reasoning shown here; the programme page does not establish PostgreSQL 18 or this exact laboratory as promised syllabus content.