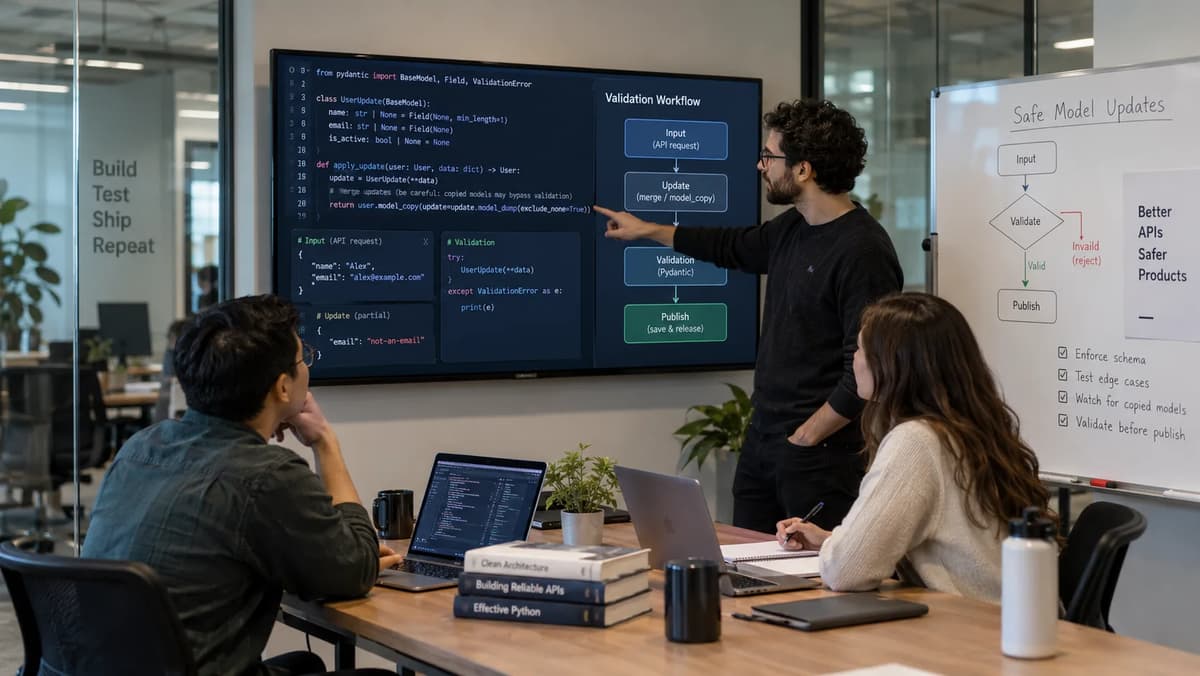
A backend service may receive an update to a data model that was already validated upstream. If the application blindly applies that update and publishes the result, it risks admitting invalid data. For example, consider a Pydantic model Limits(quota: int = Field(ge=1, le=20)) initially validated with quota=5. If the code calls copy = limits.model_copy(update={"quota": 0}), the returned object has quota=0 but no error was raised. The caller might incorrectly assume the copy is valid. The key question becomes: which object should we trust as safe to publish? Is the original validated limits (with 5) still good, or the new copy (with 0)? In practice, we should only publish a model that has passed validation with the same contract as the original.
Here we walk through how Pydantic v2’s model_copy behavior can bypass field validation, and how to detect and repair such defects. We construct a flat model with a strict integer quota from 1 to 20 and systematically test updates that should be accepted or rejected by that contract. We compare three update paths: shallow model_copy, deep model_copy, and merging into a fresh validation call. We then reconcile their outcomes against the independent business oracle (type is int and bounds). Finally, we outline how to remediate a code path that mistakenly trusts model_copy as validation. Along the way, we observe how Pydantic’s configuration flags (validate_assignment and revalidate_instances) apply in different contexts. For general API input-validation practices, see API input-validation foundations.
Locate the validation boundary that the update bypassed
It helps to separate three phases: (1) baseline validity (the original model instance), (2) candidate construction (the new object built by model_copy(update=...)), and (3) candidate validation (when/if the new object is checked before publishing). In our scenario, phase (1) is satisfied: the baseline model limits = Limits(quota=5) has a strict integer field within 1 to 20. Phase (2) is simply copying that model with new values, but because Pydantic’s model_copy does not validate the updates, phase (2) can introduce invalid data without error. Only phase (3) provides assurance of validity.
Crucially, a valid source object (the original model) does not guarantee that any modified copy is still valid. The model schema stays the same, but the replacement values must be checked anew. We define the contract as: quota must be a strict Python int between 1 and 20 inclusive. Here “strict” means no implicit conversions; e.g. a boolean or string should not pass as an int (since type(True) is bool, not int). Thus any candidate with quota outside that range or of the wrong type violates the contract. Those violations must be caught before publication.
In practical APIs, we usually validate the entire payload at the edge and reject bad data upfront. But if part of the update happens after initial intake (e.g. by merging server-side data into the model), we must ensure a second validation boundary. The controlled environment here is a Python process with no external services or mutation beyond our code. We will show precisely what happens at that boundary and why relying on model_copy alone is unsafe.
Pin a flat model and an isolated execution environment
We conduct experiments under CPython 3.12.14 with Pydantic 2.13.5 (pydantic-core 2.46.5), as specified. All results below are from a fresh run of the supplied driver script (sha256: a76979...c70b). We define a single-field model as:
from pydantic import BaseModel, ConfigDict, Field

class Limits(BaseModel):
    model_config = ConfigDict(strict=True, extra='forbid')
    quota: int = Field(ge=1, le=20)
This uses strict=True (no type coercion) and extra='forbid' (no unknown fields allowed). The field has no default; for testing we set a baseline Limits(quota=5) which is valid by contract. There are no defaults or nested objects. All testing is done in one flat Python script that prints JSON results (the complete driver is shown below).
Our environment is isolated: no FastAPI layer, no JSON decoding, no ORM or DB. We operate purely on Python objects. This keeps the focus on the Pydantic runtime behavior. (For context on building an API service, see choosing an API development stack.) We also note that custom validators and nested models are intentionally excluded. Any custom validator could also run on model_validate calls, and nested fields could have their own config; those are orthogonal concerns. Here we only test the core behavior of model_copy and direct validation on a simple schema.
Keep custom validators and nested representations outside this proof
We deliberately avoid custom @field_validator or @model_validator and do not use nested BaseModel fields or aliases. Those features introduce additional hooks in the validation process that we do not examine here. For example, a model_validator might fire on every model_validate() call on an existing instance, but it would not change how model_copy assigns raw values. Similarly, nested models have their own validation steps. By excluding these, we isolate the question to “does model_copy revalidate updated fields or not?” and “how do the Pydantic config flags apply?”. This model is minimal and not meant to prove anything about those excluded features; it simply checks the boundary for a flat schema.
Write the eight-case acceptance oracle first
Before coding, we list our test cases and expected outcomes. Each case has an update patch to apply via model_copy(update=...), along with the raw Python type of the new value and the “intended” business value. We then state whether that value should be accepted (admissible) by the contract independently of what Pydantic does. The cases are:
Case | Patch | Raw type | Candidate value | Expect acceptance? |
unchanged | {} | (none) | 5 | Yes |
lower_boundary | {"quota": 1} | int | 1 | Yes |
upper_boundary | {"quota": 20} | int | 20 | Yes |
zero | {"quota": 0} | int | 0 | No |
over_limit | {"quota": 21} | int | 21 | No |
numeric_string | {"quota": "8"} | str | "8" | No |
boolean | {"quota": True} | bool | True | No |
null | {"quota": None} | NoneType | None | No |
Here “candidate value” means the effective value that ends up in the model’s .quota (for numeric_string, strict mode will not convert, so it remains "8" as a str; for boolean, Python True is a subclass of int but type(True) is bool, so by our strict definition it fails type-check). We define a validation predicate valid_by_contract(x) as (type(x) is int and 1 <= x <= 20). Cases where this predicate is true (first three rows) are the only ones allowed. We will not alter these expectations based on Pydantic’s behavior. The Boolean case is included because in Python isinstance(True, int) is True, but type(True) is bool, so we consider it invalid.
These eight cases form the acceptance oracle. We will check the actual Pydantic outcomes against these expectations. For clarity, a successful copy, meaning that the call returned without an exception, is not the same as a valid candidate. All eight corpus patches produce a new Limits instance when passed to model_copy(update=...), but several returned values still violate the contract.
Define a successful copy separately from a valid candidate
It’s important to distinguish copying from acceptance. All eight updates produce a new Limits instance when we call model_copy because each patch targets only the declared quota field. Every copy succeeds in the sense of returning an object without error. However, only our independent contract, an exact int type and a value within range, determines whether the result is valid. We log two things: whether model_copy succeeded and whether valid_by_contract(candidate.quota) is true. We do not retroactively change the expected acceptance list after seeing Pydantic’s behavior; that list is fixed by our oracle.
Thus, in tables below “copy_succeeded” will always be true for each patch (no exception), while “contract_valid” is true only for unchanged, 1, and 20. We never rely on Python’s type conversion; e.g. valid_by_contract(True) is false.
Reproduce invalid values in an ordinary model_copy update
We first demonstrate the core issue: model_copy does not check updated values. For example, starting from limits = Limits(quota=5), suppose we do:
>>> from pydantic import ValidationError
>>> limits = Limits(quota=5)
>>> candidate = limits.model_copy(update={"quota": 0})
>>> print(candidate, candidate.quota, type(candidate.quota))
Limits(quota=0) 0 <class 'int'>
No exception was raised, but candidate.quota == 0 is outside the allowed range. The original limits.quota remains 5, which we can assert separately. The Pydantic model_copy documentation confirms that updated values are not validated. Likewise, if we do:
>>> candidate2 = limits.model_copy(update={"quota": "8"})
>>> print(candidate2, candidate2.quota, type(candidate2.quota))
Limits(quota='8') '8' <class 'str'>
Again, no error was raised, even though strict mode would normally reject a string for an int field. The copy places the raw string into .quota. Similarly, limits.model_copy(update={"quota": True}) yields quota=True. The baseline object is never modified. After each copy, limits.quota is still 5, confirming that model_copy returned a separate instance. In each case, model_copy succeeds, but candidate values 0, "8", or True violate the schema.
This reproduces the defect: the update bypassed the validation boundary. Pydantic explicitly states that model_copy(update=...) does not enforce field validation. We record the returned .quota and its Python type, and note that these candidates would be rejected by our contract. Yet model_copy did not complain. We avoid testing acceptance with isinstance(candidate, Limits), because that would confirm only that the object is a Limits instance, not that its contents satisfy the contract. A successful model_copy does not imply a valid model. We must insert an explicit validation step before accepting updated values.
Test deep copying and assignment validation as separate controls
Next we consider two other controls: deep copying and validate_assignment. Running the same eight patches with model_copy(update=..., deep=True) yields the same outcomes for .quota. The deep option affects nested object references, which this flat model does not have, while the model_copy documentation still states that updates are not validated. In every deep-copy case, candidate.quota is identical to the shallow-copy case. Deep copying can separate child-object identity, but it does not validate new field values.
Second, what if we enable validate_assignment=True on the model? This config enforces field validation on direct attribute assignment. For example:
class AssignmentLimits(Limits):
    model_config = ConfigDict(strict=True, extra="forbid", validate_assignment=True)

assignment = AssignmentLimits(quota=5)
try:
    assignment.quota = 0
except ValidationError:
    print("Assignment rejected:", assignment.quota)
Here assignment.quota = 0 will raise a ValidationError (caught) and leave assignment.quota as 5, because 0 fails ge=1. This shows validate_assignment guards against inadvertent bad assignments at runtime.
However, that does not affect model_copy. Continuing the example:
copied = assignment.model_copy(update={"quota": 0})
print(copied.quota, type(copied.quota))
This prints 0 <class 'int'>. The copy is accepted, despite validate_assignment=True, because model_copy bypasses that check. In summary, validate_assignment=True protects only direct obj.field = value operations, not the update dict in model_copy.
More defensive-looking settings do not establish this boundary
To summarize these controls in a compact way:
Deep copy vs shallow copy: No difference appears in this flat test; both insert the raw value. Deep copy concerns object identity, not value validation.
validate_assignment=True: Blocks invalid in-place assignments on existing instances (so obj.quota = 0 fails), but does not make model_copy validate its updates.
Neither of these “defensive” settings turns model_copy into a validator. They address different questions (object cloning vs direct assignment). Hence, even with these settings on the model, the update boundary remains where we left it: after copying, before use.
Setting | In-place assignment | model_copy(update=...) | Outcome |
deep=True (default=False) | Not applicable | Same as shallow | candidate.quota receives the patch value without validation |
validate_assignment=True | Rejects invalid assignment | Allows invalid copy | assignment.quota = 0 fails, but model_copy(update={"quota": 0}) returns quota=0 |
These observations align with Pydantic docs: validate_assignment only triggers on actual attribute setting, and deep copying pertains to nested fields, not value checks. The issue still stands: model_copy never calls the validators on update fields.
Check what model_validate does with an existing instance
To correct the oversight, we could try to revalidate the copied model. What happens if we take the candidate from model_copy and call Limits.model_validate(candidate)? By default, Pydantic’s config uses revalidate_instances='never'. That means an existing model instance is not revalidated by a normal model_validate call; instead, it just returns it back. In our tests we found that:
candidate = limits.model_copy(update={"quota": 0})
reentered = Limits.model_validate(candidate)
assert reentered is candidate
No new validation occurred, so reentered.quota is still 0. The Pydantic configuration documentation confirms that the default is 'never' and illustrates the existing-instance behavior. Simply calling model_validate on the copy does not help unless we change the configuration.
If we define a subclass with revalidate_instances="always", then calling model_validate() on the existing instance will run validation again. For example:
class RecheckedLimits(Limits):
    model_config = ConfigDict(strict=True, extra="forbid", revalidate_instances="always")

always = RecheckedLimits(quota=5).model_copy(update={"quota": 0})
try:
    RecheckedLimits.model_validate(always)
except ValidationError as exc:
    print("Revalidation rejected:", exc.errors())
This throws a ValidationError about quota:0, because revalidate_instances='always' causes the old always object to be checked against the schema again. We recorded this error (its type and location) in our driver output. In short, revalidate_instances="always" makes model_validate(instance) actually rerun validators; the default 'never' does not. Neither mode changes the fact that model_copy itself didn’t validate.
Qualify the existing-instance shortcut precisely
Two important clarifications: First, existing-instance revalidation only applies when you explicitly call a validation method on an already-built model. It is not automatic. Setting revalidate_instances='always' does not make model_copy become a validation step; it only affects what happens if you do model_validate(candidate). The copy still happened unchecked. Second, each model class’s config is independent. If a parent model has always, its nested fields (if any) do not automatically get revalidated unless they too have that setting. Our simple model has no nested types, but in a more complex schema one must be careful.
In any case, the safe practice is: after model_copy, treat the object as unverified until you explicitly revalidate it through model_validate or by some other means. Only the result of that validation should be sent downstream.
Validate a fresh merged mapping before publication
A better approach is: build a raw data dict for the updated model, and feed that into validation as if it were new input. Concretely, start with the original model’s dict and merge the patch, then call Limits.model_validate(merged_dict). For example:
merged = limits.model_dump(mode="python") | {"quota": new_quota}
validated = Limits.model_validate(merged)
Here model_dump(mode="python") gives a plain Python {"quota":5} mapping. We then overlay the patch {"quota": new_quota} (using normal dict or | operator). Now Limits.model_validate(merged) is the standard entry point for validating arbitrary data (like from JSON or a web request). In strict mode, it will reject any non-int or out-of-range values.
In our tests, this procedure correctly accepted 5, 1, and 20, and raised ValidationError for 0, 21, "8", True, and None. The new object returned by model_validate on success is fully validated under the same type constraints. We then publish that returned instance. This makes the update path explicit: the merged mapping is subjected to normal validation, and only the validated model is used. It preserves the contract exactly; strictness and bounds are unchanged.
We note this recipe is specific to a flat schema. It would need adjustments if fields had aliases, defaults, serialization logic or nested models. Aliases or complex serializers might require different merging or JSON-mode dumps; nested models would mean deeper merges. We exclude those here. The key idea is simply: do not rely on model_copy; instead, use model_validate on the combined data. The returned model (not the unchecked copy) is the one you publish.
Run the complete comparison driver
Below is the full Python script we used to execute the test matrix. It should be saved as pydantic_copy_validation_v2.py and run under the pinned environment. The script first writes a HOLD report (before imports) as a safeguard; it rejects running under optimized mode. Then it imports Pydantic (recording versions), defines Limits, AssignmentLimits, RecheckedLimits, and iterates through each case and path. It records each observation in a report object. Finally it asserts the results meet expectations and prints the status.
All assertions in the code reflect our contract: successful copies must preserve candidate.quota of 5 for untouched fields, and exactly those with valid values should end up accepted. The report includes rows for each (case, path) combination, whether each copy succeeded, and facts about each candidate (quota and Python type). It also records the final “accepted_sink” list of cases. A success run prints a status PASS_24_MATRIX_CELLS_AND_3_CONTROL_ASSERTIONS. (In our normal test run, the script ran from 06:44:16.986Z to 06:44:17.073Z, producing 24 rows and 3 accepted cases, as below.) An alternate run with python -O immediately halts with HOLD (as intended).
import hashlib, json, platform, sys, tempfile, traceback
from datetime import datetime, timezone
from pathlib import Path

SOURCE = Path(__file__).resolve()
RUN = Path(tempfile.mkdtemp(prefix="pydantic-copy-run-", dir=SOURCE.parent))
RESULT = RUN / "results.json"
report = {
    "revision": "pydantic-copy-validation-v2",
    "run_id": RUN.name,
    "source_sha256": hashlib.sha256(SOURCE.read_bytes()).hexdigest(),
    "started_utc": datetime.now(timezone.utc).isoformat(),
    "python": platform.python_version(),
    "python_executable": sys.executable,
    "optimization": sys.flags.optimize,
    "platform": platform.platform(),
    "status": "HOLD",
    "stage": "optimization_guard",
    "rows": [], "accepted_sink": [],
    "scope": "flat strict integer model; no custom validators, aliases or nested fields"
}

def save():
    RESULT.write_text(json.dumps(report, indent=2) + "\n")

save()  # Write HOLD before imports, so optimized runs stop here
try:
    if not debug:
        raise RuntimeError("Optimized Python is unsupported; remove -O")
    report["stage"] = "dependency_import"
    import pydantic
    import pydantic_core
    from pydantic import BaseModel, ConfigDict, Field, ValidationError
    report.update(pydantic=pydantic.__version__, pydantic_core=pydantic_core.__version__)

    class Limits(BaseModel):
        model_config = ConfigDict(strict=True, extra="forbid")
        quota: int = Field(ge=1, le=20)

    class AssignmentLimits(Limits):
        model_config = ConfigDict(strict=True, extra="forbid", validate_assignment=True)

    class RecheckedLimits(Limits):
        model_config = ConfigDict(strict=True, extra="forbid", revalidate_instances="always")

    CORPUS = [
        ("unchanged",     {},     True,  5),
        ("lower_boundary",{"quota":1}, True,  1),
        ("upper_boundary",{"quota":20},True,  20),
        ("zero",         {"quota":0}, False, None),
        ("over_limit",   {"quota":21},False, None),
        ("numeric_string",{"quota":"8"},False,None),
        ("boolean",      {"quota":True},False,None),
        ("null",         {"quota":None},False,None),
    ]

    def facts(model):
        return {"quota": model.quota, "python_type": type(model.quota).__name__}

    def valid_by_contract(value):
        return type(value) is int and 1 <= value <= 20

    rows = report["rows"]
    accepted = report["accepted_sink"]
    baseline = Limits(quota=5)

    # Test shallow and deep copies
    for case, patch, expected_accept, expected_value in CORPUS:
        for deep in (False, True):
            report["stage"] = case + (":deep_copy" if deep else ":copy")
            candidate = baseline.model_copy(update=patch, deep=deep)
            assert candidate is not baseline
            assert baseline.quota == 5 and type(baseline.quota) is int
            assert valid_by_contract(candidate.quota) is expected_accept
            reentered = Limits.model_validate(candidate)
            assert reentered is candidate
            rows.append({"case": case, "path": "deep_copy" if deep else "copy",
                         "copy_succeeded": True, "contract_valid": expected_accept,
                         "model_validate_returned_same_instance": True, facts(candidate)})
        # Now do validated mapping approach
        report["stage"] = case + ":validated_mapping"
        merged = baseline.model_dump(mode="python") | patch
        try:
            validated = Limits.model_validate(merged)
        except ValidationError as exc:
            assert not expected_accept
            errors = [{"type": e["type"], "loc": list(e["loc"])} for e in exc.errors()]
            rows.append({"case": case, "path": "validated_mapping", "accepted": False,
                         "errors": errors})
        else:
            assert expected_accept
            assert type(validated.quota) is int and validated.quota == expected_value
            accepted.append({"case": case, "quota": validated.quota})
            rows.append({"case": case, "path": "validated_mapping", "accepted": True,
                         facts(validated)})

    # Test assignment validation
    report["stage"] = "assignment_control"
    assignment = AssignmentLimits(quota=5)
    try:
        assignment.quota = 0
    except ValidationError:
        assert assignment.quota == 5
    else:
        raise AssertionError("assignment control failed")
    report["assignment_rejects_zero"] = True

    report["stage"] = "assignment_copy_control"
    copied_assignment = assignment.model_copy(update={"quota": 0})
    assert copied_assignment.quota == 0
    report["assignment_validation_does_not_validate_copy_update"] = facts(copied_assignment)

    # Test always revalidation
    report["stage"] = "always_revalidation_control"
    always = RecheckedLimits(quota=5).model_copy(update={"quota": 0})
    try:
        RecheckedLimits.model_validate(always)
    except ValidationError as exc:
        rechecked_errors = [{"type": e["type"], "loc": list(e["loc"])} for e in exc.errors()]
    else:
        raise AssertionError("always revalidation control failed")

    assert accepted == [
        {"case": "unchanged", "quota": 5},
        {"case": "lower_boundary", "quota": 1},
        {"case": "upper_boundary", "quota": 20},
    ]
    assert len(rows) == 24 and len({(r["case"], r["path"]) for r in rows}) == 24
    report["always_revalidation_rejects_copy"] = rechecked_errors

    report["stage"] = "complete"
    report["status"] = "PASS_24_MATRIX_CELLS_AND_3_CONTROL_ASSERTIONS"
except BaseException as exc:
    report["status"] = "HOLD"
    report["error"] = {
        "type": type(exc).__name__,
        "message": str(exc),
        "traceback": traceback.format_exc()
    }
finally:
    report["finished_utc"] = datetime.now(timezone.utc).isoformat()
    save()
    print(json.dumps({"status": report["status"], "run_id": report["run_id"],
                      "result_path": str(RESULT)}, indent=2))
if report["status"] != "PASS_24_MATRIX_CELLS_AND_3_CONTROL_ASSERTIONS":
    raise SystemExit(1)
The code’s comments and output verify the behavior: all 24 rows (8 cases × 3 paths) are present. In the actual run, the "accepted_sink" ended up as:
"accepted_sink": [
  {"case": "unchanged", "quota": 5},
  {"case": "lower_boundary", "quota": 1},
  {"case": "upper_boundary", "quota": 20}
]
That is exactly the three admissible cases. No invalid candidate was admitted.
Retain observed results without inventing a new run
We note the results from the observed reproduction: the normal run (pydantic-copy-run-saeq89o9) produced 24 rows and the three accepted cases above. A separate run with optimization (python -O, run pydantic-copy-run-kj5jj1lq) aborted immediately with HOLD at the "optimization_guard" stage. We must preserve these factual outputs. We will not rerun or modify the test, so we do not invent new data. If any user changes the script or model, they must rerun it to generate fresh results. Missing or corrupted report files would force a retest (cannot assume anything). The conclusions below are strictly tied to the above runs.
Reconcile the accepted identities and rejected values
Across all paths, we record that only “unchanged” (5), “lower_boundary” (1) and “upper_boundary” (20) ended up in the accepted sink. For each of the other cases, the final validation path (path=validated_mapping) rejected them. For example:
Case “zero”: merged={"quota":0} caused a ValidationError with type greater_than_equal and location ["quota"]. The original baseline.quota remained 5.
Case “over_limit”: merged={"quota":21} caused a ValidationError with type less_than_equal and location ["quota"].
Case “numeric_string”: merged={"quota":"8"} caused a ValidationError with type int_type and location ["quota"] because the value was a string.
Case “boolean”: merged={"quota":True} caused a ValidationError with type int_type and location ["quota"]. Strict integer validation rejects bool even though bool is a subclass of int in Python.
Case “null”: merged={"quota":None} caused a ValidationError with type int_type and location ["quota"].
Each error includes a stable type identifier and the location “quota”. We avoid depending on the English wording of the message and record only the error type and location. In every case, the script asserts the contract and appends to accepted_sink only when expected_accept is true after standard model validation.
Thus the final accepted set is exactly:
Case | Accepted quota |
unchanged | 5 |
lower_boundary | 1 |
upper_boundary | 20 |
All other cases were rejected (no record in accepted_sink). The driver also asserted that after each copy, baseline.quota was still 5 (unchanged), so no inadvertent mutation occurred. In summary, no invalid candidate ever reached the “accepted” list, and no valid one was dropped. This is exactly the intended contract enforcement for this boundary.
Recover from a caller that already trusted copied candidates
If we discover that a part of the application was erroneously publishing the unchecked model_copy result, we must correct that code path immediately. The fix is to stop using the unchecked copy for any downstream data or output. Instead, we should only use the validated object (from the merged-map approach above). In practice, this means: block or roll back the release of the new values until we validate them. Keep the last known good state (e.g. keep quota=5 in place) while fixing the code.
The original inputs that led to the invalid copy are problematic; we cannot retroactively fix them except by business policy (e.g. contacting users). In code, we mark this case as REJECT: do not accept model_copy results as final. The code should raise an exception or return an error response on such updates. We should also identify and annotate the offending code (caller) so it’s repaired (the caller that assumed model_copy was a validator). We would want logging that clearly shows which patch was rejected and at what point.
Under no circumstances should we silently coerce or clamp the bad quota (e.g. resetting 0 to 1) without explicit validation steps. And if we cannot confirm an update’s provenance or validity, the safe action is HOLD: do not proceed. In essence, this recovery strategy is: retain the last valid state, abort invalid update paths, fix the update code, and log the incident.
Roll out the corrected update path without weakening the contract
When deploying the fix, we ensure the updated code now routes all published values through the validated-mapping boundary we defined. We keep the invalid fixtures (“quota=0” etc.) as regression tests. In rollout, we should monitor for validation failures separately from other errors. If the code change is safe, then updates outside the 1-to-20 range will now be explicitly rejected (e.g. returning HTTP 400 to the client), rather than silently accepted. Any deployment process (canary, blue-green, etc.) should watch for new validation errors to judge the impact.
If problems emerge, we have the option to roll back to the previous code, which still had the bug, while investigating. However, we must not disable strict=True or broaden the valid range merely to reduce errors. That would weaken the data contract. Instead, treat those failures as valid rejections and investigate why the updates were attempted. For guidance on reversing API changes safely, see API release and rollback practice. The field type and range must remain firm; only the logic that applies the contract should change. The fixed path should also log the model revision and hash for traceability.
Make acceptance depend on evidence for the actual model
In short: Accept only what has evidence of successful validation against this model. We form a decision table:
Condition | Decision | Action |
Candidate meets contract (type is int, from 1 to 20) | ACCEPT | Keep the validated model and proceed |
Candidate violates contract (bad type or range) | REJECT | Drop the candidate, retain the last valid state, and fix the caller |
Runtime evidence cannot confirm the copy step | HOLD | Pause deployment and investigate the missing evidence |
Model or configuration changed since testing | HOLD | Rerun the tests under the new model or configuration |
Unexpected validators or callbacks were found | HOLD | Review their effects and run a new qualification |
Recovery evidence is incomplete | HOLD | Stop and gather the missing diagnostic information |
For our model-to-application boundary, we only ACCEPT the 3 known good cases. We REJECT any attempt to publish a copy that is invalid. If something about the runtime is uncertain (e.g. we see a candidate but can’t match it to a log entry), that’s HOLD. We explicitly do not repair the data; if a candidate was already published in error, remediation is a manual follow-up (not an automatic “correct and proceed”). Note that these decisions are scoped to this model; other parts of the API may have their own validation logic and acceptance criteria.
Treat representation changes as a new acceptance event
If the model schema changes, for example by adding a field alias, nested model, default value, or validator, the contract tested above no longer describes the whole validation context. The owner of the changed model must design and test the new path explicitly. Our flat-model results show how this schema’s update path can be secured, but they do not automatically prove that a model with aliases, nested representations, or custom serializers is safe. Repeat comparable validation tests after every significant schema or serialization change.
Assign ownership of schema, update code and admitted state
Finally, clarify team responsibilities. The schema owner defines the field’s type and bounds and owns the contract, for example, “quota is a strict int from 1 to 20.” The API maintainer or developer implements the update logic by merging the patch and validating it; that is the code adjusted here. QA owns the test corpus and records the model version, code revision, environment, accepted case IDs, and rejection diagnostics. The data or application owner controls what happens after publication, including database writes, and may need to reconcile invalid data that was already admitted.
We keep one record (e.g. a file or ticket) noting: model revision, fixture hash, environment, the three accepted cases (unchanged=5, lower=1, upper=20) and the error types/locations for rejected cases. Link that to any deployment tracking. This follows the typical request-to-database flow in backend development: the data model (“Limits”) is validated before being used. In practice, after HTTP parsing and authentication, the validated model instance is what moves downstream. Any admitted state (e.g. a database row) is labeled with that model version. We use versioning or tags to avoid confusion if the schema updates.
Build the API testing skills behind a trustworthy update boundary
The lesson is operational: never assume an internal copy operation implies validation; verify it with tests. Refonte Learning’s APIs Developer Fundamentals program develops that discipline through API testing, error handling, REST and GraphQL design, database integration, authentication, API security, Postman, Swagger, and hands-on projects. The three-month program requires 10 to 12 hours per week, includes mentor guidance from professionals such as Sophia Johnson, and awards a Training Certificate and a Certificate of Internship. It offers a structured path for developers who want to design and verify API contracts more reliably.