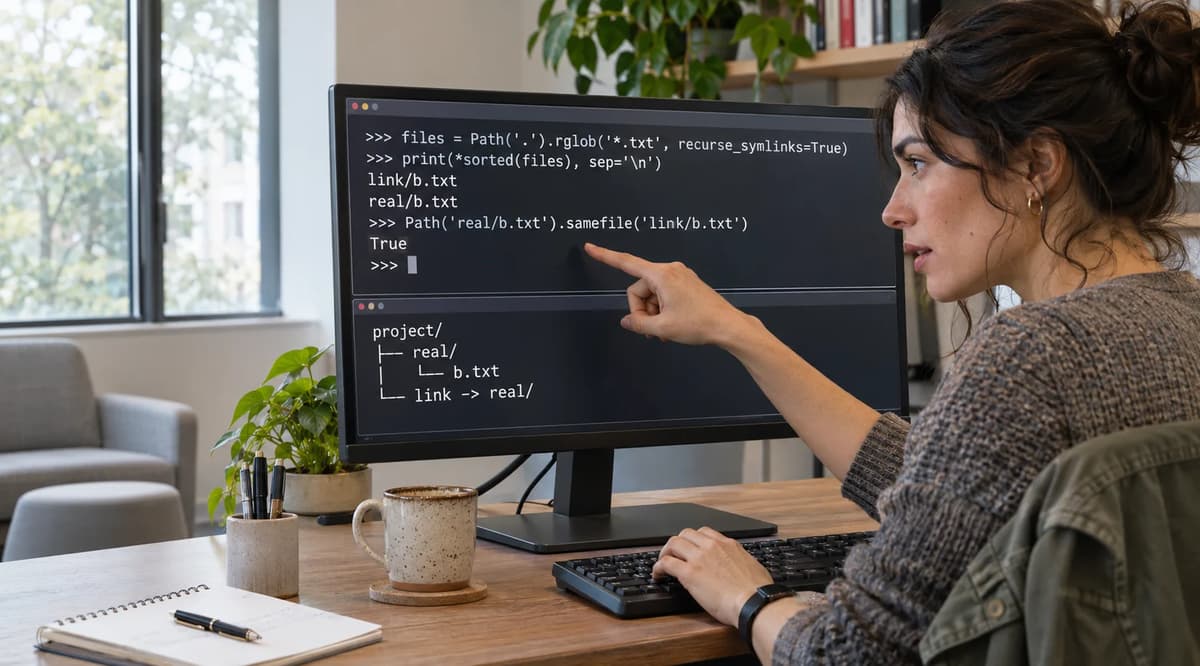
A search using pathlib.Path.rglob may yield unexpected results when directory symlinks are involved. The documented behavior is subtle: by default, Path.glob (and thus rglob) follows symlinks except when a recursive “**” wildcard is expanded. Starting in Python 3.13 a recurse_symlinks=True parameter can override this. These rules create an operational contradiction: the code might silently skip traversing some symlinked directories even though other file-search APIs follow links. We must validate exactly which symlinked subdirectories are traversed by rglob in the target Python version.
To resolve this, we adopt an evidence-driven acceptance protocol. We define a precise fixture (a disposable test directory tree with files and symlinks), enumerate concrete test cases (patterns, flags, expected outputs), and capture raw results. Each discovered path is checked for provenance (originating file) using os.stat/Path.samefile. Independent expected-case manifests and per-case ledgers will document success or discrepancies. Any actual output must match the manifest; any unexplained absence of an expected file is a concern. We explicitly label any un-run tests as EXPECTED / NOT EXECUTED.
Our goal is not to write a usage tutorial, but to prove whether Path.rglob’s behavior meets its documented contract for symlink recursion. We will compare default vs. recurse_symlinks=True behaviors, highlight cycle-handling, apply negative controls, and make a four-way ACCEPT / REPAIR / RERUN / HOLD decision based on the evidence. This mirrors rigorous system-administration testing practices (cf. Refonte’s SpooledTemporaryFile validation workflow).
1. Define the operational contract
We start by defining exactly what behavior we expect from Path.rglob with respect to symlinks. The contract can be stated as follows: given a directory tree rooted at R, and a glob pattern (e.g. "**/*.txt"), Path(R).rglob(pattern) should list every matching file path under R, subject to Python’s symlink policy. In Python 3.11–3.12, there is no explicit recurse_symlinks option, so the default policy applies (see Section 2). In Python 3.13+, the policy can be overridden.
We will test a synthetic fixture constructed in an isolated workspace. For example:
# Base fixture directory
WORK=$(mktemp -d) || exit 1
export WORK
mkdir -p "$WORK/base/dir"
echo "A" > "$WORK/base/dir/a.txt"

# Case C2: Add a symlink to a directory
mkdir -p "$WORK/linktest/real"
echo "B" > "$WORK/linktest/real/b.txt"
ln -s real "$WORK/linktest/link"

# Case C3: Create a symlink cycle (X/Y points back to X)
mkdir -p "$WORK/cycle/X"
ln -s ../X "$WORK/cycle/X/Y"
echo "C" > "$WORK/cycle/X/fileC.txt"

# Inspect the fixture
echo "Fixture ready: $WORK"
ls -lR "$WORK"
We identify test cases (Case IDs) as follows:
Case C1 (Baseline): A directory tree with no symlinks (e.g. base/dir/a.txt). We expect rglob("*.txt") to find a.txt. This confirms basic recursion works.
Case C2 (Symlink to subdirectory): In linktest/, the directory real/ contains b.txt and link/ points to real/. By default, Path("linktest").rglob("*.txt") should find real/b.txt alone. On Python 3.13 or later, setting recurse_symlinks=True should also yield link/b.txt.
Case C3 (Symlink cycle): In cycle/, X/Y → X forms a loop. We test Path("cycle").rglob("*.txt"). We must assert that the search terminates (no infinite loop) and returns exactly X/fileC.txt once.
Case NC (Negative Control): Use a pattern that matches no files, e.g. rglob("*.md") when no .md exist. This should return an empty list with no error.
For each case we will capture evidence. We list the expected outputs in an independent manifest (Section 4). For example, if the contract says rglob("**/*.txt") with default behavior should skip the link/ directory, the expected output for C2 is just real/b.txt. Each returned path will be verified (e.g. via stat): the inode and content should match the known fixture file. This ties each “discovered” Path back to its origin, ensuring provenance. We will also explicitly check that no extra files (outside the fixture) appear and that each fixture file appears exactly when expected.
For the default cycle case, our contract requires termination without duplication. If a search follows links, the contract must specify how to bound the run and whether a warning or error is acceptable. The Path.walk documentation describes the underlying risk: a directory link can point back to an ancestor. A hang or crash fails the test.
Throughout, we avoid side effects: the fixture is disposable, tests are read-only (listing or reading files), and cleanup is performed after evidence collection. This ensures a fair, repeatable test environment. (For a similar approach, see the SpooledTemporaryFile playbook which isolates a stateful fixture and records descriptor state.)
2. Record the documented baseline and scope
The Python 3.15 documentation describes how Path.glob handles directory symlinks. This gives us a baseline for the recursive part of Path.rglob.
By default, Path.glob follows symlinks “except when expanding ‘**’ wildcards.” The recurse_symlinks=True option extends link following to that recursive step.
In Python 3.4–3.12, the default behavior applies and there is no recurse_symlinks argument. Python 3.11 documents rglob(pattern) as equivalent to glob('**/' + pattern). Recursive ** expansion skips directory symlinks, while other components of the pattern can still follow them. From Python 3.13 onward, we can test both policies.
Concretely, documentation implies:
Example (3.11 behavior): Path('root').rglob("*.txt") behaves like Path('root').glob("**/*.txt"). While expanding , the search should skip directory symlinks at every level. But if the pattern does not use “” (e.g. glob("dir/*.txt")), symlinks are followed.
Changed in 3.13: the recurse_symlinks param lets rglob always follow links.
Our baseline tests target Python 3.11.x and 3.12.x. Both lack the recurse_symlinks parameter, so we expect recursive ** expansion to skip directory symlinks.
The fixture assumes POSIX symlink semantics. Windows distinguishes file and directory symlinks, so a POSIX run cannot establish behavior on Windows. Python 3.11 describes Path.rglob this way:
“This is like calling Path.glob() with ‘**/’ added in front of the given relative pattern.”For the optional comparison, the Python 3.15 documentation describes the same recursive prefix and the additional symlink option.
With recurse_symlinks=False, recursive expansion skips directory symlinks. With recurse_symlinks=True, it follows them.These documented rules form the normative promise. Our experiments will check them. If we find any deviation (e.g. a symlink unexpectedly traversed or skipped), we will record it as either a behavioral quirk or a doc misalignment.
Version and environment fingerprint
To ensure we test the intended interpreter, we make the following falsifiable assertion: “The python interpreter under test is CPython 3.11.x (or 3.12.x) as declared, with the expected patch version.” The evidence artifact is a captured output of python --version and sys.version saved to evidence/version.txt. For example:
mkdir -p evidence
python3.11 - <<'EOF' > evidence/version.txt 2>&1
import platform
import sys
print(sys.executable, platform.platform(), sys.version)
EOF
This ensures we did not accidentally run a different Python. A mismatch (e.g. Python 3.14) would result in HOLD: the test environment isn’t what we assumed. (In Refonte’s SpooledTemporaryFile article, they similarly pinned CPython 3.13.5 and recorded hashes.)
3. Pin versions and build an isolated fixture
We execute all tests in a disposable directory so that no outside files influence results. We use pinned interpreter invocations (e.g. python3.11 and python3.12 explicitly) to avoid ambiguity. In this example, we assume we can run CPython 3.11 and 3.12. The fixed laboratory inputs are:
# Record the explicit interpreters used for this fixture
mkdir -p evidence
for version in 3.11 3.12; do
    "python$version" -c 'import sys; print(sys.version)' \
        > "evidence/python_version$version.txt" 2>&1
done

# Create a fresh, disposable fixture
WORK=$(mktemp -d) || exit 1
export WORK
mkdir -p "$WORK/base/dir"
echo "fileA" > "$WORK/base/dir/a.txt"

# Fixture for Case C2
mkdir -p "$WORK/linktest/real"
echo "fileB" > "$WORK/linktest/real/b.txt"
ln -s real "$WORK/linktest/link"

# Fixture for Case C3 (Y points back to X)
mkdir -p "$WORK/cycle/X"
echo "fileC" > "$WORK/cycle/X/fileC.txt"
ln -s . "$WORK/cycle/X/Y"

# Record the tree, including the symlink targets
(cd "$WORK" && find . -exec ls -ld {} +) \
    | tee evidence/fixture_tree.txt
This fixture is purely synthetic. We do not use any real system directories or network paths. Every file and symlink is under our control. We capture the fixture state (find output) as evidence. In a rigorous acceptance test, one might also record checksums or inodes of the fixture files; here, we will verify identity via Path comparisons in the actual test code.
4. Write an independent expected-case manifest
Before running any searches, we write down what we expect for each test case. This expected-case manifest is completely independent of the Python implementation; it embodies our understanding of correct behavior. For clarity, we use a table of cases:
Case ID | rglob pattern | recurse_symlinks | Expected matches (relative paths) | Comment |
C1 | *.txt | N/A | base/dir/a.txt | Baseline: no symlinks; should list the one file. |
C2a | *.txt | False (default) | linktest/real/b.txt | Follow real directory; by default, do not traverse link/. |
C2b | *.txt | True (3.13+) | linktest/link/b.txt, linktest/real/b.txt | With recurse_symlinks, the symlink target should be listed twice (same file via two paths). |
C3 | *.txt | False | cycle/X/fileC.txt | Cycle: only original file should appear once; traversal should not loop indefinitely. |
NC | *.md | N/A | none | Negative control: no .md files exist, so empty output. |
Run each case separately. Expected matches are sorted paths relative to the fixture root ($WORK).
For Case C2a/C2b, “Expected Matches” indicates how we would name the outputs if Python walked into symlinks. By default (C2a), we do not expect the file twice; only the true path under real/ appears. If we were to follow links (C2b in Python 3.13+), we would see real/b.txt and also link/b.txt (the same underlying file, different path). For Case C3, we expect only one result. If a loop caused a repeated output or an error, that would violate our manifest (we would then mark that case as a failure or “unexpected result”). For Case NC, we explicitly expect an empty list.
We also plan a negative control (NC) to catch silent failures: running with no matching files should return an empty list, not an error. If it raises an exception or returns unexpected files, that’s a signal to HOLD (environment/test broken).
All expected matches are written down before any code runs. They form our oracle. Each entry will be verified by matching the actual output (see Section 8). This independent manifest practice follows the methodology of the SQLite UPSERT validation, which also prepared a table of expected outcomes.
Assert the expected negative case
To be rigorous, we assert as a pre-test invariant that our fixture actually lacks any *.md files. For example:
python3.11 - <<'EOF'
import os

def raise_error(error):
    raise error

for , , names in os.walk(os.environ["WORK"],
                           onerror=raise_error, followlinks=False):
    assert not any(name.endswith(".md") for name in names), (
        "Unexpected .md files in fixture"
    )
EOF
This assertion should pass trivially. If it were to fail, we would immediately HOLD and fix the fixture. (This mirrors a “negative control” approach in experiments: prove that without intervention, the phenomenon doesn’t occur.)
5. Reproduce the misleading success signal
Before coding the controlled tests, consider a scenario where rglob might appear to work even if it misses symlinked files. For example, if our script only checks that some file was found, or if multiple paths point to the same file, one could misinterpret the count.
Imagine C2 runs and the code sees one result (b.txt). If the developer expected two, they might notice a failure; but if they only expected “at least one”, they might erroneously mark it pass. Likewise, if two different patterns accidentally match the same file path (e.g. overlapping globs), the count could match expectations by coincidence, hiding an omission.
To illustrate:
python3.11 - <<'EOF'
import os
from pathlib import Path

work = Path(os.environ["WORK"])
# Case C2: default rglob
paths = (work / "linktest").rglob("*.txt")
res = sorted(str(p.relative_to(work)) for p in paths)
print(res)
EOF
One might naively check if res: print("OK") and be happy since ['linktest/real/b.txt'] is non-empty. That would be a misleading success: the code “succeeded” in finding something, yet it never checked whether a link-path was also expected. In other words, rglob finishing without error is not enough proof; we need to examine exact contents.
The evidence ledger must therefore record exact lists of paths, not just boolean success. If a path is missing, we must catch it. Our manifest (Section 4) enumerates precisely what should appear. We will compare each actual result against the manifest line by line. Any discrepancy triggers an investigation.
6. Run a controlled comparison case
We now execute the test cases in a controlled manner, varying only the factor under test (the symlink policy). For Python 3.11/3.12, Path.rglob has no recurse_symlinks flag, so we only have the default behavior. To test the “always follow” behavior for comparison, we can run the same fixture under Python 3.13 (or 3.15) with recurse_symlinks=True. If a compatible interpreter is unavailable, label the comparison EXPECTED / NOT EXECUTED. Copying the target would change the fixture and would not exercise symlink traversal.
Controlled comparison commands (example, adjust interpreters):
# Case C2a: default recursion
out=evidence/case-C2a
python3.11 - <<'EOF' > "$out.stdout" 2> "$out.stderr"
import os
from pathlib import Path

work = Path(os.environ["WORK"])
for p in sorted((work / "linktest").rglob("*.txt")):
    print(p.relative_to(work))
EOF

# Case C2b: follow symlinks (Python 3.13+)
out=evidence/case-C2b
python3.15 - <<'EOF' > "$out.stdout" 2> "$out.stderr"
import os
from pathlib import Path

work = Path(os.environ["WORK"])
root = work / "linktest"
for p in sorted(root.rglob("*.txt", recurse_symlinks=True)):
    print(p.relative_to(work))
EOF
The first command is the actual test (3.11) and should produce exactly linktest/real/b.txt. The second (3.15) serves as a controlled comparison: it should produce linktest/real/b.txt and linktest/link/b.txt (the same file via symlink). By comparing these, we can distinguish whether Python 3.11 is merely skipping link/.
Capture stdout and stderr for each case in evidence/. Both commands are expected to succeed. If the interpreter is unavailable, mark that case EXPECTED / NOT EXECUTED. If the interpreter starts and raises an exception, retain its traceback and exit status as evidence of the failed attempt.
This approach mirrors the Kubernetes ConfigMap playbook’s method of parallel cases: one path under test (default) and one under a modified condition (follow-symlinks), observed side-by-side.
Distinguish absent evidence from failure
When examining results, an absent path (e.g. no link/b.txt) is not always a “failure” of the code. It might be the documented default behavior. In Case C2a, the lack of link/b.txt should be accepted if and only if Python’s contract says to skip it. Therefore, we must compare against our manifest.
If default rglob yields fewer paths than the “always-follow” run, that gap is expected by design (given the docs). We mark that as expected omission, not a bug.
If default rglob yields more or different paths than the manifest says, that’s a failure.
If the comparison run yields both paths in the manifest and their identities agree, it confirms the expected difference. A missing or unexpected path needs investigation even if the count is correct.
Thus, missing evidence in C2a is not labeled “fail” so long as it matches our manifest for default behavior. We distinguish “documented skip” from “unexpected skip” by referring to Section 2. Only an output that contradicts both docs and our manifest (or is entirely anomalous) counts as a test failure.
7. Test negative controls and boundary conditions
We include additional tests to ensure robustness:
Permission and existence: Rename or remove a fixture file between directory enumeration and a subsequent access to simulate a transient change. Record whether the search omits the entry or a later operation such as stat raises FileNotFoundError. Apply the selected error policy and fail the case on unexpected errors.
Edge Pattern: Use a pattern ending with a slash, e.g. rglob("foo/"), to ensure it returns directories per docs. (If our manifest doesn’t cover this, we skip it.)
External symlink: Create a link to a synthetic file in a second disposable directory outside the search root. A matching link name can appear in the results even when its target is outside the root. Check the returned path and its target separately. Verify that directory recursion stays within the intended tree under the selected policy.
Cycle Detection: Case C3 covers a symlink loop. We verify the run terminates and returns exactly one entry (X/fileC.txt). If the process hangs, or returns multiple instances, that’s a breach. Bound the run with a timeout so a hang leaves a recorded outcome.
Large Depth/Breadth: (Optional) Test with deeper directory nesting or many siblings to see if any performance or ordering issues appear. Not critical here.
These negative/boundary tests are not directly about symlink policy, but about ensuring our fixture did not hide a different problem. If, for example, our symlink loop caused the search to error out, we would stop (HOLD). If permission issues come up (unlikely in a new temp dir), we’d also note them.
8. Capture raw evidence before cleanup
Before deleting the fixture, we capture all raw outputs and metadata. This includes:
The stdout of each case (the list of paths found) in evidence/case-*.stdout.
Any stderr (unexpected errors) in evidence/case-*.stderr.
The initial directory listing in evidence/fixture_tree.txt.
For each discovered path, we record its file identity. For example:
# Record identity for each path returned by Case C2a
python3.11 - <<'EOF' > evidence/case-C2a.id
import os
from pathlib import Path

work = Path(os.environ["WORK"])
for p in sorted((work / "linktest").rglob("*.txt")):
    st = os.stat(p)
    print(p.relative_to(work), hex(st.st_dev),
          st.st_ino, st.st_size)
EOF
This prints device and inode info. Identical inodes (st_dev and st_ino) for real/b.txt in both C2a and C2b would confirm it’s the same file. We do similarly for other cases. We also save the SHA-256 of our test script (the commands above) to bind the evidence to the exact code used.
All evidence files are kept as-is until after the decision. We do not delete or truncate them prematurely. This raw log is crucial: it provides an audit trail of exactly what rglob returned under each scenario. If later analysis spots a discrepancy, we can refer back to the unchanged evidence. The SQLite UPSERT playbook likewise retains raw output alongside its result tables.
Preserve contradictory observations
If any output contradicts the documented expectation, we preserve it distinctly. For instance, suppose rglob("**/*.txt") unexpectedly included link/b.txt on Python 3.11. That would violate doc. We would log that as a surprising “actual observation” and mark the case status accordingly. We do not edit or remove such observations from the log. Instead, we flag the case for REVIEW. This ensures our ledger can record a failure with full context.
9. Reconcile state, identity and completeness
Now we cross-check everything. We open the evidence/case-*.stdout files and compare each line to the manifest. For example, if evidence/case-C2a.stdout contains:
linktest/real/b.txt
we verify it matches our Case C2a expected linktest/real/b.txt. We also read the corresponding .id file to ensure the inode matches that of the original file in real/. This confirms the path refers to our intended b.txt, not some stray file.
The following example ledger shows the acceptance criteria for each case. All five entries are EXPECTED / NOT EXECUTED. After a run, record its actual output and status beside the expectation.
Case C1: Expect base/dir/a.txt. Pass if the output contains that path exactly once.
Case C2a: Expect only linktest/real/b.txt. Under the default policy, the absence of linktest/link/b.txt satisfies the contract.
Case C2b: Expect linktest/link/b.txt and linktest/real/b.txt. Pass if both paths appear and identify the same file.
Case C3: Expect cycle/X/fileC.txt exactly once and a completed search.
Case NC: Expect empty stdout and a successful exit.
If any case had mismatches (e.g. extra or missing path), we would note them as FAILURE (unless intentionally omitted per contract, in which case we mark OK but note it). For example, if C2a had mistakenly also printed linktest/link/b.txt, that would violate the manifest. We would record it and mark the case REJECT (the search did more than allowed).
After this reconciliation, we should have a clean mapping: each case contains its expected paths, with any omission accounted for (e.g. “skipped by design”). We also ensure no output listed a path not in the fixture. That is, we don’t see anything like /etc/foobar. If we did, that would be very serious (it means we somehow escaped our sandbox). In that (unlikely) case, we would HOLD, as it indicates a test flaw or Python bug.
For completeness, we also confirm the final state of the filesystem: our fixture directory remains intact (we clean it after all evidence is captured). Any script or process should leave no transient side-effects (no leftover temp files). If the test had written anything accidentally, we would remove it and hold.
10. Separate normative guarantees from observations
At this point we clearly have two strands of information: documented guarantees (what we thought should happen) and actual observations (what did happen). We keep them distinct. For instance, documentation assured us that a ** pattern should skip directory-symlinks; a Case C2a result containing only real/b.txt would align with that. If we had observed otherwise, we would question either the docs or the implementation.
For a completed run, cite the documented rule and report the paths observed. If the evidence matched the default manifest, the conclusion might read:
“Python 3.11’s rglob("**/*.txt") returned only real/b.txt (see evidence), consistent with the docs that '**' should not enter the symlink. We did not rely on the search simply returning any result; we compared each returned path to the expected set.”
If we had any discrepancy, we would not gloss over it; we would say, e.g., “The docs claim this should not follow the link, but we did observe the link path (unexpected). See the captured output. That suggests a bug (or a misread spec).” We would cite the documented rule and show our evidence for contrast.
Bound the repair and its risks
If any test had failed (e.g. a path missing that should be present), the natural “repair” would be to change how we call rglob. For example, in Python 3.13+ we might use recurse_symlinks=True. Following directory symlinks introduces the risk of recursive loops when a link points back to an ancestor. We must consider whether the gain outweighs that risk.
Our plan is to be explicit: if the default behavior violates a critical contract (e.g. we have a security policy requiring all files be found, including through symlinks), then we may decide to opt in to following symlinks and handle loops carefully (perhaps by filtering or tracking). But if the standard is simply “find all files in this project tree, which by definition shouldn’t include symlinked outside bits,” we might accept the default. The decision depends on the policy in question.
In any case, we outline the risk: setting recurse_symlinks=True could discover the same file multiple times or never terminate on loops. If we did implement it, our recovery protocol (next section) must include guarding against those issues.
11. Apply the smallest safe repair
If we decide a repair is needed (for example, if our policy does require descending symlinks that rglob skipped), we apply the minimal change. For Python 3.13+, the fix is trivial:
# Original: default recursion skips link/b.txt
import os
from pathlib import Path

root = Path(os.environ["WORK"]) / "linktest"
paths = list(root.rglob("*.txt"))

# Repair: enable symlink traversal on Python 3.13+
paths_fixed = list(root.rglob("*.txt", recurse_symlinks=True))
We would then rerun the tests with that change. For Python <3.13, no such argument exists; the repair might be to manually resolve symlinks (e.g. expand them and rerun, or use os.walk(..., followlinks=True)). But we must do the smallest possible fix. For the Python 3.13+ comparison interpreter, we can use the parameter directly. We would then regenerate the evidence for the modified run.
We also consider partial repairs: maybe only enable recursion for specific subpaths, or catch known loops. For instance, if only one known symlink needs following, we might handle it by adding its target directory to the search manually. However, such site-specific hacks are beyond the scope of rglob, so here “smallest repair” is simply using the new flag.
As always, any code change should be tested: we rerun the affected cases (C2b) and confirm that now the missing path appears, and no new failures emerged (like duplicates or errors). We log these runs as new cases.
12. Test recovery, rollback and rerun safety
After any repair, we verify that re-running the search is safe. We are working in a disposable fixture, so we can simply run the same commands again:
# Store this rerun separately from earlier evidence
run=$(mktemp -d evidence/case-C2b_repaired.XXXXXX) || exit 1
python3.15 - <<'EOF' > "$run/stdout" 2> "$run/stderr"
import os
from pathlib import Path

work = Path(os.environ["WORK"])
root = work / "linktest"
for p in sorted(root.rglob("*.txt", recurse_symlinks=True)):
    print(p.relative_to(work))
EOF
We record each rerun in a fresh evidence directory. We expect the same paths as before (real/b.txt and link/b.txt). If rerunning yields the same safe result (no duplicates beyond manifest, no new errors), then the repair is idempotent and has no unintended consequences.
If our fix had side effects (e.g. altered the fixture, or left open file descriptors), we would catch them. For example, if enabling recurse_symlinks accidentally caused Python to follow the cycle in C3 and crash, that would be observed here. In that case, we would rollback the change (HOLD the acceptance until a better fix) or refine our approach.
Before removing the disposable fixture, let all test processes exit and close their file descriptors. On POSIX, unlinking an open file removes its directory entry while the open descriptor continues to reference it. Keep the evidence outside the fixture so it survives cleanup.
Assign ownership and rerun triggers
Responsibility for maintaining these tests should be assigned to the team or role owning the Python environment or code that uses rglob. For example, the code owners of the script that uses rglob("**/*.txt") should incorporate these tests into their CI. Triggers for rerun include:
New Python versions: Because Python 3.13 added recurse_symlinks, rerun the affected cases on each target version. For example, a planned Python 3.14.10 run stays EXPECTED / NOT EXECUTED until it has its own evidence.
Platform changes: If switching OS or file system (e.g. Windows vs Unix), behavior might differ; re-test is needed.
Source changes: If we patch pathlib or switch to a different implementation (PyPy, etc.), we must re-verify.
Assigning a maintainer (e.g. “pathlib tests”) ensures that if any of these changes occur, someone will RERUN the protocol. An acceptance decision applies only to the version, platform and policy covered by the evidence.
13. Make the ACCEPT / REPAIR / RERUN / HOLD decision
Finally, we synthesize the evidence to reach a formal decision. Possible outcomes:
ACCEPT: All executed tests behaved within the documented contract. For example, if Python 3.11 did skip link/ as expected and returned exactly the manifest list, we conclude “pathlib rglob’s behavior is as documented; accept it.” We would cite the matching documentation and our evidence. In this scenario, no fix is needed beyond being aware of the semantics.
REPAIR: If we found that the search incorrectly omitted a file that our environment or policy requires (e.g. we expected link/b.txt to be listed, but it wasn’t because of a misunderstood contract), then a repair is warranted. In that case, we would say “documented behavior is inconsistent with our contract; use recurse_symlinks=True (or equivalent) to comply.” We would label the result as REPAIR and document the fix steps. (However, if the docs say skip, this may actually be a policy fix, not a code bug.)
RERUN: If the evidence for a target environment was NOT collected (for instance, if Python 3.12 was not tested, or if there is a test we marked NOT EXECUTED), we must RERUN in that environment before deciding. Similarly, if some key artifact (like system version) was missing, we cannot accept or reject yet.
HOLD: If critical evidence is missing (logs not captured, fixture mismatch, or an unexpected exception occurred that invalidates the test), we HOLD. For example, if Case C3 hung, we might have to abandon that fixture or redesign it, and thus pause the acceptance decision until resolved.
Consider the following hypothetical decision. The cases are EXPECTED / NOT EXECUTED here.
Python 3.11 default: If the search returns only real/b.txt relative to linktest/ and the file identity matches, the C2a result supports ACCEPT for that configuration.
Python 3.13 with recurse_symlinks=True: A C2b result containing both expected paths to the same file would confirm traversal through the alias. If that interpreter was unavailable, the decision for it would be RERUN.
Cycle and negative controls: If the default cycle case finishes with one file and the no-match case exits successfully with empty output, both controls support acceptance.
If all required cases meet those conditions, ACCEPT applies to the tested interpreter and policy. A Python 3.11 or 3.12 baseline cannot establish the result of the Python 3.13+ comparison. Environments that require symlink traversal need the explicit parameter or an alternative search method. Rerun the protocol after a patch or platform change.
14. Connect the skills to Refonte Learning
This systematic approach mirrors the applied testing and troubleshooting skills in professional system administration. For example, Refonte Learning’s System Administration Program (a six-month, part-time curriculum) covers many of the competencies needed here: creating isolated test environments, using shell and Python tools, and verifying system state. The program explicitly teaches areas like system installation and configuration, networking, virtualization, backup and recovery. These skills underpin reliable test fixture management. While the program page does not list pathlib or globbing by name, the general emphasis on hands-on labs and troubleshooting parallels our process of building controlled fixtures and interpreting results.
These exercises build skills relevant to system administrators, network administrators and IT support specialists. Graduates of the program earn training and internship certificates. Writing a test, checking the result against the documentation and tracing each path back to a known file put those troubleshooting skills into practice.