Separating Snapshot Capture from Receiver Integrity
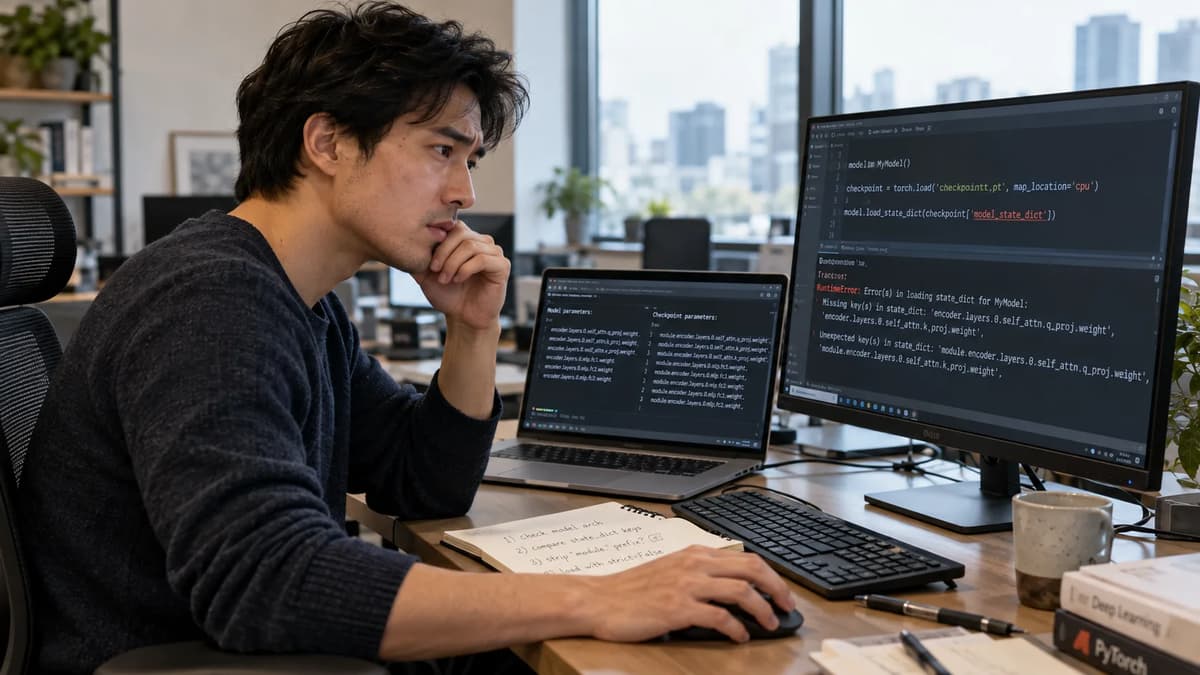
In ML pipelines, deploying a model usually involves loading saved weights and buffers into a torch.nn.Module via its load_state_dict() method. When this method raises an error (for example, due to missing keys or shape mismatches), an engineer faces a key operational question: what is the state of the receiving model object at that point? Has the model been partially updated, or does it remain in its prior state? This inquiry is distinct from choosing which checkpoint to use (see the Refonte Learning discussion on preserving a selected checkpoint snapshot). Here, we focus on the in-memory model instance and trace exactly how its parameters and buffers have been affected before the error propagates to the caller.
Notably, PyTorch’s Module.load_state_dict copies parameters and buffers in place from the provided state dict into the model with assign=False and tensor swapping disabled. With strict=True (the default) it requires the state dict’s keys to exactly match the model’s own keys, otherwise raising a RuntimeError. On normal return, the result contains lists of missing and unexpected keys; a raised exception does not also return that result. This behavior is longstanding and forms the context for our analysis: neither catching the error nor simply running a forward pass necessarily guarantees that the model’s state satisfies its previous contract.
We will explore this in a controlled CPU setting using PyTorch 2.5.1 and Python 3.12, showing when to reject or preserve a model after a load_state_dict failure.
Market Context: Partial Loading in Production
In production ML services, model initialization is often wrapped in exception handlers that catch load errors. The real question for platform engineers is whether a model object that survived an exception still “looks” exactly like it did before the load attempt. A mere absence of an exception or a successful forward computation does not prove that the model’s state is unchanged. Instead, we must verify its tensors against an independent baseline of expected values. As a precaution, this verification step is separate from selecting and preserving a “best” checkpoint snapshot.
In code, one should isolate the load attempt, check for both explicit errors and any mutated state, and only then accept or reject the new state. In what follows, we build an executable fixture to demonstrate these principles in practice, enabling platform engineers to reproduce and reason about each scenario.
Fix the runtime and define two state manifests
The fixture is designed to run under Python 3.12 with PyTorch CPU build version 2.5.1 (latest in the 2.5 line). Swapping of module tensors on conversion is explicitly disabled, and we fix the number of threads to 1 for determinism. We define a simple linear probe model Probe with float32 parameters left, right and a persistent buffer offset on CPU. This model’s forward is left*x + right + offset. We use two sets of hand-authored values: a baseline state (left=1.0, right=2.0, offset=3.0) yielding output 9.0 when input is 4.0; and a candidate state (left=10.0, right=20.0, offset=30.0) yielding output 90.0.
Each parameter/buffer is a one-element tensor (shape=(1,)). As a technical precaution, the baseline is recorded as a plain Python dictionary of lists of floats (not a state_dict) and observations are stored as plain Python lists. This ensures that any future in-place mutation to the model cannot retroactively alter our logged evidence (see independent checkpoint-state evidence for context on owning independent state copies). All expected values are encoded as independent Python lists in literal tables, so the fixture will never overwrite its own expectations with the receiver’s post-load values. This separation of concerns is key to verifying receiver state without self-fulfilling assumptions.
Run the complete receiver-state fixture
We now present the full program (in one block) that automates the nine test cases of loading payloads into fresh Probe instances. It systematically records, in JSON, the model’s state before loading, the contents of the payload (as a ledger of tensors), any error or missing/unexpected keys, the after state of the model, and the model’s output. The main nine-case matrix uses strict=True for six cases and strict=False for three controls. It later replays every payload with strict=True in isolation mode to qualify candidates. The code prints a JSON report with a status field rather than producing a separate “PASS” file; it exits with a nonzero status if any expectation fails. The outcomes discussed below are authored expectations that a completed fixture run must check.
import hashlib
import json
import platform
import sys
import uuid
from datetime import datetime, timezone
from pathlib import Path

BASELINE = {"left": [1.0], "right": [2.0], "offset": [3.0]}
CANDIDATE = {"left": [10.0], "right": [20.0], "offset": [30.0]}

def require(condition, message):
    if not condition:
        raise RuntimeError(message)

def expected(values):
    return {
        name: {"shape": [1], "dtype": "torch.float32",
               "device": "cpu", "values": list(items)}
        for name, items in values.items()
    }

def run(report):
    import torch

    report["environment"] = {
        "python": sys.version,
        "torch": torch.__version__,
        "torch_git": torch.version.git_version,
        "platform": platform.platform(),
        "fixture_sha256": hashlib.sha256(
            Path(__file__).read_bytes()
        ).hexdigest(),
        "device": "cpu", "dtype": "float32", "assign": False,
    }
    require(torch.__version__.split("+")[0] == "2.5.1", "Use PyTorch 2.5.1")
    require(torch.version.cuda is None, "Use the CPU build")
    torch.__future__.set_swap_module_params_on_conversion(False)
    require(not torch.__future__.get_swap_module_params_on_conversion(),
            "Tensor swapping must be disabled")
    torch.set_num_threads(1)
    report["environment"]["swap_module_params"] = False
    report["environment"]["threads"] = torch.get_num_threads()

    class Probe(torch.nn.Module):
        def init(self):
            super().__init__()
            self.left = torch.nn.Parameter(
                torch.tensor([1.0], dtype=torch.float32, device="cpu")
            )
            self.right = torch.nn.Parameter(
                torch.tensor([2.0], dtype=torch.float32, device="cpu")
            )
            self.register_buffer(
                "offset", torch.tensor([3.0], dtype=torch.float32, device="cpu")
            )

        def forward(self, x):
            return self.left  x + self.right + self.offset

    def tensors(values, dtype=torch.float32):
        return {name: torch.tensor(items, dtype=dtype, device="cpu")
                for name, items in values.items()}

    def ledger(state):
        return {
            name: {"shape": list(value.shape), "dtype": str(value.dtype),
                   "device": str(value.device),
                   "values": value.detach().cpu().tolist()}
            for name, value in state.items()
        }

    def observe(model, payload, strict):
        before = ledger(model.state_dict())
        record = {"strict": strict, "assign": False, "before": before,
                  "payload": ledger(payload), "error": None,
                  "missing_keys": None, "unexpected_keys": None}
        try:
            result = model.load_state_dict(payload, strict=strict, assign=False)
            record["missing_keys"] = sorted(result.missing_keys)
            record["unexpected_keys"] = sorted(result.unexpected_keys)
        except RuntimeError as exc:
            record["error"] = {"type": type(exc).__name__, "message": str(exc)}
        record["after"] = ledger(model.state_dict())
        record["changed_keys"] = sorted(
            key for key in before if before[key] != record["after"][key]
        )
        with torch.no_grad():
            record["output"] = model(
                torch.tensor([4.0], dtype=torch.float32, device="cpu")
            ).tolist()
        return record

    # Literal expectations are independent of the receiver and loader result.
    cases = [
        # name, payload dict, strict, error category, missing, unexpected,
        # expected state, expected output
        ("complete", CANDIDATE, True, None, [], [],
         {"left": [10.0], "right": [20.0], "offset": [30.0]}, [90.0]),
        ("missing_right", {"left": [10.0], "offset": [30.0]}, True,
         "Missing key(s)", None, None,
         {"left": [10.0], "right": [2.0], "offset": [30.0]}, [72.0]),
        ("wrong_right_shape", {"left": [10.0], "right": [20.0, 21.0],
                               "offset": [30.0]}, True,
         "size mismatch", None, None,
         {"left": [10.0], "right": [2.0], "offset": [30.0]}, [72.0]),
        ("wrong_first_shape", {"left": [10.0, 11.0], "right": [20.0],
                               "offset": [30.0]}, True,
         "size mismatch", None, None,
         {"left": [1.0], "right": [20.0], "offset": [30.0]}, [54.0]),
        ("unexpected_key", {*CANDIDATE, "rogue": [99.0]}, True,
         "Unexpected key(s)", None, None,
         {"left": [10.0], "right": [20.0], "offset": [30.0]}, [90.0]),
        ("missing_permissive", {"left": [10.0], "offset": [30.0]}, False,
         None, ["right"], [],
         {"left": [10.0], "right": [2.0], "offset": [30.0]}, [72.0]),
        ("shape_permissive", {"left": [10.0], "right": [20.0, 21.0],
                              "offset": [30.0]}, False,
         "size mismatch", None, None,
         {"left": [10.0], "right": [2.0], "offset": [30.0]}, [72.0]),
        ("no_matching_keys", {"rogue": [99.0]}, True,
         "Missing key(s)", None, None,
         {"left": [1.0], "right": [2.0], "offset": [3.0]}, [9.0]),
        ("empty_permissive", {}, False, None,
         ["left", "offset", "right"], [],
         {"left": [1.0], "right": [2.0], "offset": [3.0]}, [9.0]),
    ]
    report["stage"] = "receiver_matrix"
    for (name, values, strict, category, missing, unexpected,
         state, output) in cases:
        row = observe(Probe(), tensors(values), strict)
        row["case"] = name
        report["cases"].append(row)
        require(row["before"] == expected(BASELINE), name + ": bad baseline")
        require(row["after"] == expected(state),
                name + ": unexpected receiver state")
        require(row["output"] == output, name + ": unexpected output")
        changed = sorted(key for key in BASELINE if BASELINE[key] != state[key])
        require(row["changed_keys"] == changed,
                name + ": wrong mutation ledger")
        if category is None:
            require(row["error"] is None, name + ": unexpected exception")
            require(row["missing_keys"] == missing,
                    name + ": missing-key mismatch")
            require(row["unexpected_keys"] == unexpected,
                    name + ": extra-key mismatch")
        else:
            require(row["error"] is not None,
                    name + ": expected exception absent")
            require(category in row["error"]["message"],
                    name + ": wrong error category")
        if name == "no_matching_keys":
            require("Unexpected key(s)" in row["error"]["message"],
                    "No-match control must retain both key-error categories")

    approved = Probe()
    old_reference = approved
    report["stage"] = "candidate_isolation"
    report["gates"] = []

    def qualify(name, payload):
        disposable = Probe()
        row = observe(disposable, payload, True)
        row["case"] = name
        row["accepted"] = (
            row["error"] is None
            and row["missing_keys"] == []
            and row["unexpected_keys"] == []
            and row["payload"] == expected(CANDIDATE)
            and row["after"] == expected(CANDIDATE)
            and row["output"] == [90.0]
        )
        row["approved_unchanged"] = (
            ledger(approved.state_dict()) == expected(BASELINE)
        )
        report["gates"].append(row)
        require(row["approved_unchanged"],
                name + ": approved model was modified")
        return disposable if row["accepted"] else None

    for name, values, *_ in cases:
        candidate = qualify(name, tensors(values))
        require((candidate is not None) == (name == "complete"),
                name + ": incorrect complete-restoration decision")
    wrong_value = {"left": [10.0], "right": [20.0], "offset": [31.0]}
    require(qualify("wrong_value", tensors(wrong_value)) is None,
            "Value mismatch escaped the gate")
    require(qualify("wrong_source_dtype",
                    tensors(CANDIDATE, torch.float64)) is None,
            "Source dtype mismatch escaped the declared no-cast policy")

    accepted = qualify("handoff_complete", tensors(CANDIDATE))
    require(accepted is not None, "No complete candidate available for handoff")
    report["stage"] = "single_owner_handoff"
    approved = accepted
    require(approved is not old_reference, "Handoff reused the previous object")
    require(ledger(old_reference.state_dict()) == expected(BASELINE),
            "Old reference changed during handoff")
    require(ledger(approved.state_dict()) == expected(CANDIDATE),
            "Handoff did not select the candidate")
    report["handoff"] = {"old": ledger(old_reference.state_dict()),
                         "current": ledger(approved.state_dict())}
    report["status"] = "PASS"
    report["stage"] = "complete"

if name == "__main__":
    report = {"run_id": str(uuid.uuid4()),
              "started_utc": datetime.now(timezone.utc).isoformat(),
              "status": "FAIL", "stage": "environment", "cases": []}
    try:
        run(report)
    except Exception as exc:
        report["failure"] = {"type": type(exc).__name__, "message": str(exc)}
    print(json.dumps(report, indent=2, allow_nan=False))
    sys.exit(0 if report["status"] == "PASS" else 1)
Keep every expectation outside the receiving model
The fixture’s table of expected states and outputs is defined outside any model instance. We never derive expectations from the model under test. Instead we use literal dictionaries (BASELINE, CANDIDATE) and compute expected numeric results (9 and 90) in advance. During each case, the code snapshots the model’s state_dict() before loading and compares it against the precomputed baseline. After the load (or error), it snapshots again. The test then requires that the “after” state exactly matches our independent expected values. In other words, we treat the receiver as a black box and verify its behavior.
If any check fails (mismatched state keys, wrong output, or unexpected error), the fixture reports failure. Importantly, the fixture never overwrites its expected values with the contents of the model; it only checks them. Any load error remains evidence of a rejected load attempt; observing the receiver does not turn that failure into acceptance. The strict comparison of outputs and state enforces the contract that a fully-qualified load must exactly restore the candidate state.
Inspecting the model after a shape-mismatch error
Consider the case "wrong_right_shape", where the fixture converts these payload values to tensors: {"left":[10.0], "right":[20.0,21.0], "offset":[30.0]}. Before loading, the model’s left, right, and offset were 1.0, 2.0, 3.0. The payload’s right tensor has shape (2,) instead of (1,), so a RuntimeError is expected. The expected result is a RuntimeError from load_state_dict, but the shape mismatch does not stop all copying immediately. By design (and by inspection of PyTorch’s code), left is copied before the shape check fails on right, and the compatible offset buffer is still copied afterward, before the accumulated error is raised.
The expected record shows that left became 10.0 and offset became 30.0, while right remained at its original 2.0. Consequently, the model’s output is 10*4 + 2 + 30 = 72.0, not the nominal 90.0. The expected log entries for this case include the RuntimeError message (mentioning a size mismatch) and the list of changed keys ["left","offset"]. This confirms that even after an error, the model contains partial updates: it is “contaminated” by some new values. In code, we capture the full exception message and ledger of before/after state so that we know exactly what survived the load attempt.
We do not continue using this model simply because it still produces an output; it is in a mixed state.
Verify that later compatible tensors can still change
It might be tempting to assume that loading stops at the first incompatible key. However, the implementation (in PyTorch 2.5) suggests that load proceeds through all submodules and parameters, collecting any shape or missing-key errors along the way, and then raises a combined exception at the end. To illustrate, look at the "wrong_first_shape" case: the payload has left with shape (2,), which mismatches, but right and offset tensors are shape-compatible. After load, the fixture expects left to stay at 1.0 (unchanged), but right to become 20.0 and offset to become 30.0.
The final output is 54.0 (1*4 + 20 + 30). If load had stopped immediately when seeing the bad left, we would have expected right and offset to remain at 2.0 and 3.0, yielding output 9.0. This is the expected evidence that loading continued past the first error. We attribute this to PyTorch’s recursive loading logic: it accumulates the shape error and continues to later compatible parameters and persistent buffers before raising. In any case, the takeaway is that subsequent compatible parameters may still change even if an earlier one fails, so one must re-verify all parameters after an exception, not just stop at the first.
Compare missing-key vs unexpected-key errors
Next we contrast two similar failures. In "missing_right", the payload omits right, so with strict=True a missing-key error is reported. The loader still copied left=10.0 and offset=30.0 (output 72.0), and the model’s state shows those changes and right still 2.0. In "unexpected_key", the payload includes an extra key "rogue": [99.0]. Here, all three model keys match some payload (left, right, offset) and are compatible, so they all load successfully to 10.0, 20.0, 30.0 (output 90.0). Only after completing the copies does PyTorch notice the extra "rogue" key and raise a RuntimeError about unexpected keys.
The end state is the fully updated model (state as if load succeeded) but still with an exception. If one only looked at the final output (90.0), one might wrongly assume everything loaded correctly. Instead, we record both the changed_keys and the error. In the unexpected_key case we deliberately keep the rogue entry in our evidence (payload ledger), to show that the payload itself was structurally mismatched. This case reaffirms: a model’s forward output being correct does not waive the error. We still reject this load because of the unexpected-key violation, even though the math happens to work out.
Strict=False: What it changes and preserves
The key policy of strict=False (non-strict loading) is documented for transfer learning scenarios. With strict=False, missing and unexpected keys do not by themselves cause an exception; a normal return reports these lists. In our "missing_permissive" case (payload missing right, strict=False), load_state_dict returns normally (no RuntimeError) and reports missing_keys=['right']. It still copied left=10.0 and offset=30.0 (output 72.0), leaving right unchanged. Thus it acted similarly to the strict case, except without throwing an exception. By contrast, if an existing tensor is incompatible, a size mismatch still raises an error even with strict=False; see "shape_permissive".
The right payload shape (2,) causes an exception, and left and offset remain at 10.0 and 30.0, yielding output 72.0 as before. This shows that in the current loader logic, strict=False suppresses missing-key and unexpected-key errors, but it does not suppress size mismatches. In any case, partial loading (ignoring missing keys) is an intentional workflow for transfer learning (warming up a model with available weights). However, our goal here is a full restoration contract: we will not consider a load acceptable merely because strict=False avoids an exception.
Reject an empty successful return as full restoration
As a final non-exception case, the payload {} (empty dict) with strict=False returns normally, and the fixture records the sorted list missing_keys=['left','offset','right']. The model’s state is untouched (still 1,2,3) and output 9.0. A naive “no exception means loaded” check would miss that nothing was actually loaded. We explicitly require that the state contains the newly intended values, not just that load_state_dict returned successfully. In our qualification logic (later), even the empty payload fails because the missing keys indicate an incomplete restoration. We always use strict=True when deciding whether to accept a candidate, so this permissive success case is ultimately rejected.
In practice, one should never interpret a silent load_state_dict return as proof of successful loading; always inspect the populated missing_keys and ensure all critical keys are present.
An exception can leave state unchanged
It is also possible for load_state_dict to raise an error without mutating the model at all. The "no_matching_keys" case demonstrates this: we provide a payload with only an unrelated key ("rogue"). Since none of the model’s parameters match the payload, no copies are made. The method raises RuntimeError listing both missing and unexpected keys. Critically, the model’s state remains at the baseline (1.0, 2.0, 3.0) with output 9.0 unchanged. The fixture’s nine-case matrix records the final status (error or not), which keys changed, the model’s after-state, and the output for each payload.
This counterexample (“no_matching_keys”) proves that an error does not universally imply contamination; it depends on what happened during loading. However, this also does not make a rejected payload acceptable. It means that this particular payload left the measured parameters and buffer unchanged. Each case must be checked individually, and an error of any kind means full restoration failed, even if state looks intact by coincidence.
Isolate qualification: keep approved model unchanged
In an operational setting, we designate one Module instance as the approved model that the service will use. All candidate state_dicts must be tested in isolation so as not to pollute the approved instance. Our strategy is to create a fresh Probe() for each attempt. The function qualify() loads a payload into a temporary model and records the results. Crucially, after every load attempt we compare the approved instance’s state against its original baseline. We enforce that the approved model was not modified during any qualification (row["approved_unchanged"]). In other words, the isolation is achieved by simply not applying the payload to the real model object.
If a payload fails any check, we discard that candidate and the temporary model. The only time we let a state affect the approved model is at the very end: we then “handoff” by replacing the reference to the approved model with the qualified copy. Rebinding approved selects the qualified new object; existing references such as old_reference remain attached to the original object after the handoff. This is purely a single-owner reference handoff pattern; there is no transaction or atomicity in load_state_dict. We rely on Python object ownership: a failed load may have “dirtied” the temp model, but because it was used only for qualification, we discard it if its checks fail. The original approved object retains its baseline tensors, while approved is rebound only after a candidate passes.
Admit only the complete fresh candidate
In our logic, only the "complete" case (strict=True, no errors, no missing/unexpected) yields accepted=True. All other payloads, including "unexpected_key" and those used in the strict=False controls, are rejected when replayed with strict=True: accepted=False, and qualify() returns None. This enforces a full-restoration gate: we will not hand off any candidate unless the model’s parameters and persistent buffer exactly match the intended candidate manifest. We explicitly check the output equals 90.0, the payload ledger equals the expected candidate manifest, and the after-state ledger matches the candidate. For example, if the payload had the correct keys but an incorrect offset value ([31.0]), we detect that the after ledger differs from expected, and we reject it.
Likewise, if payload tensors are float64 instead of float32, PyTorch would silently cast them into the model (with assign=False preserving the receiver’s tensor properties and tensor swapping separately disabled), but that would violate our declared no-cast policy. Hence we also reject any dtype mismatch. These controls are stricter than PyTorch’s general behavior; we treat any deviation from the manifest as cause to not accept.
Reject value and dtype mismatches after structural load
In further qualification, we test two extra controls. A payload that structurally matches (all keys and shapes correct) but has even one wrong value must fail. For example, {"left":[10.0], "right":[20.0], "offset":[31.0]} (offset should be 30). The temp model loads 10,20,31 (with output 91.0) and returns no exception, but our fixture compares this to the expected offset=30 and finds a discrepancy. The qualification gate rejects it. The require check passes only when qualify returns None; otherwise it raises “Value mismatch escaped the gate”. We also test dtype: passing float64 tensors would normally be accepted by PyTorch (converted to float32 inside), but since our policy is no casting, we reject a candidate whose source dtype doesn’t match the model’s.
Thus, even after a successful structural load, we do not blindly accept; we compare every ledger entry (dtype, shape, values) to our canonical candidate manifest. (Recall that the torch.equal comparison by itself can report two finite tensors equal even if dtypes differ, and it treats NaNs specially, so we do explicit checks instead.)
Recovering a receiver whose state changed
If we discover that our approved model instance has somehow been partially updated (e.g. from an uncaught load path), the recovery is simple: stop using that instance, and build a fresh one. The steps are: note down the exception and captured ledger, then create a new Probe, load the last-known-good state into it (using the verified complete candidate or baseline), and re-verify as above. Only after all checks pass do we replace the service’s reference. Importantly, we do not attempt an in-place rollback of the original model; instead we discard it and use a newly loaded model.
This is because reloading can itself fail, and it does not automatically restore aspects like optimizer state or RNG. In practice, a failed load invalidates the previous guarantee of state; even if a later non-strict load or a forward run yields an output, it does not magically reconstruct what was lost.
Define release criteria and stop conditions
The final decision depends on a compact logical matrix of criteria. In brief: Reject any payload if strict loading does not perfectly match the expected state. Discard any candidate whose load or manifest checks failed, including receivers changed by rejected payloads. Retain the approved instance only if it remains identical to the baseline (no unexpected mutation). Rebuild from a verified state whenever needed: if the approved instance is suspected, we construct a fresh model and load the known-good parameters into it. Accept a new model only when a candidate fully satisfies all checks under strict=True.
In practice, the fixture would abort qualification if something unexpected occurs: for example, if the state, output, or expected error category deviates from our literal expectations, or if any stage of the test did not run. We record a run ID, source hash, environment details, the pre/post ledgers for all 9 cases, and the qualification gates. These form the audit trail. An incomplete observation or a PyTorch version or CPU-build mismatch is treated as a stop condition. Review the recorded Python version against the declared environment as well; the fixture records it but does not enforce its version.
The status only reports PASS when all conditions meet our strict criteria; no claim about model performance or accuracy is made at this point.
Separate the loading gate from serving-mode validation
It is important to note that passing these load tests only demonstrates correct parameter loading. It does not verify any aspects of model serving such as eval/train mode, batchnorm/bias behavior, input preprocessing, calibration or inference throughput. Those are separate contracts. For example, turning on model.eval() or hooking up preprocessing pipelines must be validated independently (see Refonte’s guide to PyTorch evaluation and inference modes). This loading gate is purely about state correctness. In a real deployment, one should still follow normal production checks (unit tests, accuracy evaluation, hardware considerations, concurrency) before declaring a new model live.
Assigning ownership and monitoring changes
We recommend clear division of responsibility in the workflow. The model maintainer (e.g. data science team) owns the checkpoint payloads; the service maintainer owns the model instance running in the application; and the reviewer (QA/DevOps) examines the evidence. This division of responsibility fits the broader MLOps roles described by Refonte Learning. Whenever the PyTorch version, model code, dtype policies, hooks, loading arguments, or deployment mechanism changes, the entire validation fixture should be re-run and its results reviewed. If a change yields different results, do not alter the expected state silently.
Instead, keep the old record for audit (“separate branches” if necessary) and investigate. The log and manifest should make it easy for another engineer to spot differences.
Building a foundation for careful PyTorch engineering
The lesson is that robust ML systems require verifying even the simplest steps. The load_state_dict API does not magically roll back on failure; parts of the model can and do change on a partial load. Engineers must therefore validate the post-load state with tests like these. For readers seeking to improve their PyTorch engineering skills, Refonte Learning offers an AI Engineering curriculum covering model development, training, deployment, evaluation, and scaling. By building on verified PyTorch semantics and model-development fundamentals (as illustrated here), you can move beyond black-box assumptions and ensure integrity at every step of your ML pipeline.