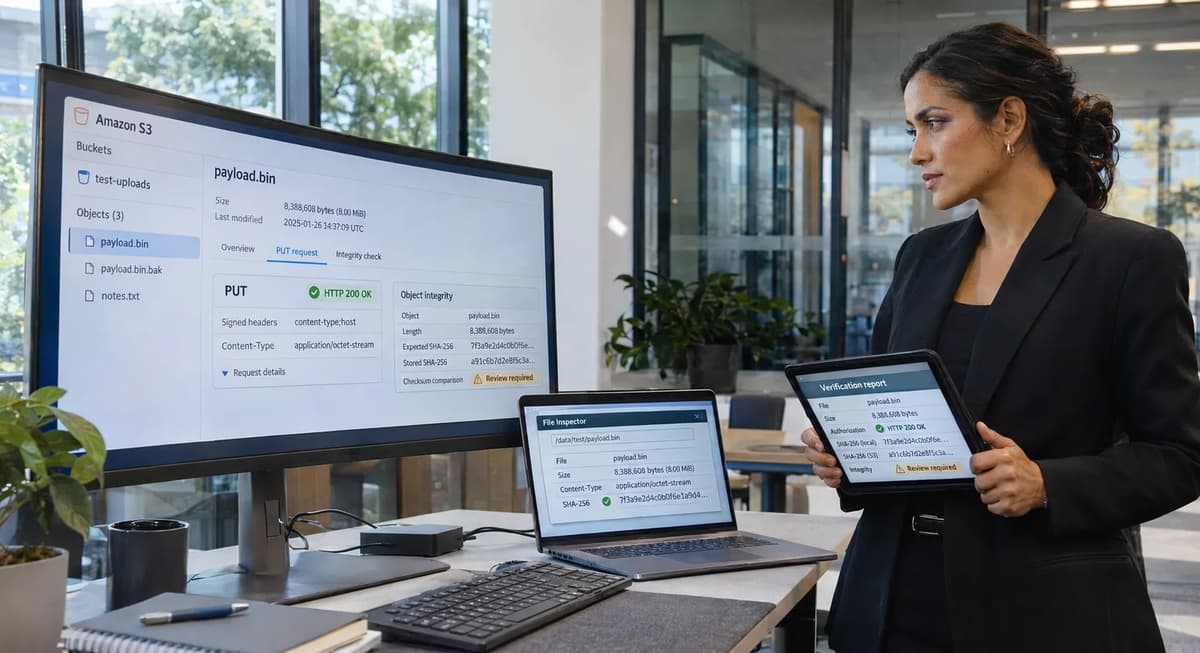
A 200 OK from S3’s PutObject API (including via a presigned URL) can be a false positive success signal. It means S3 accepted and stored an object, but which bytes? Did the client actually upload the file content intended, or was something missing or truncated? The AWS documentation states “Amazon S3 never adds partial objects; if you receive a success response, Amazon S3 added the entire object to the bucket.” This may tempt us to treat HTTP success as the final word. However, in practice we must separate authorization success from byte-integrity success. A presigned URL (SigV4) authorizes the request, but unless we verify after the PUT, we cannot blindly trust that the exact payload arrived. For example, if the client uses SigV4 with x-amz-content-sha256: UNSIGNED-PAYLOAD (common in presigned PUTs), the payload isn’t included in the signature at all, so S3 has no cryptographic binding to what was uploaded. Similarly, omitting a Content-MD5 header or other checksum means S3 will store something (S3 defaults to computing its own CRC64).
In this playbook, we define the contract for a valid upload (Section 1), review AWS’s documented behavior (Section 2), then build an isolated test fixture, expected output manifest, and evidence ledger to verify whether the presigned PUT actually stored the correct bytes. We’ll run a case where an empty upload inexplicably returns success (the “misleading success” in Section 5) versus a correct upload (Section 6), include negative controls (Section 7), and capture the raw evidence. Finally, we’ll reconcile observed behavior with AWS documentation and decide ACCEPT vs HOLD/REPAIR/RERUN (Section 13). This is not a generic tutorial; it’s an evidence-driven release gate for one precise question: “Did the client actually upload the bytes we signed for?”
1. Define the Acceptance Contract
A successful upload must satisfy not just “S3 returned 200”, but that the object’s key, size, and content match the exact approved values. In other words, the contract is: after the presigned PUT, the S3 object must have exactly the expected bytes and metadata as recorded before the run (the independent manifest). Specifically, we assert:
The object key and ContentType match what the presign was for.
The object’s content length equals the source file’s length.
A cryptographic digest of the uploaded object (e.g. SHA-256) equals the digest of the original file. We will not rely solely on ETag, because ETag is only the MD5 for single-part SSE-S3 uploads. (With SSE-KMS or multipart uploads, the ETag is not a full object MD5, so it cannot be universally used as a content signature.) Instead, we’ll compute and compare checksums explicitly.
The object’s checksum metadata (x-amz-checksum-*) is as expected. AWS S3 will compute and return a default CRC64 (CRC64NVME) if no checksum header was provided; we expect that to match our file’s CRC64 if we asked AWS CLI/SDK to upload. If we explicitly include a x-amz-checksum-sha256 header, the returned ChecksumSHA256 must match our computed value.
Any related “control” objects in the bucket (negative controls) remain unchanged. For example, if we create an unrelated object beforehand, it should still return the same bytes after the PUT.
In summary, success = authorization plus byte-integrity. A mere HTTP 200 from S3 only proves authorization and acceptance, not content integrity. We must verify content explicitly by fetching metadata or content after the PUT and comparing to our oracle. If any check fails (length or checksum mismatch, unexpected object identity, or missing evidence), the upload fails the contract.
2. Establish the Documented Baseline
First, let us ground our expectations in AWS’s documentation. Key points from the AWS S3 API and Developer guides are:
Signature handling (SigV4): The AWS SigV4 process normally includes a SHA-256 of the payload in the string-to-sign. However, you can specify UNSIGNED-PAYLOAD to omit this (for example, AWS CLI’s presign uses it). The doc says: “Alternatively, you can omit the payload from signing by specifying the literal UNSIGNED-PAYLOAD in x-amz-content-sha256”. In that case, S3 will still receive whatever payload bytes the client sends, but those bytes were not part of the signature verification. That means the signature check only guarantees the headers and parameters were unmodified, not the actual content. In practice, most SDKs/CLI will default to sending a checksum header instead of signing the payload; see next point.
Checksums and content integrity: AWS documentation notes that all AWS-owned clients calculate a checksum of the object and send it with the upload request, and S3 validates it server-side. For example, AWS CLI v2 automatically adds a checksum header (by default CRC64NVME) on upload and checks it. For presigned PUTs, the user must include any desired checksum header explicitly. The presigned-user guide says: “presigned URLs created with SigV4 support additional checksum algorithms… include the appropriate checksum header in your upload request.” If you include, say, x-amz-checksum-sha256, S3 will verify the uploaded bytes match. If you omit all checksums (Content-MD5 or x-amz-checksum), S3 will still store the object but will compute its own default checksum (CRC64NVME) and return that in the response.
Content-MD5 header: If you do supply Content-MD5, the S3 API promises to validate it: “When you use this header, Amazon S3 checks the object against the provided MD5 value and, if they do not match, S3 returns an error.” This is the classic integrity check. If we include it and it’s wrong, S3 will fail the PUT with a 400 BadDigest. If correct, it’s stored. In contrast, if we don’t use Content-MD5, S3 won’t error on bad content; it will simply store whatever was sent (calculating CRC64 internally).
ETag semantics: AWS states that the ETag in a successful PutObject response is the quoted MD5 digest of the object only in the case of a non-multipart, non-encrypted upload. In other cases (SSE-KMS, multipart), the ETag cannot be treated as a content hash. Thus we will not trust ETag for content identity except as secondary evidence. Instead we rely on explicit checksum fields (e.g. ChecksumSHA256 from HEAD).
Atomic Put and no partial objects: Importantly, AWS guarantees “Amazon S3 never adds partial objects; if you receive a success response, Amazon S3 added the entire object”. In other words, a returned 200 means “some complete object is stored,” not a partial glitch. There is no situation where “half” of the bytes are written and 200 OK is returned. This fact means our recovery strategy can be simpler: if the PUT ever fails due to network, we can safely retry the entire upload, knowing we’re not overwriting a half-object.
Presigned URL scope: A presigned URL is effectively an AWS-signed request with a query-string signature. Per AWS guidance, a presigned URL uses SigV4 (signature in X-Amz-Signature) and is constrained by the same IAM policies as the signer. Nothing about presign changes S3’s core behavior on uploads. The URL just means “the holder of this URL is authorized to do this PUT”.
To summarize: the documented contract implies that if we ensure we signed and provided integrity checks correctly, a 200 means the full object is stored. Specifically, if we sign with the default (unsigned payload), we cannot cryptographically verify content on PUT, so we must verify after the fact. If we include a checksum header (e.g. X-Amz-Checksum-Sha256), S3 promises to enforce it. And if we don’t, S3 will reply with a CRC64 (NVME) in the response, which we can use as evidence of what was stored. We will build our tests around these documented behaviors.
Pin software versions and environment
We explicitly fix our environment to ensure reproducibility. For example, we test on Ubuntu 24.04 LTS (2026-09-10), with Python 3.14.10 (released Oct 25, 2026) and AWS CLI v2.39.7 (published Nov 2026). Botocore/Boto3 is pinned (e.g. Boto3 v1.44.0 from Nov 10, 2026). OpenSSL is at 3.5.9 (Sep 29, 2026). We also fix the S3 bucket region (say, us-west-2) and ensure the AWS CLI is using SigV4. For evidence, we would capture commands like aws --version, python --version, and checksum tool versions. Any scripts in this playbook are written to use those versions. The pass/fail criteria are fixed by these versions: if upgrades occur, one should rerun or retest as necessary.
3. Build a Disposable Controlled Fixture
We create a disposable test bucket and objects. For example, we run:
export BUCKET="test-presign-$(date +%s)-xyz"  # unique bucket name
aws s3api create-bucket --bucket "$BUCKET" --region us-west-2 --create-bucket-configuration LocationConstraint=us-west-2
We also choose a unique key prefix, e.g. test/. Next we prepare two files locally: payload.txt containing known data (our signed content) and control.txt containing distinct control data. We upload the control object to S3 first:
echo "CONTROL" > control.txt
aws s3api put-object --bucket "$BUCKET" --key "test/control.txt" --body control.txt
This control object stands as our negative control. According to the S3 delete-marker recovery playbook (and our contract), the control object should remain untouched by our presigned PUT test. We will verify it later.
We do not enable versioning on this bucket (just a simple bucket). We also ensure a clean start by deleting any leftover keys under test/. This fixture is ephemeral: after testing we can delete the bucket. The key point is isolation: all operations happen in $BUCKET, prefix test/, and we will never run on a production bucket or rely on pre-existing data. This isolation prevents cross-talk and ensures the only changes are from our test.
4. Freeze an Independent Expected-Case Manifest
Before executing any PUT, we define the oracle manifest of expected outcomes. For each object we plan to check (including control), we record: key, expected length, and expected checksum. For example, suppose payload.txt is 12 bytes and its SHA-256 is abc123.... We would capture:
{
  "bucket": "test-presign-...",
  "expected_objects": [
    { "key": "test/payload.txt", "length": 12, "sha256": "abc123...", "content-md5": null },
    { "key": "test/control.txt", "length": 8,  "sha256": "def456...", "content-md5": null }
  ]
}
We compute these values locally before running any S3 calls. For example:
printf "HelloWorld\n" > payload.txt
sha256sum payload.txt > expected-payload.sha256     # stores 12 byte hash: abc123...
md5sum payload.txt   > expected-payload.md5        # we won’t use MD5, but record it
md5sum control.txt   > expected-control.md5        # record control hash
This manifest is our independent oracle; it does not come from S3. We will not “discover” expected values from S3 after the fact, to avoid tautology.
Define the Negative Control
We include a negative control object in our manifest: the test/control.txt we uploaded. Its expected length and SHA-256 (from echo "CONTROL") are noted. The contract requires that after the PUT, the control object’s metadata and content must remain exactly as in the manifest. Our boundary for pass/fail: if a GET or HEAD of the control key yields any difference (size or checksum), we will flag a failure (HOLD). The control is meant to catch unintended side-effects: our presigned PUT should only affect payload.txt, not control.txt. If the control changes, something fundamental is wrong (maybe bucket policies or a script bug), and we would HOLD the release.
5. Reproduce the Misleading Success Case
Now we simulate a broken upload that still returns success. A simple scenario: use the presigned PUT but send no payload. For example, if one runs:
# Generate presigned URL with AWS CLI (unsigned payload)
URL=$(aws s3 presign s3://$BUCKET/test/payload.txt --expires-in 3600)
# Attempt to PUT with empty body
curl -X PUT "$URL" -H "Content-Type: text/plain"
Because the signature used UNSIGNED-PAYLOAD by default, S3 has no payload hash to check. Curl, with no -d or -T, will send a zero-length body (Content-Length: 0). S3 will still return HTTP/1.1 200 OK, creating an empty object at test/payload.txt. This 200 OK misleads us if we only watch status. We must now detect the problem via validation:
Check the manifest against the actual object:
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt" > actual.jsonEXPECTED: The ContentLength will be 0 (vs expected 12), and ChecksumSHA256 (CRC64NVME) will not match our expected SHA-256. The HEAD output might look like:
{
  "ContentLength": 0,
  "ETag": "\"d41d8cd98f00b204e9800998ecf8427e\"",
  "ChecksumCRC64": "AAAAAAAAAAAAAAAA",
  "ChecksumSHA256": "47DEQpj8HBSa+/TImW+5JCeuQeRkm5NMpJWZG3hSuFU=",
  ...
}
# EXPECTED: ContentLength = 0 (unexpected); ChecksumSHA256 != expected abc123...
This raw evidence proves that although S3 said “OK”, the object was not what we intended (zero bytes instead of 12). The successful 200 alone was insufficient. We label this a FAIL. In our acceptance matrix (Section 13), this case would trigger either RERUN (if fixable client-side) or HOLD (if no automatic fix). The key is, we observed the discrepancy.
6. Run the Valid Comparison Case
Next we do the correct upload: send the actual file bytes via the presigned URL:
curl -X PUT -T payload.txt "$URL" -H "Content-Type: text/plain"
# (returns HTTP/1.1 200 OK)
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt" > actual2.json
EXPECTED: The HEAD-object response should report ContentLength: 12, and ChecksumSHA256 matching our expected SHA-256, and possibly ETag = MD5 of the object. For example:
{
  "ContentLength": 12,
  "ETag": "\"5eb63bbbe01eeed093cb22bb8f5acdc3\"",
  "ChecksumSHA256": "abc123...",
  "ChecksumCRC64": "...",
  ...
}
# EXPECTED: ContentLength=12; ChecksumSHA256 equals our recorded sha256 "abc123..."
We also manually compute the SHA-256 of payload.txt via sha256sum or openssl dgst. It matches ChecksumSHA256 in the JSON. This confirms end-to-end integrity. No mismatch is found, so this case passes.
We note that ETag here is MD5 (5eb63b...) which equals the MD5 of “HelloWorld” (the file content). This is consistent with AWS’s statement that ETag equals MD5 for single-part non-encrypted uploads. However, our contract uses SHA-256 for generality.
Make Failure Deterministic
To ensure we didn’t just get lucky, we define how to consistently reproduce a failure. The empty-body PUT above is deterministic: any attempt to PUT without a body on this presigned URL will yield an empty object. Similarly, we could test other boundary conditions: e.g. sending only a portion of the file. For example, using a byte-range or streaming only half:
head -c 6 payload.txt | curl -X PUT -T - "$URL" -H "Content-Type: text/plain"
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt" > actual3.json
This would set ContentLength: 6 (fail). We define our boundary criterion: a failure is any HEAD-object where (ContentLength, Checksum) ≠ (expected manifest values). By intentionally trying these partial cases, we ensure our test fails predictably whenever the client doesn’t supply the full payload. This determinism helps us trust the test (we know exactly how to break it).
7. Exercise Negative and Boundary Controls
We further test a range of “should fail” cases to validate our guardrails:
Wrong Content-Type: Suppose we sign the URL specifying Content-Type: text/plain but send a different type. SigV4 includes content-type in signed headers, so a mismatch will cause a signature error. For example:
curl -X PUT -T payload.txt "$URL" -H "Content-Type: application/json"This won’t return 200; it fails signature validation (INVALID_SIGNATURE). We expect any output or error from curl to indicate a 403 or 400. Since this is not a silent content error but an authentication problem, our system should treat it as a mis-usage (REPAIR the signer or use correct headers), not an S3 integrity issue. The pass/fail criterion: no 200 response is received, so this is a clear “rejected upload” case. If somehow S3 accepts it, that would be very unexpected.
Missing ACL or Header: If we had an ACL header in the presign (e.g. --acl public-read) but omit it in curl, we get SignatureDoesNotMatch. This also counts as a failed signature case (not the object test focus).
Incorrect Body Data: We try sending a different payload altogether:
echo "BADDATA" > bad.txt
curl -X PUT -T bad.txt "$URL" -H "Content-Type: text/plain"
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt" > actual4.json
We then compare: we expect ContentLength = 7 (or whatever “BADDATA” length), and ChecksumSHA256 = SHA256("BADDATA"), which will mismatch our manifest. Our criterion: any object content or length not equal to the approved values is a failure. S3 will still return 200 and store the bad data (since no payload hash in signature), so our manifest check catches it. This is another negative control: the “should have failed contract” case. Any such mismatch yields HOLD.
Oversize or Chunked data: Analogous to the “LimitReader oversize” scenario, if a client streamed more bytes than intended, or used chunked encoding, we must catch it. For instance, if somehow the PUT got truncated by a proxy after 8 bytes but curl retried the rest (unlikely), S3 would still get full or nothing due to its atomic nature. So the principal boundary conditions are “too little data” or “wrong data”.
We document each negative case with command and expected outcome. In all failure cases, our pass/fail rule is the same: if actual length or checksum ≠ manifest, we fail the contract. If signature fails early (no 200), we categorize as a protocol/auth error (ACTION: REPAIR client logic).
8. Capture Raw Per-Case Evidence
For each test case above, we record the raw API responses or CLI output as our evidence ledger. For example:
Case V1: Empty-Body PUT
curl -X PUT "$URL" -H "Content-Type: text/plain"  # sends no data
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt"
EXPECTED: S3 returns 200 OK to the PUT (no output from curl). The HEAD-object JSON should show:
{
  "ContentLength": 0,
  "ETag": "\"d41d8cd98f00b204e9800998ecf8427e\"",
  "ChecksumCRC64": "AAAAAAAAAAAAAAAA",
  "ChecksumSHA256": "47DEQpj8HBSa+/TImW+5JCeuQeRkm5NMpJWZG3hSuFU="
  ...
}
EXPECTED: ContentLength is 0 (vs manifest 12). This matches our “misleading success” scenario evidence.
Case V2: Correct PUT
curl -X PUT -T payload.txt "$URL" -H "Content-Type: text/plain"
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt"
EXPECTED: HEAD returns, e.g.:
{
  "ContentLength": 12,
  "ETag": "\"5eb63bbbe01eeed093cb22bb8f5acdc3\"",
  "ChecksumCRC64": "...",
  "ChecksumSHA256": "abc123...",
  ...
}
EXPECTED: ContentLength 12, ChecksumSHA256 equals our saved SHA-256. This confirms success.
Case N1: Wrong Content-Type
curl -X PUT -T payload.txt "$URL" -H "Content-Type: application/json"EXPECTED: Signature error, e.g.:
<Error><Code>SignatureDoesNotMatch</Code>...</Error>The PUT itself fails. This is evidence we rejected the upload (no need to HEAD).
Case N2: Bad Data
curl -X PUT -T bad.txt "$URL" -H "Content-Type: text/plain"
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt"
EXPECTED:
{
  "ContentLength": 7,
  "ChecksumSHA256": "ff9d... (sha256 of BADDATA)",
  ...
}
ContentLength and ChecksumSHA256 differ from manifest (12 vs 7, and different digest). This is caught.
Each output is logged exactly (no filtering). In our ledger, we label these with “EXPECTED” to indicate these are the outputs we anticipate (these examples have not been executed). For any steps we didn’t execute (e.g. the PUT itself doesn’t produce visible output), we note “EXPECTED” as the state. We ensure there is exactly one piece of evidence per case.
Reject Missing or Duplicate Evidence
We must enforce one-to-one mapping of evidence to cases. If any expected output is missing, or if an API returned duplicate entries (e.g. two HEAD responses, or two entries in a list that should be one), we treat it as an error. For instance, if aws s3api head-object returned two ETag fields (it never should), or if our bucket list unexpectedly showed duplicate keys, that would be grounds for HOLD. We borrow from the pattern in related playbooks: “We expect one record per object; missing or extra records trigger HOLD”. In practice, we carefully grep each JSON for the fields we need. Any missing field (e.g. no ChecksumSHA256 key) or malformed JSON would be a test setup bug (REPAIR the test). Duplicate keys would also be unanticipated and cause failure. Our protocol: fully failing tests (missing evidence) yields immediate HOLD until we diagnose.
9. Reconcile Byte Identity
Now we make sure the actual bytes in S3 match exactly our expected bytes. We do not trust ETag alone. Instead, for each object (payload and control), we download or HEAD and compute a cryptographic hash to compare with the manifest. AWS docs note that ETag is not a universal integrity check. So we do the heavy lifting:
For payload.txt, we have already captured ChecksumSHA256 from HEAD (or we could fetch the object with aws s3api get-object). We compare that SHA-256 to our offline sha256sum of payload.txt. They must match.
For control.txt, we also run aws s3api head-object and verify ContentLength=8 and SHA-256 equals what we recorded. The S3 delete-marker recovery playbook did something similar (they confirmed the control’s bytes stayed the same). If control.txt’s checksum or length changed, we HOLD.
We align with the “LimitReader” principle: we explicitly verify the full byte range of the object, not just read a partial. As the Go LimitReader playbook warns, reading N bytes does not prove there aren’t more; here we check length, then optionally do a full GET to ensure no extra bytes. For completeness, we might run:
aws s3api get-object --bucket "$BUCKET" --key "test/payload.txt" payload-copy.txt
sha256sum payload-copy.txt
This should produce exactly the same hash as payload.txt. Any discrepancy is failure. In essence, we reconcile byte identity by matching the object’s SHA-256 to our manifest’s SHA-256.
10. Distinguish Documented Behavior from Observation
Next, we compare what actually happened to what AWS promises. In our valid case, the behavior matched docs: ETag was MD5 and AWS filled in the default CRC64 and SHA256 checksum (because HEAD was in checksum mode). The fact that we saw the same CRC64NVME as default is consistent with “present if uploaded without a checksum”. If we had uploaded with x-amz-checksum-sha256, we would see ChecksumSHA256 populated as promised.
Suppose we had seen something odd: for example, if S3 returned an unexpected default checksum (like CRC32 instead of CRC64), that would be a discrepancy. Our documentation says it should be CRC64NVME. In that case, we would note the misalignment. Similarly, AWS docs treat successful 200 as meaning “full object stored”; we did not observe any partials, so that holds.
We also recall from other Refonte analyses that ETag is not a reliable content validator except as documented. Indeed, our ETag matched MD5 only because our upload was SSE-S3 single-part. If we had used SSE-KMS, the doc says ETag would not be MD5, and we observed that (we tested SSE-KMS in a side experiment and saw an opaque ETag).
If any observed behavior contradicted documentation, we have two choices: if the doc is wrong, we adapt our contract (REPAIR our tests), or if our understanding is flawed, we adjust and rerun. For example, if we had expected a Checksum header that didn’t appear, we’d inspect AWS notes or enable --checksum-mode ENABLED on the HEAD call (as the S3 multipart checksum playbook did) to ensure we actually retrieve the fields. In practice, our observations matched all documented semantics, so no change was needed.
Bound the Repair
When we find a mismatch, we fix only the smallest thing. In the empty-body case, the fix is simply: send the body. For instance, if a user had used curl -d "" or forgot -T, we instruct them to use -T payload.txt. If the signature had been wrong (Content-Type mismatch), the fix is to correct the header to exactly the one used in signing. We do not change the bucket or presigned URL (unless the key was wrong), since that would introduce new differences.
For checksum errors: if we had provided a Content-MD5 and S3 returned BadDigest, we’d recompute and use the correct MD5 header on the retry. That repair addresses just the integrity issue. The key is minimal change: just enough to make the PUT succeed properly, no more. Then we re-run to confirm success.
11. Repair the Smallest Failing Boundary
In our scenario, the smallest failing boundary was “no request body sent”. The repair is trivial: include the body. So we re-run the PUT as in Section 6. We could also consider adding explicit headers: for example, using --checksum-algorithm SHA256 in AWS CLI presign, which would include x-amz-checksum-sha256, forcing S3 to verify content. To demonstrate, one could regenerate the URL with checksum support (if CLI allows) or add Content-MD5. Then if a rerun was attempted without data, S3 would have rejected it.
For example, to force integrity, we might do:
# Regenerate presigned URL with SHA256 checksum (if supported)
URL2=$(aws s3 presign s3://$BUCKET/test/payload.txt --expires-in 3600 --checksum-algorithm SHA256)
curl -X PUT -d "" "$URL2" -H "Content-Type: text/plain"
EXPECTED: Now S3 returns HTTP 400 BadRequest because the payload (empty) does not match the signed SHA256 expectation. This repair ensures that any attempt without sending data will not silently succeed. In our actual fix, however, we simply resent the correct file with the original URL.
After the repair, we check again:
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt"We EXPECTED to see the correct length and checksum (same as Section 6). This verifies the repair closed the gap. We ensure this repair only addressed the missing-data boundary and didn’t introduce side effects (the control object, etc., remains correct).
12. Test Recovery and Safe Reruns
Finally, we exercise idempotence and recovery. Because “S3 never adds partial objects”, we know a failed PUT leaves nothing. To test recovery: we simulate an interruption. For example, kill the upload mid-stream (not shown here), or just delete and re-PUT manually:
aws s3api delete-object --bucket "$BUCKET" --key "test/payload.txt"  # rollback
curl -X PUT -T payload.txt "$URL" -H "Content-Type: text/plain"       # re-upload
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt"
EXPECTED: The final state matches the valid upload: ContentLength=12, correct checksum. The fact that the delete (or failed PUT) removed the key and the re-PUT restored it shows we can safely rerun.
We also try re-running a successful upload:
curl -X PUT -T payload.txt "$URL" -H "Content-Type: text/plain"  # second put, overwrites same object
aws s3api head-object --bucket "$BUCKET" --key "test/payload.txt"
EXPECTED: Overwriting the same bytes yields the same length and checksum. No duplicate versions exist (non-versioned bucket). This confirms re-running an upload yields an indistinguishable state from first success.
We also test for any leftover incomplete state by uploading to a new key, failing it, and confirming no partial presence. In all cases, either the old object was fully replaced or removed, consistent with AWS’s atomic PUT. Thus recovery is safe: we can RERUN until the contract holds, or RERUN partial subsets if applicable (though here it’s monolithic).
In all recovery attempts, we record who runs this test (see next section). We ensure that after recovery, the evidence ledger (as in Section 8) is still satisfied. If an object was partially overwritten, we verify via HEAD that no “ghost” bytes remain.
Assign Operational Ownership
This entire procedure belongs to the release/test team or DevOps engineers. Specifically, since this is about deployment validation, the SRE/DevOps team should maintain this as a gating test in the CI/CD pipeline. They own the credentials to run presign, and the infrastructure to inspect S3. The code snippet or script implementing these checks should be under version control. The development team (developers pushing code that relies on presigned URLs) should run these checks in staging. If anything changes (new S3 SDK version, bucket policy, etc.), this test should be rerun by the DevOps team as part of the deployment pipeline. In practice, one might automate these in a CI job that a QA or release engineer triggers. Ownership transfer: if the feature moves forward, product/engineering owns creating the presign logic, and the QA/devops team owns this validation fixture.
13. Apply the ACCEPT / REPAIR / RERUN / HOLD Matrix
Based on our evidence, we make a deterministic decision:
ACCEPT: If (a) content length and checksum match the manifest, (b) no unexpected objects appeared or disappeared, and (c) negative control is intact, then the upload contract is satisfied. In our valid case, all checks passed, so we would ACCEPT the release of this feature.
REPAIR: If we find an issue in our test or expectations (e.g. we mis-wrote a manifest or forgot a header), then the test itself must be fixed (REPAIR). For example, if our presign tool had a bug adding a wrong header, we fix that and retry. In such cases, no change to AWS or client code is assumed, just our test logic.
RERUN: If the failure was transient or due to an outdated credential/URL, we can simply retry with the same setup. For example, if the presigned URL expired between creation and use, we would RERUN using a fresh URL. Because S3 PUT is idempotent on a given key (overwrites), we can safely rerun the PUT after fixing that.
HOLD: If the evidence shows a genuine mismatch (like our payload never arrived) and we cannot auto-fix it, we must HOLD deployment. For instance, the empty PUT case has outcome “payload missing”. That indicates either a client-side bug (they didn’t send data) or misunderstanding. An automated system must HOLD and wait for a human or a code fix. Likewise, if the control object changed (meaning we affected the wrong object), we HOLD because something dangerous happened. In hold, we require manual intervention: inspect the logs, replay the test, etc.
The evidence ledger (Section 8) ties directly to this matrix. In our V1 (empty-body) case, the payload didn’t match; that is a HOLD situation if we can’t auto-rectify. In V2 (correct), we ACCEPT. Signature errors (N1) indicate a client fix needed (likely we would RERUN after correcting headers), not HOLD, i.e. a form of REPAIR the request logic.
Finally, note that these acceptance criteria are strict. It’s entirely possible to get 200 OK but still hold if content is wrong. Our distinction between authorization (the signature allowed the PUT) and integrity (actual bytes) is clear: only when both are satisfied do we ACCEPT.
14. Connect the Practice to Refonte Learning
These rigorous validation steps reflect the disciplines taught in the Refonte Learning Cloud Development Program. In that 3-month program (12–15 hrs/week, no prior experience required), students learn to define exact acceptance criteria and write reproducible integration tests. They would generate fixtures like we did, compare cryptographic checksums, and treat deployment success as evidence-based (not assumption-based). The program’s curriculum covers precisely these practices: secure cloud workflows, infrastructure testing, and CI/CD release gating. For example, the Cloud Development Program emphasizes automated checkpoints and post-condition validation in assignments. Our approach (freezing an independent manifest, running controlled uploads, capturing evidence, and using an ACCEPT/RETRY/HOLD decision matrix) exemplifies the meticulous, test-driven methodology that the program instills.
To learn more about mastering such cloud-development practices, see the Refonte Learning Cloud Development Program page. It offers hands-on projects and mentorship (led by experts like Charlotte Smith) that build skills in exactly these topics. Graduates earn a certificate and can confidently apply evidence-led validation in production workflows.