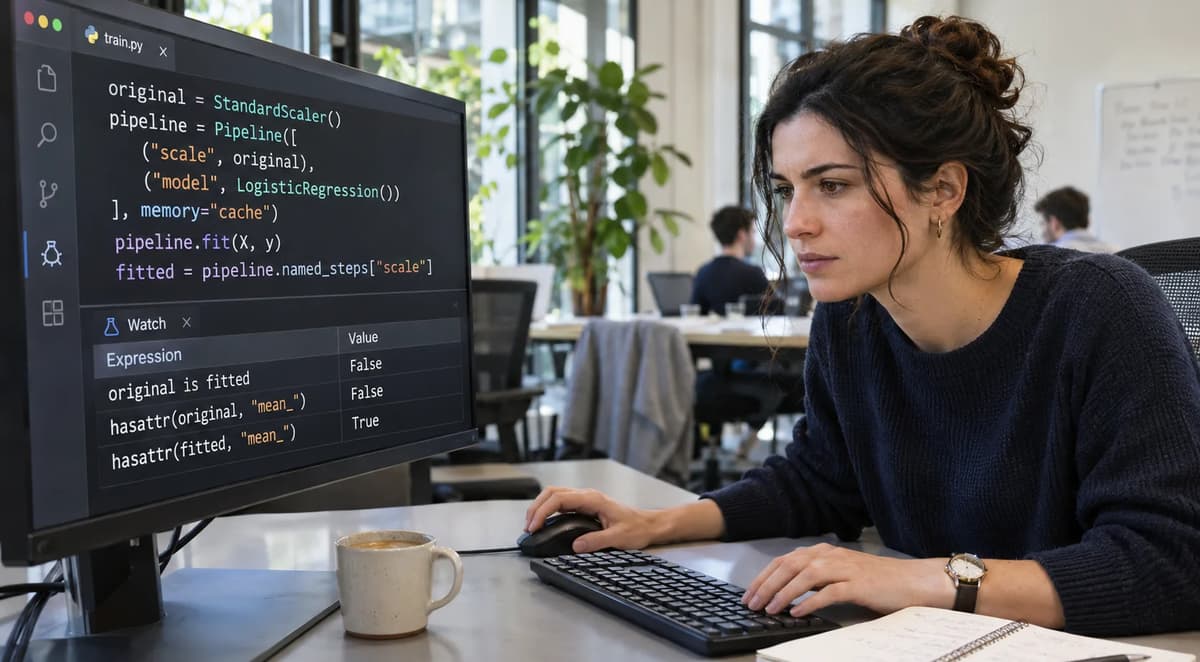
Refonters, imagine enabling memory in a scikit-learn pipeline to speed up expensive preprocessing, only to wonder afterwards which transformer was really fitted. Did the pipeline clone your transformer or fit it in place? When will cached results be reused if you repeat the fit, and what changes when you supply different data or parameters? The pipeline can still produce the expected predictions while the original transformer has no fitted attributes. Look at the transformer in pipeline.named_steps after fitting to find the state the pipeline actually uses.
The isolated fixture below uses synthetic data and pinned versions. Each case has an ID and an expected outcome for one configuration: no caching, caching with identical inputs, changed inputs, changed parameters, or a single-step pipeline. An independently written manifest sets out those expectations before execution. A separate ledger records the evidence for each case, including contradictory clues such as missing cache entries.
The examples and ledger are EXPECTED / NOT EXECUTED. The final decision (ACCEPT, REPAIR, RERUN or HOLD) depends on comparing the documented guarantees with a recorded run. The same distinction underlies Refonte’s PyTorch checkpoint aliasing test: a successful call leaves open the question of which object holds the state you intended to preserve.
1. Define the operational contract
What must happen when a pipeline fits with caching enabled? On a cache miss, scikit-learn clones each intermediate transformer before fitting it. On a hit, it can reuse the stored fitted transformer and transformed data. In both cases, the fitted intermediate step is available through the pipeline. The final estimator is fitted in place. The following cases test that contract.
Case A (NoCache): Pipeline with memory=None (default). Expect the original transformer instance to be fitted directly. The pipeline should produce correct output and the original transformer’s fitted attributes should appear after fit().
Case B (WithCache, identical data). Use Pipeline with memory=Memory(tmpdir) and fit on the data for the first time in an empty cache. Expect scikit-learn to fit a new transformer instance created by cloning. The original transformer should remain untouched, with no fitted attributes. The pipeline’s named_steps should contain the fitted transformer. Repeating fit() on the same data with the same parameters should then skip the intermediate fit.
Case C (WithCache, new data). Fit on different input data with the same cache. Expect the changed input to produce a different cache key and a new transformer fit. The original transformer should remain untouched.
Case D (WithCache, changed parameters). Keep the cache and the input data fixed, but change a transformer parameter between fits using set_params. The new parameter value should give the intermediate fit a different cache key. Expect a fresh fit for that configuration. The previous result can still exist under its original key.
Case E (Single-step pipeline): One-transformer pipeline. Since the last step is also the only step, scikit-learn docs say the last step is never cached. In this edge case, we expect no cloning at all: the original transformer itself will be fitted. This serves as a control.
Each of these is a fixture step. For each case we record an independent ID (A, B, C, D or E), the input conditions and the expected outcome. We later check object identity, fitted attributes such as scale_, and cache entries against those expectations.
Analogous example: In PyTorch, a similar aliasing issue arises when saving model.state_dict(). The Refonte PyTorch playbook made separate assertions about model state copies versus changes. Here our "state" is the fitted parameters of each transformer and whether they reside in the original or a clone.
Fixture steps for each case. Generate a tiny synthetic dataset, such as X = np.array([[0], [1], [2]]), and choose a transformer such as StandardScaler whose fitted attributes you can inspect. Set random_state=0 for the classifier. Construct each independent scenario in a fresh Python process with the pinned versions, scikit-learn 1.9.1 and joblib 1.6.0. Give each scenario a temporary cache directory. For a case that tests reuse or a changed input, keep that directory across the baseline fit and its repeat. After each fit, record repr(pipeline.named_steps), the IDs of the live objects, and their fitted attributes. Compare identities within a process. The expected outputs are predetermined by the manifest below.
Expected outputs for key checks:
Identity checks. Compare the original transformer with the stored step from the same pipeline, for example orig_scaler2 is not pipeB.named_steps['scaler'] in Case B.
Fitted attributes. Expect hasattr(orig_scaler2, 'mean_') to be false in Case B and the same check on the fitted step to be true.
Cache directory checks, e.g. existence of files under the Memory cache dir.
Pipeline output consistency (predict or transform) is a sanity check (should match non-cached pipeline).
We will keep a case-by-case evidence ledger as we execute these. For now, we have clearly defined what a pass/fail looks like for each case. These will form the basis for later acceptance or repair decisions.
2. Record the documented baseline and scope
Before running tests, record the documented behavior of Pipeline(memory=...). Both the scikit-learn 1.5.2 Pipeline documentation and the scikit-learn 1.9.1 Pipeline documentation describe the following behavior.
Caching behavior. Enabling caching causes the pipeline to clone intermediate transformers before fitting. For the StandardScaler in this fixture, scikit-learn’s estimator cloning function creates a fresh, unfitted estimator with the same constructor parameters. Inspect the fitted step through named_steps. The original instance is still accessible, but it does not acquire the clone’s learned attributes.
Final step. The last pipeline step is never cached, even when it is a transformer. In a one-step pipeline, that transformer is fitted directly. In longer pipelines, only the steps before the final estimator participate in transformer caching.
Cache mechanism. The memory argument accepts a directory path or a joblib.Memory object. The scikit-learn pipeline implementation wraps its intermediate fit-and-transform helper with Memory.cache. As the joblib guide to disk-based caching explains, a stored function result can be loaded again for the same arguments. Here those arguments include the transformer configuration, X, y and any routed step parameters. With the cache intact, a repeated call with the same key can load the earlier result. A changed input or parameter can produce a new key and require a new fit.
Version compatibility: We note any version specifics. For example, scikit-learn’s transform_input parameter (added in 1.6) is unrelated to caching, so out of scope. We stick to stable Pipeline/memory behavior documented. If we find any discrepancy (e.g. implementation vs docs), that’s the bug to capture.
Using this, we constrain our test scope: we will only test behaviors directly tied to caching/cloning. We will not dive into unrelated Pipeline features (like transform_input, multi-output, cross-validation, etc). We treat “caching semantics” as our full scope.
Version and environment fingerprint
Record the exact software versions to avoid ambiguity. The fixture specifies Python 3.13.5, scikit-learn 1.9.1 and joblib 1.6.0. Capture the interpreter and package versions at runtime and retain the output in version.txt alongside the manifest. These are the expected values for the proposed environment.
# Environment fingerprint (EXPECTED / NOT EXECUTED)
python3.13 -c "import sys; print(sys.version.split()[0])"
# Expected: 3.13.5
python3.13 - <<'PYTHON'
import sklearn, joblib
print(sklearn.__version__, joblib.__version__)
PYTHON
# Expected: 1.9.1 1.6.0
Falsifiable assertion: If the environment version does not match (say scikit-learn 1.8 or 2.0), some behavior could differ. We therefore retain an artifact (like version.txt) showing the interpreter and library versions used for all tests.
3. Pin versions and build an isolated fixture
Pin the package versions and construct the disposable test fixture. Synthetic data and a simple transformer make the learned state easy to inspect. The example uses Python 3.13.5, scikit-learn 1.9.1 and joblib 1.6.0. The following shell commands create the environment and print the installed versions.
# Environment setup (EXPECTED / NOT EXECUTED)
python3.13 -m venv .venv
. .venv/bin/activate
python -m pip install scikit-learn==1.9.1 joblib==1.6.0
python - <<'PYTHON'
import sklearn, joblib, numpy as np
print(sklearn.__version__, joblib.__version__, np.__version__)
PYTHON
# Expected: 1.9.1 1.6.0 followed by the installed NumPy version.
Within this environment, keep the fixture data minimal: X = np.array([[0.], [1.], [2.]]) and y = [0, 1, 1]. The three rows make the scaler’s learned values easy to check, and the classifier uses a fixed random seed. Run the following Python examples in a disposable working directory. All example outputs are EXPECTED / NOT EXECUTED.
from sklearn.pipeline import Pipeline
from sklearn.preprocessing import StandardScaler
from sklearn.linear_model import LogisticRegression
from joblib import Memory
import numpy as np

# Create synthetic data.
X = np.array([[0.0], [1.0], [2.0]])
y = [0, 1, 1]
# Case A: pipeline without caching (baseline).
orig_scaler = StandardScaler()
clf_a = LogisticRegression(random_state=0, solver='liblinear')
pipeA = Pipeline([('scaler', orig_scaler), ('clf', clf_a)],
memory=None)
pipeA.fit(X, y)
# Expected: the pipeline step is orig_scaler and has scale_.# Case B: pipeline with caching on the same data.
orig_scaler2 = StandardScaler()
clf_b = LogisticRegression(random_state=0, solver='liblinear')
mem = Memory(location='cache_dir', verbose=10)
pipeB = Pipeline([('scaler', orig_scaler2), ('clf', clf_b)],
memory=mem)
pipeB.fit(X, y)
# Expected: orig_scaler2 lacks scale_. The pipeline's step has it.The comments record what to expect. Inspect cache_dir for the scaler’s stored result. To isolate the test state, start independent cases in a fresh process and an empty directory, for example one created with tempfile.TemporaryDirectory(). Within each comparison, keep the cache directory available for the second fit and collect evidence before cleanup.
We also include boundary cases:
# Case E: the single step is also the last step.
orig_scaler3 = StandardScaler()
pipeE = Pipeline([('scaler', orig_scaler3)], memory=mem)
pipeE.fit(X, y=None)
# Expected: orig_scaler3 is fitted in place.
# No new intermediate fit result should appear in the cache.
Building this fixture takes care. For each case we label the pipeline, data, and expected condition. We will record actual state in the next phase.
The Refonte SQLite UPSERT playbook creates a disposable database and an expected-case manifest before executing any queries. Follow the same sequence here by preparing the versions, data and manifest before running the tests.
4. Write an independent expected-case manifest
Before running the fixture, author an expected-case manifest that lists each case ID, scenario and expected outputs. This prevents the observations from influencing the expectations. The manifest can use JSON or TSV. Here is the JSON example.
{
  "testFixture": "PipelineCaching-v1",
  "cases": [
    {
      "id": "A_NoCache",
      "description": "Pipeline(memory=None) without caching",
      "expected": {
        "transformerClone": false, "originalFitted": true, "finalUsed":
        "orig"
      }
    },
{
"id": "B_WithCache_SameData",
"description": "Pipeline with caching, fitting same data twice",
"expected": {
"transformerClone": true, "originalFitted": false,
"cacheReusedOnSecondFit": true, "finalUsed": "orig"
}
}, {
"id": "C_WithCache_NewData",
"description": "Pipeline with caching, new input data",
"expected": {
"transformerClone": true, "originalFitted": false, "cacheReused":
false, "finalUsed": "orig"
}
}, {
"id": "D_WithCache_ParamChange",
"description":
"Pipeline with caching, but transformer parameter changed between fits",
"expected": {
"transformerClone": true, "originalFitted": false, "cacheReused":
false, "finalUsed": "orig"
}
}, {
"id": "E_SingleStep",
"description": "Single-step pipeline with caching (edge case)",
"expected": {
"transformerClone": false, "originalFitted": true, "finalUsed":
"orig"
}
}
]
}Each case’s expected fields include whether we expect a clone (true/false), whether the original transformer gains fitted attributes, whether a cached result is reused on a repeated call, and whether the final estimator is the original. We do not run any tests yet. This manifest is our “oracle” against which we compare actual outputs.
Assert the expected negative case
Case E (SingleStep) supplies a negative control. The pipeline’s only step is its final step, so it should fit the supplied transformer directly. The manifest records transformerClone: false and expects the original transformer to gain fitted attributes. If the pipeline stores a different object or the original lacks its expected attributes, record the discrepancy and check the fixture and runtime version.
5. Reproduce the misleading success signal
Run Case B (WithCache_SameData) and Case A (NoCache) and compare pipeA.predict(X) with pipeB.predict(X). With identical data and classifier settings, the outputs should match. A test limited to this comparison could declare success regardless of which transformer the pipeline fitted.
Capture the prediction comparison before checking the transformer objects.
# Case B vs Case A: output equivalence
y_pred_A = pipeA.predict(X)
y_pred_B = pipeB.predict(X)
print("Predictions match:", np.array_equal(y_pred_A, y_pred_B))
# EXPECTED OUTPUT: True (so one might think everything is fine)
Both pipelines should give identical predictions (True) on this input. That result leaves the identity question open. Case B should fit a clone of its own original transformer. Check the two objects that belong to Case B directly.
# Check transformer identity after fitting (Case B).
fitted_b = pipeB.named_steps['scaler']
print(orig_scaler2 is fitted_b)
# Expected: False
print(hasattr(orig_scaler2, 'scale_'))
# Expected: False
print(fitted_b.__class__)
print(hasattr(fitted_b, 'scale_'))
# Expected: StandardScaler and True
A successful predict call gives the engine no reason to flag an identity error. The PyTorch playbook describes a similar pattern: a model can continue working while its saved checkpoint no longer preserves the selected tensor values. Record matching predictions as evidence about output. Record the original and fitted objects separately as evidence about cloning.
6. Run a controlled comparison case
To distinguish absence of issues from actual success, we explicitly compare scenarios with and without caching. In Case A vs Case B, we run two pipelines side by side under identical conditions except for the memory flag. This is a controlled comparison:
# Controlled comparison in a fresh working directory.
orig_scaler, orig_scaler2 = StandardScaler(), StandardScaler()
clf_a = LogisticRegression(random_state=0, solver='liblinear')
clf_b = LogisticRegression(random_state=0, solver='liblinear')
# Without caching
pipeA = Pipeline([('scaler', orig_scaler), ('clf', clf_a)],
memory=None)
pipeA.fit(X, y)# With caching
mem = Memory('cache_dir', verbose=10)
pipeB = Pipeline([('scaler', orig_scaler2), ('clf', clf_b)],
memory=mem)
pipeB.fit(X, y)Expected outcomes:
In Case A, the pipeline should have used the original objects. So pipeA.named_steps['scaler'] is orig_scaler and has fitting attributes.
In Case B, expect pipeB.named_steps['scaler'] to be a different object from orig_scaler2 and to have fitted attributes. The original orig_scaler2 should remain unfitted. The cache directory should contain an intermediate fit result after Case B’s first fit.
This lets us distinguish absent evidence from failure. Correct predictions alone leave the transformation state and object identities unresolved. In Refonte’s requestAnimationFrame hidden-tab investigation, a completed callback left a similar question open: the raw timestamps were needed to establish what happened while the tab was hidden. After the two pipeline fits, compare the input transformer and stored step from the same case.
original_id = id(orig_scaler2)
fitted_id = id(pipeB.named_steps['scaler'])
print("Case B transformer identity equal?", original_id == fitted_id)
# Expected: False
If the IDs match while both Case B objects are alive, preserve the result as a contradictory observation. Record the identifiers and the identity comparison together. An example ledger might contain original_id=139282319240048 and fitted_id=139281920384752. These are illustrative values. The numeric IDs vary across runs. Preserve the cache directory listing alongside the identity evidence.
7. Test negative controls and boundary conditions
We validate that our test can indeed detect when not to clone or cache: these are our negative controls.
Memory disabled: We verify that with memory=None, the transformer is fitted directly. We already have Case A. If for some reason scikit-learn erroneously cloned even when memory=None, our test would catch it.
Empty transformer list: If someone constructs Pipeline([], memory=...), this is an invalid case (Pipeline needs at least one step) and out of scope.
Passthrough or None steps: If a pipeline step is set to 'passthrough', it should simply be skipped. We include a quick check:
pipe_passthrough = Pipeline(
    [('id', 'passthrough'), ('scaler', StandardScaler())],
    memory=Memory('cache_dir'),
)
pipe_passthrough.fit(X, y)
# Expected: the first step is skipped.
# The scaler is the final step, so it is fitted in place.
This control checks that the harness accounts for a skipped intermediate step when interpreting the fitted scaler and cache entries.
One-step pipeline (Case E). Check that the fit creates no new intermediate cache entries and that orig_scaler3 gains fitted attributes. Together, those observations test whether caching is bypassed for the final transformer.
Disabled memory and invalid inputs. The scikit-learn memory validation helper treats None as disabled caching. Compare Pipeline(memory=None) with a pipeline using Memory(location=None) to check this boundary. The Boolean value False is outside the documented input types for memory.
If a control fails, for example if the Case E scaler is replaced by a clone, investigate the mismatch. Record all observations in the ledger. An existing cache may contain entries from earlier cases, so compare the listing before and after Case E to establish whether the one-step fit created a result.
8. Capture raw evidence before cleanup
Before cleaning up the fixture environment, we save all raw evidence artifacts for transparency. This includes:
Cache directory contents. List the files under cache_dir before and after each fit.
# Cache directory listing (EXPECTED / NOT EXECUTED)
find cache_dir -type f -print
# A stored intermediate call can have output.pkl and metadata.
# The final classifier should have no cached fit result of its own.
Estimator state. Capture summaries such as repr(pipe.named_steps) and the fitted attributes of the individual steps. The following check records the class and the presence of a learned scale.
scaler_b = pipeB.named_steps['scaler']
print(scaler_b.__class__, hasattr(scaler_b, 'scale_'))
# Expected: <class 'sklearn.preprocessing._data.StandardScaler'> True
We may also record the dict of objects to JSON if helpful.
Log of fitted outputs. Save the arrays y_pred_A and y_pred_B and the result of np.array_equal(y_pred_A, y_pred_B). An observed value of True records agreement on the fixture input.
At this stage, we might discover contradictory observations (see next). We preserve everything exactly as-is. For example, even if we thought “final estimator isn’t cached”, we still note the final estimator’s ID and any fitting attributes, just to complete the picture. We do not discard the evidence because it contradicts (except confidential info).
Preserve contradictory observations
If something unexpected occurs, such as missing cache results after an intermediate fit or a change in finalUsed, record it. An example entry reads, “Expected at least one cached intermediate result after the first fit. Found none in the configured directory.” Retain the raw listing, the working directory and the active memory configuration. Check the environment first. If the discrepancy survives a clean reproduction, the record gives the scikit-learn maintainers a concrete case to inspect.
9. Reconcile state, identity and completeness
With all raw evidence captured, we reconcile it against our expected manifest. We check each case in detail:
Case A (NoCache): The ledger should show the original StandardScaler instance has attributes (scale_, mean_) and its ID matches pipeA.named_steps['scaler']. This confirms no clone. If this matches (as expected), we mark Case A as PASS in the ledger.
Case B (WithCache, SameData). The evidence should show that orig_scaler2 lacks fitted attributes while pipeB.named_steps['scaler'] has them, and that the objects differ. Expect one intermediate result from the first fit in an empty cache. Run pipeB.fit(X, y) a second time without changing inputs or settings. Save the verbose joblib log showing that the intermediate result was loaded. Compare predictions and fitted values with the first fit as a consistency check. Equal outputs, elapsed time or a listing alone cannot establish reuse.
Case C (NewData). Use the same cache and parameters as Case B and fit on changed input, such as newX = X + 1.0, with the same labels. A call such as pipeC.fit(newX, y) should fit the scaler again. Its learned mean should shift with the input. Compare the two cache keys. One result should belong to X and another to newX. The original transformer should still lack fitted attributes.
Case D (ParamChange). Return to the baseline data and change the installed transformer’s parameter with pipeB.set_params(scaler__copy=False). Fit on a fresh copy of the baseline inputs so that in-place transformation cannot change the comparison data. Expect a new intermediate fit and a third distinct result if the directory contains both preceding configurations. Record the changed parameter and the resulting cache key. Changing the separately held orig_scaler2 after a cached fit would leave the fitted pipeline step untouched.
Case E (SingleStep). Check that orig_scaler3 has fitted attributes and is the object stored in the pipeline. Compare the cache entries before and after fitting. The expected increase is zero, including when the directory already contains results from other cases.
Example evidence ledger (EXPECTED / NOT EXECUTED). The table illustrates a run that meets all five expectations. The example observations are illustrative. In a real ledger, enter the observed values from each run and attach the corresponding artifacts. Cache counts refer to new intermediate result entries for the indicated fit.
Case | Expected clone? | Example clone? | Expected original fitted? | Example original fitted? | Expected new entries | Example new entries |
A | No | No | Yes | Yes | 0 (none) | 0 |
B | Yes | Yes | No | No | ≥1 | 1 |
C | Yes | Yes | No | No | ≥1 (new) | 1 (new) |
D | Yes | Yes | No | No | ≥1 (new) | 1 (new) |
E | No | No | Yes | Yes | 0 | 0 |
This ledger is the heart of our evidence. We check completeness: every case must have an entry, no missing data. Any discrepancy is noted.
10. Separate normative guarantees from observations
Compare the documentation with the observations that a run should produce. The four checks below are EXPECTED / NOT EXECUTED.
Promise 1. Cloning before fitting. With caching enabled, the pipeline clones intermediate transformers before fitting them. In Cases B, C and D, the original scaler should remain unfitted and the pipeline should hold a fitted transformer with a different identity. In Case A (no cache) and Case E (single step), the supplied scaler should be fitted directly.
Promise 2. The final step is never cached. In Case E, the scaler is the last step. In the multi-step cases, the final LogisticRegression should remain the instance supplied to that pipeline. Check pipeA.named_steps['clf'] is clf_a and pipeB.named_steps['clf'] is clf_b, then inspect their fitted attributes. The two pipelines were constructed with separate classifier objects.
Promise 3. Reuse for the same arguments. Repeat Case B on identical data with the same parameters and an intact cache. The intermediate call should load its saved result and skip fitting the scaler again. Retain the joblib load message for that call. The final estimator still fits on this run.
Promise 4. Recompute for a new key. Cases C and D change the data and the transformer parameters, respectively. Each should cause a new intermediate fit on its first use of that configuration. Save the fit log and cache entries. In Case C, also compare the learned scaler means. A changed parameter can trigger recomputation even if the learned values happen to agree.
In the example ledger, the entries agree with the documented cloning and caching rules. Matching predictions provide a separate check that enabling the cache preserves end-to-end behavior for these inputs. They do not establish the identity of the fitted transformer or show which call loaded a saved result. Those conclusions depend on the identity checks and the fit or load record for each case.
Bound the repair and its risks
If the pipeline appears to violate the documented cloning behavior, first reproduce the mismatch in the smallest failing scenario. Modifying a core API carries risk, so any proposed fix should affect only the condition that fails. A change in caching strategy after an upgrade is another reason to repeat the fixture. Include it as a gated test in CI.
11. Apply the smallest safe repair
In the worked example, no code repair would be needed. If a run did expose a failure, the smallest safe repair would change as little code as possible to resolve the discrepancy. For the caching cases, consider the following possibilities.
If a pipeline using a configured Memory directory fails to clone its intermediate transformer, check the branch that calls clone(transformer) when memory.location is set. A reproducible failure in that branch would narrow the scope of a fix.
Conversely, if a transformer was cloned erroneously when memory should be off, the fix would be to guard that code path (similar to how pipeline already checks memory.location).
If the implementation matches the documentation and the application inspected the wrong object, update the inspection code or the team’s guidance. Use pipeline.named_steps to inspect fitted intermediate transformers after a cached fit. The supplied original can remain unfitted.
Record that distinction in the ledger so that an inspection error does not prompt an unnecessary change to scikit-learn.
12. Test recovery, rollback and rerun safety
Even when the only change is to the application’s inspection code, test the recovery process. For a proposed code fix, check both rollback and rerun behavior.
Restoring the original code should reproduce the original behavior, including the previous failing check. Isolate the rollback run from cache entries written by the repaired version.
A rerun after any fix or upgrade produces predictable results.
To recover the baseline, construct a fresh pipeline with memory=None and new estimator instances. Repeat Case A and check that the supplied scaler acquires its fitted attributes. Keeping the original run’s evidence makes the two outcomes comparable.
Assign ownership and rerun triggers: We assign ownership to the core ML engineering team (the stewards of our pipelines). If scikit-learn is updated, this test must be rerun. The triggers are: any upgrade of sklearn or joblib, or changes in our pipeline usage of caching. We document this as part of our release governance: any future CI build that includes a memory-cached pipeline will have this test.
13. Make the ACCEPT / REPAIR / RERUN / HOLD decision
Finally, we use all evidence to make a gate decision:
ACCEPT. Use this decision when all cases match their expectations, the identity and reuse evidence is complete, and the ledger contains no unresolved contradictions. Under those conditions, the change enabling caching is acceptable.
REPAIR. If a reproducible discrepancy identifies an application or implementation fault, make the smallest change that addresses it. If the issue is limited to finding the fitted transformer, update the team’s guidance on pipeline.named_steps.
RERUN. Repeat the fixture after a repair, a scikit-learn or joblib patch, or a change in the way the application configures caching. A CI job, for example a nightly run, can capture new evidence under the updated pins.
HOLD. Withhold acceptance when a case fails and remains unexplained, or when evidence is missing. An environment that cannot run the fixture because a required library is unavailable is one example.
For a completed run matching the illustrative ledger, the change log could read, “ACCEPT. Pipeline caching validated. No code changes required.” The fixture shown here is EXPECTED / NOT EXECUTED. Its release decision remains HOLD until the case evidence is available.
Archive the scripts, logs, manifest, version.txt and case outputs together in the project’s release folder so the recorded decision can be checked later.
14. Connect the skills to Refonte Learning
The Refonte Data Science & AI Program spans three months at 12–14 hours per week. Its work with Python data science tools and model evaluation connects directly to this fixture. Pinning library versions and identifying input data make a run reproducible. Negative controls and boundary cases test whether a plausible output can still conceal an incorrect conclusion about the pipeline.
The program combines project-based mentorship with a virtual internship and offers training and internship certificates. A CI test harness like this one is an example of the work involved in preparing an ML system for release: define acceptance criteria, run a synthetic experiment and retain enough evidence for another engineer to check the decision. Those habits also apply to the AI engineering roles the program prepares students for.