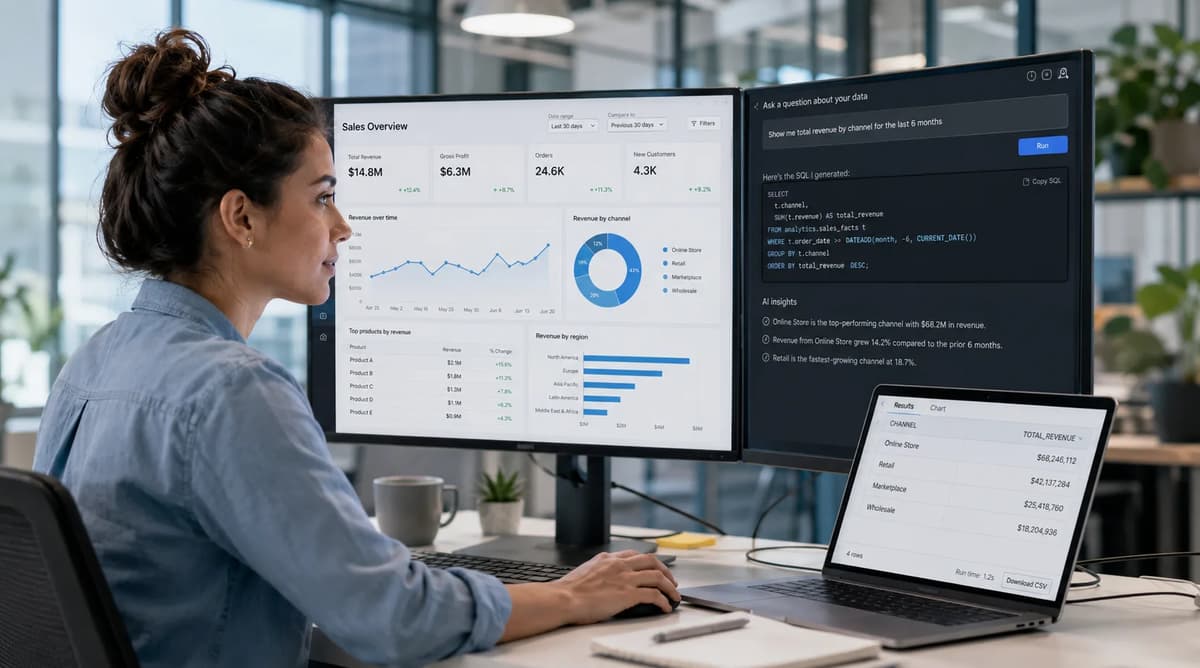
Snowflake's AI layer looks materially different in August 2026 than it did when analysts first started calling SNOWFLAKE.CORTEX.COMPLETE() from a worksheet. The current product surface centers on AI_-prefixed SQL functions, Cortex Analyst for natural-language analytics, Cortex Search for retrieval, Cortex Agents for orchestration, and a rapidly changing set of model, coding, and work-agent products.
There is one important historical correction to make at the start. It is convenient to say Snowflake "renamed its AI functions in 2026," but the migration did not begin on January 1, 2026: Snowflake introduced the Cortex AI Functions preview with the AI_ naming convention on June 2, 2025, while the old COMPLETE function is now explicitly marked as a legacy surface scheduled for deprecation by the end of 2026.
That distinction matters because AI_SUMMARIZE_AGG is not merely a renamed SUMMARIZE, and AI_SENTIMENT is documented as the successor to ENTITY_SENTIMENT, while the older SENTIMENT function remains documented. Snowflake has consolidated new development around the AI-function family, but treating every current function as a one-for-one rename of an old function would give you the wrong mental model.
The more interesting story is what those functions now automate. In the space of a few weeks in July and August 2026, Snowflake made SHOW CORTEX BASE MODELS generally available, added Anthropic's Claude Opus 5 to Cortex AI in public preview, released CoWork automations, made Cortex Agents and MCP servers in Native Apps generally available, and expanded AI_MULTI_EMBED to large-video semantic search.
So this Snowflake Cortex AI explained guide takes the mechanics-first route. Instead of adding "Cortex Analyst" to another list of 2026 analytics trends, we will trace what happens between a user's English question and the SQL Snowflake runs, what Cortex Search indexes and ranks, what an MCP server adds, which work remains human, and where SQL knowledge still determines whether you can trust the answer.
Snowflake Cortex AI in 2026: Why the Function Names Changed
For a working analyst, the simplest way to understand Snowflake AI functions in 2026 is to stop thinking of Cortex as one chatbot. Cortex AI Functions are SQL-callable operators that bring model inference into the same query layer where you already filter rows, join tables, aggregate measures, and materialize results.
Snowflake's documentation says its AI Functions can work with models from OpenAI, Anthropic, Meta, Mistral AI, and DeepSeek, with model and regional availability depending on the function and account. That does not mean every function lets you choose every model: task-specific functions such as AI_SENTIMENT and AI_SUMMARIZE_AGG can use Snowflake-managed models, while a function such as AI_COMPLETE explicitly takes the model as an argument.
Function | What it actually does |
AI_COMPLETE | Sends a prompt to a supported model and generates a completion; supports model selection and, for supported variants, multimodal inputs |
AI_SUMMARIZE_AGG | Summarizes text across rows, rather than summarizing only one short scalar value |
AI_SENTIMENT | Produces sentiment analysis, including more advanced sentiment behavior than the older compatibility functions |
AI_TRANSLATE | Translates supported text between languages |
AI_EXTRACT | Pulls structured information from text or supported files/documents |
AI_CLASSIFY | Assigns text, images, or supported content to defined categories |
AI_FILTER | Evaluates a natural-language condition and returns a Boolean that can participate in filtering logic |
AI_EMBED | Turns text or supported multimodal content into vectors for similarity and retrieval use cases |
AI_REDACT | Detects and redacts sensitive information such as PII from content |
The AI_COMPLETE change is the cleanest example of the migration. Snowflake explicitly describes AI_COMPLETE as the updated version of SNOWFLAKE.CORTEX.COMPLETE, and its current documentation tells developers to use the new function for the latest functionality.
The SQL still feels familiar:
SELECT AI_COMPLETE(
'claude-opus-5',
PROMPT(
'Review this filing and summarize the key revenue trends: {0}',
filing_text
)
)
FROM financial_filings;
Snowflake used essentially this pattern when it announced Claude Opus 5 on July 24, 2026. Claude Opus 5 was public preview, not GA, at that announcement, and Snowflake said it could be used through Cortex AI Functions, Cortex Agents, Cortex Inference, CoCo, and CoWork within the Snowflake perimeter.
AI_SUMMARIZE_AGG deserves particular attention because the familiar phrase “AI_COMPLETE AI_SUMMARIZE Snowflake” hides a meaningful difference in execution. Instead of asking an LLM to digest one prompt containing every customer ticket, you can aggregate a text column across rows; Snowflake documents AI_SUMMARIZE_AGG as capable of operating across datasets that exceed a single model context window.
That is closer to what SQL users actually need. You do not want to concatenate 80,000 support tickets by hand, guess whether the resulting prompt fits a context window, send it to an external API, parse the response, and load the output back into the warehouse; you want an aggregation function that participates in a data pipeline.
The same logic explains AI_FILTER and AI_CLASSIFY. Conventional SQL works beautifully when the rule is deterministic, such as country = 'US', revenue > 50000, status IN ('OPEN','ESCALATED'), but becomes awkward when the condition is semantic, such as whether a support ticket describes cancellation intent or whether a complaint belongs to a predefined business category.
This is where Cortex functions automate code you previously would have written around SQL. The model call, request orchestration, inference infrastructure, and result delivery become part of the Snowflake query surface rather than a separate Python service sitting between your warehouse and an external model endpoint.
That convenience has a cost model you should understand. Snowflake says Cortex AI Functions consume compute according to tokens or, for applicable document functions, pages; warehouse costs can also continue while a query invoking these functions runs, and Snowflake exposes account-usage views for tracking function-level consumption.
For context, Refonte's existing complete guide to data analytics skills, tools, and careers already places Cortex Analyst in the broader analytics-tool landscape. The gap this article fills is the layer underneath that mention: what happens technically when an AI function or natural-language analytics service replaces code an analyst previously had to write.
The practical conclusion is that Snowflake's naming shift is not cosmetic. The AI_ prefix increasingly marks a coherent SQL-native inference surface, while older names remain partly for backward compatibility during the migration period.
What Cortex Analyst Actually Does
Cortex Analyst is Snowflake's natural-language-to-SQL layer for structured analytical data. A business user asks something like, "What was net revenue by region last quarter?", and Cortex Analyst uses business metadata to translate that question into a query against the actual Snowflake objects the organization has made available.
The key piece is the semantic layer. Snowflake originally centered Cortex Analyst tutorials on YAML semantic models, and those YAML models remain supported, but the current 2026 documentation recommends native Semantic Views for new implementations; legacy YAML files stored on stages remain available for backward compatibility.
That current distinction matters for anyone searching for “Cortex Analyst natural language SQL.” A YAML file is not magic context pasted beside the prompt: it describes the analytical vocabulary Cortex Analyst needs to connect business language to physical schema, while native Semantic Views now make those concepts Snowflake schema-level objects.
Stage | What happens mechanically | What a human still controls |
Business definition | A semantic view/model defines entities, dimensions, measures, metrics, relationships, and instructions | What “revenue,” “active customer,” “churn,” or “margin” actually means |
User request | User submits a natural-language question | The analytical intent |
Semantic grounding | Analyst identifies relevant business concepts and physical data objects | Quality and completeness of semantic metadata |
SQL generation | Cortex generates SQL that represents its interpretation | Whether that SQL matches the intended business logic |
Authorization | Snowflake applies the relevant access-control context | RBAC and object privileges configured by administrators |
Execution | Generated SQL runs against Snowflake compute | Warehouse design, data quality, and underlying data |
Follow-up | Prior conversational context can support another question | Whether the follow-up remains analytically meaningful |
Imagine a warehouse where the finance team calls something “net revenue,” but the physical implementation requires gross_sales - refunds - rebates, excludes test customers, and applies a fiscal-calendar relationship rather than a calendar-month filter. An LLM reading raw column names cannot reliably infer that definition.
The semantic layer gives it the missing contract. Snowflake also provides custom instructions that let teams tell Cortex Analyst how concepts such as “performance” or “financial year” should affect generated SQL, and verified queries can pair known-good natural-language questions with approved SQL.
This is why the modern data analytics stack with dbt and Snowflake remains relevant underneath Cortex. dbt models, curated warehouse tables, testing, and transformation logic do not disappear because a natural-language interface exists; Cortex Analyst sits on top of the structured layer those practices create.
Snowflake has also added evaluation and optimization machinery around the semantic layer. Cortex Analyst evaluations can use verified query pairs as ground truth, while its optimization workflow can analyze verified queries and suggest semantic concepts, for example, inferring an approved definition of an “active” user from validated SQL.
That is a much more useful description than “AI writes SQL for you.” It is closer to: AI writes SQL inside a developer-curated semantic contract, and the organization needs a feedback loop to measure whether those translations remain correct.
The REST API makes the architecture more practical. Snowflake documents POST /api/v2/cortex/analyst/message, where a request includes natural-language messages and identifies a semantic view, a YAML semantic-model file on a stage, inline YAML, or an array of candidate models/views.
A simplified request conceptually looks like this:
POST /api/v2/cortex/analyst/message
Authorization: Bearer <snowflake-token>
Content-Type: application/json
{
"messages": [
{
"role": "user",
"content": [
{
"type": "text",
"text": "Which company had the most revenue?"
}
]
}
],
"semantic_view": "ANALYTICS.SEMANTIC.REVENUE_VIEW"
}
The messages format and semantic-view option come directly from Snowflake's current API specification. The API also supports giving Cortex Analyst multiple semantic models or views so it can choose the relevant source rather than making the end user know which dataset contains the answer.
Multi-turn support changes the user experience further. Instead of starting from zero, an application can maintain conversational context so the next question can be “Now split that by region” or “Exclude enterprise accounts,” preserving the analytical thread rather than forcing the user to reconstruct the original query.
There is an integration nuance that is easy to oversimplify. The Analyst REST API gives developers the primitive needed for a custom application, while Snowflake's broader Slack and Microsoft Teams integration patterns increasingly use Cortex Agents, which can incorporate structured-data capabilities rather than requiring a Slack bot to call Cortex Analyst as an isolated feature.
Why your data stays inside Snowflake's governance boundary is also more specific than “enterprise-grade security.” Snowflake states that Cortex Analyst does not use Customer Data to train or fine-tune models for broad customer use; for inference, its semantic metadata supports SQL generation, and generated SQL executes in the Snowflake warehouse.
Snowflake further says that, by default, Cortex Analyst uses Snowflake-hosted Mistral and Meta models so metadata and prompts remain within its governance boundary. Generated SQL follows Snowflake RBAC, meaning the natural-language interface does not become an automatic bypass around the access controls already attached to your data.
That does not eliminate governance work. A badly designed semantic layer can still encode the wrong metric, and an authorized user can still receive a logically misleading answer from data they are legitimately allowed to query.
Cortex Search, Cortex Agents, and MCP: The Other Half of Cortex
Cortex Analyst gets most of the attention because natural-language SQL is immediately understandable to analysts. Cortex Search solves a different problem: retrieving relevant pieces of text or other indexed content when an exact SQL predicate is not enough.
A support ticket containing “I don't think we can continue our subscription after this billing cycle” may express cancellation intent without containing the exact word cancel. Semantic retrieval uses embeddings to find content with related meaning, while keyword retrieval can still capture exact terms that vector similarity might underweight.
Snowflake combines those approaches. By default, Cortex Search uses vector similarity, text matching, and reranking, and Snowflake lets developers adjust component weights, add numeric boosts or time-decay signals, and disable reranking when the latency trade-off matters more than the ranking improvement.
Capability | Cortex Analyst | Cortex Search | Cortex Agents |
Primary job | Convert business questions to SQL | Retrieve semantically relevant indexed content | Plan, select tools, execute steps, synthesize answers |
Best data shape | Structured analytical tables | Text and multimodal/searchable content | Structured + unstructured + tools |
Core grounding | Semantic Views / legacy semantic YAML | Search indexes and metadata | Analyst, Search, procedures, functions, MCP tools |
Typical output | SQL-driven analytical answer | Ranked relevant records/chunks | Multi-step conversational result |
Key mental model | Text-to-SQL | Retrieval / RAG | Orchestration |
This is the essential Cortex Search vs Cortex Analyst distinction. If your question is “What was average revenue per customer in France last quarter?”, you need structured metrics and SQL; if it is “Find the support conversations in which customers describe problems similar to this outage,” you need retrieval.
The products can also cooperate. Snowflake documents an integration where Cortex Search helps Cortex Analyst resolve literal values that are hard to infer from a user's wording, for example, matching a user asking for “iced tea” to the exact product values actually present in a database.
Cortex Search starts by building an index from a source query. Snowflake can automatically embed the search text, and the service then exposes a low-latency retrieval interface rather than recalculating vector similarity over the raw source every time someone asks a question.
The 2026 efficiency changes matter because embeddings and always-on serving can otherwise turn into a quiet cost center. Cortex Search now supports auto-suspend for serving compute after inactivity; the current feature remains marked Preview, accepts a minimum inactivity period of 1,800 seconds, and automatically resumes when another query arrives.
There is a latency consequence. Snowflake warns that the first request after suspension waits for resume, while concurrent requests during the resume period can receive HTTP 429 with a Retry-After header, so an application needs retry logic rather than treating auto-suspend as a free optimization with no operational trade-off.
Another important correction concerns “primary-key-based incremental re-embedding.” Primary keys can give a Cortex Search service a unique row identifier, but incremental processing itself is what prevents Snowflake from embedding the entire corpus after each source change; Snowflake says embeddings are processed for inserted or updated documents, while unchanged documents do not repeatedly incur embedding cost.
In other words, do not think:
PRIMARY KEY → magically stops re-embedding
Think:
source change tracking + incremental index refresh → changed rows are processed → unchanged embeddings can be reused
The optional primary key helps identify rows and maintain the service, while the documented cost reduction comes from incremental processing of changes.
Cortex Search cost itself has multiple components: warehouse compute for refresh work, embedding-related AI consumption, index storage, and separate multi-tenant serving compute. Snowflake's cost guidance therefore recommends measuring a search service rather than reducing its economics to one “price per query” number.
Cortex Agents sit above this retrieval/query layer. They can reason about a request, select tools, work with structured and unstructured information, execute actions, and compose the result instead of forcing application developers to build the entire orchestration loop themselves.
The internal mechanics also changed during 2026. On April 13, Snowflake changed Agents using Cortex Analyst semantic views so the agent could generate SQL directly rather than delegating SQL generation to the Analyst service as a separate step, which Snowflake says reduced latency and improved accuracy; applications parsing old cortex_analyst_text_to_sql blocks needed to recognize the newer system_execute_sql response pattern.
That detail is exactly why dated documentation matters. A diagram from early 2026 showing an Agent always calling a separate Cortex Analyst text-to-SQL step can already describe an outdated runtime path.
Then there is MCP, the Model Context Protocol. Snowflake's August 7, 2026 Native Apps release lets providers create a Snowflake-managed MCP server that exposes approved app-owned objects, including Cortex Search services, semantic views, stored procedures, and UDFs, as tools an agent can call.
That makes Snowflake Cortex Agents MCP more than another chatbot feature. MCP provides a standardized tool boundary: instead of hard-coding a bespoke integration for every capability, an agent can discover and invoke tools that the app explicitly exposes and the consumer approves.
For an adjacent workflow-automation perspective outside this Snowflake-native mechanism, Refonte's data analytics and n8n automation guide covers a different layer of automation. The important architectural distinction is that Cortex Agents and Snowflake-managed MCP operate around governed Snowflake AI/data objects, whereas a general workflow orchestrator connects a broader collection of external systems.
The 2026 Release Timeline: The CoCo/CoWork Naming Problem
The fastest way to see why older Cortex articles age badly is to put the releases on a calendar. Between July 23 and August 10, 2026 alone, Snowflake changed model discovery, model availability, document processing, coding assistance, work automation, agent/MCP packaging, and multimodal embedding.
Date | Release | Status / practical significance |
July 23, 2026 | SHOW CORTEX BASE MODELS | GA; exposes models usable by the role/account plus lifecycle and regional information |
July 24, 2026 | Anthropic Claude Opus 5 in Cortex AI | Public Preview; available across Cortex AI surfaces including AI_COMPLETE |
July 27, 2026 | AI_EXTRACT / AI_PARSE_DOCUMENT encrypted-stage and network-restricted support | Preview; broadens document processing for client-side encryption and restricted accounts |
July 28, 2026 | GA | |
August 6, 2026 | Automations in Snowflake CoWork | Public Preview; schedules recurring questions/reports against refreshed data |
August 7, 2026 | Cortex Agents and MCP servers in Native Apps | GA |
August 10, 2026 | AI_MULTI_EMBED for large-video semantic search | GA; supports video files up to 6 GB with TwelveLabs Marengo Embed 3.0 |
SHOW CORTEX BASE MODELS may look like an administrator convenience, but it solves a real production problem. As of its July 23 GA release, Snowflake can return not merely model names but each model's lifecycle status, regional availability, legacy date, and end-of-life date, filtered through model RBAC.
That means an engineering team no longer has to treat a hard-coded model string in AI_COMPLETE as a permanent constant. You can inspect what the current role can actually use and whether a selected model is moving toward legacy or end-of-life status before building a pipeline around it.
The July 27 AI_EXTRACT and AI_PARSE_DOCUMENT update is similarly mechanical. Snowflake added Preview support for documents on stages using client-side encryption, along with network-restricted environments using PrivateLink or related policies, which addresses a deployment constraint rather than merely adding another extraction demo.
On August 6, CoWork Automations entered public preview. An automation can re-run a question against fresh data on a schedule and email the resulting summary and metrics, with a link back to the report for follow-up analysis.
August 10 extended the story beyond text and static documents. AI_MULTI_EMBED became generally available for semantic search over video files up to 6 GB using TwelveLabs Marengo Embed 3.0, allowing retrieval around scenes, actions, speech, and other multimodal content rather than only filenames or manually maintained tags.
Then there is Snowflake Summit 2026's naming churn:
Previous name | Current name | What to remember |
Cortex Code | Snowflake CoCo | Same core product; Snowflake explicitly says the functionality and architecture remain the same |
Snowflake Intelligence | Snowflake CoWork | New name accompanied by expansion from conversational analytics toward a broader personal-work-agent product |
Cortex AISQL | Cortex AI Functions | Snowflake's current product page describes AI Functions as formerly Cortex AISQL |
Genie Spaces, on the Databricks side | Genie Agents | A separate 2026 rename worth recognizing in competitor research |
Snowflake's CoCo FAQ is unusually explicit: CoCo is the new name for Cortex Code, and Snowflake says product functionality and architecture remained the same through that rename.
CoWork requires slightly more nuance. Snowflake says Snowflake Intelligence is now Snowflake CoWork, but it also says the product has expanded from conversational analytics toward a personal work agent capable of reasoning across data, automating work, and connecting to tools.
The practical consequence is search ambiguity. A February tutorial can say “Cortex Code,” a June Summit article can say “CoCo,” a job description can still say “Snowflake Intelligence,” and current product documentation can say “CoWork”; analysts researching the stack need to recognize both generations of terminology.
This also means a static certification study guide or blog post can become lexically obsolete without its underlying architecture becoming entirely wrong. Search both names when troubleshooting, evaluating a job description, or reading implementation guidance.
Cortex Analyst vs Databricks Genie: What the Comparison Looks Like Now
A Snowflake vs Databricks AI comparison is useful only if you compare today's products rather than screenshots from six months ago. Databricks has also changed its nomenclature in 2026: what used to be called Genie Spaces is now Genie Agents, alongside Genie One and Genie Code.
The standard comparison that says “Cortex Analyst is API-first while Genie is chat-only” is no longer accurate. Databricks now documents a Genie Agents API with stateful conversation endpoints for applications, bots, and agent frameworks, plus management APIs for CI/CD and programmatic configuration.
Factor | Snowflake Cortex Analyst | Databricks Genie Agents |
Primary grounding | Semantic Views; legacy YAML semantic models remain supported | Unity Catalog datasets plus curated SQL, SQL expressions, examples, instructions, and trusted assets |
Natural-language output | Generates SQL for analytical questions | Generates SQL, results, and visualizations where applicable |
Conversation | Multi-turn requests supported | Stateful conversations and follow-ups supported |
External integration | Cortex Analyst REST API; broader agent integrations through Cortex Agents | REST/SDK Conversation APIs and external-app embedding |
Current billing model | Standalone Analyst API billed per 1,000 messages; Agent invocation uses token-based AI Credits; generated SQL adds warehouse cost | As of Aug. 2026, identified-user Genie One and Genie Agents AI usage is promotional/free through Jan. 31, 2027; service-principal use is billed; SQL compute remains separate |
Data/governance center | Snowflake objects, privileges, semantic layer and warehouse execution | Unity Catalog assets and Databricks SQL compute |
Best deciding factor | You already run governed analytics in Snowflake | You already run governed analytics in Databricks/Unity Catalog |
Cortex Analyst's advantage is not that Snowflake magically knows every company's business terminology. Teams define a semantic layer that represents metrics and relationships, then use verified queries, custom instructions, evaluations, and monitoring to improve the quality of text-to-SQL behavior.
Genie requires curation too. Databricks' current documentation tells analysts to configure a Genie Agent with Unity Catalog datasets, example SQL, SQL expressions representing business semantics, and instructions tailored to organizational terminology; a Genie Agent can currently include up to 30 registered tables or views.
So “Snowflake uses human-curated semantics while Databricks automatically figures everything out” would be misleading. Both platforms increasingly automate metadata generation and assistance, but both still expect people to curate the business context that makes generated queries reliable.
Delivery is converging too. Cortex Analyst exposes REST endpoints, while Databricks supports a Genie API and lets teams embed Genie Agents in external applications subject to workspace configuration and user authentication.
Billing is where old comparisons are particularly dangerous. Snowflake's current pricing documentation says direct standalone Cortex Analyst calls are billed per 1,000 messages, while using Analyst through Cortex Agents follows the Agent token-based AI Credit model; executing generated SQL still consumes standard virtual-warehouse compute.
Databricks' August 2026 documentation says identified-user usage of Genie One and Genie Agents is free through January 31, 2027 under its current promotion, with service principals excluded and billed; Databricks separately tracks and charges relevant compute, and Genie Code follows its own pay-as-you-go rules.
This is why third-party comparisons such as “$36,000/year Snowflake versus $28,000/year Databricks” must be treated as directional estimates, not confirmed platform pricing. Those numbers come from secondary comparison blogs rather than the vendors' official pricing pages, and they can fail to account for warehouse sizes, credit contracts, token volumes, data-refresh rates, regional prices, promotional discounts, or the August 2026 Genie promotion.
Do not put such a number in a procurement model until you independently reproduce its assumptions against current official consumption tables. The current official documents already demonstrate how quickly a static annual comparison can age.
The bigger deciding factor is usually architectural rather than ideological. An organization with its governed measures, security policies, workloads, and semantic assets already in Snowflake has a lower-friction path to Cortex Analyst; a company standardized on Databricks SQL and Unity Catalog has the corresponding advantage with Genie.
That is why “Which is objectively better?” is usually the wrong first question. Start with: Where is the governed analytical context already maintained, which team owns it, and what compute/security model already surrounds it?
For readers comparing the broader responsibilities around these platforms rather than only their AI interface, Refonte's data analytics engineering guide for 2026 provides adjacent context. Cortex and Genie sit on top of the data-engineering and governance work; neither makes that layer disappear.
What Cortex Automates: What a Data Analyst Still Has to Know
The easiest way to misuse Cortex Analyst is to confuse SQL generation with analytical correctness. A query can compile, execute in 400 milliseconds, return 18,432 rows, and still answer the wrong business question.
Consider this requirement: “Show active customers by month.” Whether the generated SQL is correct depends on whether “active” means logged in during the month, had a paid subscription at month-end, generated revenue during the period, or met a company-specific status rule.
Cortex can automate | Human responsibility remains |
Translate a grounded natural-language request into SQL | Define what the business metric means |
Find relevant schema objects from a semantic layer | Model and maintain the semantic layer |
Apply natural-language AI functions at SQL scale | Decide whether the model output is appropriate for the use case |
Retrieve semantically related content | Decide what source content is authoritative |
Run repeatable AI operations inside Snowflake | Validate costs, security, and operational behavior |
Help an agent choose tools | Decide which tools an agent should be allowed to invoke |
Produce syntactically valid analytical queries | Detect logically valid but analytically wrong queries |
The last row is the one that matters most for data analyst skills in 2026. Knowing SQL is not less useful because Cortex Analyst can generate it; SQL becomes the inspection language you need to determine whether the machine's interpretation deserves to reach a dashboard, an executive briefing, or a regulatory report.
The priority order therefore looks like this:
Priority | Skill | Why it matters with Cortex-style AI |
Must | SQL fluency | You need to inspect joins, filters, grouping, window logic, null handling, and grain |
Must | Semantic-model literacy | Business terms must map to the correct dimensions, measures, metrics, and relationships |
Should | Experience with an AI-BI interface | Cortex Analyst, Genie, Fabric-style copilots, or equivalent systems teach you how NL-to-query workflows fail |
Should | Vector search and RAG basics | Needed to understand Cortex Search retrieval rather than treating it like a database LIKE clause |
Good | Semantic-layer maintenance | Useful for improving instructions, verified queries, relationships, and metric definitions |
Good | AI cost-monitoring literacy | Cortex functions, Analyst, Search, and agents have different consumption mechanics |
Snowflake itself now exposes concrete quality and observability mechanisms that reinforce this point. Cortex Analyst logs can include the question, generated SQL, errors, warnings, request/response data, and related metadata, and teams can use those records to keep refining their semantic view.
That gives analysts a familiar review workflow: sample real questions, inspect generated SQL, compare results against known-good logic, identify recurring errors, update the semantic layer, and rerun an evaluation. It is closer to testing a data product than chatting casually with a general-purpose model.
Mistake: trusting generated SQL because it executes. An error-free query proves only that Snowflake accepted the syntax and object references; it does not prove that the join grain, date semantics, inclusion rules, or metric definition match the business question.
The fix is to maintain verified question/SQL pairs for high-value analytical patterns and inspect regressions. Snowflake's Cortex Analyst evaluation feature explicitly uses verified queries as ground truth for measuring generated SQL behavior.
Mistake: treating the semantic model as a one-time configuration file. Schemas change, metric definitions change, companies rename product lines, finance adjusts fiscal logic, and business vocabulary drifts.
Snowflake's monitoring and optimization features are built around continued refinement rather than “configure once and forget.” Its own documentation says administrators need to continue refining the semantic model/view to improve answer quality.
Mistake: confusing Cortex Analyst with Cortex Search. If the answer requires SUM, COUNT DISTINCT, a date join, and a dimension filter, it belongs in the structured analytical path; if the answer depends on finding passages with similar meaning, retrieval is the relevant primitive.
Mistake: ignoring AI cost because the SQL looks simple. A six-line query can invoke an AI function over millions of records, and Snowflake's 2026 usage-history tooling can track consumption by function, model, user, role, warehouse, or query specifically because those costs require operational controls.
On certifications, there is not a single universally dominant credential titled “Cortex Analyst certification” that replaces broader Snowflake expertise. A SnowPro-oriented Snowflake credential plus a concrete Cortex portfolio project is therefore a more defensible signal than presenting a generic AI certificate as proof that you can model business semantics and validate generated SQL.
A strong portfolio project would document the semantic definitions, show natural-language test questions, expose the generated SQL, compare that SQL with verified reference queries, record failure cases, and explain the changes you made. That demonstrates the exact judgment companies need when conversational analytics moves beyond a demo.
Current hiring signals already show this vocabulary entering real requirements rather than remaining inside product marketing. A 2026 JPMorgan Chase data-analytics posting reviewed for this research specifically referenced knowledge of Snowflake Cortex features including Cortex Search and Cortex Analyst together with cloud data-warehouse and semantic-framework skills.
That does not mean every Data Analyst role now requires Cortex. It does mean platform-specific AI-BI terminology has started appearing beside the traditional SQL, warehouse, semantic-layer, and visualization requirements rather than replacing them.
Salary.com's U.S. benchmark dated August 1, 2026 reports an average Data Analyst salary of $97,717 per year, with a reported 25th-to-75th-percentile range of $87,374 to $107,616.
That salary figure is a third-party U.S. compensation estimate, not a guarantee for a particular role, location, or experience level. For the wider career discussion rather than reproducing it here, see Refonte's broader data analytics trends and career outlook and data analytics trends, tools, and career opportunities.
The deeper career implication is simpler: an analyst who can write SQL and critique AI-generated SQL has more control than an analyst who can only prompt. Natural-language interfaces reduce the cost of producing a first query; they do not eliminate the value of knowing what a correct query should look like.
Self-Study vs a Structured Data Analytics Program
You can learn SQL without enrolling in a structured program. The honest distinction is not “self-study does not work”; it is that self-study puts the burden of curriculum design, project quality, feedback, sequencing, and accountability on the learner.
Claims such as “everyone writes their first useful SQL query in two to four weeks” or “everyone becomes job-ready in six months” should not be treated as universal benchmarks. Prior programming experience, weekly practice, access to realistic data, and the depth of SQL required can move those timelines substantially.
Factor | Self-study | Refonte Learning Data Analytics Program |
Time to first SQL query | Often days to a few weeks depending on background; no universal benchmark | The published curriculum includes a dedicated SQL Database module; the exact week is not specified. |
SQL coverage | Depends entirely on resources chosen | Dedicated SQL Database curriculum module |
Visualization | Learner must assemble tools/projects independently | Dedicated EDA and Data Visualization module |
Programming | Depends on selected learning path | Python plus the program's documented analytics-tool stack |
Project structure | Self-defined | Application to Industry Projects module |
Formal completion proof | Usually personal projects or external course certificates | Training Certificate + Certificate of Internship |
Program duration | Learner-defined | 3 months, 12–14 hours/week |
“Job-ready” timeline | No reliable universal number | The program lasts 3 months; individual job-readiness varies and is not guaranteed. |
The comparison matters specifically because of Cortex Analyst. You can learn the syntax of SELECT, WHERE, GROUP BY, and JOIN quickly; the harder part is recognizing that an apparently reasonable join duplicates fact rows, a date filter uses the wrong fiscal boundary, or a generated COUNT(DISTINCT customer_id) answers a different question than the requested active-subscriber metric.
The Refonte Learning Data Analytics Program does not currently list Snowflake, Cortex Analyst, Cortex Search, or a specific cloud data warehouse in its published curriculum. That limitation should remain explicit: this is not a Snowflake Cortex course, and describing it as one would overstate what the program page promises.
Its relevant connection to this article is foundational. The program teaches SQL and analytical programming, which are the skills you use to understand what an AI-generated query is doing rather than accepting the answer because a natural-language interface produced it.
The program runs for three months, online, at an advertised commitment of 12–14 hours per week, and Refonte describes it as a combined training and virtual-internship experience. Its admission prerequisite is that the learner is currently pursuing a bachelor's degree or higher.
The eight published modules are:
· Introduction to the Program
· Python for Business Analytics
· EDA and Data Visualization
· SQL Database
· Machine Learning and Predictive Modelling
· Deep Learning Methods & Techniques
· Model Optimization & Problem-Solving
· Application to Industry Projects
The verified tool set includes Python, R, SQL, Tableau, and advanced Excel. The live program page explicitly discusses R and Python, SQL, data visualization, Tableau learning content, and advanced Excel; it does not name Snowflake or Cortex.
The mentor listed for the program is PhD Helena Ferreira, Department of Data Analytics, with 13+ years of experience. Refonte describes her background as including advanced regression work, algorithm development, financial econometrics, quantitative risk forecasting, and big-data analytics in banking and financial services.
Program detail | Published information |
Duration | 3 months |
Weekly commitment | 12–14 hours/week |
Format | Online training + virtual internship structure |
Prerequisite | Pursuing a bachelor's degree or higher |
Core tools | Python, R, SQL, Tableau, advanced Excel |
Career outcomes listed | Data Scientist, Data Analyst, ML Engineer |
Standard completion credentials | Training Certificate + Certificate of Internship |
Additional recognition | Top performers may receive a Letter of Recommendation, Certificate of Appreciation, and prizes |
One-time fee | $300 |
Installments | $204 + $98 |
Displayed list price | $387 with a displayed 30% discount |
The program page also advertises “$85K+ starting” and “30K+ jobs annually” for Data Analytics. Those figures should be understood as claims displayed by the program itself, not as independent labor-market statistics equivalent to the Salary.com benchmark cited earlier.
Certificates also need the same precise framing. Successful completion brings a Training Certificate and Certificate of Internship; outstanding/top performers may additionally receive a Letter of Recommendation, Certificate of Appreciation, and prizes according to the published program page.
What does that have to do with Snowflake Cortex AI? Not that the curriculum teaches AI_COMPLETE, but that a learner who has actually practiced SQL databases, Python analytics, EDA, visualization, and project work is in a better position to inspect the analytical logic an AI tool produces.
That distinction will matter more as AI-BI interfaces get easier to use. The barrier to generating a query is falling; the barrier to knowing whether the query deserves trust remains analytical competence.
The program details, current curriculum, eligibility, and fees are available on the Refonte Learning Data Analytics Program.
FAQ: People Also Ask and the Practical Takeaway
The mechanics can be reduced to a compact decision map:
When your problem is… | Start with… |
“Turn this business question into an analytical SQL query” | Cortex Analyst |
“Summarize/classify/extract/translate this data from SQL” | Cortex AI Functions |
“Retrieve text with related meaning, not just exact keywords” | Cortex Search |
“Coordinate Analyst, Search, procedures, and other tools” | Cortex Agents |
“Expose approved tools through a standardized agent interface” | MCP |
“Help developers build data/AI workflows” | CoCo |
“Give knowledge workers a broader personal work agent” | CoWork |
What is Snowflake Cortex Analyst?
Cortex Analyst is Snowflake's natural-language analytics capability for structured data. It uses Semantic Views (or legacy YAML semantic models still supported for backward compatibility) to connect business concepts with actual Snowflake schema, generates SQL from natural-language questions, and supports conversational follow-ups and REST-based application integration.
Why did Snowflake rename its AI functions in 2026?
By 2026, Snowflake had established AI_-prefixed functions as its current AI SQL surface, including AI_COMPLETE, AI_CLASSIFY, AI_FILTER, AI_EXTRACT, AI_SENTIMENT, and AI_SUMMARIZE_AGG. The transition actually started before 2026: the Cortex AI Functions preview launched June 2, 2025, and the mapping is not one-to-one: AI_COMPLETE is the updated COMPLETE, AI_SENTIMENT is documented as the updated ENTITY_SENTIMENT, and AI_SUMMARIZE_AGG adds across-row aggregation behavior rather than merely renaming the legacy scalar summarization function.
What is the difference between Cortex Analyst and Cortex Search?
Cortex Analyst handles structured analytical questions by turning natural language into SQL grounded in a semantic layer. Cortex Search builds retrieval indexes and combines vector similarity, text matching, and reranking, making it appropriate for semantic retrieval and RAG over text and other searchable content.
Is Cortex Analyst better than Databricks Genie?
Neither is universally better. Cortex Analyst fits naturally around Snowflake Semantic Views, Snowflake RBAC, and Snowflake warehouse execution, while Databricks Genie Agents are curated around Unity Catalog data, SQL instructions, examples, and Databricks SQL compute; both now provide APIs and conversational follow-up capabilities, so your existing governed data platform is usually the more important deciding factor.
Does using Cortex AI mean my data trains Snowflake's models?
Snowflake states that Cortex Analyst does not use Customer Data to train or fine-tune models for use across its customer base. Snowflake also says its default Snowflake-hosted Analyst inference keeps relevant metadata and prompts inside the Snowflake governance boundary, while generated SQL follows Snowflake access controls.
Do I need to learn Snowflake specifically to become a Data Analyst in 2026?
No single warehouse platform is a universal prerequisite for data-analysis work. The more transferable skill is SQL: Snowflake Cortex Analyst, Databricks Genie, and other natural-language analytics tools can generate queries, but analysts still need to understand joins, aggregation, filtering, grain, metric definitions, and data quality well enough to validate those queries rather than trusting them blindly.
The mechanics lead to four conclusions:
· Snowflake's move toward the AI_ function namespace reflects a real consolidation of its SQL-native AI surface, but the transition started before 2026 and is more nuanced than a simple COMPLETE/SUMMARIZE/SENTIMENT rename. AI_COMPLETE is now the canonical successor to COMPLETE, while newer functions add extraction, classification, filtering, embeddings, translation, redaction, and across-row summarization.
· Cortex Analyst and Cortex Search solve different problems. Analyst grounds business language in structured semantics and generates SQL; Search retrieves semantically relevant indexed content using vector, text, and reranking signals.
· Snowflake's July–August 2026 release cadence shows an actively changing platform. Claude Opus 5 arrived in public preview on July 24, SHOW CORTEX BASE MODELS reached GA on July 23, Native Apps gained GA Cortex Agents/MCP support on August 7, and large-video AI_MULTI_EMBED reached GA on August 10.
· None of those releases eliminates SQL judgment. The easier Snowflake makes it to produce queries from English, the more valuable it becomes to understand semantic definitions, join logic, aggregation grain, cost, governance, and the difference between SQL that runs and SQL that answers the right question.
For analysts who need to build the SQL and Python foundation required to evaluate AI-generated queries rather than trust them blindly, the Refonte Learning Data Analytics Program provides a three-month structured starting point without claiming to teach Snowflake or Cortex directly.